Tensor Programs V: Tuning Large Neural Networks via Zero-Shot Hyperparameter Transfer
arXiv:2203.03466v2 · This workspace stays on this version. Check arXiv for newer versions
Some source details need review 3 to check
Original formulas, table values and figures are preserved. Comparison can miss differences; use the original PDF to check details.
Reading view checked: 1393 math expressions, 23 rendering failures; 36 of 36 images available.
Compared 211 of 388 source passages against 31 of 48 PDF pages.
- Some formulas could not be rendered; their original TeX is shown. Check the original PDF. (23)
- This long paper was only partially compared; the original sources remain available.
HTML [S7_T7] gives “PTB | perplexity | 11.39 | 13.00”; PDF p. 11 gives “PTB perplexity 11.4 13.0”. The PDF table image also shows those rounded values, so this is not OCR or glyph ambiguity. Check PDF page 11
36 of 36 figure, table and graphic images captured. Open original PDF
Abstract
Hyperparameter (HP) tuning in deep learning is an expensive process, prohibitively so for neural networks (NNs) with billions of parameters. We show that, in the recently discovered Maximal Update Parametrization (P), many optimal HPs remain stable even as model size changes. This leads to a new HP tuning paradigm we call Transfer: parametrize the target model in P, tune the HP indirectly on a smaller model, and zero-shot transfer them to the full-sized model, i.e., without directly tuning the latter at all. We verify Transfer on Transformer and ResNet. For example, 1) by transferring pretraining HPs from a model of 13M parameters, we outperform published numbers of BERT-large (350M parameters), with a total tuning cost equivalent to pretraining BERT-large once; 2) by transferring from 40M parameters, we outperform published numbers of the 6.7B GPT-3 model, with tuning cost only 7% of total pretraining cost. A Pytorch implementation of our technique can be found at github.com/microsoft/mup and installable via pip install mup.
Hyperparameter (HP) tuning is critical to deep learning. Poorly chosen HPs result in subpar performance and training instability. Many published baselines are hard to compare to one another due to varying degrees of HP tuning. These issues are exacerbated when training extremely large deep learning models, since state-of-the-art networks with billions of parameters become prohibitively expensive to tune.
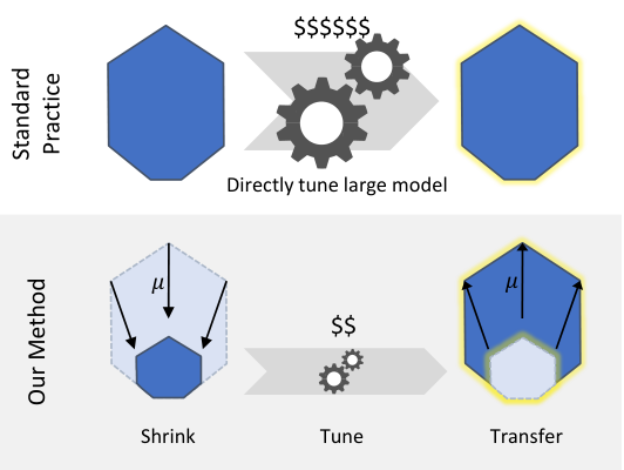
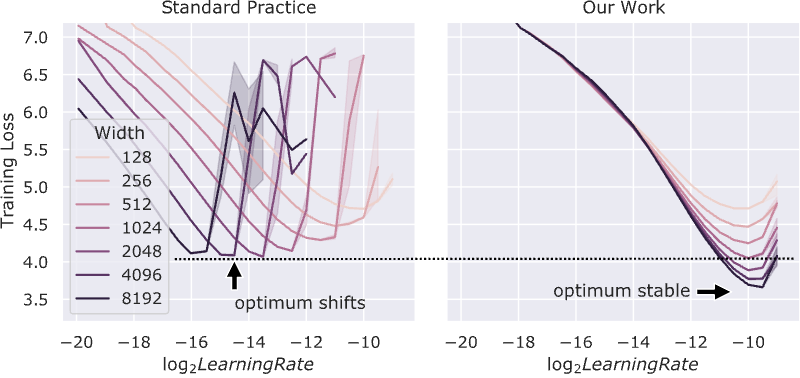
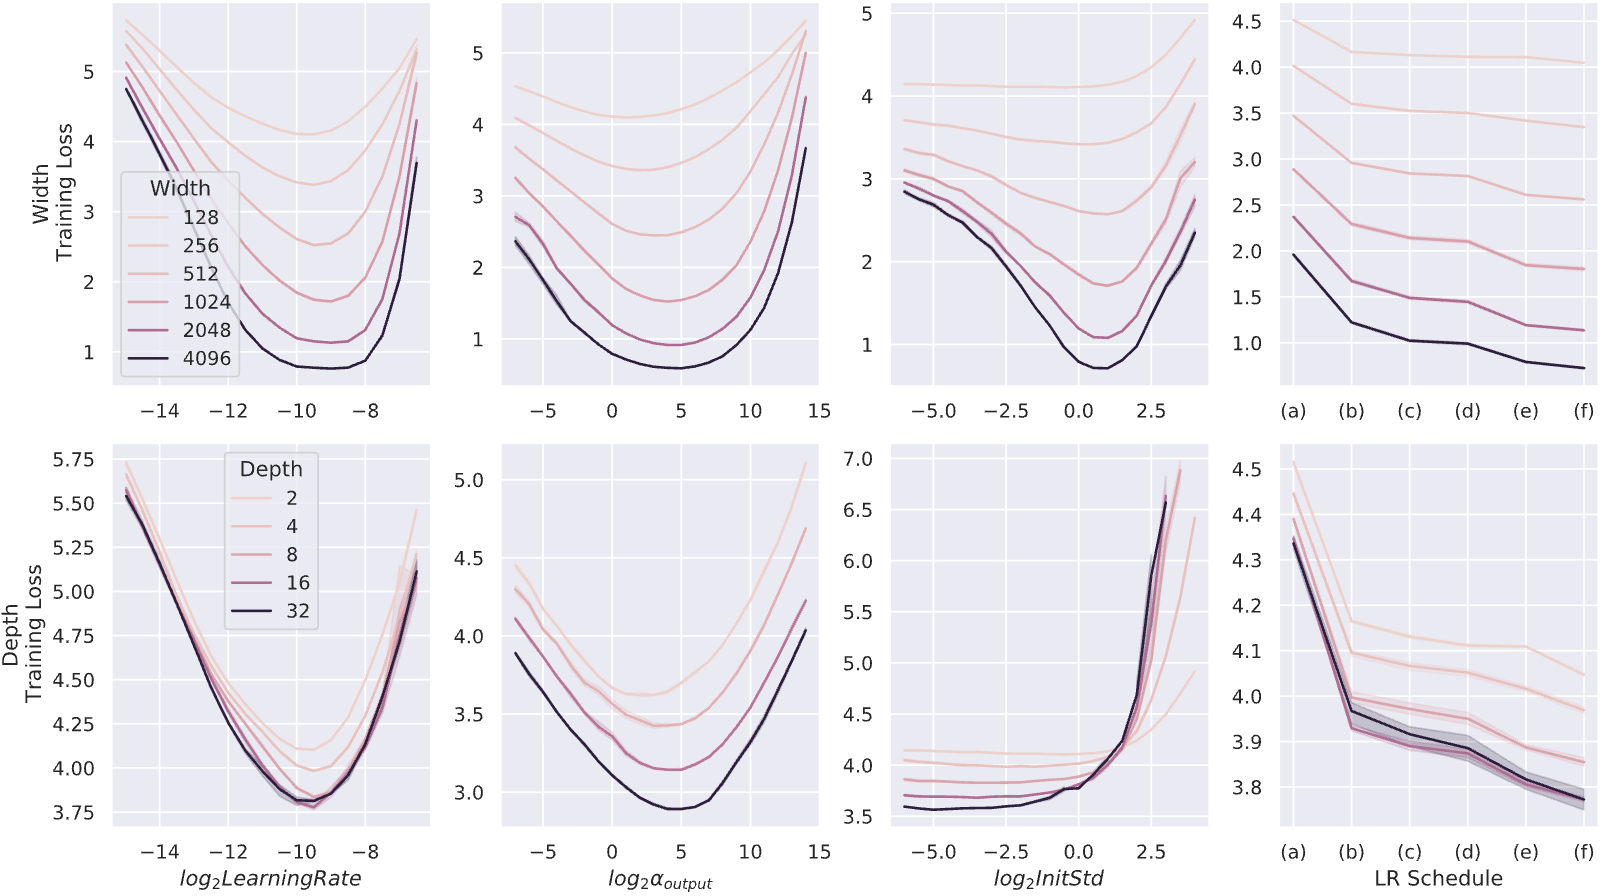
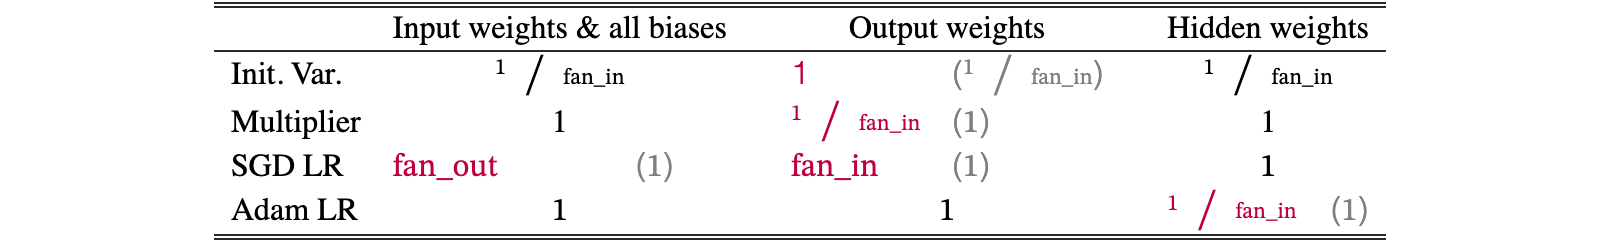
Recently, [57] showed that different neural network parametrizations induce different infinite-width limits and proposed the Maximal Update Parametrization (abbreviated P) (summarized in Table 3) that enables “maximal” feature learning in the limit. Intuitively, it ensures that each layer is updated on the same order during training regardless of width. In contrast, while the standard parametrization (SP) ensures activations are of unit order at initialization, it actually causes them to blow up in wide models during training [57] essentially due to an imbalance of per-layer learning rate (also see Fig. 5). We leverage P to zero-shot transfer HPs from small models to large models in this work – that is, we obtain near optimal HPs on a large model without directly tuning it at all! While practitioners have always guessed HPs of large models from those of small models, the results are hit-or-miss at best because of incorrect parametrization. For example, as shown in Fig. 1, in a Transformer, the optimal learning rate is stable with width in P (right) but far from so in standard parametrization (left). In addition to width, we empirically verify that, with a few caveats, HPs can also be transferred across depth (in Section 6.1) as well as batch size, language model sequence length, and training time (in Section G.2.1). This reduces the tuning problem of an (arbitrarily) large model to that of a (fixed-sized) small model. Our overall procedure, which we call Transfer, is summarized in Algorithm 1 and Fig. 2, and the HPs we cover are summarized in Tables 1 and 2.
There are several benefits to our approach: 1. Better Performance:Transfer is not just about predicting how the optimal learning rate scales in SP. In general, we expect the Transferred model to outperform its SP counterpart with learning rate optimally tuned. For example, this is the case in Fig. 1 with the width-8192 Transformer. We discuss the reason for this in Sections 5 and C. 2. Speedup:It provides massive speedup to the tuning of large models. For example, we are able to outperform published numbers of (350M) BERT-large [11] purely by zero-shot HP transfer, with tuning cost approximately equal to 1 BERT-large pretraining. Likewise, we outperform the published numbers of the 6.7B GPT-3 model [7] with tuning cost being only 7% of total pretraining cost. For models on this scale, HP tuning is not feasible at all without our approach. 3. Tune Once for Whole Family:For any fixed family of models with varying width and depth (such as the BERT family or the GPT-3 family), we only need to tune a single small model and can reuse its HPs for all models in the family. For example, we will use this technique to tune BERT-base (110M parameters) and BERT-large (350M parameters) simultaneously by transferring from a 13M model. 4. Better Compute Utilization:While large model training needs to be distributed across many GPUs, the small model tuning can happen on individual GPUs, greatly increasing the level of parallelism for tuning (and in the context of organizational compute clusters, better scheduling and utilization ratio). 5. Painless Transition from Exploration to Scaling Up:Often, researchers explore new ideas on small models but, when scaling up, find their HPs optimized during exploration work poorly on large models. Transfer would solve this problem.
In addition to the HP stability property, we find that wider is better throughout training in P, in contrast to SP (Section 8). This increases the reliability of model scaling in deep learning.
In this work, we primarily focus on hyperparameter transfer with respect to training loss. In settings where regularization is not the bottleneck to test performance, as in all of our experiments here, this also translates to efficacy in terms of test loss. In other settings, such as finetuning of models on small datasets, Transfer may not be sufficient, as we discuss in Section 6.1.
| Transferable | Not Transferable | Transferred Across |
|---|---|---|
| optimization related, init, | regularization | width, depth*, batch size*, |
| parameter multipliers, etc | (dropout, weight decay, etc) | training time*, seq length* |
View original table

| Optimizer Related | Initialization | Parameter Multipliers |
|---|---|---|
| learning rate (LR), momentum, | per-layer | multiplicative constants after |
| Adam beta, LR schedule, etc | init. variance | weight/biases, etc |
View original table

- •
We demonstrate it is possible to zero-shot transfer near optimal HPs to a large model from a small version via the Maximal Update Parametrization (P) from [57].
- •
- •
We propose a new HP tuning technique, Transfer, for large neural networks based on this observation that provides massive speedup over conventional methods and covers both SGD and Adam training;
- •
We thoroughly verify our method on machine translation and large language model pretraining (in Section 7.3) as well as image classification (in Section G.1);
- •
We release a PyTorch [35] package for implementing Transfer painlessly. A sketch of this package is given in Appendix H.
Sometimes, to be less ambiguous, we often refer to the “large model” as the target model, as it is the model we wish to ultimately tune, while we refer to the “small model” as the proxy model, as it proxies the HP tuning process. We follow standard notation regarding dimensions in a Transformer; one can see Fig. 11 for a refresher.
In this section, we give a very basic primer on why the correct parametrization can allow HP transfer across width, but see Sections J.1, J.2 and J.3 for more (mathematical) details.
The Central Limit Theorem (CLT) says that, if are iid samples from a zero-mean, unit-variance distribution, then converges to a standard Gaussian as . Therefore, we can say that is the right order of scaling factor such that converges to something nontrivial. In contrast, if we set , then ; or if , then blows up in variance as .
Now suppose we would like to minimize the function
F_{n}(c)\mathbin{\overset{\mathrm{def}}{=}}\EV_{x_{1},\ldots,x_{n}}f(c(x_{1}+\cdots+x_{n}))\tag{(1)}over , for some bounded continuous function . If we reparametrize for , then by CLT, G_{n}(\alpha)\mathbin{\overset{\mathrm{def}}{=}}F_{n}(c)\to\EV f(\mathcal{N}(0,\alpha^{2})) stabilizes into a function of as . Then for sufficiently large , the optimal should be close to for any , and indeed, for — this precisely means we can transfer the optimal or for a smaller problem (say ) to a larger problem (say ): is approximately minimized by and is approximately minimized by . Because the transfer algorithm is simply copying , we say the parametrization is the correct parametrization for this problem.
In the scenario studied in this paper, are akin to randomly initialized parameters of a width- neural network, is akin to a HP such as learning rate, and is the test-set performance of the network after training, so that gives its expectation over random initializations. Just as in this example, if we parametrize the learning rate and other HPs correctly, then we can directly copy the optimal HPs for a narrower network into a wide network and expect approximately optimal performance — this is the (zero-shot) hyperparameter transfer we propose here. It turns out the Maximal Update Parametrization (P) introduced in [57] is correct (akin to the parametrization in above), while the standard parametrization (SP) is incorrect (akin to the parametrization in ). We will review both parametrizations shortly. Theoretically, a P network has a well-defined infinite-width limit — akin to having a limit by CLT — while a SP network does not (the limit will blow up) [57]. In fact, based on the theoretical foundation laid in [57], we argue in Section J.3 that P should also be the unique parametrization that allows HP transfer across width. For a more formal discussion of the terminologies parametrization and transfer, see Appendix A
We emphasize that, to ensure transferability of any hyperparameter (such as learning rate), it’s not sufficient to reparametrize only that hyperparameter, but rather, we need to identify and correctly reparametrize all hyperparameters in Table 2. For example, in Fig. 1, the wide models in SP still underperform their counterparts in P, even with learning rate tuned optimally. This is precisely because SP does not scale parameter multipliers and input/output layer learning rates correctly in contrast to P (see Table 3). See Appendix C for more intuition via a continuation of our example here. We shall also explain this more concretely in the context of neural networks in Section 5.
In the community there seem to be conflicting assumptions about HP stability. A priori, models of different sizes don’t have any reason to share the optimal HPs. Indeed, papers aiming for state-of-the-art results often tune them separately. On the other hand, a nontrivial fraction of papers in deep learning fixes all HPs when comparing against baselines, which reflects an assumption that the optimal HPs should be stable — not only among the same model of different sizes but also among models of different designs — therefore, such comparisons are fair. Here, we demonstrate HP instability across width explicitly in MLP and Transformers in the standard parametrization. We will only look at training loss to exclude the effect of regularization.
We start with a 2-hidden-layer MLP with activation function , using the standard parametrization with LeCun initialization akin to the default in PyTorch:
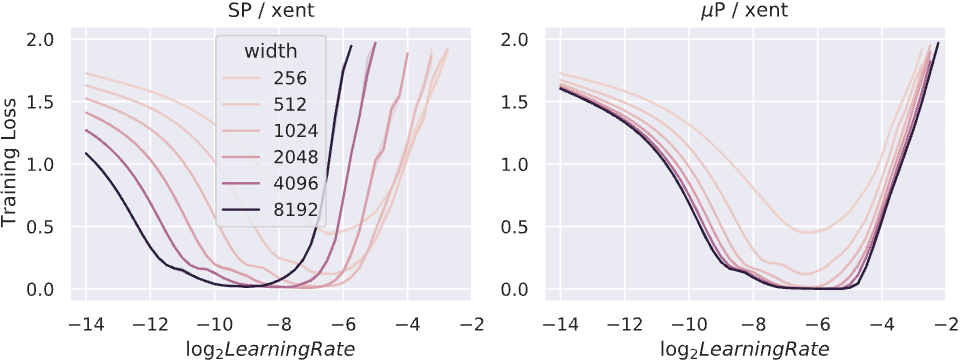
where , , and , , and are the input, hidden, and output dimensions. The particular MLP we use has and a cross-entropy (xent) loss function. We define the width of MLP as the hidden size , which is varied from 256 to 8192. The models are trained on CIFAR-10 for 20 epochs, which is more than enough to ensure convergence.
As shown on the left in Fig. 3, the optimal learning rate shifts by roughly an order of magnitude as the width increases from 256 to 8192; using the optimal learning of the smallest model on the largest model gives very bad performance, if not divergence.
This perhaps unsurprising observation holds for more complex architectures such as Transformer as well, as shown in Fig. 1 (left). We define width as , with and . The models are trained on wikitext-2 for 5 epochs. In Fig. 18 in the appendix we also show the instability of initialization scale and other HPs.
| Input weights & all biases | Output weights | Hidden weights | ||||
|---|---|---|---|---|---|---|
| Init. Var. | () | |||||
| SGD LR | () | () | ||||
| Adam LR | () | () | ||||
View original table
We show that P solves the problems we see in Section 3.
For the MLP in Section 3, to switch to P, we just need to modify Eq. 2’s initialization of the last layer and its learning rates of the first and last layer as well as of the biases. The basic form is
Here, specifies the “master” learning rate, and we highlighted in purple the differences in the two parametrizations. This basic form makes clear the scaling with width of the parametrization, but in practice we will often insert (possibly tune-able) multiplicative constants in front of each appearance of . For example, this is useful when we would like to be consistent with a SP MLP at a base width . Then we may insert constants as follows: For ,
Then at width , all purple factors above are 1, and the parametrization is identical to SP (Eq. 2) at width . Of course, as increases from , then Eq. 4 quickly deviates from Eq. 2. In other words, for a particular , P and SP can be identical up to the choice of some constants (in this case ), but P determines a different “set" of networks and optimization trajectory than SP as one varies . As we will see empirically in the next section, this deviation is crucial for HP transfer.
Indeed, in Fig. 3(right), we plot the CIFAR10 performances, over various learning rates and widths, of P MLPs with . In contrast to SP, the optimal learning rate under P is stable. This means that, the best learning rate for a width-128 network is also best for a width-8192 network in P — i.e. HP transfer works — but not for SP. In addition, we observe performance for a fixed learning rate always weakly improves with width in P , but not in SP.
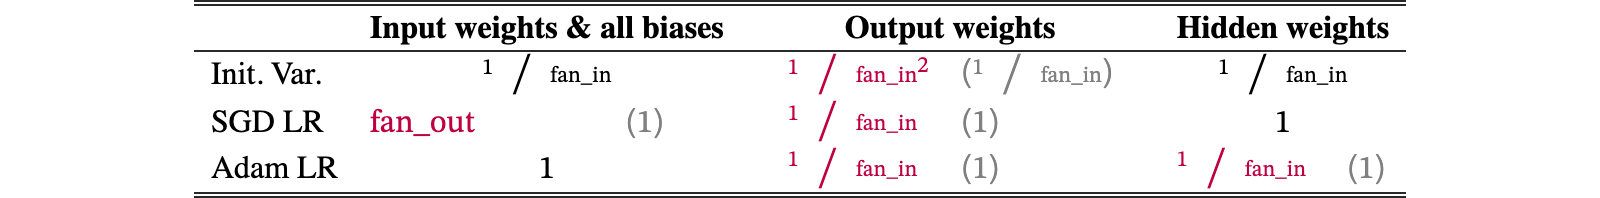
This MLP P example can be generalized easily to general neural networks trained under SGD or Adam, as summarized in Table 3, which is derived in Appendix J.
We repeat the experiments with base width for Transformers:
The Maximal Update Parametrization (P) for a Transformer is given by Table 3 and attention instead of , i.e. the attention logit is calculated as instead of where query and key have dimension .
The results are shown on the right in Fig. 1, where the optimal learning rate is stable, and the performance improves monotonically with width. See Appendix B for further explanation of P.
The question of SP vs P has already been studied at length in [57]. Here we aim to recapitulate the key insights, with more explanations given in Section J.3.
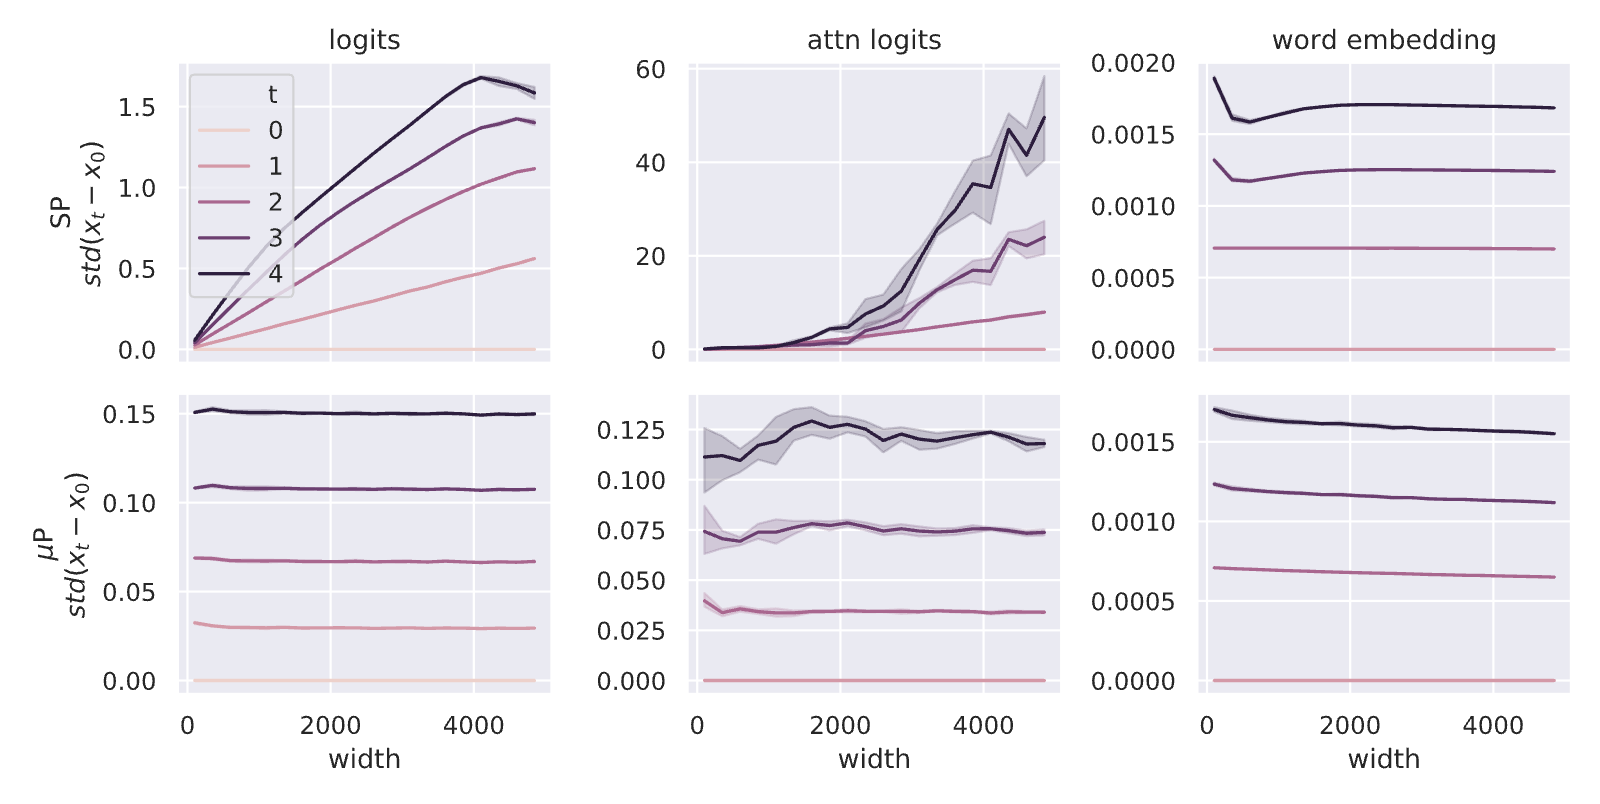
As shown in [57] and Section J.3, in SP, the network output will blow up with width after 1 step of SGD. It’s instructive to consider a 1-hidden-layer linear perceptron with scalar inputs and outputs, as well as weights . In SP, ad for each . This sampling ensures that at initialization. After 1 step of SGD with learning rate 1, the new weights are , where is some scalar of size depending on the inputs, labels, and loss function. But now
blows up with width because by Law of Large Numbers.
Now consider the same network in P. According to Table 3, we now have in contrast to SP, but as before, with learning rates . After 1 step of SGD, we now have
and one can verify this is and thus does not blow up with width.
One can observe the same behavior in more advanced architectures like Transformers and optimizers like Adam; in fact, in SP, other hidden quantities like attention logits will also blow up with width after 1 step, but in P still remain bounded, as shown in Fig. 5(middle).
One might think scaling down the learning rate with width can solve this problem in SP. However, other hidden activations like the word embedding (Fig. 5(right)) in a Transformer update by a width-independent amount for each step of training, so scaling down the learning rate will effectively mean the word embeddings are not learned in large width models. Similar conclusions apply to other models like ResNet (in fact, one can observe in the SP linear MLP example above, the input layer is updated much more slowly than the output layer). On the other hand, P is designed so that all hidden activations update with the same speed in terms of width (see Section J.2 for why).
This is why a wide model tuned with Transfer should in general outperform its SP counterpart with (global) learning rate tuned. For example, this is the case for the width-8192 Transformer in Fig. 1, where, in SP, the optimal learning rate needs to mollify the blow-up in quantities like logits and attention logits, but this implies others like word embeddings do not learn appreciably. This performance advantage means Transfer does more than just predicting the optimal learning rate of wide SP models. Relatedly, we observe, for any fixed HP combination, training performance never decreases with width in P, in contrast to SP (e.g., the P curves in Figs. 1, 3 and 16 do not cross, but the SP curves do; see also Section 8).
In this section, we explore how common HPs fit into our framework. In general, they can be divided into three kinds, summarized in Table 1:
- 1.
those that can transfer from the small to the large model, such as learning rate (Table 2);
- 2.
those that primarily control regularization and don’t work well with our technique; and
- 3.
those that define training scale, such as width as discussed above as well as others like depth and batch size, across which we transfer other HPs.
Those in the first category transfer across width, as theoretically justified above in Section 2. To push the practicality and generality of our technique, we empirically explore the transfer across the other dimensions in the third category. Note that Transfer across width is quite general, e.g. it allows varying width ratio of different layers or number of attention heads in a Transformer; see Section E.2. This will be very useful in practice. For the second category, the amount of regularization (for the purpose of controlling overfitting) naturally depends on both the model size and data size, so we should not expect transfer to work if the parametrization only depends on model size. We discuss these HPs in more detail in Section E.1.
Our empirical investigations focus on Transformers (here) and ResNet (in Section G.1.1), the most popular backbones of deep learning models today. We train a 2-layer pre-layernorm P Transformer with 4 attention heads on Wikitext-2. We sweep one of four HPs (learning rate, output weight multiplier, initialization standard deviation, and learning rate schedule) while fixing the others and sweeping along width and depth (with additional results in Fig. 19 on transfer across batch size, sequence length, and training time). Fig. 4 shows the results averaged over 5 random seeds.
Empirically, we find that for language modeling on Transformers, HPs generally transfer across scale dimensions if some minimum width (e.g. 256), depth (e.g., 4), batch size (e.g., 32), sequence length (e.g., 128), and training steps (e.g., 5000) are met, and the target scale is within the “reasonable range” as in our experiments. Now, there are some caveats. While the exact optimum can shift slightly with increasing scale, this shift usually has very small impact on the loss, compared to SP (Figs. 1 and 3(left)). However, there are some caveats. For example, the best initialization standard deviation does not seem to transfer well across depth (2nd row, 3rd column), despite having a stabler optimum across width. In addition, while our results on width, batch size, sequence length, and training time still hold for post-layernorm (Fig. 17), the transfer across depth only works for pre-layernorm Transformer. Nevertheless, in practice (e.g. our results in Section 7.3) we find that fixing initialization standard deviation while tuning other HPs works well when transferring across depth.
Now that the plausibility of Transfer has been established in toy settings, we turn to more realistic scenarios to see if one can achieve tangible gains. Specifically, we perform HP tuning only on a smaller proxy model, test the obtained HPs on the large target model directly, and compare against baselines tuned using the target model. We seek to answer the question: Can Transfer make HP tuning more efficient while achieving performance on par with traditional tuning? As we shall see by the end of the section, the answer is positive. We focus on Transformers here, while experiments on ResNets on CIFAR10 and Imagenet can be found as well in Section G.1. All of our experiments are run on V100 GPUs.
IWSLT14 De-En is a well-known machine translation benchmark. We use the default IWSLT (post-layernorm) Transformer implemented in fairseq [33] with 40M parameters, which we denote as the 1x model. For Transfer, we tune on a 0.25x model with of the width, amounting to 4M parameters. For this experiment, we tune via random search the learning rate , the output layer parameter multiplier , and the attention key-projection weight multiplier . See the grid and other experimental details in Section F.1.
We compare transferring from the 0.25x model with tuning the 1x model while controlling the total tuning budget in FLOPs. To improve the reproducibility of our result: 1) we repeat the entire HP search process (a trial) 25 times for each setup, with number of samples as indicated in Table 4, and report the 25th, 50th, 75th, and 100th percentiles in BLEU score; 2) we evaluate each selected HP combination using 5 random initializations and report the mean performance.
We pick the HP combination that achieves the lowest validation loss for each trial. The reported best outcome is chosen according to the validation loss during tuning. We compare against the default in fairseq, which is presumably heavily tuned. The result is shown in Table 4.
| Val. BLEU Percentiles | ||||||
|---|---|---|---|---|---|---|
| Setup | Total Compute | #Samples | 25 | 50 | 75 | 100 |
| fairseq[33] default | - | - | - | - | - | 35.40 |
| Tuning on 1x | 1x | 5 | 33.62 | 35.00 | 35.35 | 35.45 |
| Naive transfer from 0.25x | 1x | 64 | training diverged | |||
| Transfer from 0.25x (Ours) | 1x | 64 | 35.27 | 35.33 | 35.45 | 35.53 |
View original table
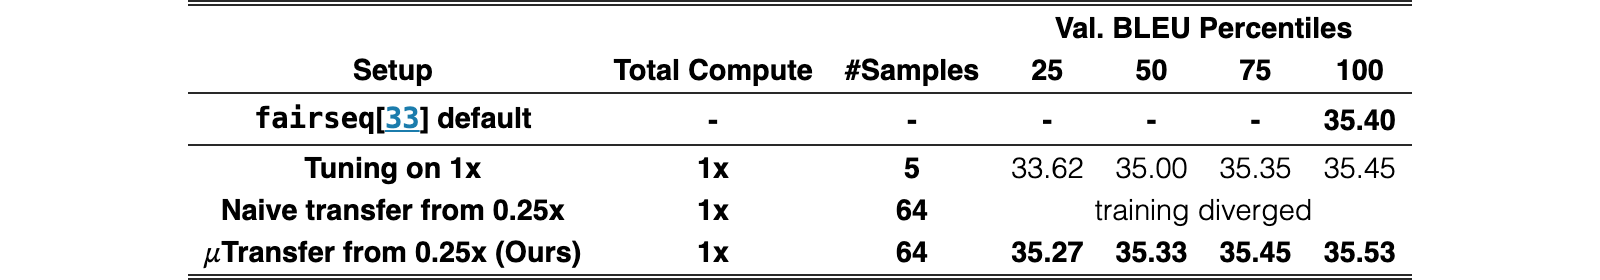
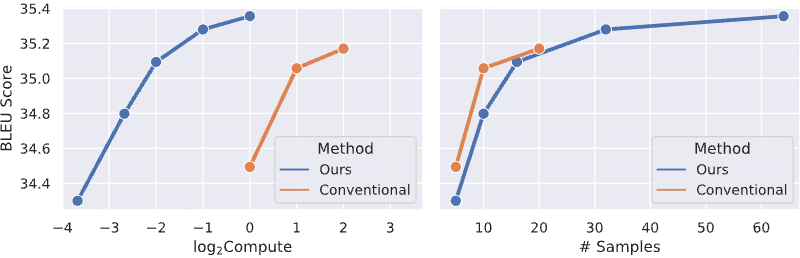
The result above only describes a particular compute budget. Is Transfer still preferable when we have a lot more (or less) compute? To answer this question, we produce the compute-performance Pareto frontier in Fig. 6(left), where we repeat the above experiment with different compute budgets. Evidently, our approach completely dominates conventional tuning.
The Pareto frontier in Fig. 6(right) suggests that, given a fixed number of random samples from the HP space, 1) tuning the target model directly yields slightly better results than tuning the proxy model (while taking much more compute of course), but 2) this performance gap seems to vanish as more samples are taken. This can be explained by the intuition that the narrower proxy model is a “noisy estimator” of the wide target model [57].With few samples, this noise can distort the random HP search, but with more samples, this noise is suppressed.
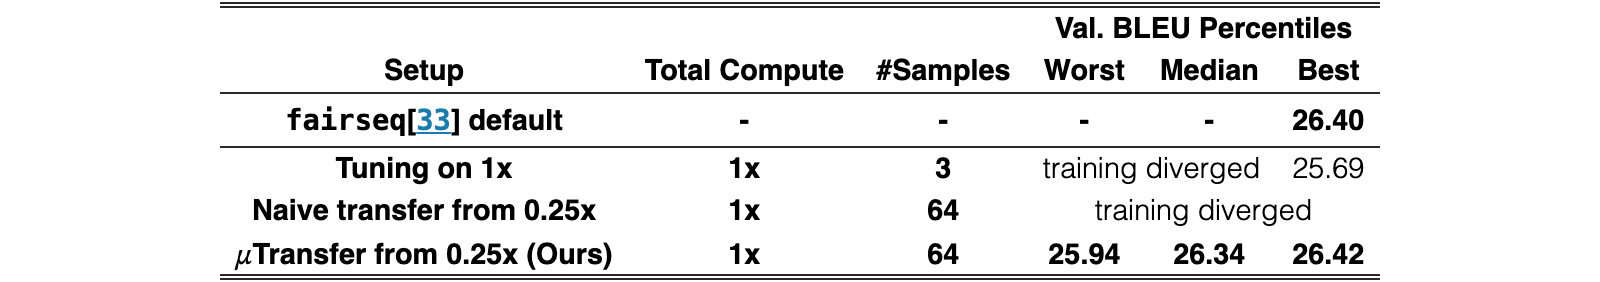
We scale up to WMT14 En-De using the large (post-layernorm) Transformer from [50] with 211M parameters. We tune on a proxy model with 15M parameters by shrinking , , and . For this experiment, we tune via random search the learning rate , the output layer parameter multiplier , and the attention key-projection weight multiplier following the grid in Section F.2. The result is shown in Table 5: While random search with 3 HP samples far underperforms the fairseq default, we are able to match it via transfer using the same tuning budget.
| Val. BLEU Percentiles | |||||
|---|---|---|---|---|---|
| Setup | Total Compute | #Samples | Worst | Median | Best |
| fairseq[33] default | - | - | - | - | 26.40 |
| Tuning on 1x | 1x | 3 | training diverged | 25.69 | |
| Naive transfer from 0.25x | 1x | 64 | training diverged | ||
| Transfer from 0.25x (Ours) | 1x | 64 | 25.94 | 26.34 | 26.42 |
View original table
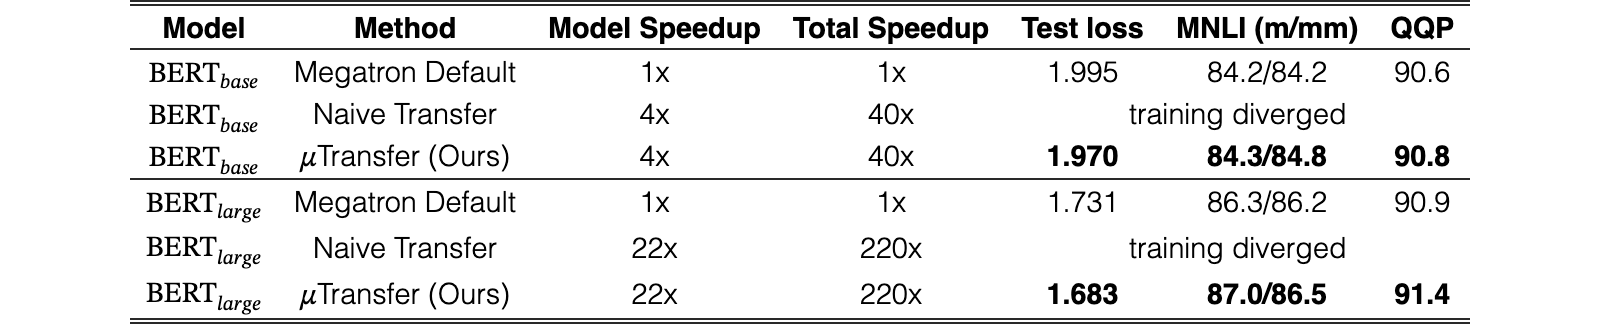
Finally, we consider large-scale language model pretraining where HP tuning is known to be challenging. Using Megatron (pre-layernorm) BERT [43] as a baseline, we hope to recover the performance of the published HPs by only tuning a proxy model that has roughly 13M parameters, which we call BERT-prototype. While previous experiments scaled only width, here we will also scale depth, as discussed in Section 6 and validated in Fig. 4. We use a batch size of 256 for all runs and follow the standard finetuning procedures. For more details on BERT-prototype, what HPs we tune, and how we finetune the trained models, see Section F.3.
During HP tuning, we sample 256 combinations from the search space and train each combination on BERT-prototype for steps. The total tuning cost measured in FLOPs is roughly the same as training 1 BERT-large for the full steps; the exact calculation is shown in Section F.3. The results are shown in Table 6. Notice that on BERT-large, we obtain sizeable improvement over the well-tuned Megatron BERT-large baseline.
| Model | Method | Model Speedup | Total Speedup | Test loss | MNLI (m/mm) | QQP |
|---|---|---|---|---|---|---|
| Megatron Default | 1x | 1x | 1.995 | 84.2/84.2 | 90.6 | |
| Naive Transfer | 4x | 40x | training diverged | |||
| Transfer (Ours) | 4x | 40x | 1.970 | 84.3/84.8 | 90.8 | |
| Megatron Default | 1x | 1x | 1.731 | 86.3/86.2 | 90.9 | |
| Naive Transfer | 22x | 220x | training diverged | |||
| Transfer (Ours) | 22x | 220x | 1.683 | 87.0/86.5 | 91.4 | |
View original table
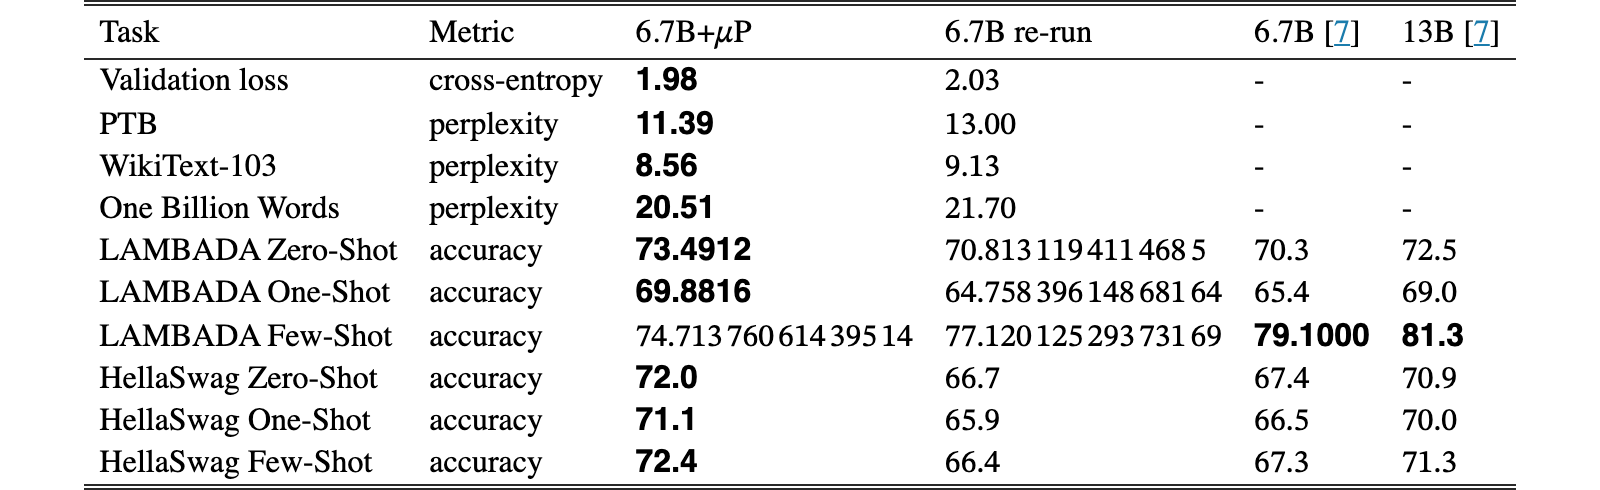
In order to further verify Transfer at scale, we applied it to GPT-3 6.7B [7] with relative attention. This target model consists of 32 residual blocks with width 4096. We form the small proxy model by shrinking width to 256, resulting in roughly 40 million trainable parameters, 168 times smaller than the target model. HPs were then determined by a random search on the proxy model. The total tuning cost was only 7% of total pretraining cost. Details of the HP sweep can be found in Section F.4.
In order to exclude code difference as a possible confounder, we also re-trained GPT-3 6.7B from scratch using the original HPs from [7]. Unfortunately, after we have finished all experiments, we found this baseline mistakenly used absolute attention (like models in [7]) when it was supposed to use relative attention like the target model. In addition, during training of the Transfer model we encountered numerical issues that lead to frequent divergences. In order to avoid them, the model was trained using FP32 precision, even though the original 6.7B model and our re-run were trained using FP16. The resulting Transfer model outperforms the 6.7B from [7], and is in fact comparable to the twice-as-large 13B model across our evaluation suite (see Table 11). Selected evaluation results can be found in Table 7 and further details are given in Table 10 and Section F.4.
| Task | Metric | 6.7B+P | 6.7B re-run | 6.7B [7] | 13B [7] |
| Validation loss | cross-entropy | 1.98 | - | - | |
| PTB | perplexity | 11.39 | - | - | |
| WikiText-103 | perplexity | 8.56 | - | - | |
| One Billion Words | perplexity | 20.51 | - | - | |
| LAMBADA Zero-Shot | accuracy | 73.4912 | |||
| LAMBADA One-Shot | accuracy | 69.8816 | |||
| LAMBADA Few-Shot | accuracy | 79.1000 | 81.3 | ||
| HellaSwag Zero-Shot | accuracy | 72.0 | |||
| HellaSwag One-Shot | accuracy | 71.1 | |||
| HellaSwag Few-Shot | accuracy | 72.4 |
View original table
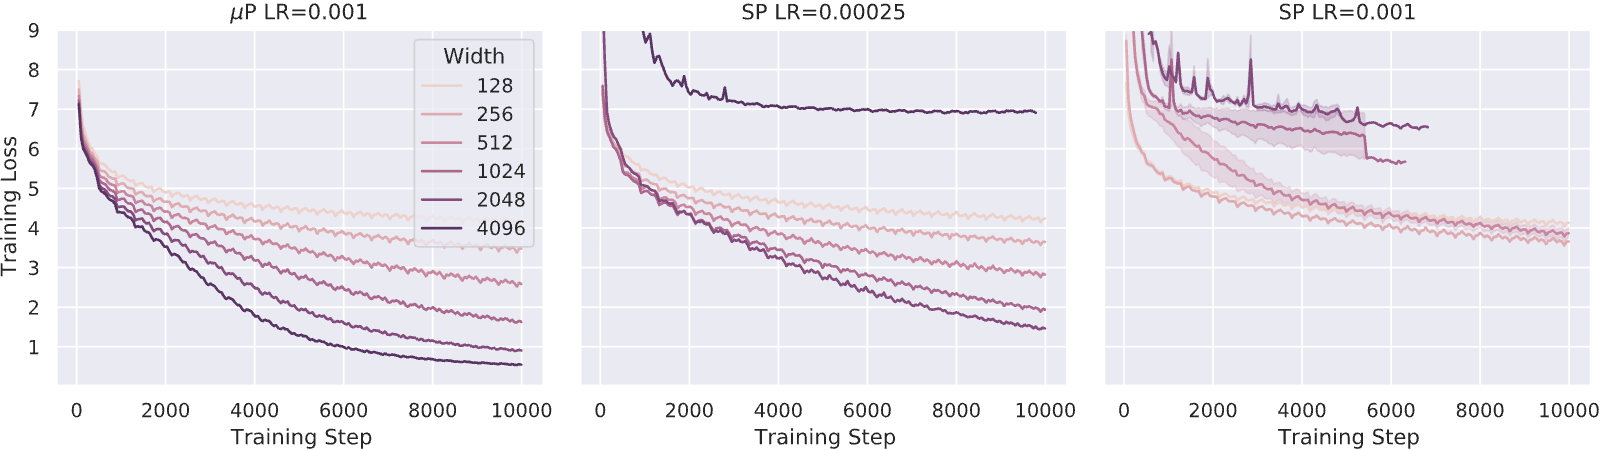
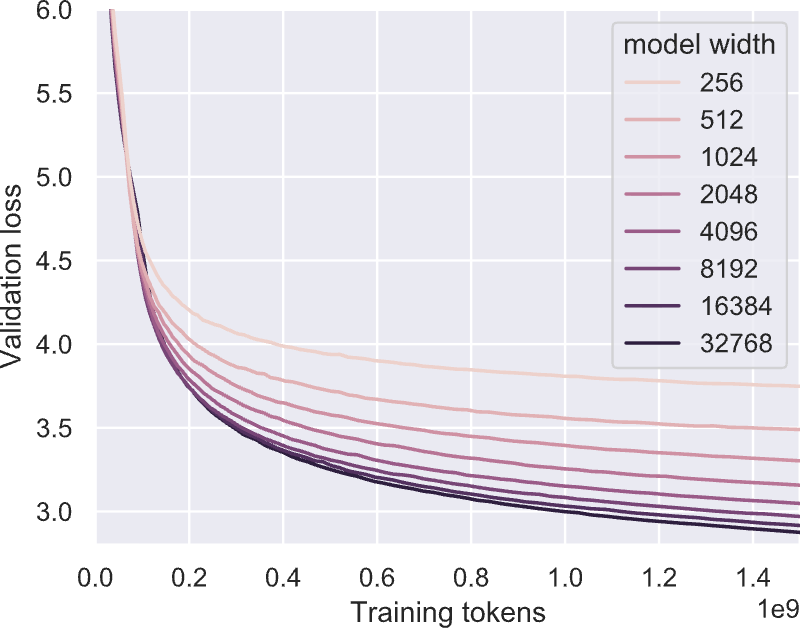
In earlier plots like Figs. 1 and 3, we saw that at the end of training, wider is always better in P but not in SP. In fact, we find this to be true throughout training, as seen in Fig. 7, modulo noise from random initialization and/or data ordering, and assuming the output layer is zero-initialized (which has no impact on performance as discussed in Section D.2). We then stress-tested this on a P GPT-3 Transformer (on the GPT-3 training data) by scaling width from 256 to 32,768 using a fixed set of HPs (Fig. 8). Wider models consistently match or outperform narrower models at each point in training (except a brief period around 1e8 training tokens, likely due to noise because we ran only 1 seed due to computational cost). Our observation suggests that wider models are strictly more data-efficient if scaled appropriately. By checking “wider-is-better” early in training, one can also cheaply debug a P implementation.
We want to tune HPs on a small model with width such that its HP landscape looks like that of a large model with width . Our intuition in Sections 2, C and J leads us to P. However, for this to be useful, we do not want the small model (as a function) after training to be close to that of the large model — otherwise there is no point in training the large model to begin with. So 1) must be large enough so that the HP optimum converges, but 2) cannot be so large that the functional dynamics (and the loss) converges. The fact that such exists, as demonstrated by our experiments, shows that: In some sense, the HP optimum is a “macroscopic” or “coarse” variable which converges quickly with width, while the neural network function (and its loss) is a very “microscopic” or “fine” detail that converges much more slowly with width. However, theoretically, it is unclear why this should happen, and where else we should expect such useful HP transfer. We leave an explanation to future work.
Many have sought to speedup HP tuning beyond the simple grid or random search. Snoek et al. 45 treated HP tuning as an optimization process and used Bayesian optimization by treating the performance of each HP combination as a sample from a Gaussian process (GP). Snoek et al. 46 further improved the runtime by swapping the GP with a neural network. Another thread of work investigated how massively parallel infrasture can be used for efficient tuning under the multi-arm bandit problem [18, 22]. There are also dedicated tools such as Optuna [4] and Talos [3] which integrate with existing deep learning frameworks and provide an easy way to apply more advanced tuning techniques.
Our approach is distinct from all of the above in that it does not work on the HP optimization process itself. Instead, it decouples the size of the target model from the tuning cost, which was not feasible prior to this work. This means that no matter how large the target model is, we can always use a fixed-sized proxy model to probe its HP landscape. Nevertheless, our method is complementary, as the above approaches can naturally be applied to the tuning of the proxy model; it is only for scientific reasons that we use either grid search or random search throughout this work.
Many previous works explored transfer learning of HP tuning (e.g. [62, 36, 47, 15]). However, to the best of our knowledge, our work is the first to explore zero-shot HP transfer. In addition, we focus on transferring across model scale rather than between different tasks or datasets. Some algorithms like Hyperband [23] can leverage cheap estimates of HP evaluations (like using a small model to proxy a large model) but they are not zero-shot algorithms, so would still be very expensive to apply to large model training. Nevertheless, all of the above methods are complementary to ours as they can be applied to the tuning of our proxy model.
[44] proposed to scale learning rate with batch size while fixing the total epochs of training; [14] proposed to scale learning rate as while fixing the total number of steps of training. However, [41] showed that there’s no consistent (learning rate, batch size) scaling law across a range of dataset and models. Later, [30] studied the trade-off of training steps vs computation as a result of changing batch size. They proposed an equation of , where and are task- and model-specific constants, for the optimal learning rate (see their fig 3 and fig 5). This law suggests that for sufficiently large batch size, the optimal learning rate is roughly constant. This supports our results here as well as the empirical results in [41, fig 8].
Assuming that the optimal learning rate should scale with batch size following [44], [34] empirically investigated how the optimal “noise ratio” scales with width for MLP and CNNs in NTK parametrization (NTP) or standard parametrization (SP) trained with SGD. They in particular focus on test loss in the regime of small batch size and training to convergence. In this regime, they claimed that in networks without batch normalization, the optimal noise ratio is constant in SP but scales like for NTP. However, they found this law breaks down for networks with normalization.
In contrast, here we focus on training loss, without training to convergence and with a range of batch sizes from small to very large (as is typical in large scale pretraining). Additionally, our work applies universally to 1) networks with normalization, along with 2) Adam and other adaptive optimizers; furthermore 3) we empirically validate transfer across depth and sequence length, and 4) explicitly validate tuning via Transfer on large models like BERT-large and GPT-3.
Finally, as argued in [57] and Section J.3, SP and NTP lead to bad infinite-width limits in contrast to P and hence are suboptimal for wide neural networks. For example, sufficiently wide neural networks in SP and NTP would lose the ability to learn features, as concretely demonstrated on word2vec in [57].
The original formulation of P in [57] (see Table 9, which is equivalent to Table 3) uses a fan-out initialization for the input layer. This is atypical in vision models, but in language models where the input and output layers are shared (corresponding to word embeddings), it can actually be more natural to use a fan-out initialization (corresponding to fan-in initialization of the output layer). In fact, we found that fairseq [33] by default actually implements both the fan-out initialization and the multiplier.
Many previous works proposed different initialization or parametrizations with favorable properties, such as better stability for training deep neural networks [13, 40, 60, 59, 66, 5, 16, 26]. Our work differs from these in that we focus on the transferability of optimal HPs from small models to large models in the same parametrization.
[57] introduced P as the unique parametrization that enables all layers of a neural network to learn features in the infinite-width limit, especially in contrast to the NTK parametrization [17] (which gives rise to the NTK limit) that does not learn features in the limit. Based on this theoretical insight, in Section J.3, we argue that P should also be the unique parametrization (in the sense of [57]) that allows HP transfer across width; in short this is because it both 1) preserves feature learning, so that performance on feature learning tasks (such as language model pretraining) does not become trivial in the limit, and 2) ensures each parameter tensor is not stuck at initialization in the large width limit, so that its learning rate does not become meaningless. At the same time, our results here suggest that P is indeed the correct parametrization for wide neural networks and thus provide empirical motivation for the theoretical study of the infinite-width P limit. Note, parametrization here refers to a rule to scale hyperparameters with width (“how should my initialization and learning rate change when my width doubles?”), which is coarser than a prescription for setting hyperparameters at any particular width (“how should I set my initialization and learning rate at width 1024?”).
Leveraging the discovery of a feature learning neural network infinite-width limit, we hypothesized and verified that the HP landscape across NNs of different width is reasonably stable if parametrized according to Maximal Update Parametrization (P). We further empirically showed that it’s possible to transfer across depth, batch size, sequence length, and training time, with a few caveats. This allowed us to indirectly tune a very large network by tuning its smaller counterparts and transferring the HPs to the full model. Our results raise an interesting new theoretical question of how useful HP transfer is possible in neural networks in the first place.
Nevertheless, our method has plenty of room to improve. For example, initialization does not transfer well across depth, and depth transfer generally still does not work for post-layernorm Transformers. This begs the question whether a more principled parametrization in depth could solve these problems. Additionally, Fig. 4 shows that the optimal HP still shifts slightly for smaller models. Perhaps by considering finite-width corrections to P one can fix this shift. Finally, it will be interesting to study if there’s a way to transfer regularization HPs as a function of both the model size and data size, especially in the context of finetuning of pretrained models.
In alphabetical order, we thank Arthur Jacot, Arturs Backurs, Colin Raffel, Denny Wu, Di He, Huishuai Zhang, Ilya Sutskever, James Martens, Janardhan Kulkarni, Jascha Sohl-Dickstein, Jeremy Bernstein, Lenaic Chizat, Luke Metz, Mark Chen, Michael Santacroce, Muhammad ElNokrashy, Pengchuan Zhang, Sam Schoenholz, Sanjeev Arora, Taco Cohen, Yiping Lu, Yisong Yue, and Yoshua Bengio for discussion and help during our research.
References
- [1] NVIDIA/DeepLearningExamples, apache v2 license. URL https://github.com/NVIDIA/DeepLearningExamples.Source
- [2] Davidnet, mit license, 2019. URL https://github.com/davidcpage/cifar10-fast.Source
- [3] Autonomio talos, mit license, 2019. URL http://github.com/autonomio/talos.Source
- [4] Takuya Akiba, Shotaro Sano, Toshihiko Yanase, Takeru Ohta, and Masanori Koyama. Optuna: A next-generation hyperparameter optimization framework, 2019.
- [5] Thomas Bachlechner, Bodhisattwa Prasad Majumder, Huanru Henry Mao, Garrison W. Cottrell, and Julian McAuley. ReZero is All You Need: Fast Convergence at Large Depth. arXiv:2003.04887 [cs, stat], June 2020. URL http://arxiv.org/abs/2003.04887.Source
- [6] Jeremy Bernstein, Arash Vahdat, Yisong Yue, and Ming-Yu Liu. On the distance between two neural networks and the stability of learning. arXiv:2002.03432 [cs, math, stat], January 2021. URL http://arxiv.org/abs/2002.03432.Source
- [7] Tom B. Brown, Benjamin Mann, Nick Ryder, Melanie Subbiah, Jared Kaplan, Prafulla Dhariwal, Arvind Neelakantan, Pranav Shyam, Girish Sastry, Amanda Askell, Sandhini Agarwal, Ariel Herbert-Voss, Gretchen Krueger, Tom Henighan, Rewon Child, Aditya Ramesh, Daniel M. Ziegler, Jeffrey Wu, Clemens Winter, Christopher Hesse, Mark Chen, Eric Sigler, Mateusz Litwin, Scott Gray, Benjamin Chess, Jack Clark, Christopher Berner, Sam McCandlish, Alec Radford, Ilya Sutskever, and Dario Amodei. Language models are few-shot learners, 2020.
- [8] Simon Carbonnelle and Christophe De Vleeschouwer. Layer rotation: a surprisingly powerful indicator of generalization in deep networks? arXiv:1806.01603 [cs, stat], July 2019. URL http://arxiv.org/abs/1806.01603.Source
- [9] Ciprian Chelba, Tomas Mikolov, Mike Schuster, Qi Ge, Thorsten Brants, Phillipp Koehn, and Tony Robinson. One billion word benchmark for measuring progress in statistical language modeling, 2014.
- [10] Zihang Dai, Zhilin Yang, Yiming Yang, Jaime Carbonell, Quoc V. Le, and Ruslan Salakhutdinov. Transformer-xl: Attentive language models beyond a fixed-length context, 2019.
- [11] Jacob Devlin, Ming-Wei Chang, Kenton Lee, and Kristina Toutanova. BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding. arXiv:1810.04805 [cs], May 2019. URL http://arxiv.org/abs/1810.04805.Source
- [12] Xiaohan Ding, Chunlong Xia, Xiangyu Zhang, Xiaojie Chu, Jungong Han, and Guiguang Ding. RepMLP: Re-parameterizing Convolutions into Fully-connected Layers for Image Recognition. arXiv:2105.01883 [cs], August 2021. URL http://arxiv.org/abs/2105.01883.Source
- [13] Xavier Glorot and Yoshua Bengio. Understanding the difficulty of training deep feedforward neural networks. In Yee Whye Teh and Mike Titterington, editors, Proceedings of the Thirteenth International Conference on Artificial Intelligence and Statistics, volume 9 of Proceedings of Machine Learning Research, pages 249–256, Chia Laguna Resort, Sardinia, Italy, May 2010. PMLR. URL http://proceedings.mlr.press/v9/glorot10a.html.Source
- [14] Elad Hoffer, Itay Hubara, and Daniel Soudry. Train longer, generalize better: closing the generalization gap in large batch training of neural networks. arXiv:1705.08741 [cs, stat], May 2017. URL http://arxiv.org/abs/1705.08741.Source
- [15] Samuel Horváth, Aaron Klein, Peter Richtárik, and Cédric Archambeau. Hyperparameter transfer learning with adaptive complexity. CoRR, abs/2102.12810, 2021. URL https://arxiv.org/abs/2102.12810.Source
- [16] Xiao Shi Huang and Felipe Pérez. Improving Transformer Optimization Through Better Initialization. page 9.
- [17] Arthur Jacot, Franck Gabriel, and Clément Hongler. Neural Tangent Kernel: Convergence and Generalization in Neural Networks. arXiv:1806.07572 [cs, math, stat], June 2018. URL http://arxiv.org/abs/1806.07572.Source
- [18] Kevin Jamieson and Ameet Talwalkar. Non-stochastic best arm identification and hyperparameter optimization, 2015.
- [19] Jared Kaplan, Sam McCandlish, Tom Henighan, Tom B. Brown, Benjamin Chess, Rewon Child, Scott Gray, Alec Radford, Jeffrey Wu, and Dario Amodei. Scaling Laws for Neural Language Models. arXiv:2001.08361 [cs, stat], January 2020. URL http://arxiv.org/abs/2001.08361.Source
- [20] Diederik Kingma and Jimmy Ba. Adam: A method for stochastic optimization. arXiv preprint arXiv:1412.6980, 2014.
- [21] Jaehoon Lee, Yasaman Bahri, Roman Novak, Sam Schoenholz, Jeffrey Pennington, and Jascha Sohl-dickstein. Deep Neural Networks as Gaussian Processes. In International Conference on Learning Representations, 2018. URL https://openreview.net/forum?id=B1EA-M-0Z.Source
- [22] Liam Li, Kevin Jamieson, Afshin Rostamizadeh, Ekaterina Gonina, Moritz Hardt, Benjamin Recht, and Ameet Talwalkar. A system for massively parallel hyperparameter tuning, 2020.
- [23] Lisha Li, Kevin Jamieson, Giulia DeSalvo, Afshin Rostamizadeh, and Ameet Talwalkar. Hyperband: A Novel Bandit-Based Approach to Hyperparameter Optimization. JMLR 18, page 52.
- [24] Hanxiao Liu, Zihang Dai, David R. So, and Quoc V. Le. Pay Attention to MLPs. arXiv:2105.08050 [cs], June 2021a. URL http://arxiv.org/abs/2105.08050.Source
- [25] Liyuan Liu, Xiaodong Liu, Jianfeng Gao, Weizhu Chen, and Jiawei Han. Understanding the difficulty of training transformers. In Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP), pages 5747–5763, Online, November 2020a. Association for Computational Linguistics. doi: 10.18653/v1/2020.emnlp-main.463. URL https://www.aclweb.org/anthology/2020.emnlp-main.463.Source
- [26] Liyuan Liu, Xiaodong Liu, Jianfeng Gao, Weizhu Chen, and Jiawei Han. Understanding the Difficulty of Training Transformers. arXiv:2004.08249 [cs, stat], September 2020b. URL http://arxiv.org/abs/2004.08249.Source
- [27] Xiaodong Liu, Pengcheng He, Weizhu Chen, and Jianfeng Gao. Multi-task deep neural networks for natural language understanding. In Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics, pages 4487–4496, Florence, Italy, July 2019. Association for Computational Linguistics. URL https://www.aclweb.org/anthology/P19-1441.Source
- [28] Yang Liu, Jeremy Bernstein, Markus Meister, and Yisong Yue. Learning by Turning: Neural Architecture Aware Optimisation. arXiv:2102.07227 [cs], September 2021b. URL http://arxiv.org/abs/2102.07227.Source
- [29] Alexander G. de G. Matthews, Mark Rowland, Jiri Hron, Richard E. Turner, and Zoubin Ghahramani. Gaussian Process Behaviour in Wide Deep Neural Networks. arXiv:1804.11271 [cs, stat], April 2018. URL http://arxiv.org/abs/1804.11271. arXiv: 1804.11271.Source
- [30] Sam McCandlish, Jared Kaplan, Dario Amodei, and OpenAI Dota Team. An Empirical Model of Large-Batch Training. arXiv:1812.06162 [cs, stat], December 2018. URL http://arxiv.org/abs/1812.06162.Source
- [31] Luke Melas-Kyriazi. Do You Even Need Attention? A Stack of Feed-Forward Layers Does Surprisingly Well on ImageNet. arXiv:2105.02723 [cs], May 2021. URL http://arxiv.org/abs/2105.02723.Source
- [32] Stephen Merity, Caiming Xiong, James Bradbury, and Richard Socher. Pointer sentinel mixture models, 2016.
- [33] Myle Ott, Sergey Edunov, Alexei Baevski, Angela Fan, Sam Gross, Nathan Ng, David Grangier, and Michael Auli. fairseq: A fast, extensible toolkit for sequence modeling, mit license. In Proceedings of NAACL-HLT 2019: Demonstrations, 2019.
- [34] Daniel S. Park, Jascha Sohl-Dickstein, Quoc V. Le, and Samuel L. Smith. The Effect of Network Width on Stochastic Gradient Descent and Generalization: an Empirical Study. May 2019. URL https://arxiv.org/abs/1905.03776v1.Source
- [35] Adam Paszke, Sam Gross, Francisco Massa, Adam Lerer, James Bradbury, Gregory Chanan, Trevor Killeen, Zeming Lin, Natalia Gimelshein, Luca Antiga, Alban Desmaison, Andreas Kopf, Edward Yang, Zachary DeVito, Martin Raison, Alykhan Tejani, Sasank Chilamkurthy, Benoit Steiner, Lu Fang, Junjie Bai, and Soumith Chintala. Pytorch: An imperative style, high-performance deep learning library, bsd-style license. In H. Wallach, H. Larochelle, A. Beygelzimer, F. dÁlché Buc, E. Fox, and R. Garnett, editors, Advances in Neural Information Processing Systems 32, pages 8024–8035. Curran Associates, Inc., 2019. URL http://papers.neurips.cc/paper/9015-pytorch-an-imperative-style-high-performance-deep-learning-library.pdf.Source
- [36] Valerio Perrone, Rodolphe Jenatton, Matthias W Seeger, and Cedric Archambeau. Scalable Hyperparameter Transfer Learning. NeurIPS 2018, page 11.
- [37] Martin Popel and Ondřej Bojar. Training Tips for the Transformer Model. The Prague Bulletin of Mathematical Linguistics, 110(1):43–70, April 2018. ISSN 1804-0462. doi: 10.2478/pralin-2018-0002. URL http://content.sciendo.com/view/journals/pralin/110/1/article-p43.xml.Source
- [38] Colin Raffel, Noam Shazeer, Adam Roberts, Katherine Lee, Sharan Narang, Michael Matena, Yanqi Zhou, Wei Li, and Peter J. Liu. Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer. arXiv:1910.10683 [cs, stat], July 2020. URL http://arxiv.org/abs/1910.10683.Source
- [39] Jonathan S. Rosenfeld, Amir Rosenfeld, Yonatan Belinkov, and Nir Shavit. A Constructive Prediction of the Generalization Error Across Scales. arXiv:1909.12673 [cs, stat], December 2019. URL http://arxiv.org/abs/1909.12673.Source
- [40] Samuel S. Schoenholz, Justin Gilmer, Surya Ganguli, and Jascha Sohl-Dickstein. Deep Information Propagation. arXiv:1611.01232 [cs, stat], November 2016. URL http://arxiv.org/abs/1611.01232.Source
- [41] Christopher J. Shallue, Jaehoon Lee, Joseph Antognini, Jascha Sohl-Dickstein, Roy Frostig, and George E. Dahl. Measuring the Effects of Data Parallelism on Neural Network Training. arXiv:1811.03600 [cs, stat], November 2018. URL http://arxiv.org/abs/1811.03600.Source
- [42] Noam Shazeer and Mitchell Stern. Adafactor: Adaptive Learning Rates with Sublinear Memory Cost. April 2018. URL https://arxiv.org/abs/1804.04235v1.Source
- [43] Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper, and Bryan Catanzaro. Megatron-lm: Training multi-billion parameter language models using model parallelism. CoRR, abs/1909.08053, 2019. URL http://arxiv.org/abs/1909.08053.Source
- [44] Samuel L. Smith, Pieter-Jan Kindermans, and Quoc V. Le. Don’t Decay the Learning Rate, Increase the Batch Size. arXiv:1711.00489 [cs, stat], November 2017. URL http://arxiv.org/abs/1711.00489.Source
- [45] Jasper Snoek, Hugo Larochelle, and Ryan P. Adams. Practical bayesian optimization of machine learning algorithms, 2012.
- [46] Jasper Snoek, Oren Rippel, Kevin Swersky, Ryan Kiros, Nadathur Satish, Narayanan Sundaram, Md. Mostofa Ali Patwary, Prabhat, and Ryan P. Adams. Scalable bayesian optimization using deep neural networks, 2015.
- [47] Danny Stoll, Jörg K.H. Franke, Diane Wagner, Simon Selg, and Frank Hutter. Hyperparameter transfer across developer adjustments, 2021. URL https://openreview.net/forum?id=WPO0vDYLXem.Source
- [48] Ilya Tolstikhin, Neil Houlsby, Alexander Kolesnikov, Lucas Beyer, Xiaohua Zhai, Thomas Unterthiner, Jessica Yung, Andreas Steiner, Daniel Keysers, Jakob Uszkoreit, Mario Lucic, and Alexey Dosovitskiy. MLP-Mixer: An all-MLP Architecture for Vision. arXiv:2105.01601 [cs], June 2021. URL http://arxiv.org/abs/2105.01601.Source
- [49] Hugo Touvron, Piotr Bojanowski, Mathilde Caron, Matthieu Cord, Alaaeldin El-Nouby, Edouard Grave, Gautier Izacard, Armand Joulin, Gabriel Synnaeve, Jakob Verbeek, and Hervé Jégou. ResMLP: Feedforward networks for image classification with data-efficient training. arXiv:2105.03404 [cs], June 2021. URL http://arxiv.org/abs/2105.03404.Source
- [50] Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N. Gomez, Lukasz Kaiser, and Illia Polosukhin. Attention is all you need. CoRR, abs/1706.03762, 2017. URL http://arxiv.org/abs/1706.03762.Source
- [51] Alex Wang, Amanpreet Singh, Julian Michael, Felix Hill, Omer Levy, and Samuel R Bowman. Glue: A multi-task benchmark and analysis platform for natural language understanding. EMNLP 2018, page 353, 2018.
- [52] Adina Williams, Nikita Nangia, and Samuel Bowman. A broad-coverage challenge corpus for sentence understanding through inference. In Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers), pages 1112–1122. Association for Computational Linguistics, 2018. URL http://aclweb.org/anthology/N18-1101.Source
- [53] Greg Yang. Tensor Programs I: Wide Feedforward or Recurrent Neural Networks of Any Architecture are Gaussian Processes. arXiv:1910.12478 [cond-mat, physics:math-ph], December 2019a. URL http://arxiv.org/abs/1910.12478.Source
- [54] Greg Yang. Scaling Limits of Wide Neural Networks with Weight Sharing: Gaussian Process Behavior, Gradient Independence, and Neural Tangent Kernel Derivation. arXiv:1902.04760 [cond-mat, physics:math-ph, stat], February 2019b. URL http://arxiv.org/abs/1902.04760.Source
- [55] Greg Yang. Tensor Programs II: Neural Tangent Kernel for Any Architecture. arXiv:2006.14548 [cond-mat, stat], August 2020a. URL http://arxiv.org/abs/2006.14548.Source
- [56] Greg Yang. Tensor Programs III: Neural Matrix Laws. arXiv:2009.10685 [cs, math], September 2020b. URL http://arxiv.org/abs/2009.10685.Source
- [57] Greg Yang and Edward J. Hu. Feature learning in infinite-width neural networks. arXiv, 2020.
- [58] Greg Yang and Etai Littwin. Tensor Programs IIb: Architectural Universality of Neural Tangent Kernel Training Dynamics. arXiv:2105.03703 [cs, math], May 2021. URL http://arxiv.org/abs/2105.03703.Source
- [59] Greg Yang and Sam S. Schoenholz. Deep Mean Field Theory: Layerwise Variance and Width Variation as Methods to Control Gradient Explosion. February 2018. URL https://openreview.net/forum?id=rJGY8GbR-.Source
- [60] Greg Yang and Samuel S. Schoenholz. Mean Field Residual Networks: On the Edge of Chaos. arXiv:1712.08969 [cond-mat, physics:nlin], December 2017. URL http://arxiv.org/abs/1712.08969.Source
- [61] Greg Yang, Michael Santacroce, and Edward J Hu. Efficient computation of deep nonlinear infinite-width neural networks that learn features. In International Conference on Learning Representations, 2022. URL https://openreview.net/forum?id=tUMr0Iox8XW.Source
- [62] Dani Yogatama and Gideon Mann. Efficient Transfer Learning Method for Automatic Hyperparameter Tuning. In Artificial Intelligence and Statistics, pages 1077–1085. PMLR, April 2014. URL http://proceedings.mlr.press/v33/yogatama14.html.Source
- [63] Yang You, Igor Gitman, and Boris Ginsburg. Large Batch Training of Convolutional Networks. arXiv:1708.03888 [cs], September 2017. URL http://arxiv.org/abs/1708.03888.Source
- [64] Yang You, Jing Li, Sashank Reddi, Jonathan Hseu, Sanjiv Kumar, Srinadh Bhojanapalli, Xiaodan Song, James Demmel, Kurt Keutzer, and Cho-Jui Hsieh. Large Batch Optimization for Deep Learning: Training BERT in 76 minutes. arXiv:1904.00962 [cs, stat], January 2020. URL http://arxiv.org/abs/1904.00962.Source
- [65] Sergey Zagoruyko and Nikos Komodakis. Wide residual networks, 2017.
- [66] Hongyi Zhang, Yann N. Dauphin, and Tengyu Ma. Residual Learning Without Normalization via Better Initialization. In International Conference on Learning Representations, 2019. URL https://openreview.net/forum?id=H1gsz30cKX.Source
This section seeks to make formal and clarify some of the notions regarding parametrization discussed informally in the main text.
In a neural network, one may insert a “multiply by ” operation anywhere, where is a non-learnable scalar hyperparameter. If , then this operation is a no-op. This is called a multiplier.
Relatedly, for any parameter tensor in a neural network, we may replace with for some non-learnable scalar hyperparameter . When , we recover the original formulation. This is referred to as a parameter multiplier.
For example, in the attention logit calculation where , the factor is a multiplier. It may also be thought of as the parameter multiplier of if we rewrite the attention logit as .
Note parameter multipliers cannot be absorbed into the initialization in general, since they affect backpropagation. Nevertheless, after training is done, parameter multipliers can always be absorbed into the weight.
In this work, a parametrization is a rule for how to change hyperparameters when the widths of a neural network change, but note that it does not necessarily prescribes how to set the hyperparameters for any specific width. In particular, for any neural network, an abc-parametrization is a rule for how to scale a) the parameter multiplier, b) the initialization, and c) the learning rate individually for each parameter tensor as the widths of the network change, as well as any other multiplier in the network; all other hyperparameters are kept fixed with width.
For example, SP and P are both abc-parametrizations. Again, we note that, in this sense, a parametrization does not prescribe, for example, that the initialization variance be , but rather that it be halved when doubles.
In this work, we say a parametrization admits zero-shot transfer of a set of hyperparameters w.r.t. a metric if the optimal combination of values of w.r.t. converges as width goes to infinity, i.e. it stays approximately optimal w.r.t. under this parametrization as width increases.
Throughout this paper, we take to be the training loss, but because regularization is not the bottleneck in our experiments (especially large scale pretraining with BERT and GPT-3), we nevertheless see high quality test performance in all of our results. We also remark that empirically, using training loss as the metric can be more robust to random seed compared to validation loss and especially BLEU score. See Table 1(left) for . By our arguments in Section J.3 and our empirical results, P is the unique abc-parametrization admitting zero-shot transfer for such and in this sense.
More generally, one may define a -shot transfer algorithm of a set of hyperparameters w.r.t. a metric as one that 1) takes width values and and an approximately optimal combination of values of w.r.t. at a width and 2) returns an approximately optimal combination of values of w.r.t. at width , given 3) a budget of evaluations of candidate hyperparameter combinations on models of width . However, we will have no use for this definition in this paper.
| Input weights & all biases | Output weights | Hidden weights | ||||
| Init. Var. | 1 | () | ||||
| Multiplier | 1 | () | 1 | |||
| SGD LR | () | () | ||||
| Adam LR | () | |||||
View original table
| Input weights & all biases | Output weights | Hidden weights | ||||
| Init. Var. | ||||||
| Multiplier | () | () | 1 | |||
| SGD LR | ||||||
| Adam LR | () | () | () | |||
View original table
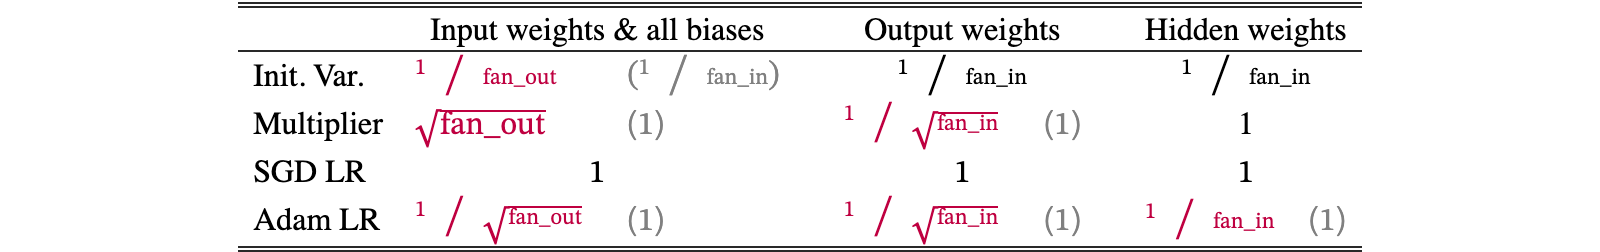
In addition to Table 3, we provide Table 8 as an equivalent P formulation that is easier to implement, as well as Table 9 for those more familiar with the original P formulation in [57]. Below, we provide some commentary on corner cases not well specified by the tables. Ultimately, by understanding Appendix J, one can derive P for any architecture, new or old.
We can classify any dimension in a neural network as “infinite” if it scales with width, or “finite” otherwise. For example, in a Transformer, are all infinite, but vocab size and context size are finite. Then we can categorize parameter tensors by how many infinite dimensions they have. If there are two such dimensions, then we say the parameter is matrix-like; if there is only one, then we say it is vector-like; if there is none, we say it is scalar-like. Then in Tables 3, 8 and 9, “input weights & all biases” and “output weights” are all vector-like parameters, while hidden weights are matrix-like parameters. An advantage of Table 8 is that it gives a uniform scaling rule of initialization and learning rate for all vector-like parameters. The multiplier rule in Table 8 can be more interpreted more generally as the following: a multiplier of order should accompany any weight that maps an infinite dimension to a finite one. This interpretation then nicely covers both the output logits and the attention logits (i.e. attention).
Scalar-like parameters are not as common as matrix-like and vector-like ones, but we will mention a few examples in Section B.2. The scaling rule for their initialization, learning rate (for both SGD and Adam), and multiplier is very simple: hold them constant with width.
We did not specify the initialization mean in the tables, since most commonly the mean is just set to 0, but it can be nonzero for vector-like parameters (e.g., layernorm weights) and scalar-like parameters but must be 0 for matrix-like parameters.
The initialization scaling rules in our tables can all be trivially satisfied if the initialization variance is set to 0. This can be useful in some settings (e.g., Section D.2) but detrimental in other settings (e.g., hidden weights).
Here, input weights very specifically refer to weights that map from an infinite dimension to a finite dimension. As a counterexample, in some architectures, the first layer can actually map from a finite dimension to another finite dimension, e.g., a PCA layer. Then this is not an “input weight”; if the next layer maps into an infinite dimension, then that’s the input weight. A similar, symmetric discussion applies to output weights.
For our tables, a model is specifically a function that maps a finite dimension to another finite dimension, consistent with the discussion above. For example, for an image model on CIFAR10, it maps from dimensions to 10 dimensions, and these numbers are fixed regardless of the width of the model. Likewise, for an autoregressive Transformer model, the input and output dimension are both the vocab size, which is independent of the width. In contrast, an MLP inside a Transformer is not a “model” in this sense because its input and output dimension are both equal to the width of the Transformer.
To ground the abstract description in Tables 3, 8 and 9, we walk through the parameters of a typical Transformer and discuss concretely how to parametrize each.
We assume that the user wants to replicate SP when the model widths are equal to some base widths, for example, when , etc, as in the MLP example in Section 4. For this purpose, it’s useful to define , and so on. One can always take for a “pure” P.
Below, we introduce hyperparameters for each parameter tensor, as well as a few multipliers . One may always tie (resp. ) across all parameter tensors, but in our experiments, we found it beneficial to at least distinguish the input and output layer initialization and learning rates.
The input word embedding matrix has size , where is the fan-in and is the fan-out. Follow the “input weight & all biases” column in Tables 3, 8 and 9. For example, for Tables 3 and 8,
Note here, because fan-in () here is independent of width (), the “” for the initialization variance in these tables is equivalent to “”, i.e. the initialization variance can be anything fixed with width. In this case of the word embedding, setting the variance to 1, for example, is more natural than setting the variance to , because the embedding is one-hot ( would be more natural for image inputs).
Layernorm weights and biases both have shape and can be thought of “input weights” to the scalar input of 1. Hence one should follow the “input weight & all biases” column in Tables 3, 8 and 9. In particular, the usual initialization of layernorm weights as all 1s and biases as all 0s suffice (where the initialization variance is 0). For example, for Tables 3 and 8,
We use instead of attention. To be compatible with attention when at a particular base , we set
where is a tunable multiplier.
Symmetric to the discussion on input word embeddings, the output word unembeddings should be parametrized according to the “output weights” column of Tables 3, 8 and 9. Often, the unembeddings are tied with the embeddings, and Tables 8 and 9 allow for this as their initialization schemes are symmetric between input and output weights.
For example, for Table 3, we’d set
For Table 8, we would instead have
(note here is the base width and therefore is a constant) and the output is computed as
where is the final layer embedding of a token, and is a tunable multiplier.
Recent works [24, 48, 31, 49, 12] on MLP-only architectures in NLP and CV replace the self-attention layer in Transformers with MLPs across tokens or spatial locations. In our language here, such MLPs have finite input and output dimensions (the context size) and infinite hidden dimensions, so their input, output, and hidden weights should be parametrized via the corresponding columns in Tables 3, 8 and 9.
Exactly the same as Adam in all of our tables, with the added benefit that weight decay is automatically scaled correctly in AdamW (but is incompatible with P Adam). For this reason, we recommend using AdamW when weight decay is desired (which is consistent with current standard practice).
LARS [63], Adafactor [42], Lamb [64], Layca [8], Fromage [6], Nero [28] all involve a normalization step in which the update (which may be obtained from SGD, Adam, or other optimzers) is normalized to have Frobenius norm equal to that of the parameter : . They can be made compatible with P in Table 8 by scaling their learning rate for hidden weights like (for Table 3, the output weight learning rate should be likewise scaled). The intuitive reasoning (which can be formalized straightforwardly using Tensor Programs) is as follows.
This normalization implicitly encodes a width scaling: If one initializes a weight matrix with variance , then an matrix (e.g., a hidden weight matrix) has Frobenius norm at initialization. Thus, in the first step and, by induction, in any step , the normalized update to this weight also has Frobenius norm (for any fixed , as ). Heuristically, this means each entry of is approximately of size . But, by the derivation of Appendix J, we want and this is too large! Thus, in wide enough networks, one should see a network blowup after one update, like demonstrated in Fig. 5.
However, note that the coordinate size induced by the normalization here is closer to the right size than Adam, whose update have coordinate size . This may partially explain the apparent benefit of these optimizers. In particular, this may explain the observation that T5 [38], using Adafactor, was able to train its entire range of models from 220 million to 11 billion parameters with a fixed set of hyperparameters, while GPT-3 [7], using Adam, needed to decrease its learning rate with model size.
RAdam [25] is a variant of Adam that uses SGD with momentum in an initial stage with learning rate warmup, followed by a second stage of Adam with a particular setting of learning rate with time. Thus, one can adapt RAdam to P by individually scaling the learning rates of the initial SGD stage and the final Adam stage according to Table 3, Table 8, or Table 9.
Exactly the same as Adam in all of our tables.
All of our derivations here assume is negligible in Adam. If it is set to a non-negligible number, then it needs to be scaled, for all parameters, like if it is added before the square root, or like if it is added after the square root.
Weight decay should be scaled independently of width in SGD and AdamW, for all of our tables. However, note it’s not compatible with P Adam.
Momentum should be scaled independently of width for all of our tables.
Here we give more intuition why we need to reparametrize all hyperparameters. In practice, neural networks have multitudes of hyperparameters all interacting together. In our example of Section 2, hyperparameter optimization would be akin to minimizing the function
F_{n}(c^{1},\ldots,c^{k})\mathbin{\overset{\mathrm{def}}{=}}\EV_{x_{1},\ldots,x_{n}}f((c^{1}+\cdots+c^{k})(x_{1}+\cdots+x_{n})).where are as in Eq. 1 and are analogous to hyperparameters. For the same reasoning in Section 2, the correct parametrization is in where .
While this is straightforward, in practice, researchers often fix some hyperparameters (e.g., they tune only learning rate but neglects to scale parameter multipliers or initialization correctly). For example, if we only partially reparametrize and optimize in while fixing , then the optimal is where is the optimal for Eq. 1. Thus, as , still blows up even though we parametrized correctly. More generally, the incorrect parametrization of some hyperparameters forces other hyperparameters to increasingly compensate for it as width grows, distorting their optima, even if the latter are correctly parametrized.
In this section, we outline several useful tips and tricks that can improve the quality of hyperparameter transfer in practice.
Even though P is neatly encapsulated by Table 3, implementing it correctly can in practice be error-prone, just like how implementing autograd by hand can be error-prone even though the math behind is just chain-rule. In the case of autograd, gradient checking is a simple way of verifying implementation correctness; similarly, we propose coordinate checking to verify the correctness of P implementation: Exemplified by Fig. 5, one calculates the average coordinate size of every (pre)activation vector in the network over a few steps of training, as width is varied over a large range. An incorrect implementation will see some activation vector blow up or shrink to zero with width (like in the top row of Fig. 5). In the mup package we release with this paper, we include an easy-to-use method for coordinate checking.
We find that the optimal hyperparameters of small and large width models match more closely when we initialize output layers at 0 (i.e. with variance where instead of positive ). This is because the neural network in P is approximately a Gaussian process (GP) at initialization with variance on the order (contrast this with SP networks, which approximates a GP with variance) [53, 57, 21, 29]. Of course, when width is large, this variance vanishes, but this can be far from so in the small proxy model. This discrepancy in the initial GP can cause the training trajectory of the proxy model to be very different from the trajectory of the large target model, causing a mismatch in the optimal hyperparameters. By initializing the output layer at 0, we remove this mismatch in the initial GP. Empirically we do not find this modification to be detrimental to performance.
A similar consideration applies to the query layer in self-attention: At initialization, the attention logit looks like a Gaussian with variance because and are almost independent and zero-mean. In the limit , the logit is exactly 0, which can be a large discrepancy compared to when is small in the small proxy model we want to tune. By initializing the query projection matrix to 0, will also be 0, and hence the attention logit is always 0 at initialization regardless of width (but will generally become nonzero after a gradient step), resolving this discrepancy.
More generally, any layer or computation that goes from an “infinite” dimension (i.e. width) to a “finite” dimension (e.g. output dimension or sequence length) can exhibit this kind of discrepancy due to the initial GP. When and is fixed, attention logit calculation can be viewed in the same vein as a function , which “reduces to” .
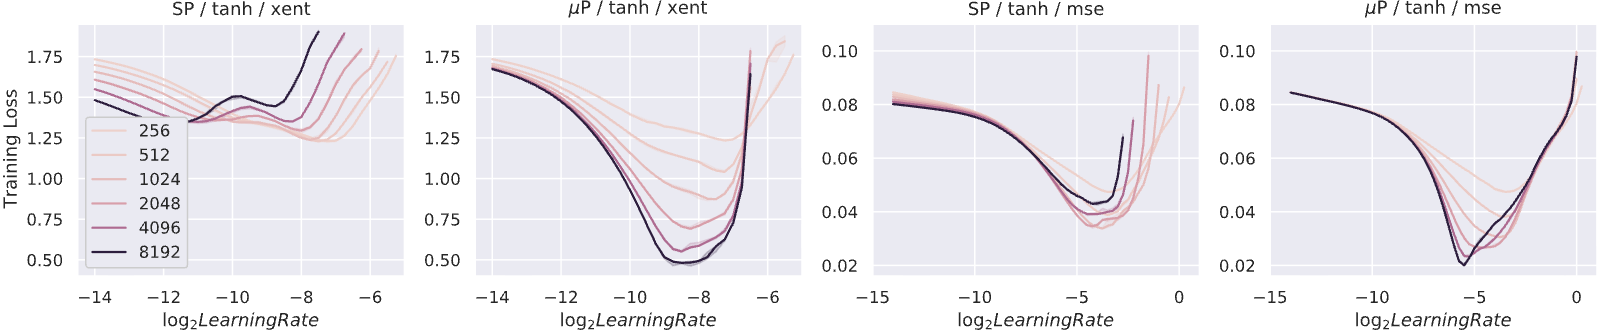
When the network is narrow, its approximation to the infinite-width behavior becomes crude, which is manifested as large fluctuations in preactivation coordinates. When using a squashing activation functions like softmax or tanh, this causes narrower networks to saturate the activation more than wider ones, which results in a systematic bias toward small gradients and therefore distorting the hyperparameter landscape. This can be seen in Fig. 9, where we use tanh as the network activation function.
Therefore, we recommend replacing non-essential squashing activation functions with ReLU, whose derivative depends only on the sign of the pre-activation. A similar reasoning can be applied to superlinear activation functions, where the distribution of activation values can have heavy tails, leading to slow convergence to the infinite-width limit. However, such activations are rarely used in practice.
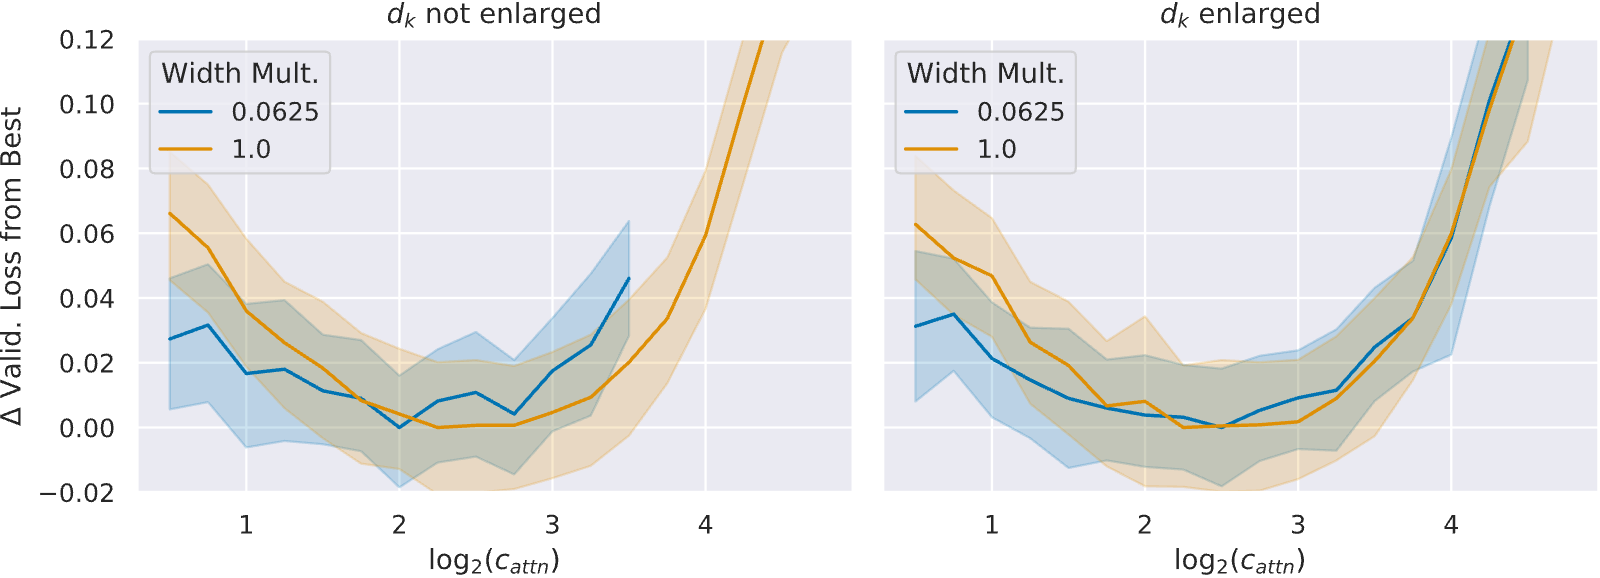
We find that small can lead to a highly noisy HP landscape, as shown in Fig. 10. This can significiantly decrease the quality of random HP search on the small proxy model. To solve this, we find it useful to decouple from (so that ) and maintain a relatively large even as is shrunk in the proxy model. For example, pegging is generally effective. Training or inference speed are not usually affected much by the larger because of CUDA optimizations. By Section E.2, this decoupling of from is theoretically justified, and as shown in Fig. 10, it significantly denoises the HP landscape.
We find non-Gaussian (e.g. uniform) initialization can sometimes cause wider models to perform worse than narrower models, whereas we do not find this behavior for Gaussian initialization. This is consistent with theory, since in the large width limit, one should expect non-Gaussian initialization to behave like Gaussian initializations anyway (essentially due to Central Limit Theorem, or more precisely, universality), but the non-Gaussianity slows down the convergence to this limit.
For Transformers, we empirically find that we can better transfer initialization standard deviation from a narrower model (to a wide model) if we use a larger sequence length. It is not clear why this is the case. We leave an explanation to future work.
The techniques in this paper allow the transfer across width of (learning rate, initialization, multipliers) simultaneously for all parameter tensors. Thus, to get the best results, one should ideally tune all such hyperparameters. In practice, we find that just tuning the global learning rate and initialization, along with input, output, and attention multipliers, yield good results.
Below, we discuss the reasoning behind each kind, which are supported by our empirical evidence collected in Fig. 4 on Transformers as well as those in Section G.1 on ResNet.
In Table 2, we summarize which HPs can be transferred across training scale. The transfer across width, as explained in Section 2, is theoretically justified, while we present the transfer across the other dimensions as empirical results.
These cover most of the well-known and important HPs when the need for regularization is not paramount, e.g., during large scale language model pretraining. Parameter Multipliers are not well-known HPs, yet we include them here as they serve a bridge between SP and P and can impact model performance in practice. Concretely, any SP and P neural networks of the same width can have their Parameter Multipliers tuned so that their training dynamics become identical.
Not all HPs transfer well even if we use P. In particular, those whose primary function is to regularize training to mitigate “overfitting" tend not to transfer well. Intuitively, regularization needs to be applied more heavily in larger models and when data is scarce, but P does not know the data size so cannot adjust the regularization accordingly.
To the best of our knowledge, there is no strict separation between HPs that regularize and those that don’t. However, conventional wisdom tells us that there exists a spectrum of how much regularizing effect a HP has. For example, dropout probability and weight decay are among those whose primary function is to regularize, whereas batch size and learning rate might regularize training in some cases but affect the dynamics more so in other ways. Our empirical exploration tells us that the former do not transfer well, while the latter do. Our subsequent discussion will focus on the latter; we leave to future works the expansion to the former.
We have left out a category of HPs that defines the training scale, or in practical terms, training cost. This includes 1) those that define how many operations a model’s forward/backward pass takes, such as the model’s width, depth, and in the case of language modeling, sequence length; and 2) those that define how many such passes are performed, such as batch size and number of training steps.
As recent works have shown [39, 7, 19], improvements along any of these scale dimensions lead to apparently sustainable gain in performance; as a result, we are primarily interested in transferring other HPs across these dimensions that define scale, rather than finding the optimal scale. This category of HPs is particularly crucial as one can speedup training by downsizing in one or multiple such dimensions. Indeed, it’s very common for practitioners to implicitly transfer HPs across the number of training samples by tuning on only a subset of the full training data.
Our insights from the infinite-width limit inspired us to explore HP tranfer across width, which does not work under SP as we have shown earlier. Building upon our success with width, which is well explained theoretically, we hope to push the limit of compute-saving by investigating the other dimensions empirically. To the best of our knowledge, the transferability of optimal HPs across depth, batch size, sequence length, and training time has not been rigorously investigated previously, with the main exception of the literature on (learning rate, batch size) scaling [44, 41] where our transferability result of learning rate across batch size recapitulates [30]. See Section 10.3 on how our results relate to prior works. We will primarily focus on the Transformer architecture in the main text with evidence for ResNet in Section G.1.
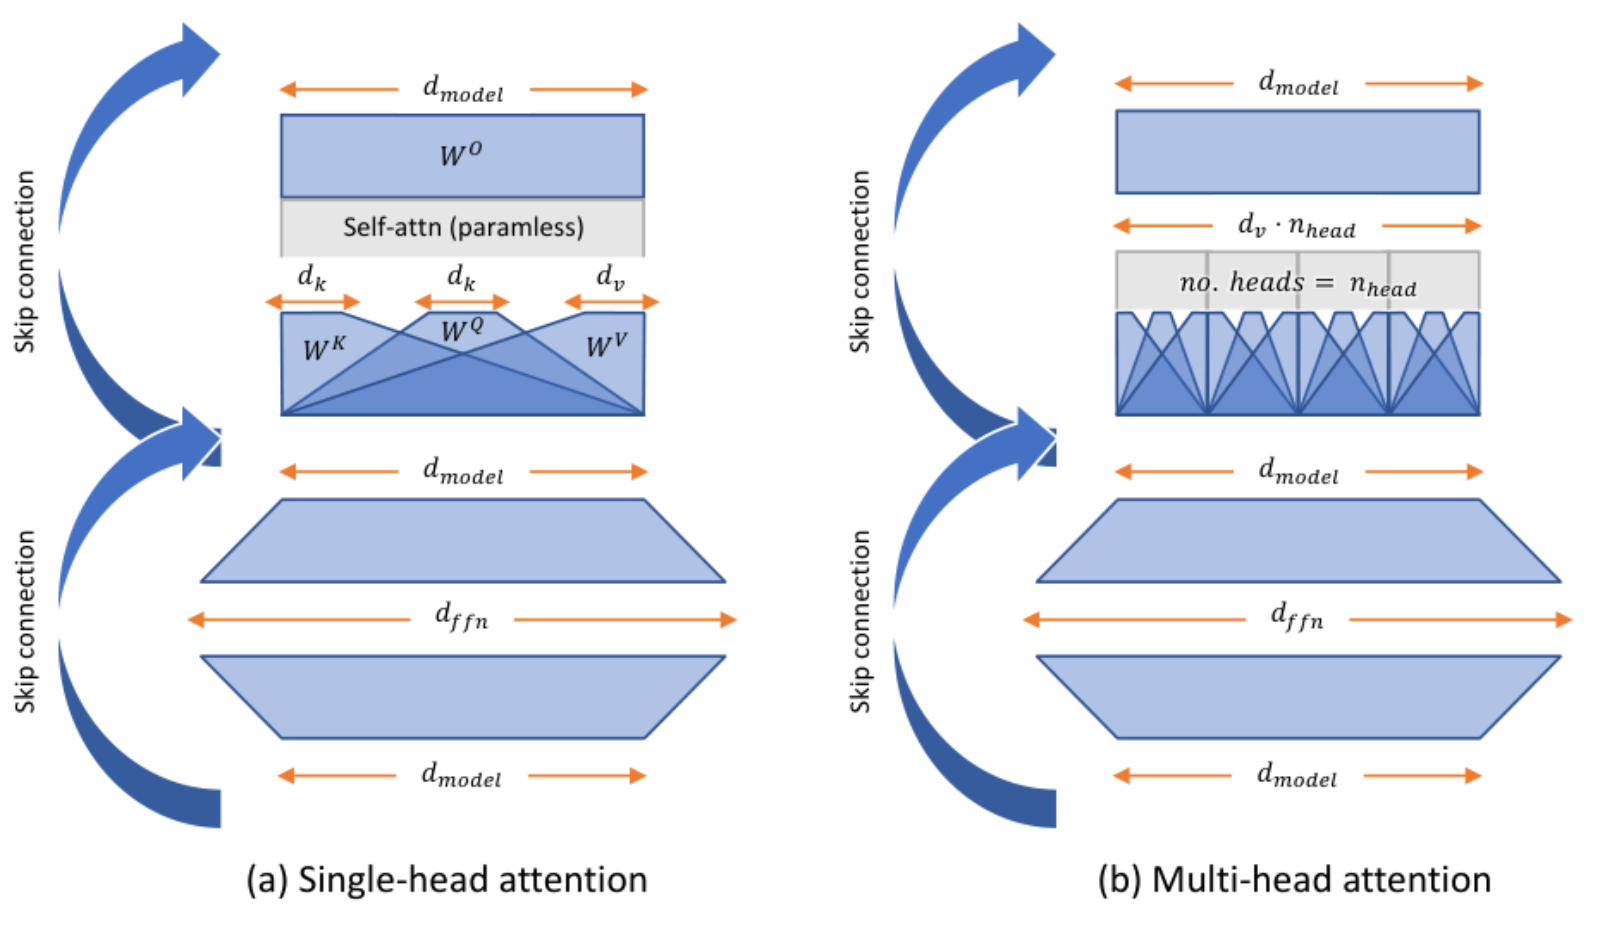
Our theory allows more general notions of width. This is especially relevant in Transformers, where (see Fig. 11) can all be construed as measures of width. We briefly discuss these here, with more theoretical justification in Section J.2.1 and empirical validation below.
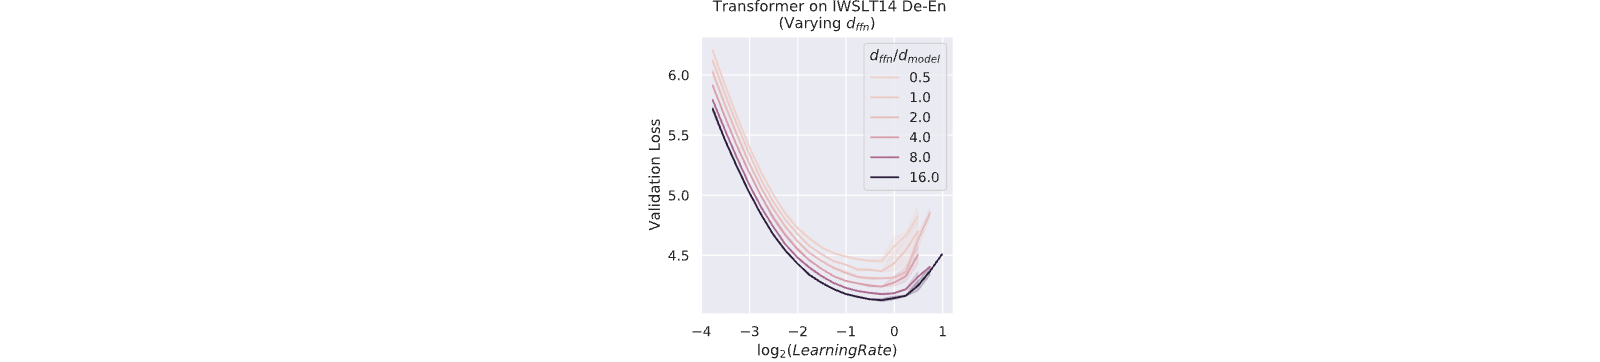
So far we have assumed that every hidden layer is widened by the same factor. But in fact we can widen different hidden layers differently. This is useful, for example, in a Transformer where we may want to use a smaller during tuning. If we are using Adam, as long as the width of every layer still tends to infinity, we still obtain approximately the same limit, so the Transfer remains theoretically justified.
See Fig. 12 for an empirical validation on IWSLT-14 using a Transformer.
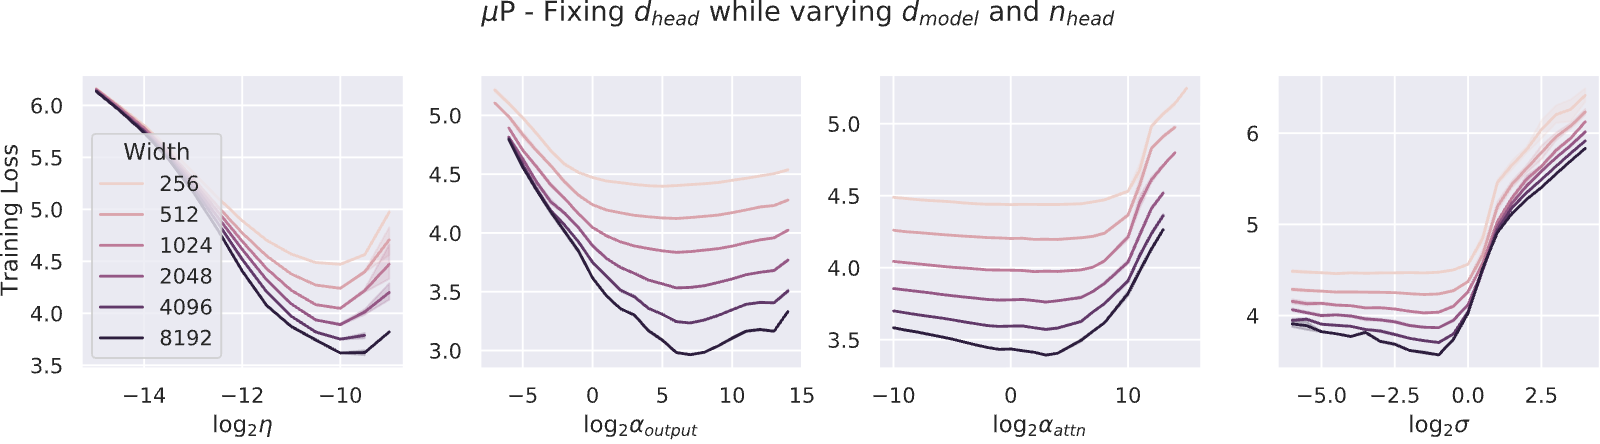
In attention-based models, one typically splits hidden size into multiple attention heads following . So far we have assumed and to be width, but it’s possible and potentially advantageous to fix and treat as the width, or increasing both simultaneously. This allows our technique to handle many popular models, including GPT-3 [7], which scale up by fixing and increasing . See Fig. 13 for an empirical validation on Wikitext-2.
A specific useful instance of varying width ratio is decoupling the key and value dimensions and and scaling differently from (typically larger than) . This works as long as we use scaled-attention as in Definition 4.1 (instead of as is done commonly). When tuning on the small proxy model, if is too small, the HP landscape can be quite noisy. Keeping relatively large while shrinking all other dimensions solves this problem, while still obtaining significant speedup.
IWSLT14 De-En is a well-known machine translation benchmark. We use a Transformer implemented in fairseq [33] with a default and (amounting to 40M parameters), which we denote as the 1x model. For transfer, we tune on a proxy model with the same but with and other dimensions 4 times smaller; we will call this the 0.25x model (but it has 4M parameters). All models are trained with Adam for 100 epochs and validated at the end of every epoch. We tune via random search the learning rate , the output layer parameter multiplier , and the attention key-projection weight multiplier following the grid
- •
:
- •
:
- •
:
We scale up to WMT14 En-De using the large Transformer from [50], with a and . We use the exact same setup and reproduce their result as our baseline. Then, we build the proxy model by shrinking the target model’s from the original to , from to and from to . This reduces the total parameter count from 211M to 15M. We then perform the HP search on the proxy model and take the best according to validation loss, before testing on the target model. We tune via random search the learning rate , the output layer parameter multiplier , and the attention key-projection weight multiplier following the grid
- •
:
- •
:
- •
:
Our proxy model has 10 Transformer layers with . We also reduce the number of attention heads to 8 with a of 32. We call it BERT Prototype since we can increase its width and depth according to our definitions to recover both BERT Base and BERT Large, which enables us to sweep HPs once and use for both models. Overall, BERT Prototype has 13M trainable parameters, a fraction of the 110M in BERT Base and the 350M in BERT Large.
We tune the following HPs for pretraining: Adam learning rate , embedding learning rate , output weight multiplier , attention logits multiplier , layernorm gain multiplier , and bias multiplier .
We sample 256 combinations from the follow grid:
- •
:
- •
:
- •
:
- •
:
- •
:
- •
:
The ranges are chosen to include the implicit choices of these HPs in SP BERT Large.
We hand-pick the finetuning HPs after training the full-sized model. As regularization is an essential ingredient in successful finetuning, we do not transfer such HPs (at least via the suite of techniques presented in this work) (see Table 1). We focus on MNLI [52] and QQP, which are two representative tasks from GLUE [51]. Following [27], we used Adam [20] with a learning rate of and a batch size of 64. The maximum number of epochs was set to . A linear learning rate decay schedule with warm-up of was used. All the texts were tokenized using wordpieces and were chopped to spans no longer than tokens.
As the GPT-3 codebase has evolved since the publication of [7], we re-trained the 6.7B model from scratch to remove changes in our codebase as a possible confounder. The main differences to [7] are 1) a modified learning rate decay schedule, where the learning rate is decayed to zero at the end of training rather than being decayed to 0.1 of the initial value, and 2) use of relative attention in place of absolute attention. Unfortunately, after all experiments were finished, we found this re-run baseline used absolute attention instead of relative attention, while the Transfer model still used relative attention.
In order to find a good set of hyperparameters for the Transfer version of the 6.7B model, we performed a hyperparameter search over a reduced version of the model (i.e., the proxy model), where the width is set to 256 hidden units. This proxy model inherits changes from the evolved GPT-3 codebase: it uses relative [10] (instead of absolute) position encoding. Early on, we noted that on the proxy model, linear learning rate decay outperformed the default cosine schedule, so all subsequent experiments for the proxy models use a linear decay schedule. By Fig. 4, Transferring this linear decay schedule to the full model should maintain such a performance advantage over the cosine schedule.
The hyperparameter search space consists of the following hyperparameters:
- •
learning rate: Sampled from
- •
initialization scale: All the parameters are multiplied - sampled from
- •
attention temperature: Reciprocal of the multiplier applied to the input to attention softmax. Sampled from .
- •
output temperature: Reciprocal of the multiplier applied to the input to softmax that produces the distribution over output tokens. Sampled from .
- •
embedding multiplier: Scalar by which we multiply the output of the embedding layer. Sampled from .
- •
relative position embedding multiplier: Scalar by which we multiply vectors representing relative position. Sampled from .
In order to make the search more efficient we reduced the total number of training tokens. We hypothesized that tuning hyperparameters on a reduced total number of tokens does not significantly affect optimal hyperparameters. To verify, we trained two different horizons and compared the results. While the target model was to be trained on 300 billion tokens, we tuned the proxy model on only subsets consisting of 4 billion and 16 billion tokens. This impacts both the total training time and the length of the linear learning rate decay schedule. Other than hyperparameters explicitly listed above and the training horizon, the rest was the same as what we intended to use for the full width 6.7B training run.
We performed 467 training runs of the proxy model, out of which 350 were for 4 billion tokens (286 completed without diverging) and 117 for 16b tokens (80 completed without diverging). See Fig. 14 for summary of the results.
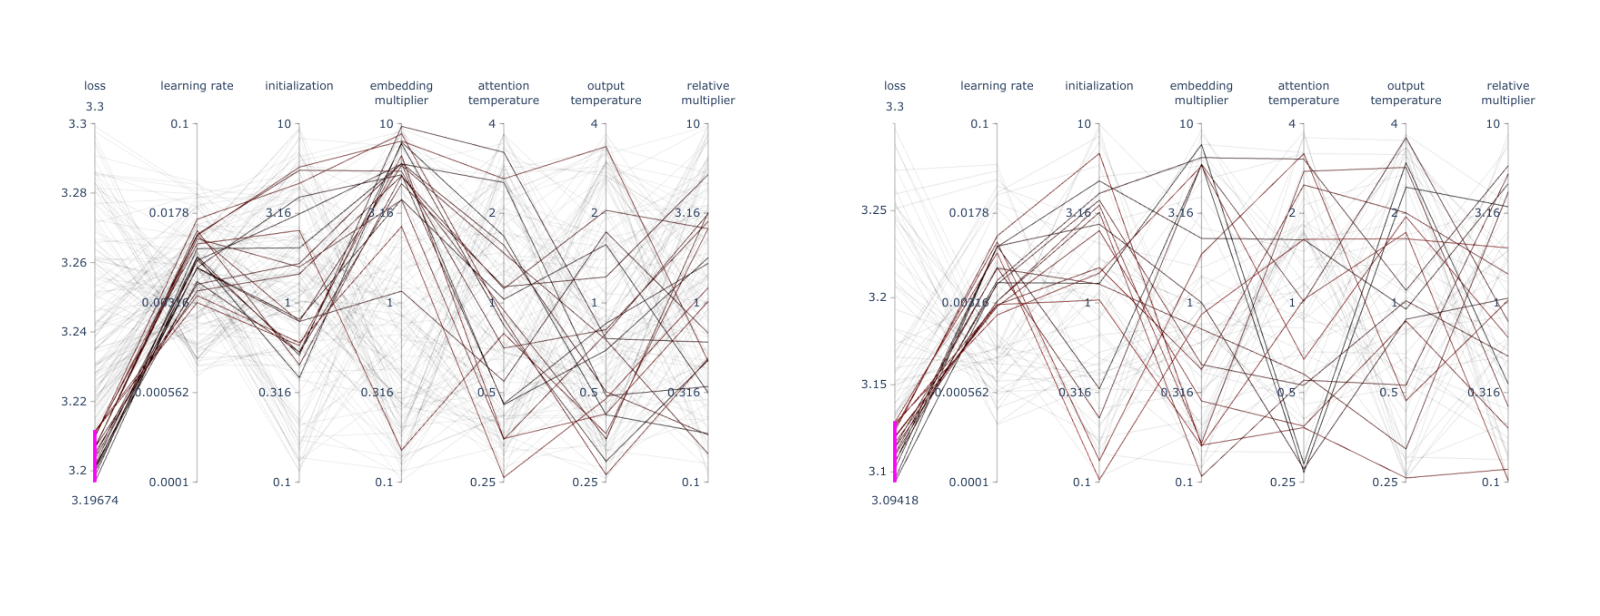
As suspected, we observed that the results are well-aligned for both 4 and 16 billion tokens versions. We observe learning rate and initialization scale impact the results the most. Based on the results we chose 0.006 for the former and 2.5 for the latter. Since most other hyperparameters appear to have negligible effect on performance, they were kept at their default values of 1, the only exception being the embedding scale, where higher values seem to perform better and it was therefore set to 10.
We encountered frequent divergences in our initial attempt to train the Transfer model. We traced the issue back to underflow of FP16 tensors in the backwards pass and therefore switched to training the model in FP32. This allowed us to finish the training run without divergences. We hypothesize that the divergence issue is related to Transfer picking more aggressive hyperparameters, for example a higher learning rate on linear weight tensors compared to the original model. In order to exclude code differences as a possible confounder, we re-trained GPT-3 6.7B from scratch using the original hyperparameters. The only difference compared to the version published in [7] is that the learning rate was decayed fully, whereas the learning rate of the model from [7] was only decayed to 10% of its starting value. The retrained model performs slightly worse than the original published in [7]. We suspect that this is because it made less progress during the last phase of training where the learning rate is close to zero. The training curves of the Transfer model and the re-run of the original 6.7B can be seen in Fig. 15. Detailed evaluation results can be found in Table 10 and Table 11.
in FLOPs can be approximated as
where
- •
Million is number of parameters of the proxy model
- •
Billion is number of parameters of the target model
- •
Billion is the number of training tokens for the short horizon HP search, and is the corresponding number of random HP search trials.
- •
Billion is the number of training tokens for the longer horizon HP search, and is the corresponding number of random HP search trials.
- •
Billion is the number of training tokens for the 6.7B target model.
Here we are using the fact that the training FLOPs of a Transformer per token is roughly proportional to its number of parameters.
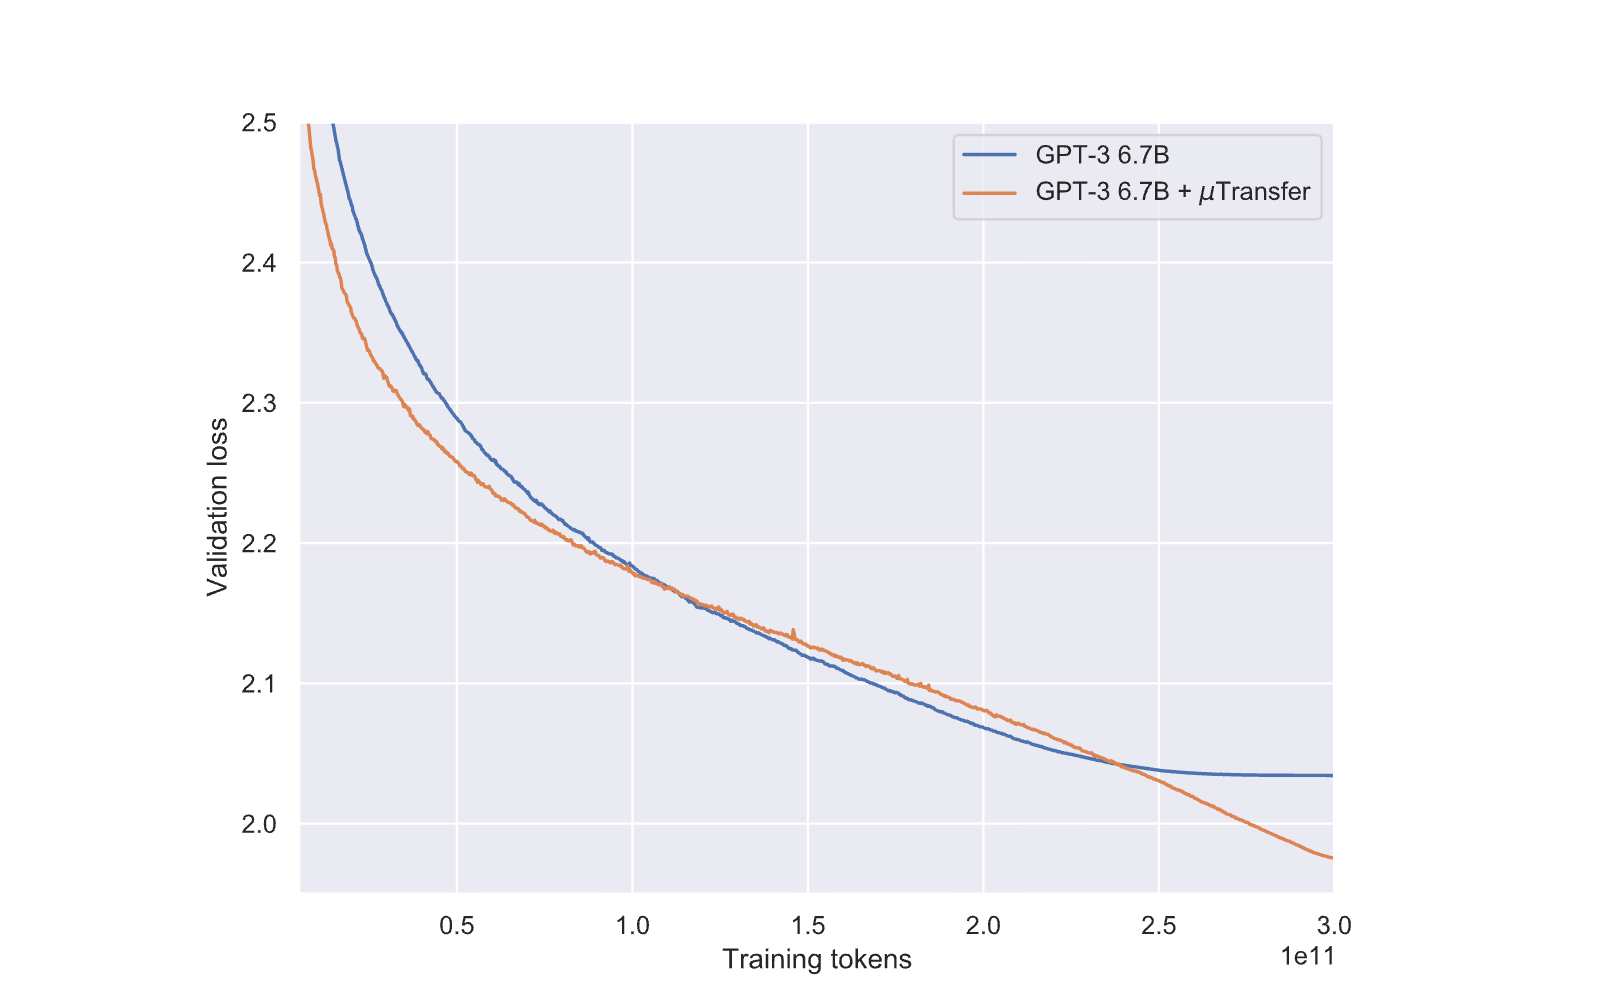
| Zero-shot | One-shot | Few-shot | |||||||||
| Task | Split | Metric | P | [7] | re-run | P | [7] | re-run | P | [7] | re-run |
| Validation dataset | valid | ce | 1.98 | ||||||||
| PTB | test | ppl | 11.3921 | ||||||||
| Wikitext 103 | test | ppl | 8.5612 | ||||||||
| LM1B | test | ppl | 20.5135 | ||||||||
| HellaSwag | dev | acc | 71.9877 | 71.0516 | 72.4358 | ||||||
| LAMBADA | test | acc | 73.4912 | 69.8816 | 79.1000 | ||||||
| StoryCloze | test | acc | 79.4228 | 80.5986 | 84.2330 | ||||||
| NaturalQS | test | acc | 9.8615 | 14.6814 | 20.2216 | ||||||
| TriviaQA | dev | acc | 47.0036 | 50.4441 | 55.5361 | ||||||
| WebQS | test | acc | 11.3189 | 20.2264 | 32.9724 | ||||||
| RoEn 16 | test | BLEU-sb | 26.9000 | 36.5000 | 38.2000 | ||||||
| EnRo 16 | test | BLEU-sb | 18.1000 | 21.0000 | 22.0000 | ||||||
| FrEn 14 | test | BLEU-sb | 29.8000 | 31.7000 | 38.0000 | ||||||
| EnFr 14 | test | BLEU-sb | 29.6000 | 28.8000 | 33.3000 | ||||||
| DeEn 16 | test | BLEU-sb | 31.7000 | 33.3000 | 38.9000 | ||||||
| EnDe 16 | test | BLEU-sb | 23.1000 | 24.6000 | 27.6000 | ||||||
| Winograd | test | acc | 86.8132 | 84.6154 | 86.4469 | ||||||
| Winogrande | dev | acc | 66.7719 | 67.5612 | 71.0339 | ||||||
| PIQA | dev | acc | 79.0533 | 77.3123 | 79.2165 | ||||||
| ARC (Challenge) | test | acc | 42.4825 | 43.9685 | 43.7937 | ||||||
| ARC (Easy) | test | acc | 64.2857 | 65.3439 | 67.3280 | ||||||
| OpenBookQA | test | acc | 54.4000 | 56.4000 | 58.4000 | ||||||
| Quac | dev | f1 | 41.7609 | 43.1352 | 44.0041 | ||||||
| RACE-h | test | acc | 45.0257 | 44.8828 | 45.1973 | ||||||
| RACE-m | test | acc | 58.3565 | 57.9387 | 58.5655 | ||||||
| SQuADv2 | dev | f1 | 59.9188 | 64.9009 | 68.8726 | ||||||
| CoQA | dev | f1 | 78.5000 | 80.9000 | 81.3000 | ||||||
| DROP | dev | f1 | 17.3645 | 27.3000 | 33.9242 | ||||||
| BoolQ | dev | acc | 69.3578 | 74.0673 | 73.9144 | ||||||
| CB | dev | acc | 37.5000 | 60.7143 | 66.0714 | ||||||
| Copa | dev | acc | 82.0000 | 82.0000 | 88.0000 | ||||||
| RTE | dev | acc | 55.2347 | 61.0108 | 59.9278 | ||||||
| WiC | dev | acc | 0.0000 | 0.0000 | 0.0000 | 50.3135 | 53.1000 | ||||
| ANLI R1 | test | acc | 33.7000 | 32.4000 | 33.1000 | ||||||
| ANLI R2 | test | acc | 33.8000 | 34.8000 | 35.0000 | ||||||
| ANLI R3 | test | acc | 34.8000 | 34.7500 | 36.9167 | ||||||
Note: Zero-shot, One-Shot and Few-Shot refer to the number of additional query and answer pairs passed in the context when performing the sampling-based evaluations, not the ”shots” involved in hyperparameter transfer.
View original table
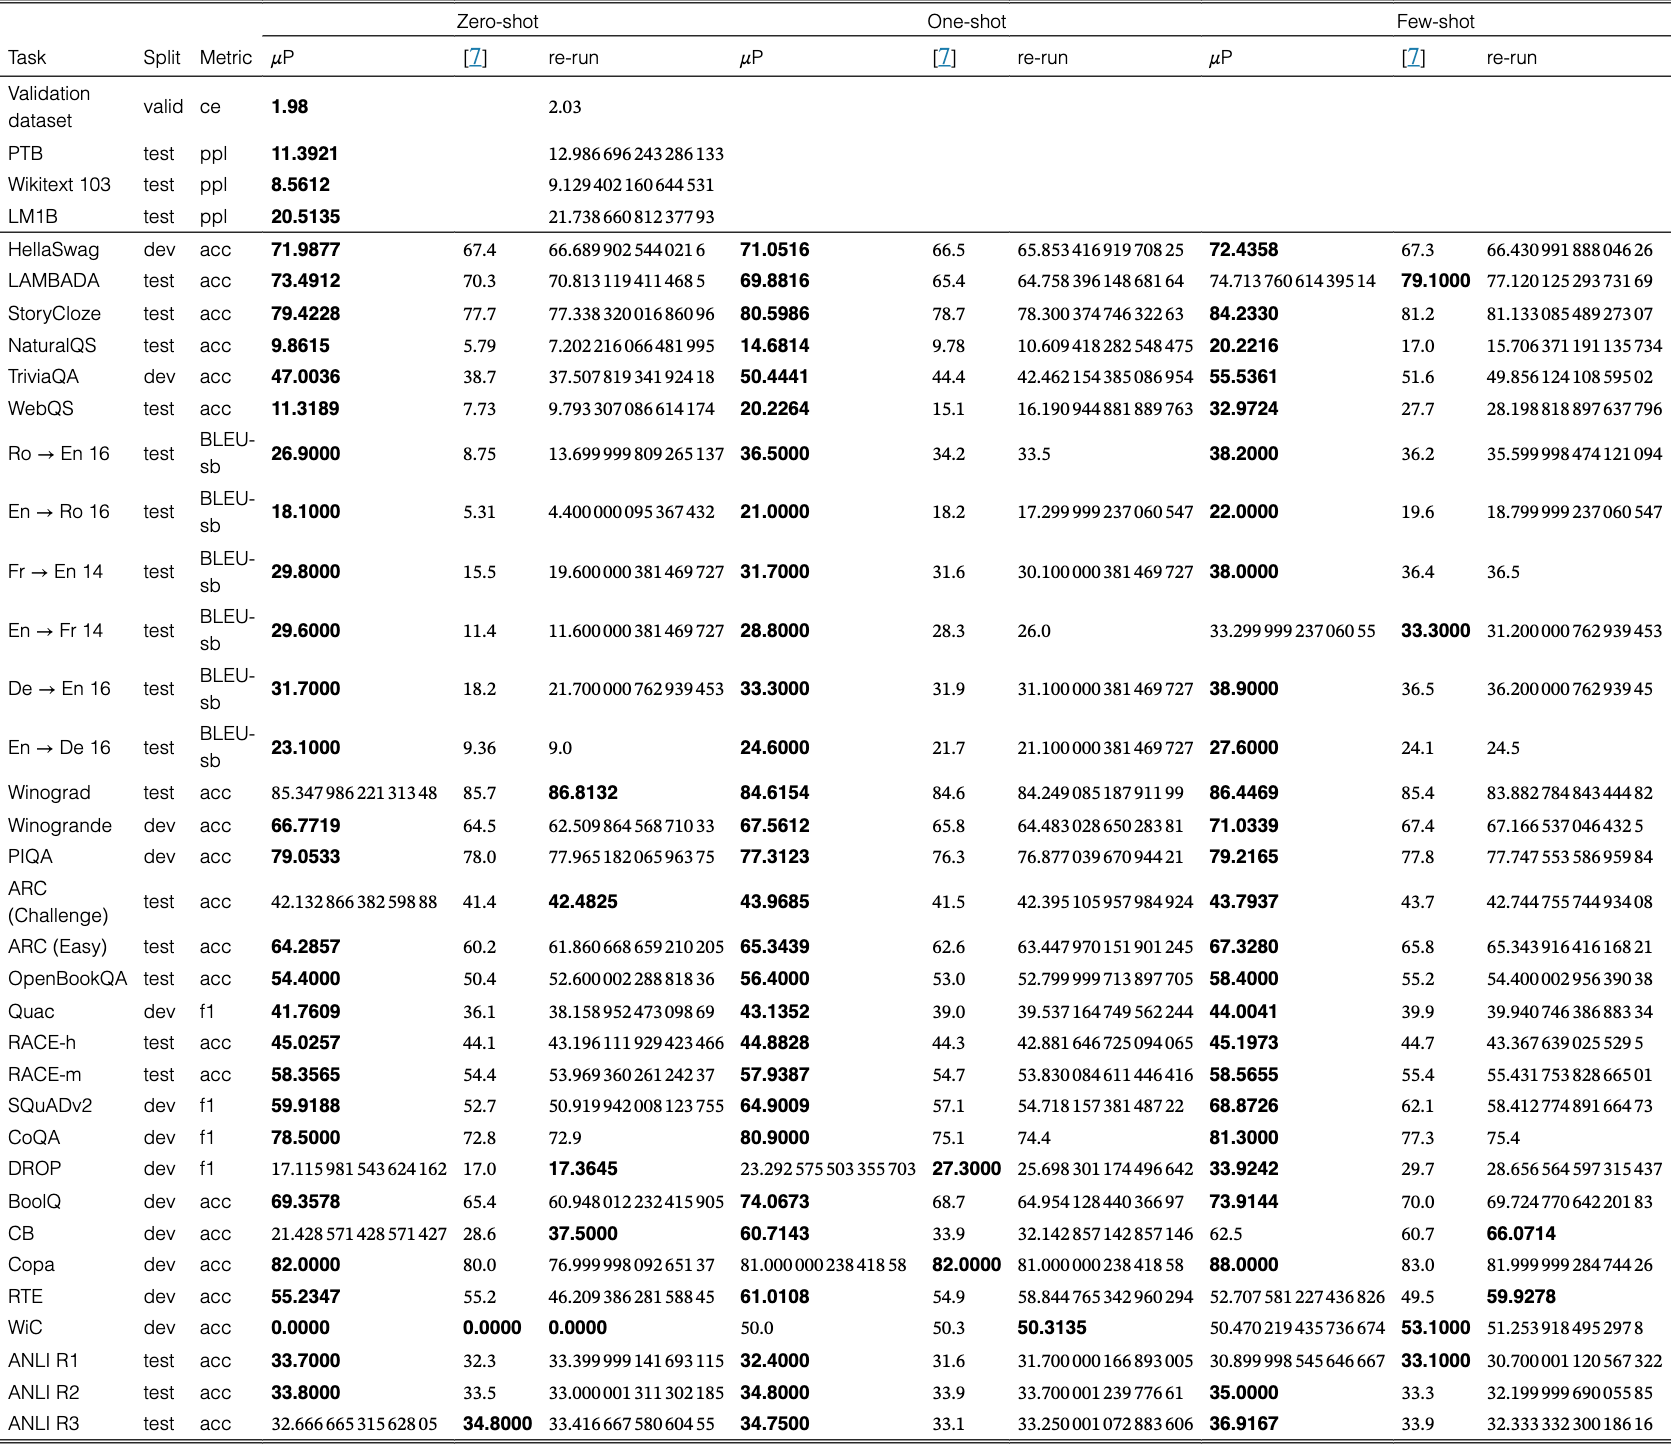
| Zero-shot | One-shot | Few-shot | ||||||
| Task | Split | Metric | 6.7B+P | 13B[7] | 6.7B+P | 13B[7] | 6.7B+P | 13B[7] |
| HellaSwag | dev | acc | 71.9877 | 71.0516 | 72.4358 | |||
| LAMBADA | test | acc | 73.4912 | 69.8816 | 81.3000 | |||
| StoryCloze | test | acc | 79.5000 | 80.5986 | 84.2330 | |||
| NaturalQS | test | acc | 9.8615 | 14.6814 | 21.0000 | |||
| TriviaQA | dev | acc | 47.0036 | 51.3000 | 57.5000 | |||
| WebQS | test | acc | 11.3189 | 20.2264 | 33.5000 | |||
| RoEn 16 | test | BLEU-sb | 26.9000 | 36.7000 | 38.4000 | |||
| EnRo 16 | test | BLEU-sb | 18.1000 | 21.0000 | 22.0000 | |||
| FrEn 14 | test | BLEU-sb | 29.8000 | 31.7000 | 38.3000 | |||
| EnFr 14 | test | BLEU-sb | 29.6000 | 30.1000 | 35.5000 | |||
| DeEn 16 | test | BLEU-sb | 31.7000 | 34.5000 | 39.1000 | |||
| EnDe 16 | test | BLEU-sb | 23.1000 | 24.6000 | 27.7000 | |||
| Winograd | test | acc | 87.9000 | 86.1000 | 86.4469 | |||
| Winogrande | dev | acc | 67.9000 | 67.5612 | 71.0339 | |||
| PIQA | dev | acc | 79.0533 | 77.8000 | 79.9000 | |||
| ARC (Challenge) | test | acc | 43.7000 | 43.9685 | 44.8000 | |||
| ARC (Easy) | test | acc | 64.2857 | 66.8000 | 69.1000 | |||
| OpenBookQA | test | acc | 55.6000 | 56.4000 | 60.8000 | |||
| Quac | dev | f1 | 41.7609 | 43.1352 | 44.0041 | |||
| RACE-h | test | acc | 45.0257 | 44.8828 | 45.1973 | |||
| RACE-m | test | acc | 58.3565 | 57.9387 | 58.5655 | |||
| SQuADv2 | dev | f1 | 59.9188 | 64.9009 | 68.8726 | |||
| CoQA | dev | f1 | 78.5000 | 80.9000 | 81.3000 | |||
| DROP | dev | f1 | 24.0000 | 29.2000 | 33.9242 | |||
| BoolQ | dev | acc | 69.3578 | 74.0673 | 73.9144 | |||
| CB | dev | acc | 21.4286 | 60.7143 | 66.1000 | |||
| Copa | dev | acc | 84.0000 | 86.0000 | 88.0000 | |||
| RTE | dev | acc | 62.8000 | 61.0108 | 60.6000 | |||
| WiC | dev | acc | 0.0000 | 0.0000 | 50.0000 | 50.0000 | 51.1000 | |
| ANLI R1 | test | acc | 33.7000 | 32.7000 | 33.3000 | |||
| ANLI R2 | test | acc | 33.8000 | 34.8000 | 35.0000 | |||
| ANLI R3 | test | acc | 34.4000 | 34.7500 | 36.9167 | |||
View original table
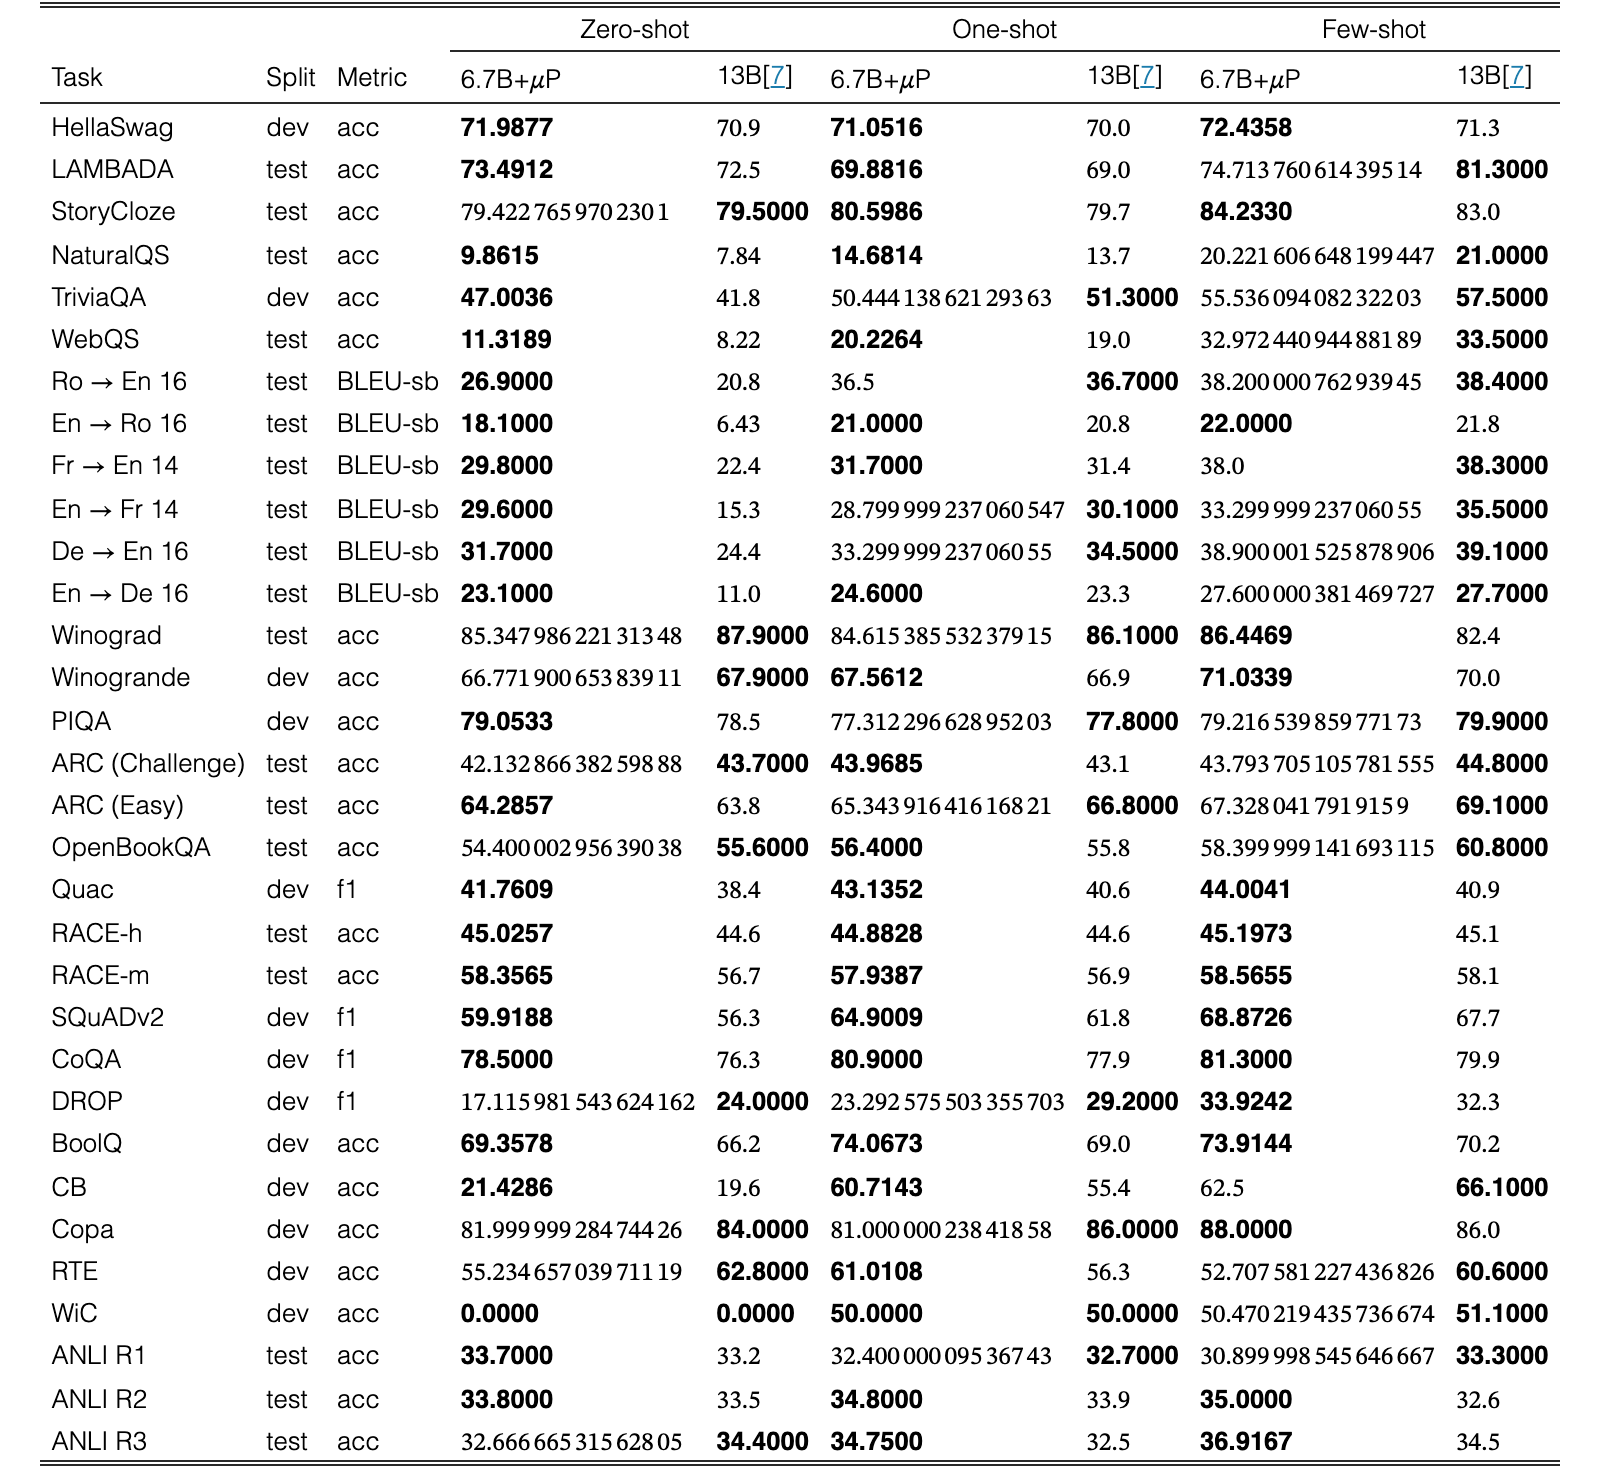
For this case we use Davidnet [2], a ResNet variant that trains quickly on CIFAR-10, so as to efficiently investigate its HP landscape. We train with SGD on CIFAR-10 for 10 epochs; all results are averaged over 15 random seeds. We use a width multiplier to identify models of different width, and a multiplier of 1 corresponds to the original model in [2]. We look at validation accuracy here as the model barely overfits, and our observations will hold for the training accuracy as well. We first conduct a learning rate sweep for models of different widths using SP; the result is shown in Fig. 16, on the left.
Note that the best model with a width multiplier of 8 under-performs that with a multiplier of 4. We run the same sweep with P, along with a sweep of the output multiplier (); the result is shown in Fig. 16, on the right. We notice that wider models always perform better under P and that the optimal learning rate and are stable across width.
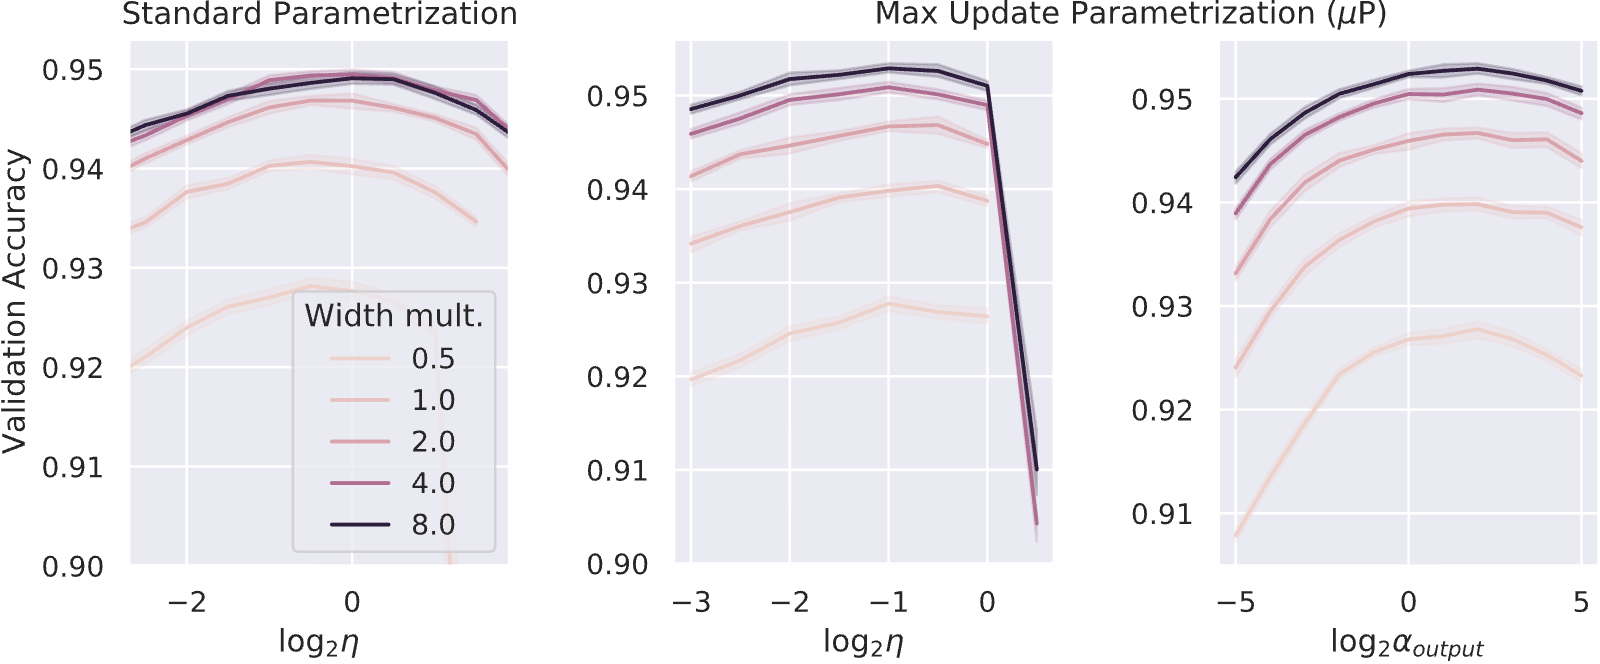
Next, we perform a grid search for learning rate () and on the 0.5x model for both SP and P. Then, we take the best combination and test on the 8x model, simulating how a practitioner might use Transfer. The result is shown in Table 12, where P outperforms SP by .
| Transfer Setup | Best | Best | Valid. Acc. (0.5x) | Valid. Acc. (8x) |
|---|---|---|---|---|
| SP | 0.707 | 4 | 92.82% | 94.86% |
| P | 0.5 | 4 | 92.78% | 95.29% |
View original table

For this case we use Wide-Resnet, or WRN [65], a ResNet variant with more channels per layer, to further showcase Transfer across width, i.e., number of channels. We train with SGD on ImageNet for 50 epochs following standard data augmentation procedures. We use a width multiplier to identify models of different width, and a multiplier of 1 corresponds to the original WRN-50-2-bottleneck in [65].
We start with a proxy model with a width multiplier of 0.125 and tune several HPs using the following grid:
- •
:
- •
:
- •
weight decay co-efficient :
- •
SGD momentum :
The grid is centered around the default HPs used by [1] for ResNet-50; while not expected to be competitive for WRN, they represent a reasonable starting point for our experiment.
We randomly sample 64 HP combinations from the grid and train for 50 epochs, before selecting the one with the highest top-1 validation accuracy. Then, we scale up the model following both P and SP and run with the same HPs we just selected. The result is shown in Table 13, where P outperforms SP by in terms of top-1 validation accuracy.
| Transfer Setup | Best | Best | Best | Best | Valid. Acc. (0.125x) | Valid. Acc. (1x) |
|---|---|---|---|---|---|---|
| SP | 32.768 | .625 | .000015 | .4375 | 58.12% | 76.75% |
| P | 32.768 | .625 | .000015 | .4375 | 58.12% | 77.16% |
View original table

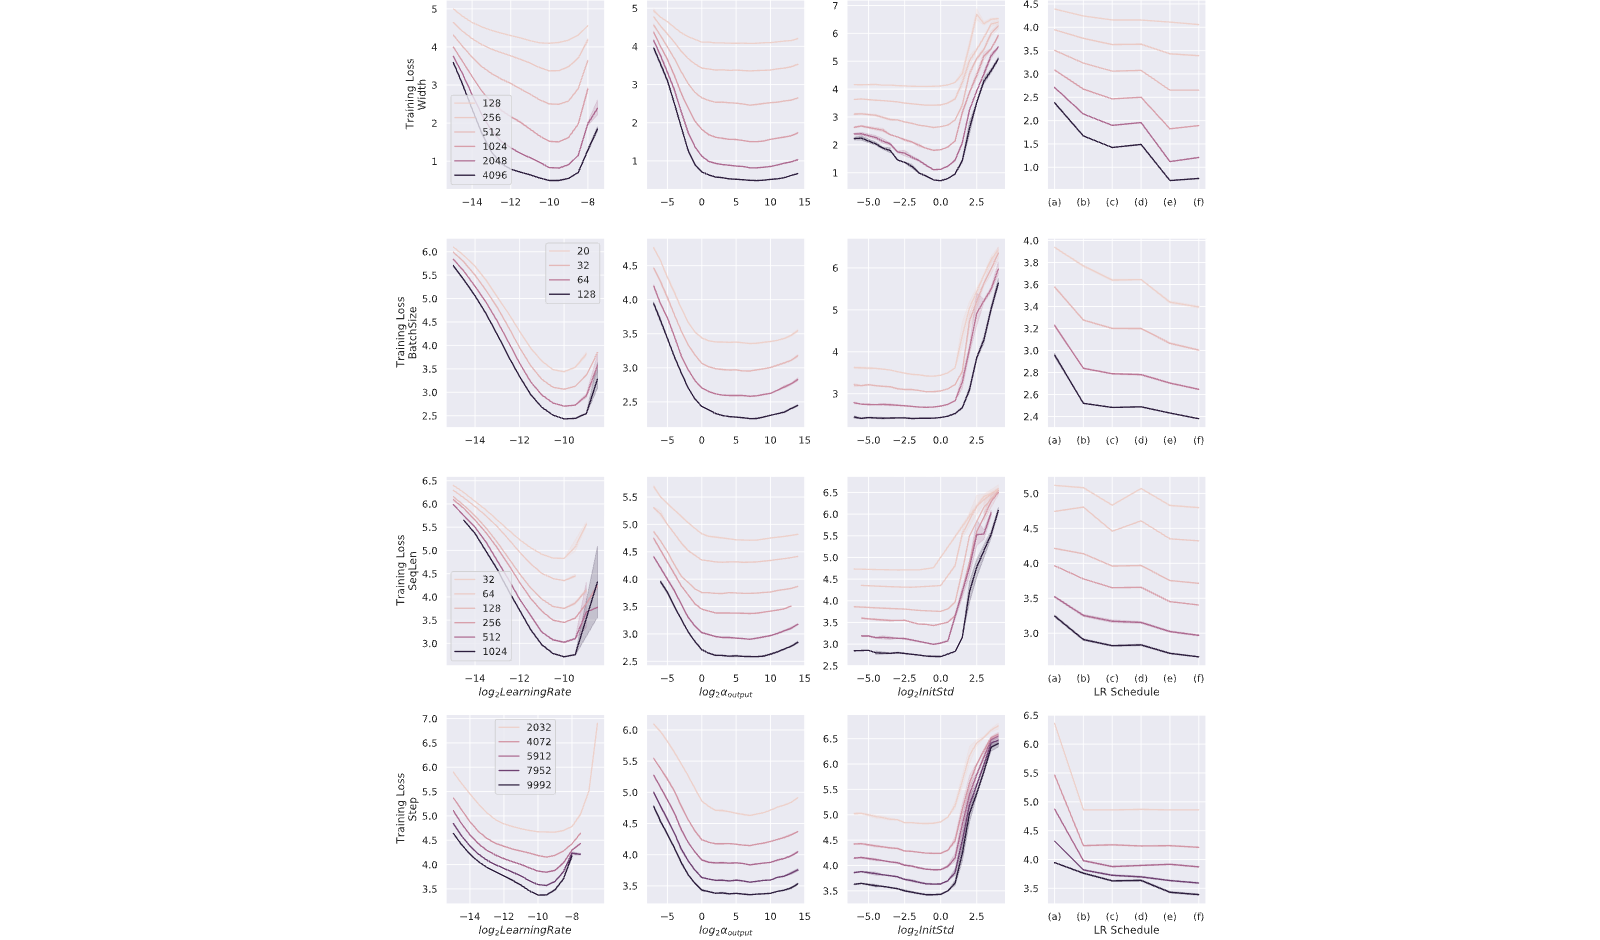
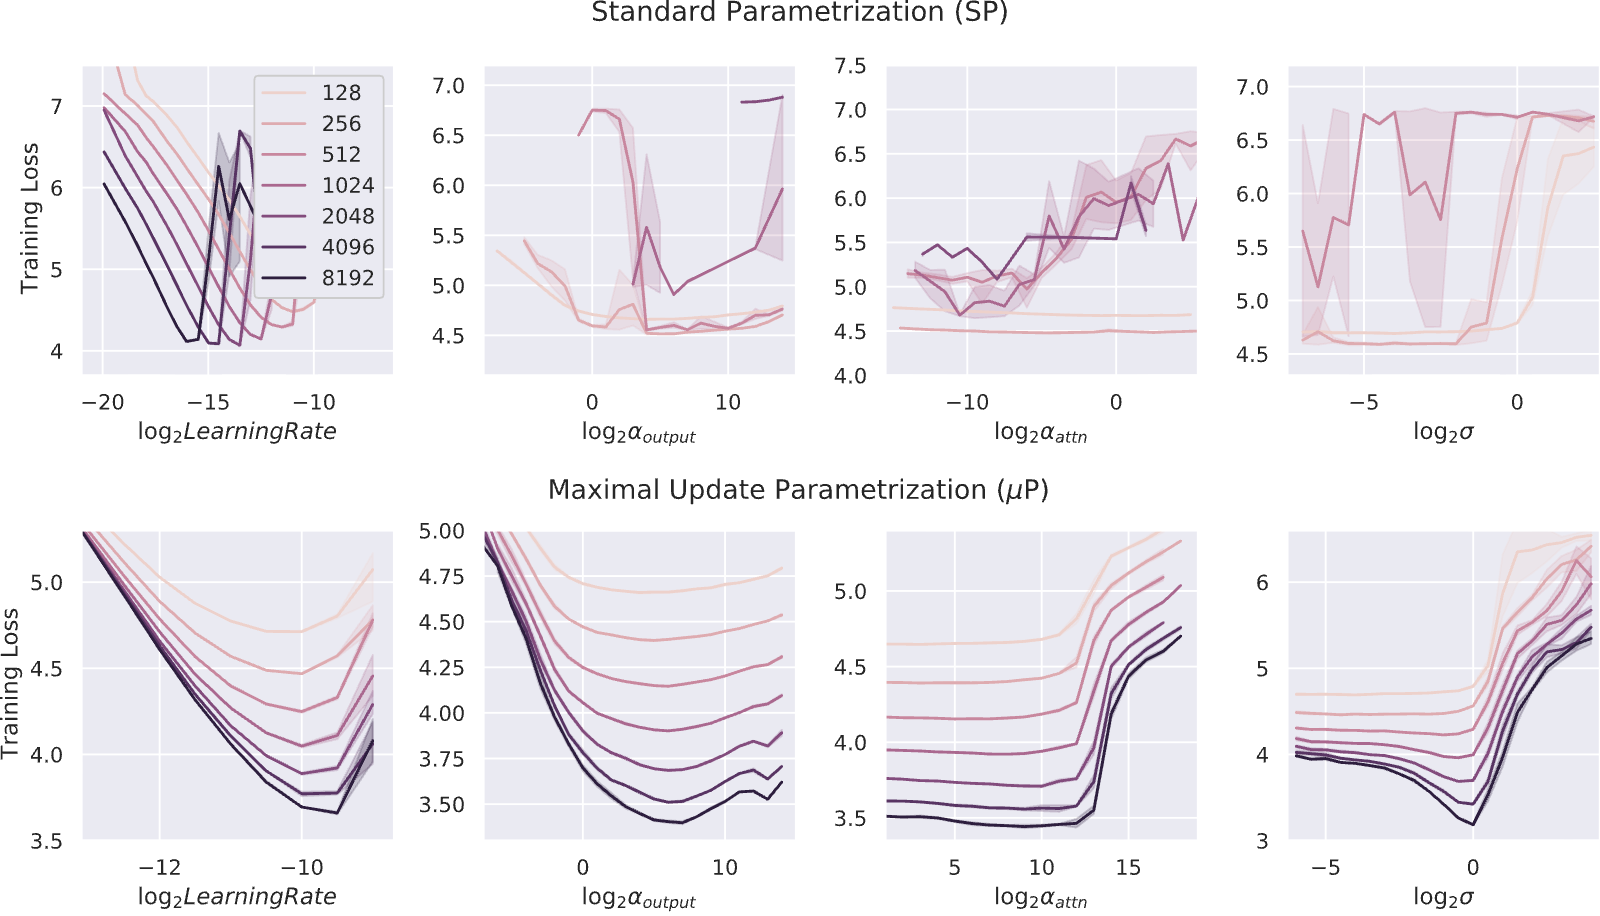
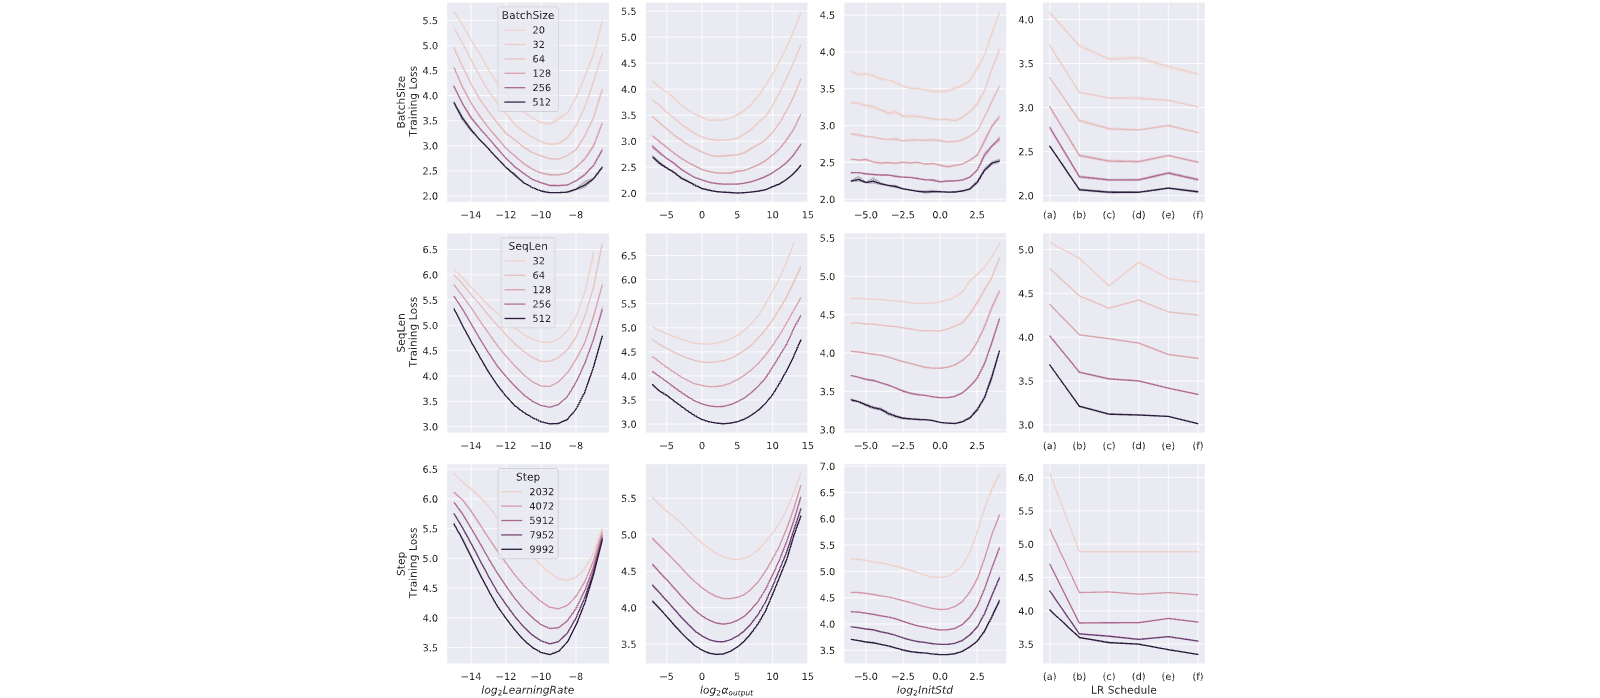
See Fig. 19.
Fig. 17 shows the transferability of learning rate, , initialization standard deviation, and Adam across width, batch size, sequence length, and training steps for post-layernorm Transformers. However, in general, we find transfer across depth to be fragile.
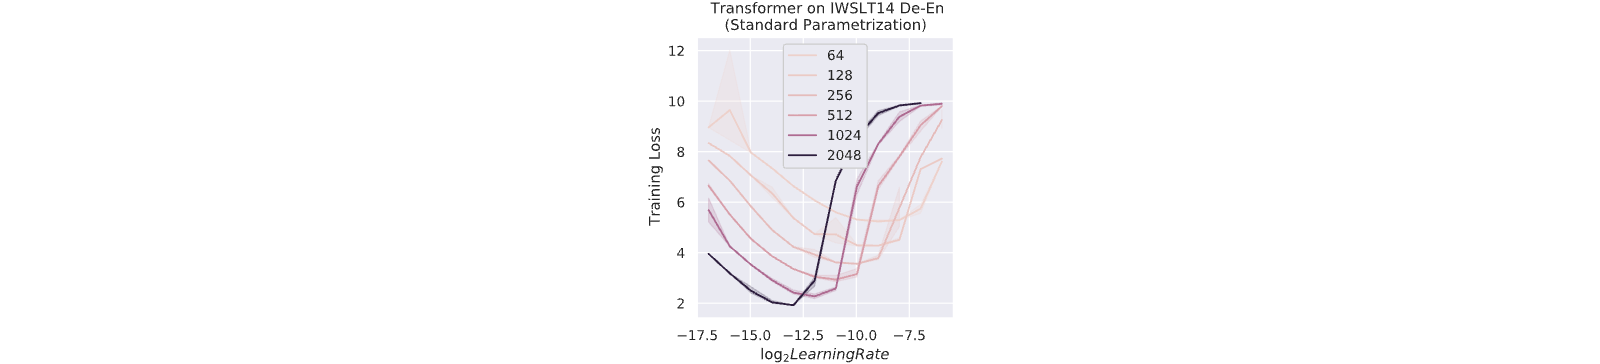
As we have shown, one can enable Transfer by just reparametrizing the desired model in Maximal Update Parametrization (P). While conceptually simple, switching from Standard Parametrization (SP) to P can be error-prone, as popular deep learning frameworks are built around SP. We strive to build a tool that fulfills two goals:
- 1.
Minimize code changes when switching to P;
- 2.
Keep model behavior invariant, under this switch, at a given base model shape.
By model shape, we mean the collection of dimensions of all parameters of the model. The latter goal, which we call parametrization backward compatibility, ensures that any code base works exactly as before at the base model shape, similar to Eq. 4, e.g. the loss at any time step remains exactly the same before and after the switch to P. Of course, when widths start to differ from the base model shape, the model behavior necessarily changes so that HPs can be transferred.
There are two common approaches to setting the base model shape: 1) If one intends to tune a large target model, then the user can set the base model shape to be the shape of the target model (e.g. BERT-large or T5-large), so that the target model itself is in standard parametrization. Then one can tune a proxy model with e.g. to obtain the optimal HPs for the target model. In addition, if one wishes to scale up further e.g. , then these HPs remain optimal. 2) If one has done exploration on a new idea with a small model and now wishes to scale up, reusing the HP found during this exploration, then one can set the base model shape to be the shape of the exploratory small model. Of course, in both scenarios, depth, batch size, and sequence lengths can be scaled up and down as well according to Fig. 19 (though note that currently we require users to recreate the base model shape at new depths, since the number of parameters now change with depth).
We provide our tool as a Python package called mup designed to work with PyTorch. The following example illustrates the usage of our package.
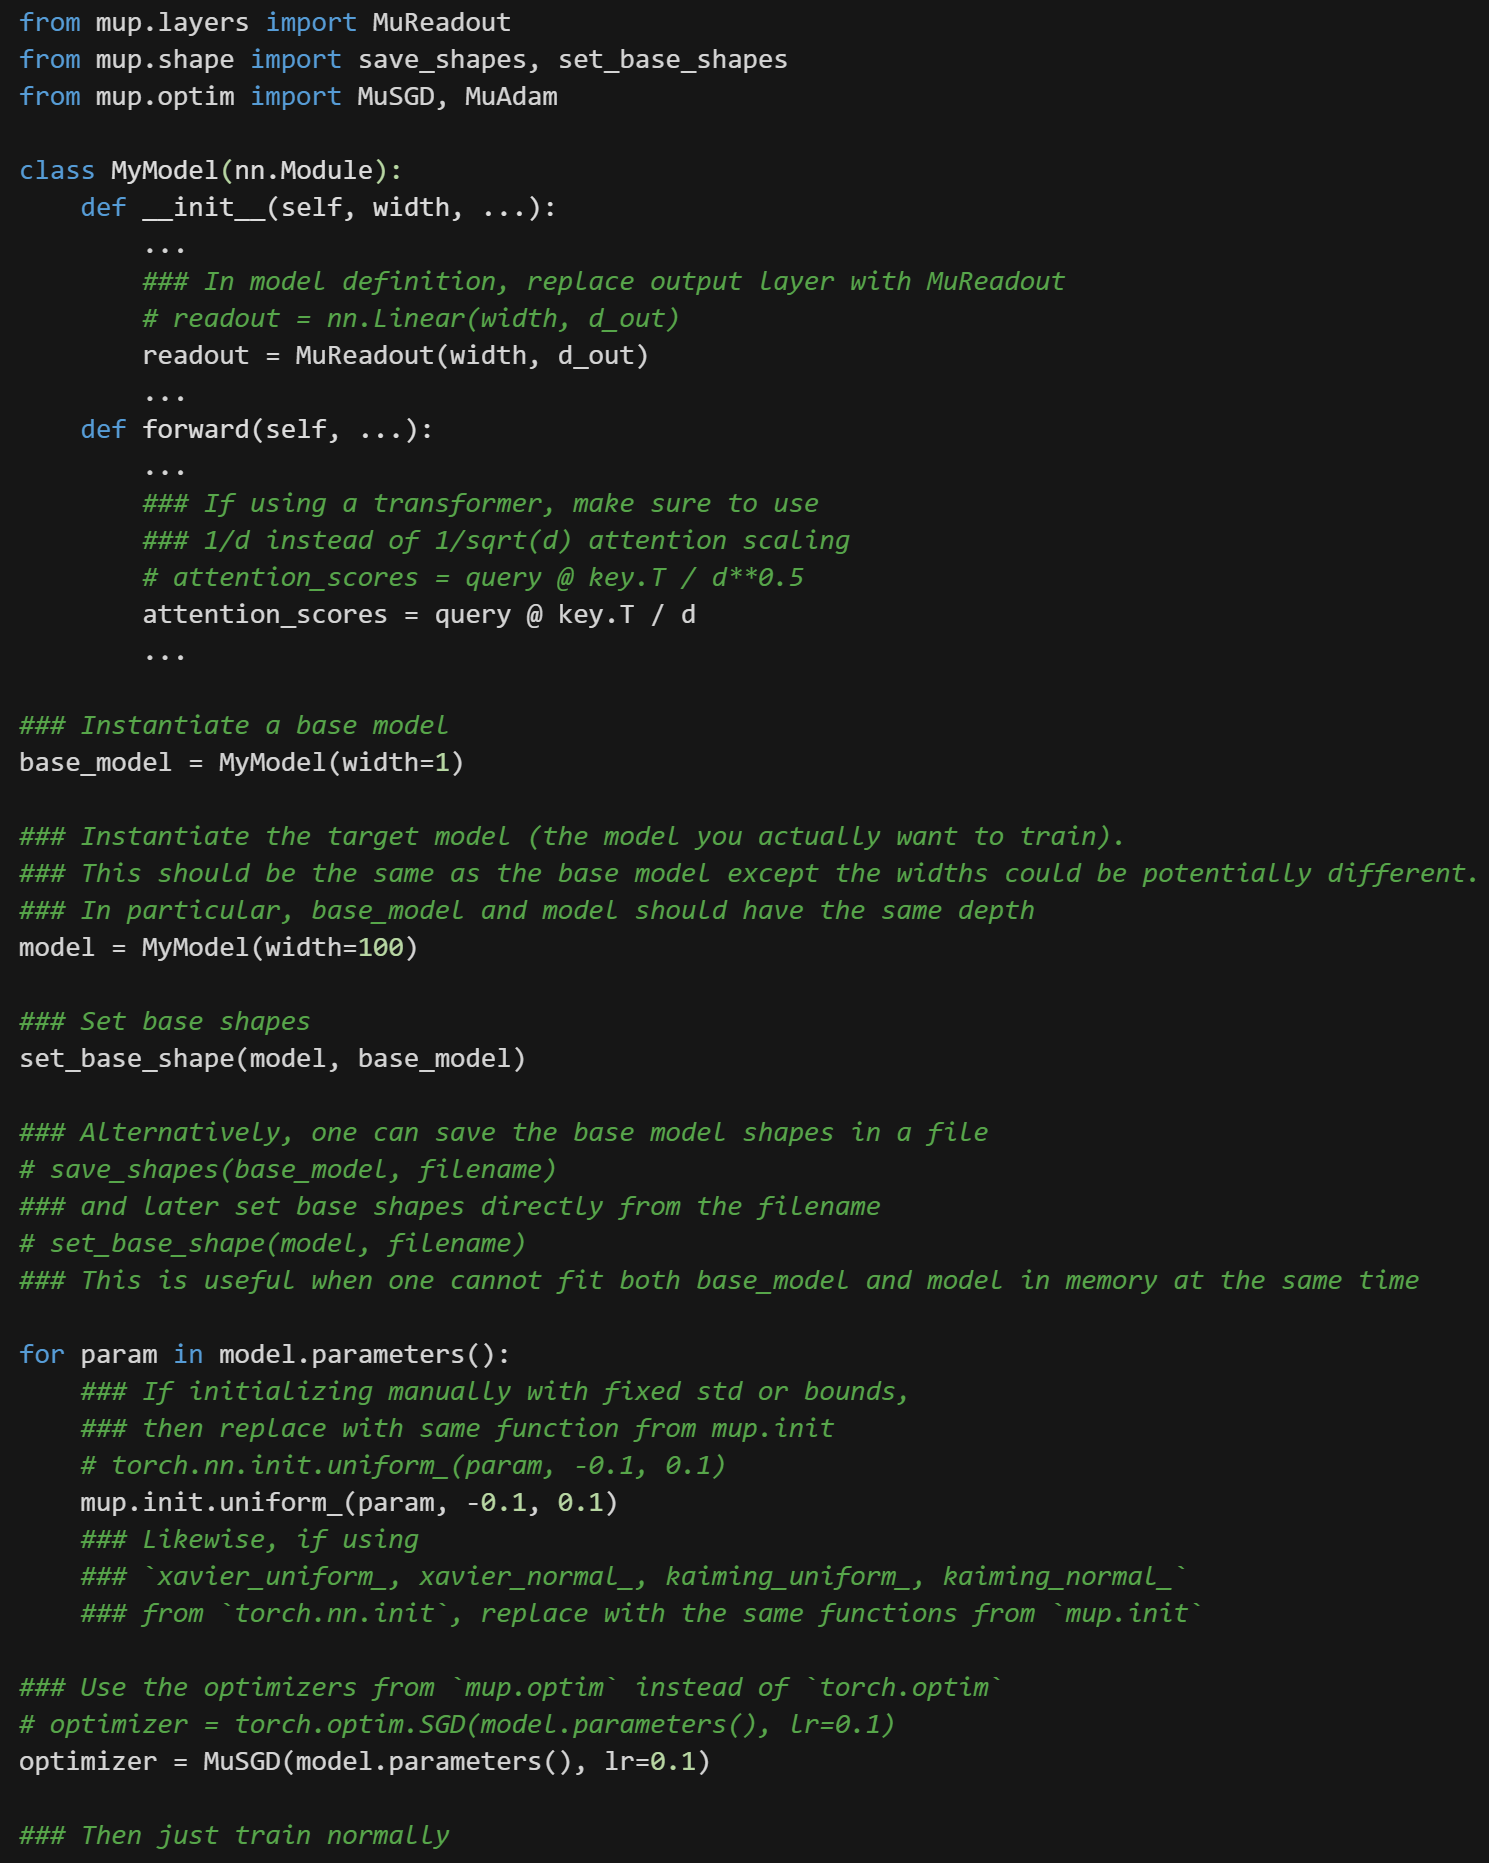
Text in this graphic
[Uncaptioned image]
Under the hood, mup implements the P formulation in Table 8. By invoking set_base_shape(model, base_model), each parameter tensor p of model gets a p.infshape attribute that stores, for each of its dimensions, the corresponding base dimension and whether that dimension should be considered “infinite” (i.e. will be scaled up/down, e.g., of a Transformer) or “finite” (i.e. will be fixed, e.g., vocabulary size). This information is used in the initializers and optimizers to automatically scale the parameters or learning rates to be compliant with P. For example, by Table 8, the Adam learning rate of hidden weights p is calculated as , where p.infshape.width_mult() essentially calculates
Large Transformers are famously fickle to train [37, 25]. We note that a possible source of this instability for larger transformers is the failure of naive hyperparameter transfer via the standard parametrization. This is certainly consistent with Fig. 1, which shows that the optimal learning rate for small Transformers can lead to trivial performance in large Transformers. We support this hypothesis further by reverse-Transferring the instability-inducing HPs from a large Transformer to a small one and replicating the training instability. This is shown in Footnote 23.
Practically, this reverse-Transfer technique can be used to diagnose or debug training instability problems of large models. We offer two case studies toward this claim.
1) When training transformers of width 8192 on Wikitext-2, we found certain HP combinations caused divergence in the middle of training. We reverse-Transferred one such HP combination to a model of width 256 and replicated this divergence. By analyzing this small model’s activations right before this divergence, we found that the cause is due to attention logits blowing up. Note this debugging session proceeded much more quickly than if we directly worked with the large model. Later we confirmed this is indeed the same cause of the width-8192 model’s divergence.
2) A 6B-parameter language model (in standard parametrization) in a separate project experienced repeated blow-up in the middle of training. We reverse-Transferred its hyperparameters to a smaller, 100M-parameter model and replicated the training instability. This was solved by a retuning of the small model via random search.
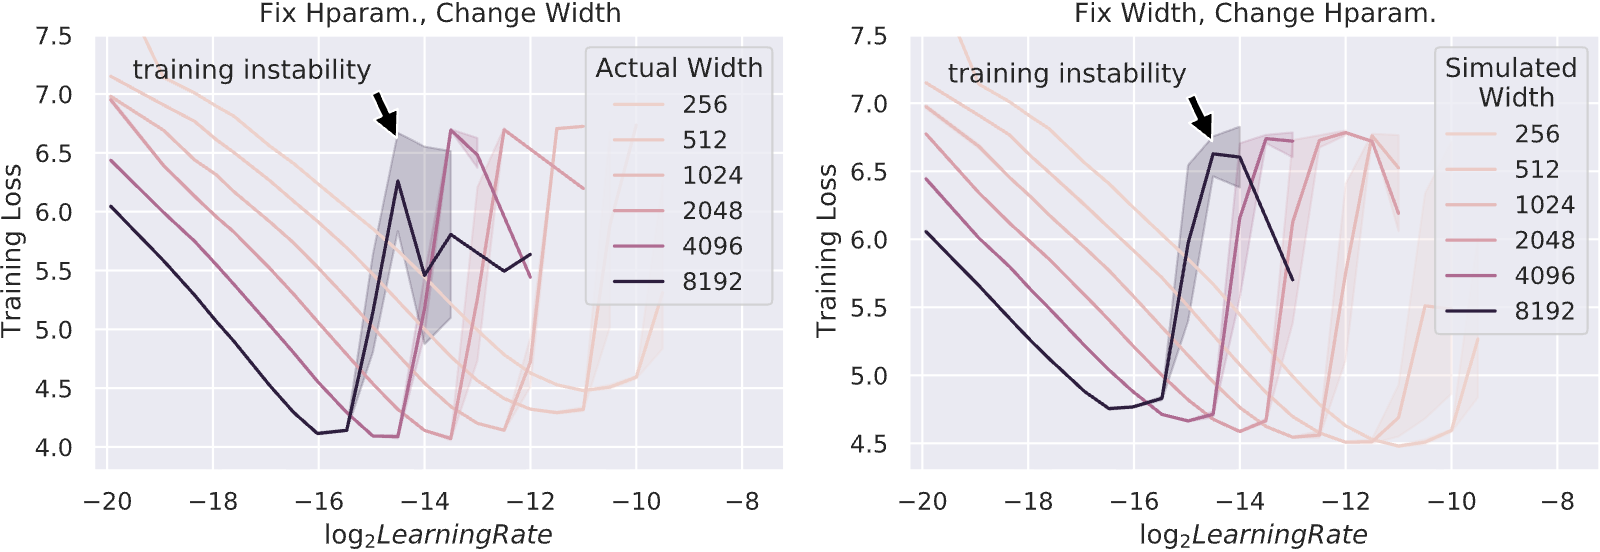
In what follows, we seek to describe useful intuitions and rules of thumb that would be helpful to practitioners and empirical researchers alike in figuring out what is the right neural network parametrization. The intuitions we shall describe regarding SGD can be made rigorous as in [56, 57]; those regarding Adam are new, and their formalization will be done in an upcoming paper.
First, we write down the most basic intuition regarding sums of many random elements, which will underlie all of the calculations that follow.
If “look like” random independent samples of a random variable , then
\frac{1}{n}\sum_{i=1}^{n}x_{i}\to\EV[X],\quad\text{as $n\to\infty$}.In the same scenario as above,
\frac{1}{\sqrt{n}}\sum_{i=1}^{n}(x_{i}-\EV[X])\to\mathcal{N}(0,\sigma(X)),\quad\text{as $n\to\infty$},where is the standard deviation of the random variable .
Of course, there are many subtleties one must resolve to make the statements above truly rigorous (e.g., what is the meaning of “look like”?), but as rules of thumb, they typically give the correct prediction.
In particular, here we want to note the following basic intuition regarding the size of a sum of :
\text{when $n$ is large, }\sum_{i=1}^{n}x_{i}\text{ has typical size }\begin{cases}\Theta(n)&\text{if $\EV[X]\neq 0$}\\ \Theta(\sqrt{n})&\text{otherwise}\end{cases}Here, “typical size” can be taken to mean the size of time. Again, we stress that this is a good rule of thumb that yields the correct prediction in the cases we are concerned with here; the rigorous versions of this will come from the Tensor Programs framework (e.g., [56]).
Central to the derivation of P for any architecture are key insights on the behaviors of two kinds of random matrices: 1) iid Gaussian random matrix and 2) tensor product matrix (by which we mean a sum of outer products) and more generally what we call nonlinear tensor product matrix (see Eq. 7). For example, a neural network, randomly initialized in the typical way, will have each weight matrix look like the former. However, every step of training by gradient descent adds a sum of outer products to this initial matrix, so that the change in weights constitute a tensor product matrix. For Adam, the change in weights is not a tensor product but a more general nonlinear tensor product matrix (see Eq. 7). In this section, we will particularly focus on the right scaling for the entries of such matrices, leading to a discussion of the right neural network parametrization in the next section. We concentrate on the key heuristics but eschew burdensome rigor.
Consider a random vector with approximately iid entries and a random matrix of either size or , both having entries of size . In the context of deep learning, for example can be an activation vector in an MLP, a Gaussian the hidden weights at initialization, a (nonlinear) tensor product the change in hidden weights due to training, and a vector the readout layer weights. Then corresponds to a part of the next layer preactivation or the network output. To make sure the preactivations and the output don’t blow up, we thus need to understand the scale of , especially in the general case where is correlated with . This is summarized in Table 14, with the derivations below. Intuitively, a (nonlinear) tensor product or vector will interact with a correlated via Law of Large Numbers, hence the -scaling, while a Gaussian interacts with via Central Limit Theorem, hence the -scaling.
| Standard Gaussian | (Nonlinear) Tensor Product | Vector | |
|---|---|---|---|
| Entry size of |
View original table

In the derivations below, we answer a slightly different but equivalent question of “how to scale such that has entry size ?”
By the results of [57], each (pre-)activation vector and its gradient vector in a multi-layer perceptron, at any time during training, have approximately iid coordinates in the large width limit, and something similar can be said for more advanced networks such as ResNet and Transformers .
We say any such vector has -sized coordinates, or just -coordinates for short, if as . Because, by the above discussion, the coordinates are roughly iid when is large, this intuitively means that each entry of has “typical size” . We make similar definitions with replaced by and .
Furthermore, to each such vector with -sized coordinates, we can associate a random variable , independent of , that represents the coordinate distribution of , in such a way that: If vector is correlated with , then will also be correlated with , and \lim_{n\to\infty}v^{\top}u/n=\EV Z^{u}Z^{v}.
The case of (linear) tensor product matrix can be reduced to the outer product case by linearity. Given having approximately iid coordinates (of size ) like discussed above, we can form the outer product
which is the form of a single (batch size 1) gradient update to a weight matrix. Then, by Law of Large Numbers,
Ax=u\frac{v^{\top}x}{n}\approx cu,\quad\text{where}\quad c=\EV Z^{v}Z^{x}.So also has approximately iid coordinates, distributed like Z^{Ax}\mathbin{\overset{\mathrm{def}}{=}}Z^{u}\EV Z^{v}Z^{x}. Likewise, if is a sum of outer products , then
Ax=\sum_{i=1}^{k}u^{i}\frac{v^{i\top}x}{n},\quad\text{with coordinates distributed as}\quad Z^{Ax}=\sum_{i=1}^{k}Z^{u^{i}}\EV Z^{v^{i}}Z^{x}.Notice that each coordinate of has size . The above reasoning shows that, in order for to have coordinate size (assuming does), then is the right coordinate size for , in the general case that and are correlated (as is generically the case during gradient descent, with for some weights and being the previous activations).
When using Adam or another adaptive optimizer that normalizes the gradient coordinatewise before applying them, we need to modify our argument slightly to obtain the right coordinate size scaling of the matrix. The gradient update , after such normalization, will take the form of
A_{\alpha\beta}=\psi(u_{\alpha}^{1},\ldots,u_{\alpha}^{k},v_{\beta}^{1},\ldots,v_{\beta}^{k}),\quad\text{for some $\psi:\mathbb{R}^{2k}\to\mathbb{R}$ and vectors $u^{i},v^{j}\in\mathbb{R}^{n}.}\tag{(7)}$
We say a matrix of this form is a nonlinear tensor product matrix.
First, note the tensor product matrices (e.g. the form of SGD update) discussed previously (Eq. 6) already takes this form, with , so Eq. 7 is a strict generalization of linear tensor products. Next, for the example of Adam, each gradient update is where (resp. ) is the moving average of previous (unnormalized) gradients (resp. the coordinatewise square of the same). If these unnormalized gradients are the outer products , then the update has coordinates
where and are the weights involved in the moving averages.
Now suppose we have some of the form Eq. 7, where have approximately iid coordinates (of size ), and where doesn’t depend on (in terms of Adam where corresponds to the of Eq. 8, this corresponds to using a learning rate of ). Then for having approximately iid coordinates of size , by Law of Large Numbers,
(Ax)_{\alpha}=\frac{1}{n}\sum_{\beta=1}^{n}\bar{\psi}(u_{\alpha}^{1},\ldots,u_{\alpha}^{k},v_{\beta}^{1},\ldots,v_{\beta}^{k})x_{\beta}\approx\EV\bar{\psi}(u_{\alpha}^{1},\ldots,u_{\alpha}^{k},Z^{v^{1}},\ldots,Z^{v^{k}})Z^{x}\mathbin{\overset{\mathrm{def}}{=}}\Psi(u_{\alpha}^{1},\ldots,u_{\alpha}^{k}).Here we made the obvious definition
\Psi:\mathbb{R}^{k}\to\mathbb{R},\qquad\Psi(r_{1},\ldots,r_{k})\mathbin{\overset{\mathrm{def}}{=}}\EV\bar{\psi}(r_{1},\ldots,r_{k},Z^{v^{1}},\ldots,Z^{v^{k}})Z^{x}.Thus also has approximately iid coordinates (of size ),
For example, in the SGD example with and , this formula gives where \Psi(z)=z\EV Z^{v}Z^{x}, recovering the earlier derivation.
In any case, the point here is that has coordinate size , and this is the unique scaling that leads to having coordinate size .
The vector case is similar to the tensor product cases above.
Now consider the case where is random Gaussian matrix with and has approximately iid coordinates distributed like . In the context of neural network training, should be thought of as a randomly initialized weight matrix, and for example can be taken to be an activation vector in the first forward pass.
By standard random matrix theory, has operator norm with high probability. Thus, with high probability, for any “typical” vector , we expect , even if is correlated with . If ’s coordinates are “evenly distributed”, then this would imply has -coordinates if does. However, this is not so clear. Below we provide intuitions for why this would be the case.
If is independent from (or sufficiently uncorrelated), then each coordinate has variance \EV(Z^{x})^{2}=\Theta(1) (so by definition has size ). Thus, here having -coordinates leads to having -coordinates, in contrast to the tensor product case above.
When is correlated with , it turns out the same scaling applies ( is the unique scaling for ’s entries such so that has entries), but the reasoning is much more subtle: In the context of neural network training, it turns out all scenario where is correlated with can be reduced to the case where for some coordinatewise nonlinearity and some other vector . Let’s consider a very simple example with for the all 1s vector (which has coordinate size as can be checked easily). Then, for each index , we can calculate
Since \EV A_{\alpha\beta}^{2}=1/n, by the Law of Large Number, the first sum . On the other hand, there are summands of the form , all iid with variance . Thus by the Central Limit Theorem, we expect . Therefore, each coordinate of looks like and thus has size ; again this is caused by having -coordinates.
This example can be generalized to more general that is correlated with , but the mathematics is quite involved. See [56] for more details.
Armed with the insight from the last section, we now outline the key steps to derive P in Table 3 for any architecture. In practice, P implies the following desiderata
At any time during training
- 1.
Every (pre)activation vector in a network should have -sized coordinates
- 2.
Neural network output should be .
- 3.
All parameters should be updated as much as possible (in terms of scaling in width) without leading to divergence.
Let’s briefly justify these desiderata. For the desideratum 1, if the coordinates are or , then for sufficiently wide networks their values will go out of floating point range. This problem is particularly acute for low-precision formats that are essential for training large models such as BERT or GPT. Moreover, a general nonlinearity is only well-behaved if its input is in a fixed range (although this is not a problem for homogeneous nonlinearities like relu). For example, for tanh nonlinearity, if the preactivation is vanishing , then is essentially linear; if the preactivation is exploding , then the tanh gradient vanishes.
For the desideratum 2, a similar justification applies to the numerical fidelity of the loss function and loss derivative. Note that, with desideratum 3, this means the network output should be after training (but it can go to zero at initialization).
Finally, desideratum 3 means that 1) we are doing “maximal feature learning” [57] and 2) every parameter contribute meaningfully in the infinite-width limit. This ensures that learning rate “plays the same role” in the finite-width case as in the infinite-width limit. For example, it prevents the scenario where a weight matrix gets stuck at initialization in the limit for any learning rate (so learning rate does not matter) but evolves nontrivially in any finite-width network (so learning rate does matter).
These desiderata will essentially uniquely single out P. More formally, P is the unique parametrization that admits feature learning in all parameters of the neural network [57], and this property theoretically guarantees HP transfer across width (for sufficiently large width). However, for the sake of reaching a broader audience, we will focus more on the intuitive derivations from the desiderata rather than on this formal aspect.
Below, we first assume for simplicity that the width of every layer is , and we focus only on dense weights. Later, we will discuss convolutions and varying the widths between layers.
Below, we will derive the P formulation in Table 3. Tables 8 and 9 can be derived from Table 3 via the following equivalences, which can be easily derived via some simple calculations.
Let denote the neural network function after steps of training (using any fixed sequence of batches), evaluated on input . Consider a parameter tensor with learning rate , initialized as , and with a multiplier . Then for any , stays fixed for all and if we set
- •
when the optimizer is SGD
- •
when the optimizer is Adam,
For example, for output weights, Table 3 has , , for SGD and Adam. Then taking , we get the entries in Table 8, with , , for SGD and for Adam. Taking instead, we get the entries in Table 9, with , , for SGD and for Adam. Similar calculations hold for the input weights scaling in those tables, after taking into consideration that is considered a constant in terms of width for the input layer.
We proceed with the derivation of Table 3 below. Recall the definitions of -sized coordinates or -coordinates from Definition J.1.
Suppose is an output weight. By desideratum 1, the input to has -sized coordinates. Thus should have -coordinates so that . We can initialize with -coordinates and scale its (per-layer) LR so that has -coordinates as well. This means initializing and use learning rate for both SGD and Adam.
Consider a square weight matrix . Desiderata 1 guarantees that the input to has -sized coordinates. Generally, will be correlated with . By Table 14, we can immediately derive
Initialization
should be randomly initialized with coordinate size
LR
The learning rate should be scaled so that has coordinate size
so that is if is, inductively satisfying desideratum 1. With Adam, this just means the per-layer LR is . With SGD and the scaling of output layers above, we can calculate that the gradient of has -coordinates, so the SGD LR derived above suffices as well.
Suppose is an input weight. To satisfy desideratum 1 (i.e. for any input , should have -coordinates), we want to have -coordinates. We can initialize with -coordinates and scale its (per-layer) LR so that has -coordinates as well. This implies initialization variance of (or since here) and Adam learning rate . As above, we can calculate that the gradient of has -coordinates, so we want SGD learning rate .
Biases follow the same reasoning as input weights (just think of it as an input weight with input 1).
Suppose the key dimension is tending to infinity with width with number of heads fixed. Then the key-query contraction scales like by Law of Large Numbers (instead of Central Limit Theorem because and are generally correlated) and desideratum 1, hence the we propose rather than .
Now suppose instead that tends to infinity with width with fixed. Let be keys, queries, and values across all heads and tokens. Thinking of as constants, we may view attention as a nonlinearity coordinatewise in the dimension. Then it’s clear that our parametrization described above already works.
Finally, we may freely let and both tend to infinity, and the above reasoning shows that our parametrization still works.
As noted above, at any time in training, every (pre-)activation vector will have approximately iid coordinates (of order by desideratum 1). Another desideratum for P is to ensure that this coordinate distribution (at any particular time) stays roughly invariant as widths increases. When all layer widths are tied, this is automatic if the other desiderata are satisfied, hence why we did not list this above.
When width ratios vary, this is not automatic. In this case, we need to choose whether to replace each with fan-in or fan-out (or some function of them). Making the wrong choices will let the coordinate distributions vary with width ratios.
Obviously, we should replace with fan-in for the output layers and with fan-out for the input layers since they are the only dimension scaling with . For the hidden weights, we replace with fan-in so that the forward pass is preserved. When using Adam (and assuming the initialization of is quickly dominated by the change in ), this ensures that the (pre-)activation coordinate distributions are preserved at any time during training even if we vary widths in different layers differently. (For SGD this doesn’t quite work in general because the varying width ratios change the gradient sizes of different layers differently, whereas Adam always normalizes the gradient coordinatewise).
A convolution weight tensor with kernel size can be thought of just as a -sized collection of dense weights. Then all of our discussions above apply accordingly.
SP doesn’t work essentially because it leads to blow-up in the infinite-width limit.
- 1.
For Adam with LR , would have -coordinates, causing preactivations to blow up like by Desideratum 1 and Table 14. We can avoid this blowup with LR , but this induces a non-maximal feature learning limit, which, as we argue below, cannot transfer hyperparameters in all situations.
- 2.
For SGD, the gradient of weight has -coordinates, so learning rate would make preactivation scale like and hence blow up. If we use learning rate, then blow-up does not occur. However, this infinite-width limit is in the kernel regime [57] and thus does not allow HP transfer for the same reason that NTP below does not.
We have concrete examples, e.g. Word2Vec in [57], where the NTK limit has trivial performance — so HPs have no effect at all — vastly outperformed by finite-width networks — where HPs matter. More importantly, wider does not always do better in NTP, especially in tasks where feature learning is crucial [57, 61]. So in the context of modern deep learning e.g. large language model pretraining, NTP (or SP with LR) does not make sense for wide neural networks.
Recall the Dynamical Dichotomy Theorem proven in [57], which says that any nontrivial stable “natural parametrization” (formally, “abc-parametrization,” [57]) either admits a feature learning limit or a kernel limit, but not both.
Our argument above against SP and NTP will also work against any parametrization inducing a kernel limit. Therefore, it remains to ask, can other feature learning parametrizations transfer HPs?
We argue no. As shown in [57], any other feature learning parametrization differs from P essentially only in that some parameters are not updated maximally. By [57, Sec 6.4], in the infinite-width limit, such parameters can be thought of as being fixed at initialization. Therefore, in such infinite-width limits, the learning rate of such parameters becomes useless. As such, we cannot hope for the HP landscape of the limit to reflect the HP landscape of finite-width neural networks.
P is the unique feature learning parametrization that updates all parameters maximally, so that the learning rate of each parameter plays approximately the same role in finite-width neural networks as in the infinite-width limit. Consequently, the HP landscape of the P limit should reflect the HP landscape of finite-width neural networks.