Flow Straight and Fast: Learning to Generate and Transfer Data with Rectified Flow
arXiv:2209.03003v1 · This workspace stays on this version. Check arXiv for newer versions
Some source details need review 4 to check
Original formulas, table values and figures are preserved. Comparison can miss differences; use the original PDF to check details.
Reading view checked: 968 math expressions, 30 rendering failures; 22 of 23 images available.
Compared 230 of 266 source passages against 41 of 41 PDF pages.
- Some figure, table or graphic images are unavailable; the original paper is still accessible. (1)
- Some formulas could not be rendered; their original TeX is shown. Check the original PDF. (30)
- S5_F7: capture coverage or occlusion check failed; image withheld.
- This long paper was only partially compared; the original sources remain available.
22 of 23 figure, table and graphic images captured. Open original PDF
Abstract
We present rectified flow, a surprisingly simple approach to learning (neural) ordinary differential equation (ODE) models to transport between two empirically observed distributions and , hence providing a unified solution to generative modeling and domain transfer, among various other tasks involving distribution transport. The idea of rectified flow is to learn the ODE to follow the straight paths connecting the points drawn from and as much as possible. This is achieved by solving a straightforward nonlinear least squares optimization problem, which can be easily scaled to large models without introducing extra parameters beyond standard supervised learning. The straight paths are special and preferred because they are the shortest paths between two points, and can be simulated exactly without time discretization and hence yield computationally efficient models. We show that the procedure of learning a rectified flow from data, called rectification, turns an arbitrary coupling of and to a new deterministic coupling with provably non-increasing convex transport costs. In addition, recursively applying rectification allows us to obtain a sequence of flows with increasingly straight paths, which can be simulated accurately with coarse time discretization in the inference phase. In empirical studies, we show that rectified flow performs superbly on image generation, image-to-image translation, and domain adaptation. In particular, on image generation and translation, our method yields nearly straight flows that give high quality results even with a single Euler discretization step.
Compared with supervised learning, the shared difficulty of various forms of unsupervised learning is the lack of paired input/output data with which standard regression or classification tasks can be invoked. The gist of most unsupervised methods is to find, in one way or another, meaningful correspondences between points from two distributions. For example, generative models such as generative adversarial networks (GAN) and variational autoencoders (VAE) [19, 32, 14, e.g.,] seek to map data points to latent codes following a simple elementary (Gaussian) distribution with which the data can be generated and manipulated. Representation learning rests on the idea that if a sufficiently smooth function can map a structured data distribution to an elementary distribution, it can (likely) be endowed with certain semantically meaningful interpretation and useful for various downstream learning tasks. On the other hand, domain transfer methods find mappings to transfer points from two different data distributions, both observed empirically, for the purpose of image-to-image translation, style transfer, and domain adaption [100, 16, 79, 59, e.g.,]. All these tasks can be framed unifiedly as finding a transport map between two distributions:
The Transport Mapping Problem Given empirical observations of two distributions on , find a transport map (hopefully nice or optimal in certain sense), such that when , that is, is a coupling (a.k.a transport plan) of and .
Several lines of techniques have been developed depending on how to represent and train the map . In traditional generative models, is parameterized as a neural network, and trained with either GAN-type minimax algorithms or (approximate) maximum likelihood estimation (MLE). However, GANs are known to suffer from numerically instability and mode collapse issues, and require substantial engineering efforts and human tuning, which often do not transfer well across different model architecture and datasets. On the other hand, MLE tends to be intractable for complex models, and hence requires approximate variational or Monte Carlo inference techniques such as those used in variational auto-encoders (VAE), or special model structures such as normalizing flow and auto-regressive models, to yield tractable likelihood, causing difficult trade-offs between expressive power and computational cost.
Recently, advances have been made by representing the transport plan implicitly as a continuous time process, such as flow models with neural ordinary differential equations (ODEs) [6, 56, e.g.,] and diffusion models by stochastic differential equations (SDEs) [73, 23, 80, 11, 82, e.g.,]; in these models, a neural network is trained to represent the drift force of the processes and a numerical ODE/SDE solver is used to simulate the process during inference. The key idea is that, by leveraging the mathematical structures of ODEs/SDEs, the continuous-time models can be trained efficiently without resorting to minimax or traditional approximate inference techniques. The most notable examples are the recent score-based generative models [71, 72, 73] and denoising diffusion probabilistic models (DDPM) [23], which we call denoising diffusion methods collectively. These methods allow us to train large-scale diffusion/SDE-based generative models that surpass GANs on image generation in both image quality and diversity, without the instability and mode collapse issues [12, 53, 61, 64, e.g.,]. The learned SDEs can be converted into deterministic ODE models for faster inference with the method of probability flow ODEs [73] and DDIM [70].
However, compared with the traditional one-step models like GAN and VAE, a key drawback of continuous-times models is the high computational cost in inference time: drawing a single point (e.g., image) requires to solve the ODE/SDE with a numerical solver that needs to repeatedly call the expensive neural drift function. In addition, the existing denoising diffusion techniques require substantial hyper-parameter search in an involved design space and are still poorly understood both empirically and theoretically [29].
In existing approaches, generative modeling and domain transfer are typically treated separately. It often requires to extend or customize a generative learning techniques to solve domain transfer problems; see e.g., Cycle GAN [100] and diffusion-based image-to-image translation [75, 97, e.g.,]. One framework that naturally unifies both domains is optimal transport (OT) [85, 2, 15, 59, e.g.,], which endows a collection of techniques for finding optimal couplings with minimum transport costs of form w.r.t. a cost function , yielding natural applications to both generative and transfer learning. However, the existing OT techniques are slow for problems with high dimensional and large volumes of data [59]. Furthermore, as the transport costs do not perfectly align with the actual learning performance, methods that faithfully find the optimal transport maps do not necessarily have better learning performance [34].
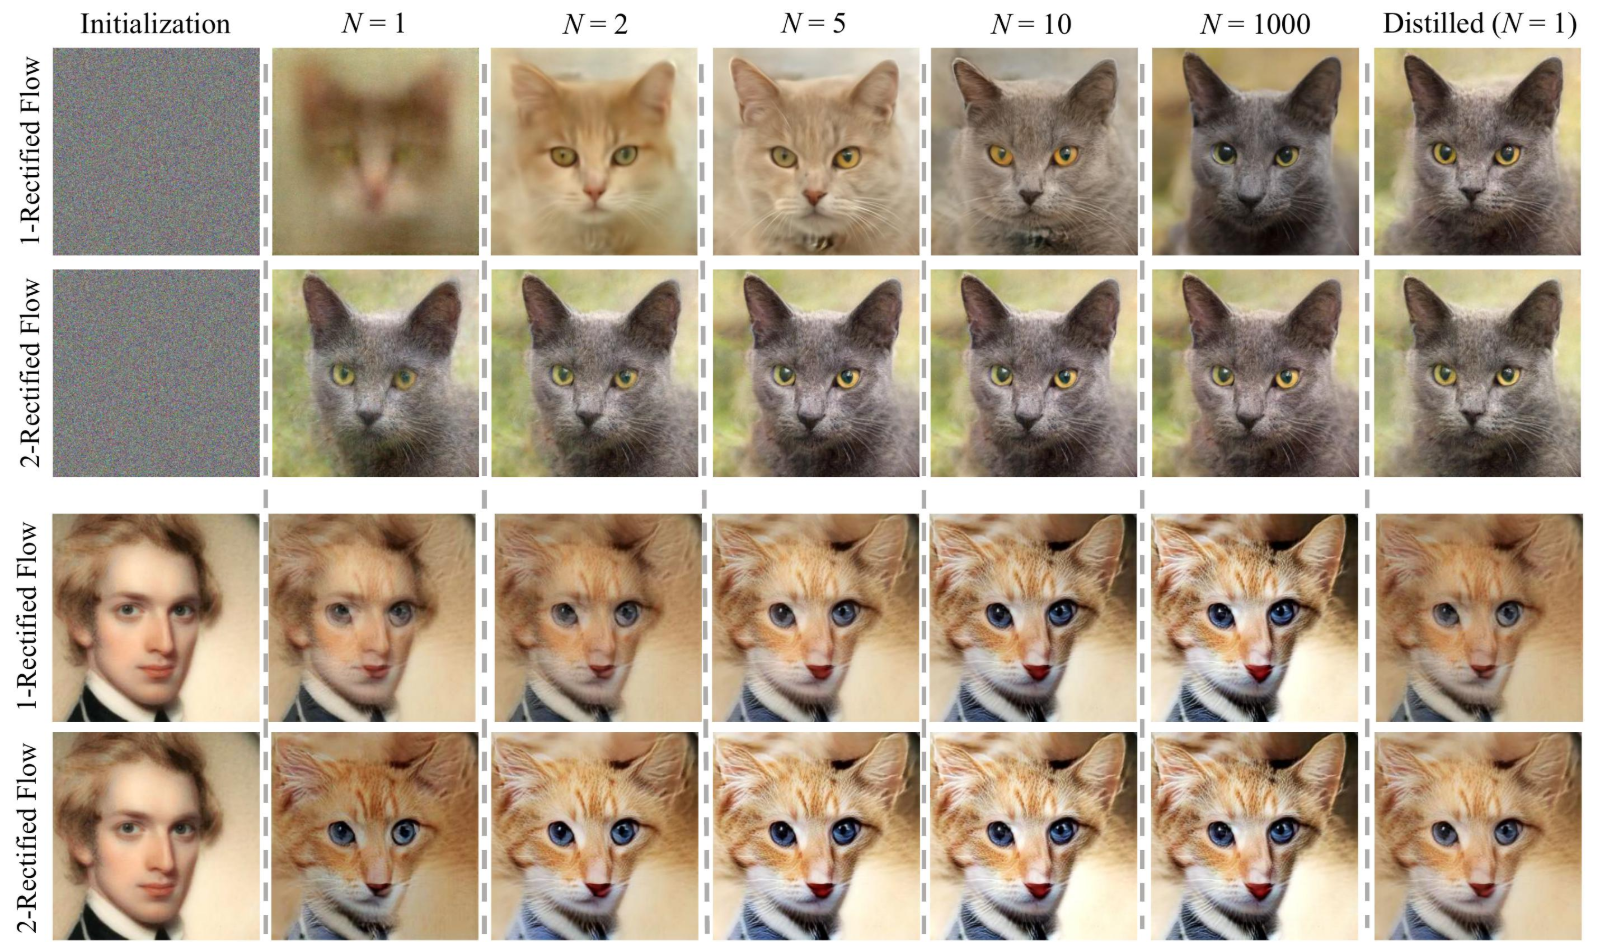
We introduce rectified flow, a surprisingly simple approach to the transport mapping problem, which unifiedly solves both generative modeling and domain transfer. The rectified flow is an ODE model that transport distribution to by following straight line paths as much as possible. The straight paths are preferred both theoretically because it is the shortest path between two end points, and computationally because it can be exactly simulated without time discretization. Hence, flows with straight paths bridge the gap between one-step and continuous-time models.
Algorithmically, the rectified flow is trained with a simple and scalable unconstrained least squares optimization procedure, which avoids the instability issues of GANs, the intractable likelihood of MLE methods, and the subtle hyper-parameter decisions of denoising diffusion models. The procedure of obtaining the rectified flow from the training data has the attractive theoretical property of 1) yielding a coupling with non-increasing transport cost jointly for all convex cost , and 2) making the paths of flow increasingly straight and hence incurring lower error with numerical solvers. Therefore, with a reflow procedure that iteratively trains new rectified flows with the data simulated from the previously obtained rectified flow, we obtain nearly straight flows that yield good results even with the coarsest time discretization, i.e., one Euler step. Our method is purely ODE-based, and is both conceptually simpler and practically faster in inference time than the SDE-based approaches of [23, 73, 70].
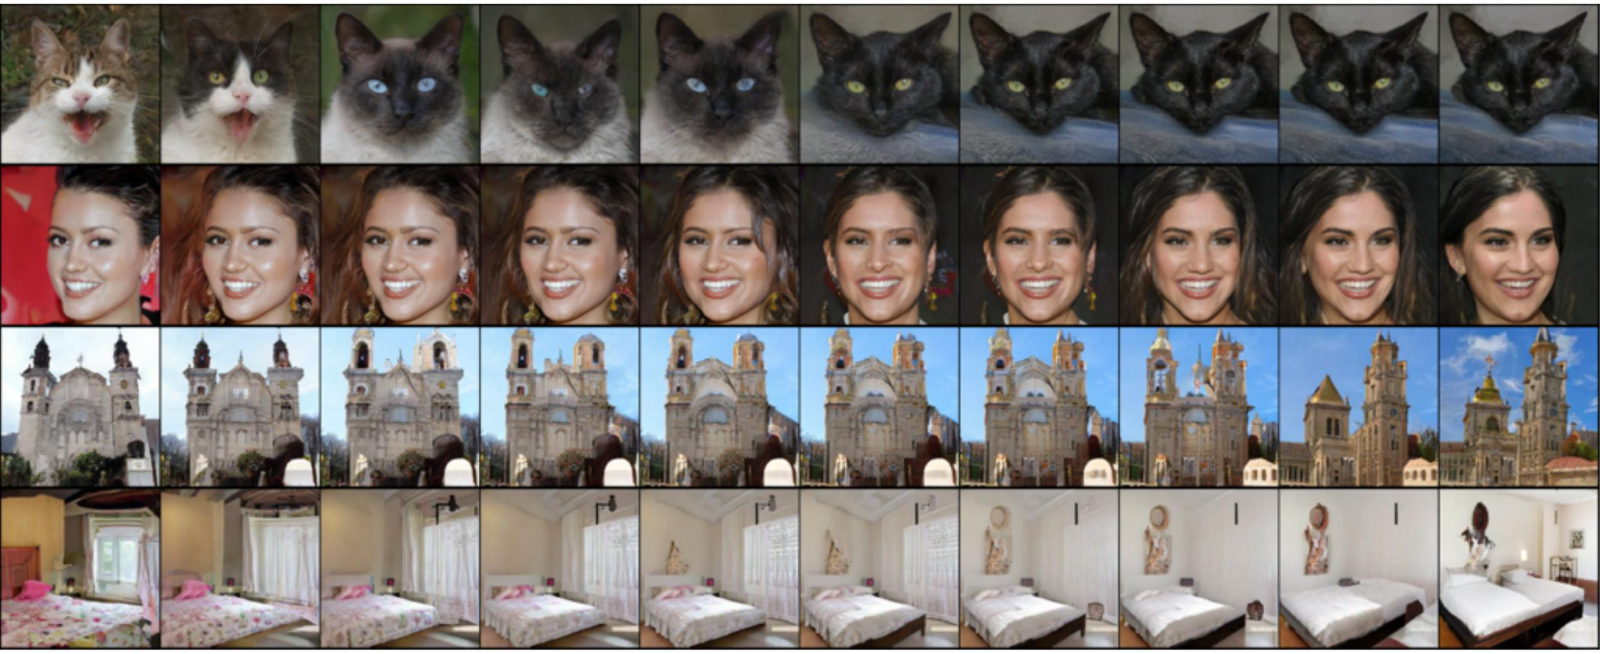
Empirically, rectified flow can yield high-quality results for image generation when simulated with a very few number of Euler steps (see Figure 1, top row). Moreover, with just one step of reflow, the flow becomes nearly straight and hence yield good results with a single Euler discretization step (Figure 1, the second row). This substantially improves over the standard denoising diffusion methods. Quantitatively, we claim a state-of-the-art result of FID (4.85) and recall (0.51) on CIFAR10 for one-step fast diffusion/flow models [5, 48, 91, 99, 47]. The same algorithm also achieves superb result on domain transfer tasks such as image-to-image translation (see the bottom two rows of Figure 1) and transfer learning.
We provide a quick overview of the method in Section 2.1, followed with some discussion and remarks in Section 2.2. We introduce a nonlinear extension of our method in Section 2.3, with which we clarify the connection and advantages of our method with the method of probability flow ODEs [73] and DDIM [70].
Given empirical observations of , the rectified flow induced from is an ordinary differentiable model (ODE) on time ,
which converts from to a following . The drift force is set to drive the flow to follow the direction of the linear path pointing from to as much as possible, by solving a simple least squares regression problem:
\displaystyle\min_{v}\int_{0}^{1}\mathbb{E}\left[\left\lVert(X_{1}-X_{0})-v\big(X_{t},\penalty\ t\big)\right\rVert^{2}\right]\mathrm{d}t,\penalty\ \penalty\ \penalty\ \penalty\ \penalty\ \text{with}\penalty\ \penalty\ \penalty\ \penalty\ X_{t}=tX_{1}+(1-t)X_{0},\tag{(1)}where is the linear interpolation of and . Naviely, follows the ODE of which is non-causal (or anticipating) as the update of requires the information of the final point . By fitting the drift with , the rectified flow causalizes the paths of linear interpolation , yielding an ODE flow that can be simulated without seeing the future.
In practice, we parameterize with a neural network or other nonlinear models and solve (1) with any off-the-shelf stochastic optimizer, such as stochastic gradient descent, with empirical draws of . See Algorithm 1. After we get , we solve the ODE starting from to transfer to , backwardly starting from to transfer to . Specifically, for backward sampling, we simply solve initialized from and set . The forward and backward sampling are equally favored by the training algorithm, because the objective in (1) is time-symmetric in that it yields the equivalent problem if we exchange and and flip the sign of .
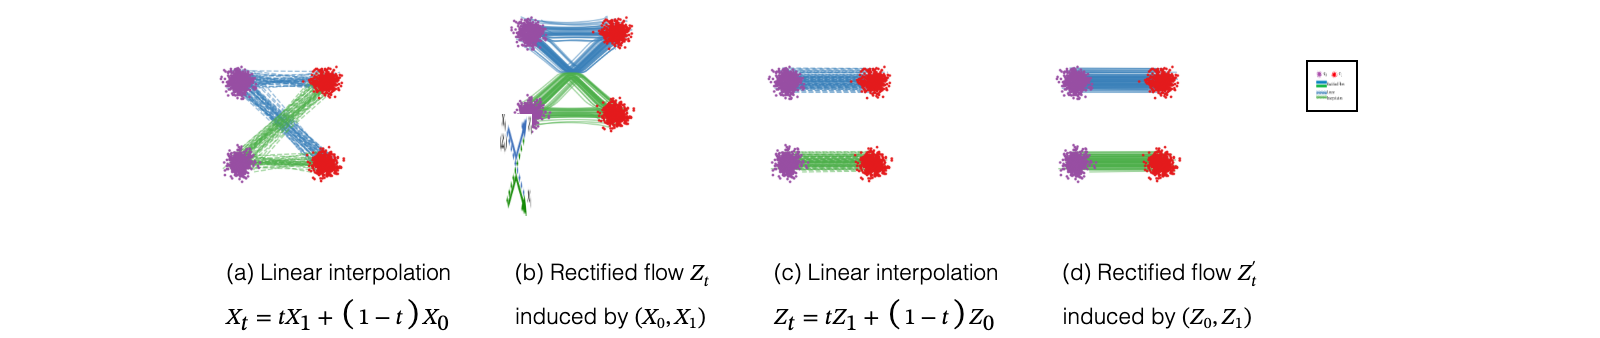
A key to understanding the method is the non-crossing property of flows: the different paths following a well defined ODE , whose solution exists and is unique, cannot cross each other at any time . Specifically, there exists no location and time , such that two paths go across at time along different directions, because otherwise the solution of the ODE would be non-unique. On the other hand, the paths of the interpolation process may intersect with each other (Figure 2a), which makes it non-causal. Hence, as shown in Figure 2b, the rectified flow rewires the individual trajectories passing through the intersection points to avoid crossing, while tracing out the same density map as the linear interpolation paths due to the optimization of (1). We can view the linear interpolation as building roads (or tunnels) to connect and , and the rectified flow as traffics of particles passing through the roads in a myopic, memoryless, non-crossing way, which allows them to ignore the global path information of how and are paired, and rebuild a more deterministic pairing of .
If (1) is solved exactly, the pair of the rectified flow is guaranteed to be a valid coupling of (Theorem 3.3), that is, follows if . Moreover, guarantees to yield no larger transport cost than the data pair simultaneously for all convex cost functions (Theorem 3.5). The data pair can be an arbitrary coupling of , typically independent (i.e., ) as dictated by the lack of meaningfully paired observations in practical problems. In comparison, the rectified coupling has a deterministic dependency as it is constructed from an ODE model. Denote by the mapping from to . Hence, converts an arbitrary coupling into a deterministic coupling with lower convex transport costs.
Following Algorithm 1, denote by the rectified flow induced from . Applying this operator recursively yields a sequence of rectified flows with , where is the -th rectified flow, or simply -rectified flow, induced from .
This reflow procedure not only decreases transport cost, but also has the important effect of straightening paths of rectified flows, that is, making the paths of the flow more straight. This is highly attractive computationally as flows with nearly straight paths incur small time-discretization error in numerical simulation. Indeed, perfectly straight paths can be simulated exactly with a single Euler step and is effectively a one-step model. This addresses the very bottleneck of high inference cost in existing continuous-time ODE/SDE models.
\displaystyle\hat{\theta}=\argmin_{\theta}\mathbb{E}\left[\left\lVert X_{1}-X_{0}-v(tX_{1}+(1-t)X_{0},\penalty\ t)\right\rVert^{2}\right], with .We provide more in-depth discussions on the main properties of rectified flow. We keep the discussion informal to highlight the intuitions in this section and defer the full course theoretical analysis to Section 3.
First, for a given input coupling , it is easy to see that the exact minimum of (1) is achieved if
\displaystyle v^{X}(x,t)=\mathbb{E}[X_{1}-X_{0}\penalty\ |\penalty\ X_{t}=x],\tag{(2)}which is the expectation of the line directions that pass through at time . We discuss below the property of rectified flow with , assuming that the ODE has an unique solution.
[Theorem 3.3] The pair is a coupling of and . In fact, the marginal law of equals that of at every time , that is, .
Intuitively, this is because, by the definition of in (2), the expected amount of mass that passes through every infinitesmal volume at all location and time are equal under the dynamics of and , which ensures that they trace out the same marginal distributions:
\begin{aligned}\displaystyle\text{ Flow in $\&$ out}\!\left(\vbox{\hbox{\includegraphics[height=25.83325pt]{arxiv_figures/arrow11_new.png}}}\right)\!\!=\text{Flow in $\&$ out}\!\left(\vbox{\hbox{\includegraphics[height=25.83325pt]{arxiv_figures/arrow22_new.png}}}\right)\!,\penalty\ \forall\text{time $\&$ location} & & \displaystyle\implies & & \displaystyle\mathrm{Law}(Z_{t})=\mathrm{Law}(X_{t}),\forall t.\end{aligned}On the other hand, the joint distributions of the whole trajectory of and that of are different in general. In particular, is in general a non-causal, non-Markov process, with a stochastic coupling, and causalizes, Markovianizes and derandomizes , while preserving the marginal distributions at all time.
[Theorem 3.5] The coupling yields lower or equal convex transport costs than the input in that for any convex cost .
The transport costs measure the expense of transporting the mass of one distribution to another following the assignment relation specified by the coupling and is a central topic in optimal transport [84, 85, 65, 59, 15, e.g.,]. Typical examples are with . Hence, yields a Pareto descent on the collection of all convex transport costs, without targeting any specific . This distinguishes it from the typical optimal transport optimization methods, which are explicitly framed to optimize a given . As a result, recursive application of does not guarantee to attain the -optimal coupling for any given , with the exception in the one-dimensional case when the fixed point of coincides with the unique monotonic coupling that simultaneously minimizes all non-negative convex costs ; see Section 3.4.
Intuitively, the convex transport costs are guaranteed to decrease because the paths of the rectified flow is a rewiring of the straight paths connecting . To give an illustration, consider the simple case of when transport costs and are the expected length of the straight lines connecting the end points. The inequality can be proved graphically as follows:
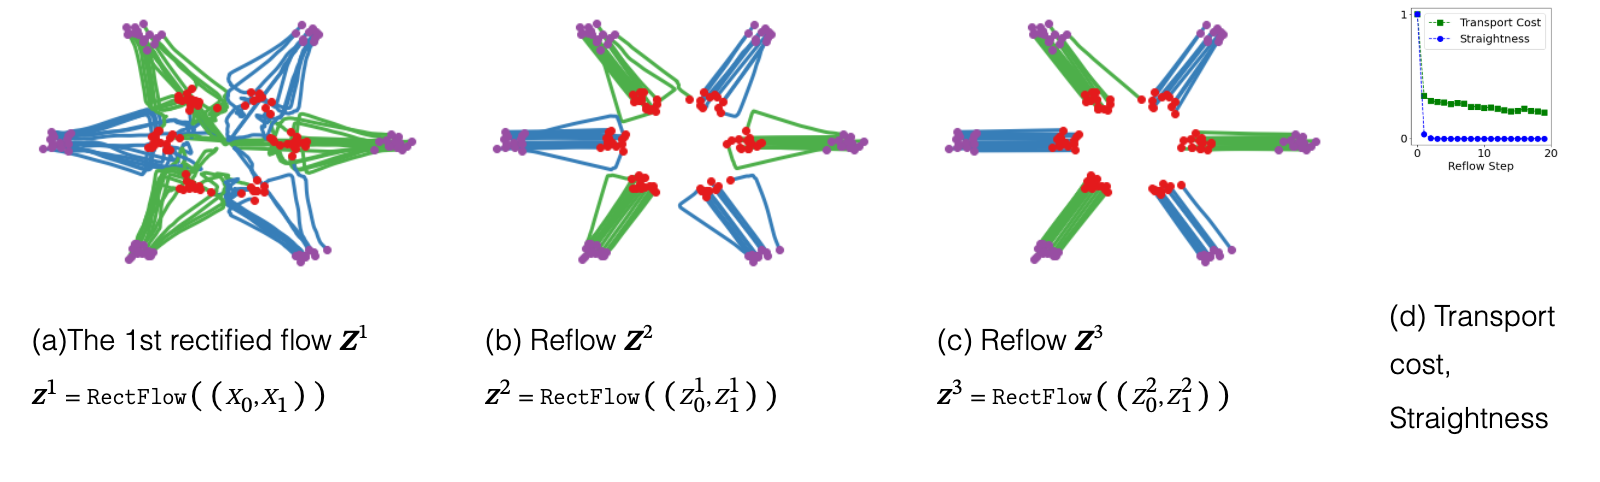
\text{ $\mathbb{E}[\left\lVert Z_{0}-Z_{1}\right\rVert]$ $=$ Length$\left(\vbox{\hbox{\includegraphics[height=25.83325pt]{arxiv_figures/=.png}}}\right)$ $\overset{\scriptsize(*)}{\leq}$ Length$\left(\vbox{\hbox{\includegraphics[height=25.83325pt]{arxiv_figures/v2.png}}}\right)$ $\overset{\scriptsize(**)}{=}$ Length$\left(\vbox{\hbox{\includegraphics[height=25.83325pt]{arxiv_figures/x.png}}}\right)$ $=$ ${\mathbb{E}[\left\lVert X_{0}-X_{1}\right\rVert]}$ },As shown in Figure 3, when we recursively apply the procedure , the paths of the -rectified flow are increasingly straight, and hence easier to simulate numerically, as increases. This straightening tendency can be guaranteed theoretically.
Specifically, we say that a flow is straight if we have almost surely that for , or equivalently following each path. (More precisely, “straight” here refers to straight with a constant speed.) Such straight flows are highly attractive computationally as it is effective a one-step model: a single Euler step update calculates the exact from . Note that the linear interpolation is straight by this definition but it is not a (causal) flow and hence can not be simulated without an oracle assess to draws of both and . In comparison, it is non-trivial to make a flow straight, because if so must satisfy the inviscid Burgers’ equation :
More generally, we can measure the straightness of any continuously differentiable process by
means exact straightness. A flow whose is small has nearly straight paths and hence can be simulated accurately using numerical solvers with a small number of discretization steps. Section 3.3 shows that applying rectification recursively provably decreases towards zero.
[Theorem 3.7] Let be the -th rectified flow induced from . Then
As shown Figure 1, applying one step of reflow can already provide nearly straight flows that yield good performance when simulated with a single Euler step. It is not recommended to apply too many reflow steps as it may accumulate estimation error on .
After obtaining the -th rectified flow , we can further improve the inference speed by distilling the relation of into a neural network to directly predict from without simulating the flow. Given that the flow is already nearly straight (and hence well approximated by the one-step update), and the distillation can be done efficiently. In particular, if we take , then the loss function for distilling is , which is the term in (1) when .
We should highlight the difference between distillation and rectification: distillation attempts to faithfully approximate the coupling while rectification yields a different coupling with lower transport cost and more straight flow. Hence, distillation should be applied only in the final stage when we want to fine-tune the model for fast one-step inference.
If yields a conditional density function \rho(x_{0}\penalty\ |\penalty\ x_{1}) when conditioned on then the optimal velocity field can be represented by
\begin{aligned}\displaystyle v^{X}(z,t)=\mathbb{E}\left[\frac{X_{1}-z}{1-t}\eta_{t}(X_{1},z)\right], & & \displaystyle\eta_{t}(X_{1},z)={\rho\left(\frac{z-tX_{1}}{1-t}\penalty\ \bigg|\penalty\ X_{1}\right)}\bigg/{\mathbb{E}\left[\rho\left(\frac{z-tX_{1}}{1-t}\penalty\ \bigg|\penalty\ X_{1}\right)\right]},\end{aligned}\tag{(4)}where the expectation is taken w.r.t. . This can be seen by noting that and , when conditioned on . Hence, if is positive and continuous everywhere, then is well defined and continuous on . Further, if is continuously differentiable w.r.t. , we can show that
Note that is guaranteed to have a unique solution if is uniformly Lipschitz continuous on for any .
If does not yield a conditional density function, may be undefined or discontinuous, making the ODE ill-behaved. A simple fix is to add with a Gaussian noise independent of to yield a smoothed variable , and transfer to using rectified flow. This would effectively give a randomized mapping of form transporting to .
Following (4), we can exactly calculate if the conditional density function exists and is known, and is the empirical measure of a finite number of points (whose expectation can be evaluated exactly). In this case, running the rectified flow forwardly would precisely recover the points in . This, however, is not practically useful in most cases as it completely overfits the data. Hence, it is both necessary and beneficial to fit with a smooth function approximator such as neural network or non-parametric models, to obtain smoothed distributions with novel samples that are practically useful.
Deep neural networks are no doubt the best function approximators for large scale problems. For low dimensional problems, the following simple Nadaraya–Watson style non-parametric estimator of can yield a good approximation to the exact rectified flow without knowing the conditional density :
where , and is a smoothing kernel with a bandwith parameter that measures the similarity between and . Taking the Gaussian RBF kernel , then when , it can be shown that converges to v^{X}(z,t)=\mathbb{E}\left[\frac{X_{1}-z}{1-t}\penalty\ |\penalty\ X_{t}=z\right] on points that can be attained by (i.e., the conditional expectation \mathbb{E}\left[\cdot\penalty\ |\penalty\ X_{t}=z\right] exists. ). On points that can not attain, extrapolates the value by finding the that is close to . In practice, we replace the expectations in (5) with empirical averaging. We find that performs well in practice because it is a mixture of linear functions that always point to a point in the support of .
We present a nonlinear extension of rectified flow in which the linear interpolation is replaced by any time-differentiable curve connecting and . Such generalized rectified flows can still transport to (Theorem 3.3), but no longer guarantee to decrease convex transport costs, or have the straightening effect. Importantly, the method of probability flows [73] and DDIM [70] can be viewed (approximately) as special cases of this framework, allows us to clarify the connection with and the advantages over these methods.
Let be any time-differentiable random process that connects and . Let be the time derivative of . The (nonlinear) rectified flow induced from is defined as
\displaystyle\mathrm{d}Z_{t}=v^{{\boldsymbol{X}}}(Z_{t},t)\mathrm{d}t,\penalty\ \penalty\ \penalty\ \text{with}\penalty\ \penalty\ \penalty\ \penalty\ Z_{0}=X_{0},\penalty\ \penalty\ \penalty\ \penalty\ \text{and}\penalty\ \penalty\ \penalty\ \penalty\ v^{{\boldsymbol{X}}}(z,t)=\mathbb{E}\left[\dot{X}_{t}\penalty\ |\penalty\ X_{t}=t\right].We can estimate by solving
\displaystyle\min_{v}\int_{0}^{1}\mathbb{E}\left[w_{t}\left\lVert v(X_{t},\penalty\ t)-\dot{X}_{t}\right\rVert^{2}\right]\mathrm{d}t,\tag{(6)}where is a positive weighting sequence ( by default). When using the linear interpolation , we have and (6) with reduces to (1). As we show in Theorem 3.3, the flow given by this method still preserves the marginal laws of , that is, , , and hence remains to be a coupling of . However, if is not straight, no longer guarantees to decrease the convex transport costs over . More importantly, the reflow procedure no longer straightens the paths of .
A simple class of interpolation processes is where and are two differentiable sequences that satisfy and to ensure that the process equals at the starting and end points. In this case, we have in (6) where and are the time derivatives of and . The shape of the curve is controlled by the relation of and . If we take for all , then have straight paths but does not travel at a constant speed; it can be viewed as a time-changed variant of the canonical case when is reparameterized to . When , the paths of are not straight lines except some special cases (e.g., or , or for some ).
The probability flow ODEs (PF-ODEs) [73] and denoising diffusion implicit models (DDIM) [70] are methods for learning ODE-based generative models of from a spherical Gaussian initial distribution , derived by converting a SDE learned by denoising diffusion methods to an ODE with equivalent marginal laws. In [73], three types of PF-ODEs are derived from three types of SDEs learned as score-based generative models, including variance-exploding (VE) SDE, variance-preserving (VP) SDE, and sub-VP SDE, which we denote by VE ODE, VP ODE, and sub-VP ODE, respectively. VP ODE is equivalent to the continuous time limit of DDIM, which is derived from the denoising diffusion probability model (DDPM) [23]. As the derivations of PF-ODEs and DDIM require advanced tools in stochastic calculus, we limit our discussion on the final algorithmic procedures suggested in [73, 23], which we summarize in Section 3.5. The readers are referred to [73, 70] for the details.
[Proposition 3.11] All variants of PF-ODEs can be viewed as instances of (6) when using for some with , where is a standard Gaussian random variable.
Here we need to use introduce to replace because the choices of and suggested in [73, 70, 23] do not satisfy the boundary condition of and at , and hence . Instead, in these methods, the initial distribution is implicitly defined as , which is approximated by by making . Hence, is set to be in these methods. Viewed through our framework, there is no reason to restrict to be , or not set to avoid the approximation.
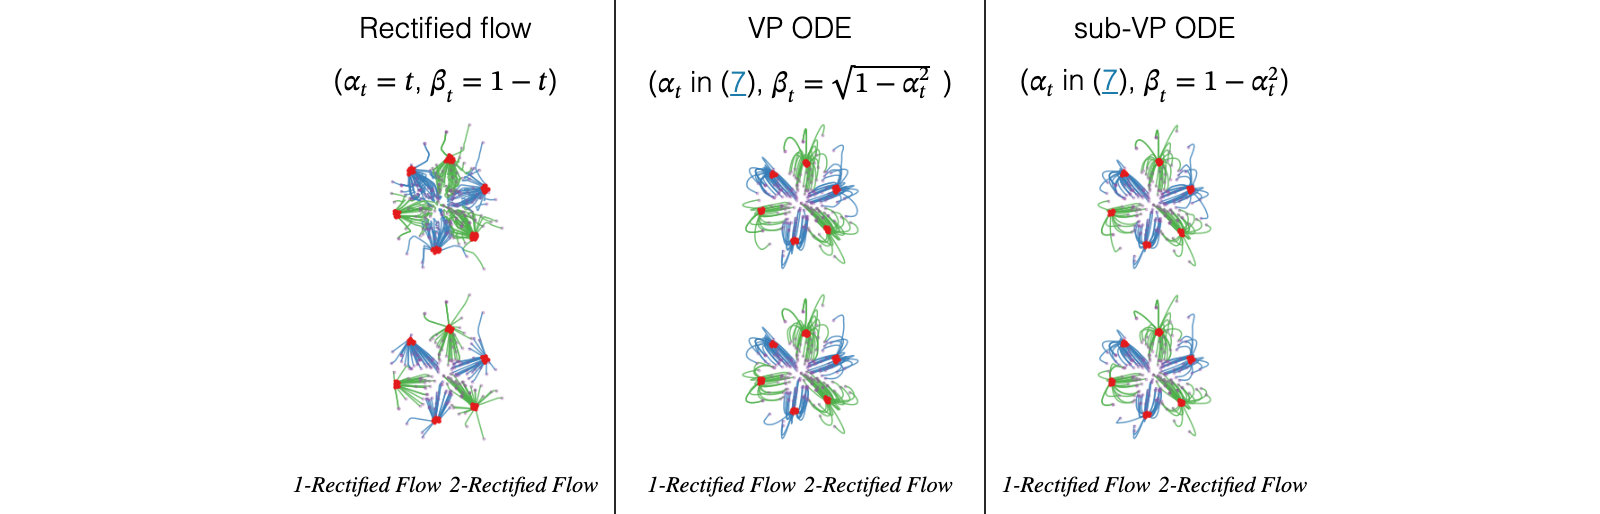
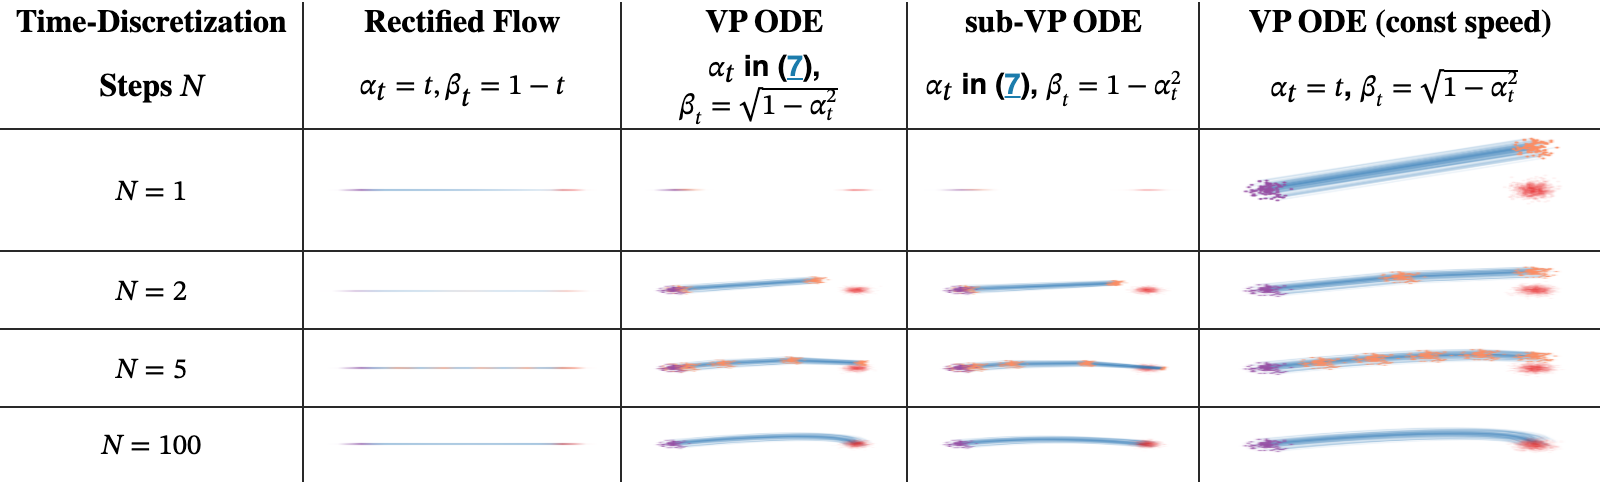
The VP ODE and sub-VP ODE of [73] use the following shared :
\begin{aligned}\displaystyle\text{(sub-)VP ODE:}\penalty\ \penalty\ \penalty\ \penalty\ \alpha_{t}=\exp\left(-\frac{1}{4}a(1-t)^{2}-\frac{1}{2}b(1-t)\right); & & a=19.9 b=0.1\end{aligned}\tag{(7)}where the default values of are chosen to match the continuous time limit of the shared training procedure of DDIM and DDPM. The difference of VP ODE and sub-VP ODE is on the choice of , given as follows:
\begin{aligned}\displaystyle\text{VP ODE:\penalty\ \penalty\ \penalty\ }\beta_{t}=\sqrt{1-\alpha_{t}^{2}}, & & \displaystyle\text{sub-VP ODE:\penalty\ \penalty\ \penalty\ }\beta_{t}={1-\alpha_{t}^{2}}.\end{aligned}\tag{(8)}As in both VP and sub-VP ODE, the in both cases are taken as .
The choices of above are the consequence of the SDE-based derivation in [73]. However, they are not well-motivated when we exam the path properties of the induced ODEs:
Non-straight paths: Due to choices of in (8), the trajectories of VP ODE and sub-VP ODE are curved in general, and can not be straightened by the reflow procedure. We should choose to induce straight paths.
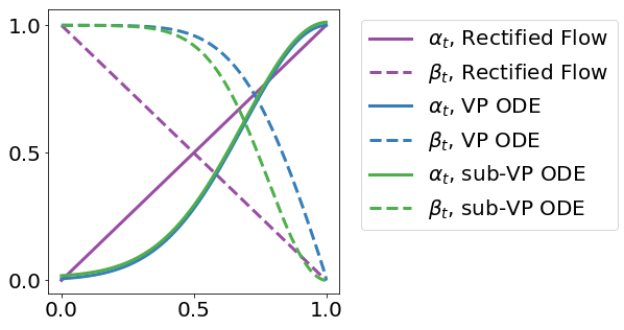
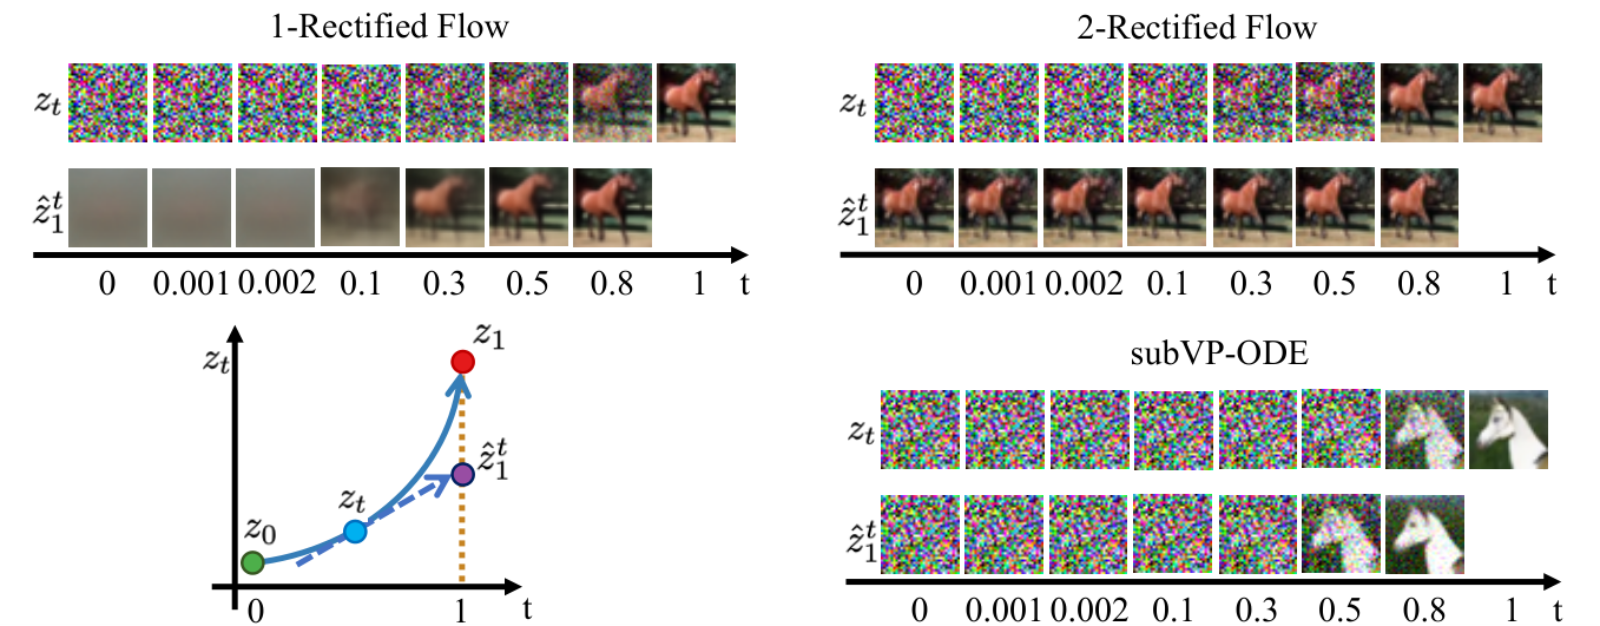
Non-uniform speed: The exponential form of in (7) is a consequence of using Ornstein–Uhlenbeck processes in the derivation of SDE models [73, 23]. However, there is no clear advantage of using (7) for ODEs. As shown in Figure 5, the and of VP and sub-VP ODE change slowly in the early phase (). As a result, the flow also moves slowly in beginning and hence most of the updates are concentrated in the later phase. Such non-uniform update speed, in addition to the non-straight paths, make VP ODE and sub-VP ODE perform sub-optimally when using large step sizes, even for transport between simple spherical Gaussian distributions (see Figure 5). As we show in the last column of Figure 5, changing the exponential to the linear function in VP ODE allows us to get a uniform update speed while preserving the same continuous-time trajectories.
The VE ODE of [73] uses and where by default is set such that is as large as the maximum Euclidean distance between all pairs of training data points from (Technique 1 of [72]). Assume that is much larger than both and the variance of , then , and we can set the initial distribution to be , which has much larger variance than . Hence, VE ODE can not be applied to (and not shown in) the toys in Figure 4 and Figure 5. As the case of (sub-)VP ODE, the restriction on is in fact unnecessary and requirement that is unnatural viewed from our framework. On the other hand, the trajectories of in VE ODE are indeed straight lines, because the direction of is always the same as . However, the choice of causes a non-uniform speed issue similar to that of (sub-)VP ODE.
Following [73, 23], a line of works have been proposed to improve the choices of , but remain to be constrained by the basic design space from the SDE-to-ODE derivation; see for example [54, 29, 95].
To summarize, the simple nonlinear rectified flow framework in (6) both simplifies and extends the existing framework, and sheds a number of importance insights:
Learning ODEs can be considered directly and independently without resorting to diffusion/SDE methods;
The paths of the learned ODEs can be specified by any smooth interpolation curve of and ;
The initial distribution can be chosen arbitrarily, independent with the choice of the interpolation .
The canonical linear interpolation should be recommended as a default choice.
On the other hand, non-linear choices of can be useful when we want to incorporate certain non-Euclidan geometry structure of the variable, or want to place certain constraints on the trajectories of the ODEs. We leave this for future works.
We present the theoretical analysis for rectified flow. The results are summarized as follows.
[Section 3.1] All nonlinear rectified flows with any interpolation preserve the marginal laws.
[Section 3.2] The rectified flow (with the canonical linear interpolation) reduces convex transport costs.
[Section 3.3] Reflow guarantees to straighten the (linear) rectified flows.
[Section 3.4] We clarify the relation between straight couplings and -optimal couplings.
[Section 3.5] We establish PF-ODEs as instances of nonlinear rectified flows.
The marginal preserving property that for is a general property of the nonlinear rectified flows in (6), regardless whether the interpolation is straight or not.
For a path-wise continuously differentiable random process , its expected velocity is defined as
v^{{\boldsymbol{X}}}(x,t)=\mathbb{E}[\dot{X}_{t}\penalty\ |\penalty\ X_{t}=x],\penalty\ \penalty\ \penalty\ \penalty\ \penalty\ \forall x\in\mathrm{supp}(X_{t}).For , the conditional expectation is not defined and we set arbitrarily, say .
We call that is rectifiable if is locally bounded and the solution of the integral equation below exists and is unique:
\displaystyle Z_{t}=Z_{0}+\int_{0}^{t}v^{{\boldsymbol{X}}}(Z_{t},t)\mathrm{d}t,\penalty\ \penalty\ \penalty\ \penalty\ \forall t\in[0,1],\penalty\ \penalty\ \penalty\ \penalty\ Z_{0}=X_{0}.\tag{(9)}In this case, is called the rectified flow induced from .
Assume is rectifiable and is its rectified flow. Then for .
For any compactly supported continuously differentiable test function , we have
where we used . By definition, this is equivalent to that solves in the sense of distributions the continuity equation with drift :
where we use integration by parts that .
Because is driven by the same velocity field , its marginal law solves the very same equation with the same initial condition (). Hence, the equivalence of and follows if the solution of (11) is unique, which is equivalent to the uniqueness of the solution of following Corollary 1.3 of Kurtz 37 (see also Theorem 4.1 of Ambrosio and Crippa 1). ∎
The fact that yields no larger convex transport costs than is a consequence of using the special linear interpolation as the geodesic of Euclidean space.
A coupling is called rectifiable if its linear interpolation process is rectifiable. In this case, the in (9) is called the rectified flow of coupling , denoted as , and is called the rectified coupling of , denoted as
Assume is rectifiable and . Then for any convex function , we have
The proof is based on elementary applications of Jensen’s inequality.
\begin{aligned}\displaystyle\mathbb{E}\left[c(Z_{1}-Z_{0})\right] & \displaystyle=\mathbb{E}\left[c\left(\int_{0}^{1}v^{{\boldsymbol{X}}}(Z_{t},t)\mathrm{d}t\right)\right]\penalty\ \penalty\ \penalty\ \penalty\ \penalty\ \penalty\ \penalty\ \text{{\color[rgb]{1,0,1}//as $\mathrm{d}Z_{t}=v^{{\boldsymbol{X}}}(Z_{t},t)\mathrm{d}t$}}\end{aligned}\begin{aligned} & \displaystyle\leq\mathbb{E}\left[\int_{0}^{1}c\left(v^{{\boldsymbol{X}}}(Z_{t},t)\right)\mathrm{d}t\right]\penalty\ \penalty\ \penalty\ \penalty\ \penalty\ \penalty\ \penalty\ \text{{\color[rgb]{1,0,1}//convexity of $c$, Jensen's inequality}}\end{aligned}\begin{aligned} & \displaystyle=\mathbb{E}\left[\int_{0}^{1}c\left(v^{{\boldsymbol{X}}}(X_{t},t)\right)\mathrm{d}t\right]\penalty\ \penalty\ \penalty\ \penalty\ \penalty\ \penalty\ \penalty\ \text{{\color[rgb]{1,0,1}//$X_{t}$ and $Z_{t}$ shares the same marginals}}\end{aligned}\begin{aligned} & \displaystyle=\mathbb{E}\left[\int_{0}^{1}c\left(\mathbb{E}\left[(X_{1}-X_{0})\penalty\ |\penalty\ X_{t}\right]\right)\mathrm{d}t\right]\penalty\ \penalty\ \penalty\ \penalty\ \penalty\ \penalty\ \penalty\ \text{{\color[rgb]{1,0,1}//definition of $v^{{\boldsymbol{X}}}$}}\end{aligned}\begin{aligned} & \displaystyle\leq\mathbb{E}\left[\int_{0}^{1}\mathbb{E}\left[c\left(X_{1}-X_{0}\right)|\penalty\ X_{t}\right]\mathrm{d}t\right]\penalty\ \penalty\ \penalty\ \penalty\ \penalty\ \penalty\ \penalty\ \text{{\color[rgb]{1,0,1}//convexity of $c$, Jensen's inequality}}\end{aligned}\begin{aligned} & \displaystyle=\int_{0}^{1}\mathbb{E}\left[c\left(X_{1}-X_{0}\right)\right]\mathrm{d}t\penalty\ \penalty\ \penalty\ \penalty\ \penalty\ \penalty\ \penalty\ \text{{\color[rgb]{1,0,1}//$\mathbb{E}[\mathbb{E}[(X_{1}-X_{0})|X_{t}]]=\mathbb{E}[(X_{1}-X_{0})]$}}\end{aligned}∎
If is straight but with positive non-constant speed, that is, with and , then we still have if is convex and -homogeneous in that for , with some constant .
A coupling is said to be straight (or fully rectified) if it is a fixed point of the mapping. It is desirable to obtain a straight coupling because its rectified flow is straight and hence can be simulated exactly with one step using numerical solvers. In this section, we first characterize the basic properties of straight couplings, showing that a coupling is straight iff its linear interpolation paths do not intersect with each other. Then, we prove that recursive rectification straightens the coupling and its related flow with a rate, where is the number of rectification steps.
Assume is rectifiable. Let and . Then is a straight coupling iff the following equivalent statements hold.
- 1.
There exists a strictly convex function , such that .
- 2.
is a fixed point of , that is, .
- 3.
The rectified flow coincides with the linear interpolation process: .
- 4.
The paths of the linear interpolation do not intersect:
\displaystyle\hskip-17.25105ptV((X_{0},X_{1})):=\int_{0}^{1}\mathbb{E}\left[\left\lVert X_{1}-X_{0}-\mathbb{E}\left[X_{1}-X_{0}\penalty\ |\penalty\ X_{t}\right]\right\rVert^{2}\right]\mathrm{d}t=0,\tag{(12)}where indicates that almost surely when , meaning that the lines passing through each is unique, and hence no linear interpolation paths intersect.
: Obvious.
: If , the two applications of Jensen’s inequality in the proof of Theorem 3.5 are tight. Because is strictly convex, the second Jensen’s inequality in the proof implies that X_{1}-X_{0}=\mathbb{E}[X_{1}-X_{0}\penalty\ |\penalty\ X_{t}] almost surely w.r.t. and which implies that
: If , we have for . Hence
Because satisfies the same equation (9), we have by the uniqueness of the solution.
∎
We now show that as we apply rectification recursively, the rectified flows become increasingly straight and the linear interpolation of the couplings becomes increasingly non-intersecting.
Let the -th rectified flow of , that is, and . Assume each is rectifiable for .
Then
Hence, , we have .
Taking in the proof of Theorem 3.5, we can obtain that
Applying it to each rectification step yields
A telescoping sum on gives the result.
∎
A coupling is called -optimal if it achieves the minimum of among all couplings that share the same marginals. Understanding and computing the optimal couplings have been the main focus of optimal transport [84, 2, 15, 59, e.g.,]. Straight couplings is a different desirable property. In the following, we show that straightness is a necessary but not sufficient condition of being -optimal for a strictly convex function , except in the one dimensional case when the two concepts coincides. Hence, it is “easier” to find a straight coupling than a -optimal couplings.
If a rectifiable coupling is -optimal for some strictly convex cost function , then is a straight coupling.
Let . If is -optimal, we must have . This implies Statement 1 in Theorem 3.6 and hence that is straight. ∎
For any on , there exists an unique coupling that is simultaneously optimal for all non-negative convex cost functions . This coupling is uniquely characterized by a monotonic property: for every and in the support of , if , then . Furthermore, if is absolutely continuously w.r.t. the Lebesgue measure, then must be deterministic in that there exists a mapping such that . See [65].
In the following, we show that straight couplings on coincides with the deterministic monotonic coupling and hence is unique and simultaneously optimal for all convex when is absolutely continuous. The idea is that, in , a coupling is monotonic iff its linear interpolation paths do not intersect, a characteristic feature of straight couplings.
A coupling on is straight iff it is deterministic and monotonic.
For any on , there exists either no straight coupling, or a unique straight coupling. Further, if exists, the unique straight coupling is deterministic and monotonic, and jointly optimal w.r.t. all convex cost functions for which the minimum value of exists and is finite.
If on is straight, then it coincides with its rectified coupling But because is induced from the rectified flow , it is obviously deterministic. It is also monotonic due to the non-crossing property of flows. Specifically, if is not monotonic, there exists and in the support of such that and . If this happens, there must exists , such that . But by the uniqueness of the solution, we have for , which is conflicting with .
Assume is deterministic and monotonic. Due to the monotonicity, there exists no and in the support of , such that and for some . This suggests that X_{1}-X_{0}=\mathbb{E}[X_{1}-X_{0}\penalty\ |\penalty\ X_{t}]=v^{X}(X_{t},t) for , and hence , which is the ODE of the rectified flow. In addition, is obviously the unique solution of this ODE. Hence is rectifiable and straight following Statement 3 of Theorem 3.6. ∎
On the other hand, on with , the different cost functions do not share a common optimal coupling in general, and a straight coupling is not guaranteed to optimize a specific ; this is expected because the procedure does not depend on a particular choice of . Hence, one must modify the procedure to tailor it to a specific of interest.
In a recent work [30], it was conjectured that the couplings induced from VP ODE (equivalently DDIM) yields an optimal coupling w.r.t. the quadratic loss, which was proved to be false in [39, 78]. Here we show that even straight couplings are not guaranteed to be optimal, not to mention that VP ODE does not follow straight paths by design.
We explore this in a separate work [42] that is devoted to modifying rectified flow to find -optimal couplings; a result from [42] that can be easily stated is that the optimal coupling w.r.t. the quadratic cost can be achieved as the fixed point of if is restricted to be a gradient field of form when solving (1). Restricting to be a gradient field removes the rotational component of the velocity field that causes sub-optimal transport cost.
We prove that the probability flow ODEs (PF-ODEs) of [73] can be viewed as nonlinear rectified flows in (6) with We start with introducing the algorithmic procedures of the denoising diffusion models and PF-ODEs, and refer the readers to the original works [73, 23, 70] for the theoretical derivations.
The denoising diffusion methods learn to generative models by constructing an SDE model driven by a standard Brownian motion :
\displaystyle\mathrm{d}U_{t}=b(U_{t},t)\mathrm{d}t+\sigma_{t}\mathrm{d}W_{t},\penalty\ \penalty\ \penalty\ U_{0}\sim{\pi}_{0},\tag{(14)}where is a (typically) fixed diffusion coefficient, is a trainable neural network, and the initial distribution is restricted to a spherical Gaussian distribution determined by hyper-parameter setting of the algorithm. The idea is to first collapse the data into an (approximate) Gaussian distribution using a diffusion process, mostly an Ornstein-Uhlenbeck (OU) process, and then estimate the generative diffusion process (14) as the time reversal [3, e.g.,] of the collapsing process.
Without diving into the derivations, the training loss of the VE, VP, sub-VP SDEs for in [73] can be summarized as follows:
where is a diffusion process satisfying , and are the hyper-parameter sequences of the algorithm, and are determined by via
\displaystyle\alpha_{t}=\exp\left(\int_{t}^{1}\eta_{s}\mathrm{d}s\right),\penalty\ \penalty\ \penalty\ \penalty\ \penalty\ \beta_{t}^{2}=\int_{t}^{1}\exp\left(2\int_{t}^{s}\eta_{r}\mathrm{d}r\right)\sigma_{s}^{2}\mathrm{d}s.\tag{(16)}The relation in (16) is derived to make follow the Ornstein-Uhlenbeck (OU) processes .
VE SDE, which is equivalent to SMLD in [71, 72], takes and hence has . (sub-)VP SDE takes to be a linear function of , yielding the exponential in (7). VP SDE (which is equivalent to DDPM [23]) takes which yields that as shown in (8). In DDPM, it was suggested to write , and estimate as a neural network that predicts from .
Theoretically, the SDE in (14) with solving (15) is ensured to yield when initialized from , which can be approximated by when .
By using the properties of Fokker-Planck equations, it was observed in [73, 70] that the SDE in (14) with trained in (15) can be converted into an ODE that share the same marginal laws:
\displaystyle\mathrm{d}Z_{t}=\tilde{b}(Z_{t},t)\mathrm{d}t,\penalty\ \penalty\ \penalty\ \penalty\ \text{with}\penalty\ \penalty\ \penalty\ \penalty\ \tilde{b}(z,t)=\frac{1}{2}(b(z,t)-\eta_{t}z),\penalty\ \penalty\ \penalty\ \penalty\ \text{starting from\penalty\ \penalty\ }Z_{0}=U_{0}=\alpha_{0}X_{1}+\beta_{0}\xi_{0}.\tag{(17)}Equivalently, we can regard as the solution of
which defers from (14) only by a factor of in the second term of . This simple equivalence holds only when (14) and (17) use the special initialization of .
In the following, we are ready to prove that (18) is can be viewed as the nonlinear rectified flow objective in (6) using with . We mainly need to show that is equivalent to by eliminating and using the relation in (16).
First, note that we can take for all time , as the correlation structure of does not impact the result. Hence, we have . To show the equivalence of (18) and (6), we just need to verify that .
where in we used that and which can be derived from (16). ∎
GANs [19, 4, 43], VAEs [32], and (discrete-time) normalizing flows [62, 13, 14] have been three classical approaches for learning deep generative models. GANs have been most successful in terms of generation qualities (for images in particular), but suffer from the notorious training instability and mode collapse issues due to use of minimax updates. VAEs and normalizing flows are both trained based on the principle of maximum likelihood estimation (MLE) and need to introduce constraints on the model architecture and/or special approximation techniques to ensure tractable likelihood computation: VAEs typically use a conditional Gaussian distribution in addition to the variational approximation of the likelihood; normalizing flows require to use specially designed invertible architectures and need to copy with calculating expensive Jacobian matrices.
The reflow+distillation approach in this work provides another promising approach to training one-step models, avoiding the minimax issues of GANs and the intractability issues of the likelihood-based methods.
There are two major approaches for learning neural ODEs: the PF-ODEs/DDIM approach discussed in Section 2.3, and the more classical MLE based approach of [6].
The MLE approach. In [6], neural ODEs are trained for learning generative models by maximizing the likelihood of the distribution of the ODE outcome at time under the data distribution . Specifically, with observations from , it estimates a neural drift of an ODE by
\displaystyle\max_{v}\mathbb{D}({\pi}_{1};\penalty\ \penalty\ \rho^{v,{\pi}_{0}}),\tag{(19)}where \mathbb{D}(\cdot;\penalty\ \cdot) denotes KL divergence (or other discrepancy measures), and is the density of following from ; the density of should be known and tractable to calculate.
By using an instantaneous change of variables formula, it was observed in [6] that the likelihood of neural ODEs are easier to compute than the discrete-time normalizing flow without constraints on the model structures. However, this MLE approach is still computationally expensive for large scale models as it requires repeated simulation of the ODE during each training step. In addition, as the optimization procedure of MLE requires to backpropagate through time, it can easily suffer the gradient vanishing/exploding problem unless proper regularization is added.
Another fundamental problem is that the MLE (19) of neural ODEs is theoretically under-specified, because MLE only concerns matching the law of the final outcome with the data distribution , and there are infinitely many ODEs to achieve the same output law of while traveling through different paths. A number of works have been proposed to remedy this by adding regularization terms, such as these based on transport costs, to favor shorter paths; see [54, 55]. With a regularization term, the ODE learned by MLE would be implicitly determined by the initialization and other hyper-parameters of the optimizer used to solve (19).
Probability Flow ODEs. The method of PF-ODEs [73] and DDIM [70] provides a different approach to learning ODEs that avoids the main disadvantages of the MLE approach, including the expensive likelihood calculation, training-time simulation of the ODE models, and the need of backpropagation through time. However, because PF-ODEs and DDIM were derived as the side product of learning the mathematically more involved diffusion/SDE models, their theories and algorithm forms were made unnecessarily restrictive and complicated. The nonlinear rectified flow framework shows that the learning of ODEs can be approached directly in a very simple way, allowing us to identify the canonical case of linear rectified flow and open the door of further improvements with flexible and decoupled choices of the interpolation curves and initial distributions
Viewed through the general non-linear rectified flow framework, the computational and theoretical drawbacks of MLE can be avoided because we can simply pre-determines the “roads” that the ODEs should travel through by specifying the interpolation curve , rather than leaving it for the algorithm to figure out implicitly. It is theoretically valid to pre-specify any interpolation because the neural ODE is highly over-parameterized as a generative model: when is a universal approximator and is absolutely continuous, the distribution of can approximate any distribution given any fixed interpolation curve . The idea of rectified flow is to the simplest geodesic paths for .
Although the scope of this work is limited to learning ODEs, the score-based generative models [71, 72, 73, 74] and denoising diffusion probability models (DDPM) [23] are of high relevance as the basis of PF-ODEs and DDIM. The diffusion/SDE models trained with these methods have been found outperforming GANs in image synthesis in both quality and diversity [12]. Notably, thanks to the stable and scalable optimization-based training procedure, the diffusion models have successfully used in huge text-to-image generation models with astonishing results [53, 61, 64, e.g.,]. It has been quickly popularized in other domains, such as video [24, 92, 21, e.g.,], music [51], audio [33, 40, 60, e.g.,], and text [41, 88], and more tasks such as image editing [97, 50]. A growing literature has been developed for improving the inference speed of denoising diffusion models, an example of which is the PF-ODEs/DDIM approach which gains speedup by turning SDEs into ODEs. We provide below some examples of recent works, which is by no mean exhaustive.
Improved training and inference. A line of works focus on improving the inference and sampling procedure of denoising diffusion models. For example, [54] presents a few simple modifications of DDPM to improve the likelihood, sampling speed, and generation quality. [29] systematic exams the design space of diffusion generative models with empirical studies and identifies a number of training and inference recipes for better generative quality with fewer sampling steps. [94] proposes a diffusion exponential integrator sampler for fast sampling of diffusion models. [46] provides a customized high order solver for PF-ODEs. [5] provides an analytic estimate of the optimal diffusion coefficient.
Combination with other methods. Another direction is to speed up diffusion models by combining them with GANs and other generative models. DDPM Distillation [47] accelerates the inference speed by distilling the trajectories of a diffusion model into a series of conditional GANs. The truncated diffusion probabilistic model (TDPM) of [99] trains a GAN model as so that the diffusion process can be truncated to improve the speed; the similar idea was explored in [48, 18], and [18] provides an analysis on the optimal truncation time. [68, 89, 81] learns a denoising diffusion model in the latent spaces and combines it with variational auto-encoders. These methods can be potentially applied to rectified flow to gain similar speedups for learning neural ODEs.
Unpaired Image-to-Image translation. The standard denoising diffusion and PF-ODEs methods focus on the generative task of transferring a Gaussian noise () to the data (). A number of works have been proposed to adapt it to transferring data between arbitrary pairs of source-target domains. For example, SDEdit [50] synthesizes realistic images guided by an input image by first adding noising to the input and then denoising the resulting image through a pre-trained SDE model. [8] proposes a method to guide the generative process of DDPM to generate realistic images based on a given reference image. [75] leverages two two PF-ODEs for image translation, one translating source images to a latent variable, and the other constructing the target images from the latent variable. [97] proposes an energy-guided approach that employs an energy function pre-trained on the source and target domains to guide the inference process of a pretrained SDE for better image translation. In comparison, our framework shows that domain transfer can be achieved by essentially the same algorithm as generative modeling, by simply setting to be the source domain.
Diffusion bridges. Some recent works [57, 44] show that the design space of denoising diffusion models can be made highly flexible with the assistant of diffusion bridge processes that are pinned to a fixed data point at the end time. This reduces the design of denoising diffusion methods to constructing a proper bridge processes. The bridges in Song et al. 73 are constructed by a time-reversal technique, which can be equivalently achieved by Doob’s -transform as shown in [57, 44], and more general construction techniques are discussed in [44, 90]. Despite the significantly extended design spaces, an unanswered question is what type of diffusion bridge processes should be preferred. This question is made challenging because the presence of diffusion noise and the need of advanced stochastic calculus tools make it hard to intuit how the methods work. By removing the diffusion noise, our work makes it clear that straight paths should be preferred. We expect that the idea can be extended to provide guidance on designing optimal bridge processes for learning SDEs.
The introduction of diffusion noise was consider essential due to the key role it plays in the derivations of the successful methods [73, 23]. However, as rectified flow can achieve better or comparable results with a ODE-only framework, the role of diffusion mechanisms should be re-examed and clearly decoupled from the other merits of denoising diffusion models. The success of the denoising diffusion models may be mainly attributed to the simple and stable optimization-based training procedure that allows us to avoid the instability issues and the need of case-by-case tuning of GANs, rather than the presence of diffusion noises.
Because our work shows that there is no need to invoke SDE tools if the goal is to learn ODEs, the remaining question is whether we should learn an ODE or an SDE for a given problem. As already argued by a number of works [73, 70, 29], ODEs should be preferred over SDEs in general. Below is a detailed comparison between ODEs and SDEs.
Conceptual simplicity and numerical speed. SDEs are more mathematically involved and are more difficult to understand. Numerical simulation of ODEs are simpler and faster than SDEs.
Time reversibility. It is equally easy to solve the ODEs forwardly and backwardly. In comparison, the time reversal of SDEs [3, 22, 17, e.g.,] is more involved theoretically and may not be computationally tractable.
Latent spaces. The couplings of ODEs are deterministic and yield low transport cost in the case of rectified flows, hence providing a good latent space for representing and manipulating outputs. Introducing diffusion noises make more stochastic and hence less useful. In fact, the given by DDPM [23] and the SDEs of [73] and hence useless for latent presentation.
Training difficulty. There is no reason to believe that training an ODE is harder, if not easier, than training an SDE sharing the same marginal laws: the training loss of both cases would share the distributions of covariant and differ only on the targets. In the setting of [73], the two loss functions (15) and (18) are equivalent upto a linear reparameterization.
Expressive power. As every SDE can be converted into an ODE that has the same marginal distribution using the techniques in [70, 73] (see also [84]), ODEs are as powerful as SDEs for representing marginal distributions, which is what needed for the transport mapping problems considered in this work. On the other hand, SDEs may be preferred if we need to capture richer time-correlation structures.
Manifold data. When equipped with neural network drifts, the outputs of ODEs tend to fall into a smooth low dimensional manifold, a key inductive for structured data in AI such as images and text. In comparison, when using SDEs to model manifold data, one has to carefully anneal the diffusion noise to obtain smooth outcomes, which causes slow computation and a burden of hyperparameter tuning. SDEs might be more useful in for modeling highly noisy data in areas like finance and economics, and in areas that involve diffusion processes physically, such as molecule simulation.
Optimal transport has been extensively explored in machine learning as a powerful way to compare and transfer between probability measures. For the transport mapping problem considered in this work, a natural approach is to finding the optimal coupling that minimizes a transport cost for a given . The most common choice of is the quadratic cost .
However, finding the optimal couplings, especially for high dimensional continuous measures, is highly challenging computationally and is the subject of active research; see for example [67, 34, 35, 49, 63, 10]. In addition, although the optimal couplings are known to have nice smoothness and other regularity properties, it is not necessary to accurately find the optimal coupling because the transport cost do not exactly align with the learning performance of individual problems; see e.g., [34].
In comparison, our reflow procedure finds a straight coupling, which is not optimal w.r.t. a given (see Section 3.4). From the perspective of fast inference, all straight couplings are equally good because they all yield straight rectified flows and hence can be simulated with one Euler step.
We start by studying the impact of reflow on toy examples. After that, we demonstrate that with multiple times of reflow, rectified flow achieves state-of-the-art performance on CIFAR-10. Moreover, it can also generate high-quality images on high-resolution image datasets. Going beyond unconditioned image generation, we apply our method to unpaired image-to-image translation tasks to generate visually high-quality image pairs.
We follow the procedure in Algorithm 1. We start with drawing and use it to get the first rectified flow by minimizing (1). The second rectified flow is obtained by the same procedure except with the data replaced by the draws from , obtained by simulating the first rectified flow . This process is repeated for times to get the -rectified flow . Finally, we can further distill the -rectified flow into a one step model by fitting it on draws from .
By default, the ODEs are simulated using the vanilla Euler method with constant step size for steps, that is, for . We use the Runge-Kutta method of order 5(4) from Scipy [86], denoted as RK45, which adaptively decide the step size and number of steps based on user-specified relative and absolute tolerances. In our experiments, we stick to the same parameters as [73].
To accurately illustrate the theoretical properties, we use the non-parametric estimator in (5) in the toy examples in Figure 2, 3, 4, 5. In practice, we approximate the expectation in (5) an nearest neighbor estimator: given a sample drawn from , we estimate by
\begin{aligned}\displaystyle v^{X,h}(z,t)\approx\!\!\!\sum_{i\in\mathrm{knn}(z,m)}\!\!\!\frac{x_{1}^{(i)}-z}{1-t}\omega_{h}(x_{t}^{(i)},z)\penalty\ \penalty\ /\!\!\!\sum_{i\in\mathrm{knn}(z,m)}\!\!\!\!\!\omega_{h}(x_{t}^{(i)},z), & & \displaystyle x_{t}^{(i)}=tx_{1}^{(i)}+(1-t)x_{0}^{(i)},\end{aligned}where denotes the top nearest neighbors of in . We find that the results are not sensitive to the choice of and the bandwidth (see Figure 7). We use and by default. The flows are simulated using Euler method with a constant step size of for steps. We use steps unless otherwise specified.
Alternatively, can be parameterized as a neural network and trained with stochastic gradient descent or Adam. Figure 7 shows an example of when is parameterized as an 2-hidden-layer fully connected neural network with 64 neurons in both hidden layers. We see that the neural networks fit less perfectly with the linear interpolation trajectories (which should be piece-wise linear in this toy example). As shown in Figure 7, we find that enhancing the smoothness of the neural networks (by increasing the L2 regularization coefficient during training) can help straighten the flow, in addition to the rectification effect.
In Figure 3 of Section 2.2, the straightness is calculated as the empirical estimation of (3) based on the simulated trajectories. The relative transport cost is calculated based on drawn from by simulating the flow, as , where is the optimal L2 assignment of obtained by solving the discrete L2 optimal transport problem between and . We should note that this metric is only useful in low dimensions, as it tends to be identically zero in high dimensional cases even is set to be a random neural network. This misleading phenomenon is what causes [30] to make the false hypothesis that DDIM yields L2 optimal transport.
We test rectified flow for unconditioned image generation on CIAFR-10 and a number of high resolution datasets. The methods are evaluated by the quality of generated images by Fréchet inception distance (FID) and inception score (IS), and the diversity of the generated images by the recall score following [38].
For the purpose of generative modeling, we set to be the standard Gaussian distribution and the data distribution. Our implementation of rectified flow is modified upon the open-source code of [73]. We adopt the U-Net architecture of DDPM++ [73] for representing the drift , and report in Table 1 (a) and Figure 8 the results of our method and the (sub)-VP ODE from [73] using the same architecture. Other recent results using different network architectures are shown in Table 1 (b) for reference. More detailed settings can be found in the Appendix.
| Method | NFE() | IS () | FID () | Recall () ODE | One-Step Generation (Euler solver, N=1) 1-Rectified Flow (+Distill) | 1 | 1.13 (9.08) | 378 (6.18) | 0.0 (0.45) 2-Rectified Flow (+Distill) | 1 | 8.08 (9.01) | 12.21 (4.85) | 0.34 (0.50) 3-Rectified Flow (+Distill) | 1 | 8.47 (8.79) | 8.15 (5.21) | 0.41 (0.51) VP ODE [73] (+Distill) | 1 | 1.20 (8.73) | 451 (16.23) | 0.0 (0.29) sub-VP ODE [73] (+Distill) | 1 | 1.21 (8.80) | 451 (14.32) | 0.0 (0.35) ODE | Full Simulation (Runge–Kutta (RK45), Adaptive ) 1-Rectified Flow | 127 | 9.60 | 2.58 | 0.57 2-Rectified Flow | 110 | 9.24 | 3.36 | 0.54 3-Rectified Flow | 104 | 9.01 | 3.96 | 0.53 VP ODE [73] | 140 | 9.37 | 3.93 | 0.51 sub-VP ODE [73] | 146 | 9.46 | 3.16 | 0.55 SDE | Full Simulation (Euler solver, N=2000) VP SDE [73] | 2000 | 9.58 | 2.55 | 0.58 sub-VP SDE [73] | 2000 | 9.56 | 2.61 | 0.58 | Method | NFE() | IS () | FID () | Recall () GAN | One-Step Generation SNGAN [52] | 1 | 8.22 | 21.7 | 0.44 StyleGAN2 [28] | 1 | 9.18 | 8.32 | 0.41 StyleGAN-XL [66] | 1 | - | 1.85 | 0.47 StyleGAN2 + ADA [28] | 1 | 9.40 | 2.92 | 0.49 StyleGAN2 + DiffAug [98] | 1 | 9.40 | 5.79 | 0.42 TransGAN + DiffAug [26] | 1 | 9.02 | 9.26 | 0.41 GAN with U-Net | One-step Generation TDPM (T=1) [99] | 1 | 8.65 | 8.91 | 0.46 Denoising Diffusion GAN (T=1) [91] | 1 | 8.93 | 14.6 | 0.19 ODE | One Step Generation (Euler solver, N=1) DDIM Distillation [47] | 1 | 8.36 | 9.36 | 0.51 NCSN++ (VE ODE) [73] (+Distill) | 1 | 1.18 (2.57) | 461 (254) | 0.0 (0.0) ODE | Full Simulation (Runge–Kutta (RK45), Adaptive ) NCSN++ (VE ODE) [73] | 176 | 9.35 | 5.38 | 0.56 SDE | Full Simulation (Euler solver) DDPM [23] | 1000 | 9.46 | 3.21 | 0.57 NCSN++ (VE SDE) [73] | 2000 | 9.83 | 2.38 | 0.59 |
| (a) Results using the DDPM++ architecture. | (b) Recent results with different architectures reported in literature. |
View original table
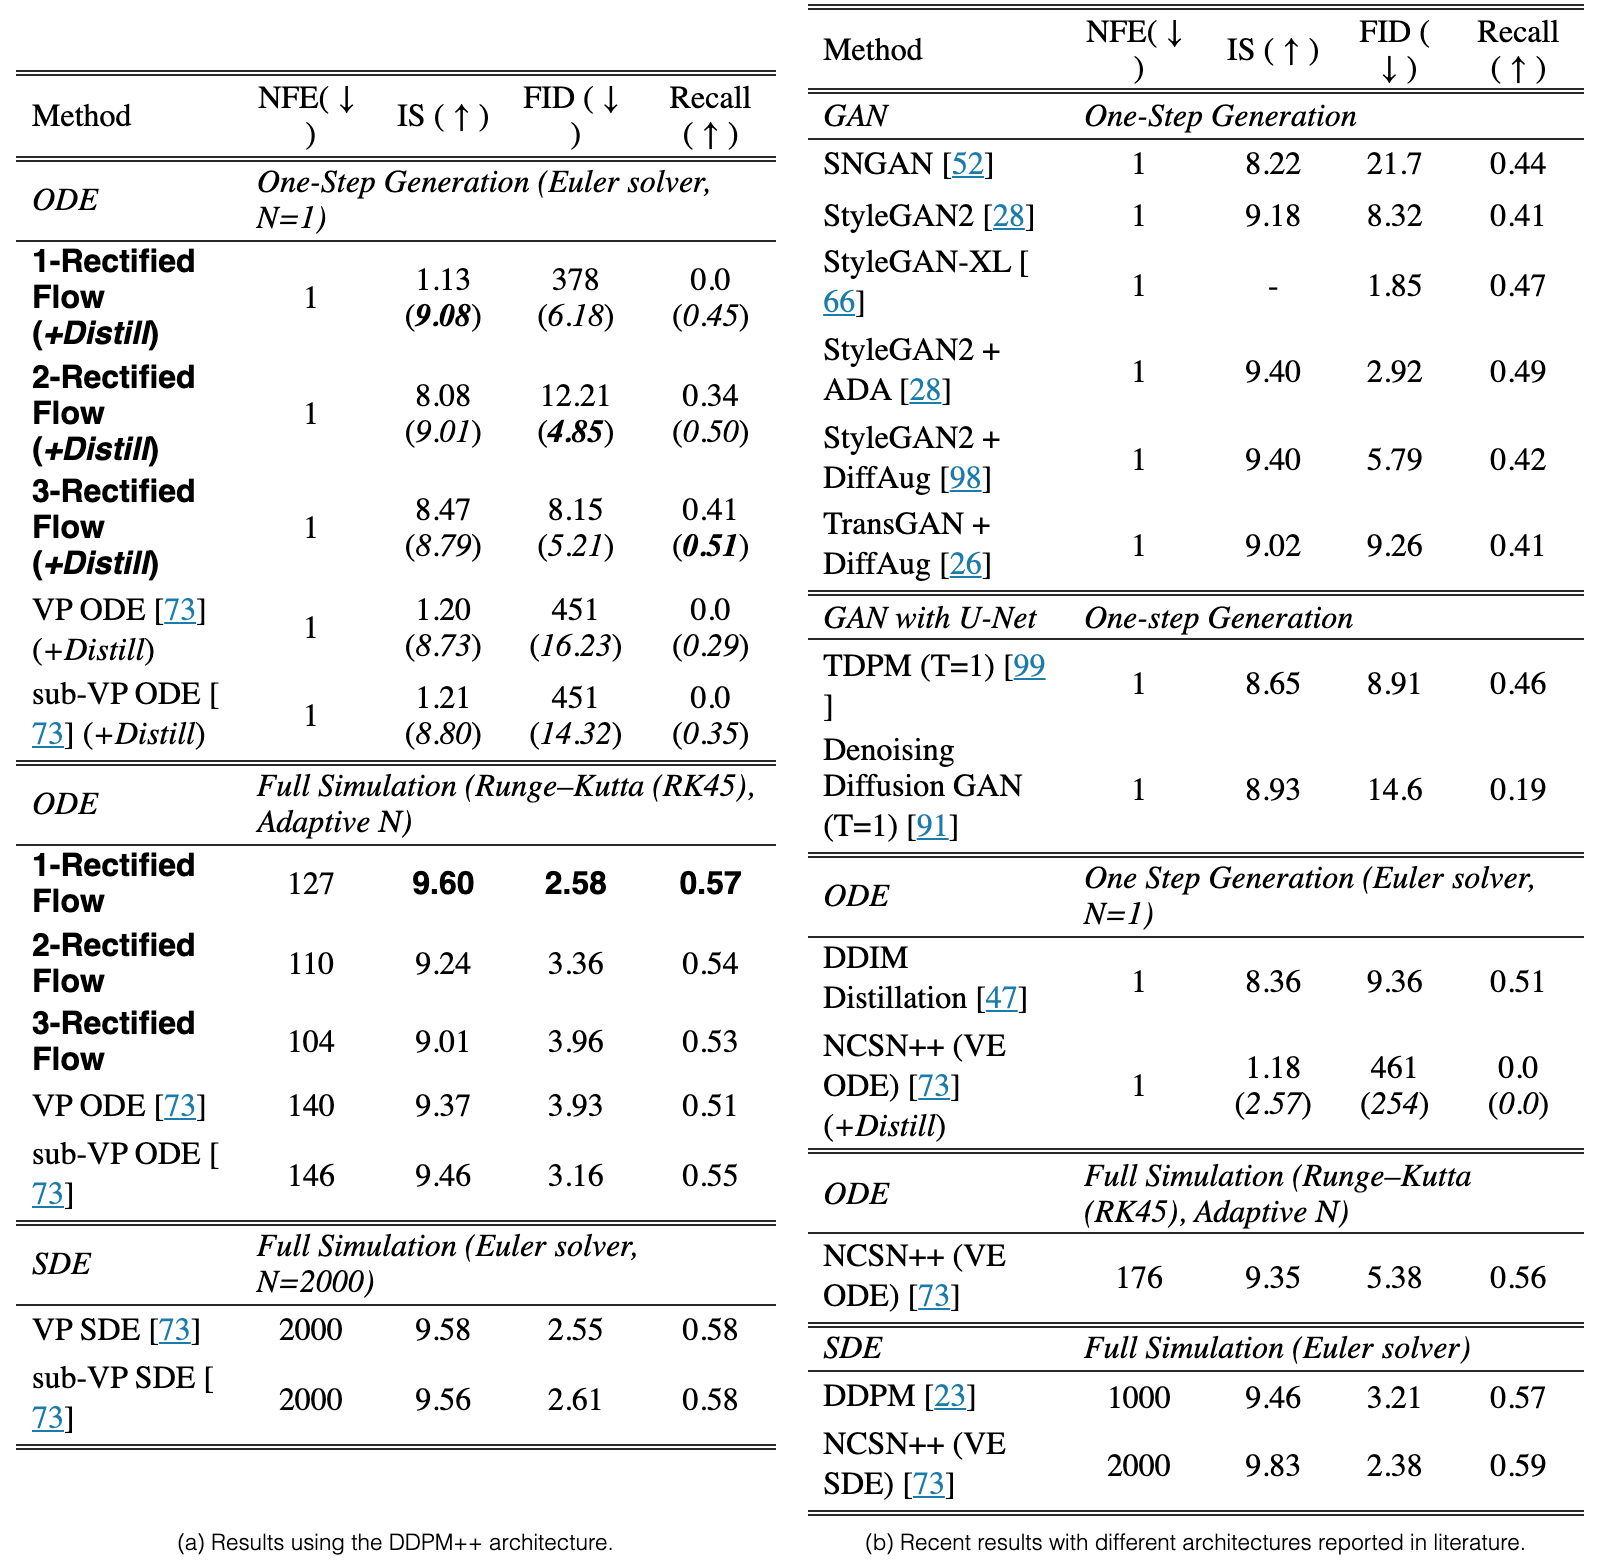
Results of fully solved ODEs. As shown in Table 1 (a), the 1-rectified flow trained on the DDPM++ architecture, solved with RK45, yields the lowest FID () and highest recall () among all the ODE-based methods. In particular, the recall of 0.57 yields a substantial improvement over existing ODE and GAN methods. Using the same RK45 ODE solver, rectified flows require fewer steps to generate the images compared with VE, VP, sub-VP ODEs. The results are comparable to the fully simulated (sub-)VP SDE, which yields simulation cost.
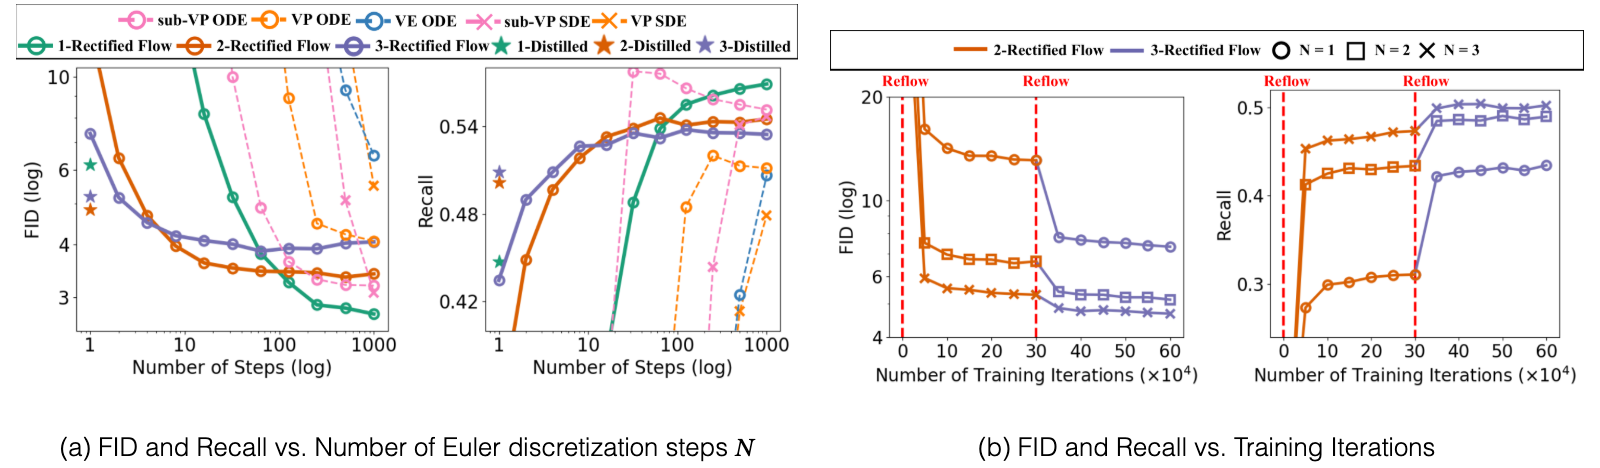
Results on few and single step generation. As shown in Figure 8, the reflow procedure substantially improves both FID and recall in the small step regime (e.g., ), even though it worsens the results in the large step regime due to the accumulation of error on estimating . Figure 8 (b) show that each reflow leads to a noticeable improvement in FID and recall. For one-step generation , the results are further boosted by distillation (see the stars in Figure 8 (a)). Overall, the distilled -Rectified Flow with yield one-step generative models beating all previous ODEs with distillation; they also beat the reported results of one-step models with similar U-net type architectures trained using GANs (see the GAN with U-Net in Table 1 (b)).
In particular, the distilled 2-rectified flow achieves an FID of , beating the best known one-step generative model with U-net architecture, (TDPM, Table 1 (b)). The recalls of both 2-rectified flow () and 3-rectified flow () outperform the best known results of GANs ( from StyleGAN2+ADA) showing an advantage in diversity. We should note that the reported results of GANs have been carefully optimized with special techniques such as adaptive discriminator augmentation (ADA) [28], while our results are based on the vanilla implementation of rectified flow. It is likely to further improve rectified flow with proper data augmentation techniques, or the combination of GANs such as those proposed by TDPM [99] and denoising diffusion GAN [91].
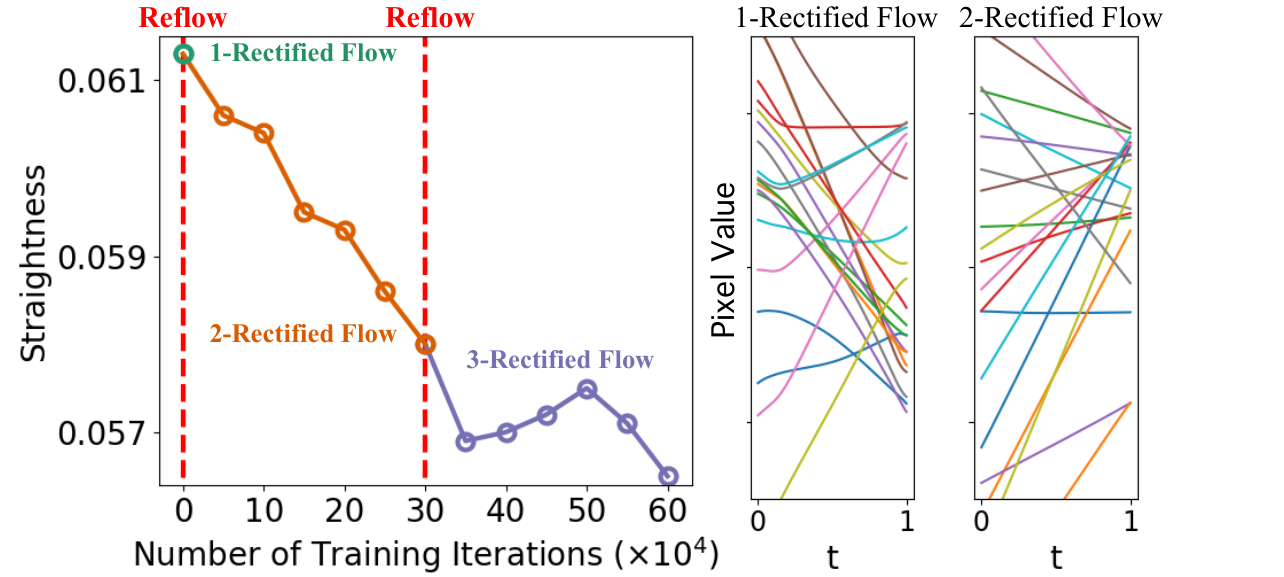
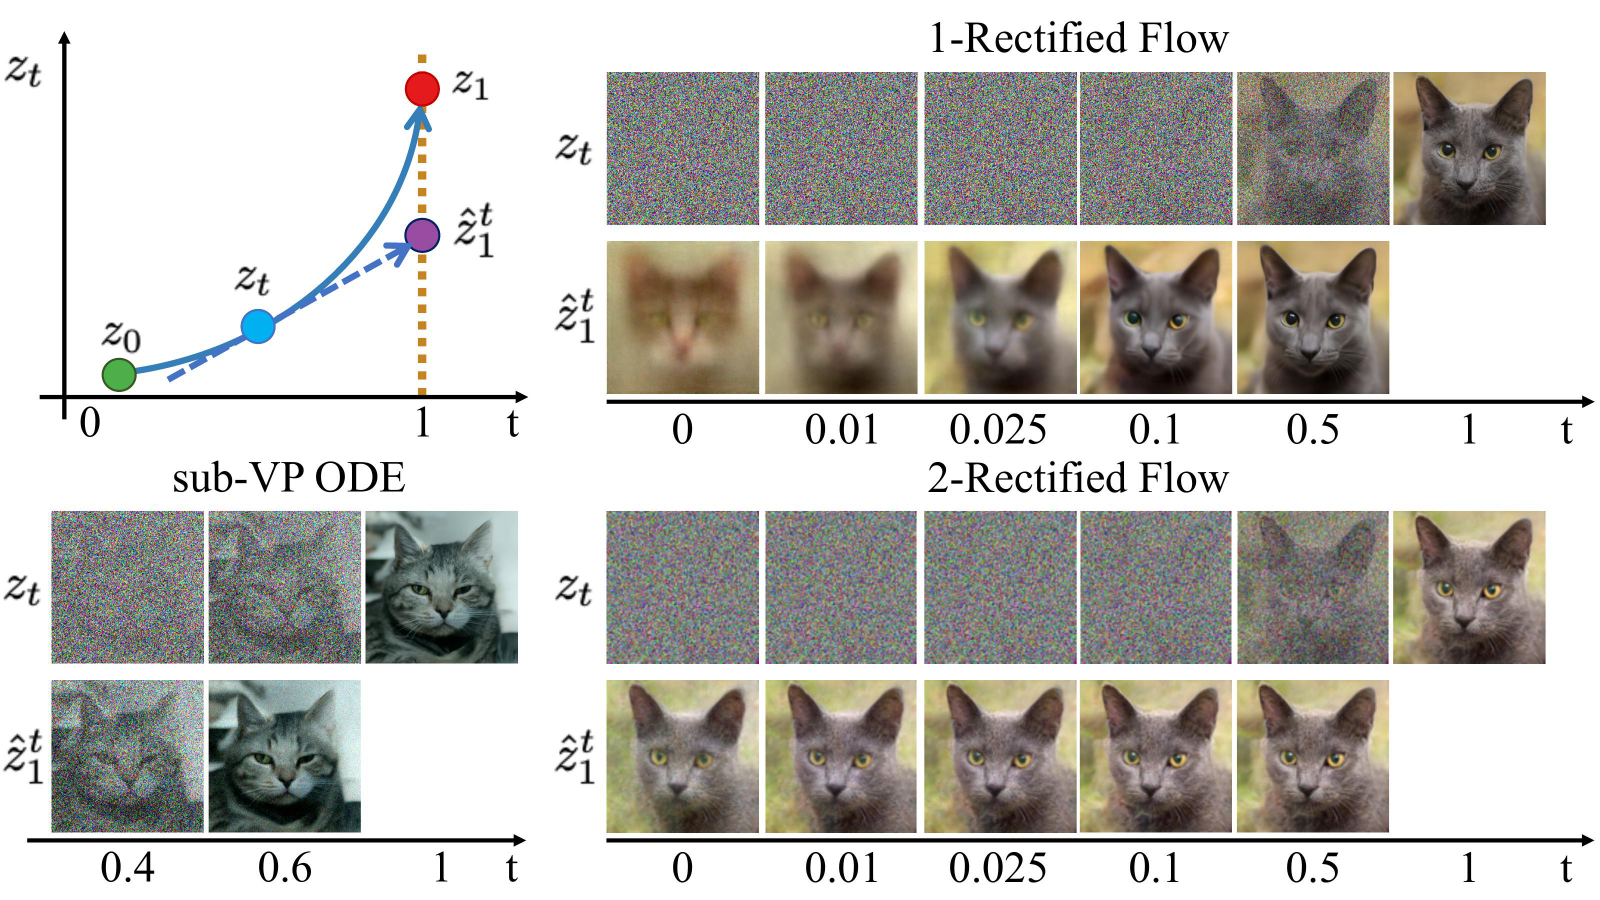
Reflow straightens the flow. Figure 9 shows the reflow procedure decreases improves the straightness of the flow on CIFAR10. In Figure 10 visualizes the trajectories of 1-rectified flow and 2-rectified flow on the AFHQ cat dataset: at each point , we extrapolate the terminal value at by ; if the trajectory of ODE follows a straight line, should not change as we vary when following the same path. We observe that is almost independent with for 2-rectified flow, showing the path is almost straight. Moreover, even though 1-rectified flow is not straight with over time, it still yields recognizable and clear images very early (). In comparison, it is need to get a clear image from the extrapolation of sub-VP ODE.
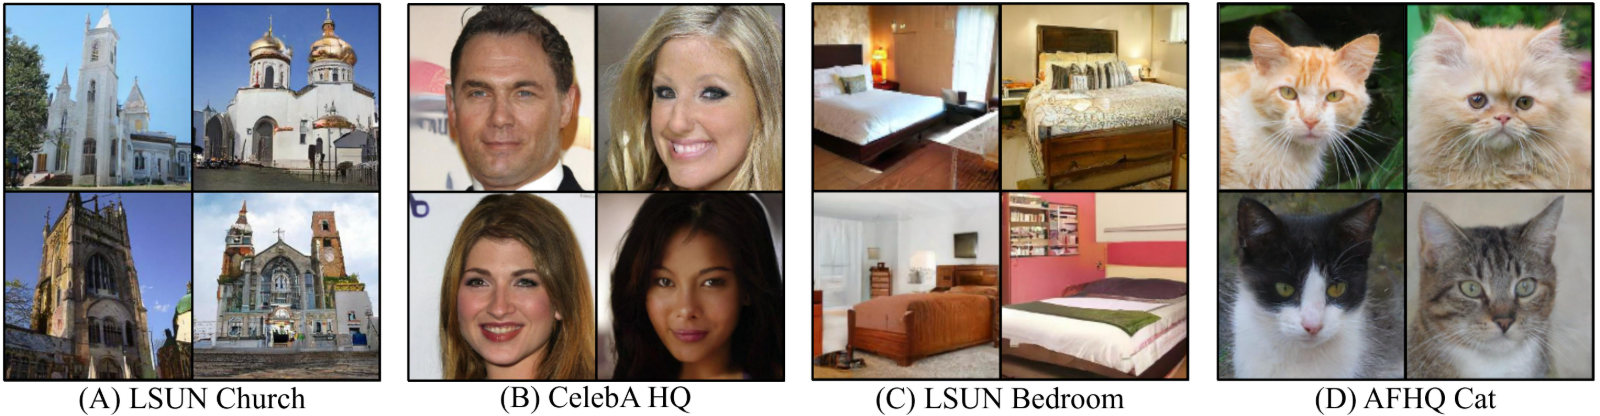
Figure 11 shows the result of 1-rectified flow on image generation on high-resolution () datasets, including LSUN Bedroom [93], LSUN Church [93], CelebA HQ [27] to AFHQ Cat [9]. We can see that it can generate high quality results across the different datasets. Figure 1 & 10 show that 1-(2-)rectified flow yields good results within one or few Euler steps.
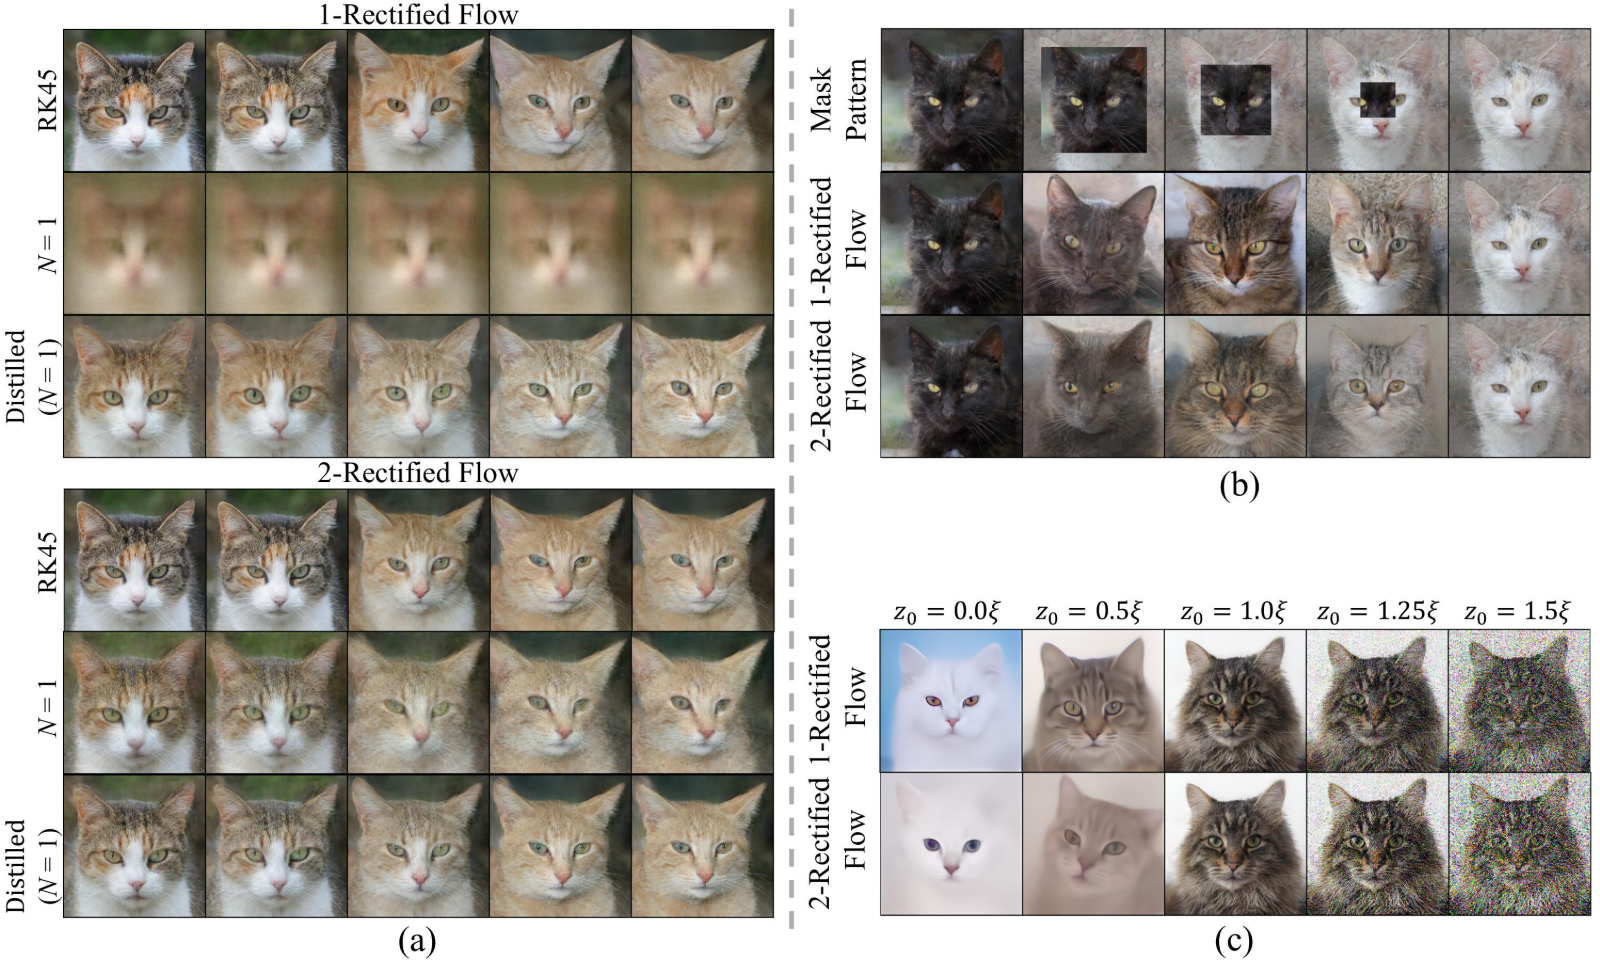
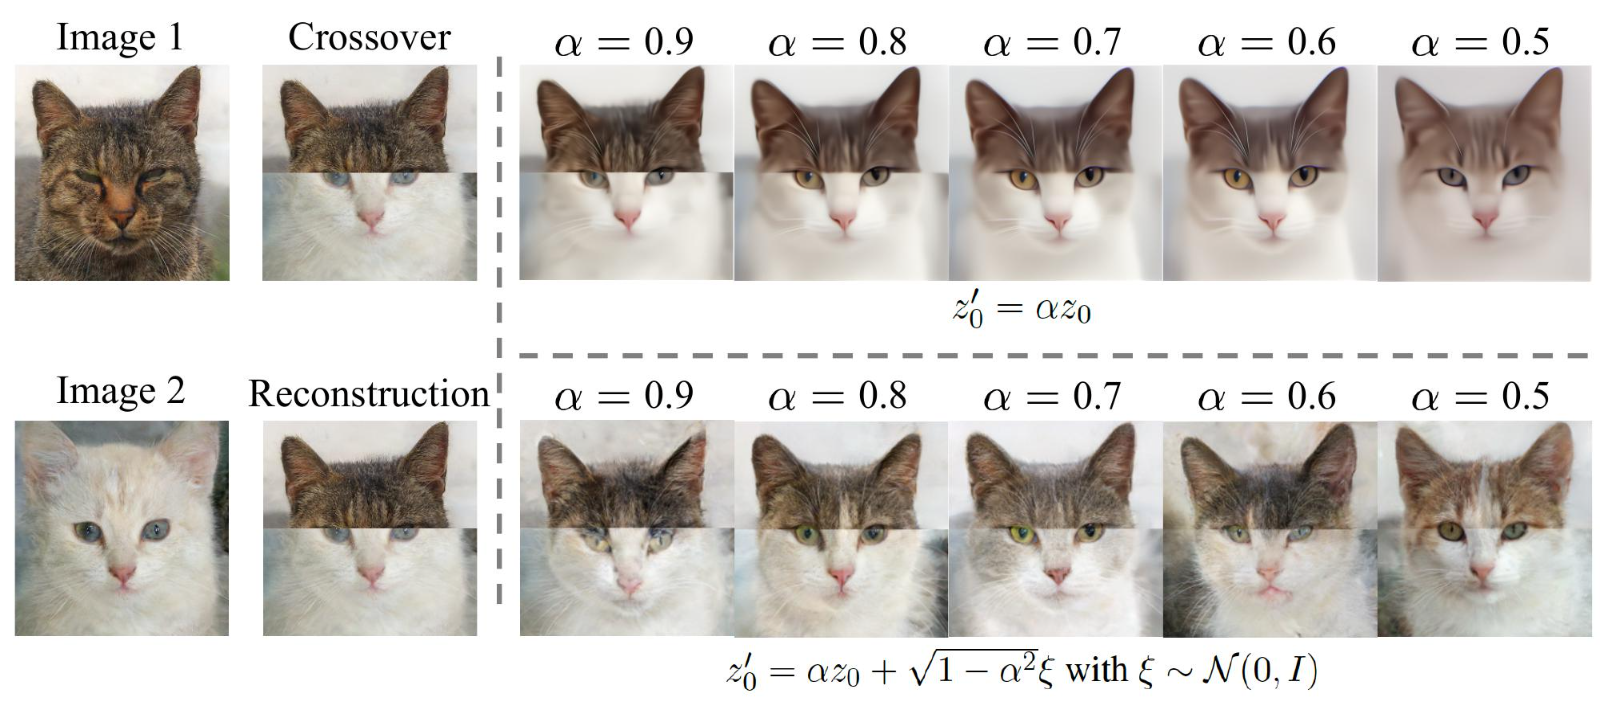
Figure 12 shows a simple example of image editing using 1-rectified flow: We first obtain an unnatural image by stitching the upper and lower parts of two natural images, and then run 1-rectified flow backwards to get a latent code . We then modify to increase its likelihood under (which is ) to get more naturally looking variants of the stitched image.
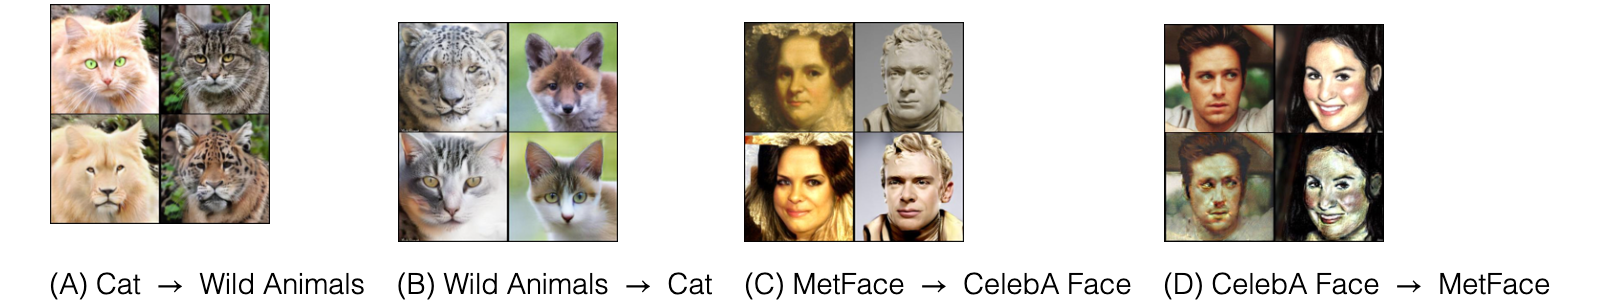
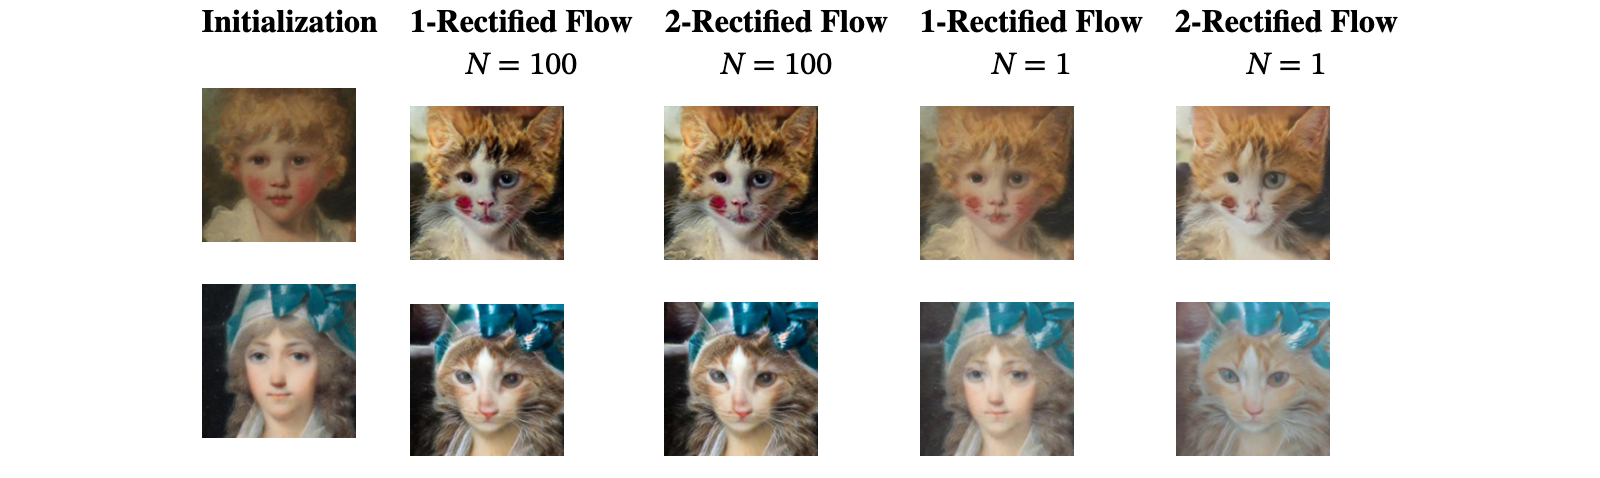
Assume we are given two sets of images of different styles (a.k.a. domains), whose distributions are denoted by , respectively. We are interested in transferring the style (or other key characteristics) of the images in one domain to the other domain, in the absence of paired examples. A classical approach to achieving this is cycle-consistent adversarial networks (a.k.a. CycleGAN) [100, 25], which jointly learns a forward and backward mapping by minimizing the sum of adversarial losses on the two domains, regularized by a cycle consistency loss to enforce for all image .
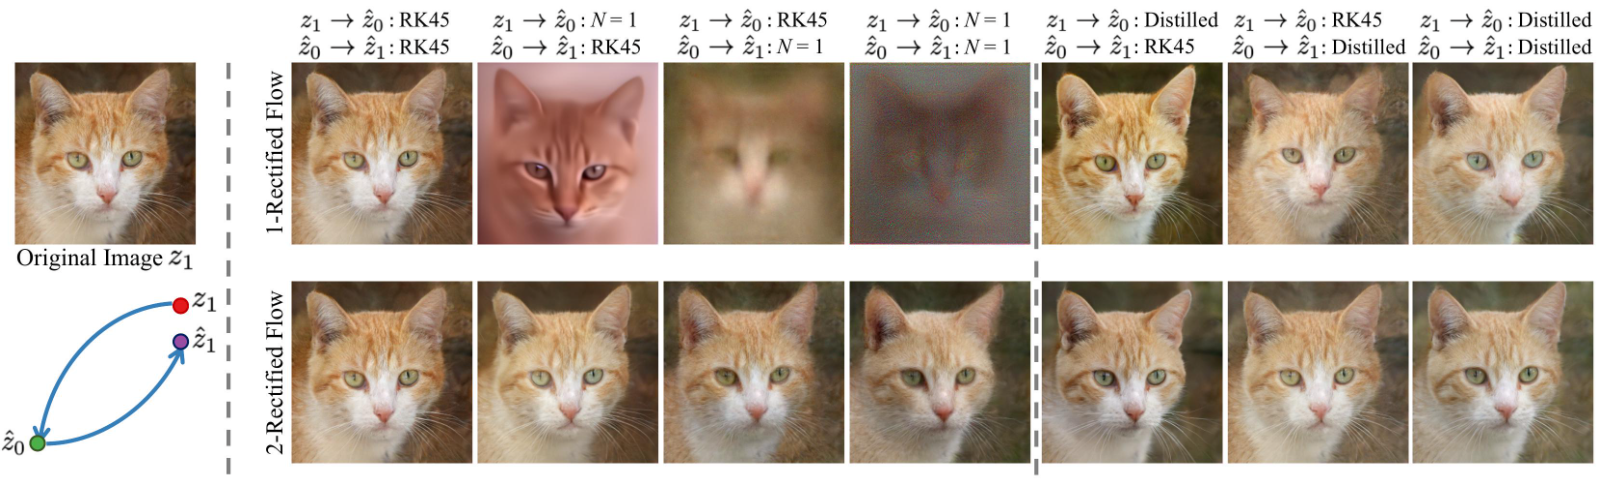
By constructing the rectified flow of and , we obtain a simple approach to image translation that requires no adversarial optimization and cycle-consistency regularization: training the rectified flow requires a simple optimization procedure and the cycle consistency is automatically in flow models satisfied due to reversibility of ODEs.
As the main goal here is to obtain good visual results, we are not interested in faithfully transferring to an that exactly follows . Rather, we are interested in transferring the image styles while preserving the identity of the main object in the image. For example, when transferring a human face image to a cat face, we are interested in getting a unrealistic face of human-cat hybrid that still “looks like” the original human face.
To achieve this, let be a feature mapping of image representing the styles that we are interested in transferring. Let . Then follows an ODE of Hence, to ensure that the style is transferred correctly, we propose to learn such that with approximates as much as possible. Because , we propose to minimize the following loss:
In practice, we set to be latent representation of a classifier trained to distinguish the images from the two domains , fine-tuned from a pre-trained ImageNet [77] model. Intuitively, serves as a saliency score and re-weights coordinates so that the loss in (20) focuses on penalizing the error that causes significant changes on .
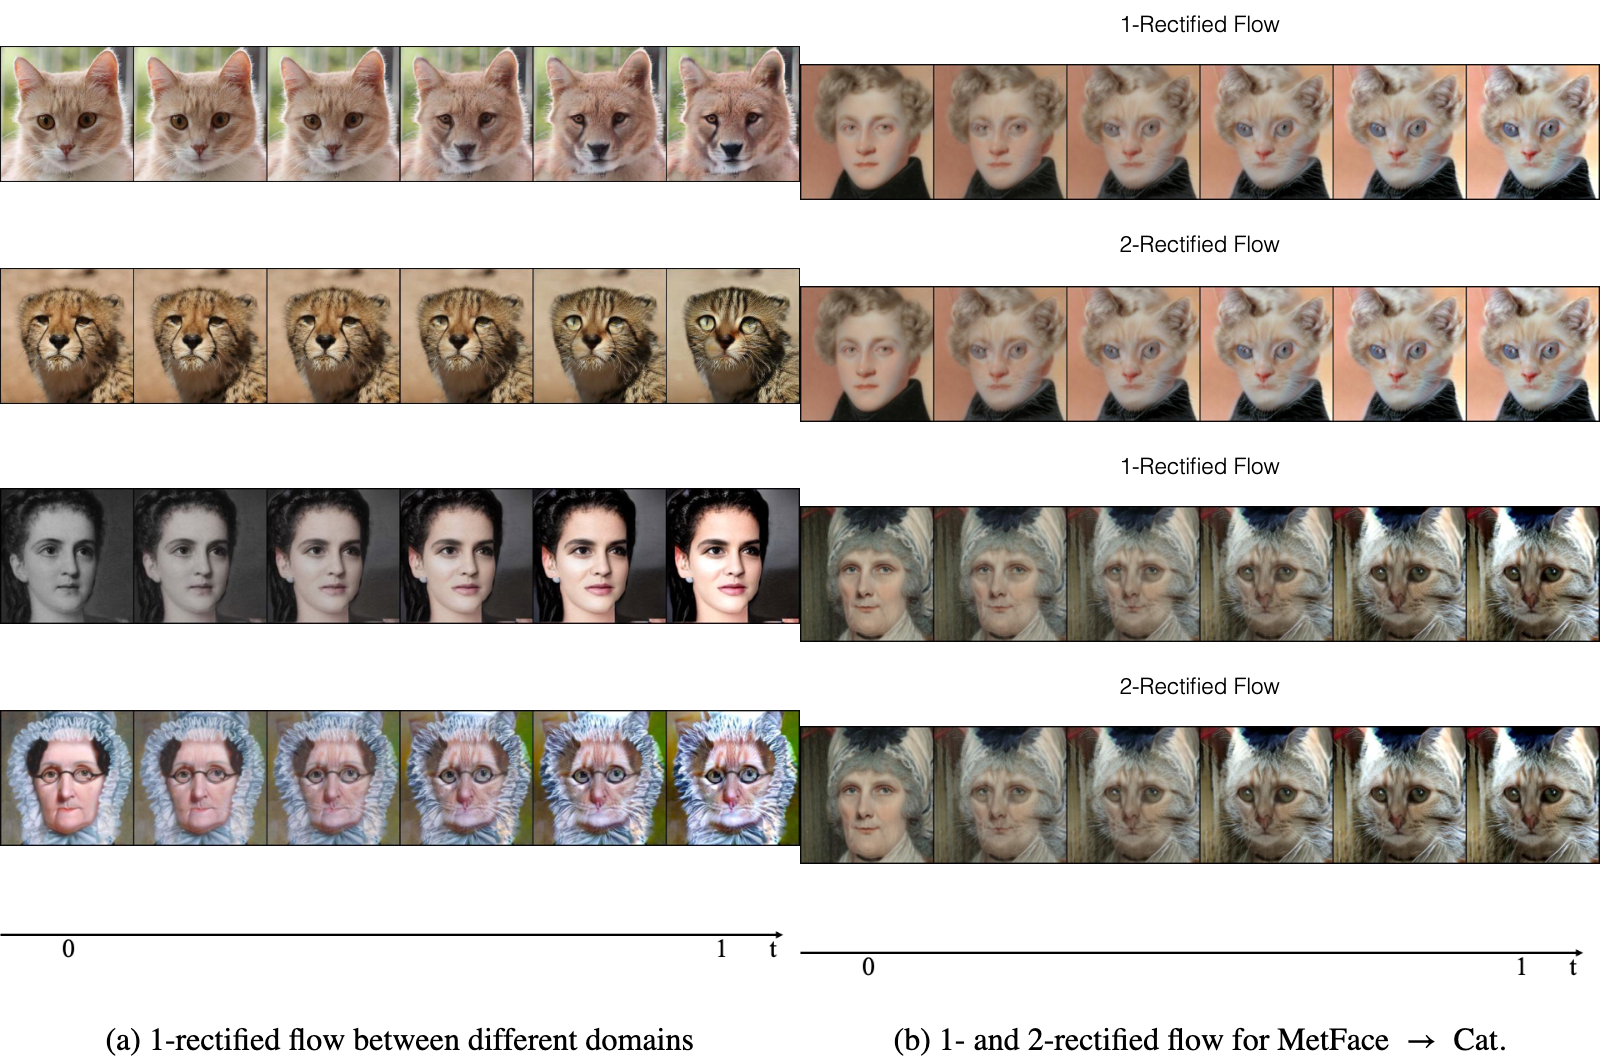
We set the domains to be pairs of the AFHQ [9], MetFace [28] and CelebA-HQ [27] dataset. For each dataset, we randomly select as the training data and regard the rest as the test data; and the results are shown by initializing the trained flows from the test data. We resize the image to . The training and network configurations generally follow the experiment settings in Section 5.2. See the appendix for detailed descriptions.
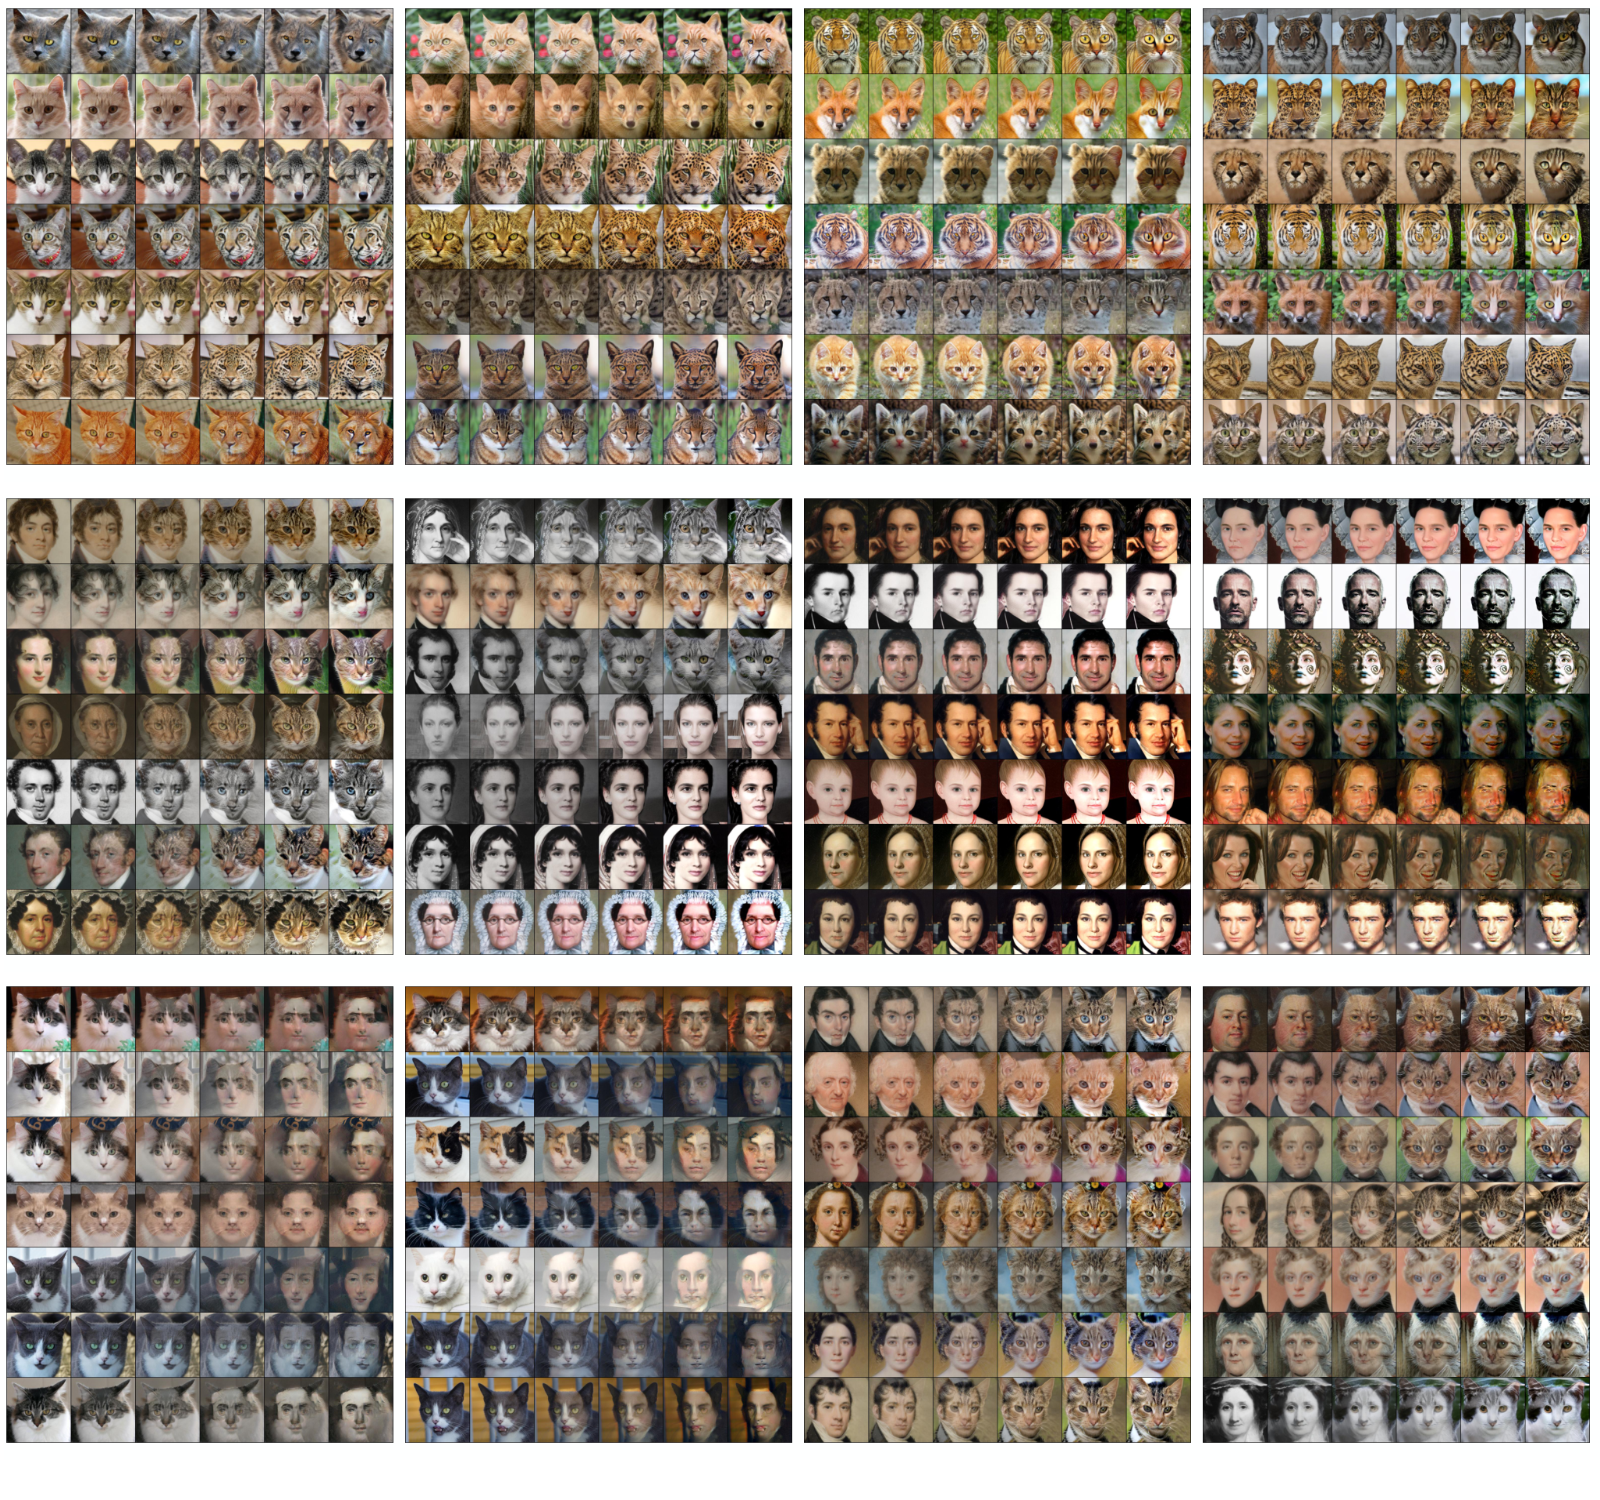
Figure 1, 13, 14, 15 show examples of results of 1- and 2-rectified flow simulated with Euler method with different number of steps . We can see that rectified flows can successfully transfer the styles and generate high quality images. For example, when transferring cats to wild animals, we can generate diverse images with different animal faces, e.g., fox, lion, tiger and cheetah. Moreover, with one step of reflow, 2-rectified flow returns good results with a single Euler step (). See more examples in Appendix.
A key challenge of applying machine learning to real-world problems is the domain shift between the training and test datasets: the performance of machine learning models may degrade significantly when tested on a novel domain different from the training set. Rectified flow can be applied to transfer the novel domain () to the training domain () to mitigate the impact of domain shift.
We test the rectified flow for domain adaptation on a number of datasets. DomainNet [58] is a dataset of common objects in six different domain taken from DomainBed [20]. All domains from DomainNet include 345 categories (classes) of objects such as Bracelet, plane, bird and cello. Office-Home [83] is a benchmark dataset for domain adaptation which contains 4 domains where each domain consists of 65 categories. To apply our method, first we map both the training and testing data to the latent representation from final hidden layer of the pre-trained model, and construct the rectified flow on the latent representation. We use the same DDPM++ model architecture for training. For inference, we set the number of steps of our flow model as using uniform discretization. The methods are evaluated by the prediction accuracy of the transferred testing data on the classification model trained on the training data.
As demonstrated in Table 2, the 1-rectified flow shows state-of-the-art performance on both DomainNet and OfficeHome. It is better or on par with the previous best approach (Deep CORAL [76]), while sustainably improve over all other methods.
| Method | ERM | IRM | ARM | Mixup | MLDG | CORAL | Ours |
|---|---|---|---|---|---|---|---|
| OfficeHome | |||||||
| DomainNet |
View original table

References
- [1] Luigi Ambrosio and Gianluca Crippa. Existence, uniqueness, stability and differentiability properties of the flow associated to weakly differentiable vector fields. In Transport equations and multi-D hyperbolic conservation laws, pages 3–57. Springer, 2008.
- [2] Luigi Ambrosio, Elia Brué, and Daniele Semola. Lectures on optimal transport. Springer, 2021.
- [3] Brian DO Anderson. Reverse-time diffusion equation models. Stochastic Processes and their Applications, 12(3):313–326, 1982.
- [4] Martin Arjovsky, Soumith Chintala, and Léon Bottou. Wasserstein generative adversarial networks. In International conference on machine learning, pages 214–223. PMLR, 2017.
- [5] Fan Bao, Chongxuan Li, Jun Zhu, and Bo Zhang. Analytic-DPM: an analytic estimate of the optimal reverse variance in diffusion probabilistic models. arXiv preprint arXiv:2201.06503, 2022.
- [6] Ricky TQ Chen, Yulia Rubanova, Jesse Bettencourt, and David K Duvenaud. Neural ordinary differential equations. Advances in neural information processing systems, 31, 2018.
- [7] Tianrong Chen, Guan-Horng Liu, and Evangelos A Theodorou. Likelihood training of Schrödinger bridge using forward-backward sdes theory. arXiv preprint arXiv:2110.11291, 2021.
- [8] Jooyoung Choi, Sungwon Kim, Yonghyun Jeong, Youngjune Gwon, and Sungroh Yoon. Ilvr: Conditioning method for denoising diffusion probabilistic models. arXiv preprint arXiv:2108.02938, 2021.
- [9] Yunjey Choi, Youngjung Uh, Jaejun Yoo, and Jung-Woo Ha. StarGAN v2: Diverse image synthesis for multiple domains. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition, pages 8188–8197, 2020.
- [10] Max Daniels, Tyler Maunu, and Paul Hand. Score-based generative neural networks for large-scale optimal transport. Advances in neural information processing systems, 34:12955–12965, 2021.
- [11] Valentin De Bortoli, James Thornton, Jeremy Heng, and Arnaud Doucet. Diffusion Schrödinger bridge with applications to score-based generative modeling. Advances in Neural Information Processing Systems, 34, 2021.
- [12] Prafulla Dhariwal and Alexander Nichol. Diffusion models beat GANs on image synthesis. Advances in Neural Information Processing Systems, 34, 2021.
- [13] Laurent Dinh, David Krueger, and Yoshua Bengio. Nice: Non-linear independent components estimation. arXiv preprint arXiv:1410.8516, 2014.
- [14] Laurent Dinh, Jascha Sohl-Dickstein, and Samy Bengio. Density estimation using real nvp. arXiv preprint arXiv:1605.08803, 2016.
- [15] Alessio Figalli and Federico Glaudo. An Invitation to Optimal Transport, Wasserstein Distances, and Gradient Flows. 2021.
- [16] R Flamary, N Courty, D Tuia, and A Rakotomamonjy. Optimal transport for domain adaptation. IEEE Trans. Pattern Anal. Mach. Intell, 1, 2016.
- [17] Hans Föllmer. An entropy approach to the time reversal of diffusion processes. In Stochastic Differential Systems Filtering and Control, pages 156–163. Springer, 1985.
- [18] Giulio Franzese, Simone Rossi, Lixuan Yang, Alessandro Finamore, Dario Rossi, Maurizio Filippone, and Pietro Michiardi. How much is enough? a study on diffusion times in score-based generative models. arXiv preprint arXiv:2206.05173, 2022.
- [19] Ian Goodfellow, Jean Pouget-Abadie, Mehdi Mirza, Bing Xu, David Warde-Farley, Sherjil Ozair, Aaron Courville, and Yoshua Bengio. Generative adversarial nets. Advances in neural information processing systems, 27, 2014.
- [20] Ishaan Gulrajani and David Lopez-Paz. In search of lost domain generalization. arXiv preprint arXiv:2007.01434, 2020.
- [21] William Harvey, Saeid Naderiparizi, Vaden Masrani, Christian Weilbach, and Frank Wood. Flexible diffusion modeling of long videos. arXiv preprint arXiv:2205.11495, 2022.
- [22] Ulrich G Haussmann and Etienne Pardoux. Time reversal of diffusions. The Annals of Probability, pages 1188–1205, 1986.
- [23] Jonathan Ho, Ajay Jain, and Pieter Abbeel. Denoising diffusion probabilistic models. Advances in Neural Information Processing Systems, 33:6840–6851, 2020.
- [24] Jonathan Ho, Tim Salimans, Alexey Gritsenko, William Chan, Mohammad Norouzi, and David J Fleet. Video diffusion models. arXiv preprint arXiv:2204.03458, 2022.
- [25] Phillip Isola, Jun-Yan Zhu, Tinghui Zhou, and Alexei A Efros. Image-to-image translation with conditional adversarial networks. In Proceedings of the IEEE conference on computer vision and pattern recognition, pages 1125–1134, 2017.
- [26] Yifan Jiang, Shiyu Chang, and Zhangyang Wang. TransGAN: Two pure transformers can make one strong GAN, and that can scale up. Advances in Neural Information Processing Systems, 34, 2021.
- [27] Tero Karras, Timo Aila, Samuli Laine, and Jaakko Lehtinen. Progressive growing of GANs for improved quality, stability, and variation. In International Conference on Learning Representations, 2018.
- [28] Tero Karras, Miika Aittala, Janne Hellsten, Samuli Laine, Jaakko Lehtinen, and Timo Aila. Training generative adversarial networks with limited data. Advances in Neural Information Processing Systems, 33:12104–12114, 2020.
- [29] Tero Karras, Miika Aittala, Timo Aila, and Samuli Laine. Elucidating the design space of diffusion-based generative models. arXiv preprint arXiv:2206.00364, 2022.
- [30] Valentin Khrulkov and Ivan Oseledets. Understanding DDPM latent codes through optimal transport. arXiv preprint arXiv:2202.07477, 2022.
- [31] Diederik P Kingma and Jimmy Ba. Adam: A method for stochastic optimization. arXiv preprint arXiv:1412.6980, 2014.
- [32] Diederik P Kingma and Max Welling. Auto-encoding variational bayes. arXiv preprint arXiv:1312.6114, 2013.
- [33] Zhifeng Kong, Wei Ping, Jiaji Huang, Kexin Zhao, and Bryan Catanzaro. Diffwave: A versatile diffusion model for audio synthesis. In International Conference on Learning Representations, 2020.
- [34] Alexander Korotin, Lingxiao Li, Aude Genevay, Justin M Solomon, Alexander Filippov, and Evgeny Burnaev. Do neural optimal transport solvers work? a continuous wasserstein-2 benchmark. Advances in Neural Information Processing Systems, 34:14593–14605, 2021.
- [35] Alexander Korotin, Daniil Selikhanovych, and Evgeny Burnaev. Neural optimal transport. arXiv preprint arXiv:2201.12220, 2022.
- [36] Alex Krizhevsky, Geoffrey Hinton, et al. Learning multiple layers of features from tiny images. 2009.
- [37] Thomas G Kurtz. Equivalence of stochastic equations and martingale problems. In Stochastic analysis 2010, pages 113–130. Springer, 2011.
- [38] Tuomas Kynkäänniemi, Tero Karras, Samuli Laine, Jaakko Lehtinen, and Timo Aila. Improved precision and recall metric for assessing generative models. Advances in Neural Information Processing Systems, 32, 2019.
- [39] Hugo Lavenant and Filippo Santambrogio. The flow map of the fokker–planck equation does not provide optimal transport. Applied Mathematics Letters, page 108225, 2022.
- [40] Junhyeok Lee and Seungu Han. Nu-wave: A diffusion probabilistic model for neural audio upsampling. arXiv preprint arXiv:2104.02321, 2021.
- [41] Xiang Lisa Li, John Thickstun, Ishaan Gulrajani, Percy Liang, and Tatsunori B Hashimoto. Diffusion-lm improves controllable text generation. arXiv preprint arXiv:2205.14217, 2022.
- [42] Qiang Liu. On rectified flow and optimal coupling. preprint, 2022.
- [43] Xingchao Liu, Chengyue Gong, Lemeng Wu, Shujian Zhang, Hao Su, and Qiang Liu. Fusedream: Training-free text-to-image generation with improved clip+ gan space optimization. arXiv preprint arXiv:2112.01573, 2021.
- [44] Xingchao Liu, Lemeng Wu, Mao Ye, and Qiang Liu. Let us build bridges: Understanding and extending diffusion generative models. arXiv preprint arXiv:2208.14699, 2022.
- [45] Ilya Loshchilov and Frank Hutter. Decoupled weight decay regularization. arXiv preprint arXiv:1711.05101, 2017.
- [46] Cheng Lu, Yuhao Zhou, Fan Bao, Jianfei Chen, Chongxuan Li, and Jun Zhu. DPM-solver: A fast ODE solver for diffusion probabilistic model sampling in around 10 steps. arXiv preprint arXiv:2206.00927, 2022.
- [47] Eric Luhman and Troy Luhman. Knowledge distillation in iterative generative models for improved sampling speed. arXiv preprint arXiv:2101.02388, 2021.
- [48] Zhaoyang Lyu, Xudong Xu, Ceyuan Yang, Dahua Lin, and Bo Dai. Accelerating diffusion models via early stop of the diffusion process. arXiv preprint arXiv:2205.12524, 2022.
- [49] Ashok Makkuva, Amirhossein Taghvaei, Sewoong Oh, and Jason Lee. Optimal transport mapping via input convex neural networks. In International Conference on Machine Learning, pages 6672–6681. PMLR, 2020.
- [50] Chenlin Meng, Yang Song, Jiaming Song, Jiajun Wu, Jun-Yan Zhu, and Stefano Ermon. Sdedit: Image synthesis and editing with stochastic differential equations. arXiv preprint arXiv:2108.01073, 2021.
- [51] Gautam Mittal, Jesse Engel, Curtis Hawthorne, and Ian Simon. Symbolic music generation with diffusion models. arXiv preprint arXiv:2103.16091, 2021.
- [52] Takeru Miyato, Toshiki Kataoka, Masanori Koyama, and Yuichi Yoshida. Spectral normalization for generative adversarial networks. In International Conference on Learning Representations, 2018.
- [53] Alex Nichol, Prafulla Dhariwal, Aditya Ramesh, Pranav Shyam, Pamela Mishkin, Bob McGrew, Ilya Sutskever, and Mark Chen. Glide: Towards photorealistic image generation and editing with text-guided diffusion models. arXiv preprint arXiv:2112.10741, 2021.
- [54] Alexander Quinn Nichol and Prafulla Dhariwal. Improved denoising diffusion probabilistic models. In International Conference on Machine Learning, pages 8162–8171. PMLR, 2021.
- [55] Derek Onken, Samy Wu Fung, Xingjian Li, and Lars Ruthotto. Ot-flow: Fast and accurate continuous normalizing flows via optimal transport. In Proceedings of the AAAI Conference on Artificial Intelligence, volume 35, pages 9223–9232, 2021.
- [56] George Papamakarios, Eric T Nalisnick, Danilo Jimenez Rezende, Shakir Mohamed, and Balaji Lakshminarayanan. Normalizing flows for probabilistic modeling and inference. J. Mach. Learn. Res., 22(57):1–64, 2021.
- [57] Stefano Peluchetti. Non-denoising forward-time diffusions. 2021.
- [58] Xingchao Peng, Qinxun Bai, Xide Xia, Zijun Huang, Kate Saenko, and Bo Wang. Moment matching for multi-source domain adaptation. In Proceedings of the IEEE/CVF international conference on computer vision, pages 1406–1415, 2019.
- [59] Gabriel Peyré, Marco Cuturi, et al. Computational optimal transport: With applications to data science. Foundations and Trends® in Machine Learning, 11(5-6):355–607, 2019.
- [60] Vadim Popov, Ivan Vovk, Vladimir Gogoryan, Tasnima Sadekova, and Mikhail Kudinov. Grad-tts: A diffusion probabilistic model for text-to-speech. In International Conference on Machine Learning, pages 8599–8608. PMLR, 2021.
- [61] Aditya Ramesh, Prafulla Dhariwal, Alex Nichol, Casey Chu, and Mark Chen. Hierarchical text-conditional image generation with clip latents. arXiv preprint arXiv:2204.06125, 2022.
- [62] Danilo Rezende and Shakir Mohamed. Variational inference with normalizing flows. In International conference on machine learning, pages 1530–1538. PMLR, 2015.
- [63] Litu Rout, Alexander Korotin, and Evgeny Burnaev. Generative modeling with optimal transport maps. arXiv preprint arXiv:2110.02999, 2021.
- [64] Chitwan Saharia, William Chan, Saurabh Saxena, Lala Li, Jay Whang, Emily Denton, Seyed Kamyar Seyed Ghasemipour, Burcu Karagol Ayan, S Sara Mahdavi, Rapha Gontijo Lopes, et al. Photorealistic text-to-image diffusion models with deep language understanding. arXiv preprint arXiv:2205.11487, 2022.
- [65] Filippo Santambrogio. Optimal transport for applied mathematicians. Birkäuser, NY, 55(58-63):94, 2015.
- [66] Axel Sauer, Katja Schwarz, and Andreas Geiger. StyleGAN-XL: Scaling StyleGAN to large diverse datasets. In Special Interest Group on Computer Graphics and Interactive Techniques Conference Proceedings, pages 1–10, 2022.
- [67] Vivien Seguy, Bharath Bhushan Damodaran, Rémi Flamary, Nicolas Courty, Antoine Rolet, and Mathieu Blondel. Large-scale optimal transport and mapping estimation. arXiv preprint arXiv:1711.02283, 2017.
- [68] Abhishek Sinha, Jiaming Song, Chenlin Meng, and Stefano Ermon. D2C: Diffusion-decoding models for few-shot conditional generation. Advances in Neural Information Processing Systems, 34:12533–12548, 2021.
- [69] Leslie N Smith and Nicholay Topin. Super-convergence: Very fast training of neural networks using large learning rates. In Artificial intelligence and machine learning for multi-domain operations applications, volume 11006, pages 369–386. SPIE, 2019.
- [70] Jiaming Song, Chenlin Meng, and Stefano Ermon. Denoising diffusion implicit models. In International Conference on Learning Representations, 2020a.
- [71] Yang Song and Stefano Ermon. Generative modeling by estimating gradients of the data distribution. Advances in Neural Information Processing Systems, 32, 2019.
- [72] Yang Song and Stefano Ermon. Improved techniques for training score-based generative models. Advances in neural information processing systems, 33:12438–12448, 2020.
- [73] Yang Song, Jascha Sohl-Dickstein, Diederik P Kingma, Abhishek Kumar, Stefano Ermon, and Ben Poole. Score-based generative modeling through stochastic differential equations. In International Conference on Learning Representations, 2020b.
- [74] Yang Song, Conor Durkan, Iain Murray, and Stefano Ermon. Maximum likelihood training of score-based diffusion models. Advances in Neural Information Processing Systems, 34, 2021.
- [75] Xuan Su, Jiaming Song, Chenlin Meng, and Stefano Ermon. Dual diffusion implicit bridges for image-to-image translation. arXiv preprint arXiv:2203.08382, 2022.
- [76] Baochen Sun and Kate Saenko. Deep coral: Correlation alignment for deep domain adaptation. In European conference on computer vision, pages 443–450. Springer, 2016.
- [77] Mingxing Tan and Quoc Le. Efficientnet: Rethinking model scaling for convolutional neural networks. In International conference on machine learning, pages 6105–6114. PMLR, 2019.
- [78] Anastasiya Tanana. Comparison of transport map generated by heat flow interpolation and the optimal transport brenier map. Communications in Contemporary Mathematics, 23(06):2050025, 2021.
- [79] Giulio Trigila and Esteban G Tabak. Data-driven optimal transport. Communications on Pure and Applied Mathematics, 69(4):613–648, 2016.
- [80] Belinda Tzen and Maxim Raginsky. Theoretical guarantees for sampling and inference in generative models with latent diffusions. In Conference on Learning Theory, pages 3084–3114. PMLR, 2019.
- [81] Arash Vahdat, Karsten Kreis, and Jan Kautz. Score-based generative modeling in latent space. Advances in Neural Information Processing Systems, 34:11287–11302, 2021.
- [82] Francisco Vargas, Pierre Thodoroff, Austen Lamacraft, and Neil Lawrence. Solving Schrödinger bridges via maximum likelihood. Entropy, 23(9):1134, 2021.
- [83] Hemanth Venkateswara, Jose Eusebio, Shayok Chakraborty, and Sethuraman Panchanathan. Deep hashing network for unsupervised domain adaptation. In Proceedings of the IEEE conference on computer vision and pattern recognition, pages 5018–5027, 2017.
- [84] Cédric Villani. Optimal transport: old and new, volume 338. Springer, 2009.
- [85] Cédric Villani. Topics in optimal transportation, volume 58. American Mathematical Soc., 2021.
- [86] Pauli Virtanen, Ralf Gommers, Travis E. Oliphant, Matt Haberland, Tyler Reddy, David Cournapeau, Evgeni Burovski, Pearu Peterson, Warren Weckesser, Jonathan Bright, Stéfan J. van der Walt, Matthew Brett, Joshua Wilson, K. Jarrod Millman, Nikolay Mayorov, Andrew R. J. Nelson, Eric Jones, Robert Kern, Eric Larson, C J Carey, İlhan Polat, Yu Feng, Eric W. Moore, Jake VanderPlas, Denis Laxalde, Josef Perktold, Robert Cimrman, Ian Henriksen, E. A. Quintero, Charles R. Harris, Anne M. Archibald, Antônio H. Ribeiro, Fabian Pedregosa, Paul van Mulbregt, and SciPy 1.0 Contributors. SciPy 1.0: Fundamental Algorithms for Scientific Computing in Python. Nature Methods, 17:261–272, 2020. doi: 10.1038/s41592-019-0686-2.
- [87] Gefei Wang, Yuling Jiao, Qian Xu, Yang Wang, and Can Yang. Deep generative learning via Schrödinger bridge. In International Conference on Machine Learning, pages 10794–10804. PMLR, 2021.
- [88] Rose E Wang, Esin Durmus, Noah Goodman, and Tatsunori Hashimoto. Language modeling via stochastic processes. arXiv preprint arXiv:2203.11370, 2022.
- [89] Antoine Wehenkel and Gilles Louppe. Diffusion priors in variational autoencoders. arXiv preprint arXiv:2106.15671, 2021.
- [90] Lemeng Wu, Chengyue Gong, Xingchao Liu, Mao Ye, and Qiang Liu. Diffusion-based molecule generation with informative prior bridges. arXiv preprint, 2022.
- [91] Zhisheng Xiao, Karsten Kreis, and Arash Vahdat. Tackling the generative learning trilemma with denoising diffusion GANs. arXiv preprint arXiv:2112.07804, 2021.
- [92] Ruihan Yang, Prakhar Srivastava, and Stephan Mandt. Diffusion probabilistic modeling for video generation. arXiv preprint arXiv:2203.09481, 2022.
- [93] Fisher Yu, Ari Seff, Yinda Zhang, Shuran Song, Thomas Funkhouser, and Jianxiong Xiao. Lsun: Construction of a large-scale image dataset using deep learning with humans in the loop. arXiv preprint arXiv:1506.03365, 2015.
- [94] Qinsheng Zhang and Yongxin Chen. Fast sampling of diffusion models with exponential integrator. arXiv preprint arXiv:2204.13902, 2022.
- [95] Qinsheng Zhang, Molei Tao, and Yongxin Chen. gDDIM: Generalized denoising diffusion implicit models. arXiv preprint arXiv:2206.05564, 2022.
- [96] Richard Zhang, Phillip Isola, Alexei A Efros, Eli Shechtman, and Oliver Wang. The unreasonable effectiveness of deep features as a perceptual metric. In Proceedings of the IEEE conference on computer vision and pattern recognition, pages 586–595, 2018.
- [97] Min Zhao, Fan Bao, Chongxuan Li, and Jun Zhu. EGSDE: Unpaired image-to-image translation via energy-guided stochastic differential equations. arXiv preprint arXiv:2207.06635, 2022.
- [98] Shengyu Zhao, Zhijian Liu, Ji Lin, Jun-Yan Zhu, and Song Han. Differentiable augmentation for data-efficient GAN training. Advances in Neural Information Processing Systems, 33:7559–7570, 2020.
- [99] Huangjie Zheng, Pengcheng He, Weizhu Chen, and Mingyuan Zhou. Truncated diffusion probabilistic models. arXiv preprint arXiv:2202.09671, 2022.
- [100] Jun-Yan Zhu, Taesung Park, Phillip Isola, and Alexei A Efros. Unpaired image-to-image translation using cycle-consistent adversarial networks. In Proceedings of the IEEE international conference on computer vision, pages 2223–2232, 2017.
# Input: Data={x0, x1}
# Output: Model for the rectified flow
initialize Model
for x0, x1 in Data: # x0, x1: samples from ,
Optimizer.zero_grad()
t = torch.rand(batchsize) # Randomly sample [0,1]
Loss = ( Model(t*x1+(1-t)*x0, t) - (x1-x0) ).pow(2).mean()
Loss.backward()
Optimizer.step()
return Model
# Input: Model of the rectified flow
# Output: draws of the rectified coupling
coupling = []
for x0, _ in Data: # x0: samples from (batchsizedim)
x1 = model.ODE_solver(x0)
coupling.append((x0, x1))
return coupling
# Input: Data={x0, x1}
# Output: draws of the -th rectified coupling
Coupling = Data
for :
Model = Train(Coupling)
Coupling = sample(Model, Data)
return Coupling
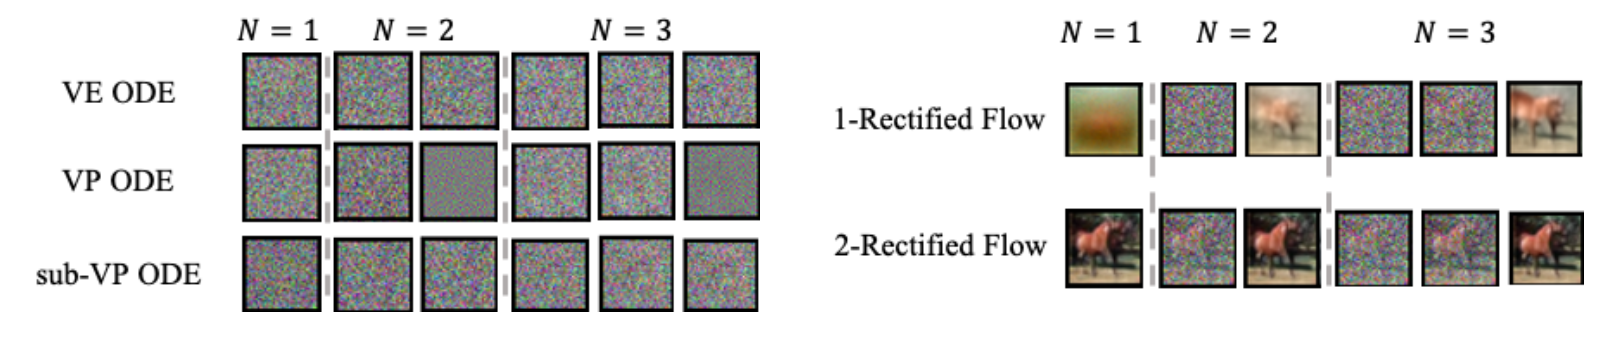
We conduct unconditional image generation with the CIFAR-10 dataset [36]. The resolution of the images are set to . For rectified flow, we adopt the same network structure as DDPM++ in [73]. The training of the network is smoothed by exponential moving average as in [73], with a ratio of . We adopt Adam [31] optimizer with a learning rate of and a dropout rate of .
For reflow, we first generate 4 million pairs of to get a new dataset , then fine-tune the -rectified flow model for steps to get the -rectified flow model. We further distill these rectified flow models for few-step generation. To get a -step image generator from the -rectified flow, we randomly sample during fine-tuning, instead of randomly sampling . Specifically, for , we replace the L2 loss function with the LPIPS similarity [96] since it empirically brings better performance.
In this experiment, we also adopt the same U-Net structure of DDPM++ [73] for representing the drift . We follow the procedure in Algorithm 1. For the purpose of generative modeling, we set to be one domain dataset and the other domain dataset. For optimization, we use AdamW [45] optimizer with , weight decay and dropout rate . We train the model with a batch size of for epochs. We further apply exponential moving average (EMA) optimizer with coefficient . We perform grid-search on the learning rate from and pick the model with the lowest training loss.
We use the AFHQ [9], MetFace [28] and CelebA-HQ [27] dataset. Animal Faces HQ (AFHQ) is an animal-face dataset consisting of 15,000 high-quality images at resolution. The dataset includes three domains of cat, dog, and wild animals, each providing 5000 images. MetFace consists of 1,336 high-quality PNG human-face images at resolution, extracted from works of art. CelebA-HQ is a human-face dataset which consists of 30,000 images at resolution. We randomly select as the training data and regard the rest as the test data, and resize the image to .
For training the model, we apply AdamW [45] optimizer with batch size , number of iterations k, learning rate , weight decay and OneCycle [69] learning rate schedule.