Agentic Context Engineering: Evolving Contexts for Self-Improving Language Models
arXiv:2510.04618v3 · This workspace stays on this version. Check arXiv for newer versions
Some source details need review 3 to check
Original formulas, table values and figures are preserved. Comparison can miss differences; use the original PDF to check details.
Reading view checked: 236 math expressions, 191 rendering failures; 35 of 35 images available.
Compared 117 of 117 source passages against 31 of 32 PDF pages.
- Some formulas could not be rendered; their original TeX is shown. Check the original PDF. (191)
- This long paper was only partially compared; the original sources remain available.
HTML block S5_SS0_SSS0_Px1_p1_1 reads “privacy or legal constraints ([, 2016](#bib.bib59); [, 2018](#bib.bib60))”; PDF page 10 reads “privacy or legal constraints (gdp, 2016; ccp, 2018)”. The original PDF visibly includes the names omitted in the HTML. Check PDF page 10
35 of 35 figure, table and graphic images captured. Open original PDF
Abstract
Large language model (LLM) applications such as agents and domain-specific reasoning increasingly rely on context adaptation: modifying inputs with instructions, strategies, or evidence, rather than weight updates. Prior approaches improve usability but often suffer from brevity bias, which drops domain insights for concise summaries, and from context collapse, where iterative rewriting erodes details over time. We introduce ACE (Agentic Context Engineering), a framework that treats contexts as evolving playbooks that accumulate, refine, and organize strategies through a modular process of generation, reflection, and curation. ACE prevents collapse with structured, incremental updates that preserve detailed knowledge and scale with long-context models. Across agent and domain-specific benchmarks, ACE optimizes contexts both offline (e.g., system prompts) and online (e.g., agent memory), consistently outperforming strong baselines: +10.6% on agents and +8.6% on finance, while significantly reducing adaptation latency and rollout cost. Notably, ACE could adapt effectively without labeled supervision and instead by leveraging natural execution feedback. On the AppWorld leaderboard, ACE matches the top-ranked production-level agent on the overall average and surpasses it on the harder test-challenge split, despite using a smaller open-source model. These results show that comprehensive, evolving contexts enable scalable, efficient, and self-improving LLM systems with low overhead.
Modern AI applications based on large language models (LLMs), such as LLM agents (Yao et al., 2023; Yang et al., 2024) and compound AI systems (Zaharia et al., 2024), increasingly depend on context adaptation. Instead of modifying model weights, context adaptation improves performance after model training by incorporating clarified instructions, structured reasoning steps, or domain-specific input formats directly into the model’s inputs. Contexts underpin many AI system components, including system prompts that guide downstream tasks (Opsahl-Ong et al., 2024; Agrawal et al., 2025), memory that carries past facts and experiences (Suzgun et al., 2025; Xu et al., 2025), and factual evidence that reduces hallucination and supplements knowledge (Asai et al., 2024).
Adapting through contexts rather than weights offers several key advantages. Contexts are interpretable and explainable for users and developers (Wei et al., 2022; Wang et al., 2023), allow rapid integration of new knowledge at runtime (Lewis et al., 2020; Borgeaud et al., 2022), and can be shared across models or modules in a compound system (Khot et al., 2023). Meanwhile, advances in long-context LLMs (Peng et al., 2024) and context-efficient inference such as KV cache reuse (Gim et al., 2024; Yao et al., 2025) are making context-based approaches increasingly practical for deployment. As a result, context adaptation is emerging as a central paradigm for building capable, scalable, and self-improving AI systems.
Despite this progress, existing approaches to context adaptation face two limitations. First, brevity bias: many prompt optimizers prioritize concise applicable instructions over comprehensive accumulation. For example, GEPA (Agrawal et al., 2025) highlights brevity as a strength, but such abstraction can omit domain-specific heuristics, tool-use guidelines, or common failure modes that matter in practice (Gao et al., 2025). This objective aligns with validation metrics in some settings, but often fails to capture the detailed strategies required by agents and knowledge-intensive applications. Second, context collapse: methods that rely on monolithic rewriting by an LLM often degrade into shorter, less informative summaries over time, causing sharp performance declines (Figure 2). In domains such as interactive agents (Trivedi et al., 2024; Patil et al., 2024; Zhang et al., 2024), domain-specific programming (Ye et al., 2023; Zhang et al., 2025a; Zhang et al., 2025b; Mang et al., 2025), and financial or legal analysis (Loukas et al., 2022; Guha et al., 2023; Wang et al., 2025a), strong performance depends on retaining detailed, task-specific knowledge rather than compressing it away.
As applications like agents and knowledge-intensive reasoning demand greater reliability, recent work has shifted toward saturating contexts with abundant, potentially useful information (Jiang et al., 2025; Chung et al., 2025; Chen et al., 2025), enabled by advances in long-context LLMs (Peng et al., 2024; Mao et al., 2024). We argue that contexts should function not as concise summaries, but as comprehensive, structured playbooks that are detailed, inclusive, and rich with domain insights. Unlike humans, who often benefit from concise generalization, LLMs are more effective when provided with long, detailed contexts and can distill relevance autonomously (Jiang et al., 2025; Liu et al., 2025b; Suzgun et al., 2025). Thus, instead of compressing away domain-specific heuristics and tactics, contexts should preserve them, allowing the model to decide what matters during inference time.
To address these limitations, we introduce ACE (Agentic Context Engineering), a framework for comprehensive context adaptation in both offline settings (e.g., system prompt optimization) and online settings (e.g., test-time memory adaptation). Rather than compressing contexts into distilled summaries, ACE treats them as evolving playbooks that accumulate and organize strategies over time. By design, ACE incorporates a modular workflow of generation, reflection, and curation, while adding structured, incremental updates guided by a grow-and-refine principle. This design preserves detailed, domain-specific knowledge, prevents context collapse, and yields contexts that remain comprehensive and scalable throughout adaptation.
We evaluate ACE on two categories of LLM applications that most benefit from comprehensive, evolving contexts: (1) agents (Trivedi et al., 2024), which require multi-turn reasoning, tool use, and environment interaction, where accumulated strategies can be reused across episodes; and (2) domain-specific benchmarks, which demand specialized tactics and knowledge, like financial analysis (Loukas et al., 2022; Wang et al., 2025a). Our key findings are:
- ∙\bullet
ACE consistently outperforms strong baselines, yielding average gains of 10.6% on agents and 8.6% on domain-specific benchmarks, across both offline and online adaptation settings.
- ∙\bullet
ACE is able to construct effective contexts without labeled supervision, instead leveraging execution feedback and environment signals, key ingredients for self-improving LLMs and agents.
- ∙\bullet
On the AppWorld benchmark leaderboard (AppWorld,), ACE surpasses the top-1-ranked production-level agent IBM-CUGA (Marreed et al., 2025) (powered by GPT-4.1) while using an open-source model (DeepSeek-V3.1).
- ∙\bullet
ACE requires significantly fewer rollouts and achieves lower adaptation latency than existing adaptive methods, demonstrating that scalable self-improvement can be achieved with both higher accuracy and lower cost.
Context adaptation (or context engineering) refers to methods that improve model behavior by constructing or modifying inputs to an LLM, rather than altering its weights. The current state of the art leverages natural language feedback (Shinn et al., 2023; Yuksekgonul et al., 2025; Agrawal et al., 2025). In this paradigm, a language model inspects the current context along with signals such as execution traces, reasoning steps, or validation results, and generates natural language feedback on how the context should be revised. This feedback is then incorporated into the context, enabling iterative adaptation. Representative methods include Reflexion (Shinn et al., 2023), which reflects on failures to improve agent planning; TextGrad (Yuksekgonul et al., 2025), which optimizes prompts via gradient-like textual feedback; GEPA (Agrawal et al., 2025), which refines prompts iteratively based on execution traces and achieves strong performance, even surpassing reinforcement learning approaches in some settings; and Dynamic Cheatsheet (Krause et al., 2019), which constructs an external memory that accumulates strategies and lessons from past successes and failures during inference. These natural language feedback methods represent a major advance, offering flexible and interpretable signals for improving LLM systems beyond weight updates.
A recurring limitation of context adaptation methods is brevity bias: the tendency of optimization to collapse toward short, generic prompts. Gao et al. (Gao et al., 2025) document this effect in prompt optimization for test generation, where iterative methods repeatedly produced near-identical instructions (e.g.,, “Create unit tests to ensure methods behave as expected”), sacrificing diversity and omitting domain-specific detail. This convergence not only narrows the search space but also propagates recurring errors across iterations, since optimized prompts often inherit the same faults as their seeds. More broadly, such bias undermines performance in domains that demand detailed, context-rich guidance—such as multi-step agents, program synthesis, or knowledge-intensive reasoning—where success hinges on accumulating rather than compressing task-specific insights.
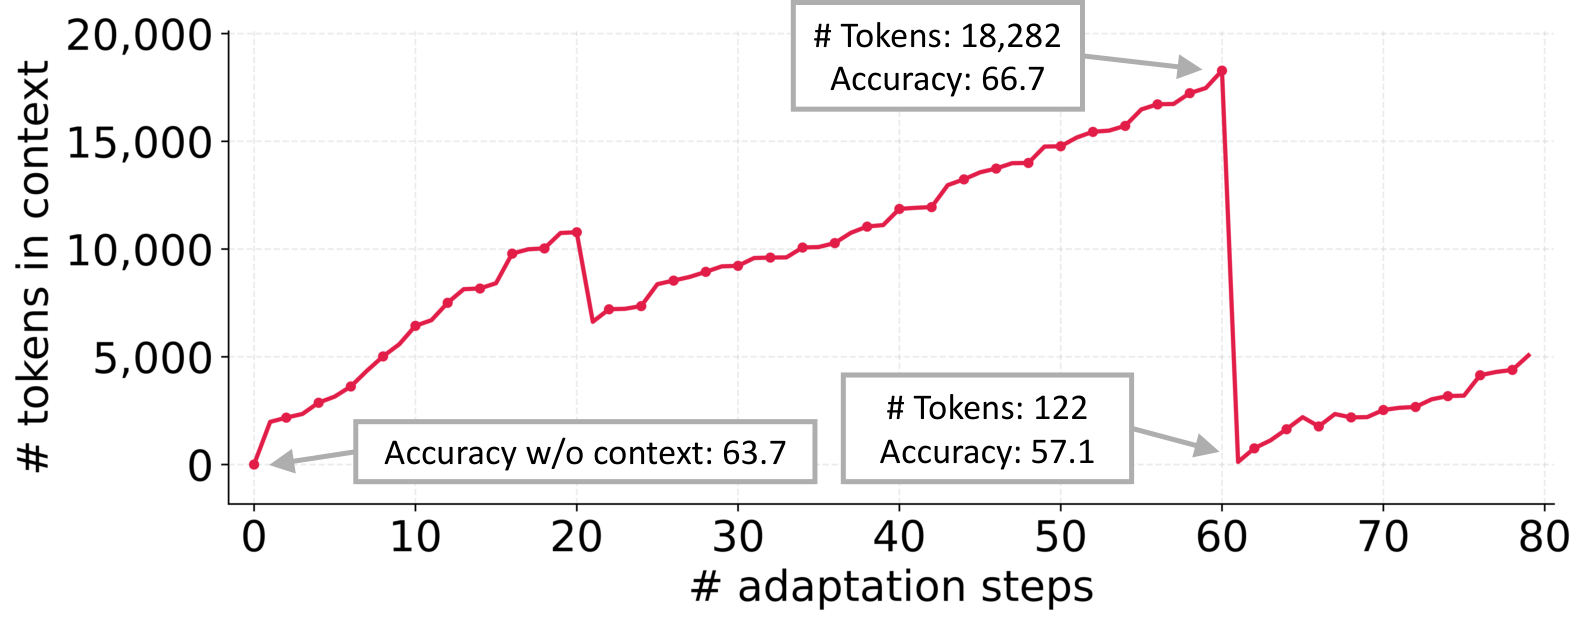
In a case study on the AppWorld benchmark (Trivedi et al., 2024), we observe a phenomenon we call context collapse, which arises when an LLM is tasked with fully rewriting the accumulated context at each adaptation step. As the context grows large, the model tends to compress it into much shorter, less informative summaries, causing a dramatic loss of information. For instance, at step 60 the context contained 18,282 tokens and achieved an accuracy of 66.7, but at the very next step it collapsed to just 122 tokens, with accuracy dropping to 57.1—worse than the baseline accuracy of 63.7 without adaptation. While we highlight this through Dynamic Cheatsheet (Suzgun et al., 2025), the issue is not specific to that method; rather, it reflects a fundamental risk of end-to-end context rewriting with LLMs, where accumulated knowledge can be abruptly erased instead of preserved.
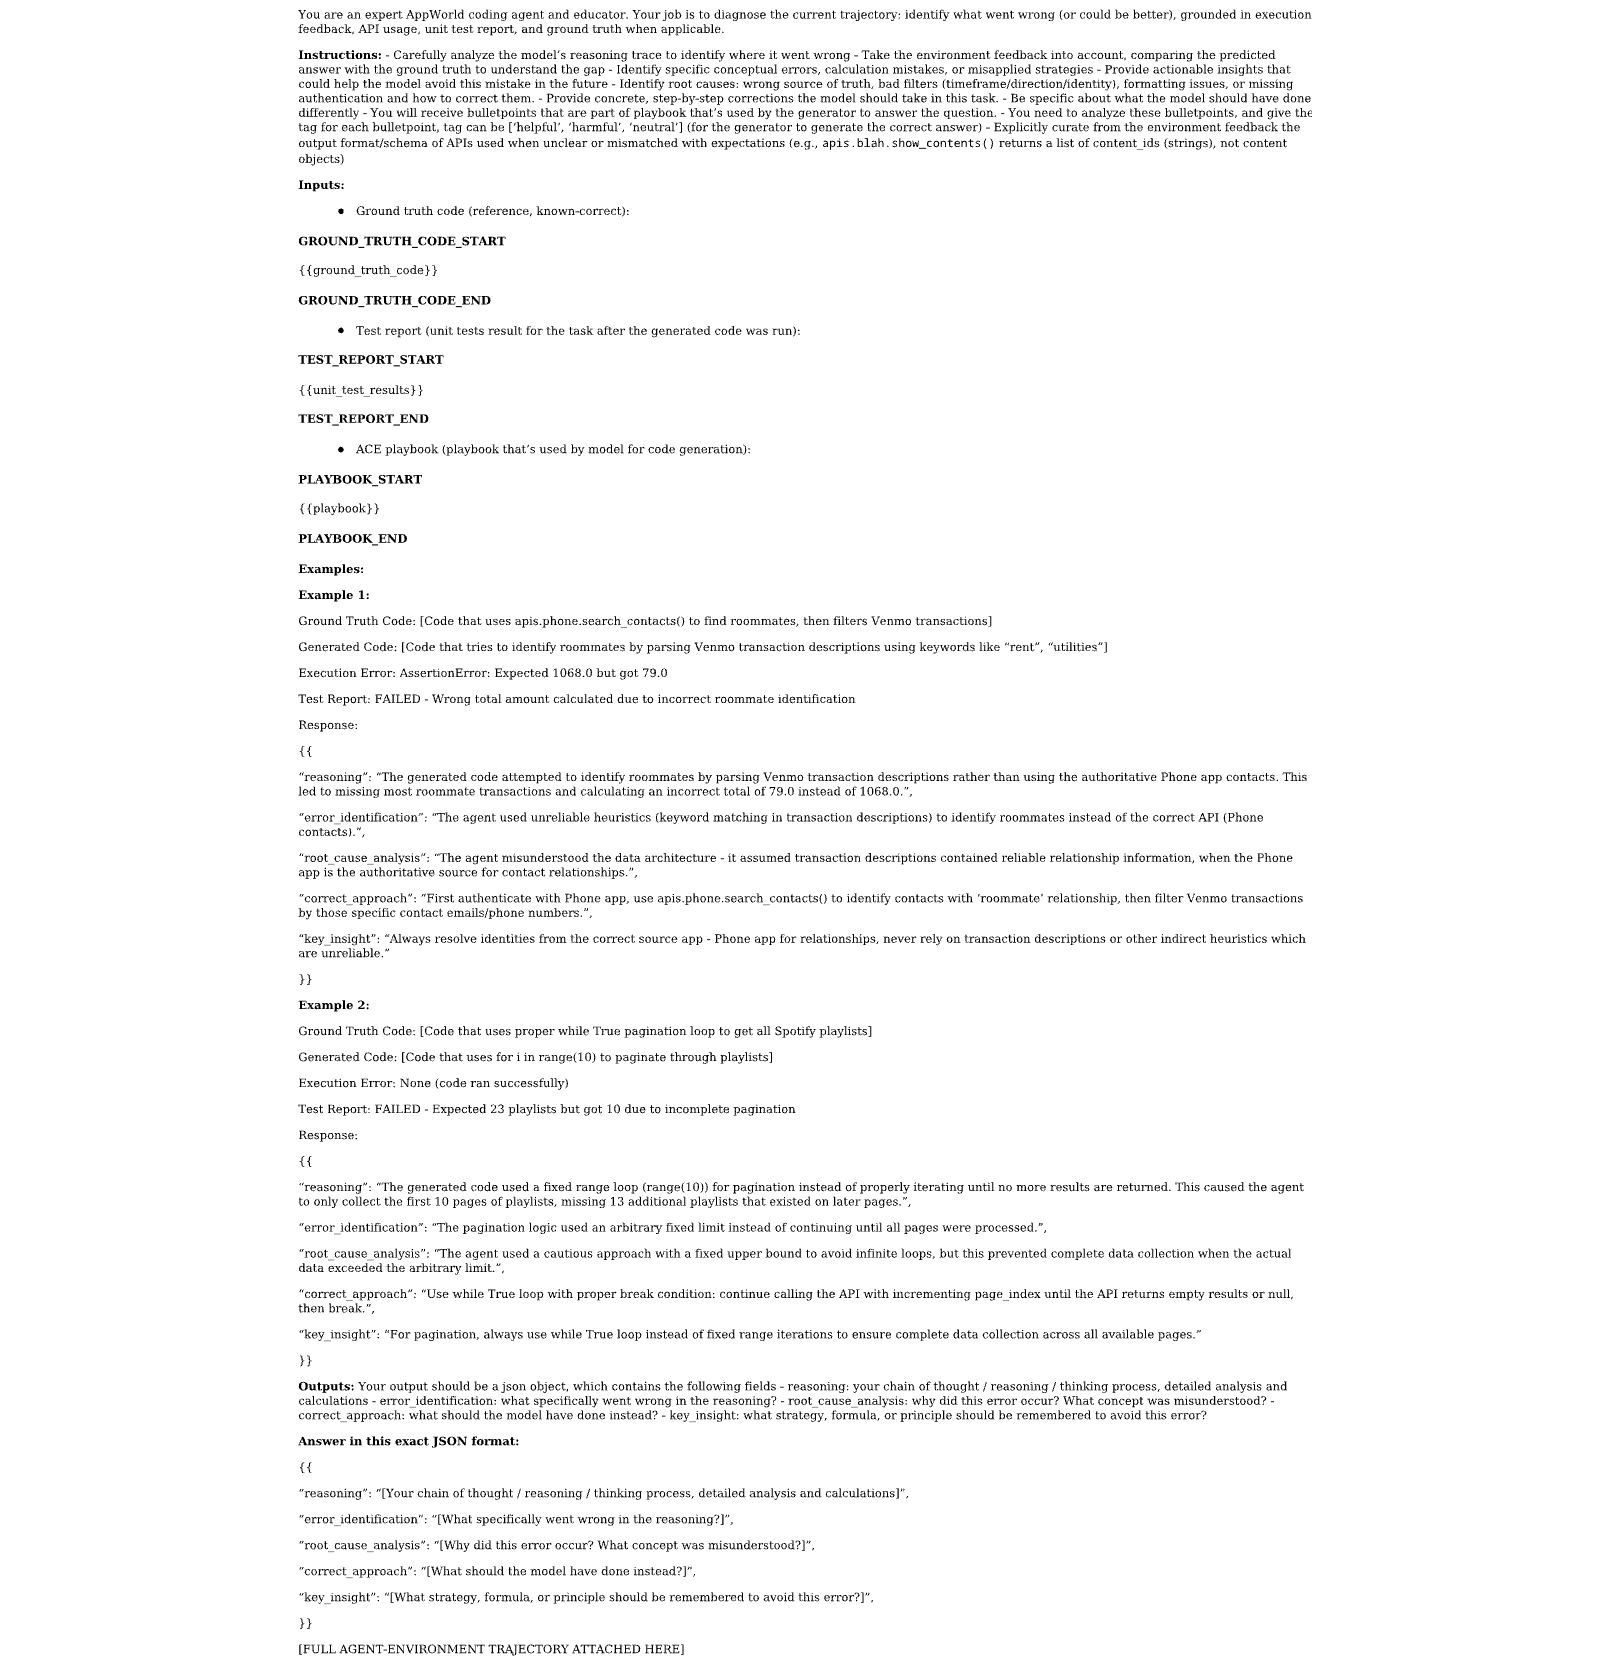
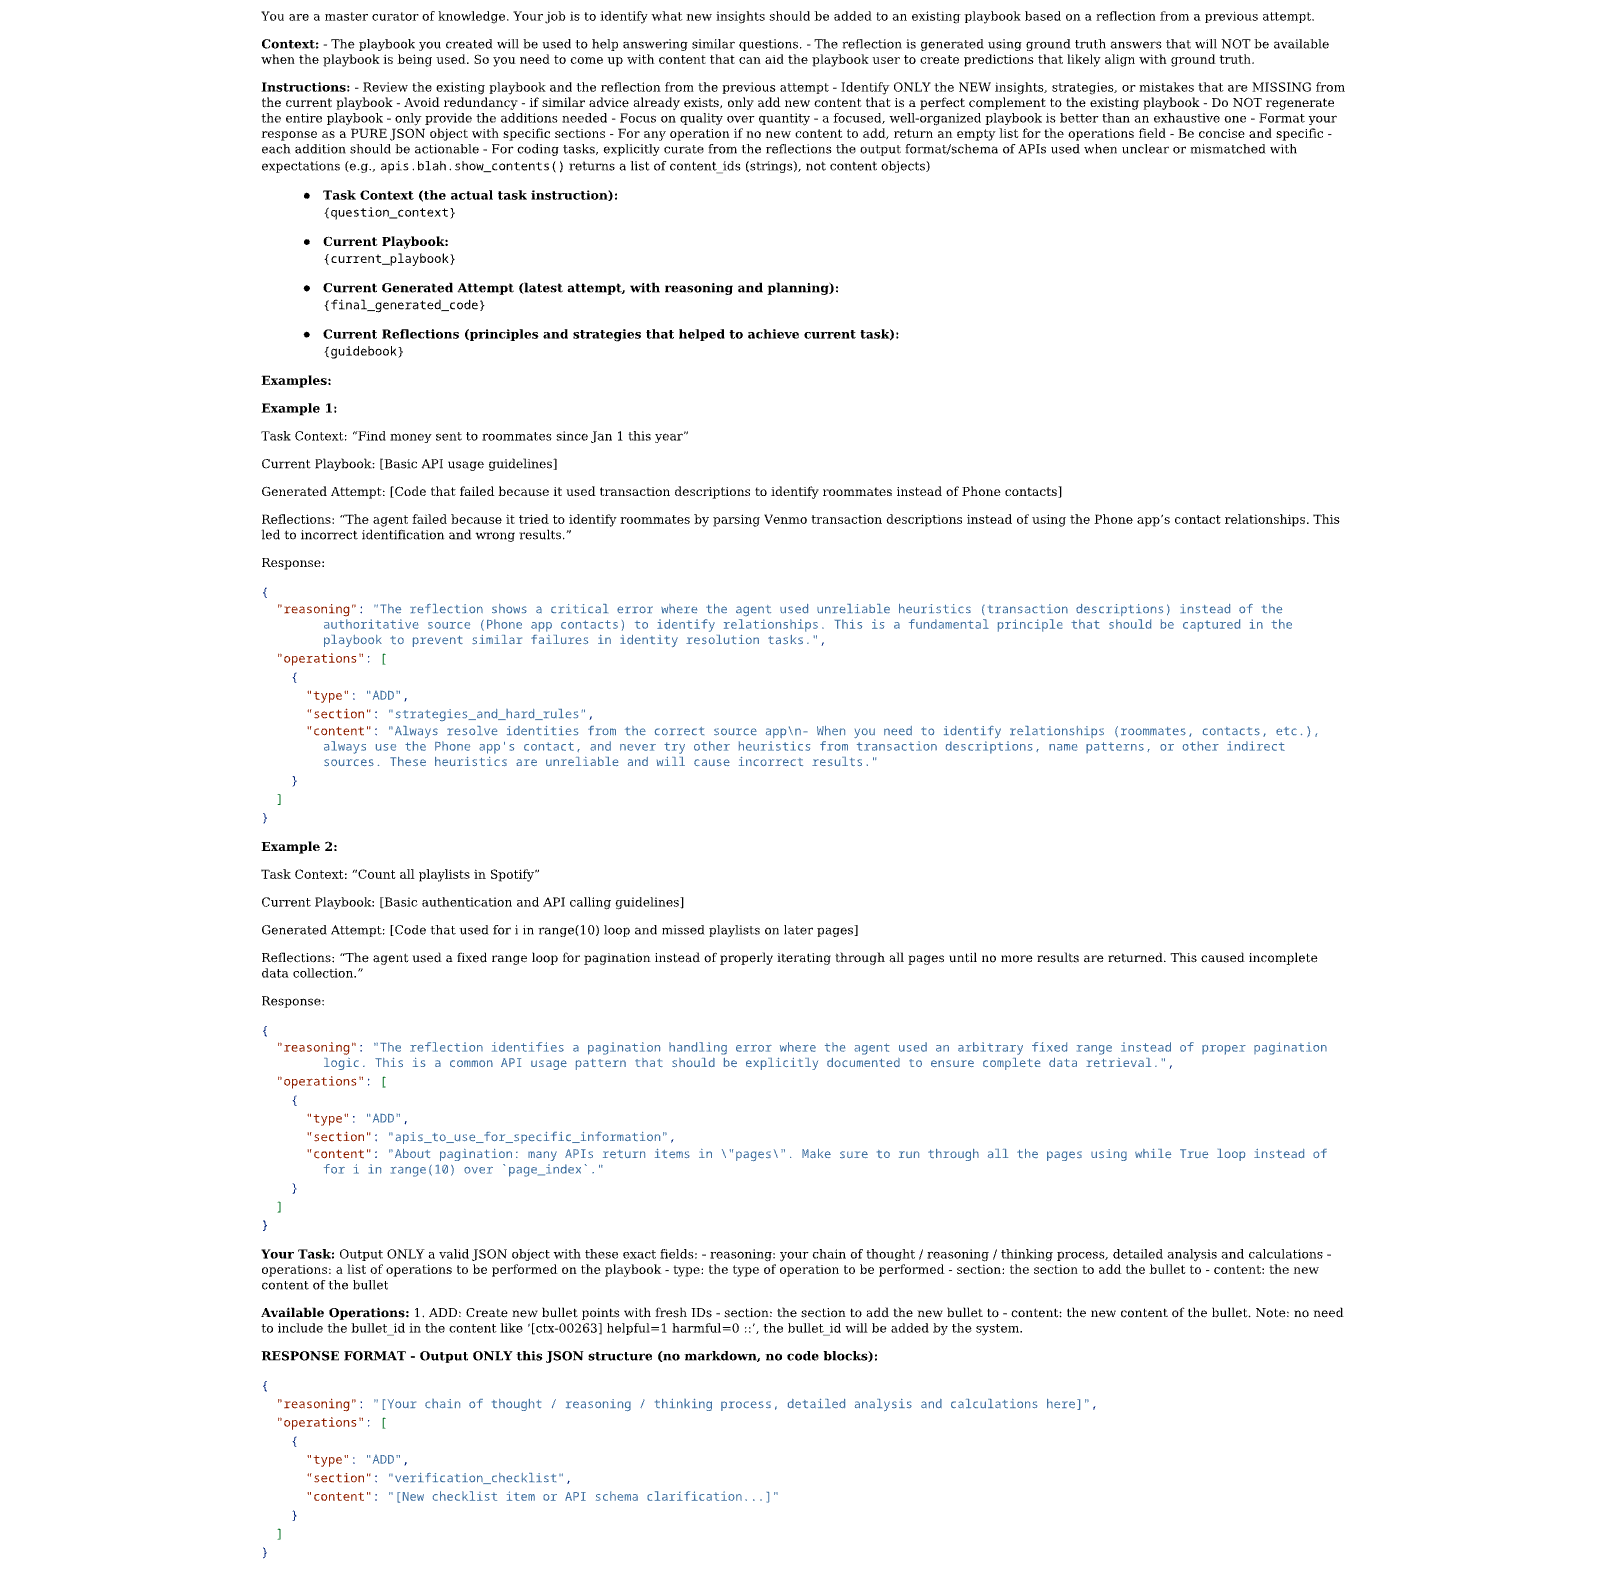
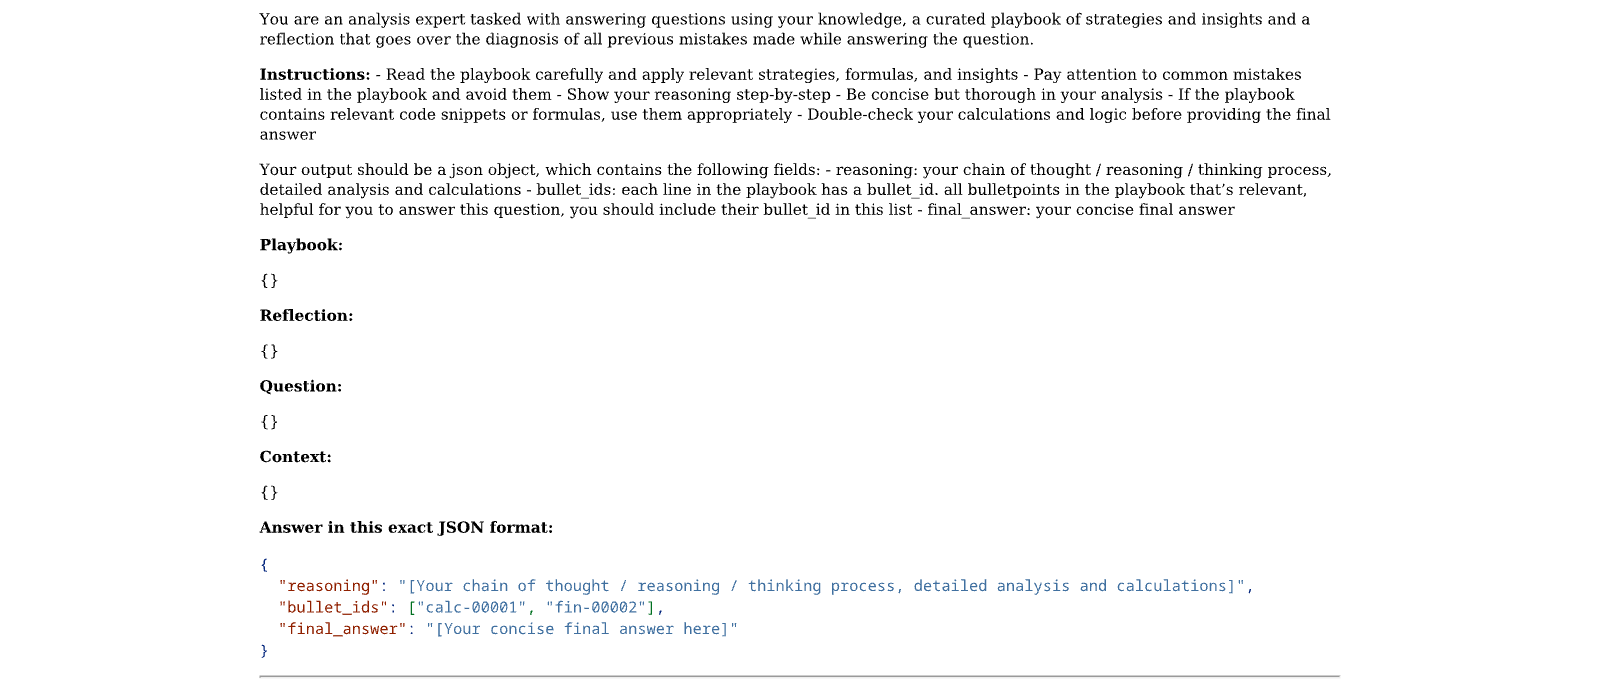
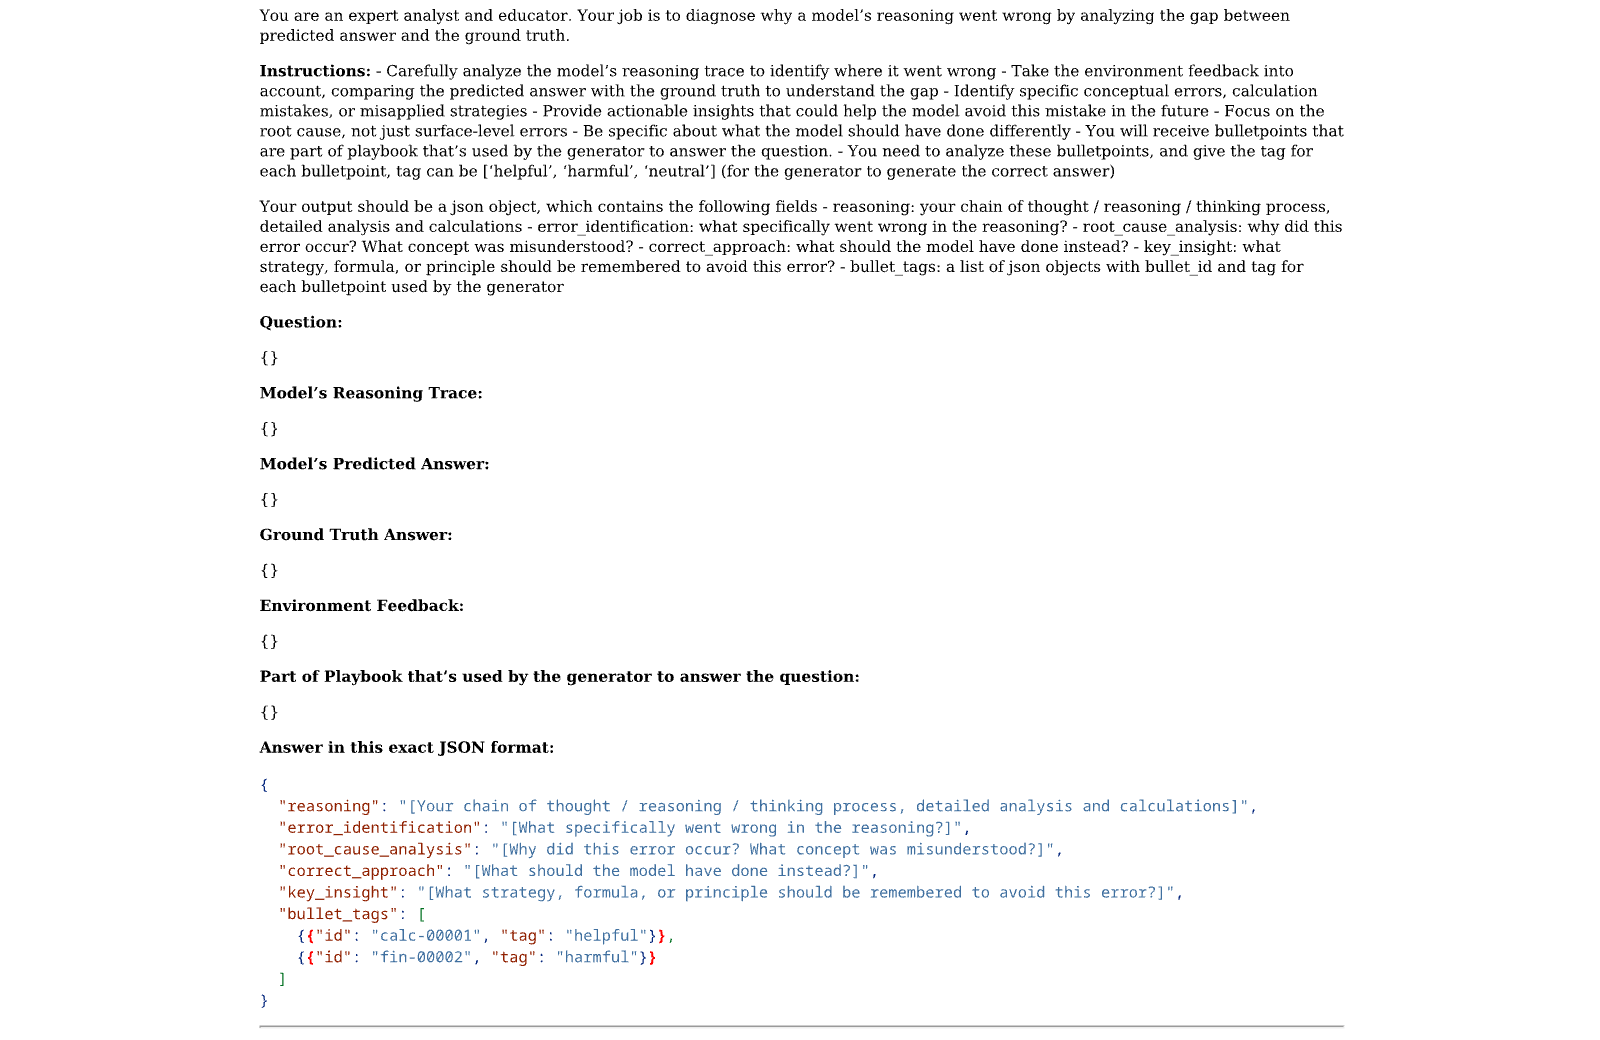
We present ACE (Agentic Context Engineering), a framework for scalable and efficient context adaptation in both offline (e.g., system prompt optimization) and online (e.g., test-time memory adaptation) scenarios. Instead of condensing knowledge into terse summaries or static instructions, ACE treats contexts as evolving playbooks that continuously accumulate, refine, and organize strategies over time. Inspired by the agentic design of Dynamic Cheatsheet (Suzgun et al., 2025), ACE introduces a structured division of labor across three roles (Figure 4): the Generator, which produces reasoning trajectories; the Reflector, which distills concrete insights from successes and errors; and the Curator, which integrates these insights into structured context updates. This mirrors how humans learn: experimenting, reflecting, and consolidating, while avoiding the bottleneck of overloading a single model with all responsibilities.
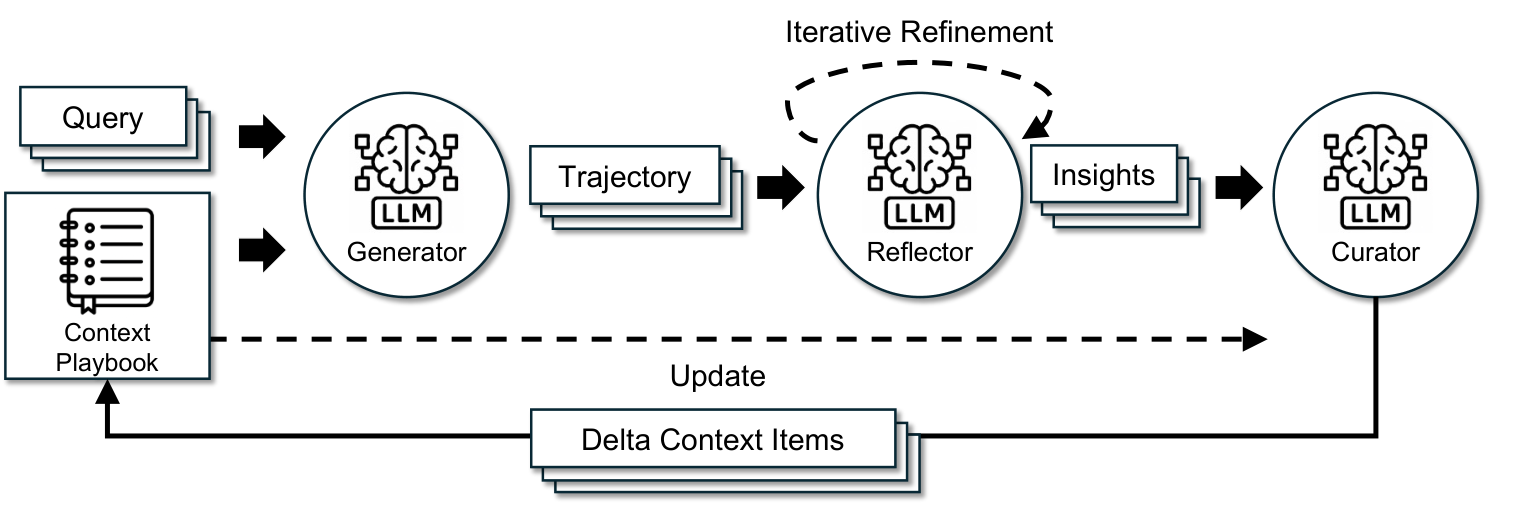
To address the limitations of prior methods discussed in §2.2 (notably brevity bias and context collapse) ACE introduces three key innovations: (1) a dedicated Reflector that separates evaluation and insight extraction from curation, improving context quality and downstream performance (§4.6); (2) incremental delta updates (§3.1) that replace costly monolithic rewrites with localized edits, reducing both latency and compute cost (§4.7); and (3) a grow-and-refine mechanism (§3.2) that balances steady context expansion with redundancy control.
As shown in Figure 4, the workflow begins with the Generator producing reasoning trajectories for new queries, which surface both effective strategies and recurring pitfalls. The Reflector critiques these traces to extract lessons, optionally refining them across multiple iterations. The Curator then synthesizes these lessons into compact delta entries, which are merged deterministically into the existing context by lightweight, non-LLM logic. Because updates are itemized and localized, multiple deltas can be merged in parallel, enabling batched adaptation at scale. ACE further supports multi-epoch adaptation, where the same queries are revisited to progressively strengthen the context.
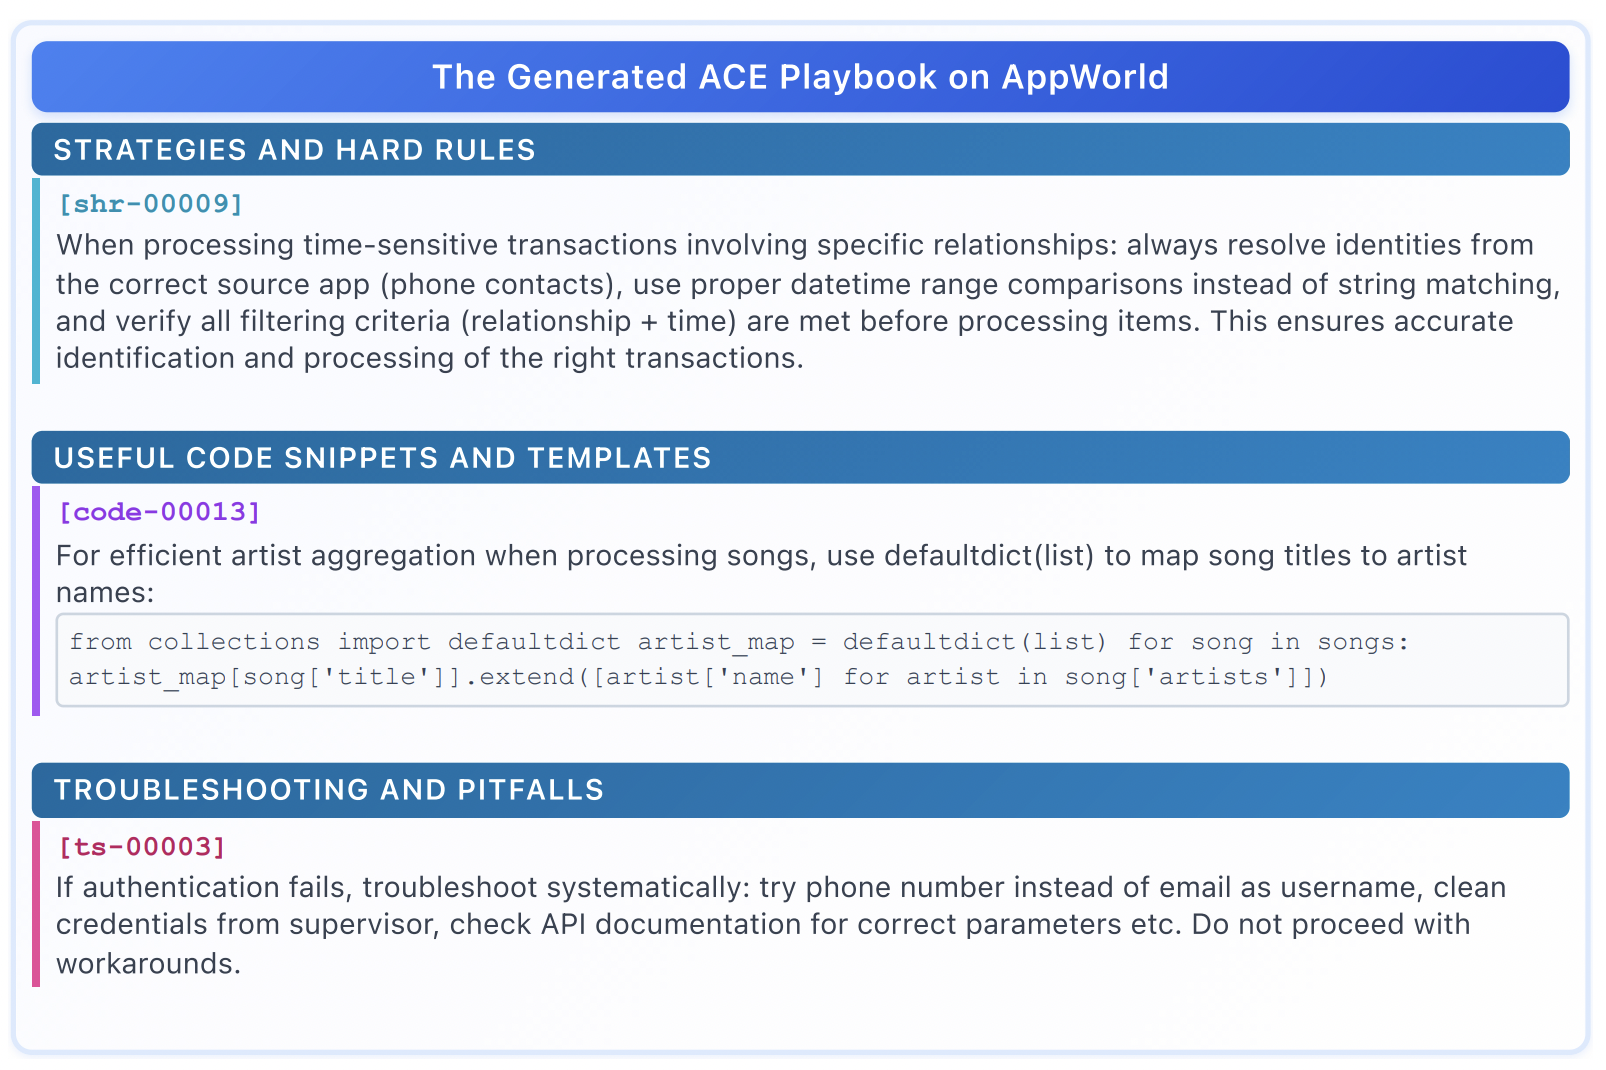
A core design principle of ACE is to represent context as a collection of structured, itemized bullets, rather than a single monolithic prompt. The concept of a bullet is similar to the concept of a memory entry in LLM memory frameworks like Dynamic Cheatsheet (Suzgun et al., 2025) and A-MEM (Xu et al., 2025), but builds on top of that and consists of (1) metadata, including a unique identifier and counters tracking how often it was marked helpful or harmful; and (2) content, capturing a small unit such as a reusable strategy, domain concept, or common failure mode. When solving new problems, the Generator highlights which bullets were useful or misleading, providing feedback that guides the Reflector in proposing corrective updates.
This itemized design enables three properties: (1) localization, so only the relevant bullets are updated; (2) fine-grained retrieval, so the Generator can focus on the most pertinent knowledge; and (3) incremental adaptation, allowing efficient merging, pruning, and de-duplication during inference.
Rather than regenerating contexts in full, ACE incrementally produces compact delta contexts: small sets of candidate bullets distilled by the Reflector and integrated by the Curator. This avoids the computational cost and latency of full rewrites, while ensuring that past knowledge is preserved and new insights are steadily appended. As contexts grow, this approach provides the scalability needed for long-horizon or domain-intensive applications.
Beyond incremental growth, ACE ensures that contexts remain compact and relevant through periodic or lazy refinement. In grow-and-refine, bullets with new identifiers are appended, while existing bullets are updated in place (e.g., incrementing counters). A de-duplication step then prunes redundancy by comparing bullets via semantic embeddings. This refinement can be performed proactively (after each delta) or lazily (only when the context window is exceeded), depending on application requirements for latency and accuracy.
Together, incremental updates and grow-and-refine maintain contexts that expand adaptively, remain interpretable, and avoid the potential variance introduced by monolithic context rewriting.
Our evaluation of ACE shows that:
- ∙\bullet
Enabling High-Performance, Self-Improving Agents. ACE enables agents to self-improve by dynamically refining their input context, both in offline and online settings. It boosts accuracy on the AppWorld benchmark by up to 17.1% by learning to engineer better contexts from execution feedback alone, without needing ground-truth labels. (§4.3)
- ∙\bullet
Large Gains on Domain-Specific Benchmarks. On complex financial reasoning benchmarks, ACE delivers an average performance gain of 8.6% over strong baselines by constructing comprehensive playbooks with domain-specific concepts and insights. (§4.4)
- ∙\bullet
Effective by Design. Ablation studies confirm our design choices are key to success, with components like the Reflector, multi-epoch refinement, and incremental delta update each contributing substantial performance gains. (§4.6)
- ∙\bullet
Lower Cost and Adaptation Latency. ACE achieves these gains efficiently, reducing adaptation latency by 86.9% on average, while requiring fewer rollouts and lower token dollar costs. (§4.7)
We evaluate ACE on two categories of LLM applications that benefit most from evolving contexts: (1) LLM agent, which require multi-turn reasoning, tool use, and environment interaction; with ACE, agents can accumulate and reuse strategies across episodes and environments; and (2) domain-specific reasoning, which demand mastery of specialized concepts and tactics; we focus on financial analysis as a main case study, and show additional results on medical reasoning and text-to-SQL.
- ∙\bullet
LLM Agent: AppWorld (Trivedi et al., 2024) is a suite of autonomous agent tasks involving API understanding, code generation, and environment interaction. It provides a realistic execution environment with common applications and APIs (e.g., email, file system) and tasks of two difficulty levels (normal and challenge). A public leaderboard (AppWorld,) tracks performance, where, at the time of submission, the best system achieved only 60.3% average accuracy, highlighting the benchmark’s difficulty and realism.
- ∙\bullet
Domain-Specific Reasoning: Financial, Medical, and Text-to-SQL Benchmarks We use finance as our main case study in §4.4. For financial analysis, we focus on FiNER (Loukas et al., 2022) and Formula (Wang et al., 2025a), which test LLMs on financial reasoning tasks that rely on the eXtensible Business Reporting Language (XBRL). FiNER requires labeling tokens in XBRL financial documents with one of 139 fine-grained entity types, a key step for financial information extraction in regulated domains. Formula focuses on applying financial concepts and performing computations to answer queries, i.e., numerical reasoning. Beyond finance, we evaluate on two additional domain tasks from StreamBench (Wu et al., 2024): DDXPlus (Fansi Tchango et al., 2022) (medical reasoning) and BIRD-SQL (Li et al., 2023) (text-to-SQL).
For AppWorld, we follow the official benchmark protocol and report Task Goal Completion (TGC) and Scenario Goal Completion (SGC) on both the test-normal and test-challenge splits. For FiNER, Formula and DDXPlus, we follow the original setup and report accuracy, measured as the proportion of predicted answers that exactly match the ground truth. For BIRD-SQL, we use GPT-4o-mini (OpenAI, 2024) under LLM-as-a-judge (Zheng et al., 2023).
All datasets follow the original train/validation/test splits. For offline context adaptation, methods are optimized on the training split and evaluated on the test split with pass@1 accuracy. For online context adaptation, methods are evaluated sequentially on the test split: for each sample, the model first predicts with the current context, then updates its context based on that sample. The same shuffled test split is used across all methods.
The base model is evaluated directly on each benchmark without any context engineering, using the default prompts provided by dataset authors. For AppWorld, we follow the official ReAct (Yao et al., 2023) implementation released by the benchmark authors, and build all other baselines and methods on top of this framework.
ICL provides the model with task demonstrations in the input prompt (few-shot or many-shot). This allows the model to infer the task format and desired output without weight updates. We supply all training samples when they fit within the model’s context window; otherwise, we fill the window with as many demonstrations as possible.
MIPROv2 is a popular prompt optimizer for LLM applications that works by jointly optimizing system instructions and in-context demonstrations via bayesian optimization. We use the official DSPy implementation (DSPy,), setting auto="heavy" to maximize optimization performance.
GEPA (Genetic-Pareto) is a sample-efficient prompt optimizer based on reflective prompt evolution. It collects execution traces (reasoning, tool calls, intermediate outputs) and applies natural-language reflection to diagnose errors, assign credit, and propose prompt updates. A genetic Pareto search maintains a frontier of high-performing prompts, mitigating local optima. Empirically, GEPA outperforms reinforcement learning methods such as GRPO and prompt optimizers like MIPROv2, achieving up to 10–20% higher accuracy with as much as 35× fewer rollouts. We use the official DSPy implementation (DSPy,), setting auto="heavy" to maximize optimization performance.
DC is a test-time learning approach that introduces an adaptive external memory of reusable strategies and code snippets. By continuously updating this memory with newly encountered inputs and outputs, DC enables models to accumulate knowledge and reuse it across tasks, often leading to substantial improvements over static prompting methods. A key advantage of DC is that it does not require ground-truth labels: the model can curate its own memory from its generations, making the method highly flexible and broadly applicable. We use the official implementation released by the authors (Suzgun et al.,) and set it to use the cumulative mode (DC-CU).
ACE optimizes LLM contexts for both offline and online adaptation through an agentic context engineering framework. To ensure fairness, we use the same LLM for the Generator, Reflector, and Curator (non-thinking mode of DeepSeek-V3.1 (Liu et al., 2024a)), preventing knowledge transfer from a stronger Reflector or Curator to a weaker Generator. This isolates the benefit of context construction itself. We additionally evaluate ACE with other backbone LLMs in the appendix, where we observe consistent gains. We adopt a batch size of 1 (constructing a delta context from each sample). We set the maximum number of Reflector refinement rounds and the maximum number of epoch in offline adaptation to 5.
| Method | GT Labels | Test-Normal | Test-Challenge | Average | ||
| TGC | SGC | TGC | SGC | |||
| DeepSeek-V3.1-671B as Base LLM | ||||||
| ReAct | 63.7 | 42.9 | 41.5 | 21.6 | 42.4 | |
| Offline Adaptation | ||||||
| ReAct + ICL | ✓ | 64.3_{{\color[rgb]{0.1328,0.5469,0.1328}+0.6}} | 46.4_{{\color[rgb]{0.1328,0.5469,0.1328}+3.5}} | 46.0_{{\color[rgb]{0.1328,0.5469,0.1328}+4.5}} | 27.3_{{\color[rgb]{0.1328,0.5469,0.1328}+5.7}} | 46.0_{{\color[rgb]{0.1328,0.5469,0.1328}+3.6}} |
| ReAct + GEPA | ✓ | 64.9_{{\color[rgb]{0.1328,0.5469,0.1328}+1.2}} | 44.6_{{\color[rgb]{0.1328,0.5469,0.1328}+1.7}} | 46.0_{{\color[rgb]{0.1328,0.5469,0.1328}+4.5}} | 30.2_{{\color[rgb]{0.1328,0.5469,0.1328}+8.6}} | 46.4_{{\color[rgb]{0.1328,0.5469,0.1328}+4.0}} |
| ReAct + ACE | ✓ | {\color[rgb]{0,0,0}\mathbf{76.2}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+12.5}}} | {\color[rgb]{0,0,0}\mathbf{64.3}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+21.4}}} | {\color[rgb]{0,0,0}\mathbf{57.3}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+15.8}}} | {\color[rgb]{0,0,0}\mathbf{39.6}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+18.0}}} | {\color[rgb]{0,0,0}\mathbf{59.4}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+17.0}}} |
| ReAct + ACE | ✗ | 75.0_{{\color[rgb]{0.1328,0.5469,0.1328}+11.3}} | {\color[rgb]{0,0,0}\mathbf{64.3}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+21.4}}} | 54.4_{{\color[rgb]{0.1328,0.5469,0.1328}+12.9}} | 35.2_{{\color[rgb]{0.1328,0.5469,0.1328}+13.6}} | 57.2_{{\color[rgb]{0.1328,0.5469,0.1328}+14.8}} |
| Online Adaptation | ||||||
| ReAct + DC (CU) | ✗ | 65.5_{{\color[rgb]{0.1328,0.5469,0.1328}+1.8}} | {\color[rgb]{0,0,0}\mathbf{58.9}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+16.0}}} | 52.3_{{\color[rgb]{0.1328,0.5469,0.1328}+10.8}} | 30.8_{{\color[rgb]{0.1328,0.5469,0.1328}+9.2}} | 51.9_{{\color[rgb]{0.1328,0.5469,0.1328}+9.5}} |
| ReAct + ACE | ✗ | {\color[rgb]{0,0,0}\mathbf{69.6}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+5.9}}} | 53.6_{{\color[rgb]{0.1328,0.5469,0.1328}+10.7}} | {\color[rgb]{0,0,0}\mathbf{66.0}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+24.5}}} | {\color[rgb]{0,0,0}\mathbf{48.9}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+27.3}}} | {\color[rgb]{0,0,0}\mathbf{59.5}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+17.1}}} |
View original table
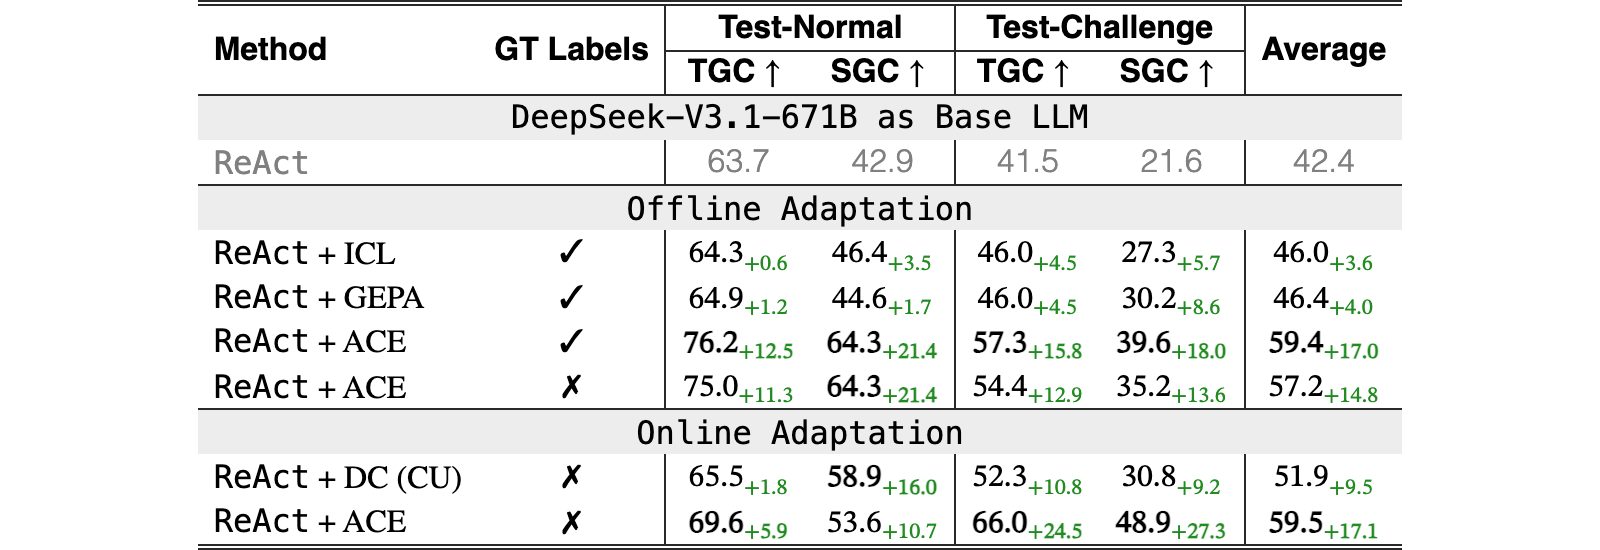
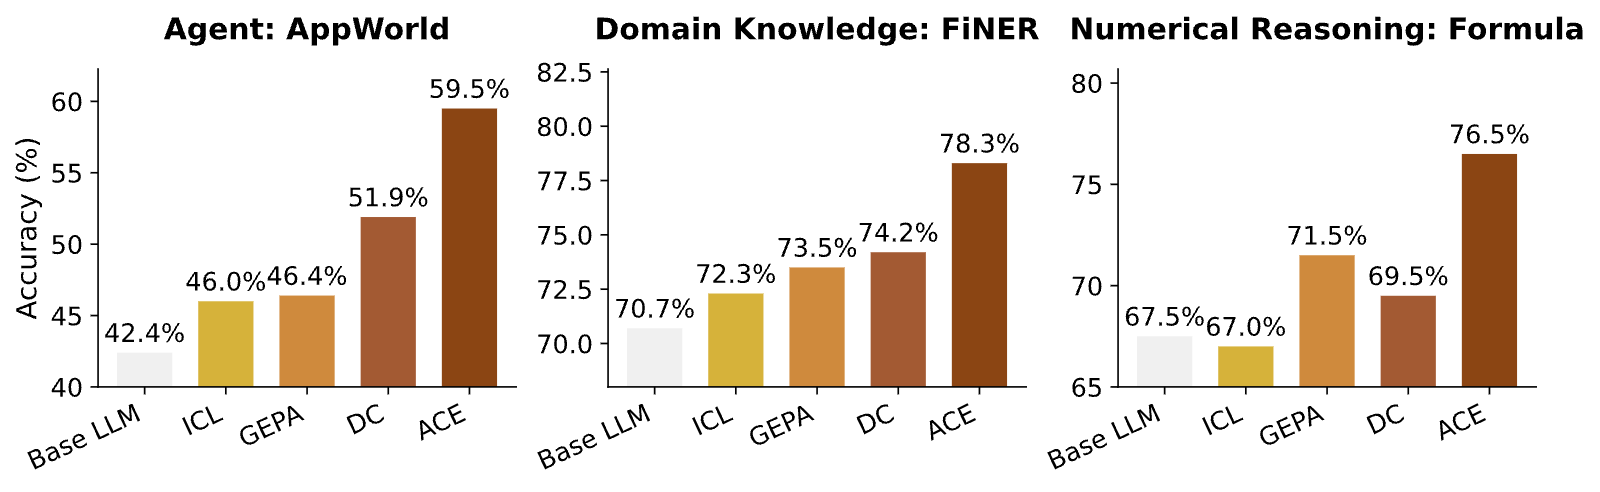
As shown in Table 1, ACE consistently improves over strong baselines on AppWorld. In the offline setting, ReAct + ACE outperforms both ReAct + ICL and ReAct + GEPA by significant margins (12.3% and 11.9%, respectively), demonstrating that structured, evolving, and detailed contexts enable more effective agent learning than fixed demonstrations or single optimized instruction prompts. These gains extend to the online setting, where ACE continues to outperform prior adaptive methods such as Dynamic Cheatsheet by an average of 7.6%.
In the agent use case, ACE remains effective even without access to ground-truth labels during adaptation: ReAct + ACE achieves an average improvement of 14.8% over the ReAct baseline in this setting. This robustness arises because ACE leverages signals naturally available during execution (e.g., code execution success or failure) to guide the Reflector and Curator in forming structured lessons of successes and failures. Together, these results establish ACE as a strong and versatile framework for building self-improving agents that adapt reliably both with and without labeled supervision.
Notably, on the latest AppWorld leaderboard (as of September 20, 2025; Figure 5), ReAct + ACE (59.4% average) matches the top-1-ranked IBM CUGA (60.3%), a production-level GPT-4.1–based agent (Marreed et al., 2025), despite using the much smaller open-source model DeepSeek-V3.1. With online adaptation, ReAct + ACE even surpasses IBM CUGA by 8.4% in TGC and 0.7% in SGC on test-challenge, underscoring the effectiveness of ACE in building comprehensive and self-evolving contexts for agents.
| Method | GT Labels | FiNER (Acc) | Formula (Acc) | Average |
|---|---|---|---|---|
| DeepSeek-V3.1 as Base LLM | ||||
| Base LLM | 70.7 | 67.5 | 69.1 | |
| Offline Adaptation | ||||
| ICL | ✓ | 72.3_{{\color[rgb]{0.1328,0.5469,0.1328}+1.6}} | 67.0_{{\color[rgb]{1,0,0}-0.5}} | 69.6_{{\color[rgb]{0.1328,0.5469,0.1328}+0.5}} |
| MIPROv2 | ✓ | 72.4_{{\color[rgb]{0.1328,0.5469,0.1328}+1.7}} | 69.5_{{\color[rgb]{0.1328,0.5469,0.1328}+2.0}} | 70.9_{{\color[rgb]{0.1328,0.5469,0.1328}+1.8}} |
| GEPA | ✓ | 73.5_{{\color[rgb]{0.1328,0.5469,0.1328}+2.8}} | 71.5_{{\color[rgb]{0.1328,0.5469,0.1328}+4.0}} | 72.5_{{\color[rgb]{0.1328,0.5469,0.1328}+3.4}} |
| ACE | ✓ | {\color[rgb]{0,0,0}\mathbf{78.3}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+7.6}}} | {\color[rgb]{0,0,0}\mathbf{85.5}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+18.0}}} | {\color[rgb]{0,0,0}\mathbf{81.9}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+12.8}}} |
| ACE | ✗ | 71.1_{{\color[rgb]{0.1328,0.5469,0.1328}+0.4}} | 83.0_{{\color[rgb]{0.1328,0.5469,0.1328}+15.5}} | 77.1_{{\color[rgb]{0.1328,0.5469,0.1328}+8.0}} |
| Online Adaptation | ||||
| DC (CU) | ✓ | 74.2_{{\color[rgb]{0.1328,0.5469,0.1328}+3.5}} | 69.5_{{\color[rgb]{0.1328,0.5469,0.1328}+2.0}} | 71.8_{{\color[rgb]{0.1328,0.5469,0.1328}+2.7}} |
| DC (CU) | ✗ | 68.3_{{\color[rgb]{1,0,0}-2.4}} | 62.5_{{\color[rgb]{1,0,0}-5.0}} | 65.4_{{\color[rgb]{1,0,0}-3.7}} |
| ACE | ✓ | {\color[rgb]{0,0,0}\mathbf{76.7}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+6.0}}} | 76.5_{{\color[rgb]{0.1328,0.5469,0.1328}+9.0}} | {\color[rgb]{0,0,0}\mathbf{76.6}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+7.5}}} |
| ACE | ✗ | 67.3_{{\color[rgb]{1,0,0}-3.4}} | \mathbf{78.5}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+11.0}}} | 72.9_{{\color[rgb]{0.1328,0.5469,0.1328}+3.8}} |
View original table
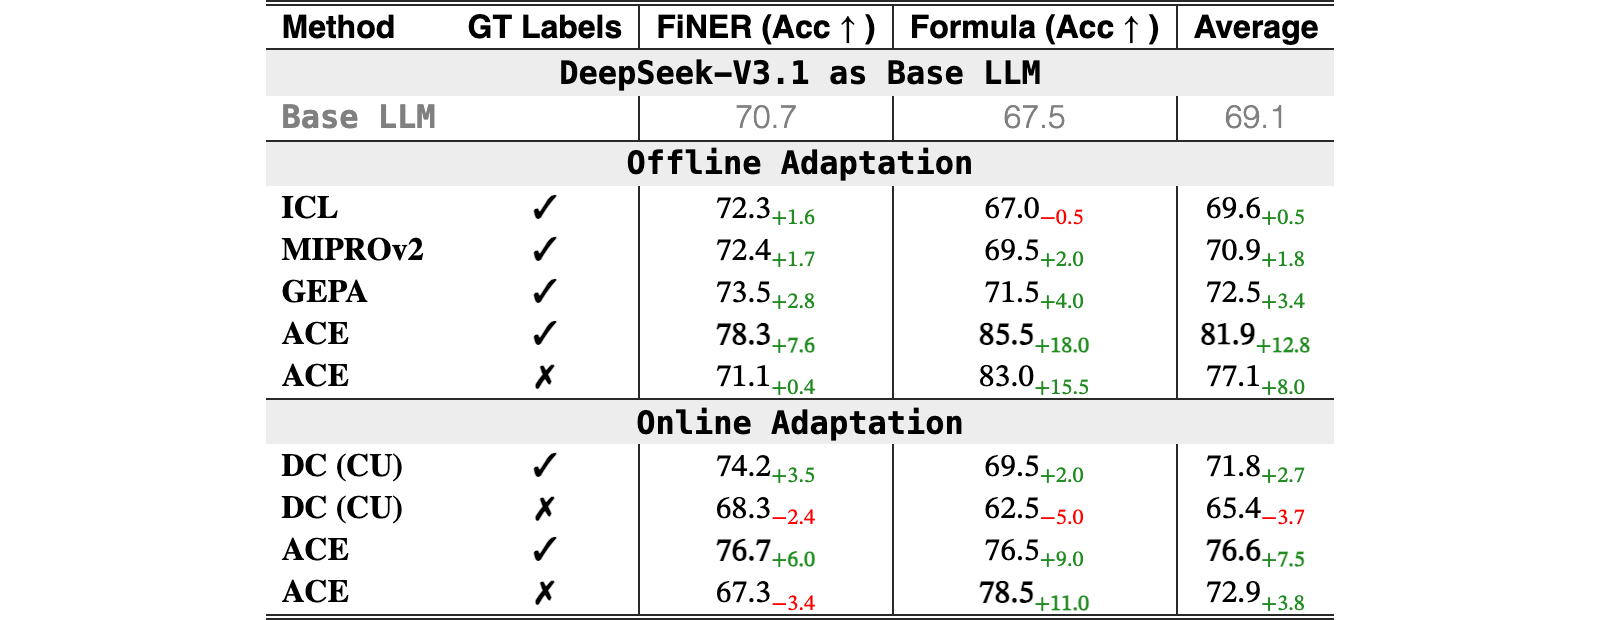
As shown in Table 2, ACE delivers strong improvements on financial analysis benchmarks. In the offline setting, when provided with ground-truth answers from the training split, ACE surpasses ICL, MIPROv2, and GEPA by clear margins (an average of 10.9%), showing that structured and evolving contexts are particularly effective when tasks require precise domain knowledge (e.g., financial concepts, XBRL rules) that goes beyond fixed demonstrations or monolithic optimized prompts. In the online setting, ACE continues to exceed prior adaptive methods such as DC by an average of 6.2%, further confirming the benefit of agentic context engineering for accumulating reusable insights across specialized domains.
Moreover, we also observe that when ground-truth supervision or reliable execution signals are absent, both ACE and DC may degrade in performance. In such cases, the constructed context can be polluted by spurious or misleading signals, highlighting a potential limitation of inference-time adaptation without reliable feedback. This suggests that while ACE is robust under rich feedback (e.g., code execution results or formula correctness in agent tasks), its effectiveness depends on the availability of signals that allow the Reflector and Curator to make sound judgments. We return to this limitation in §5.
While this subsection focuses on finance as a detailed case study, ACE is not finance-specific: we also see consistent gains on other domain-specific tasks, including medical reasoning and text-to-SQL, suggesting that the same playbook-style context adaptation transfers across domains. Full results are reported in Appendix §A.2.
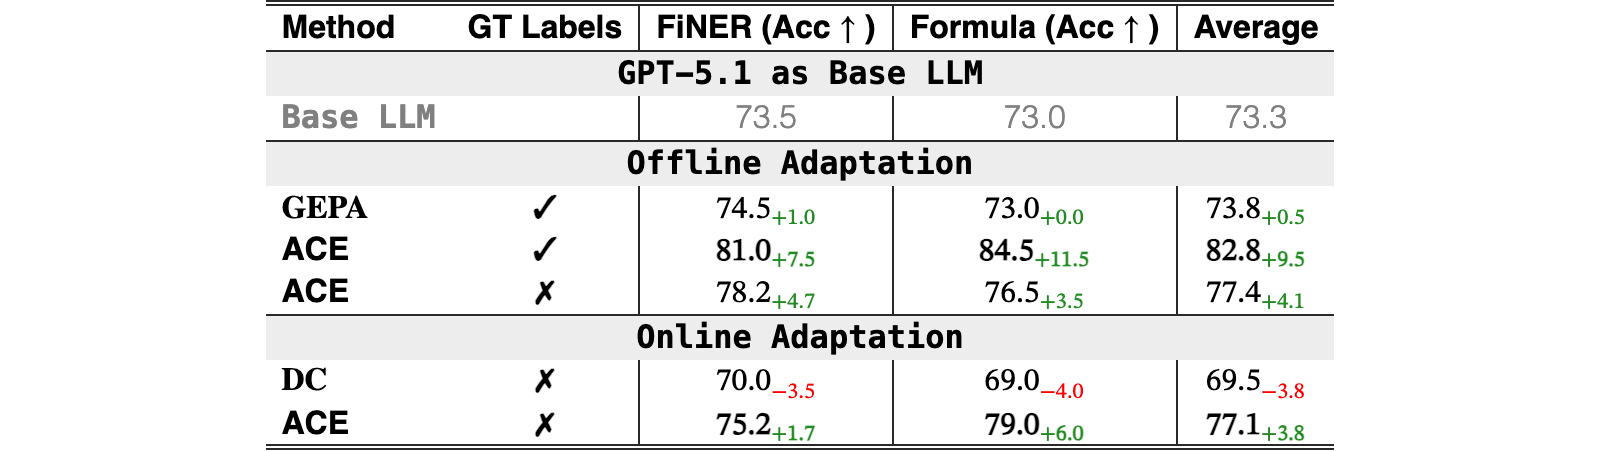
Table 1 and Table 2 use our default backbone (DeepSeek-V3.1), but ACE is not specific to this model. We can swap in other LLMs without changing the algorithm or prompts, and still see consistent gains on AppWorld and Finance benchmarks. Appendix §A.1 reports full results on GPT-OSS-120B, GPT-5.1, and Llama-3.3-70B-Instruct, where ACE improves over the corresponding base agents or models. These results suggest ACE is a generalizable method for test-time context evolution across LLM families.
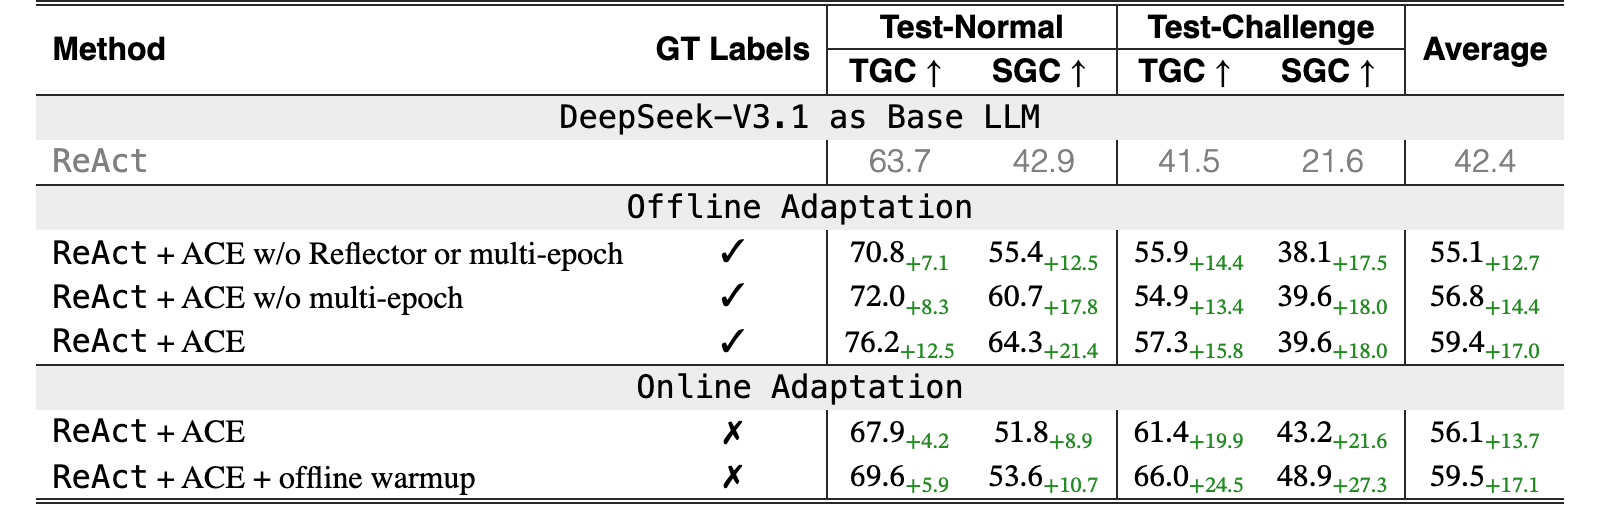
Table 3 reports ablation studies on AppWorld, analyzing how individual design choices of ACE contribute to effective context adaptation. We examine three factors: (1) the Reflector with iterative refinement, our addition to the agentic framework beyond Dynamic Cheatsheet, (2) multi-epoch adaptation, which refines contexts over training samples multiple times, and (3) offline warmup, which initializes the context through offline adaptation before online adaptation begins. Additionally, we study the effect of incremental context update and why it is a key enabler for ACE’s performance gain in Appendix §A.5.
| Method | GT Labels | Test-Normal | Test-Challenge | Average | ||
| TGC | SGC | TGC | SGC | |||
| DeepSeek-V3.1 as Base LLM | ||||||
| ReAct | 63.7 | 42.9 | 41.5 | 21.6 | 42.4 | |
| Offline Adaptation | ||||||
| ReAct + ACE w/o Reflector or multi-epoch | ✓ | 70.8_{{\color[rgb]{0.1328,0.5469,0.1328}+7.1}} | 55.4_{{\color[rgb]{0.1328,0.5469,0.1328}+12.5}} | 55.9_{{\color[rgb]{0.1328,0.5469,0.1328}+14.4}} | 38.1_{{\color[rgb]{0.1328,0.5469,0.1328}+17.5}} | 55.1_{{\color[rgb]{0.1328,0.5469,0.1328}+12.7}} |
| ReAct + ACE w/o multi-epoch | ✓ | 72.0_{{\color[rgb]{0.1328,0.5469,0.1328}+8.3}} | 60.7_{{\color[rgb]{0.1328,0.5469,0.1328}+17.8}} | 54.9_{{\color[rgb]{0.1328,0.5469,0.1328}+13.4}} | 39.6_{{\color[rgb]{0.1328,0.5469,0.1328}+18.0}} | 56.8_{{\color[rgb]{0.1328,0.5469,0.1328}+14.4}} |
| ReAct + ACE | ✓ | 76.2_{{\color[rgb]{0.1328,0.5469,0.1328}+12.5}} | 64.3_{{\color[rgb]{0.1328,0.5469,0.1328}+21.4}} | 57.3_{{\color[rgb]{0.1328,0.5469,0.1328}+15.8}} | 39.6_{{\color[rgb]{0.1328,0.5469,0.1328}+18.0}} | 59.4_{{\color[rgb]{0.1328,0.5469,0.1328}+17.0}} |
| Online Adaptation | ||||||
| ReAct + ACE | ✗ | 67.9_{{\color[rgb]{0.1328,0.5469,0.1328}+4.2}} | 51.8_{{\color[rgb]{0.1328,0.5469,0.1328}+8.9}} | 61.4_{{\color[rgb]{0.1328,0.5469,0.1328}+19.9}} | 43.2_{{\color[rgb]{0.1328,0.5469,0.1328}+21.6}} | 56.1_{{\color[rgb]{0.1328,0.5469,0.1328}+13.7}} |
| ReAct + ACE + offline warmup | ✗ | 69.6_{{\color[rgb]{0.1328,0.5469,0.1328}+5.9}} | 53.6_{{\color[rgb]{0.1328,0.5469,0.1328}+10.7}} | 66.0_{{\color[rgb]{0.1328,0.5469,0.1328}+24.5}} | 48.9_{{\color[rgb]{0.1328,0.5469,0.1328}+27.3}} | 59.5_{{\color[rgb]{0.1328,0.5469,0.1328}+17.1}} |
View original table
ACE is robust to reflection quality: it remains effective with a much weaker Reflector and shows only modest additional gains from stronger reflectors, and it degrades gracefully under noisy/harmful reflections, staying above the base model except under fully adversarial updates every iteration. Full experiment results are in Appendix §A.4.
ACE’s gains are stable across a wide range of reasonable hyperparameter settings (e.g., Reflector refinement rounds, number of adaptation epochs, and grow-and-refine thresholds): performance changes are modest, and ACE consistently remains above the corresponding baselines. Full discussion and detailed results are reported in Appendix §A.6.
Due to its support for incremental, “delta” context updates and non-LLM-based context merging and de-duplication, ACE demonstrates particular advantages in reducing the cost (in terms of the number of rollouts or the amount of dollar cost for token ingestion/generation) and latency of adaptation.
As examples, on the offline adaptation of AppWorld, ACE achieves 82.3% reduction in adaptation latency and 75.1% reduction in the number of rollouts as compared to GEPA (Table 4(a)). On the online adaptation of FiNER, ACE achieves 91.5% reduction in adaptation latency and 83.6% reduction in token dollar cost for token ingestion/generation as compared to DC (Table 4(b)).
| Method | Latency (s) | # Rollouts |
|---|---|---|
| ReAct + GEPA | 53898 | 1434 |
| ReAct + ACE | 9517(-82.3%) | 357(-75.1%) |
| Method | Latency (s) | Token Cost ($) |
|---|---|---|
| DC (CU) | 65104 | 17.7 |
| ACE | 5503(-91.5%) | 2.9(-83.6%) |
View original table
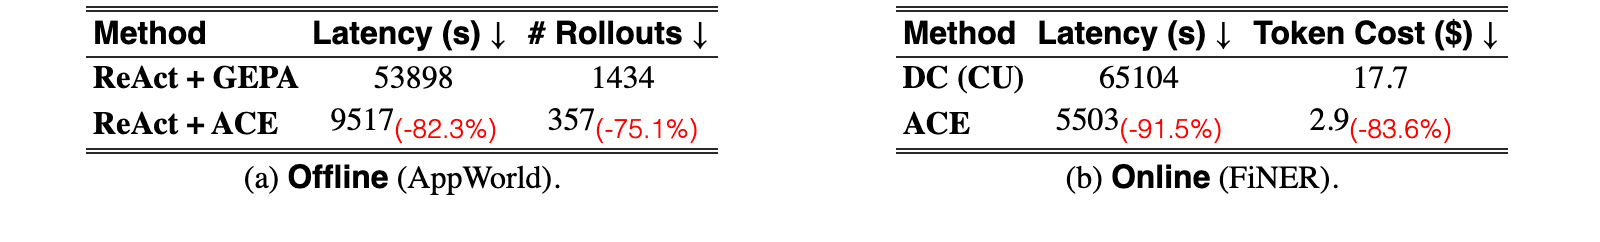
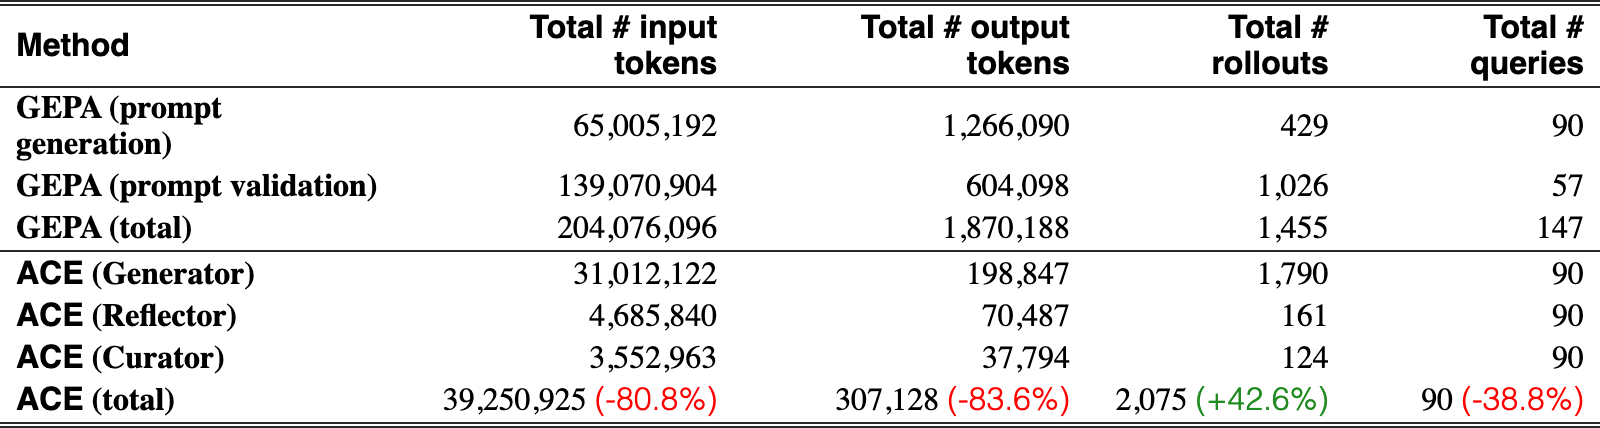
We conduct a fine-grained cost analysis of ACE and GEPA (as a representative baseline). On AppWorld, ACE is substantially cheaper during offline adaptation, reducing input/output token usage by 80.8%/83.6% vs. GEPA: ACE avoids GEPA’s prompt-validation loop and replaces repeated full rewrites with localized delta updates. At evaluation time, while ACE may use more raw input tokens due to a richer playbook, this does not necessarily translate to higher billed serving cost because a large fraction of the context is reused by KV caching; we quantify this effect in the next paragraph. Full results, including a component-wise token breakdown for both methods, are in Appendix §A.3.
Although ACE produces longer contexts than methods such as GEPA, this does not translate to linearly higher inference cost or GPU memory usage. Modern serving infrastructures are increasingly optimized for long-context workloads through techniques such as the reuse (Gim et al., 2024; Yao et al., 2025), compression (Liu et al., 2024c; Liu et al., 2024b), and offload (Lee et al., 2024; Li et al., 2025) of KV cache. These mechanisms allow frequently reused context segments to be cached locally or remotely, avoiding repetitive and expensive prefill operations. Ongoing advances in ML systems suggest that the amortized cost of handling long contexts is likely to decrease, making context-rich approaches like ACE increasingly practical in deployment. In our prompt-caching study with the OpenAI API (GPT-5.1), we find that ACE achieves high cache reuse: 91.8% of input tokens are served from cache during evaluation stage, which reduces billed input-token cost by 82.6% relative to counting raw context tokens.
Online and continual learning are key research directions in machine learning for addressing issues like distribution shifts (Koh et al., 2021; Gulrajani and Lopez-Paz, 2021) and limited training data (Pan and Yang, 2010; Hutchinson et al., 2017; Zhuang et al., 2019). ACE offers a flexible and efficient alternative to conventional model fine-tuning, as adapting contexts is generally cheaper than updating model weights (Brown et al., 2020; Lester et al., 2021; Li and Liang, 2021; Hu et al., 2022). Moreover, because contexts are human-interpretable, ACE enables selective unlearning (Cao and Yang, 2015; Bourtoule et al., 2021; Liu et al., 2025a), whether due to privacy or legal constraints (, 2016; , 2018), or when outdated or incorrect information is identified by domain experts. These are promising directions for future work, where ACE could play a central role in advancing continuous and responsible learning.
A limitation of ACE is its reliance on a reasonably strong Reflector: if the Reflector fails to extract meaningful insights from generated traces or outcomes, the constructed context may become noisy or even harmful. In domain-specific tasks where no model can extract useful insights, the resulting context will naturally lack them. This dependency is similar to Dynamic Cheatsheet (Suzgun et al., 2025), where the quality of adaptation hinges on the underlying model’s ability to curate memory. We also note that not all applications require rich or detailed contexts. Tasks like HotPotQA (Yang et al., 2018) often benefit more from concise, high-level instructions (e.g., how to retrieve and synthesize evidence) than from long contexts. Similarly, games with fixed strategies such as Game of 24 (Suzgun et al., 2025) may only need a single reusable rule, rendering additional context redundant. Overall, ACE is most beneficial in settings that demand detailed domain knowledge, complex tool use, or environment-specific strategies that go beyond what is already embedded in model weights or simple system instructions.
We thank the anonymous reviewers and area chair for their constructive feedback, which improved this paper. Qizheng Zhang is supported by NSF award CNS-2211384 and DARPA award TFAWI-HR00112520038. We also thank Lakshya A Agrawal, Xuekai Zhu, Yuhan Liu, Junchen Jiang, and Azalia Mirhoseini for helpful discussions.
This work does not raise specific ethical concerns. Our contributions focus on developing algorithms and system frameworks for effective context adaptation in large language models (LLMs). All experiments are conducted on publicly available benchmarks with open-source models, without involving human subjects, sensitive data, or privacy-related information. No potential conflicts of interest are present.
Our code is available at github.com/ace-agent/ace. We provide detailed descriptions of our experimental setup, including datasets, benchmarks, evaluation metrics, baselines, and hyperparameter choices. Additional details, such as prompts for large language models and extended experimental settings, are included in the appendix. With this information, readers with reasonable computational resources should be able to reproduce our results.
References
- Agarwal et al. (2024) R. Agarwal, A. Singh, L. Zhang, B. Bohnet, L. Rosias, S. Chan, B. Zhang, A. Anand, Z. Abbas, A. Nova, et al. Many-Shot In-Context Learning. Advances in Neural Information Processing Systems (NeurIPS) 37, pp. 76930–76966. Cited by: §4.2.
- Agrawal et al. (2025) L. A. Agrawal, S. Tan, D. Soylu, N. Ziems, R. Khare, K. Opsahl-Ong, A. Singhvi, H. Shandilya, M. J. Ryan, M. Jiang, et al. GEPA: Reflective Prompt Evolution Can Outperform Reinforcement Learning. arXiv preprint arXiv:2507.19457. Cited by: §1, §1, §2.1, §4.2.
- [3] AppWorld Leaderboard. Note: https://appworld.dev/leaderboardAccessed: 09/2025 Cited by: 3rd item, 1st item.Source
- Asai et al. (2024) A. Asai, Z. Wu, Y. Wang, A. Sil, and H. Hajishirzi Self-RAG: Learning to Retrieve, Generate, and Critique through Self-Reflection. In The Twelfth International Conference on Learning Representations (ICLR), Cited by: §1.
- Borgeaud et al. (2022) S. Borgeaud, A. Mensch, J. Hoffmann, T. Cai, E. Rutherford, K. Millican, G. B. Van Den Driessche, J. Lespiau, B. Damoc, A. Clark, et al. Improving Language Models by Retrieving from Trillions of Tokens. In International Conference on Machine Learning (ICML), pp. 2206–2240. Cited by: §1.
- Bourtoule et al. (2021) L. Bourtoule, V. Chandrasekaran, C. Choquette-Choo, H. Jia, A. Travers, B. Zhang, D. Lie, and N. Papernot Machine Unlearning. In IEEE Symposium on Security and Privacy (IEEE S&P), Cited by: §5.
- Brown et al. (2020) T. Brown, B. Mann, N. Ryder, M. Subbiah, J. D. Kaplan, P. Dhariwal, A. Neelakantan, P. Shyam, G. Sastry, A. Askell, et al. Language Models are Few-Shot Learners. Advances in Neural Information Processing Systems (NeurIPS) 33, pp. 1877–1901. Cited by: §5.
- [8] (2018) California Consumer Privacy Act, Civil Code §1798.105: Right to Delete. Note: State of California Civil Code Cited by: §5.
- Cao and Yang (2015) Y. Cao and J. Yang Towards Making Systems Forget with Machine Unlearning. In IEEE Symposium on Security and Privacy (IEEE S&P), Cited by: §5.
- Chen et al. (2025) T. Chen, Z. Tan, X. Bo, Y. Wu, T. Gong, Q. Chu, J. Ye, and N. Yu Flora: Effortless Context Construction to Arbitrary Length and Scale. arXiv preprint arXiv:2507.19786. Cited by: §1.
- Chung et al. (2025) Y. Chung, G. T. Kakkar, Y. Gan, B. Milne, and F. Özcan Is Long Context All You Need? Leveraging LLM’s Extended Context for NL2SQL. Proceedings of the VLDB Endowment 18 (8), pp. 2735–2747. Cited by: §1.
- [12] DSPy dspy.GEPA: Reflective Prompt Optimizer. Note: https://dspy.ai/api/optimizers/GEPA/overview/Accessed: 09/2025 Cited by: §4.2.Source
- [13] DSPy dspy.MIPROv2: Multiprompt Instruction PRoposal Optimizer Version 2. Note: https://dspy.ai/api/optimizers/MIPROv2/Accessed: 09/2025 Cited by: §A.3, §4.2.Source
- Fansi Tchango et al. (2022) A. Fansi Tchango, R. Goel, Z. Wen, J. Martel, and J. Ghosn DDXPlus: A New Dataset For Automatic Medical Diagnosis. Advances in neural information processing systems (NeurIPS). Cited by: §A.2, 2nd item.
- Gao et al. (2025) S. Gao, C. Wang, C. Gao, X. Jiao, C. Y. Chong, S. Gao, and M. Lyu The Prompt Alchemist: Automated LLM-Tailored Prompt Optimization for Test Case Generation. arXiv preprint arXiv:2501.01329. Cited by: §1, §2.2.
- [16] (2016) General Data Protection Regulation (GDPR) Article 17: Right to Erasure. Note: EU Regulation 2016/679 Cited by: §5.
- Gim et al. (2024) I. Gim, G. Chen, S. Lee, N. Sarda, A. Khandelwal, and L. Zhong Prompt Cache: Modular Attention Reuse for Low-Latency Inference. Proceedings of Machine Learning and Systems (MLSys) 6, pp. 325–338. Cited by: §1, §4.7.
- Guha et al. (2023) N. Guha, J. Nyarko, D. Ho, C. Ré, A. Chilton, A. Chohlas-Wood, A. Peters, B. Waldon, D. Rockmore, D. Zambrano, et al. LegalBench: A Collaboratively Built Benchmark for Measuring Legal Reasoning in Large Language Models. Advances in neural information processing systems (NeurIPS). Cited by: §1.
- Gulrajani and Lopez-Paz (2021) I. Gulrajani and D. Lopez-Paz In Search of Lost Domain Generalization. In International Conference on Learning Representations (ICLR), Cited by: §5.
- Hu et al. (2022) E. J. Hu, Y. Shen, P. Wallis, Z. Allen-Zhu, Y. Li, S. Wang, L. Wang, and W. Chen LoRA: Low-Rank Adaptation of Large Language Models. In The Tenth International Conference on Learning Representations (ICLR), Cited by: §5.
- Hutchinson et al. (2017) M. L. Hutchinson, E. Antono, B. M. Gibbons, S. Paradiso, J. Ling, and B. Meredig Overcoming Data Scarcity with Transfer Learning. arXiv preprint arXiv:1711.05099. Cited by: §5.
- Jiang et al. (2025) M. Jiang, Y. Ruan, L. Lastras, P. Kapanipathi, and T. Hashimoto Putting It All into Context: Simplifying Agents with LCLMs. arXiv preprint arXiv:2505.08120. Cited by: §1.
- Khot et al. (2023) T. Khot, H. Trivedi, M. Finlayson, Y. Fu, K. Richardson, P. Clark, and A. Sabharwal Decomposed Prompting: A Modular Approach for Solving Complex Tasks. In International Conference on Learning Representations (ICLR), Cited by: §1.
- Koh et al. (2021) P. W. Koh, S. Sagawa, H. Marklund, S. M. Xie, M. Zhang, A. Balsubramani, W. Hu, M. Yasunaga, R. L. Phillips, I. Gao, et al. WILDS: A Benchmark of in-the-Wild Distribution Shifts. In International conference on machine learning (ICML), Cited by: §5.
- Krause et al. (2019) B. Krause, E. Kahembwe, I. Murray, and S. Renals Dynamic Evaluation of Transformer Language Models. arXiv preprint arXiv:1904.08378. Cited by: §2.1.
- Lee et al. (2024) W. Lee, J. Lee, J. Seo, and J. Sim InfiniGen: Efficient Generative Inference of Large Language Models with Dynamic KV Cache Management. In 18th USENIX Symposium on Operating Systems Design and Implementation (OSDI 24), pp. 155–172. Cited by: §4.7.
- Lester et al. (2021) B. Lester, R. Al-Rfou, and N. Constant The Power of Scale for Parameter-Efficient Prompt Tuning. In Proceedings of the 2021 conference on empirical methods in natural language processing (EMNLP), pp. 3045–3059. Cited by: §5.
- Lewis et al. (2020) P. Lewis, E. Perez, A. Piktus, F. Petroni, V. Karpukhin, N. Goyal, H. Küttler, M. Lewis, W. Yih, T. Rocktäschel, et al. Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks. Advances in neural information processing systems (NeurIPS). Cited by: §1.
- Li et al. (2025) H. Li, Q. Mang, R. He, Q. Zhang, H. Mao, X. Chen, H. Zhou, A. Cheung, J. Gonzalez, and I. Stoica Continuum: Efficient and Robust Multi-Turn LLM Agent Scheduling with KV Cache Time-to-Live. arXiv preprint arXiv:2511.02230. Cited by: §4.7.
- Li et al. (2023) J. Li, B. Hui, G. Qu, J. Yang, B. Li, B. Li, B. Wang, B. Qin, R. Geng, N. Huo, et al. Can LLM Already Serve as A Database Interface? A BIg Bench for Large-Scale Database Grounded Text-to-SQLs. Advances in Neural Information Processing Systems (NeurIPS). Cited by: §A.2, 2nd item.
- Li and Liang (2021) X. L. Li and P. Liang Prefix-Tuning: Optimizing Continuous Prompts for Generation. In Proceedings of the 59th Annual Meeting of the Association for Computational Linguistics and the 11th International Joint Conference on Natural Language Processing (Volume 1: Long Papers), pp. 4582–4597. Cited by: §5.
- Liu et al. (2024a) A. Liu, B. Feng, B. Xue, B. Wang, B. Wu, C. Lu, C. Zhao, C. Deng, C. Zhang, C. Ruan, et al. DeepSeek-V3 Technical Report. arXiv preprint arXiv:2412.19437. Cited by: §4.2.
- Liu et al. (2025a) S. Liu, Y. Yao, J. Jia, S. Casper, N. Baracaldo, P. Hase, Y. Yao, C. Y. Liu, X. Xu, H. Li, et al. Rethinking Machine Unlearning for Large Language Models. Nature Machine Intelligence 7 (2), pp. 181–194. Cited by: §5.
- Liu et al. (2024b) Y. Liu, H. Li, Y. Cheng, S. Ray, Y. Huang, Q. Zhang, K. Du, J. Yao, S. Lu, G. Ananthanarayanan, et al. CacheGen: KV Cache Compression and Streaming for Fast Large Language Model Serving. In Proceedings of the ACM SIGCOMM 2024 Conference, pp. 38–56. Cited by: §4.7.
- Liu et al. (2025b) Z. Liu, R. A. Amjad, R. Adkathimar, T. Wei, and H. Tong SelfElicit: Your Language Model Secretly Knows Where is the Relevant Evidence. In Proceedings of the 63rd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), pp. 9153–9173. Cited by: §1.
- Liu et al. (2024c) Z. Liu, J. Yuan, H. Jin, S. Zhong, Z. Xu, V. Braverman, B. Chen, and X. Hu KIVI: A Tuning-Free Asymmetric 2bit Quantization for KV Cache. In International Conference on Machine Learning (ICML), Cited by: §4.7.
- Loukas et al. (2022) L. Loukas, M. Fergadiotis, I. Chalkidis, E. Spyropoulou, P. Malakasiotis, I. Androutsopoulos, and G. Paliouras FiNER: Financial Numeric Entity Recognition for XBRL Tagging. In Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), pp. 4419–4431. Cited by: §1, §1, 2nd item.
- Mang et al. (2025) Q. Mang, W. Chai, Z. Li, H. Mao, S. Zhou, A. Du, H. Li, S. Liu, E. Chen, Y. Wang, et al. FrontierCS: Evolving Challenges for Evolving Intelligence. arXiv preprint arXiv:2512.15699. Cited by: §1.
- Mao et al. (2024) Y. Mao, J. Li, F. Meng, J. Xiong, Z. Zheng, and M. Zhang LIFT: Improving Long Context Understanding Through Long Input Fine-Tuning. arXiv preprint arXiv:2412.13626. Cited by: §1.
- Marreed et al. (2025) S. Marreed, A. Oved, A. Yaeli, S. Shlomov, I. Levy, O. Akrabi, A. Sela, A. Adi, and N. Mashkif Towards Enterprise-Ready Computer Using Generalist Agent. arXiv preprint arXiv:2503.01861. Cited by: 3rd item, §4.3.
- OpenAI (2024) OpenAI GPT‑4o mini: Advancing Cost-Efficient Intelligence. Note: https://openai.com/index/gpt-4o-mini-advancing-cost-efficient-intelligence/ Cited by: §4.1.Source
- Opsahl-Ong et al. (2024) K. Opsahl-Ong, M. J. Ryan, J. Purtell, D. Broman, C. Potts, M. Zaharia, and O. Khattab Optimizing Instructions and Demonstrations for Multi-Stage Language Model Programs. In Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing (EMNLP), pp. 9340–9366. Cited by: §1, §4.2.
- Pan and Yang (2010) S. J. Pan and Q. Yang A Survey on Transfer Learning. IEEE Transactions on Knowledge and Data Engineering 22 (10), pp. 1345–1359. Cited by: §5.
- Patil et al. (2024) S. G. Patil, T. Zhang, X. Wang, and J. E. Gonzalez Gorilla: Large Language Model Connected with Massive APIs. Advances in Neural Information Processing Systems (NeurIPS). Cited by: §1.
- Peng et al. (2024) B. Peng, J. Quesnelle, H. Fan, and E. Shippole YaRN: Efficient Context Window Extension of Large Language Models. In The Twelfth International Conference on Learning Representations (ICLR), Cited by: §1, §1.
- Shinn et al. (2023) N. Shinn, F. Cassano, A. Gopinath, K. Narasimhan, and S. Yao Reflexion: Language Agents with Verbal Reinforcement Learning. Advances in Neural Information Processing Systems (NeurIPS). Cited by: §2.1.
- [47] M. Suzgun, M. Yuksekgonul, F. Bianchi, D. Jurafsky, and J. Zou Dynamic Cheatsheet: Test-Time Learning with Adaptive Memory. Note: https://github.com/suzgunmirac/dynamic-cheatsheetAccessed: 09/2025 Cited by: §4.2.Source
- Suzgun et al. (2025) M. Suzgun, M. Yuksekgonul, F. Bianchi, D. Jurafsky, and J. Zou Dynamic Cheatsheet: Test-Time Learning with Adaptive Memory. arXiv preprint arXiv:2504.07952. Cited by: §1, §1, §2.2, §3.1, §3, §4.2, §5.
- Trivedi et al. (2024) H. Trivedi, T. Khot, M. Hartmann, R. Manku, V. Dong, E. Li, S. Gupta, A. Sabharwal, and N. Balasubramanian AppWorld: A Controllable World of Apps and People for Benchmarking Interactive Coding Agents. In Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), pp. 16022–16076. Cited by: §1, §1, §2.2, 1st item.
- Wang et al. (2025a) D. Wang, J. Patel, D. Zha, S. Y. Yang, and X. Liu FinLoRA: Benchmarking LoRA Methods for Fine-Tuning LLMs on Financial Datasets. arXiv preprint arXiv:2505.19819. Cited by: §1, §1, 2nd item.
- Wang et al. (2023) X. Wang, J. Wei, D. Schuurmans, Q. Le, E. Chi, S. Narang, A. Chowdhery, and D. Zhou Self-Consistency Improves Chain of Thought Reasoning in Language Models. In The Eleventh International Conference on Learning Representations (ICLR), Cited by: §1.
- Wang et al. (2025b) Z. Z. Wang, J. Mao, D. Fried, and G. Neubig Agent Workflow Memory. In Forty-second International Conference on Machine Learning (ICML), Cited by: §B.1.
- Wei et al. (2022) J. Wei, X. Wang, D. Schuurmans, M. Bosma, F. Xia, E. Chi, Q. V. Le, D. Zhou, et al. Chain-of-Thought Prompting Elicits Reasoning in Large Language Models. Advances in neural information processing systems (NeurIPS) 35, pp. 24824–24837. Cited by: §1.
- Wu et al. (2024) C. Wu, Z. R. Tam, C. Lin, Y. Chen, and H. Lee StreamBench: Towards Benchmarking Continuous Improvement of Language Agents. Advances in Neural Information Processing Systems (NeurIPS). Cited by: §A.2, 2nd item.
- Xu et al. (2025) W. Xu, K. Mei, H. Gao, J. Tan, Z. Liang, and Y. Zhang A-Mem: Agentic Memory for LLM Agents. Advances in neural information processing systems (NeurIPS). Cited by: §B.1, §1, §3.1.
- Yang et al. (2024) J. Yang, C. E. Jimenez, A. Wettig, K. Lieret, S. Yao, K. Narasimhan, and O. Press SWE-agent: Agent-Computer Interfaces Enable Automated Software Engineering. Advances in Neural Information Processing Systems (NeurIPS). Cited by: §1.
- Yang et al. (2018) Z. Yang, P. Qi, S. Zhang, Y. Bengio, W. Cohen, R. Salakhutdinov, and C. D. Manning HotpotQA: A Dataset for Diverse, Explainable Multi-hop Question Answering. In Proceedings of the 2018 conference on empirical methods in natural language processing (EMNLP), pp. 2369–2380. Cited by: §5.
- Yao et al. (2025) J. Yao, H. Li, Y. Liu, S. Ray, Y. Cheng, Q. Zhang, K. Du, S. Lu, and J. Jiang CacheBlend: Fast Large Language Model Serving for RAG with Cached Knowledge Fusion . In Proceedings of the Twentieth European Conference on Computer Systems (EuroSys), pp. 94–109. Cited by: §1, §4.7.
- Yao et al. (2023) S. Yao, J. Zhao, D. Yu, N. Du, I. Shafran, K. Narasimhan, and Y. Cao ReAct: Synergizing Reasoning and Acting in Language Models. In International Conference on Learning Representations (ICLR), Cited by: §1, §4.2.
- Ye et al. (2023) J. Ye, C. Li, L. Kong, and T. Yu Generating Data for Symbolic Language with Large Language Models. In Proceedings of the 2023 conference on empirical methods in natural language processing (EMNLP), pp. 8418–8443. Cited by: §1.
- Yuksekgonul et al. (2025) M. Yuksekgonul, F. Bianchi, J. Boen, S. Liu, P. Lu, Z. Huang, C. Guestrin, and J. Zou Optimizing Generative AI by Backpropagating Language Model Feedback. Nature 639 (8055), pp. 609–616. Cited by: §2.1.
- Zaharia et al. (2024) M. Zaharia, O. Khattab, L. Chen, J. Q. Davis, H. Miller, C. Potts, J. Zou, M. Carbin, J. Frankle, N. Rao, and A. Ghodsi The Shift from Models to Compound AI Systems. Note: https://bair.berkeley.edu/blog/2024/02/18/compound-ai-systems/ Cited by: §1.Source
- Zhang et al. (2025a) G. Zhang, W. Liang, O. Hsu, and K. Olukotun Adaptive Self-Improvement LLM Agentic System for ML Library Development. In Forty-second International Conference on Machine Learning (ICML), Cited by: §1.
- Zhang et al. (2025b) G. Zhang, S. Zhu, A. Wei, Z. Song, A. Nie, Z. Jia, N. Vijaykumar, Y. Wang, and K. Olukotun AccelOpt: A Self-Improving LLM Agentic System for AI Accelerator Kernel Optimization. arXiv preprint arXiv:2511.15915. Cited by: §1.
- Zhang et al. (2024) Q. Zhang, A. Imran, E. Bardhi, T. Swamy, N. Zhang, M. Shahbaz, and K. Olukotun Caravan: Practical Online Learning of In-Network ML Models with Labeling Agents. In 18th USENIX Symposium on Operating Systems Design and Implementation (OSDI), pp. 325–345. Cited by: §1.
- Zhang et al. (2025c) Q. Zhang, M. Wornow, and K. Olukotun Agentic Plan Caching: Test-Time Memory for Fast and Cost-Efficient LLM Agents. In The Thirty-ninth Annual Conference on Neural Information Processing Systems (NeurIPS), Cited by: §B.1.
- Zheng et al. (2023) L. Zheng, W. Chiang, Y. Sheng, S. Zhuang, Z. Wu, Y. Zhuang, Z. Lin, Z. Li, D. Li, E. Xing, et al. Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena. Advances in neural information processing systems (NeurIPS) 36, pp. 46595–46623. Cited by: §4.1.
- Zhou et al. (2025) H. Zhou, Y. Chen, S. Guo, X. Yan, K. H. Lee, Z. Wang, K. Y. Lee, G. Zhang, K. Shao, L. Yang, et al. AgentFly: Fine-tuning LLM Agents without Fine-tuning LLMs. arXiv preprint arXiv:2508.16153. Cited by: §B.1.
- Zhou et al. (2024) Y. Zhou, Y. Han, H. Zhuang, K. Guo, Z. Liang, H. Bao, and X. Zhang Defending Jailbreak Prompts via In-Context Adversarial Game. In Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing (EMNLP), pp. 20084–20105. Cited by: §A.4.
- Zhuang et al. (2019) F. Zhuang, Z. Qi, K. Duan, D. Xi, Y. Zhu, H. Zhu, H. Xiong, and Q. He A Comprehensive Survey on Transfer Learning. arXiv:1911.02685. Cited by: §5.
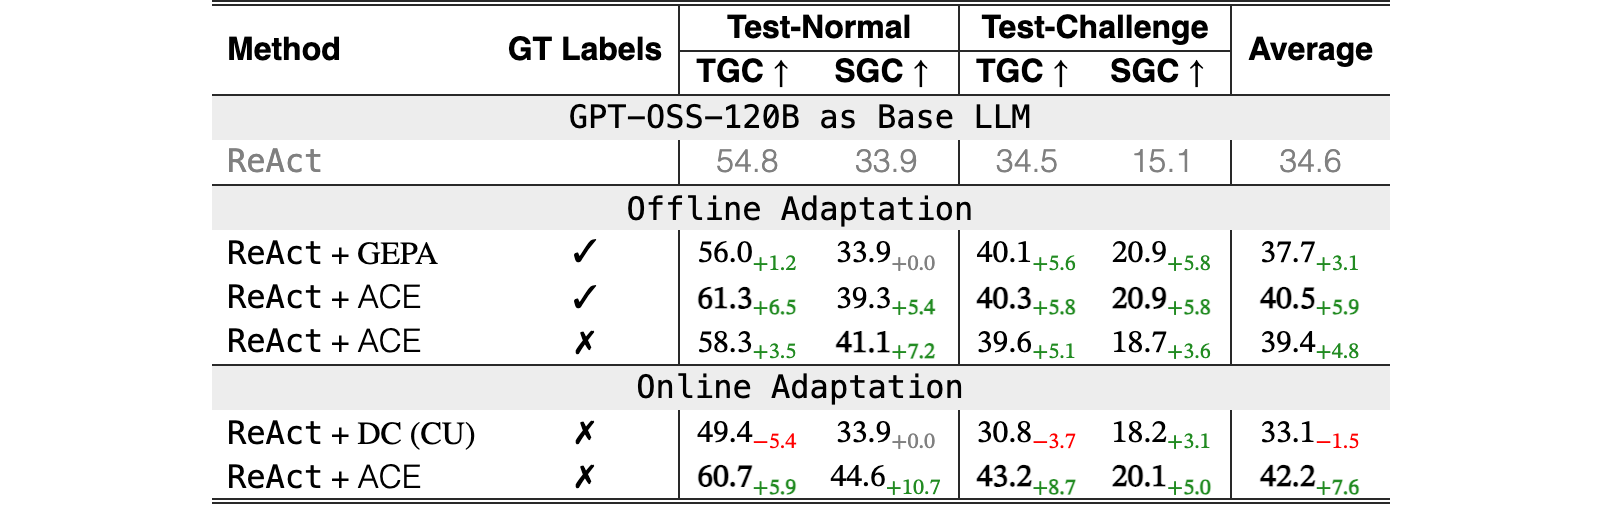
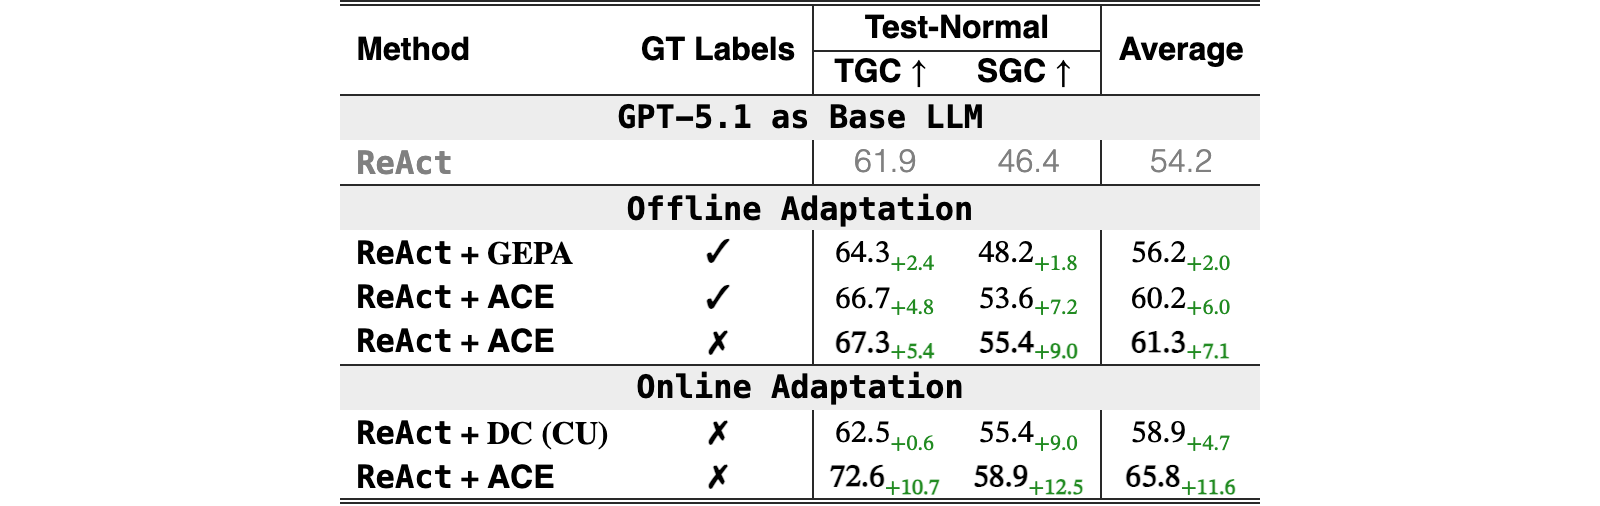
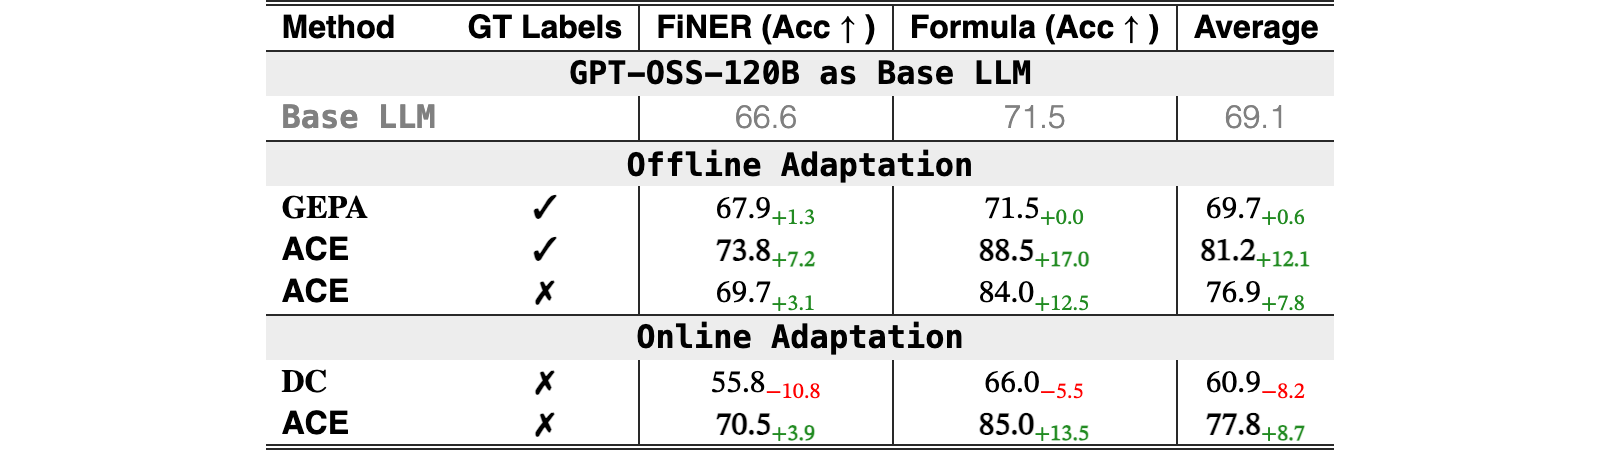
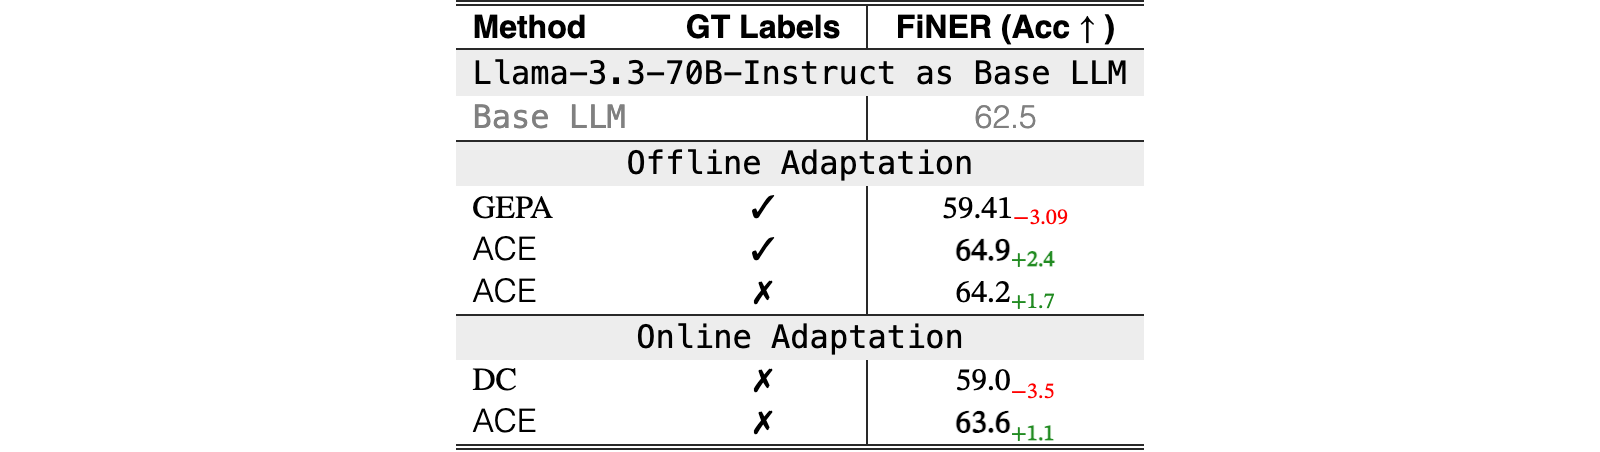
ACE is a model-agnostic framework that operates on execution traces and contextual deltas, and does not rely on any architectural or training-specific features of DeepSeek-V3.1 (the default backbone we use in the main text). We evaluated ACE with three additional models of varying size, cost, and capability: GPT-OSS-120B (Table 5 and 7), GPT-5.1 (Table 6 and 8), and Llama-3.3-70B-Instruct (Table 9). In each case, the Generator, Reflector, and Curator were all switched to the new model without changes to the algorithm.
Across all four LLM families we tested (DeepSeek-V3.1, GPT-OSS-120B, GPT-5.1, and Llama-3.3-70B-Instruct), ACE consistently improves performance over both the base LLM/agent, GEPA, and other baselines, often by 5 to 12 points depending on the task and supervision setting. The relative gains of ACE remain stable even when switching to models that differ significantly in size, cost, and training recipe, and ACE delivers benefits with or without ground-truth labels, validating the robustness of its context adaptation mechanism. The online variant reliably achieves the strongest performance across all models.
We note that the magnitude of improvement can vary across model families: for example, Llama-3.3-70B-Instruct shows smaller gains compared to GPT-5.1 or GPT-OSS-120B. This is expected since ACE relies on the quality of intermediate reflections and calibrations, and smaller or weaker models naturally generate noisier feedback. Even in these cases, however, ACE remains beneficial, demonstrating that the framework is broadly applicable while still reflecting the inherent capability limits of the underlying LLM, as we discussed in the “Limitations and Challenges” paragraph in §5.
| Method | GT Labels | Test-Normal | Test-Challenge | Average | ||
| TGC | SGC | TGC | SGC | |||
| GPT-OSS-120B as Base LLM | ||||||
| ReAct | 54.8 | 33.9 | 34.5 | 15.1 | 34.6 | |
| Offline Adaptation | ||||||
| ReAct + GEPA | ✓ | 56.0_{{\color[rgb]{0.1328,0.5469,0.1328}+1.2}} | 33.9_{{\color[rgb]{0.5,0.5,0.5}+0.0}} | 40.1_{{\color[rgb]{0.1328,0.5469,0.1328}+5.6}} | 20.9_{{\color[rgb]{0.1328,0.5469,0.1328}+5.8}} | 37.7_{{\color[rgb]{0.1328,0.5469,0.1328}+3.1}} |
| ReAct + ACE | ✓ | {\color[rgb]{0,0,0}\mathbf{61.3}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+6.5}}} | {\color[rgb]{0,0,0}39.3}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+5.4}}} | {\color[rgb]{0,0,0}\mathbf{40.3}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+5.8}}} | {\color[rgb]{0,0,0}\mathbf{20.9}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+5.8}}} | {\color[rgb]{0,0,0}\mathbf{40.5}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+5.9}}} |
| ReAct + ACE | ✗ | 58.3_{{\color[rgb]{0.1328,0.5469,0.1328}+3.5}} | {\color[rgb]{0,0,0}\mathbf{41.1}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+7.2}}} | 39.6_{{\color[rgb]{0.1328,0.5469,0.1328}+5.1}} | 18.7_{{\color[rgb]{0.1328,0.5469,0.1328}+3.6}} | 39.4_{{\color[rgb]{0.1328,0.5469,0.1328}+4.8}} |
| Online Adaptation | ||||||
| ReAct + DC (CU) | ✗ | 49.4_{{\color[rgb]{1,0,0}-5.4}} | 33.9_{{\color[rgb]{0.5,0.5,0.5}+0.0}} | 30.8_{{\color[rgb]{1,0,0}-3.7}} | 18.2_{{\color[rgb]{0.1328,0.5469,0.1328}+3.1}} | 33.1_{{\color[rgb]{1,0,0}-1.5}} |
| ReAct + ACE | ✗ | {\color[rgb]{0,0,0}\mathbf{60.7}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+5.9}}} | 44.6_{{\color[rgb]{0.1328,0.5469,0.1328}+10.7}} | {\color[rgb]{0,0,0}\mathbf{43.2}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+8.7}}} | {\color[rgb]{0,0,0}\mathbf{20.1}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+5.0}}} | {\color[rgb]{0,0,0}\mathbf{42.2}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+7.6}}} |
View original table
| Method | GT Labels | Test-Normal | Average | |
|---|---|---|---|---|
| TGC | SGC | |||
| GPT-5.1 as Base LLM | ||||
| ReAct | 61.9 | 46.4 | 54.2 | |
| Offline Adaptation | ||||
| ReAct + GEPA | ✓ | 64.3_{{\color[rgb]{0.1328,0.5469,0.1328}+2.4}} | 48.2_{{\color[rgb]{0.1328,0.5469,0.1328}+1.8}} | 56.2_{{\color[rgb]{0.1328,0.5469,0.1328}+2.0}} |
| ReAct + ACE | ✓ | 66.7_{{\color[rgb]{0.1328,0.5469,0.1328}+4.8}} | 53.6_{{\color[rgb]{0.1328,0.5469,0.1328}+7.2}} | 60.2_{{\color[rgb]{0.1328,0.5469,0.1328}+6.0}} |
| ReAct + ACE | ✗ | {\color[rgb]{0,0,0}\mathbf{67.3}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+5.4}}} | {\color[rgb]{0,0,0}\mathbf{55.4}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+9.0}}} | {\color[rgb]{0,0,0}\mathbf{61.3}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+7.1}}} |
| Online Adaptation | ||||
| ReAct + DC (CU) | ✗ | 62.5_{{\color[rgb]{0.1328,0.5469,0.1328}+0.6}} | 55.4_{{\color[rgb]{0.1328,0.5469,0.1328}+9.0}} | 58.9_{{\color[rgb]{0.1328,0.5469,0.1328}+4.7}} |
| ReAct + ACE | ✗ | {\color[rgb]{0,0,0}\mathbf{72.6}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+10.7}}} | {\color[rgb]{0,0,0}\mathbf{58.9}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+12.5}}} | {\color[rgb]{0,0,0}\mathbf{65.8}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+11.6}}} |
View original table
| Method | GT Labels | FiNER (Acc) | Formula (Acc) | Average |
|---|---|---|---|---|
| GPT-OSS-120B as Base LLM | ||||
| Base LLM | 66.6 | 71.5 | 69.1 | |
| Offline Adaptation | ||||
| GEPA | ✓ | 67.9_{{\color[rgb]{0.1328,0.5469,0.1328}+1.3}} | 71.5_{{\color[rgb]{0.1328,0.5469,0.1328}+0.0}} | 69.7_{{\color[rgb]{0.1328,0.5469,0.1328}+0.6}} |
| ACE | ✓ | {\color[rgb]{0,0,0}\mathbf{73.8}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+7.2}}} | {\color[rgb]{0,0,0}\mathbf{88.5}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+17.0}}} | {\color[rgb]{0,0,0}\mathbf{81.2}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+12.1}}} |
| ACE | ✗ | 69.7_{{\color[rgb]{0.1328,0.5469,0.1328}+3.1}} | 84.0_{{\color[rgb]{0.1328,0.5469,0.1328}+12.5}} | 76.9_{{\color[rgb]{0.1328,0.5469,0.1328}+7.8}} |
| Online Adaptation | ||||
| DC | ✗ | 55.8_{{\color[rgb]{1,0,0}-10.8}} | 66.0_{{\color[rgb]{1,0,0}-5.5}} | 60.9_{{\color[rgb]{1,0,0}-8.2}} |
| ACE | ✗ | \mathbf{70.5}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+3.9}}} | \mathbf{85.0}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+13.5}}} | \mathbf{77.8}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+8.7}}} |
View original table
| Method | GT Labels | FiNER (Acc) | Formula (Acc) | Average |
|---|---|---|---|---|
| GPT-5.1 as Base LLM | ||||
| Base LLM | 73.5 | 73.0 | 73.3 | |
| Offline Adaptation | ||||
| GEPA | ✓ | 74.5_{{\color[rgb]{0.1328,0.5469,0.1328}+1.0}} | 73.0_{{\color[rgb]{0.1328,0.5469,0.1328}+0.0}} | 73.8_{{\color[rgb]{0.1328,0.5469,0.1328}+0.5}} |
| ACE | ✓ | {\color[rgb]{0,0,0}\mathbf{81.0}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+7.5}}} | {\color[rgb]{0,0,0}\mathbf{84.5}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+11.5}}} | {\color[rgb]{0,0,0}\mathbf{82.8}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+9.5}}} |
| ACE | ✗ | 78.2_{{\color[rgb]{0.1328,0.5469,0.1328}+4.7}} | 76.5_{{\color[rgb]{0.1328,0.5469,0.1328}+3.5}} | 77.4_{{\color[rgb]{0.1328,0.5469,0.1328}+4.1}} |
| Online Adaptation | ||||
| DC | ✗ | 70.0_{{\color[rgb]{1,0,0}-3.5}} | 69.0_{{\color[rgb]{1,0,0}-4.0}} | 69.5_{{\color[rgb]{1,0,0}-3.8}} |
| ACE | ✗ | \mathbf{75.2}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+1.7}}} | \mathbf{79.0}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+6.0}}} | \mathbf{77.1}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+3.8}}} |
View original table
| Method | GT Labels | FiNER (Acc) |
| Llama-3.3-70B-Instruct as Base LLM | ||
| Base LLM | 62.5 | |
| Offline Adaptation | ||
| GEPA | ✓ | 59.41_{{\color[rgb]{1,0,0}-3.09}} |
| ACE | ✓ | {\color[rgb]{0,0,0}\mathbf{64.9}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+2.4}}} |
| ACE | ✗ | 64.2_{{\color[rgb]{0.1328,0.5469,0.1328}+1.7}} |
| Online Adaptation | ||
| DC | ✗ | 59.0_{{\color[rgb]{1,0,0}-3.5}} |
| ACE | ✗ | \mathbf{63.6}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+1.1}}} |
View original table
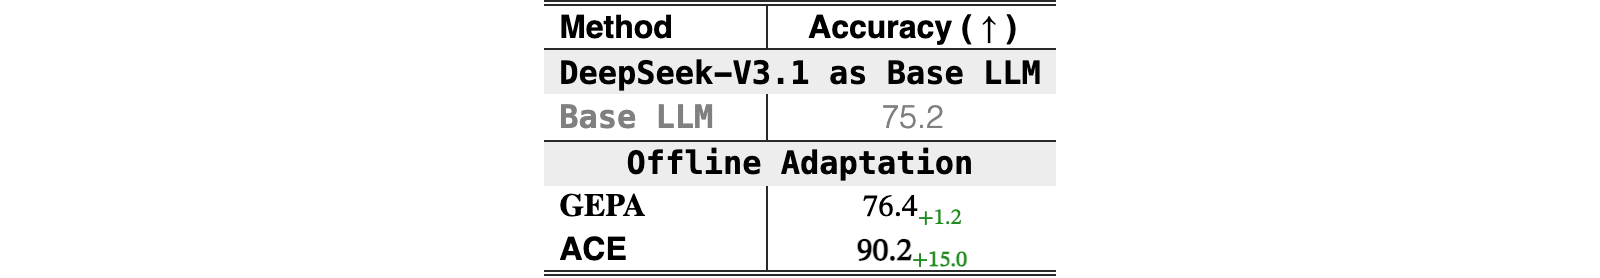
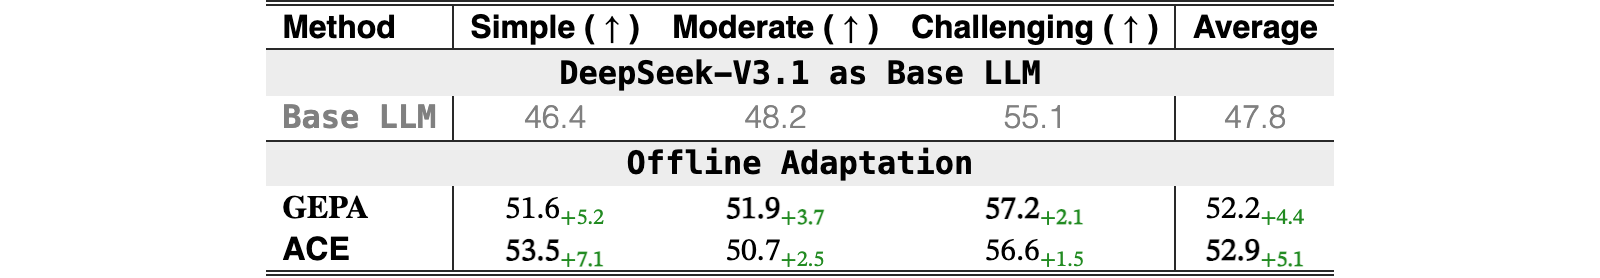
We evaluate ACE on two additional domain tasks from StreamBench (Wu et al., 2024) under the non-streaming setting (i.e., offline adaptation): DDXPlus (Fansi Tchango et al., 2022) for medical reasoning (Table 10) and BIRD-SQL (Li et al., 2023) for Text-to-SQL generation (Table 11). For ACE, we perform offline adaptation using 1000 randomly sampled training examples. For GEPA, we use the same 1000 examples for training, and reserve a separate validation set of 500 examples for BIRD-SQL or 372 examples for DDXPlus (StreamBench provides 1372 train/val examples for DDXPlus in total). All other settings follow the main-text configuration unless stated otherwise.
On DDXPlus, ACE substantially improves over the base LLM, rising from 75.2 to 90.2 accuracy (+15.0). In contrast, GEPA yields a much smaller gain (76.4, +1.2). This suggests that ACE’s test-time evolving context transfers well to multi-step, domain-heavy diagnostic reasoning. On BIRD-SQL, ACE also improves consistently over the base model on all splits, achieving better overall average (52.9, +5.1). The gains are driven mainly by the Simple subset (53.5, +7.1). While GEPA yields larger gains on Moderate and Challenging, ACE still improves over the base model on both splits. Overall, these results indicate that ACE generalizes beyond finance to both knowledge-intensive reasoning and structured code generation tasks.
| Method | Accuracy () |
|---|---|
| DeepSeek-V3.1 as Base LLM | |
| Base LLM | 75.2 |
| Offline Adaptation | |
| GEPA | 76.4_{{\color[rgb]{0.1328,0.5469,0.1328}+1.2}} |
| ACE | {\color[rgb]{0,0,0}\mathbf{90.2}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+15.0}}} |
View original table
| Method | Simple () | Moderate () | Challenging () | Average |
|---|---|---|---|---|
| DeepSeek-V3.1 as Base LLM | ||||
| Base LLM | 46.4 | 48.2 | 55.1 | 47.8 |
| Offline Adaptation | ||||
| GEPA | 51.6_{{\color[rgb]{0.1328,0.5469,0.1328}+5.2}} | \mathbf{51.9}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+3.7}}} | \mathbf{57.2}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+2.1}}} | 52.2_{{\color[rgb]{0.1328,0.5469,0.1328}+4.4}} |
| ACE | \mathbf{53.5}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+7.1}}} | 50.7_{{\color[rgb]{0.1328,0.5469,0.1328}+2.5}} | 56.6_{{\color[rgb]{0.1328,0.5469,0.1328}+1.5}} | \mathbf{52.9}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+5.1}}} |
View original table
We perform a fine-grained cost analysis of ACE and GEPA for both the adaptation and evaluation stages (offline adaptation setting), using AppWorld as a representative application. For ACE, we run offline adaptation with 1 epoch and 1 reflector refinement round. While increasing the number of epochs or refinement rounds will increase cost, the qualitative trends below should remain: ACE avoids expensive validation-time re-evaluation and performs localized updates rather than repeated full rewrites. For GEPA, we use the official DSPy implementation (DSPy,) with auto="heavy" to maximize optimization strength.
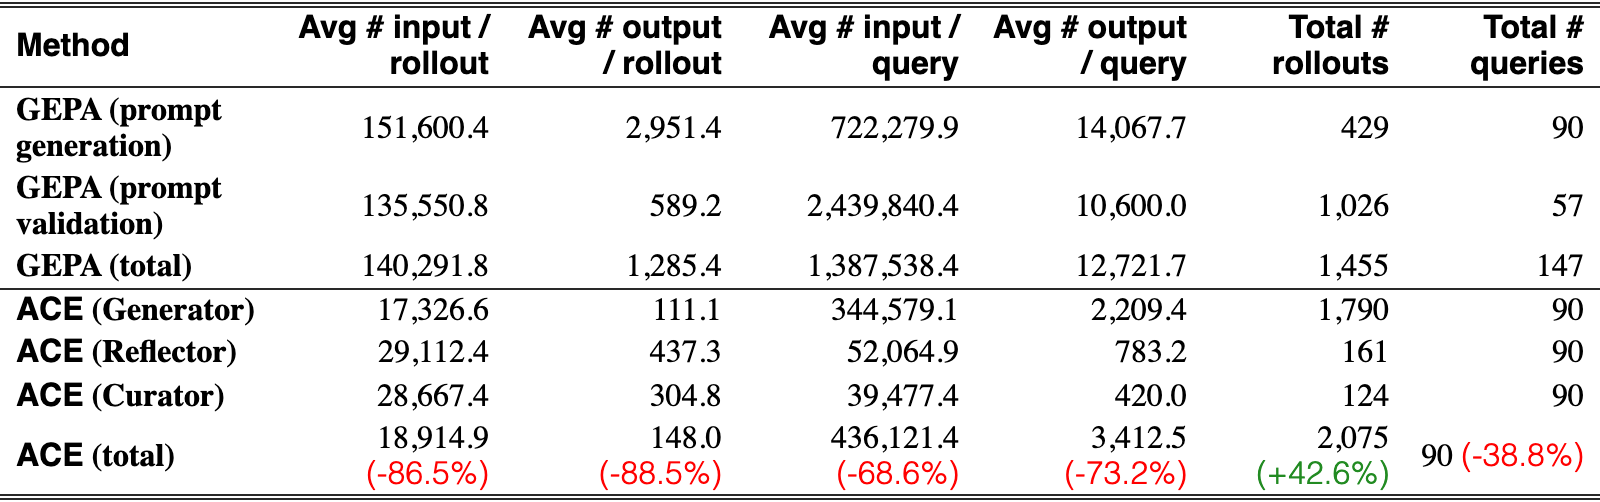
Across adaptation (Table 12 and Table 13), ACE reduces input-token usage by 80.8% relative to GEPA (204.1M 39.3M) and output-token usage by 83.6% (1.87M 0.31M). This gap is primarily driven by (1) GEPA’s prompt-validation loop, which repeatedly evaluates candidate prompts on a held-out validation set (57 queries), incurring substantial additional LLM calls and validation tokens, and (2) ACE’s incremental context updates, which replace full prompt rewrites with localized Generator-Reflector-Curator updates.
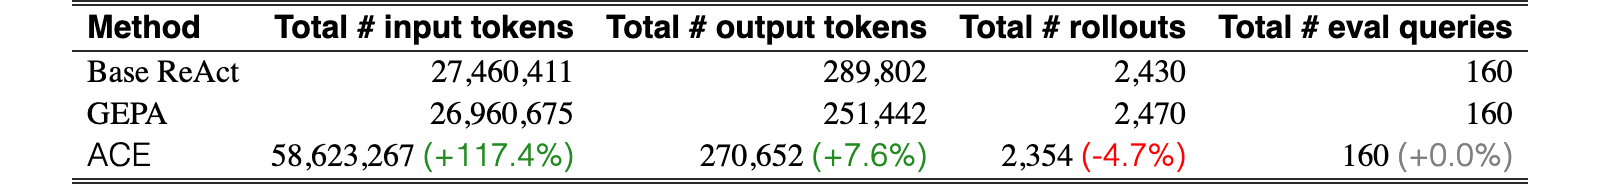
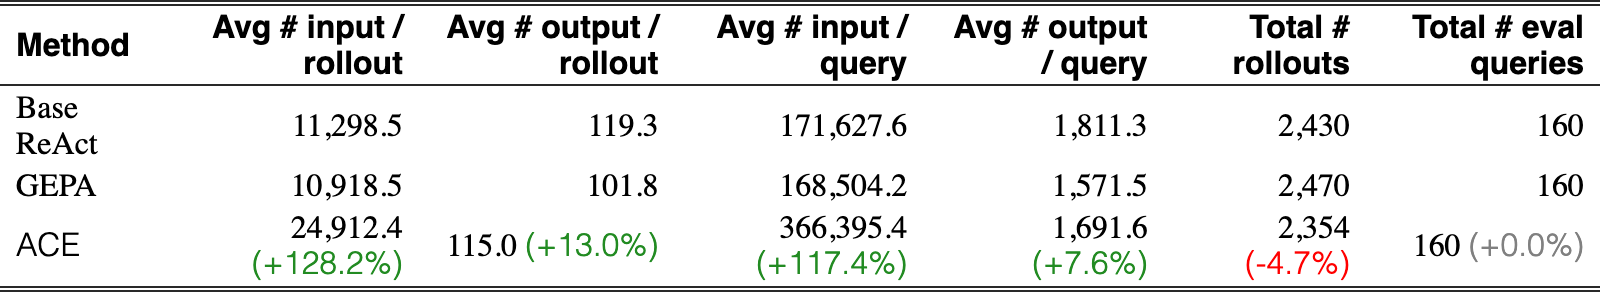
At evaluation time (Table 14 and Table 15), ACE uses more raw input tokens per query than GEPA due to its richer, more actionable playbook. However, output-token usage is similar (115.0 vs. 101.8), and the number of rollouts is comparable across methods. Moreover, under modern prompt/KV-caching infrastructures, the additional input tokens can be largely amortized: using OpenAI’s default prompt caching, 91.8% of ACE’s input tokens are served from cache, resulting in an 82.6% reduction in billed input-token cost (see §4.7).
| Method | Total # input tokens | Total # output tokens | Total # rollouts | Total # queries |
|---|---|---|---|---|
| GEPA (prompt generation) | 65,005,192 | 1,266,090 | 429 | 90 |
| GEPA (prompt validation) | 139,070,904 | 604,098 | 1,026 | 57 |
| GEPA (total) | 204,076,096 | 1,870,188 | 1,455 | 147 |
| ACE (Generator) | 31,012,122 | 198,847 | 1,790 | 90 |
| ACE (Reflector) | 4,685,840 | 70,487 | 161 | 90 |
| ACE (Curator) | 3,552,963 | 37,794 | 124 | 90 |
| ACE (total) | 39,250,925 (-80.8%) | 307,128 (-83.6%) | 2,075 (+42.6%) | 90 (-38.8%) |
View original table
| Method | Avg # input / rollout | Avg # output / rollout | Avg # input / query | Avg # output / query | Total # rollouts | Total # queries |
|---|---|---|---|---|---|---|
| GEPA (prompt generation) | 151,600.4 | 2,951.4 | 722,279.9 | 14,067.7 | 429 | 90 |
| GEPA (prompt validation) | 135,550.8 | 589.2 | 2,439,840.4 | 10,600.0 | 1,026 | 57 |
| GEPA (total) | 140,291.8 | 1,285.4 | 1,387,538.4 | 12,721.7 | 1,455 | 147 |
| ACE (Generator) | 17,326.6 | 111.1 | 344,579.1 | 2,209.4 | 1,790 | 90 |
| ACE (Reflector) | 29,112.4 | 437.3 | 52,064.9 | 783.2 | 161 | 90 |
| ACE (Curator) | 28,667.4 | 304.8 | 39,477.4 | 420.0 | 124 | 90 |
| ACE (total) | 18,914.9 (-86.5%) | 148.0 (-88.5%) | 436,121.4 (-68.6%) | 3,412.5 (-73.2%) | 2,075 (+42.6%) | 90 (-38.8%) |
View original table
| Method | Total # input tokens | Total # output tokens | Total # rollouts | Total # eval queries |
|---|---|---|---|---|
| Base ReAct | 27,460,411 | 289,802 | 2,430 | 160 |
| GEPA | 26,960,675 | 251,442 | 2,470 | 160 |
| ACE | 58,623,267 (+117.4%) | 270,652 (+7.6%) | 2,354 (-4.7%) | 160 (+0.0%) |
View original table
| Method | Avg # input / rollout | Avg # output / rollout | Avg # input / query | Avg # output / query | Total # rollouts | Total # eval queries |
|---|---|---|---|---|---|---|
| Base ReAct | 11,298.5 | 119.3 | 171,627.6 | 1,811.3 | 2,430 | 160 |
| GEPA | 10,918.5 | 101.8 | 168,504.2 | 1,571.5 | 2,470 | 160 |
| ACE | 24,912.4 (+128.2%) | 115.0 (+13.0%) | 366,395.4 (+117.4%) | 1,691.6 (+7.6%) | 2,354 (-4.7%) | 160 (+0.0%) |
View original table
We conduct two analyses to evaluate ACE’s sensitivity to reflection quality. Unless otherwise noted, experiments are run on FiNER with ACE offline adaptation.
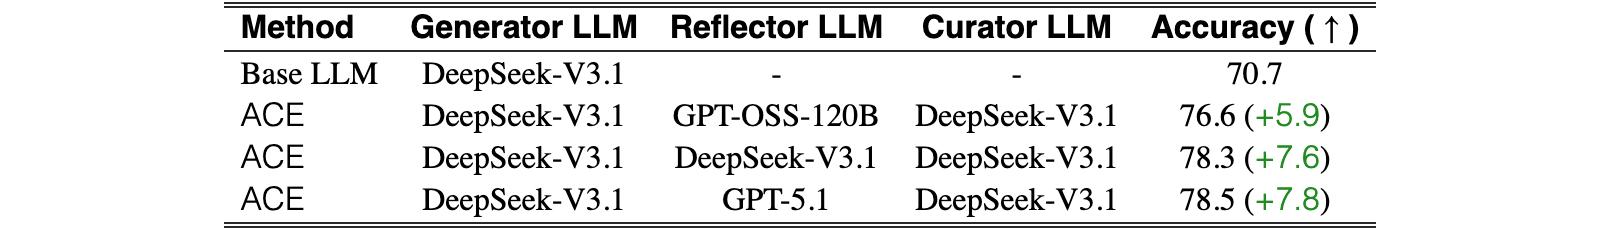
To test whether ACE requires a strong reflector, we vary the Reflector across three models with substantially different capability: GPT-OSS-120B, DeepSeek-V3.1-671B, and GPT-5.1 (Table 16). Across all choices, ACE consistently improves over the base LLM, including when the Reflector is much weaker. While stronger reflectors yield larger gains, the method remains effective across a wide range of reflector strengths.
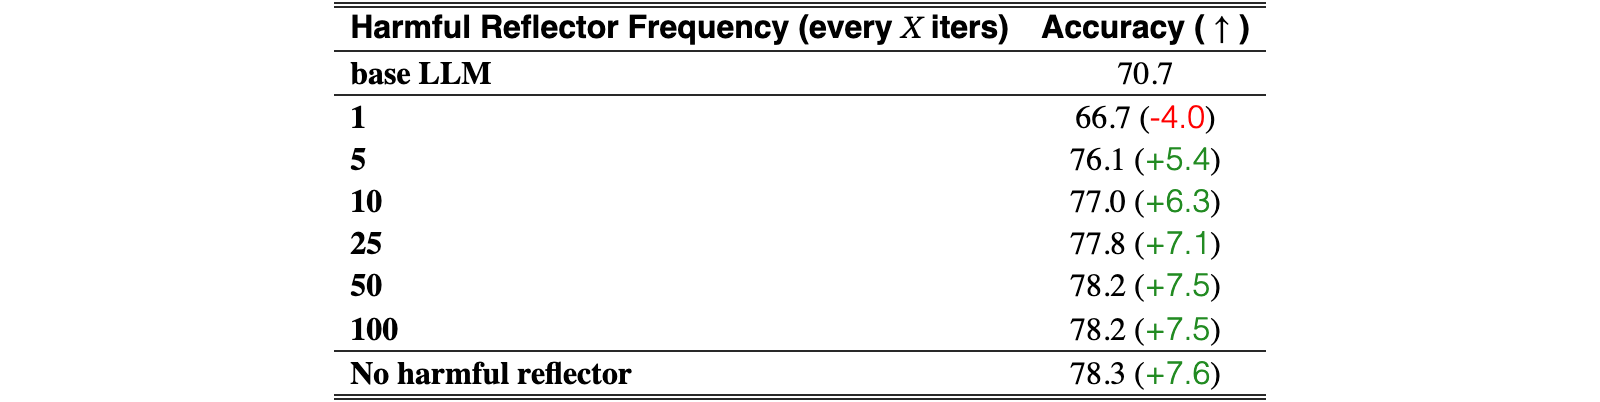
We further stress-test ACE with actively harmful reflector outputs by injecting adversarial or conflicting bullets: we invoke a “harmful” reflector that is explicitly instructed to inject harmful reflection once every adaptation steps, where larger means less frequent corruption (Table 17). ACE is robust to moderate noise levels: performance degrades gradually as corruption becomes more frequent and stays above the base LLM except in the extreme case of injecting harmful updates every iteration. This suggests that ACE’s update mechanism tolerates substantial noise in the reflection stream, with failures emerging only under intentionally adversarial conditions.
ACE is not highly sensitive to reflector quality: (1) weaker reflectors still provide substantial gains, (2) moderate noise or conflicting updates are largely tolerated, and (3) performance drops below the base model only under sustained adversarial corruption. In practice, ACE’s bullet-point analyzer (“grow-and-refine”; §3.2), which merges and deduplicates semantically similar bullets and can filter entries flagged as potentially harmful via metadata, serves as a first line of defense against context noise. Additional safeguards (e.g., contradiction detection, prompting the Curator to prioritize high-confidence updates, or periodic pruning of outdated entries) are compatible extensions that could further improve playbook compactness and consistency (Zhou et al., 2024).
| Method | Generator LLM | Reflector LLM | Curator LLM | Accuracy () |
|---|---|---|---|---|
| Base LLM | DeepSeek-V3.1 | - | - | 70.7 |
| ACE | DeepSeek-V3.1 | GPT-OSS-120B | DeepSeek-V3.1 | 76.6 (+5.9) |
| ACE | DeepSeek-V3.1 | DeepSeek-V3.1 | DeepSeek-V3.1 | 78.3 (+7.6) |
| ACE | DeepSeek-V3.1 | GPT-5.1 | DeepSeek-V3.1 | 78.5 (+7.8) |
View original table
| Harmful Reflector Frequency (every iters) | Accuracy () |
|---|---|
| base LLM | 70.7 |
| 1 | 66.7 (-4.0) |
| 5 | 76.1 (+5.4) |
| 10 | 77.0 (+6.3) |
| 25 | 77.8 (+7.1) |
| 50 | 78.2 (+7.5) |
| 100 | 78.2 (+7.5) |
| No harmful reflector | 78.3 (+7.6) |
View original table
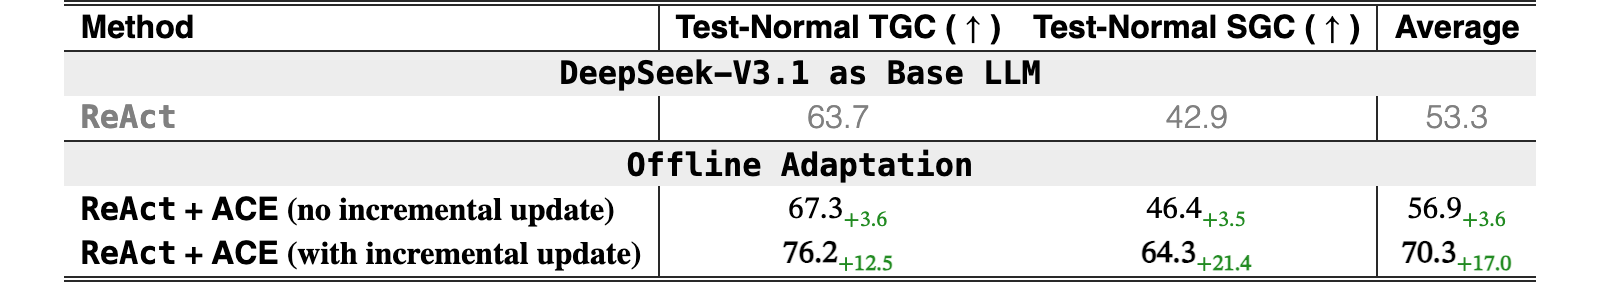
In this ablation, we run offline context adaptation on AppWorld using ACE with and without incremental context updates, and evaluate on the test-normal split with DeepSeek-V3.1. We find that incremental updates are critical: by preserving useful information that would otherwise be lost to context collapse, they account for a large share of ACE ’s gains.
| Method | Test-Normal TGC () | Test-Normal SGC () | Average |
|---|---|---|---|
| DeepSeek-V3.1 as Base LLM | |||
| ReAct | 63.7 | 42.9 | 53.3 |
| Offline Adaptation | |||
| ReAct + ACE (no incremental update) | 67.3_{{\color[rgb]{0.1328,0.5469,0.1328}+3.6}} | 46.4_{{\color[rgb]{0.1328,0.5469,0.1328}+3.5}} | 56.9_{{\color[rgb]{0.1328,0.5469,0.1328}+3.6}} |
| ReAct + ACE (with incremental update) | {\color[rgb]{0,0,0}\mathbf{76.2}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+12.5}}} | {\color[rgb]{0,0,0}\mathbf{64.3}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+21.4}}} | {\color[rgb]{0,0,0}\mathbf{70.3}}_{{\color[rgb]{0.1328,0.5469,0.1328}\mathbf{+17.0}}} |
View original table
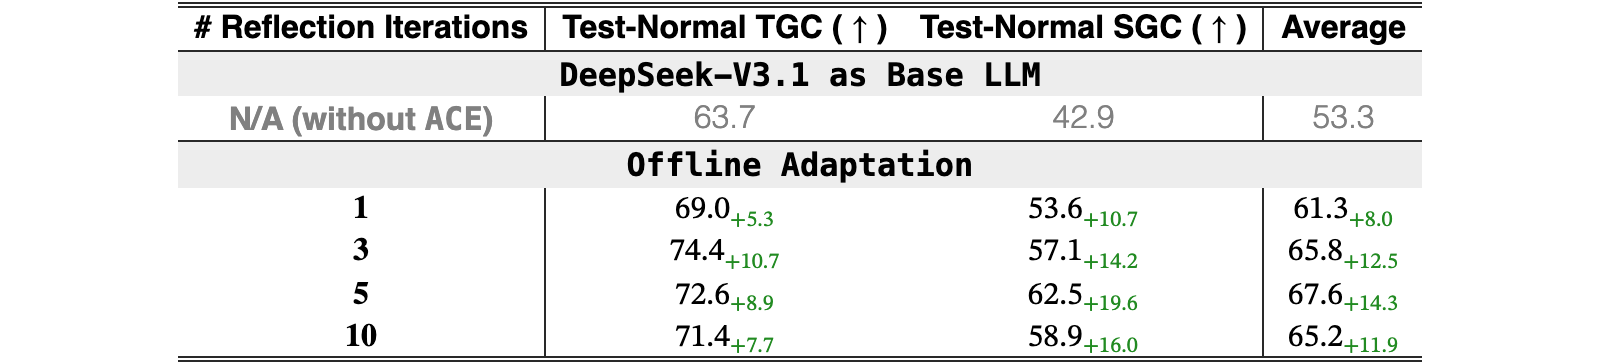
This parameter trades off (1) extracting enough high-quality insights from the inference traces and (2) avoiding “overthinking” that introduces noisy or unnecessary updates. Empirically, 5 rounds offers a good balance. On AppWorld, 1 round under-extracts useful strategy fragments and leaves clear headroom, while too many rounds (e.g., 10) can degrade performance.
| # Reflection Iterations | Test-Normal TGC () | Test-Normal SGC () | Average |
|---|---|---|---|
| DeepSeek-V3.1 as Base LLM | |||
| N/A (without ACE) | 63.7 | 42.9 | 53.3 |
| Offline Adaptation | |||
| 1 | 69.0_{{\color[rgb]{0.1328,0.5469,0.1328}+5.3}} | 53.6_{{\color[rgb]{0.1328,0.5469,0.1328}+10.7}} | 61.3_{{\color[rgb]{0.1328,0.5469,0.1328}+8.0}} |
| 3 | 74.4_{{\color[rgb]{0.1328,0.5469,0.1328}+10.7}} | 57.1_{{\color[rgb]{0.1328,0.5469,0.1328}+14.2}} | 65.8_{{\color[rgb]{0.1328,0.5469,0.1328}+12.5}} |
| 5 | 72.6_{{\color[rgb]{0.1328,0.5469,0.1328}+8.9}} | 62.5_{{\color[rgb]{0.1328,0.5469,0.1328}+19.6}} | 67.6_{{\color[rgb]{0.1328,0.5469,0.1328}+14.3}} |
| 10 | 71.4_{{\color[rgb]{0.1328,0.5469,0.1328}+7.7}} | 58.9_{{\color[rgb]{0.1328,0.5469,0.1328}+16.0}} | 65.2_{{\color[rgb]{0.1328,0.5469,0.1328}+11.9}} |
View original table
This controls how aggressively newly extracted insights are merged with existing entries. On FiNER, performance changes only mildly across the tested range, suggesting ACE is robust to moderate variation in dedup aggressiveness.
| Deduplication Threshold | FiNER (Acc ) |
|---|---|
| DeepSeek-V3.1 as Base LLM | |
| N/A (without ACE) | 70.7 |
| Offline Adaptation | |
| 50% | 77.0_{{\color[rgb]{0.1328,0.5469,0.1328}+6.3}} |
| 70% | 73.9_{{\color[rgb]{0.1328,0.5469,0.1328}+3.2}} |
| 90% | 78.6_{{\color[rgb]{0.1328,0.5469,0.1328}+7.9}} |
View original table
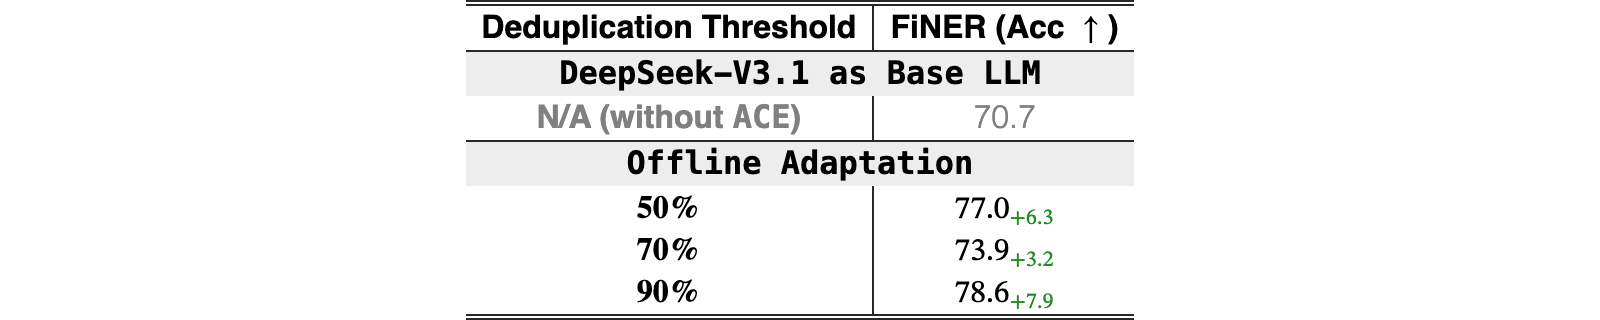
This threshold determines when ACE merges and prunes older or low-utility entries to prevent unbounded growth. It balances (1) retaining enough accumulated context to improve learning from experience and (2) keeping the context compact to reduce cost and limit noise. On FiNER, performance is stable from 10K to 100K tokens, indicating ACE does not require finely tuned length thresholds; pruning mainly removes stale or harmful fragments while preserving core reusable strategies.
| Max Context Length | FiNER (Acc ) |
|---|---|
| DeepSeek-V3.1 as Base LLM | |
| N/A (without ACE) | 70.7 |
| Offline Adaptation | |
| 10K | 78.6_{{\color[rgb]{0.1328,0.5469,0.1328}+7.9}} |
| 50K | 78.4_{{\color[rgb]{0.1328,0.5469,0.1328}+7.7}} |
| 100K | 78.3_{{\color[rgb]{0.1328,0.5469,0.1328}+7.6}} |
View original table
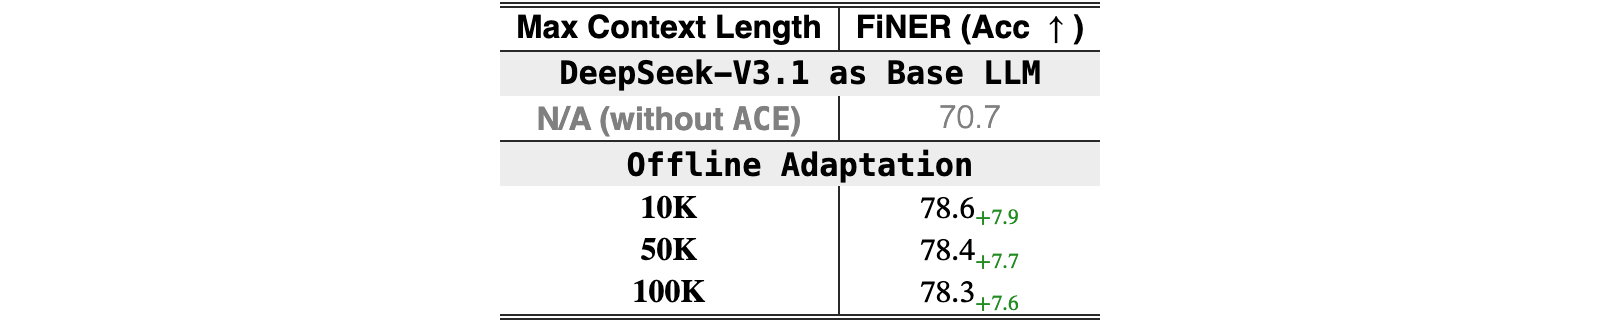
Overall, ACE is not highly sensitive to these hyperparameters: reasonable choices (e.g., 3-5 reflection rounds, 50-90% dedup threshold, and 10K-100K pruning triggers) consistently yield strong performance.
A growing body of work explores how agents can accumulate experience from past trajectories and leverage external (often non-parametric) memory to guide future actions. AgentFly (Zhou et al., 2025) presents an extensible framework where memory evolves continuously as agents solve tasks, enabling scalable reinforcement learning and long-horizon reasoning across diverse environments. AWM (Agent Workflow Memory) (Wang et al., 2025b) induces reusable workflows, i.e., structured routines distilled from past trajectories, and selectively injects them into memory to improve efficiency and generalization in web navigation benchmarks. A-MEM (Xu et al., 2025) introduces a dynamically organized memory system inspired by the Zettelkasten method: each stored memory is annotated with structured attributes (e.g., tags, keywords, contextual descriptions) and automatically linked to relevant past entries, while existing entries are updated to integrate new knowledge, yielding adaptive and context-aware retrieval. Agentic Plan Caching (Zhang et al., 2025c) instead focuses on cost efficiency by extracting reusable plan templates from agent trajectories and caching them for fast execution at test time.
Together, these works demonstrate the value of external memory for improving adaptability, efficiency, and generalization in LLM agents. Our work differs by tackling the broader challenge of context adaptation, which spans not only agent memory but also system prompts, factual evidence, and other inputs underpinning AI systems. We further highlight two fundamental limitations of existing adaptation methods: brevity bias and context collapse; and show that addressing them is essential for robustness, reliability, and scalability beyond raw task performance. Accordingly, our evaluation considers not only accuracy but also cost, latency, and scalability.
Scope and Objective Both GEPA and ACE improve model or agent behavior by adapting context at test time (rather than updating model weights), but they are designed for different forms of adaptation. GEPA treats adaptation as prompt evolution: it iteratively proposes and selects improved instruction prompts using rollout trajectories and reflective feedback, aiming to maximize a task evaluator under a rollout budget. ACE targets settings where performance depends on accumulating and preserving many granular, reusable insights over long horizons. For multi-turn agents (e.g., AppWorld), the model must retain step-by-step procedures and tool-use rules across an interaction. For domain-specific and knowledge-intensive benchmarks (e.g., FiNER, Formula), accuracy depends on keeping many specific rules, edge cases, and domain concepts that are difficult to compress into a single instruction prompt without losing detail.
Update Mechanism and Representation GEPA updates context by generating and selecting new prompt variants in an evolutionary loop, where each candidate is a full prompt optimized end-to-end. ACE instead represents context as a structured, itemized Playbook and applies incremental delta updates: the Curator writes only the new insight, and we merge it into the Playbook with simple deterministic logic. This avoids repeated full-prompt rewrites, helps keep earlier rules stable over long runs, and enables fine-grained bookkeeping (e.g., de-duplication, targeted refinement, and tracking which entries helped or harmed accuracy).
Scope and Objective Both DC and ACE collect reusable insights at test time, but they are aimed at different settings. DC is mainly evaluated on single-turn reasoning benchmarks (e.g., AIME, Game-of-24, GPQA) where each query is independent. In this regime, improvements often come from saving short, reusable heuristics and executable artifacts (e.g., code snippets) that help on later problems. ACE focuses on settings where the details and high-fidelity guidenace need to stick around. For multi-turn agents (e.g., AppWorld), the model must remember step-by-step procedures and tool-use rules across an interaction. For domain-specific and knowledge-intensive benchmarks (e.g., FiNER, Formula), accuracy depends on keeping many specific rules, edge cases, and domain concepts, which are hard to compress without losing information.
Update Mechanism DC updates its memory by rewriting the cheatsheet as a whole, either by regenerating the full cheatsheet each step (DC-CU) or by writing a new summary from retrieved examples (DC-RS). With repeated full rewrites, the model tends to shorten and compress what was written before. This can cause context collapse, which means that useful domain-specific details get dropped over time or disappear suddenly (§2.2). ACE avoids full rewrites by using incremental delta updates. The Curator only writes the new insight, and we merge it into a structured and itemized Playbook with simple deterministic logic. This keeps earlier rules stable over long runs and also makes it easier to track which items helped, remove duplicates, and refine entries. In our ablations (§4.6), removing delta updates leads to a large drop on AppWorld (-11.7% TGC and -27.8% SGC on test-normal), showing that delta updates are a core part of our method.
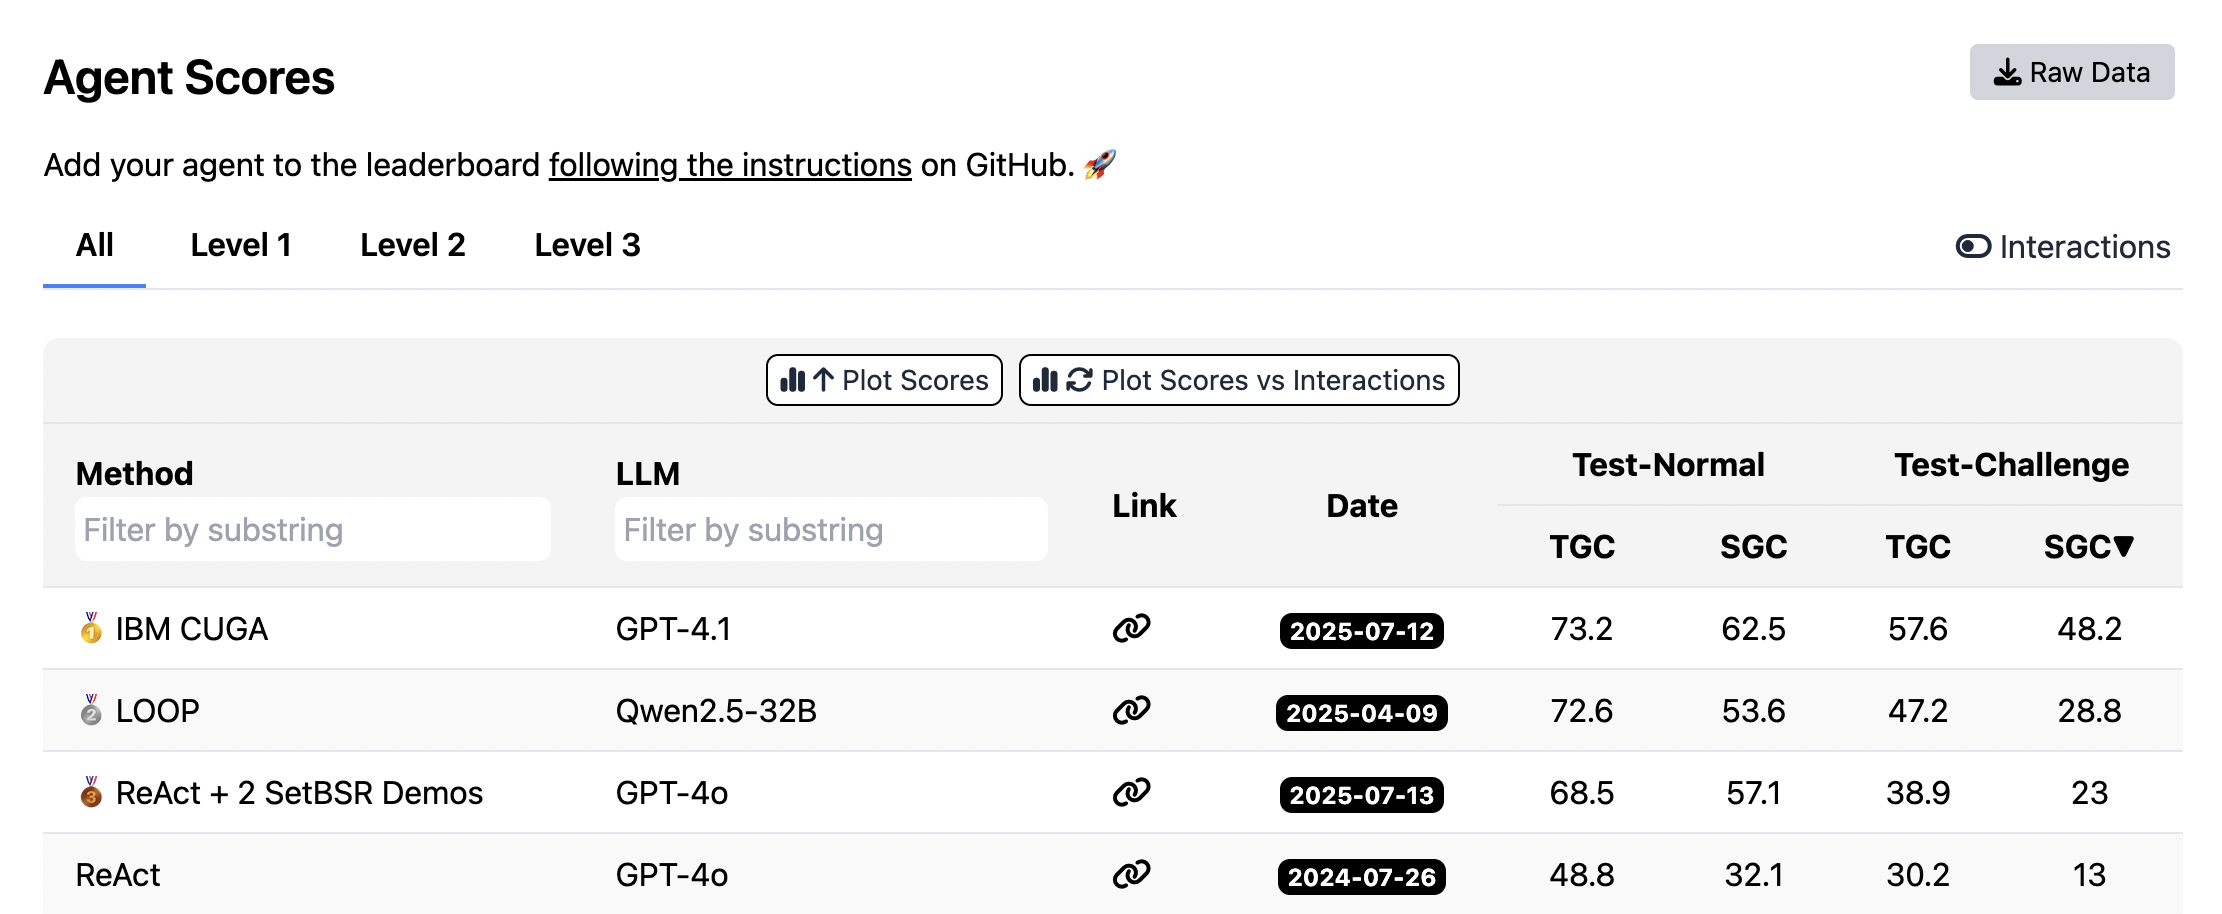
This work focuses on developing algorithms and system frameworks for effective context adaptation in large language models (LLMs). Accordingly, our experiments employ LLMs for the empirical evaluation of the proposed methods. For paper preparation, we used LLMs only to polish writing (e.g., correcting grammatical errors), and not to generate new text from scratch.