mHC: Manifold-Constrained Hyper-Connections
arXiv:2512.24880v2 · This workspace stays on this version. Check arXiv for newer versions
Source comparison finished
Original formulas, table values and figures are preserved. Comparison can miss differences; use the original PDF to check details.
Reading view checked: 221 math expressions, 0 rendering failures; 13 of 13 images available.
Compared 88 of 88 source passages against 19 of 19 PDF pages.
The HTML source contains failed formatting commands; these were omitted from the reading view. The original sources are retained. (1)
13 of 13 figure, table and graphic images captured. Open original PDF
Abstract
Recently, studies exemplified by Hyper-Connections (HC) have extended the ubiquitous residual connection paradigm established over the past decade by expanding the residual stream width and diversifying connectivity patterns. While yielding substantial performance gains, this diversification fundamentally compromises the identity mapping property intrinsic to the residual connection, which causes severe training instability and restricted scalability, and additionally incurs notable memory access overhead. To address these challenges, we propose Manifold-Constrained Hyper-Connections (mHC), a general framework that projects the residual connection space of HC onto a specific manifold to restore the identity mapping property, while incorporating rigorous infrastructure optimization to ensure efficiency. Empirical experiments demonstrate that mHC is effective for training at scale, offering tangible performance improvements and superior scalability. We anticipate that mHC, as a flexible and practical extension of HC, will contribute to a deeper understanding of topological architecture design and suggest promising directions for the evolution of foundational models.
001
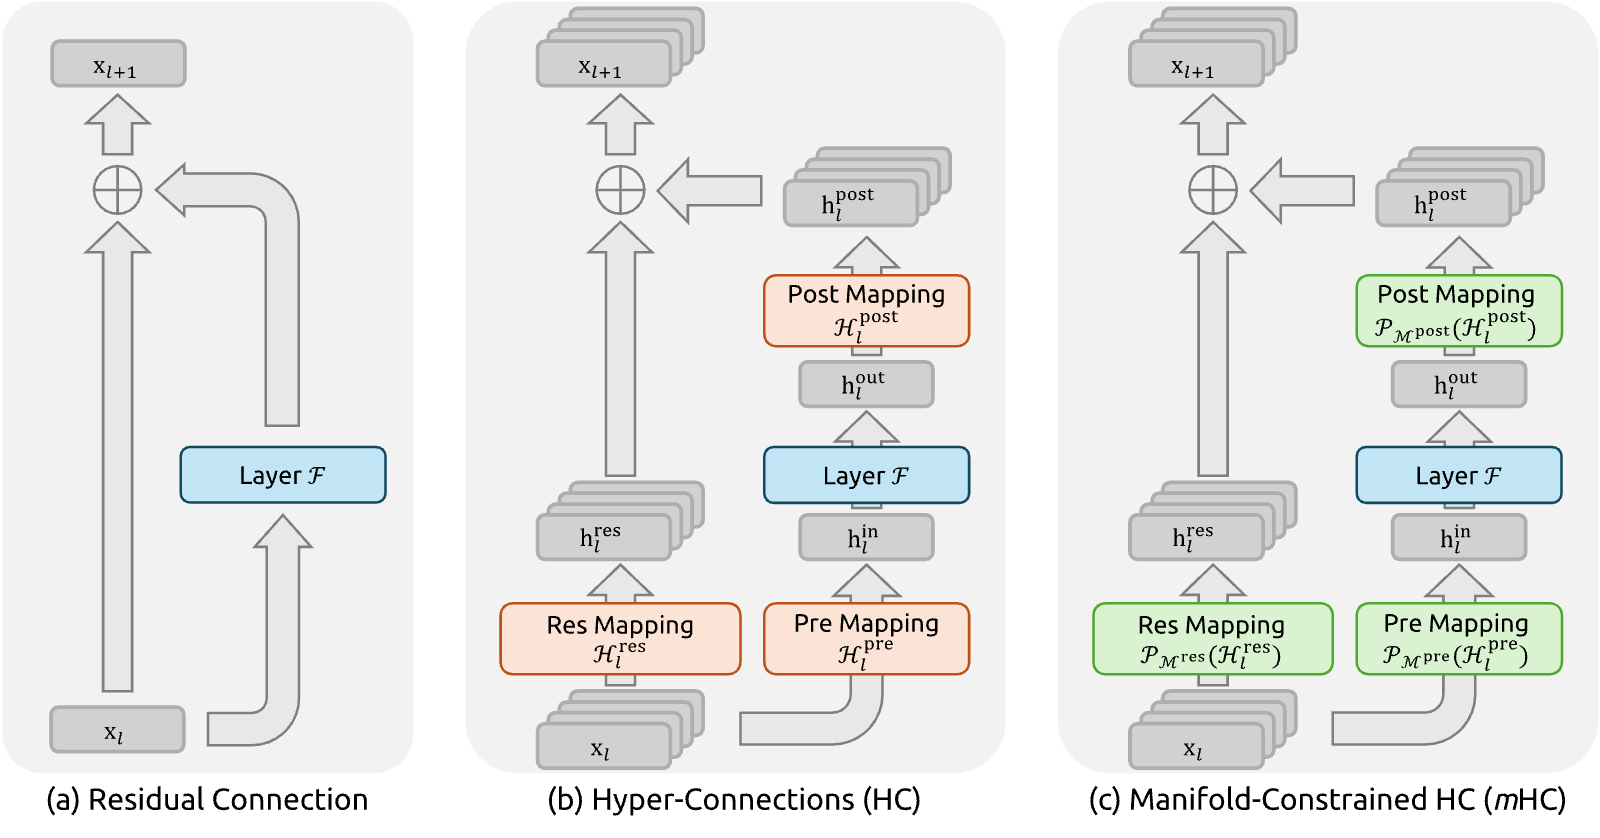
Deep neural network architectures have undergone rapid evolution since the introduction of ResNets (He et al., 2016a). As illustrated in Fig. 1(a), the structure of a single-layer can be formulated as follows:
where and denote the -dimensional input and output of the -th layer, respectively, and represents the residual function. Although the residual function has evolved over the past decade to include various operations such as convolution, attention mechanisms, and feed forward networks, the paradigm of the residual connection has maintained its original form. Accompanying the progression of Transformer (Vaswani et al., 2017) architecture, this paradigm has currently established itself as a fundamental design element in large language models (LLMs) (Brown et al., 2020; Touvron et al., 2023; Liu et al., 2024b).
This success is primarily attributed to the concise form of the residual connection. More importantly, early research (He et al., 2016b) revealed that the identity mapping property of the residual connection maintains stability and efficiency during large-scale training. By recursively extending the residual connection across multiple layers, Eq. (1) yields:
where and correspond to deeper and shallower layers, respectively. The term identity mapping refers to the component itself, which emphasizes the property that the signal from the shallower layer maps directly to the deeper layer without any modification.
Recently, studies exemplified by Hyper-Connections (HC) (Zhu et al., 2024) have introduced a new dimension to the residual connection and empirically demonstrated its performance potential. The single-layer architecture of HC is illustrated in Fig. 1(b). By expanding the width of the residual stream and enhancing connection complexity, HC significantly increases topological complexity without altering the computational overhead of individual units regarding FLOPs. Formally, single-layer propagation in HC is defined as:
where and denote the input and output of the -th layer, respectively. Unlike the formulation in Eq. (1), the feature dimension of and is expanded from to , where is the expansion rate. The term represents a learnable mapping that mixes features within the residual stream. Also as a learnable mapping, aggregates features from the -dim stream into a -dim layer input, and conversely, maps the layer output back onto the stream.
However, as the training scale increases, HC introduces potential risks of instability. The primary concern is that the unconstrained nature of HC compromises the identity mapping property when the architecture extends across multiple layers. In architectures comprising multiple parallel streams, an ideal identity mapping serves as a conservation mechanism. It ensures that the average signal intensity across streams remains invariant during both forward and backward propagation. Recursively extending HC to multiple layers via Eq. (3) yields:
where and represent a deeper layer and a shallower layer, respectively. In contrast to Eq. (2), the composite mapping in HC fails to preserve the global mean of the features. This discrepancy leads to unbounded signal amplification or attenuation, resulting in instability during large-scale training. A further consideration is that, while HC preserves computational efficiency in terms of FLOPs, the hardware efficiency concerning memory access costs for the widened residual stream remains unaddressed in the original design. These factors collectively restrict the practical scalability of HC and hinder its application in large-scale training.
To address these challenges, we propose Manifold-Constrained Hyper-Connections (mHC), as shown in Fig. 1(c), a general framework that projects the residual connection space of HC onto a specific manifold to restore the identity mapping property, while incorporating rigorous infrastructure optimization to ensure efficiency. Specifically, mHC utilizes the Sinkhorn-Knopp algorithm (Sinkhorn and Knopp, 1967) to entropically project onto the Birkhoff polytope. This operation effectively constrains the residual connection matrices within the manifold that is constituted by doubly stochastic matrices. Since the row and column sums of these matrices equal to , the operation functions as a convex combination of the input features. This characteristic facilitates a well-conditioned signal propagation where the feature mean is conserved, and the signal norm is strictly regularized, effectively mitigating the risk of vanishing or exploding signals. Furthermore, due to the closure of matrix multiplication for doubly stochastic matrices, the composite mapping retains this conservation property. Consequently, mHC effectively maintains the stability of identity mappings between arbitrary depths. To ensure efficiency, we employ kernel fusion and develop mixed precision kernels utilizing TileLang (Wang et al., 2025). Furthermore, we mitigate the memory footprint through selective recomputing and carefully overlap communication within the DualPipe schedule (Liu et al., 2024b).
Extensive experiments on language model pretraining demonstrate that mHC exhibits exceptional stability and scalability while maintaining the performance advantages of HC. In-house large-scale training indicates that mHC supports training at scale and introduces only a 6.7% additional time overhead when expansion rate .
Architectural advancements in deep learning can be primarily classified into micro-design and macro-design. Micro-design concerns the internal architecture of computational blocks, specifying how features are processed across spatial, temporal, and channel dimensions. In contrast, macro-design establishes the inter-block topological structure, thereby dictating how feature representations are propagated, routed, and merged across distinct layers.
Driven by parameter sharing and translation invariance, convolution initially dominated the processing of structured signals. While subsequent variations such as depthwise separable (Chollet, 2017) and grouped convolutions (Xie et al., 2017) optimized efficiency, the advent of Transformers (Vaswani et al., 2017) established Attention and Feed-Forward Networks (FFNs) as the fundamental building blocks of modern architecture. Attention mechanisms facilitate global information propagation, while FFNs enhance the representational capacity of individual features. To balance performance with the computational demands of LLMs, attention mechanisms have evolved towards efficient variants such as Multi-Query Attention (MQA) (Shazeer, 2019), Grouped-Query Attention (GQA) (Ainslie et al., 2023), and Multi-Head Latent Attention (MLA) (Liu et al., 2024a). Simultaneously, FFNs have been generalized into sparse computing paradigms via Mixture-of-Experts (MoE) (Shazeer et al., 2017; Lepikhin et al., 2020; Fedus et al., 2022), allowing for massive parameter scaling without proportional computational costs.
Macro-design governs the global topology of the network (Srivastava et al., 2015). Following ResNet (He et al., 2016a), architectures such as DenseNet (Huang et al., 2017) and FractalNet (Larsson et al., 2016) aimed to enhance performance by increasing topological complexity through dense connectivity and multi-path structures, respectively. Deep Layer Aggregation (DLA) (Yu et al., 2018) further extended this paradigm by recursively aggregating features across various depths and resolutions.
More recently, the focus of macro-design has shifted toward expanding the width of the residual stream (Chai et al., 2020; Fang et al., 2023; Xie et al., 2023; Pagliardini et al., 2024; Menghani et al., 2025; Heddes et al., 2025; Zhu et al., 2024; Mak and Flanigan, 2025; Xiao et al., 2025). Hyper-Connections (HC) (Zhu et al., 2024) introduced learnable matrices to modulate connection strengths among features at varying depths, while the Residual Matrix Transformer (RMT) (Mak and Flanigan, 2025) replaced the standard residual stream with an outer-product memory matrix to facilitate feature storage. Similarly, MUDDFormer (Xiao et al., 2025) employs multiway dynamic dense connections to optimize cross-layer information flow. Despite their potential, these approaches compromise the inherent identity mapping property of the residual connection, thereby introducing instability and hindering scalability. Furthermore, they incur significant memory access overhead due to expanded feature widths. Building upon HC, the proposed mHC restricts the residual connection space onto a specific manifold to restore the identity mapping property, while also incorporating rigorous infrastructure optimizations to ensure efficiency. This approach enhances stability and scalability while maintaining the topological benefits of expanded connections.
We first establish the notation used in this work. In the HC formulation, the input to the -th layer, , is expanded by a factor of to construct a hidden matrix which can be viewed as -stream residual. This operation effectively broadens the width of the residual stream. To govern the read-out, write-in, and updating processes of this stream, HC introduces three learnable linear mappings—, and . These mappings modify the standard residual connection shown in Eq. (1), resulting in the formulation given in Eq. (3).
In the HC formulation, learnable mappings are composed of two parts of coefficients: the input-dependent one and the global one, referred to as dynamic mappings and static mappings, respectively. Formally, HC computes the coefficients as follows:
where (Zhang and Sennrich, 2019) is applied to the last dimension, and the scalars and are learnable gating factors initialized to small values. The dynamic mappings are derived via linear projections parameterized by and , while the static mappings are represented by learnable biases and .
It is worth noting that the introduction of these mappings—, , and —incurs negligible computational overhead, as the typical expansion rate , e.g. 4, is much smaller than the input dimension . With this design, HC effectively decouples the information capacity of the residual stream from the layer’s input dimension, which is strongly correlated with the model’s computational complexity (FLOPs). Consequently, HC offers a new avenue for scaling by adjusting the residual stream width, complementing the traditional scaling dimensions of model FLOPs and training data size discussed in pre-training scaling laws (Hoffmann et al., 2022).
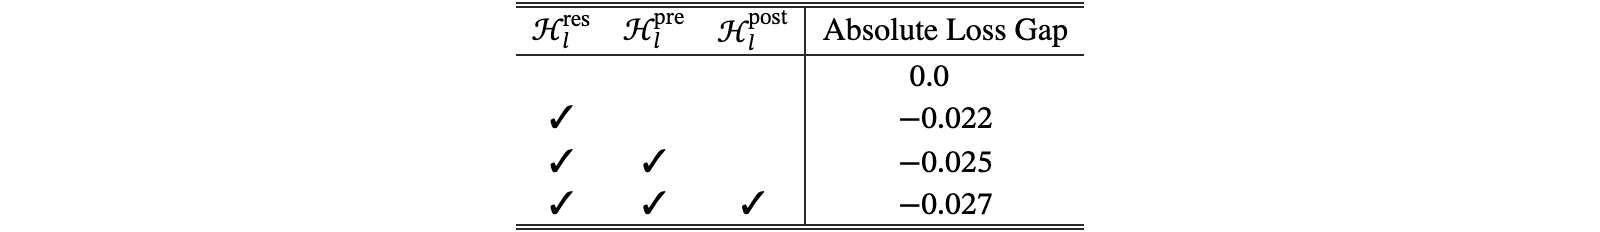
Although HC necessitates three mappings to manage the dimensional mismatch between the residual stream and the layer input, preliminary experiments presented in Tab. 1 indicate that the residual mapping yields the most significant performance gain. This finding underscores the critical importance of effective information exchange within the residual stream.
| Absolute Loss Gap | |||
| ✓ | |||
| ✓ | ✓ | ||
| ✓ | ✓ | ✓ |
View original table
While the residual mapping is instrumental for performance, its sequential application poses a significant risk to numerical stability. As detailed in Eq. (4), when HC is extended across multiple layers, the effective signal propagation from layer to is governed by the composite mapping . Since the learnable mapping is unconstrained, this composite mapping inevitably deviates from the identity mapping. Consequently, the signal magnitude is prone to explosion or vanishing during both the forward pass and backpropagation. This phenomenon undermines the fundamental premise of residual learning, which relies on unimpeded signal flow, thereby destabilizing the training process in deeper or larger-scale models.
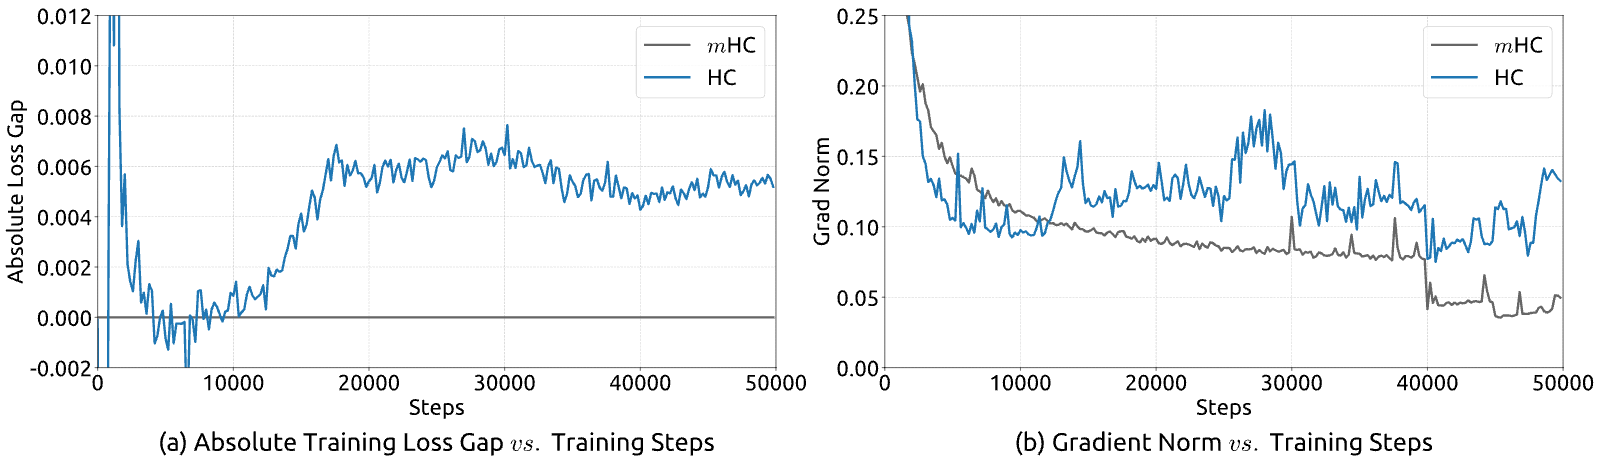
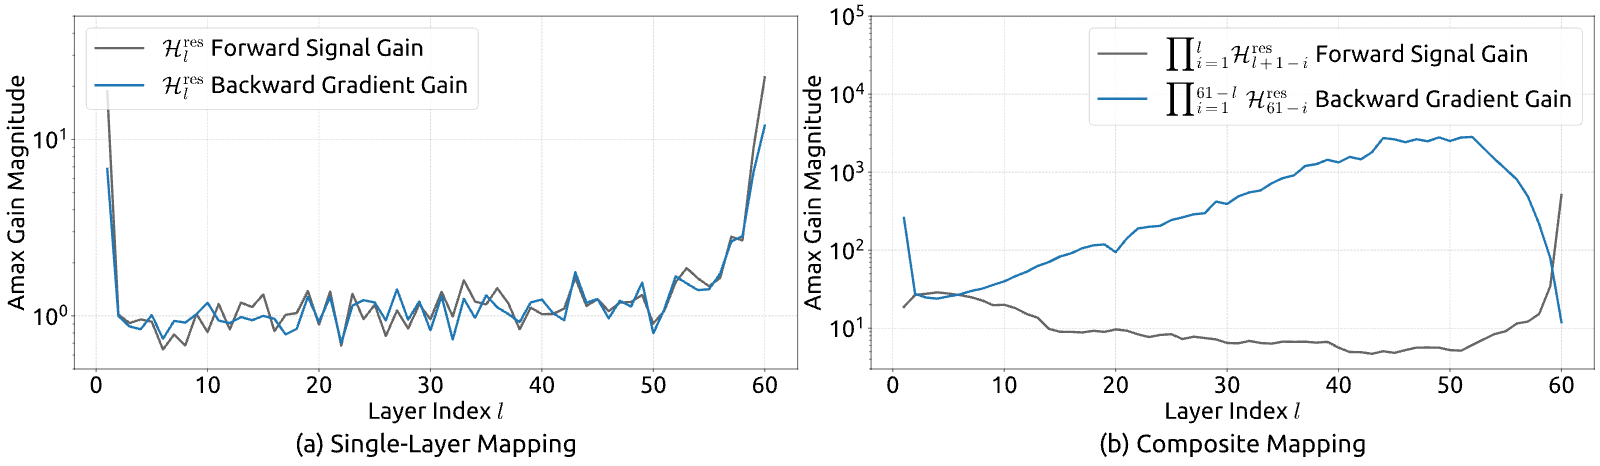
Empirical evidence supports this analysis. We observe unstable loss behavior in large-scale experiments, as illustrated in Fig. 2. Taking mHC as the baseline, HC exhibits an unexpected loss surge around the 12k step, which is highly correlated with the instability in the gradient norm. Furthermore, the analysis on validates the mechanism of this instability. To quantify how the composite mapping amplifies signals along the residual stream, we utilize two metrics. The first, based on the maximum absolute value of the row sums of the composite mapping, captures the worst-case expansion in the forward pass. The second, based on the maximum absolute column sum, corresponds to the backward pass. We refer to these metrics as the Amax Gain Magnitude of the composite mapping. As shown in Fig. 3 (b), the Amax Gain Magnitude yields extreme values with peaks of 3000, a stark divergence from 1 that confirms the presence of exploding residual streams.
While the computational complexity of HC remains manageable due to the linearity of the additional mappings, the system-level overhead prevents a non-negligible challenge. Specifically, memory access (I/O) costs often constitute one of the primary bottlenecks in modern model architectures, which is widely referred to as the “memory wall” (Dao et al., 2022). This bottleneck is frequently overlooked in architectural design, yet it decisively impacts runtime efficiency.
| Method | Operation | Read (Elements) | Write (Elements) |
| Residual Connection | Residual Merge | ||
| Total I/O | |||
| Hyper- Connections | Calculate , , | ||
| Residual Merge | |||
| Total I/O |
View original table
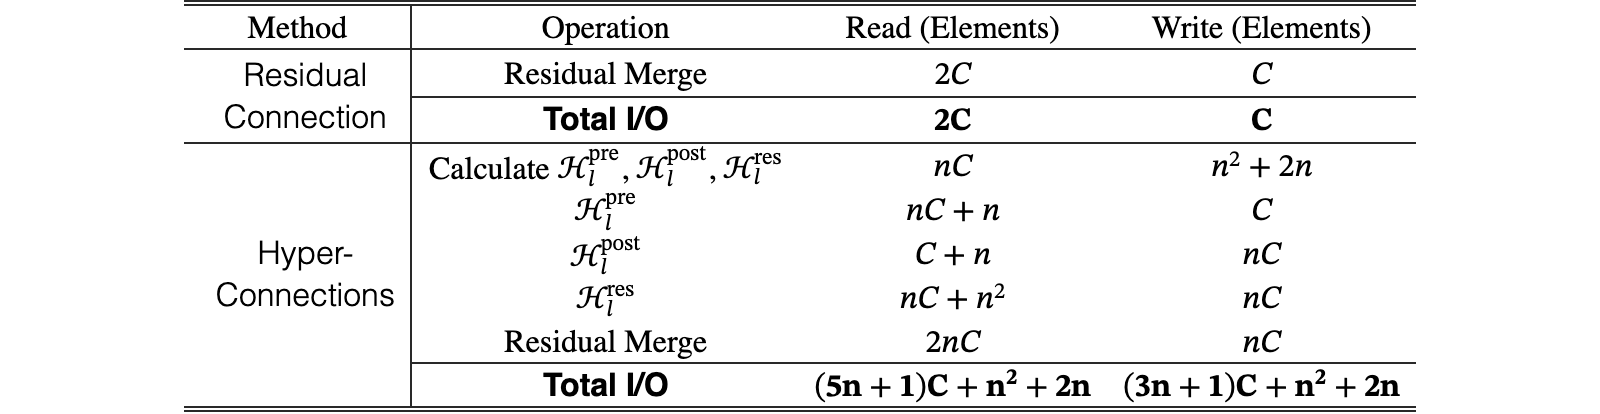
Focusing on the widely adopted pre-norm Transformer (Vaswani et al., 2017) architecture, we analyze the I/O patterns inherent to HC. Tab. 2 summarizes the per token memory access overhead in a single residual layer introduced by the -stream residual design. The analysis reveals that HC increases the memory access cost by a factor approximately proportional to . This excessive I/O demand significantly degrades training throughput without the mitigation of fused kernels. Besides, since , , and involve learnable parameters, their intermediate activations are required for backpropagation. This results in a substantial increase in the GPU memory footprint, often necessitating gradient checkpointing to maintain feasible memory usage. Furthermore, HC requires -fold more communication cost in pipeline parallelism (Qi et al., 2024), leading to larger bubbles and decreasing the training throughput.
Drawing inspiration from the identity mapping principle (He et al., 2016b), the core premise of mHC is to constrain the residual mapping onto a specific manifold. While the original identity mapping ensures stability by enforcing , it fundamentally precludes information exchange within the residual stream, which is critical for maximizing the potential of multi-stream architectures. Therefore, we propose projecting the residual mapping onto a manifold that simultaneously maintains the stability of signal propagation across layers and facilitates mutual interaction among residual streams to preserve the model’s expressivity. To this end, we restrict to be a doubly stochastic matrix, which has non-negative entries where both the rows and columns sum to 1. Formally, let denote the manifold of doubly stochastic matrices (also known as the Birkhoff polytope). We constrain to , defined as:
where represents the -dimensional vector of all ones.
It is worth noting that when , the doubly stochastic condition degenerates to the scalar , thereby recovering the original identity mapping. The choice of double stochasticity confers several rigorous theoretical properties beneficial for large-scale model training:
- 1.
Norm Preservation: The spectral norm of a doubly stochastic matrix is bounded by 1 (i.e., ). This implies that the learnable mapping is non-expansive, effectively mitigating the gradient explosion problem.
- 2.
Compositional Closure: The set of doubly stochastic matrices is closed under matrix multiplication. This ensures that the composite residual mapping across multiple layers, , remains doubly stochastic, thereby preserving stability throughout the entire depth of the model.
- 3.
Geometric Interpretation via the Birkhoff Polytope: The set forms the Birkhoff polytope, which is the convex hull of the set of permutation matrices. This provides a clear geometric interpretation: the residual mapping acts as a convex combination of permutations. Mathematically, the repeated application of such matrices tends to increase the mixing of information across streams monotonically, effectively functioning as a robust feature fusion mechanism.
Additionally, we impose non-negativity constraints on the input mappings and output mappings . This constrain prevents signal cancellation arising from the composition of positive and negative coefficients, which can also be considered as a special manifold projection.
In this section, we detail the calculation process of in mHC. Given the input hidden matrix at the -th layer, we first flatten it into a vector to preserve full context information. Then, we follow the original HC formulation to get the dynamic mappings and the static mappings as follows:
where and are linear projections for dynamic mappings and is a reshape function from to .
Then, the final constrained mappings are obtained via:
where denotes the Sigmoid function. The operator firstly makes all elements to be positive via an exponent operator and then conducts iterative normalization process that alternately rescales rows and columns to sum to 1. Specifically, given a positive matrix as the start point, the normalization iteration proceeds as:
where and denote row and column normalization, respectively. This process converges to a doubly stochastic matrix as . We choose as a practical value in our experiments.
In this section, we detail the infrastructure design tailored for mHC. Through rigorous optimization, we implement mHC (with ) in large-scale models with a marginal training overhead of only 6.7%.
Observing that RMSNorm in mHC imposes significant latency when operating on the high-dimensional hidden state , we reorder the dividing-by-norm operation to follow the matrix multiplication. This optimization maintains mathematical equivalence while improving efficiency. Furthermore, we employ mixed-precision strategies to maximize numerical accuracy without compromising speed, and fuse multiple operations with shared memory access into unified compute kernels to reduce memory bandwidth bottlenecks. Based on the inputs and parameters detailed in Eq. (10) to (13), we implement three specialized mHC kernels to compute , , and . In these kernels, the biases and linear projections are consolidated into and , and the RMSNorm weight is also absorbed in .
- •
Eq. (14) to (15): We develop a unified kernel that fuses two scans on , leveraging matrix multiplication units to maximize memory bandwidth utilization. The backward pass—comprising two matrix multiplications—is similarly consolidated into a single kernel, eliminating redundant reloading of . Both kernels feature a finely tuned pipeline (load, cast, compute, store) to efficiently handle mixed-precision processing.
- •
- •
Eq. (19): We implement the Sinkhorn-Knopp iteration within a single kernel. For the backward pass, we derive a custom backward kernel that recomputes the intermediate results on-chip and traverses the entire iteration.
Using the coefficients derived from the aforementioned kernels, we introduce two additional kernels to apply these mappings: one for and another for . Through fusing the application of and with residual merging, we reduce the number of elements read from to and the number of elements written from to for this kernel. We efficiently implement the majority of kernels (excluding Eq. (14) to (15)) using TileLang (Wang et al., 2025). This framework streamlines the implementation of kernels with complex calculation process and allows us to fully utilize the memory bandwidth with minimal engineering effort.
The -stream residual design introduces substantial memory overhead during training. To mitigate this, we discard the intermediate activations of the mHC kernels after the forward pass and recompute them on-the-fly in the backward pass, through re-executing the mHC kernels without the heavy layer function . Consequently, for a block of consecutive layers, we need only store the input to the first layer. Excluding lightweight coefficients while accounting for the pre-norm with in , Tab. 3 summarizes the intermediate activations preserved for the backward pass.
| Activations | |||||
| Size (Elements) | |||||
| Stored Method | Every layers | Every layer | Transient inside layers | ||
View original table
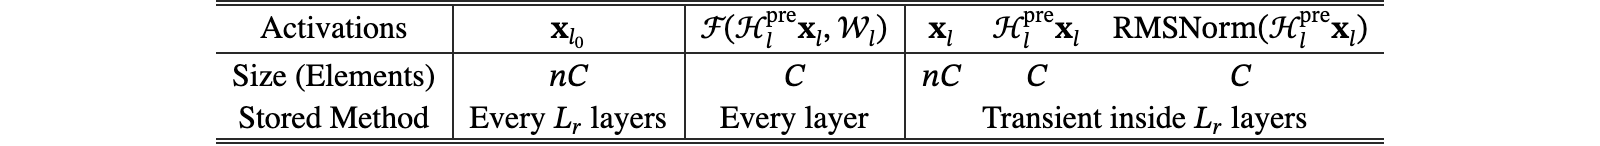
Since mHC kernels recomputation is performed for blocks of consecutive layers, given a total of layers, we must persistently store the first layer input for all blocks for the backward pass. In addition to this resident memory, the recomputation process introduces a transient memory overhead of elements for the active block, which determines the peak memory usage during backpropagation. Consequently, we determine the optimal block size by minimizing the total memory footprint corresponded to :
Furthermore, pipeline parallelism in large-scale training imposes a constraint: recomputation blocks must not cross pipeline stage boundaries. Observing that the theoretical optimum typically aligns with the number of layers per pipeline stage, we choose to synchronize the recomputation boundaries with the pipeline stages.
In large-scale training, pipeline parallelism is the standard practice for mitigating parameter and gradient memory footprints. Specifically, we adopt the DualPipe schedule (Liu et al., 2024b), which effectively overlaps scale-out interconnected communication traffic, such as those in expert and pipeline parallelism. However, compared to the single-stream design, the proposed -stream residual in mHC incurs substantial communication latency across pipeline stages. Furthermore, at stage boundaries, the recomputation of mHC kernels for all layers introduces non-negligible computational overhead. To address these bottlenecks, we extend the DualPipe schedule (see Fig. 4) to facilitate improved overlapping of communication and computation at pipeline stage boundaries.
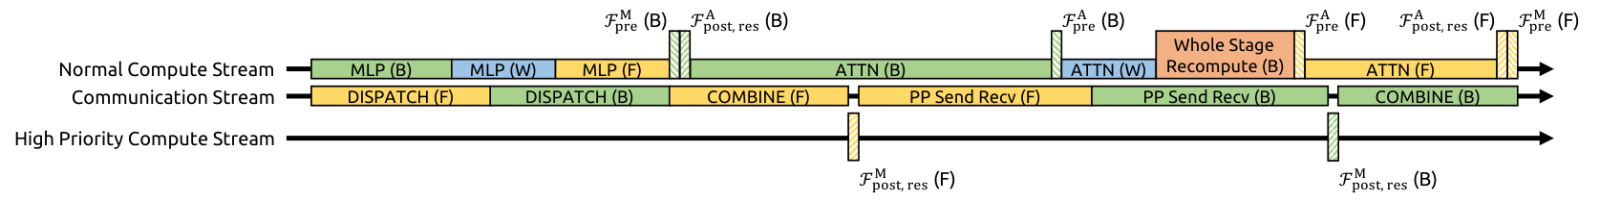
Notably, to prevent blocking the communication stream, we execute the kernels of MLP (i.e. FFN) layers on a dedicated high-priority compute stream. We further refrain from employing persistent kernels for long-running operations in attention layers, thereby preventing extended stalls. This design enables the preemption of overlapped attention computations, allowing for flexible scheduling while maintaining high utilization of the compute device’s processing units. Furthermore, the recomputation process is decoupled from pipeline communication dependencies, as the initial activation of each stage is already cached locally.
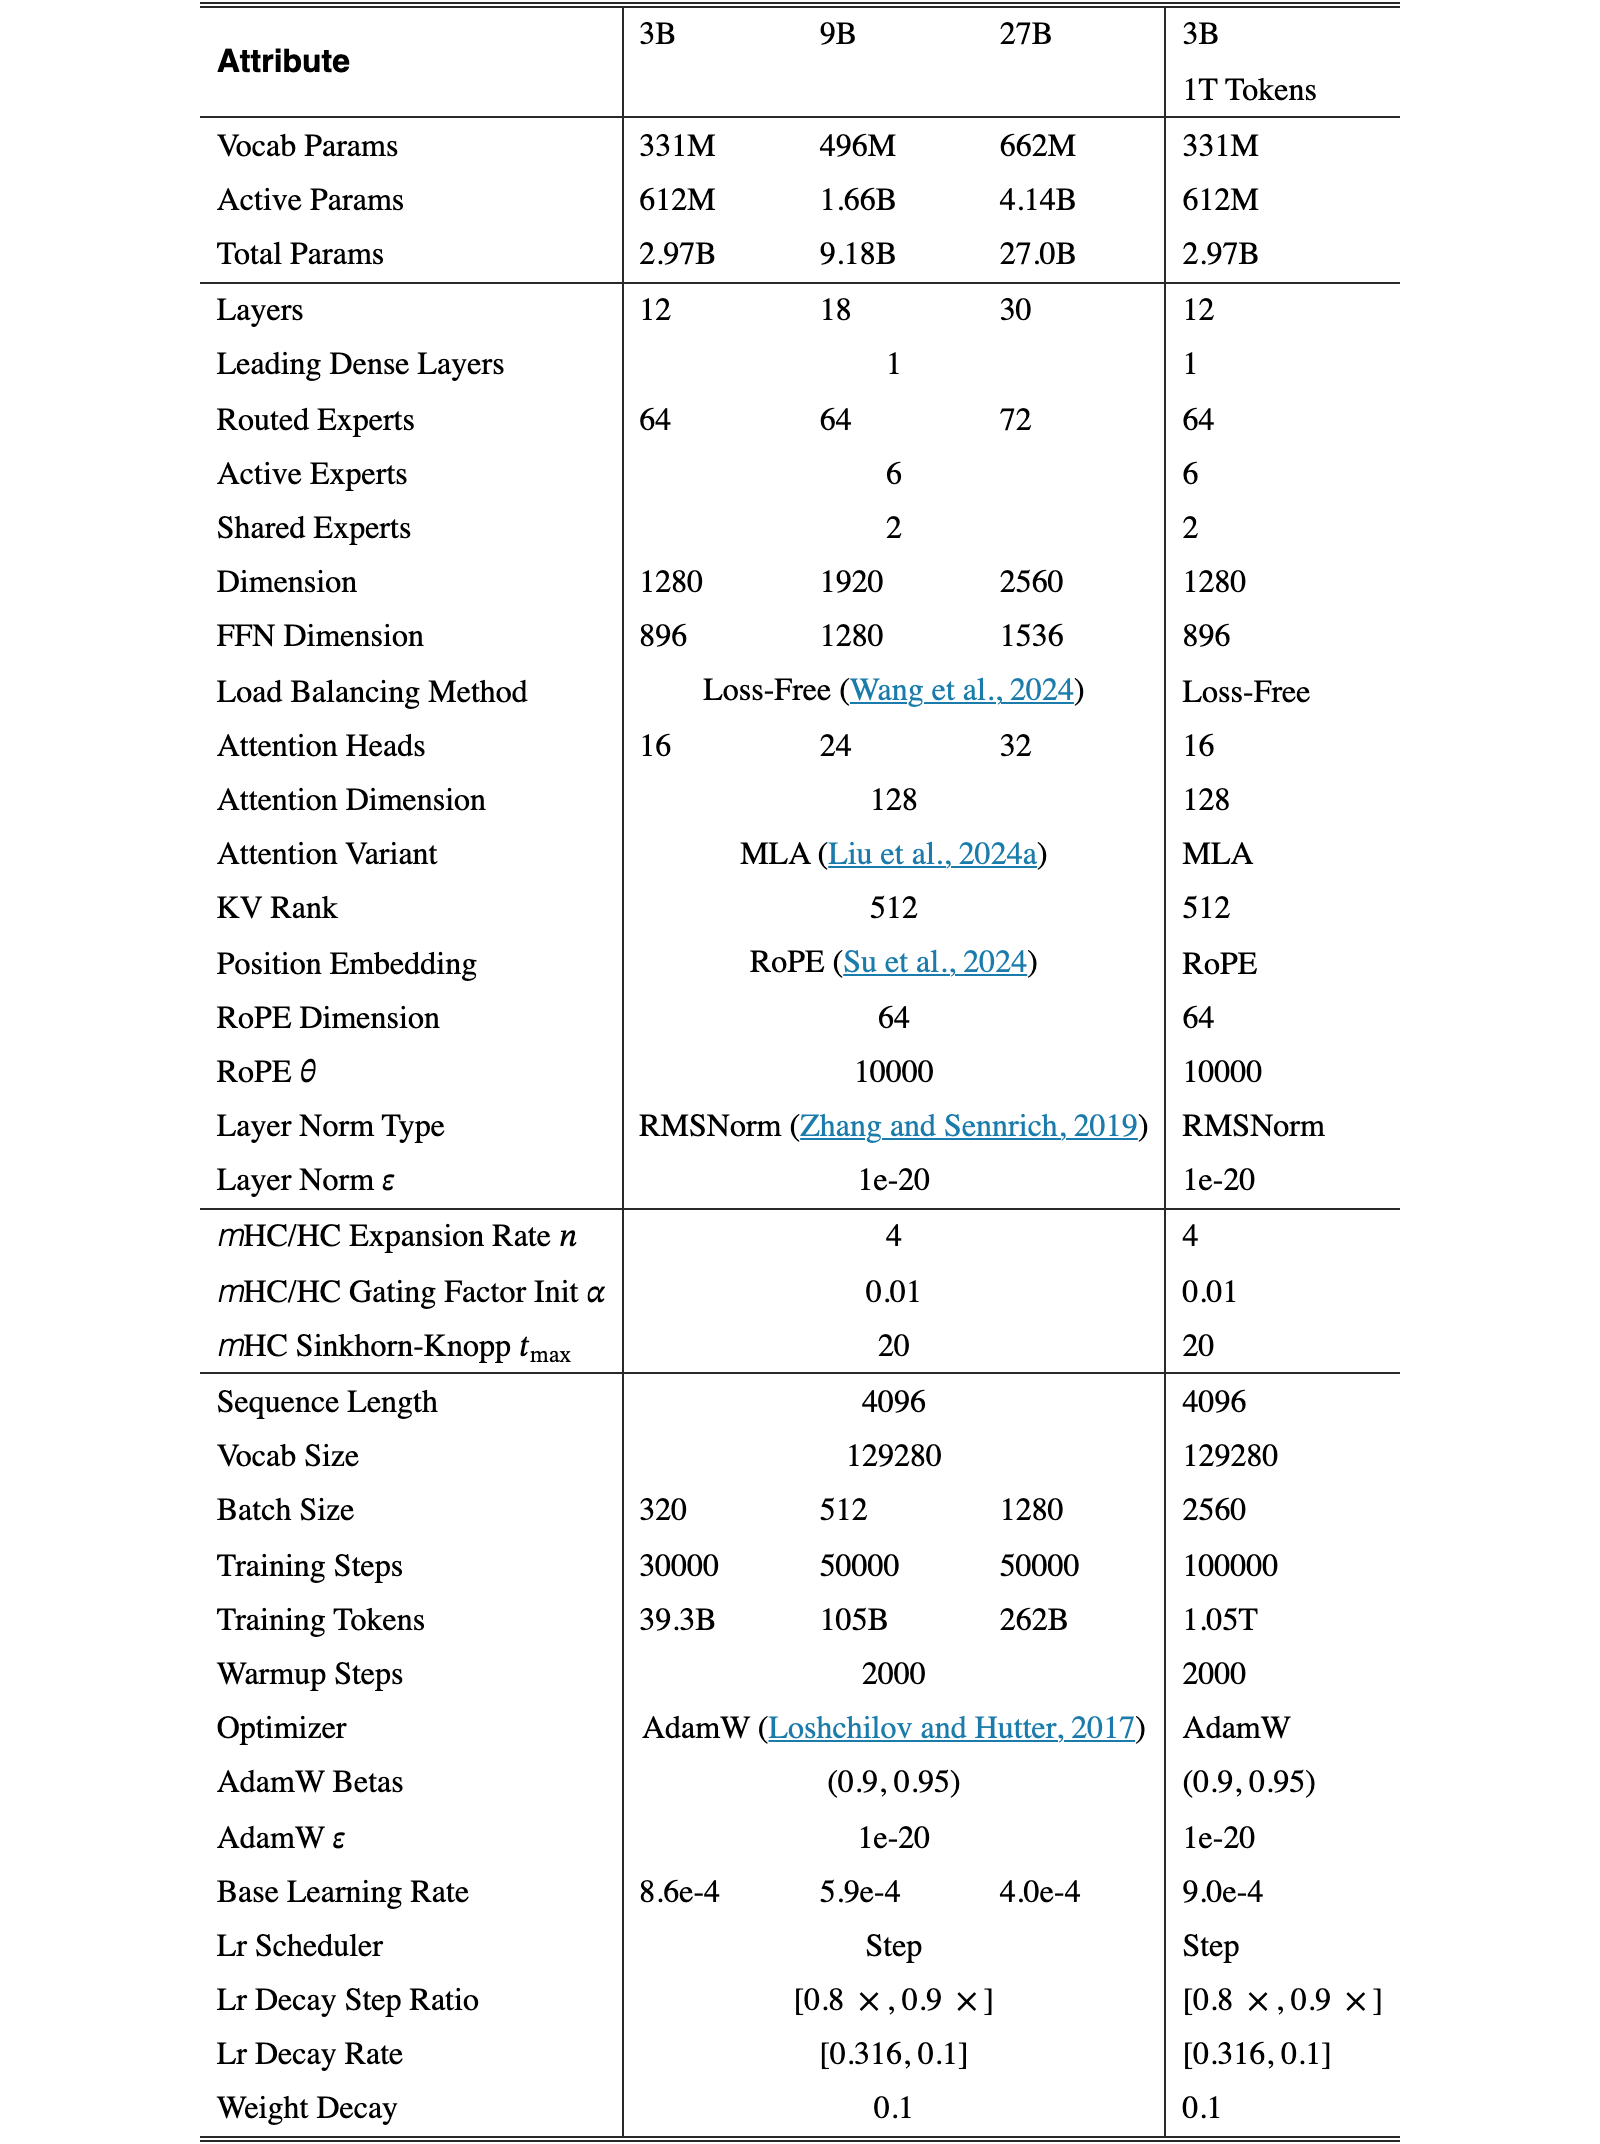
We validate the proposed method via language model pre-training, conducting a comparative analysis between the baseline, HC, and our proposed mHC. Utilizing MoE architectures inspired by DeepSeek-V3 (Liu et al., 2024b), we train four distinct model variants to cover different evaluation regimes. Specifically, the expansion rate for both HC and mHC is set to 4. Our primary focus is a 27B model trained with a dataset size proportional to its parameters, which serves as the subject for our system-level main results. Expanding on this, we analyze the compute scaling behavior by incorporating smaller 3B and 9B models trained with proportional data, which allows us to observe performance trends across varying compute. Additionally, to specifically investigate the token scaling behavior, we train a separate 3B model on a fixed corpus of 1 trillion tokens. Detailed model configurations and training hyper-parameters are provided in Appendix A.1.
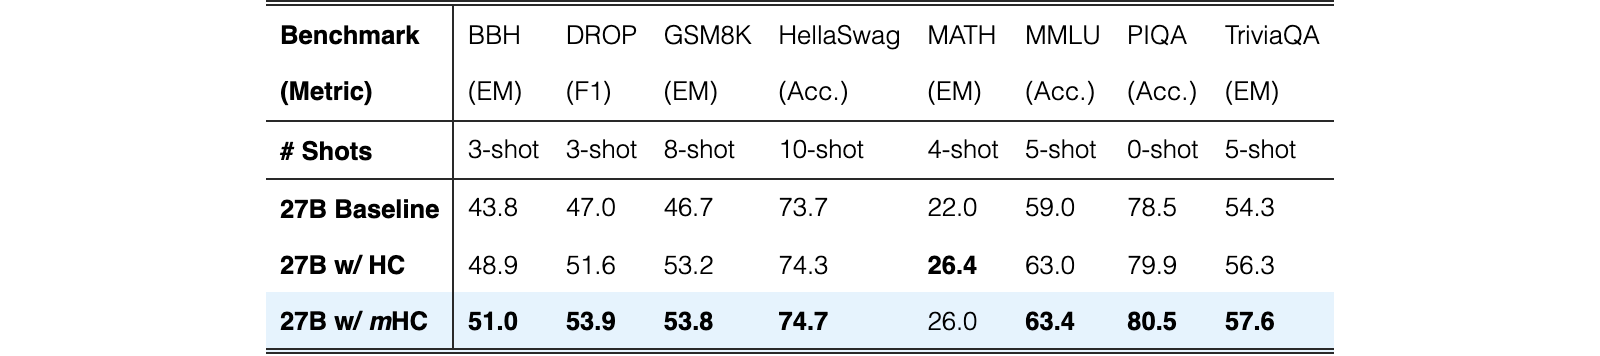
| Benchmark | BBH | DROP | GSM8K | HellaSwag | MATH | MMLU | PIQA | TriviaQA |
| (Metric) | (EM) | (F1) | (EM) | (Acc.) | (EM) | (Acc.) | (Acc.) | (EM) |
| # Shots | 3-shot | 3-shot | 8-shot | 10-shot | 4-shot | 5-shot | 0-shot | 5-shot |
| 27B Baseline | 43.8 | 47.0 | 46.7 | 73.7 | 22.0 | 59.0 | 78.5 | 54.3 |
| 27B w/ HC | 48.9 | 51.6 | 53.2 | 74.3 | 26.4 | 63.0 | 79.9 | 56.3 |
| 27B w/ mHC | 51.0 | 53.9 | 53.8 | 74.7 | 26.0 | 63.4 | 80.5 | 57.6 |
View original table
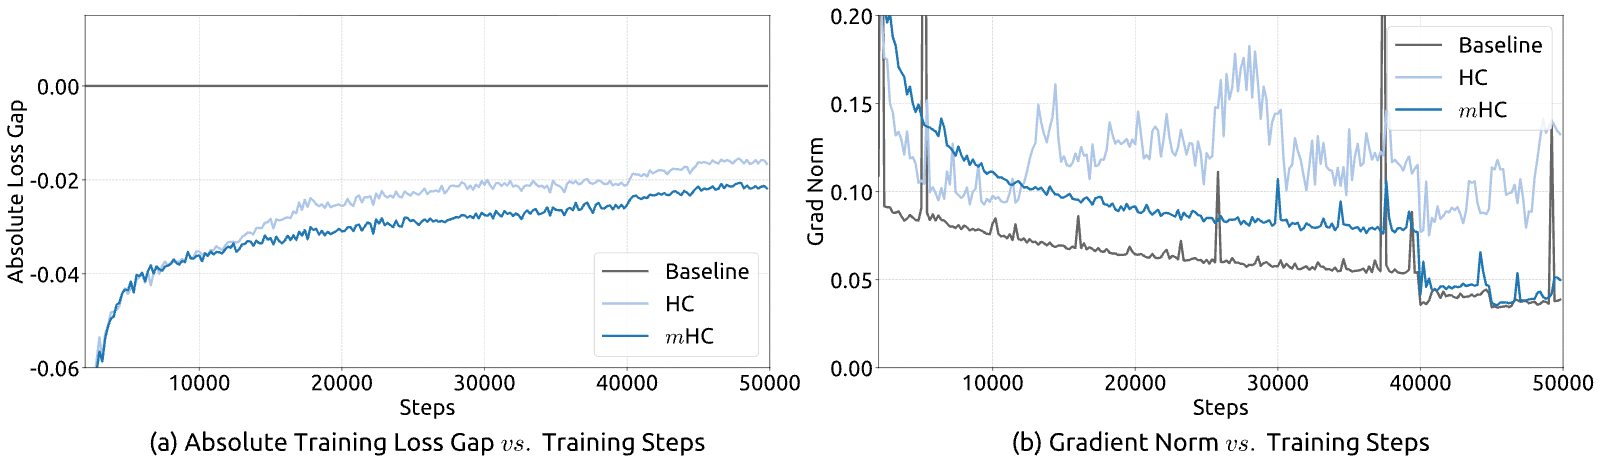
We begin by examining the training stability and convergence of the 27B models. As illustrated in Fig. 5 (a), mHC effectively mitigates the training instability observed in HC, achieving a final loss reduction of 0.021 compared to the baseline. This improved stability is further corroborated by the gradient norm analysis in Fig. 5 (b), where mHC exhibits significantly better behavior than HC, maintaining a stable profile comparable to the baseline.
Tab. 4 presents the downstream performance across a diverse set of benchmarks (Hendrycks et al., 2020; Cobbe et al., 2021; Zellers et al., 2019; Hendrycks et al., 2021; Bisk et al., 2020; Joshi et al., 2017). mHC yields comprehensive improvements, consistently outperforming the baseline and surpassing HC on the majority of tasks. Notably, compared to HC, mHC further enhances the model’s reasoning capabilities, delivering performance gains of 2.1% on BBH (Suzgun et al., 2022) and 2.3% on DROP (Dua et al., 2019).
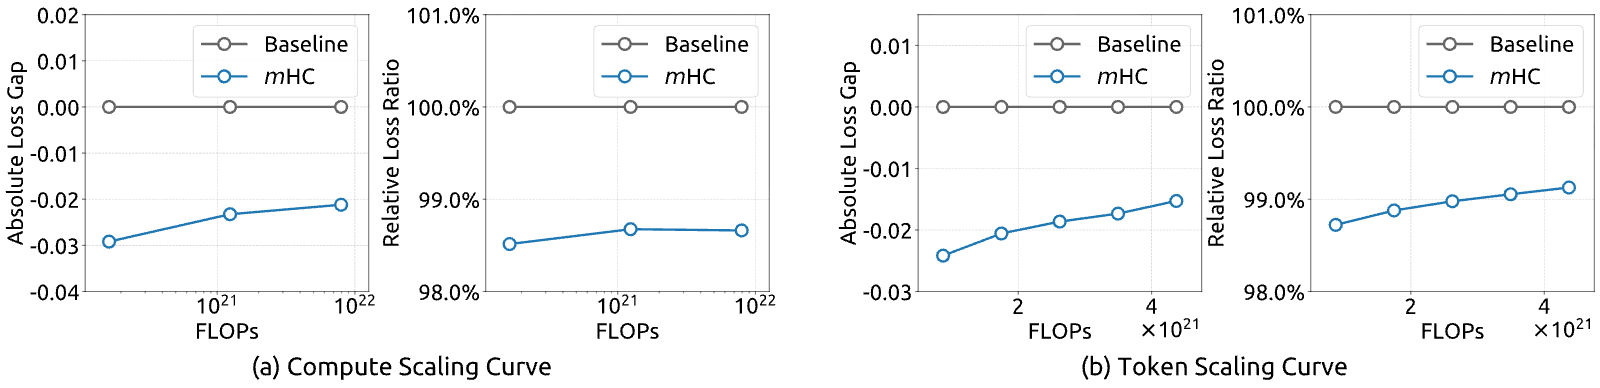
To assess the scalability of our approach, we report the relative loss improvement of mHC against the baseline across different scales. In Fig. 6 (a), we plot the compute scaling curve spanning 3B, 9B, and 27B parameters. The trajectory indicates that the performance advantage is robustly maintained even at higher computational budgets, showing only marginal attenuation. Furthermore, we examine the within-run dynamics in Fig. 6 (b), which presents the token scaling curve for the 3B model. Collectively, these findings validate the effectiveness of mHC in large-scale scenarios. This conclusion is further corroborated by our in-house large-scale training experiments.
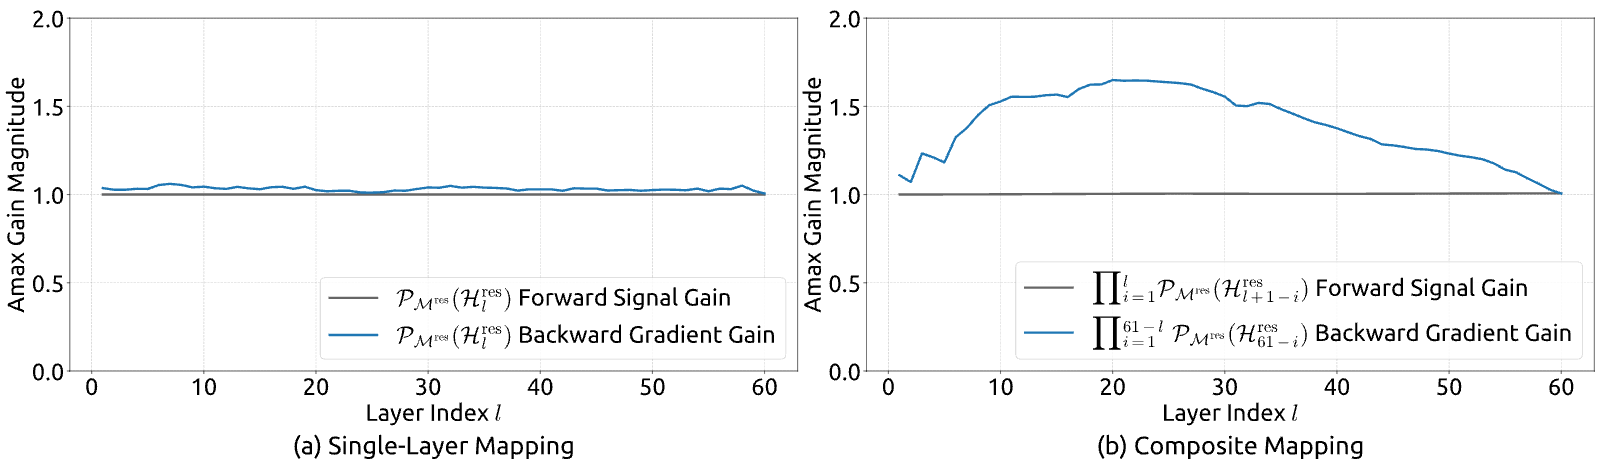
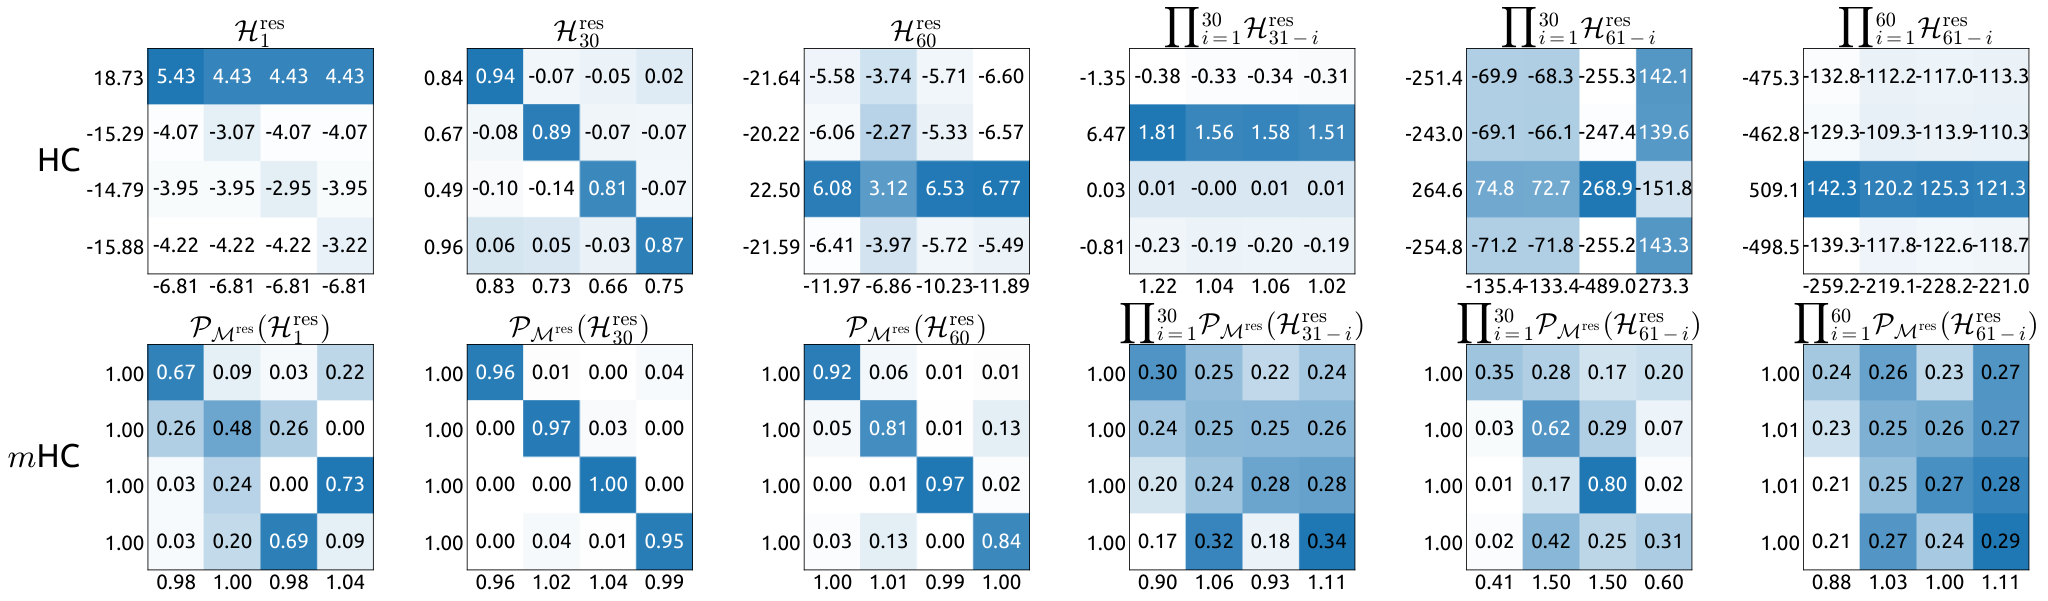
Similar to Fig. 3, Fig. 7 illustrates the propagation stability of mHC. Ideally, the single-layer mapping satisfies the doubly stochastic constraint, implying that both the forward signal gain and the backward gradient gain should equal to 1. However, practice implementations utilizing the Sinkhorn-Knopp algorithm must limit the number of iterations to achieve computational efficiency. In our settings, we use 20 iterations to obtain an approximate solution. Consequently, as shown in Fig. 7(a), the backward gradient gain deviates slightly from 1. In the composite case shown in Fig. 7(b), the deviation increases but remains bounded, reaching a maximum value of approximately 1.6. Notably, compared to the maximum gain magnitude of nearly 3000 in HC, mHC significantly reduces it by three orders of magnitude. These results demonstrate that mHC significantly enhances propagation stability compared to HC, ensuring stable forward signal and backward gradient flows. Additionally, Fig. 8 displays representative mappings. We observe that for HC, when the maximum gain is large, other values also tend to be significant, which indicates general instability across all propagation paths. In contrast, mHC consistently yields stable results.
In this paper, we identify that while expanding the width of residual stream and diversifying connections yields performance gains as proposed in Hyper-Connections (HC), the unconstrained nature of these connections leads to signal divergence. This disruption compromises the conservation of signal energy across layers, inducing training instability and hindering the scalability of deep networks. To address these challenges, we introduce Manifold-Constrained Hyper-Connections (mHC), a generalized framework that projects the residual connection space onto a specific manifold. By employing the Sinkhorn-Knopp algorithm to enforce a doubly stochastic constraint on residual mappings, mHC transforms signal propagation into a convex combination of features. Empirical results confirm that mHC effectively restores the identity mapping property, enabling stable large-scale training with superior scalability compared to conventional HC. Crucially, through efficient infrastructure-level optimizations, mHC delivers these improvements with negligible computational overhead.
As a generalized extension of the HC paradigm, mHC opens several promising avenues for future research. Although this work utilizes doubly stochastic matrices to ensure stability, the framework accommodates the exploration of diverse manifold constraints tailored to specific learning objectives. We anticipate that further investigation into distinct geometric constraints could yield novel methods that better optimize the trade-off between plasticity and stability. Furthermore, we hope mHC rejuvenates community interest in macro-architecture design. By deepening the understanding of how topological structures influence optimization and representation learning, mHC will help address current limitations and potentially illuminate new pathways for the evolution of next-generation foundational architectures.
References
- Ainslie et al. (2023) J. Ainslie, J. Lee-Thorp, M. De Jong, Y. Zemlyanskiy, F. Lebrón, and S. Sanghai Gqa: training generalized multi-query transformer models from multi-head checkpoints. arXiv preprint arXiv:2305.13245. Cited by: §2.1.
- Bisk et al. (2020) Y. Bisk, R. Zellers, R. L. Bras, J. Gao, and Y. Choi PIQA: reasoning about physical commonsense in natural language. In The Thirty-Fourth AAAI Conference on Artificial Intelligence, AAAI 2020, The Thirty-Second Innovative Applications of Artificial Intelligence Conference, IAAI 2020, The Tenth AAAI Symposium on Educational Advances in Artificial Intelligence, EAAI 2020, New York, NY, USA, February 7-12, 2020, pp. 7432–7439. External Links: Link, Document Cited by: §5.2.SourceSource
- Brown et al. (2020) T. Brown, B. Mann, N. Ryder, M. Subbiah, J. D. Kaplan, P. Dhariwal, A. Neelakantan, P. Shyam, G. Sastry, A. Askell, et al. Language models are few-shot learners. Advances in neural information processing systems 33, pp. 1877–1901. Cited by: §1.
- Chai et al. (2020) Y. Chai, S. Jin, and X. Hou Highway transformer: self-gating enhanced self-attentive networks. In Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics, D. Jurafsky, J. Chai, N. Schluter, and J. Tetreault (Eds.), Online, pp. 6887–6900. External Links: Link, Document Cited by: §2.2.SourceSource
- Chollet (2017) F. Chollet Xception: deep learning with depthwise separable convolutions. In Proceedings of the IEEE conference on computer vision and pattern recognition, pp. 1251–1258. Cited by: §2.1.
- Cobbe et al. (2021) K. Cobbe, V. Kosaraju, M. Bavarian, M. Chen, H. Jun, L. Kaiser, M. Plappert, J. Tworek, J. Hilton, R. Nakano, et al. Training verifiers to solve math word problems. arXiv preprint arXiv:2110.14168. Cited by: §5.2.
- Dao et al. (2022) T. Dao, D. Y. Fu, S. Ermon, A. Rudra, and C. Ré FlashAttention: fast and memory-efficient exact attention with IO-awareness. In Advances in Neural Information Processing Systems (NeurIPS), Cited by: §3.2.
- Dua et al. (2019) D. Dua, Y. Wang, P. Dasigi, G. Stanovsky, S. Singh, and M. Gardner DROP: A reading comprehension benchmark requiring discrete reasoning over paragraphs. In Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, NAACL-HLT 2019, Minneapolis, MN, USA, June 2-7, 2019, Volume 1 (Long and Short Papers), J. Burstein, C. Doran, and T. Solorio (Eds.), pp. 2368–2378. External Links: Link, Document Cited by: §5.2.SourceSource
- Fang et al. (2023) Y. Fang, Y. CAI, J. Chen, J. Zhao, G. Tian, and G. Li Cross-layer retrospective retrieving via layer attention. In The Eleventh International Conference on Learning Representations, External Links: Link Cited by: §2.2.Source
- Fedus et al. (2022) W. Fedus, B. Zoph, and N. Shazeer Switch transformers: scaling to trillion parameter models with simple and efficient sparsity. Journal of Machine Learning Research 23 (120), pp. 1–39. Cited by: §2.1.
- He et al. (2016a) K. He, X. Zhang, S. Ren, and J. Sun Deep residual learning for image recognition. In Proceedings of the IEEE conference on computer vision and pattern recognition, pp. 770–778. Cited by: §1, §2.2.
- He et al. (2016b) K. He, X. Zhang, S. Ren, and J. Sun Identity mappings in deep residual networks. In European conference on computer vision, pp. 630–645. Cited by: §1, §4.1.
- Heddes et al. (2025) M. Heddes, A. Javanmard, K. Axiotis, G. Fu, M. Bateni, and V. Mirrokni DeepCrossAttention: supercharging transformer residual connections. In Forty-second International Conference on Machine Learning, External Links: Link Cited by: §2.2.Source
- Hendrycks et al. (2020) D. Hendrycks, C. Burns, S. Basart, A. Zou, M. Mazeika, D. Song, and J. Steinhardt Measuring massive multitask language understanding. arXiv preprint arXiv:2009.03300. Cited by: §5.2.
- Hendrycks et al. (2021) D. Hendrycks, C. Burns, S. Kadavath, A. Arora, S. Basart, E. Tang, D. Song, and J. Steinhardt Measuring mathematical problem solving with the math dataset. arXiv preprint arXiv:2103.03874. Cited by: §5.2.
- Hoffmann et al. (2022) J. Hoffmann, S. Borgeaud, A. Mensch, E. Buchatskaya, T. Cai, E. Rutherford, D. de Las Casas, L. A. Hendricks, J. Welbl, A. Clark, T. Hennigan, E. Noland, K. Millican, G. van den Driessche, B. Damoc, A. Guy, S. Osindero, K. Simonyan, E. Elsen, O. Vinyals, J. Rae, and L. Sifre An empirical analysis of compute-optimal large language model training. In Advances in Neural Information Processing Systems, S. Koyejo, S. Mohamed, A. Agarwal, D. Belgrave, K. Cho, and A. Oh (Eds.), Vol. 35, pp. 30016–30030. External Links: Link Cited by: §3.Source
- Huang et al. (2017) G. Huang, Z. Liu, L. Van Der Maaten, and K. Q. Weinberger Densely connected convolutional networks. In Proceedings of the IEEE conference on computer vision and pattern recognition, pp. 4700–4708. Cited by: §2.2.
- Joshi et al. (2017) M. Joshi, E. Choi, D. Weld, and L. Zettlemoyer TriviaQA: a large scale distantly supervised challenge dataset for reading comprehension. In Proceedings of the 55th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), R. Barzilay and M. Kan (Eds.), Vancouver, Canada, pp. 1601–1611. External Links: Link, Document Cited by: §5.2.SourceSource
- Larsson et al. (2016) G. Larsson, M. Maire, and G. Shakhnarovich Fractalnet: ultra-deep neural networks without residuals. arXiv preprint arXiv:1605.07648. Cited by: §2.2.
- Lepikhin et al. (2020) D. Lepikhin, H. Lee, Y. Xu, D. Chen, O. Firat, Y. Huang, M. Krikun, N. Shazeer, and Z. Chen Gshard: scaling giant models with conditional computation and automatic sharding. arXiv preprint arXiv:2006.16668. Cited by: §2.1.
- Liu et al. (2024a) A. Liu, B. Feng, B. Wang, B. Wang, B. Liu, C. Zhao, C. Dengr, C. Ruan, D. Dai, D. Guo, et al. Deepseek-v2: a strong, economical, and efficient mixture-of-experts language model. arXiv preprint arXiv:2405.04434. Cited by: Table 5, §2.1.
- Liu et al. (2024b) A. Liu, B. Feng, B. Xue, B. Wang, B. Wu, C. Lu, C. Zhao, C. Deng, C. Zhang, C. Ruan, et al. Deepseek-v3 technical report. arXiv preprint arXiv:2412.19437. Cited by: Table 5, Table 5, §1, §1, §4.3.3, §5.1.
- Loshchilov and Hutter (2017) I. Loshchilov and F. Hutter Decoupled weight decay regularization. arXiv preprint arXiv:1711.05101. Cited by: Table 5.
- Mak and Flanigan (2025) B. Mak and J. Flanigan Residual matrix transformers: scaling the size of the residual stream. arXiv preprint arXiv:2506.22696. Cited by: §2.2.
- Menghani et al. (2025) G. Menghani, R. Kumar, and S. Kumar LAurel: learned augmented residual layer. In Forty-second International Conference on Machine Learning, External Links: Link Cited by: §2.2.Source
- Pagliardini et al. (2024) M. Pagliardini, A. Mohtashami, F. Fleuret, and M. Jaggi DenseFormer: enhancing information flow in transformers via depth weighted averaging. In The Thirty-eighth Annual Conference on Neural Information Processing Systems, External Links: Link Cited by: §2.2.Source
- Qi et al. (2024) P. Qi, X. Wan, G. Huang, and M. Lin Zero bubble (almost) pipeline parallelism. In The Twelfth International Conference on Learning Representations, External Links: Link Cited by: §3.2.Source
- Shazeer et al. (2017) N. Shazeer, A. Mirhoseini, K. Maziarz, A. Davis, Q. Le, G. Hinton, and J. Dean Outrageously large neural networks: the sparsely-gated mixture-of-experts layer. arXiv preprint arXiv:1701.06538. Cited by: §2.1.
- Shazeer (2019) N. Shazeer Fast transformer decoding: one write-head is all you need. arXiv preprint arXiv:1911.02150. Cited by: §2.1.
- Sinkhorn and Knopp (1967) R. Sinkhorn and P. Knopp Concerning nonnegative matrices and doubly stochastic matrices. Pacific Journal of Mathematics 21 (2), pp. 343–348. Cited by: §1.
- Srivastava et al. (2015) R. K. Srivastava, K. Greff, and J. Schmidhuber Training very deep networks. In Advances in Neural Information Processing Systems, C. Cortes, N. Lawrence, D. Lee, M. Sugiyama, and R. Garnett (Eds.), Vol. 28, pp. . External Links: Link Cited by: §2.2.Source
- Su et al. (2024) J. Su, M. Ahmed, Y. Lu, S. Pan, W. Bo, and Y. Liu Roformer: enhanced transformer with rotary position embedding. Neurocomputing 568, pp. 127063. Cited by: Table 5.
- Suzgun et al. (2022) M. Suzgun, N. Scales, N. Schärli, S. Gehrmann, Y. Tay, H. W. Chung, A. Chowdhery, Q. V. Le, E. H. Chi, D. Zhou, et al. Challenging big-bench tasks and whether chain-of-thought can solve them. arXiv preprint arXiv:2210.09261. Cited by: §5.2.
- Touvron et al. (2023) H. Touvron, T. Lavril, G. Izacard, X. Martinet, M. Lachaux, T. Lacroix, B. Rozière, N. Goyal, E. Hambro, F. Azhar, et al. Llama: open and efficient foundation language models. arXiv preprint arXiv:2302.13971. Cited by: §1.
- Vaswani et al. (2017) A. Vaswani, N. Shazeer, N. Parmar, J. Uszkoreit, L. Jones, A. N. Gomez, Ł. Kaiser, and I. Polosukhin Attention is all you need. Advances in neural information processing systems 30. Cited by: §1, §2.1, §3.2.
- Wang et al. (2024) L. Wang, H. Gao, C. Zhao, X. Sun, and D. Dai Auxiliary-loss-free load balancing strategy for mixture-of-experts. arXiv preprint arXiv:2408.15664. Cited by: Table 5.
- Wang et al. (2025) L. Wang, Y. Cheng, Y. Shi, Z. Tang, Z. Mo, W. Xie, L. Ma, Y. Xia, J. Xue, F. Yang, et al. TileLang: a composable tiled programming model for ai systems. arXiv preprint arXiv:2504.17577. Cited by: §1, §4.3.1.
- Xiao et al. (2025) D. Xiao, Q. Meng, S. Li, and X. Yuan Muddformer: breaking residual bottlenecks in transformers via multiway dynamic dense connections. arXiv preprint arXiv:2502.12170. Cited by: §2.2.
- Xie et al. (2017) S. Xie, R. Girshick, P. Dollár, Z. Tu, and K. He Aggregated residual transformations for deep neural networks. In Proceedings of the IEEE conference on computer vision and pattern recognition, pp. 1492–1500. Cited by: §2.1.
- Xie et al. (2023) S. Xie, H. Zhang, J. Guo, X. Tan, J. Bian, H. H. Awadalla, A. Menezes, T. Qin, and R. Yan ResiDual: transformer with dual residual connections. External Links: 2304.14802, Link Cited by: §2.2.Source
- Yu et al. (2018) F. Yu, D. Wang, E. Shelhamer, and T. Darrell Deep layer aggregation. In Proceedings of the IEEE conference on computer vision and pattern recognition, pp. 2403–2412. Cited by: §2.2.
- Zellers et al. (2019) R. Zellers, A. Holtzman, Y. Bisk, A. Farhadi, and Y. Choi HellaSwag: can a machine really finish your sentence?. In Proceedings of the 57th Conference of the Association for Computational Linguistics, ACL 2019, Florence, Italy, July 28- August 2, 2019, Volume 1: Long Papers, A. Korhonen, D. R. Traum, and L. Màrquez (Eds.), pp. 4791–4800. External Links: Link, Document Cited by: §5.2.SourceSource
- Zhang and Sennrich (2019) B. Zhang and R. Sennrich Root mean square layer normalization. Advances in neural information processing systems 32. Cited by: Table 5, §3.
- Zhu et al. (2024) D. Zhu, H. Huang, Z. Huang, Y. Zeng, Y. Mao, B. Wu, Q. Min, and X. Zhou Hyper-connections. arXiv preprint arXiv:2409.19606. Cited by: §1, §2.2.
| Attribute | 3B | 9B | 27B | 3B |
| 1T Tokens | ||||
| Vocab Params | 331M | 496M | 662M | 331M |
| Active Params | 612M | 1.66B | 4.14B | 612M |
| Total Params | 2.97B | 9.18B | 27.0B | 2.97B |
| Layers | 12 | 18 | 30 | 12 |
| Leading Dense Layers | 1 | 1 | ||
| Routed Experts | 64 | 64 | 72 | 64 |
| Active Experts | 6 | 6 | ||
| Shared Experts | 2 | 2 | ||
| Dimension | 1280 | 1920 | 2560 | 1280 |
| FFN Dimension | 896 | 1280 | 1536 | 896 |
| Load Balancing Method | Loss-Free (Wang et al., 2024) | Loss-Free | ||
| Attention Heads | 16 | 24 | 32 | 16 |
| Attention Dimension | 128 | 128 | ||
| Attention Variant | MLA (Liu et al., 2024a) | MLA | ||
| KV Rank | 512 | 512 | ||
| Position Embedding | RoPE (Su et al., 2024) | RoPE | ||
| RoPE Dimension | 64 | 64 | ||
| RoPE | 10000 | 10000 | ||
| Layer Norm Type | RMSNorm (Zhang and Sennrich, 2019) | RMSNorm | ||
| Layer Norm | 1e-20 | 1e-20 | ||
| mHC/HC Expansion Rate | 4 | 4 | ||
| mHC/HC Gating Factor Init | 0.01 | 0.01 | ||
| mHC Sinkhorn-Knopp | 20 | 20 | ||
| Sequence Length | 4096 | 4096 | ||
| Vocab Size | 129280 | 129280 | ||
| Batch Size | 320 | 512 | 1280 | 2560 |
| Training Steps | 30000 | 50000 | 50000 | 100000 |
| Training Tokens | 39.3B | 105B | 262B | 1.05T |
| Warmup Steps | 2000 | 2000 | ||
| Optimizer | AdamW (Loshchilov and Hutter, 2017) | AdamW | ||
| AdamW Betas | (0.9, 0.95) | (0.9, 0.95) | ||
| AdamW | 1e-20 | 1e-20 | ||
| Base Learning Rate | 8.6e-4 | 5.9e-4 | 4.0e-4 | 9.0e-4 |
| Lr Scheduler | Step | Step | ||
| Lr Decay Step Ratio | [0.8 , 0.9 ] | [0.8 , 0.9 ] | ||
| Lr Decay Rate | [0.316, 0.1] | [0.316, 0.1] | ||
| Weight Decay | 0.1 | 0.1 | ||
View original table