HERMES: KV Cache as Hierarchical Memory for Efficient Streaming Video Understanding
arXiv:2601.14724v4 · This workspace stays on this version. Check arXiv for newer versions
Some source details need review 3 to check
Original formulas, table values and figures are preserved. Comparison can miss differences; use the original PDF to check details.
Reading view checked: 94 math expressions, 0 rendering failures; 18 of 18 images available.
Compared 116 of 116 source passages against 29 of 35 PDF pages.
The HTML source contains failed formatting commands; these were omitted from the reading view. The original sources are retained. (4)
- This long paper was only partially compared; the original sources remain available.
- An unsupported comparison claim was rejected; source verification is incomplete.
PDF page 7 includes the rows “Qwen3-VL-8B [4]” and “Qwen3-VL-4B [4]”; HTML S4_T1 ends with “+ HERMES (4K tokens) | 1 fps | 80.08 | 72.37 | 55.42 | 63.90,” so the PDF contradicts the HTML’s omission. Check PDF page 7
18 of 18 figure, table and graphic images captured. Open original PDF
[Correspondence], Homepage Repository
Recent years have witnessed remarkable evolution in the capabilities of Multimodal Large Language Models (MLLMs) in video understanding tasks [12, 23, 4]. Despite the progress, the rapid emergence of real-time applications demands stable long video understanding, low-latency response, and memory-efficient deployment. However, existing MLLMs struggle to simultaneously satisfy these requirements on streaming videos. Notably, TimeChat-Online [50] observes that a large number of streaming video tokens are redundant, motivating compression methods to address these challenges. While numerous compression techniques have been proposed for offline videos [44, 48, 40], most are ill-suited for memory management in streaming scenarios, as streaming inputs are unpredictable in future frames and queries.
To adapt to streaming inputs, recent research introduces specialized memory management techniques, which generally fall into two paradigms: external memory and internal memory. External memory methods store video content as captions or raw vision patches in databases, and perform ad-hoc retrieval and multimodal prefilling at query time [45, 47], suffering from high latency and a lack of end-to-end cohesion. Additionally, many of these methods necessitate costly model-specific training [41, 46, 51]. In contrast, internalizing memory directly into the key-value cache (KV cache) remains underexplored, yet is crucial for low-latency responses and seamless end-to-end reasoning over stored video contexts. Moreover, KV cache naturally acts as a latent, model-intrinsic memory [19] that frequently interacts with the video stream, making it particularly suitable for training-free memory management. ReKV [13] and LiveVLM [31] are representative training-free, cache-based methods for streaming memory management. They store previous video segments in external CPU or disk and need to perform an additional retrieval when a user query arrives, which still rely on external computational resources and leads to significant latency. StreamMem [49] leverages chat template tokens to guide compression but lacks fine-grained KV management and mechanistic interpretability.
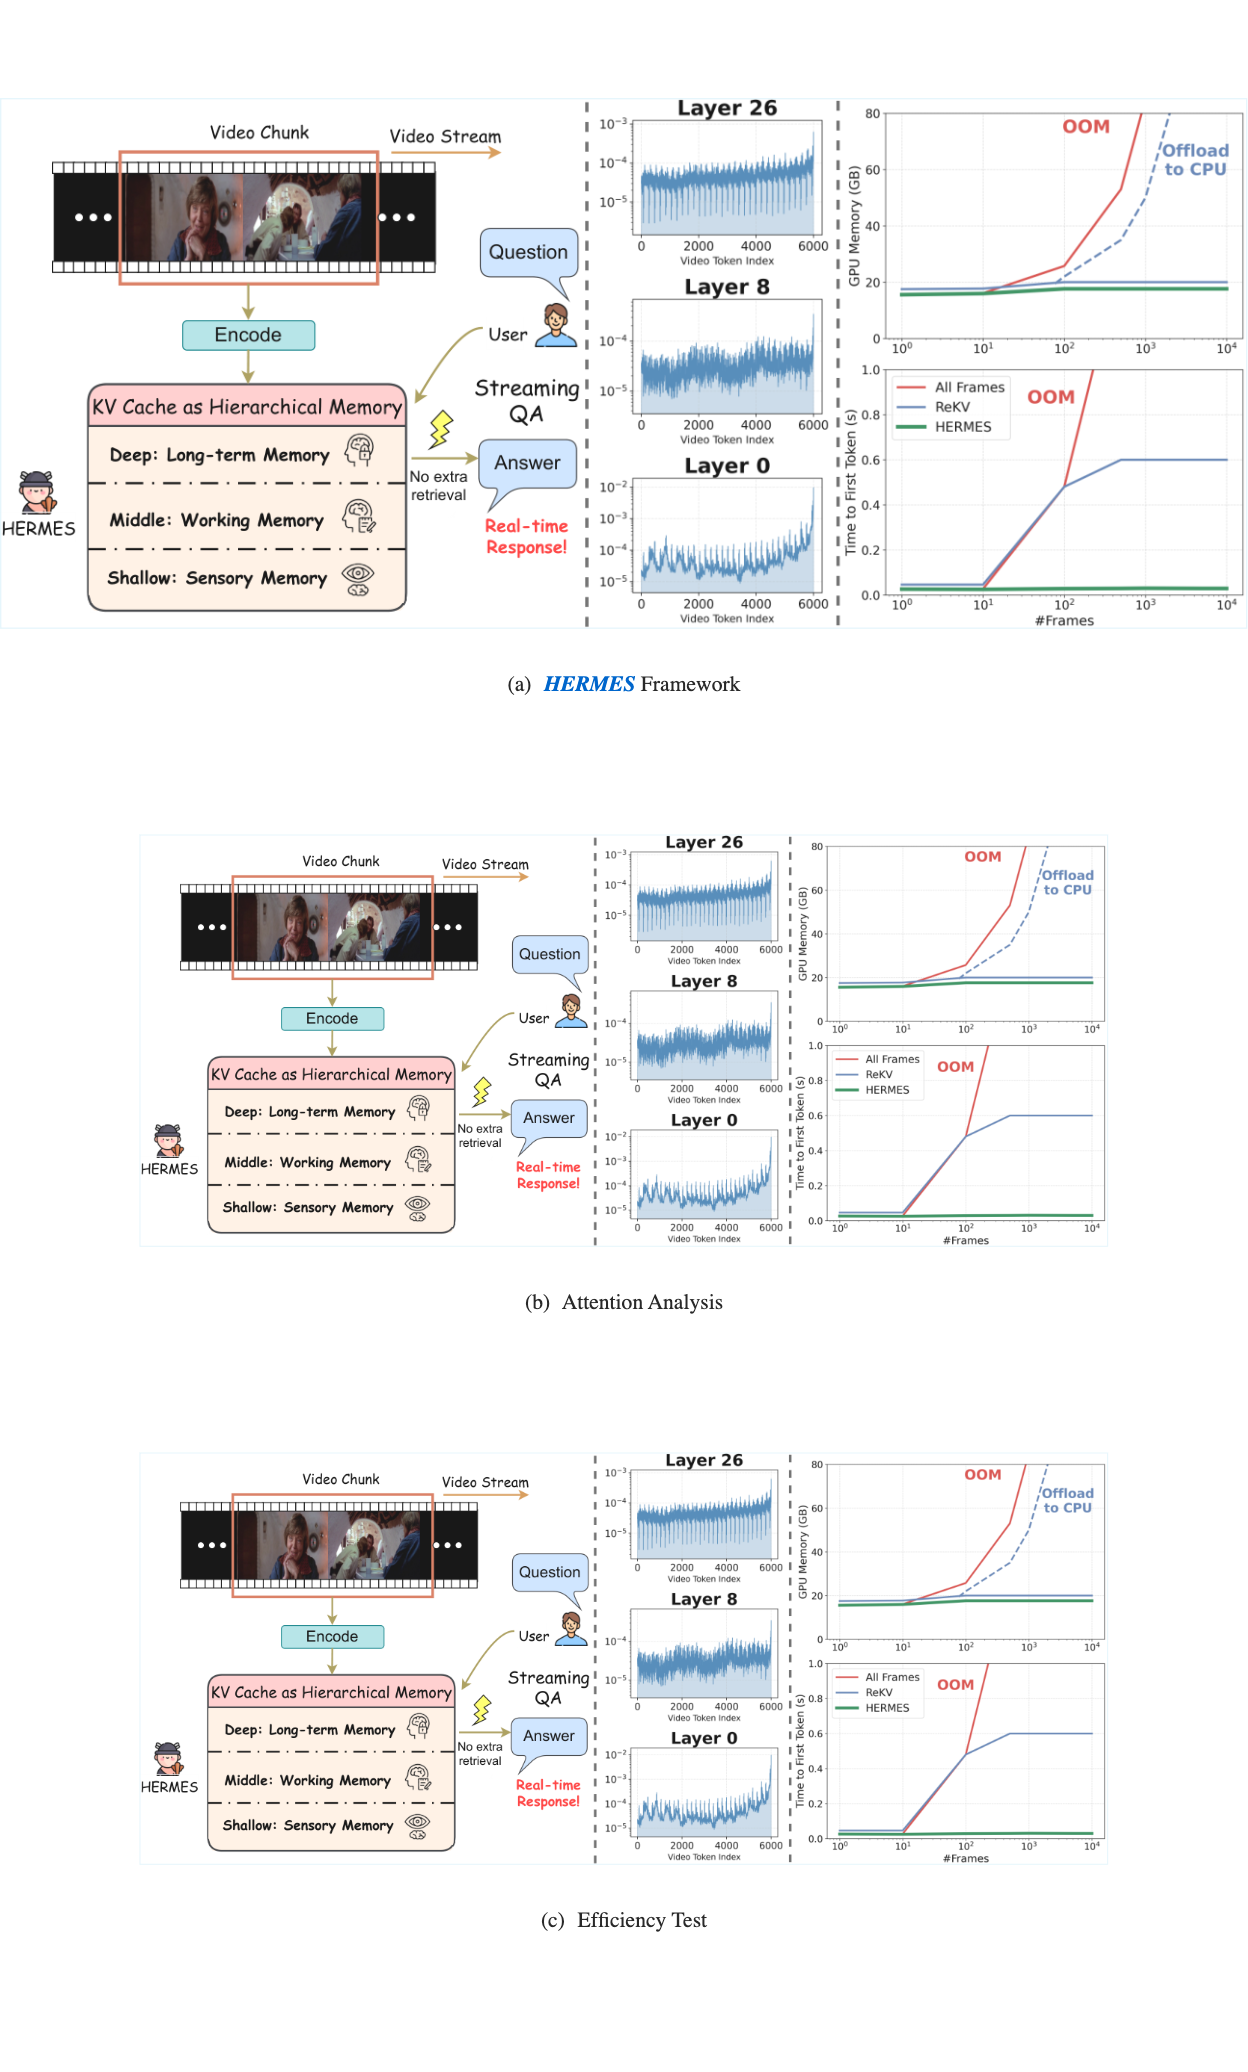
To overcome the aforementioned limitations of existing streaming video methods, we propose HERMES (KV Cache as HiERarchical Memory for Efficient Streaming Video Understanding), a training-free and plug-and-play approach that can be seamlessly integrated into existing MLLMs. Grounded in a mechanistic investigation of layer-wise attention shown in figure 1(b), we conceptualize KV cache as a hierarchical memory framework that stores video information across multiple levels of granularity: shallow layers function as sensory memory, exhibiting a strong recency bias toward newly arriving frames; deep layers act as long-term memory, focusing on frame-level rhythmic anchor tokens; and middle layers serve as transitional working memory that balances recency information with frame-level semantic representations. Our method HERMES comprises three components: hierarchical KV cache management, cross-layer memory smoothing, and position re-indexing. During inference, HERMES reuses the compact KV cache and requires no auxiliary computations or external devices upon the arrival of user queries, thereby guaranteeing real-time responses. Experiments show that HERMES maintains stable and accurate performance with up to 68% fewer video tokens, while maintaining consistently low response latency and a constant GPU memory footprint.
To summarize, our main contributions are as follows:
- 1.
Grounded in a mechanistic analysis on attention visualization, we pioneer the conceptualization of KV cache as a hierarchical video memory framework across multiple granularities.
- 2.
We propose HERMES, a training-free method for streaming video understanding by reusing hierarchically managed KV cache. Despite reducing video tokens by up to 68%, HERMES achieves competitive accuracy, with gains of up to 11.4% on streaming benchmarks.
- 3.
HERMES exhibits outstanding efficiency in streaming scenarios. Compared to the prior training-free SOTA method, it achieves up to a 10 speedup in latency. With a constant, compact GPU memory footprint and no auxiliary computation at query time, HERMES ensures consistently low-latency responses.
Sliding Window is a standard paradigm for streaming video processing by incrementally encoding the continuous video stream chunk by chunk. When KV cache reaches the pre-defined memory budget, token eviction is triggered, and deciding which tokens to keep is crucial for stable understanding. Existing methods [13, 49, 46] rely on coarse-grained eviction strategies such as FIFO uniformly across all layers, overlooking layer-wise attention preferences.
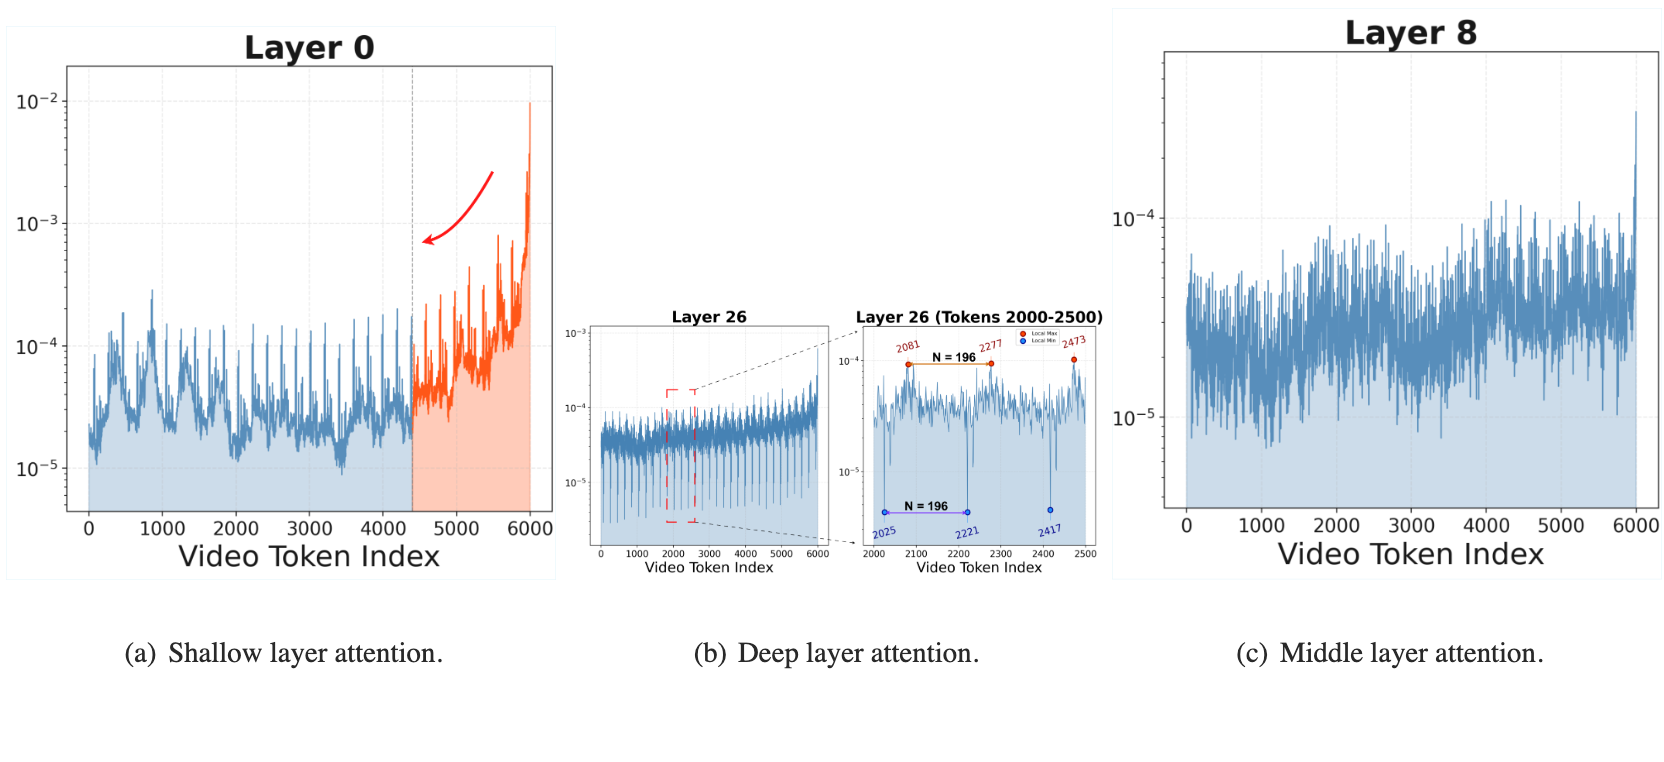
To fill this gap, we conduct a mechanistic investigation of attention preferences in MLLM decoder layers, revealing how layers specialize in storing multiple-granularity video memory. To derive generalized insights, we randomly sample 100 video-question pairs from each of the short (62s - 141s), medium (251s - 1,092s) and long (1,795s - 3,579s) duration subsets of the VideoMME benchmark [16] to cover diverse video durations and user queries. The video samples are uniformly sampled at 0.5 fps and subsequently fed into LLaVA-OV-7B in a streaming chunk-wise manner, with each chunk containing 8 frames. LLaVA-OV-7B consists of 28 decoder layers, and each video frame is uniformly encoded into 196 visual tokens. During the prefilling stage for video tokens, we maintain a constant budget of 6K video tokens per KV cache layer. After each eviction step, the positional indices of tokens per KV cache layer are re-indexing to contiguous [0, ).
Layer-wise attention visualizations over video tokens maintained in a FIFO KV cache in figure 2 reveal three general stages of attention preference, along with more visualization results presented in section 7:
- •
Shallow Layers as Sensory Memory: As shown in figure 2(a), the shallow layers (e.g., layer 0) exhibit an intense recency bias, with attention sharply concentrated on the most recent visual tokens and rapidly decaying over earlier ones. This behavior aligns with the concept of Sensory Memory [2, 37]: shallow layers function as a short-lived buffer for the most recent visual inputs, enabling the model to quickly perceive incoming frames.
- •
Deep Layers as Long-term Memory: In deep layers (e.g., layer 26 in figure 2(b)), recency bias largely disappears. Instead, the attention pattern becomes highly sparse and rhythmic, with local extrema appearing at regular intervals. These extrema are exactly N = 196 tokens apart, matching to the number of tokens encoding a single frame in LLaVA-OV-7B. These local maxima can be regarded as frame-level "anchor tokens", summarizing the visual information of each frame. This pattern reflects Long-term Memory [2, 37]: deep layers store critical frame-level semantic representations for long-horizon understanding.
- •
Middle Layers as Working Memory: Middle layers (e.g., layer 8 in figure 2(c)) exhibit a gradual reduction in recency bias, with attention more evenly distributed across recent and earlier tokens. Simultaneously, the attention begins to transition toward the rhythmic patterns in the deep layers. This behavior corresponds to Working Memory [3, 19]: middle layers integrate recent and earlier visual information, bridging short-term sensory traces with frame-level semantic summaries.
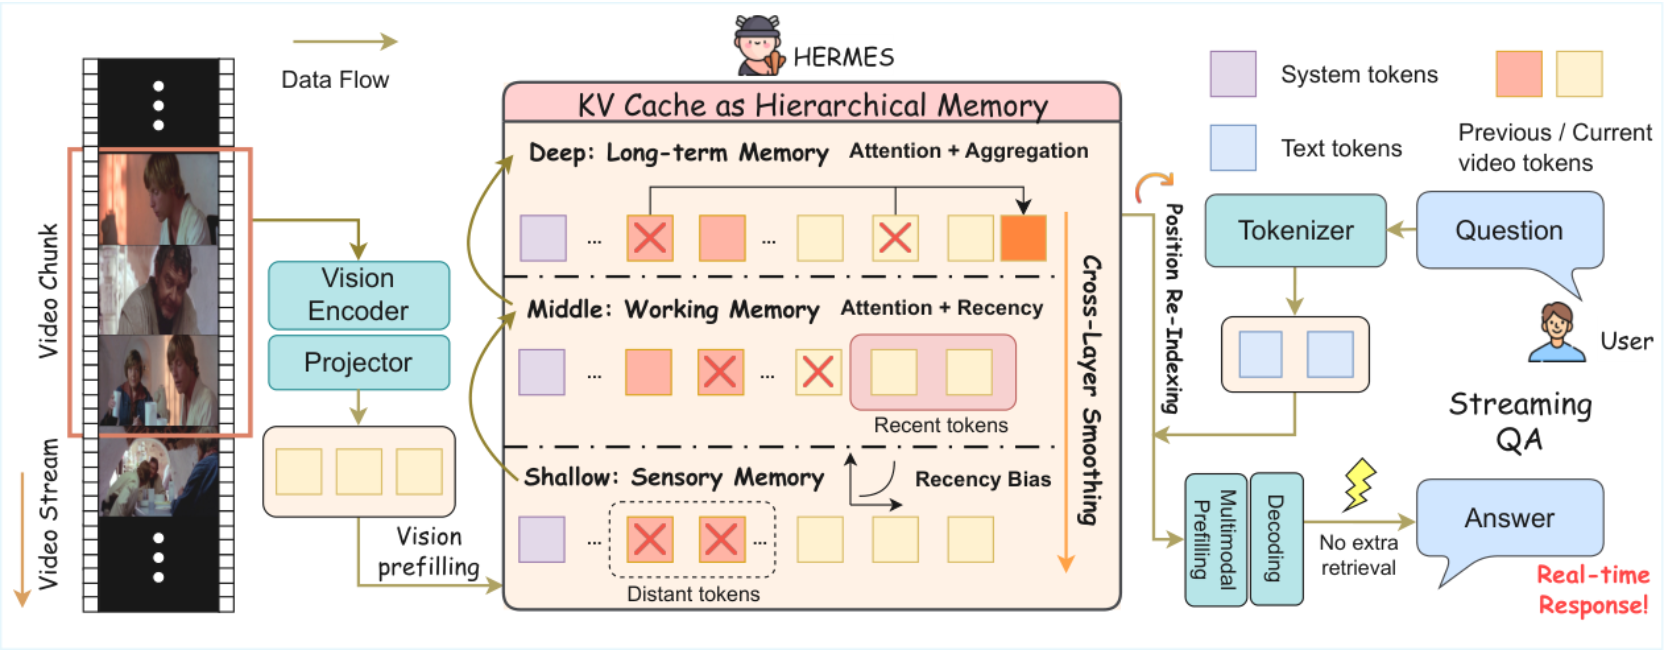
We propose HERMES, a training-free framework that can be seamlessly integrated with MLLMs. As shown in figure 3, HERMES has three components: hierarchical KV cache management, cross-layer memory smoothing, and position re-indexing.
Motivated by the layer-wise attention patterns identified in section 2, we design a hierarchical KV cache strategy. For each video token with KV cache index at layer , where denotes its physical position in KV cache, we compute an importance score to decide its retention:
- •
Shallow Layers: They act as sensory memory with strong recency bias. Inspired by Ebbinghaus’ memory decay theory [14], we model token importance using an exponential forgetting curve based on temporal distance:
(1)where is the total number of video tokens in the cache, is the forgetting rate, denotes the normalization factor.
- •
Deep Layers: Deep layers function as frame-level long-term memory with stable anchor tokens. Their attention distributions are sparse, and these anchor tokens consistently receive high attention across frames, making attention magnitude a reliable indicator of long-term importance. We therefore compute token importance directly from attention weights with respect to the user query. To handle unpredictable queries in streaming scenarios, we use a generic guidance prompt (see section 8) as a pseudo query. Token importance is computed as:
(2)where denotes the attention weight of the -th token at the layer .
- •
Middle Layers: Middle layers serve as working memory, transitioning from recency-dominated shallow layers to attention-driven deep layers. We compute importance by interpolating recency and attention with a layer-dependent weight:
(3)where and denote the layer indices, with and . The importance score of token at layer is then computed as
(4)where and denote the normalized attention weight and recency score, respectively, computed as in equations 2 and 1.
Hierarchical KV cache management may introduce cross-layer inconsistency, as tokens at the same cache index can be evicted independently across layers, leading to misaligned visual memory. Since effective LLM memory relies on cross-layer interaction [33, 6, 39, 19], we address this issue with Cross-Layer Memory Smoothing.
Instead of treating video tokens at the same KV cache index as independent across layers, we propagate and smooth importance signals from deeper to shallower layers. Given raw importance scores , the smoothed score is computed as:
is the smoothing hyperparameter that controls the strength of cross-layer smoothing.
We then apply Top-K selection based on to maintain a fixed memory budget per layer:
To preserve long-term information, evicted tokens are aggregated into a summary token per layer, which compactly encodes long-term memory and is retained in the KV cache (see algorithm 1).
Continuous accumulation of streaming inputs causes positional indices to exceed the model’s maximum supported range, severely degrading text generation quality. To stabilize inference, we apply position re-indexing, which remaps positional indices to a contiguous range within the memory budget . We design two strategies:
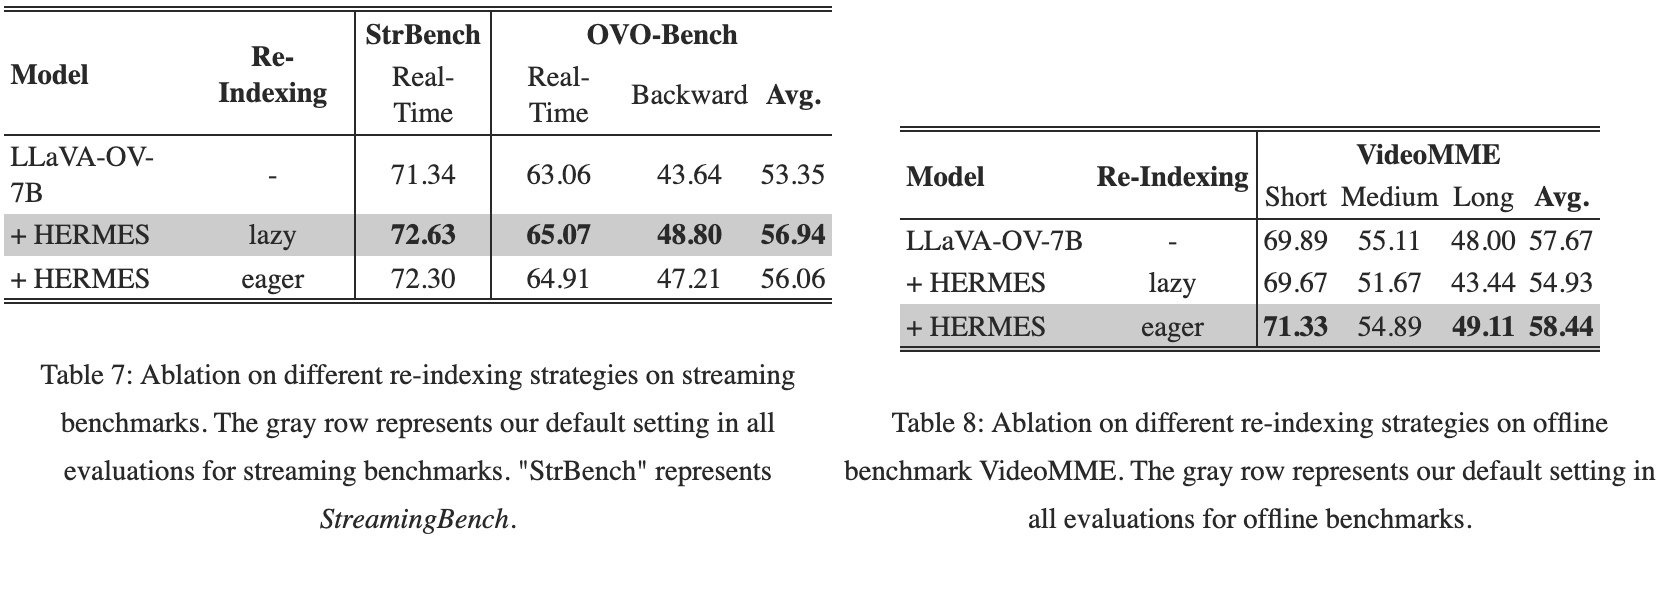
Re-indexing is triggered only when positional indices approach the model limit, resulting in lower computational overhead. By preserving the original positional indices of recent tokens, it prevents positional drift compared to eager re-indexing, making it well suited for streaming video understanding.
Re-indexing is performed at each compression step, maintaining strictly contiguous RoPE indices in KV cache. While this strategy stabilizes long-range visual semantics [21, 22, 46], it leads to higher computational cost due to frequent re-indexing, making it more suitable for offline videos.
The details of re-indexing implementation for 1D RoPE (LLaVA-OV) and 3D M-RoPE (Qwen2.5-VL) are illustrated in section 11.1 and section 11.2, respectively.
We evaluate HERMES on diverse streaming and offline benchmarks. For streaming understanding, we use StreamingBench [27], OVO-Bench [25] and RVS (including RVS-Ego and EVS-Movie) [53]. For offline video evaluation, we adopt one short video dataset MVBench [24], along with two long video datasets, VideoMME [16] and Egoschema [30]. We conduct evaluation on the official dev split of Egoschema and report VideoMME results without subtitles. Our benchmark selection covers both multiple-choice and open-ended questions as QA form. The details of utilized benchmarks are demonstrated in section 10.
To further verify the broad applicability of our method, we select two popular open-source MLLM series, LLaVA-OneVision (LLaVA-OV) [23] and Qwen2.5-VL [5]. Each is tested across two different parameter scales, covering a large range from 0.5B to 32B. For Qwen2.5-VL, we maintain its native dynamic resolution on video input, ensuring a fair comparison with the base model.
For evaluating HERMES across all benchmarks, each video is encoded and processed chunk by chunk, with 16 frames per chunk, and sequentially prefilling the backbone LLM. Then, token compression is triggered once the predefined memory budget is exceeded.
For the layer partition, we follow the mechanistic investigations presented in section 2: 10% shallow, 60% middle and 30% deep layers. A more comprehensive analysis of attention behaviors as supportive evidence can be found in figure 6. The cross-layer memory smoothing hyperparameter proposed in section 3.2 is layer-dependent, with detailed configurations reported in section 9.
| Model | #Frames | StreamingBench | OVO-Bench | ||
| Real-Time | Real-Time | Backward | Avg. | ||
| Human | - | 91.46 | 93.20 | 92.33 | 92.83 |
| Proprietary MLLMs | |||||
| Gemini 1.5 pro [12] | 1 fps | 75.69 | 69.32 | 62.54 | 66.41 |
| GPT-4o [32] | 64 | 73.28 | 64.46 | 60.75 | 62.87 |
| Claude 3.5 Sonnet [1] | 20 | 72.44 | - | - | - |
| Open-source Offline MLLMs | |||||
| Video-LLaMA2-7B [11] | 32 | 49.52 | - | - | - |
| VILA-1.5-8B [26] | 14 | 52.32 | - | - | - |
| Video-CCAM-14B [15] | 96 | 53.96 | - | - | - |
| LongVA-7B [54] | 128 | 59.96 | - | - | - |
| Qwen2-VL-7B [43] | 64 | 69.04 | 60.65 | 48.58 | 54.62 |
| InternVL-V2-8B [10] | 16 | 63.72 | 60.73 | 44.00 | 52.37 |
| LLaVA-NeXT-Video-32B [28] | 64 | 66.96 | - | - | - |
| MiniCPM-V-2.6-8B [18] | 32 | 67.44 | - | - | - |
| Open-source Online MLLMs | |||||
| Flash-VStream-7B [52] | - | 23.23 | 29.86 | 25.35 | 27.61 |
| VideoLLM-online-8B [7] | 2 fps | 35.99 | 20.79 | 17.73 | 19.26 |
| Dispider-7B [35] | 1 fps | 67.63 | 54.55 | 36.06 | 45.31 |
| TimeChat-Online-7B [50] | 1 fps | 75.36 | 61.90 | 41.70 | 51.80 |
| StreamForest-7B [51] | 1 fps | 77.26 | 61.20 | 52.02 | 56.61 |
| Training-free Offline-to-Online Methods | |||||
| LLaVA-OV-7B [23] | 64 | 71.34 | 63.06 | 43.64 | 53.35 |
| + ReKV [13] | 0.5 fps | 69.22 | 57.33 | 44.16 | 50.75 |
| + LiveVLM [31] | 0.5 fps | 72.92 | - | - | - |
| + StreamKV [9] | 0.5 fps | 68.80 | - | - | - |
| + HERMES (6K tokens) | 0.5 fps | 72.63 | 65.07 | 48.80 | 56.94 |
| + HERMES (4K tokens) | 0.5 fps | 73.23 | 66.34 | 50.20 | 58.27 |
| LLaVA-OV-0.5B [23] | 64 | 59.64 | 49.70 | 34.59 | 42.15 |
| + ReKV [13] | 0.5 fps | 57.39 | 43.77 | 33.06 | 38.42 |
| + HERMES (6K tokens) | 0.5 fps | 61.04 | 50.34 | 34.75 | 42.55 |
| + HERMES (4K tokens) | 0.5 fps | 62.04 | 50.72 | 34.80 | 42.76 |
| Qwen2.5-VL-7B [5] | 1 fps | 73.31 | 59.90 | 44.65 | 52.28 |
| + HERMES (6K tokens) | 1 fps | 78.72 | 68.42 | 48.10 | 58.26 |
| + HERMES (4K tokens) | 1 fps | 79.44 | 68.98 | 49.43 | 59.21 |
| Qwen2.5-VL-32B [5] | 1 fps | 74.27 | 64.40 | 50.33 | 57.37 |
| + HERMES (6K tokens) | 1 fps | 80.20 | 71.93 | 57.71 | 64.82 |
| + HERMES (4K tokens) | 1 fps | 80.08 | 72.37 | 55.42 | 63.90 |
View original table
| Model | RVS-Ego | RVS-Movie | ||
| Acc | Score | Acc | Score | |
| LLaVA-OV-7B [23] | 56.2 | 3.7 | 43.0 | 3.3 |
| + ReKV† [13] | 63.7 | 4.0 | 54.4 | 3.6 |
| + ReKV w/o off. [13] | 55.8 | 3.3 | 50.8 | 3.4 |
| + Flash-VStream [52] | 57.0 | 4.0 | 53.1 | 3.3 |
| + InfiniPot-V [22] | 57.9 | 3.5 | 51.4 | 3.5 |
| + StreamMem [49] | 57.6 | 3.8 | 52.7 | 3.4 |
| + StreamingTOM [8] | 58.3 | 3.9 | 53.2 | 3.5 |
| + HERMES (6K tokens) | 60.3 | 4.0 | 54.4 | 3.6 |
| + HERMES (4K tokens) | 58.3 | 3.9 | 54.4 | 3.6 |
| LLaVA-OV-0.5B [23] | 51.8 | 3.7 | 37.2 | 3.2 |
| + ReKV† [13] | 54.7 | 3.9 | 44.6 | 3.4 |
| + HERMES (6K tokens) | 53.0 | 3.8 | 42.5 | 3.4 |
| + HERMES (4K tokens) | 52.7 | 3.8 | 41.7 | 3.4 |
| Metric | Frames | |||
| 16 | 64 | 256 | 512 | |
| Chunk Size: 8 | ||||
| GPU Mem. / GB | 16.54 | 16.66 | 16.66 | 16.66 |
| TTFT / ms | 27.01 | 28.41 | 28.44 | 28.41 |
| TPOT / ms | 24.43 | 23.89 | 24.02 | 23.98 |
| Chunk Size: 16 | ||||
| GPU Mem. / GB | 17.46 | 17.66 | 17.66 | 17.66 |
| TTFT / ms | 27.02 | 28.97 | 28.50 | 28.38 |
| TPOT / ms | 24.50 | 23.59 | 23.56 | 23.63 |
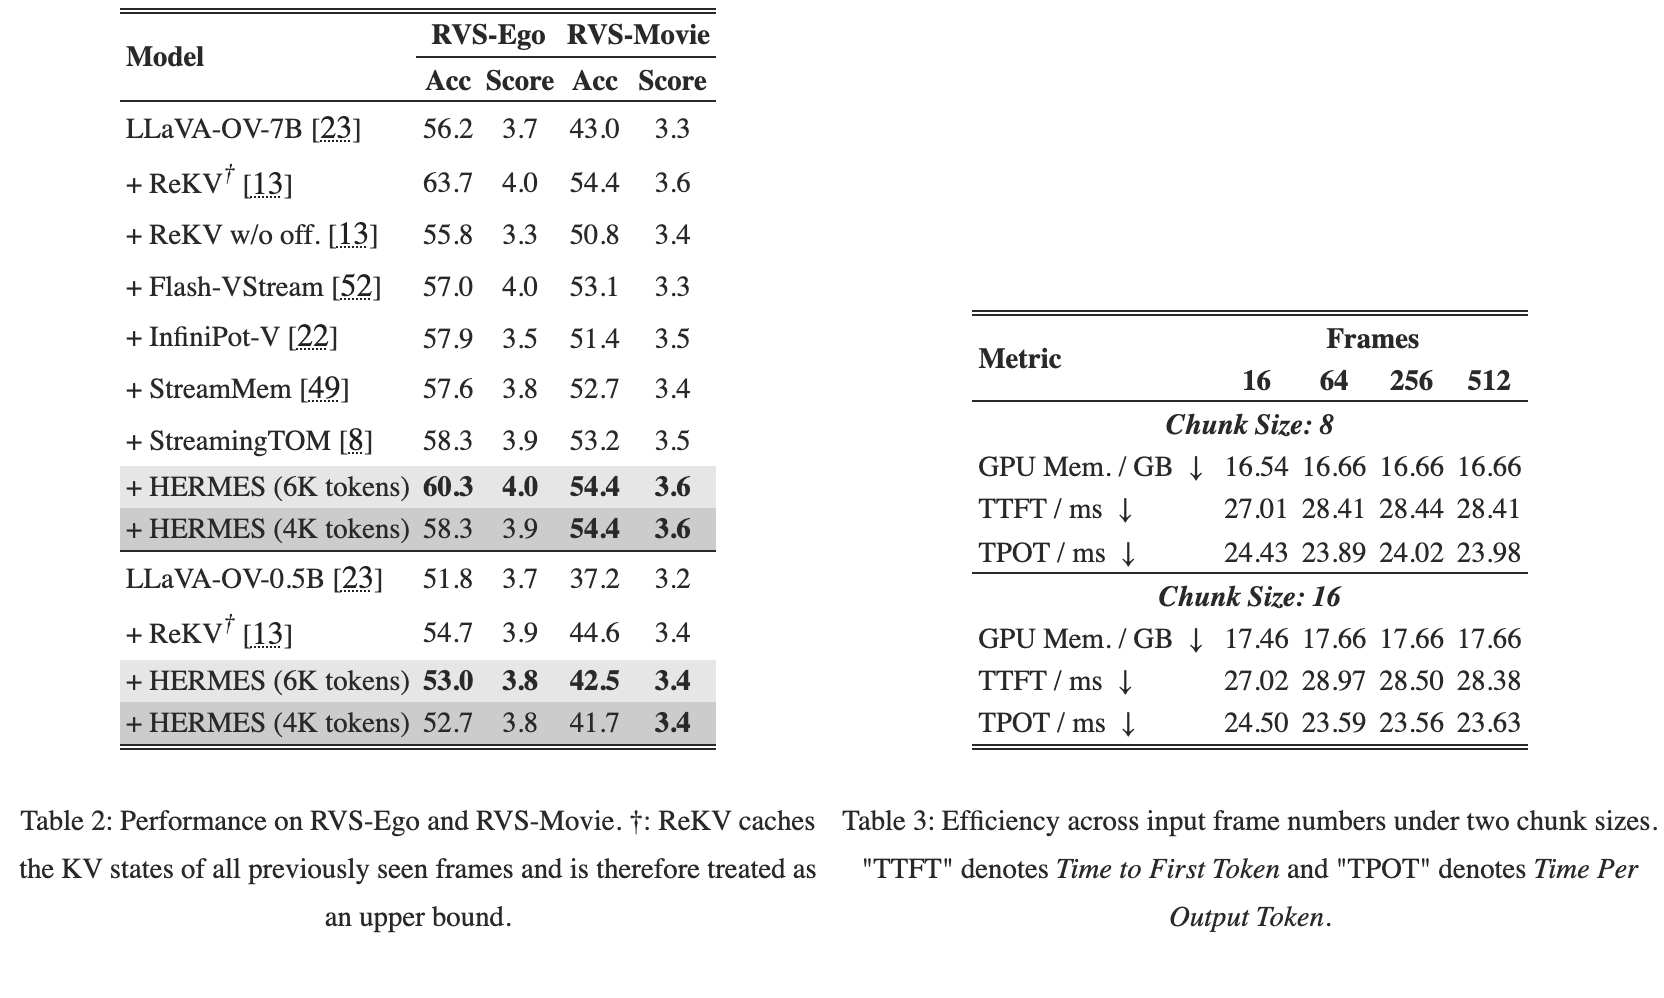
Table 3 Efficiency across input frame numbers under two chunk sizes. "TTFT" denotes Time to First Token and "TPOT" denotes Time Per Output Token.
View original table
Extensive experiments on streaming benchmarks reveal the key findings:
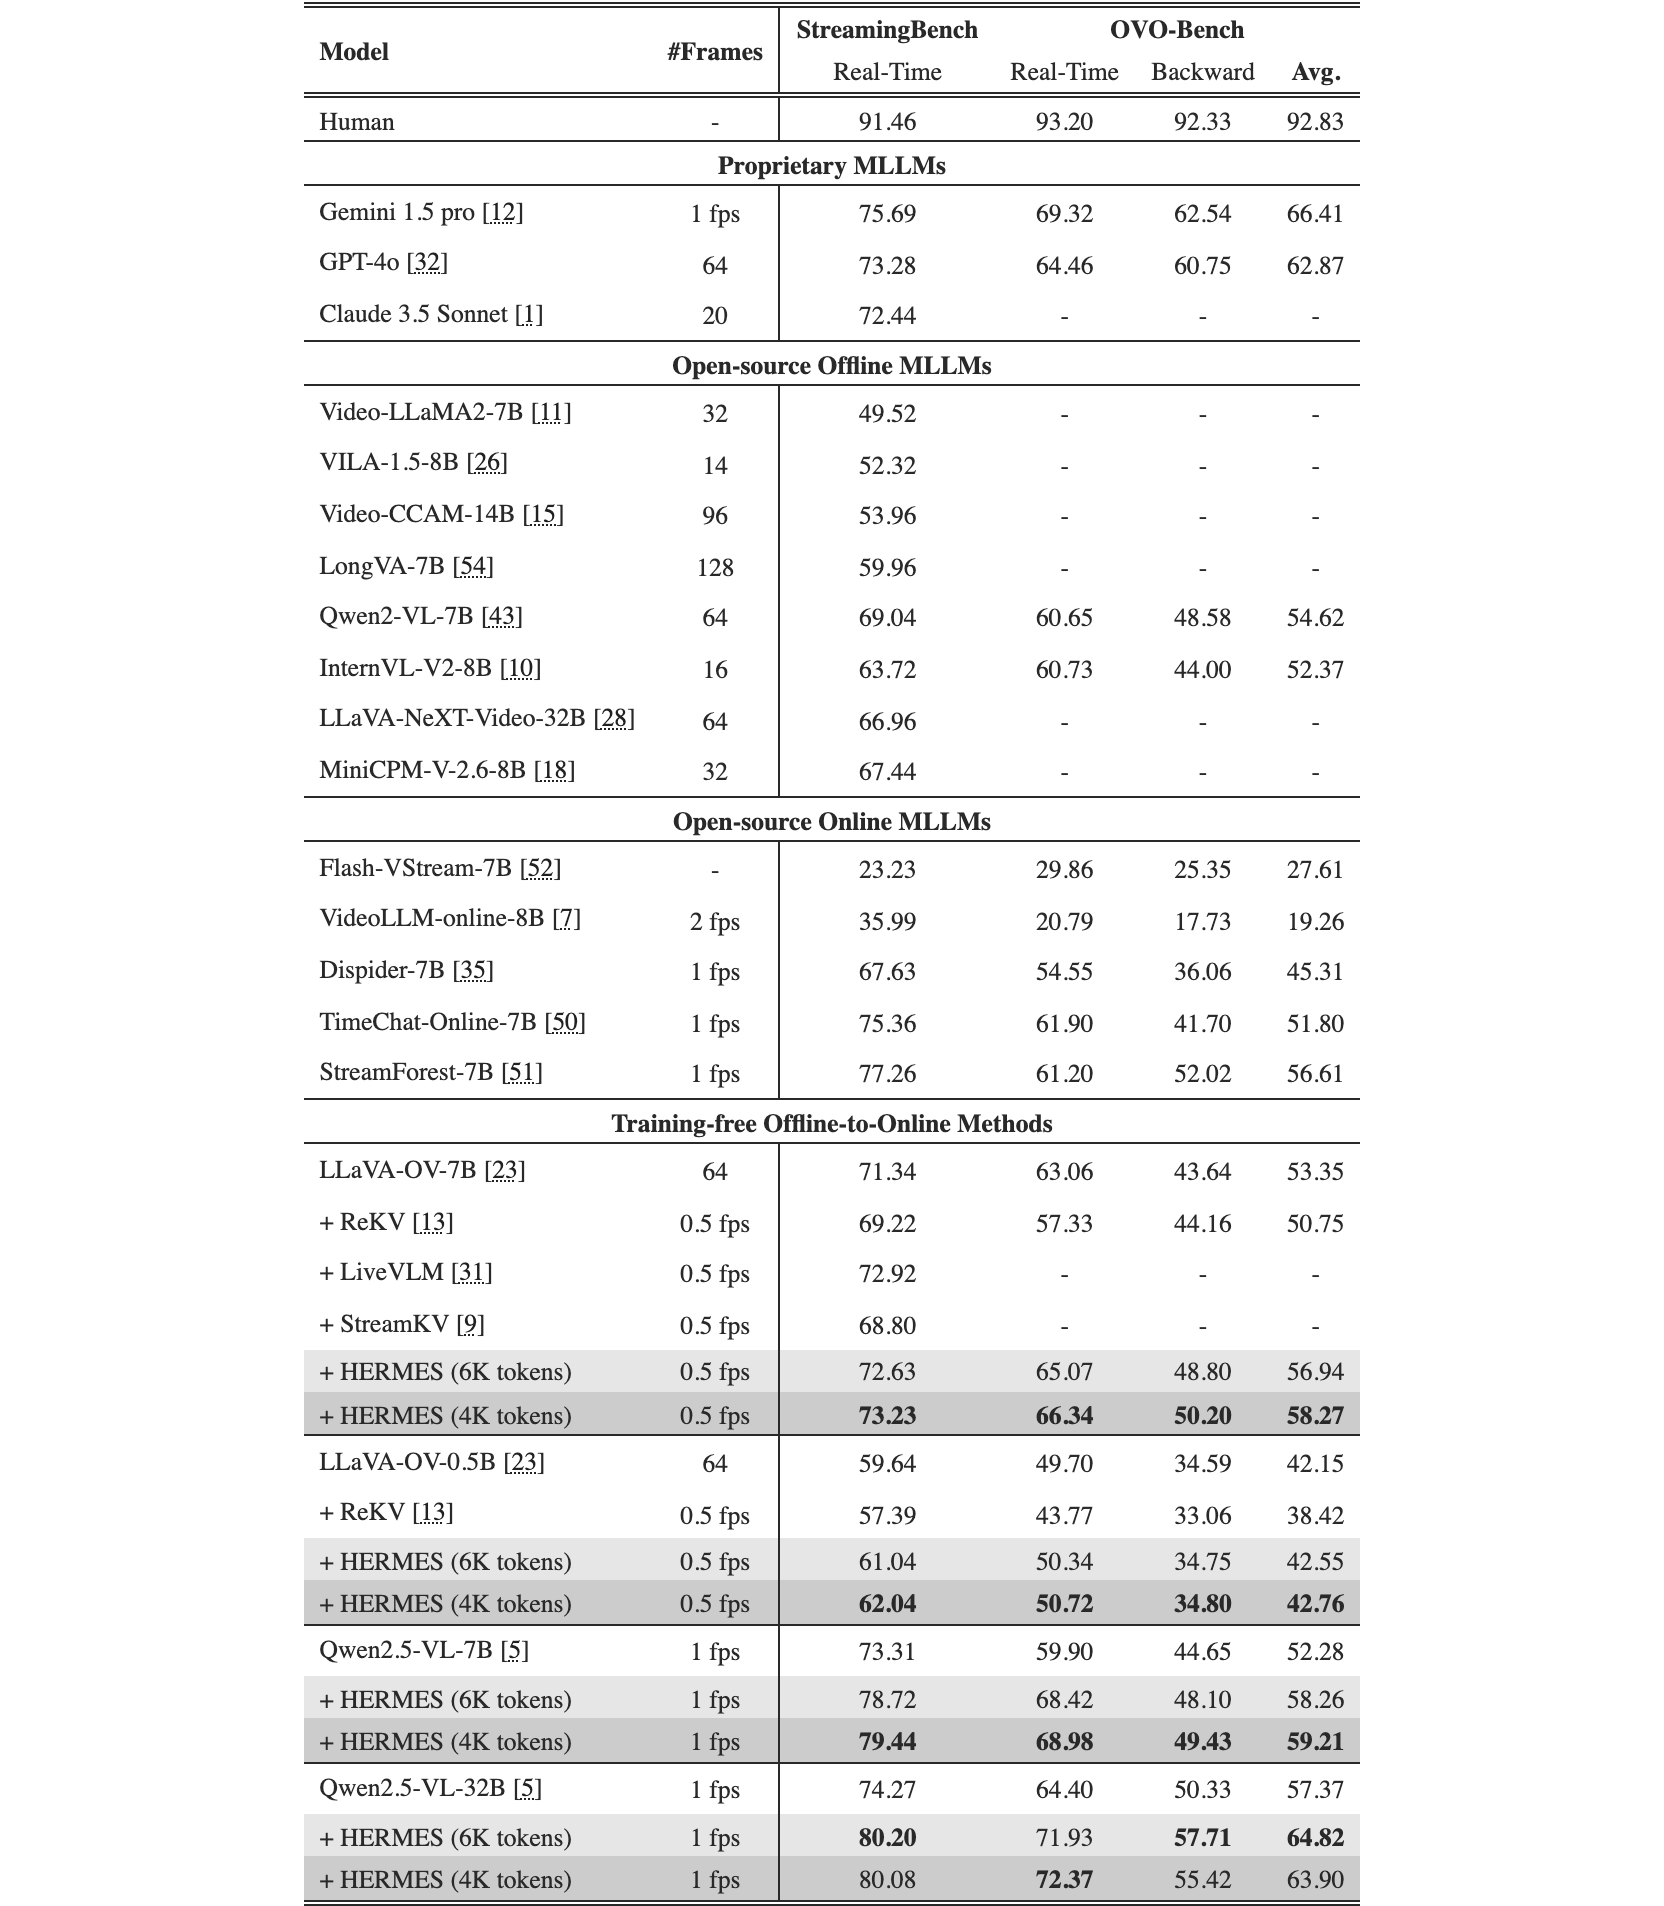
(1) HERMES outperforms on multiple-choice streaming datasets, showing exceptional real-time understanding and backward tracing capabilities. As shown in table 1, it achieves state-of-the-art performance on StreamingBench and OVO-Bench, significantly surpassing base models and training-free baselines. Built on Qwen2.5-VL-7B, HERMES reaches 79.44% and 59.21% accuracy using only 4K video tokens, improving over Qwen2.5-VL-7B by 6.13% and 6.93%, while outperforming all 7B-scale open-source online and offline models. Full results on StreamingBench and OVO-Bench are shown in table 11 and table 12 respectively.
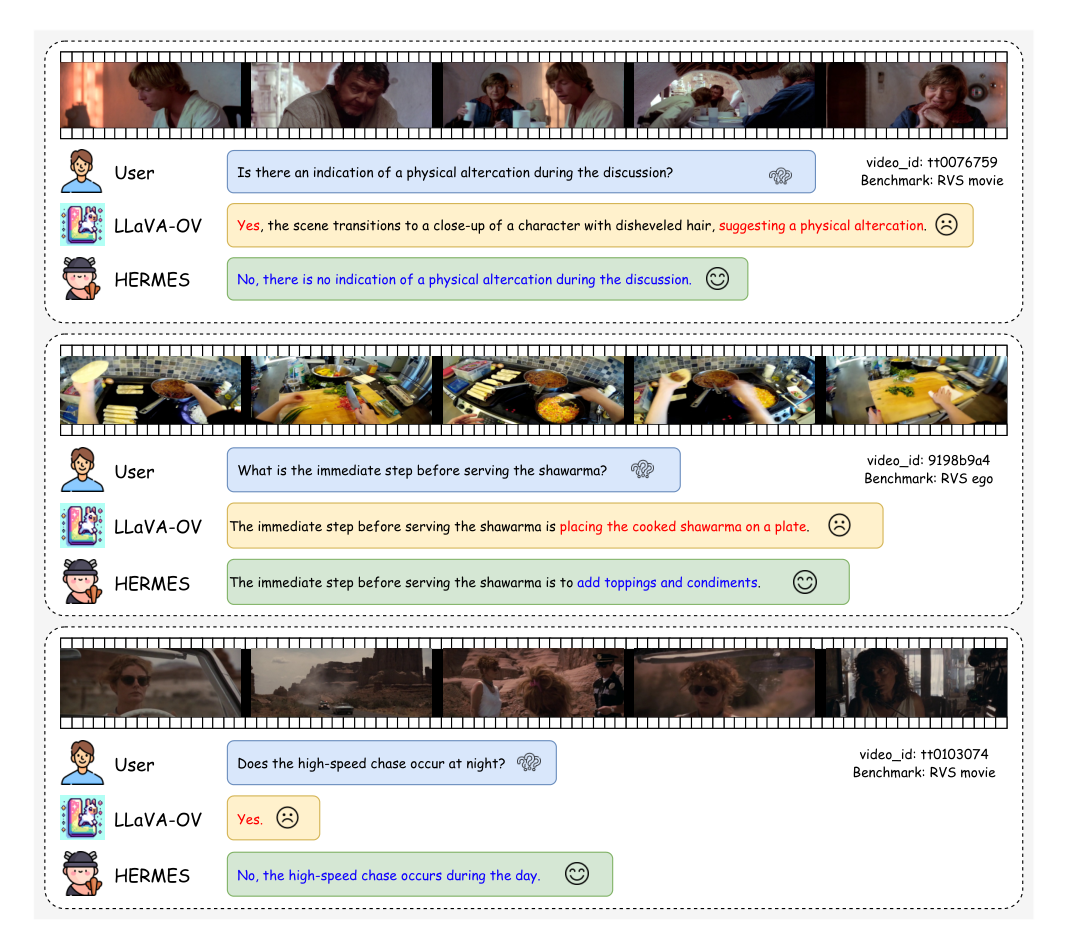
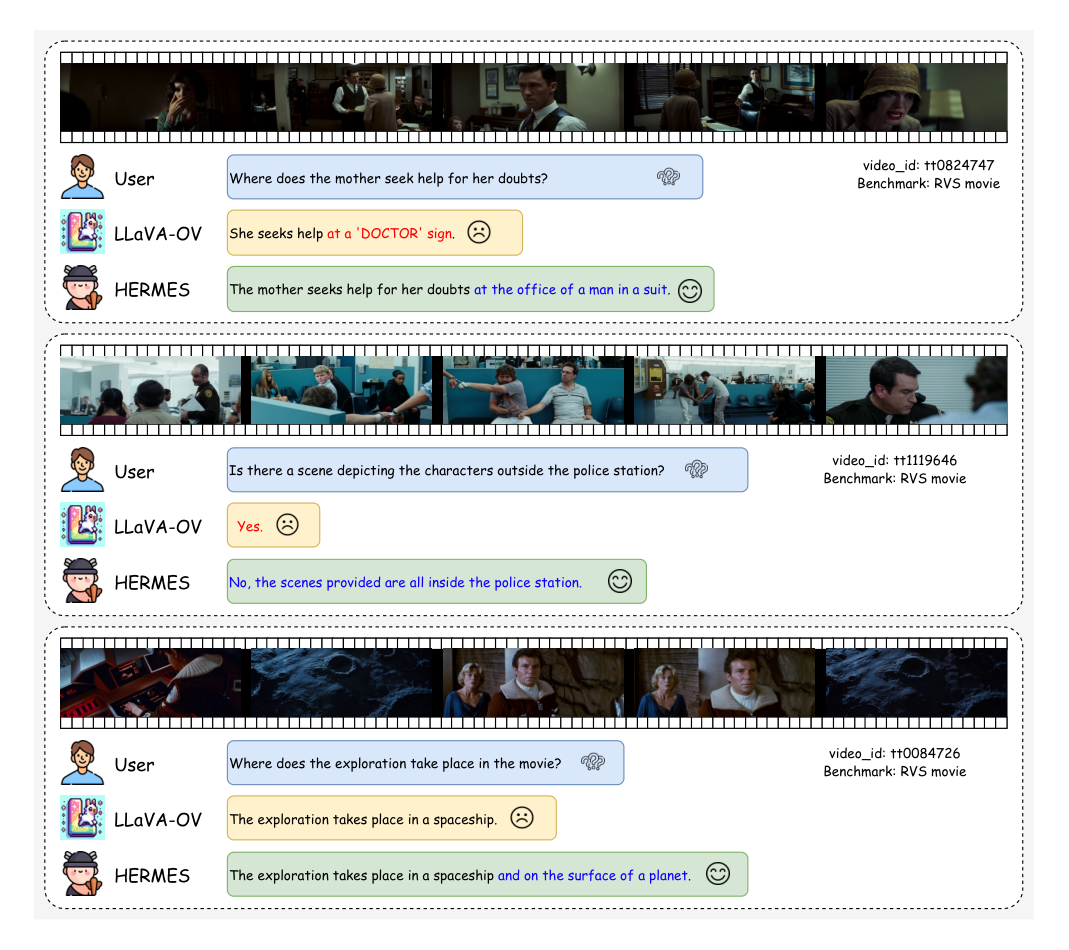
(2) HERMES excels on open-ended streaming tasks, showing fine-grained temporal and spatial comprehension. On RVS-Ego and RVS-Movie (table 3), we evaluate the model answer by GPT-3.5-turbo-0125 on accuracy and score (1–5 scale), consistent with compared baselines. HERMES consistently surpasses all prior training-free methods and improves accuracy by up to 11.4% over the base model with uniformly sampled 64 frames. These extensive experiments demonstrate HERMES’s strong abilities in various streaming tasks, as well as its general applicability across foundation models. Moreover, we provide case studies from RVS benchmark, showing finer-grained temporal (shown in figure 11) and spatial understanding (shown in figure 12) abilities of HERMES than its base model.
| Model | #Frames | MVBench | Egoschema | VideoMME | |
| Long | Avg. | ||||
| Proprietary MLLMs | |||||
| Gemini 1.5 pro [12] | 1 fps | 75.69 | 69.32 | 62.54 | 66.41 |
| GPT-4o [32] | 64 | 73.28 | 64.46 | 60.75 | 62.87 |
| Claude 3.5 Sonnet [1] | 20 | 72.44 | - | - | - |
| Open-source Offline MLLMs | |||||
| Video-LLaMA2-7B [11] | 32 | 49.52 | - | - | - |
| VILA-1.5-8B [26] | 14 | 52.32 | - | - | - |
| Video-CCAM-14B [15] | 96 | 53.96 | - | - | - |
| LongVA-7B [54] | 128 | 59.96 | - | - | - |
| LLaVA-Video-7B [55] | 32 | 58.60 | 57.3 | - | 63.30 |
| Qwen2-VL-7B [43] | 64 | 67.00 | 66.70 | - | 63.30 |
| InternVL-V2-8B [10] | 16 | 65.80 | - | - | 56.30 |
| Kangaroo-7B [29] | 64 | 64.60 | - | - | - |
| LLaVA-NeXT-Video-32B [28] | 64 | 66.96 | - | - | - |
| MiniCPM-V-2.6-8B [18] | 32 | 67.44 | - | - | - |
| Open-source Online MLLMs | |||||
| Dispider-7B [35] | 1 fps | - | 55.60 | - | 57.20 |
| TimeChat-Online-7B [50] | 1 fps | 75.36 | 61.90 | 41.70 | 53.22 |
| StreamForest-7B [51] | 1 fps | 70.20 | - | - | 61.40 |
| Training-free Offline-to-Online Methods | |||||
| LLaVA-OV-7B [23] | 64 | 57.02 | 59.93 | 48.00 | 57.67 |
| + ReKV [13] | 0.5 fps | 56.83 | 60.70 | 46.89 | 57.74 |
| + HERMES (6K tokens) | 0.5 fps | 56.95 | 60.23 | 49.11 | 58.44 |
| + HERMES (4K tokens) | 0.5 fps | 56.92 | 60.29 | 49.22 | 58.85 |
| Qwen2.5-VL-7B [5] | 1 fps | 65.00 | 58.47 | 53.89 | 64.52 |
| + HERMES (6K tokens) | 1 fps | 65.40 | 59.47 | 54.44 | 62.00 |
| + HERMES (4K tokens) | 1 fps | 65.53 | 59.97 | 53.44 | 60.63 |
View original table
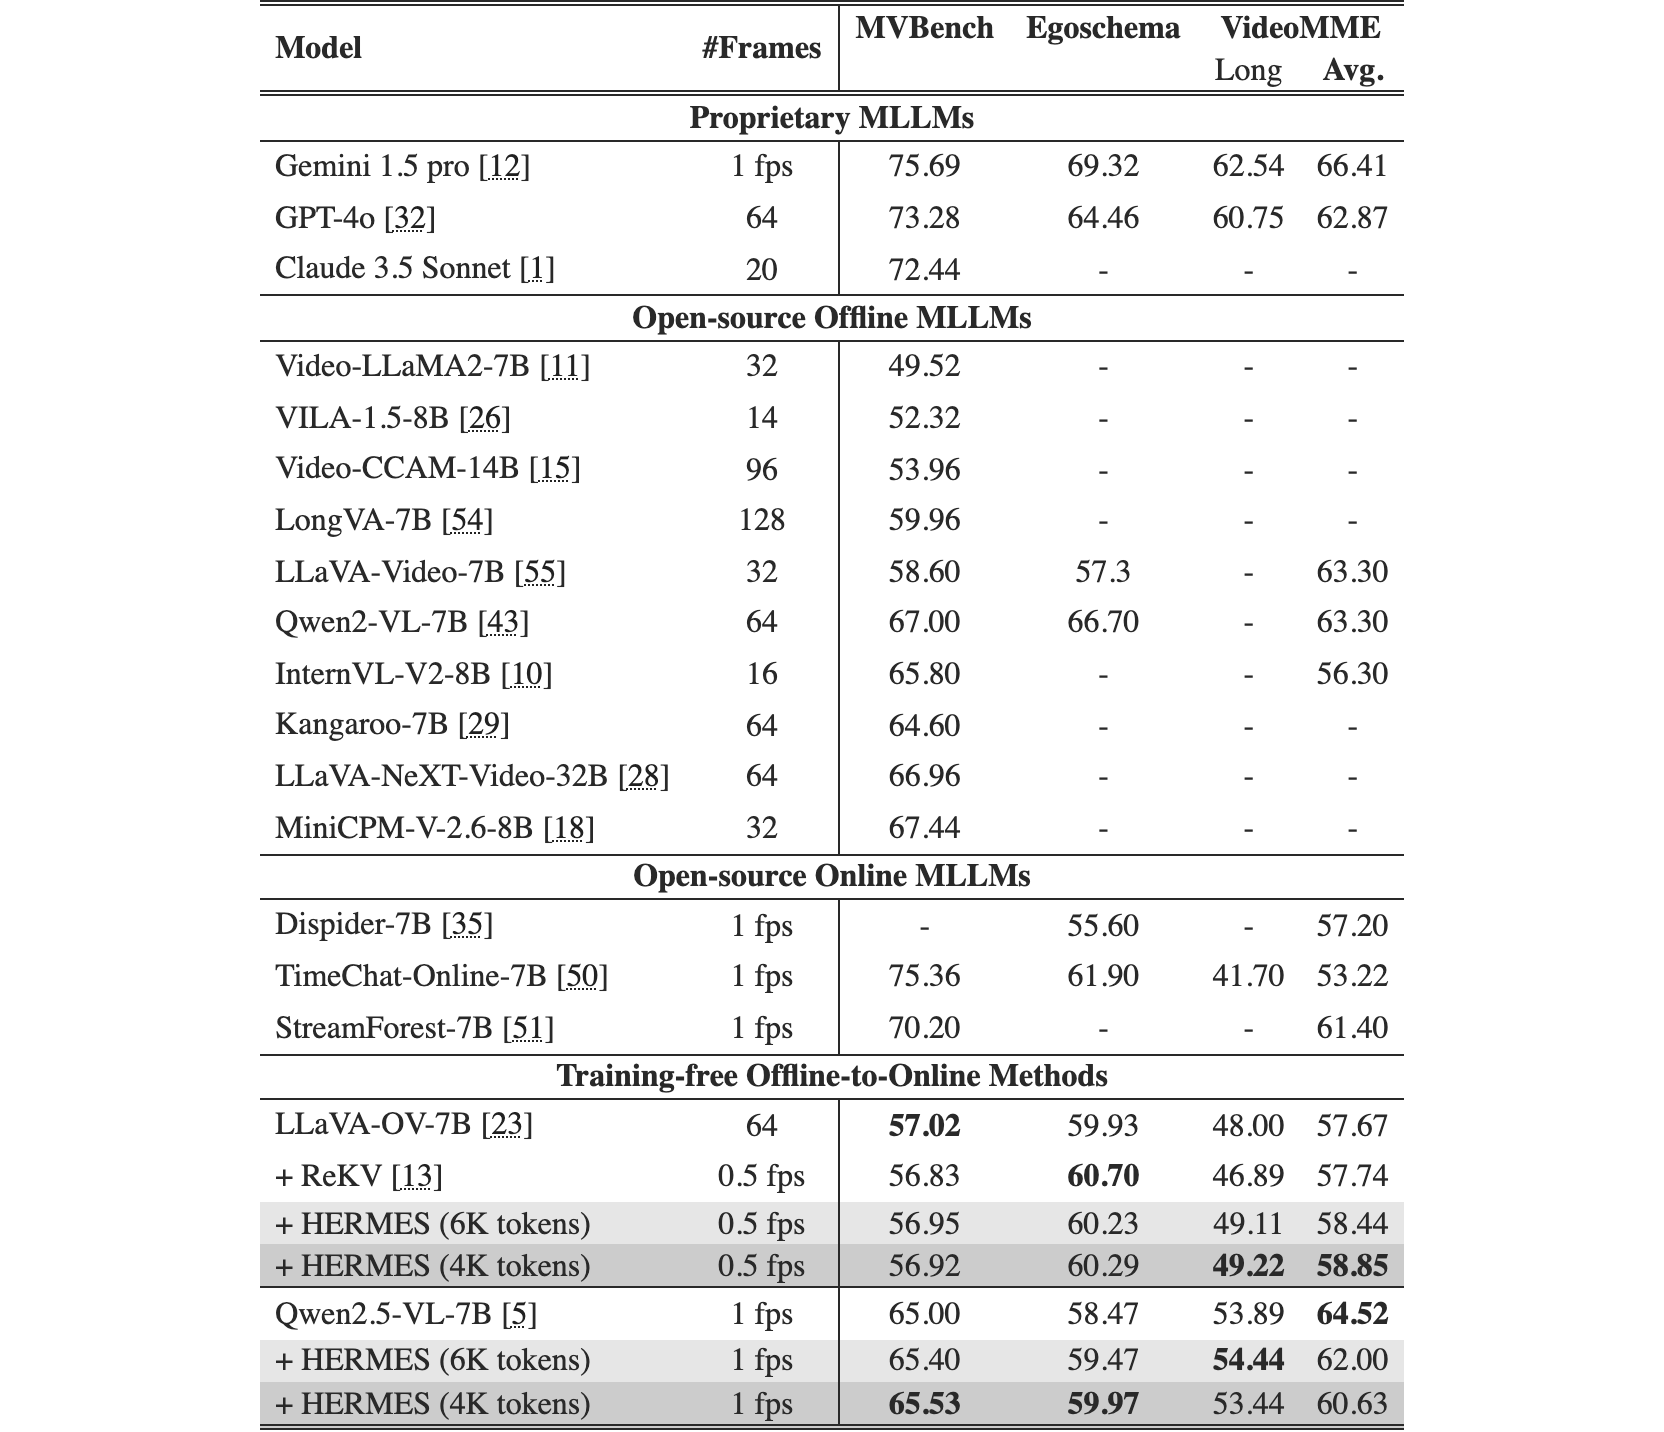
The results presented in table 4 demonstrate the competitive performance of HERMES across multiple temporal scales on offline benchmarks, compared to the base model and other training-free methods. Under a limited budget of video tokens, HERMES achieves performance that is better than or comparable to the corresponding base models. HERMES based on LLaVA-OV-7B surpasses the base model on long video datasets Egoschema and VideoMME, achieving 60.29% and 58.85%, respectively, and attains 56.92% accuracy on the short video dataset MVBench, which is comparable to the base model’s 57.02%.
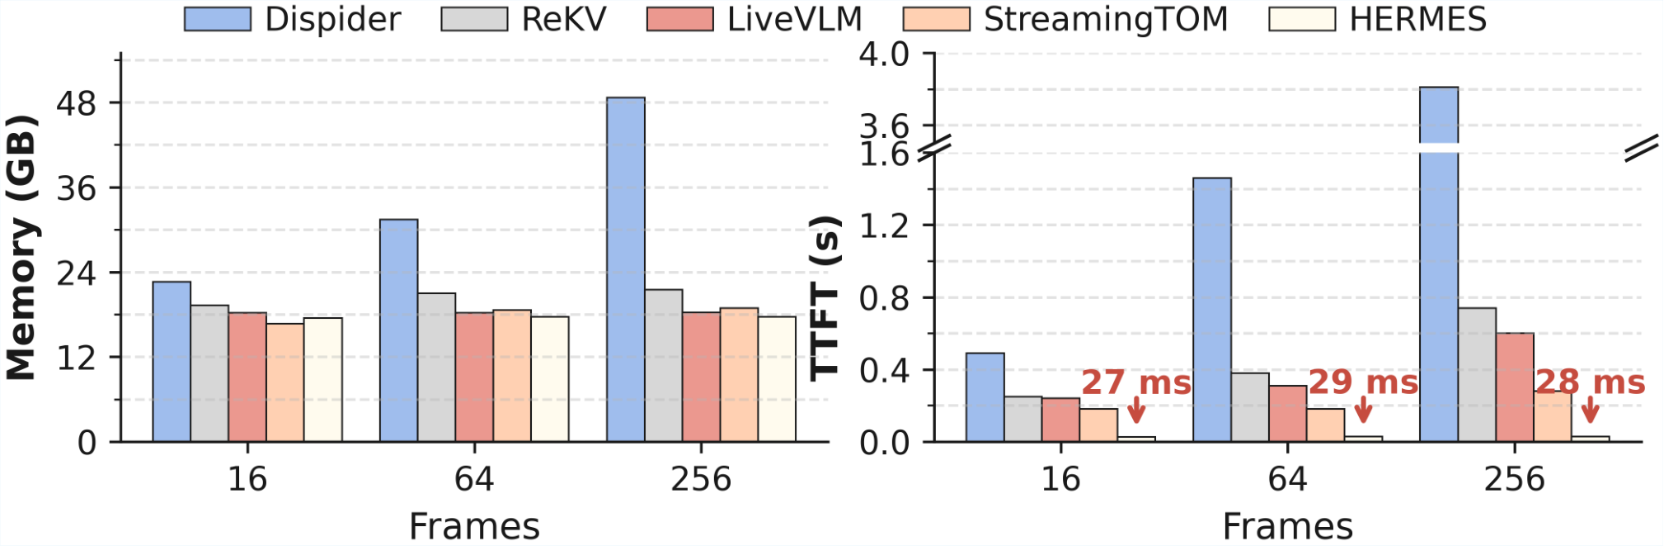
To evaluate the efficiency of HERMES, we utilize three metrics: peak GPU memory usage, Time to First Token (TTFT), defined as the latency measured from the moment a user inputs a query to the decoding of the first output token, and Time Per Output Token (TPOT) across varying numbers of input frames. All experiments are conducted using LLaVA-OV-7B as the base model with a 4K-token memory budget. figure 4 shows the comparison of memory usage and TTFT among HERMES and representative streaming methods. Unlike Dispider and LiveVLM, HERMES consistently maintains stable memory usage and TTFT as frames increase. Notably, under the 256-frame setting, HERMES achieves 1.04 reduction in peak memory compared to the prior SOTA LiveVLM, while achieving an impressive 10 speedup in TTFT over the prior SOTA StreamingTOM.
We further examine the efficiency of HERMES under varying encoded video chunk sizes, with the results shown in table 3. GPU memory usage does not increase with longer video lengths due to the fixed memory budget. TTFT and TPOT remain consistently low across varying video lengths and encoding chunk sizes, confirming real-time responsiveness in practical streaming scenarios.
We conduct ablation studies to evaluate the contributions of HERMES’s components and hyperparameter choices, covering: (1) KV cache memory budget, (2) cross-layer memory smoothing and its hyperparameters, (3) position re-indexing strategies for streaming and offline datasets, and (4) summary tokens for long-term memory retention.
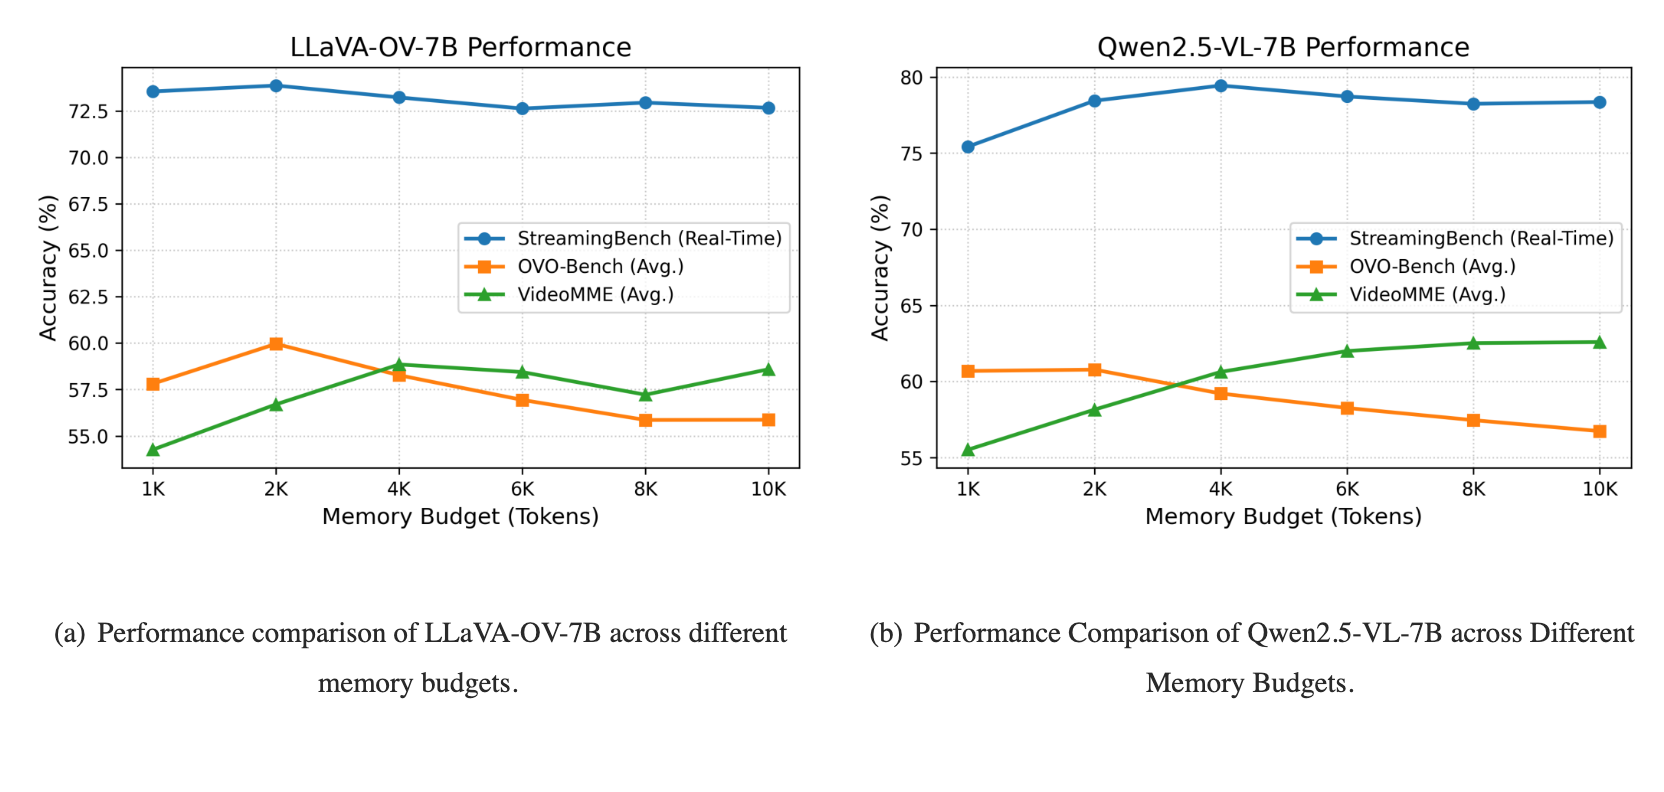
To investigate the impact of memory budget on understanding performance, we conduct ablations by varying the memory budget from 1K to 10K. As shown in figure 5(a), for HERMES built upon LLaVA-OV-7B, the performance on both streaming and offline datasets stabilizes once memory budget reaches 4K. Notably, streaming datasets can tolerate a smaller memory budget. In contrast, the performance on long offline datasets degrades significantly when the memory budget is below 4K. The ablation on Qwen2.5-VL-7B is provided in figure 5(b), yielding conclusions consistent with those on LLaVA-OV-7B.
| Hyperparameter | VideoMME | |||||
| Short | Medium | Long | Avg. | |||
| 0 | 0 | 0 | 69.67 | 51.11 | 43.44 | 54.74 |
| 0.5 | 0 | 0 | 69.67 | 51.44 | 43.56 | 54.89 |
| 0 | 0.5 | 0 | 70.89 | 54.78 | 46.44 | 57.37 |
| 0 | 0 | 0.5 | 70.89 | 54.44 | 47.00 | 57.44 |
| 0.5 | 0.5 | 0.5 | 71.78 | 54.78 | 47.33 | 57.96 |
| 0.4 | 0.3 | 0.1 | 71.33 | 54.89 | 49.11 | 58.44 |
| Model | Aggregation | VideoMME | |||
| Short | Medium | Long | Avg. | ||
| LLaVA-OV-7B | - | 69.89 | 55.11 | 48.00 | 57.67 |
| + HERMES | w/o | 71.33 | 54.78 | 47.78 | 57.96 |
| + HERMES | w/ | 71.33 | 54.89 | 49.11 | 58.44 |
Table 6 Ablation on summary tokens in deep layers. The gray row is our default setting in all experiments.
View original table
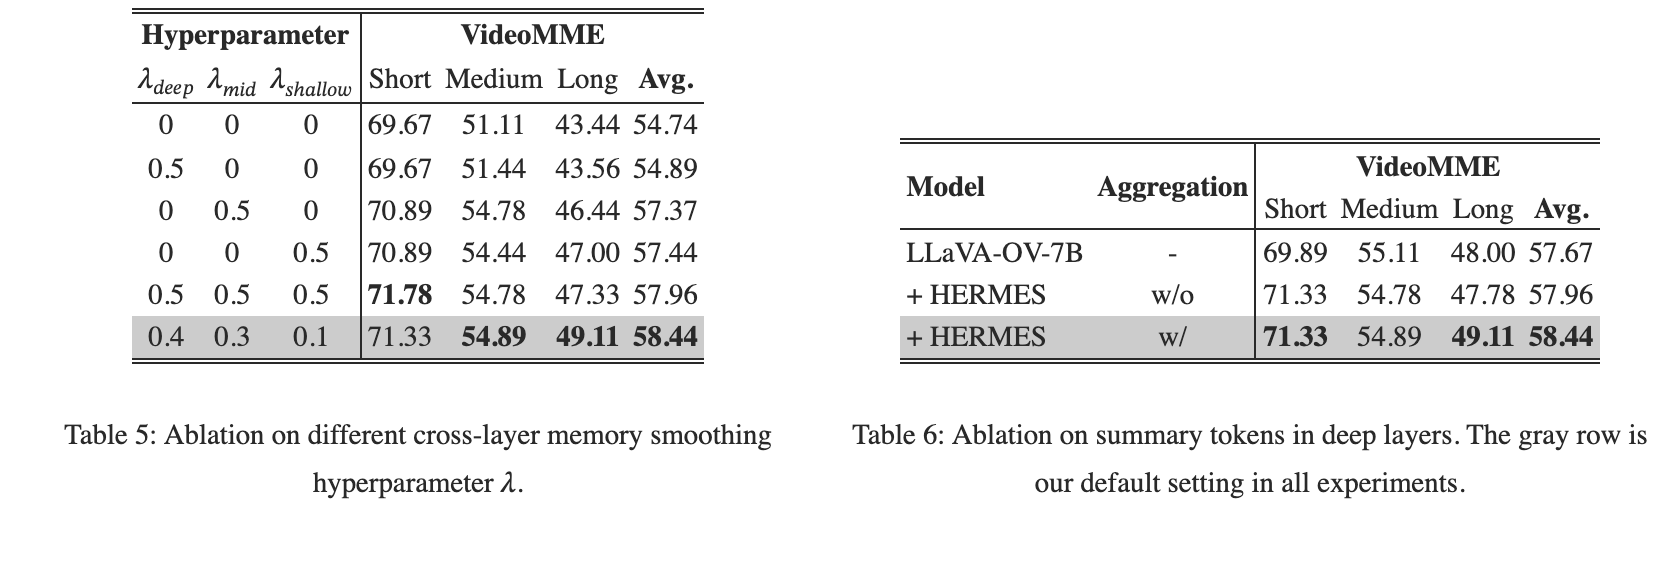
In table 6, we evaluate variants without the proposed cross-layer memory smoothing mechanism, as well as alternative hyperparameter configurations. All these variants exhibit degraded performance on the VideoMME benchmark, demonstrating both the critical role of memory smoothing and the effectiveness of our chosen hyperparameter settings.
| Model | Re-Indexing | StrBench | OVO-Bench | ||
| Real-Time | Real-Time | Backward | Avg. | ||
| LLaVA-OV-7B | - | 71.34 | 63.06 | 43.64 | 53.35 |
| + HERMES | lazy | 72.63 | 65.07 | 48.80 | 56.94 |
| + HERMES | eager | 72.30 | 64.91 | 47.21 | 56.06 |
| Model | Re-Indexing | VideoMME | |||
| Short | Medium | Long | Avg. | ||
| LLaVA-OV-7B | - | 69.89 | 55.11 | 48.00 | 57.67 |
| + HERMES | lazy | 69.67 | 51.67 | 43.44 | 54.93 |
| + HERMES | eager | 71.33 | 54.89 | 49.11 | 58.44 |
Table 8 Ablation on different re-indexing strategies on offline benchmark VideoMME. The gray row represents our default setting in all evaluations for offline benchmarks.
View original table
In section 3.2, we aggregate the evicted tokens in each deep layer into one summary token at each compression step. The results in table 6 indicate that these summary tokens effectively preserve long-term memory, leading to improved performance on VideoMME.
Existing MLLMs [12, 23, 5, 4] are primarily designed for pre-defined offline videos and struggle with continuous streaming videos. While some prior works have adapted existing offline MLLMs to online settings [50, 51, 46], they rely on costly model-specific training. Training-free streaming methods, such as ReKV [13] and LiveVLM [31], prefill offload KV cache to external devices. At user query time, they retrieve the full KV cache and reconstruct it on the GPU, incurring high latency and overall memory usage. In contrast, StreamMem [49] heuristically reuses KV cache, but lacks fine-grained KV cache management and interpretability. Unlike prior training-free methods, HERMES is grounded in a systematic attention analysis with improved interpretability and reliability.
Numerous KV cache compression techniques have been proposed for offline video understanding [48, 42, 44, 40], but most of these methods are poorly suited for streaming scenarios due to the unpredictable future frames and user queries [8]. Existing online KV cache compression paradigms [13, 31, 49, 8] largely overlook the inherently hierarchical storage structure of the KV cache. HERMES addresses this gap by introducing a hierarchical KV cache management strategy, which enables fine-grained memory utilization and low-latency responses.
This paper proposes HERMES, a training-free framework for efficient streaming video understanding. Guided by mechanistic attention analysis, we conceptualizes KV cache as a hierarchical video memory system across multiple granularities. By introducing a cross-layer memory smoothing and position re-indexing, HERMES further enhances the understanding performance for long streaming input. Extensive experiments demonstrate that HERMES delivers accurate performance under continuously growing video streams, while consistently maintaining extremely low response latency and compact GPU memory usage, making it well suited for real-world streaming deployment.
References
- [1] Anthropic (2024) Claude 3.5 sonnet. External Links: Link Cited by: Table 11, Table 1, Table 4.Source
- [2] R.C. Atkinson and R.M. ShiffrinK. W. Spence and J. T. Spence (Eds.) (1968) Human memory: a proposed system and its control processes. Psychology of Learning and Motivation, Vol. 2, Academic Press. External Links: ISSN 0079-7421, Document, Link Cited by: 1st item, 2nd item.SourceSource
- [3] A. D. Baddeley and G. HitchG. H. Bower (Ed.) (1974) Working memory. Psychology of Learning and Motivation, Vol. 8, Academic Press. External Links: ISSN 0079-7421, Document, Link Cited by: 3rd item.SourceSource
- [4] S. Bai, Y. Cai, R. Chen, K. Chen, X. Chen, Z. Cheng, L. Deng, W. Ding, C. Gao, C. Ge, W. Ge, Z. Guo, Q. Huang, J. Huang, F. Huang, B. Hui, S. Jiang, Z. Li, M. Li, M. Li, K. Li, Z. Lin, J. Lin, X. Liu, J. Liu, C. Liu, Y. Liu, D. Liu, S. Liu, D. Lu, R. Luo, C. Lv, R. Men, L. Meng, X. Ren, X. Ren, S. Song, Y. Sun, J. Tang, J. Tu, J. Wan, P. Wang, P. Wang, Q. Wang, Y. Wang, T. Xie, Y. Xu, H. Xu, J. Xu, Z. Yang, M. Yang, J. Yang, A. Yang, B. Yu, F. Zhang, H. Zhang, X. Zhang, B. Zheng, H. Zhong, J. Zhou, F. Zhou, J. Zhou, Y. Zhu, and K. Zhu (2025) Qwen3-vl technical report. External Links: 2511.21631, Link Cited by: §1, §5.Source
- [5] S. Bai, K. Chen, X. Liu, J. Wang, W. Ge, S. Song, K. Dang, P. Wang, S. Wang, J. Tang, H. Zhong, Y. Zhu, M. Yang, Z. Li, J. Wan, P. Wang, W. Ding, Z. Fu, Y. Xu, J. Ye, X. Zhang, T. Xie, Z. Cheng, H. Zhang, Z. Yang, H. Xu, and J. Lin (2025) Qwen2.5-vl technical report. External Links: 2502.13923, Link Cited by: Table 11, Table 11, Table 12, Table 12, §4.1, Table 1, Table 1, Table 4, §5.Source
- [6] A. Behrouz, P. Zhong, and V. Mirrokni (2024) Titans: learning to memorize at test time. External Links: 2501.00663, Link Cited by: §3.2.Source
- [7] J. Chen, Z. Lv, S. Wu, K. Q. Lin, C. Song, D. Gao, J. Liu, Z. Gao, D. Mao, and M. Z. Shou (2024) VideoLLM-online: online video large language model for streaming video. External Links: 2406.11816, Link Cited by: Table 11, Table 12, Table 1.Source
- [8] X. Chen, K. Tao, K. Shao, and H. Wang (2025) StreamingTOM: streaming token compression for efficient video understanding. External Links: 2510.18269, Link Cited by: §4.1, Table 3, §5.Source
- [9] Y. Chen, X. Bai, Z. Wang, C. Bai, Y. Dai, M. Lu, and S. Zhang (2025) StreamKV: streaming video question-answering with segment-based kv cache retrieval and compression. External Links: 2511.07278, Link Cited by: Table 11, Table 1.Source
- [10] Z. Chen, W. Wang, H. Tian, S. Ye, Z. Gao, E. Cui, W. Tong, K. Hu, J. Luo, Z. Ma, J. Ma, J. Wang, X. Dong, H. Yan, H. Guo, C. He, B. Shi, Z. Jin, C. Xu, B. Wang, X. Wei, W. Li, W. Zhang, B. Zhang, P. Cai, L. Wen, X. Yan, M. Dou, L. Lu, X. Zhu, T. Lu, D. Lin, Y. Qiao, J. Dai, and W. Wang (2024) How far are we to gpt-4v? closing the gap to commercial multimodal models with open-source suites. External Links: 2404.16821, Link Cited by: Table 11, Table 12, Table 1, Table 4.Source
- [11] Z. Cheng, S. Leng, H. Zhang, Y. Xin, X. Li, G. Chen, Y. Zhu, W. Zhang, Z. Luo, D. Zhao, and L. Bing (2024) VideoLLaMA 2: advancing spatial-temporal modeling and audio understanding in video-llms. External Links: 2406.07476, Link Cited by: Table 11, Table 1, Table 4.Source
- [12] G. Comanici, E. Bieber, M. Schaekermann, I. Pasupat, N. Sachdeva, I. Dhillon, M. Blistein, O. Ram, D. Zhang, E. Rosen, L. Marris, S. Petulla, C. Gaffney, A. Aharoni, N. Lintz, T. C. Pais, H. Jacobsson, I. Szpektor, N. Jiang, K. Haridasan, A. Omran, N. Saunshi, D. Bahri, G. Mishra, E. Chu, T. Boyd, B. Hekman, A. Parisi, C. Zhang, K. Kawintiranon, T. Bedrax-Weiss, O. Wang, Y. Xu, O. Purkiss, U. Mendlovic, I. Deutel, N. Nguyen, A. Langley, F. Korn, L. Rossazza, A. Ramé, S. Waghmare, H. Miller, N. Byrd, A. Sheshan, R. Hadsell, S. Bhardwaj, P. Janus, T. Rissa, D. Horgan, A. Abdagic, L. Belenki, J. Allingham, A. Singh, T. Guidroz, S. Srinivasan, H. Schmit, K. Chiafullo, A. Elisseeff, N. Jha, P. Kolhar, L. Berrada, F. Ding, X. Si, S. B. Mallick, F. Och, S. Erell, E. Ni, T. Latkar, S. Yang, P. Sirkovic, Z. Feng, R. Leland, R. Hornung, G. Wu, C. Blundell, H. Alvari, P. Huang, C. Yip, S. Deur, L. Liu, G. Surita, P. Duque, D. Damen, J. Jia, A. Guez, M. Mircea, A. Sinha, A. Magni, P. Stradomski, T. Marian, V. Galić, W. Chen, H. Husain, A. Singhal, D. Grewe, F. Aubet, S. Song, L. Blanco, L. Rechis, L. Ho, R. Munoz, K. Zheng, J. Hamrick, K. Mather, H. Taitelbaum, E. Rutherford, Y. Lei, K. Chen, A. Shukla, E. Moreira, E. Doi, B. Isik, N. Shabat, D. Rogozińska, K. Kolipaka, J. Chang, E. Vušak, S. Venkatachary, S. Noghabi, T. Bharti, Y. Jun, A. Zaks, S. Green, J. Challagundla, W. Wong, M. Mohammad, D. Hirsch, Y. Cheng, I. Naim, L. Proleev, D. Vincent, A. Singh, M. Krikun, D. Krishnan, Z. Ghahramani, A. Atias, R. Aggarwal, C. Kirov, D. Vytiniotis, C. Koh, A. Chronopoulou, P. Dogra, V. Ion, G. Tyen, J. Lee, F. Weissenberger, T. Strohman, A. Balakrishna, J. Rae, M. Velic, R. de Liedekerke, O. Elyada, W. Yuan, C. Liu, L. Shani, S. Kishchenko, B. Alessio, Y. Li, R. Song, S. Kwei, O. Jankowski, A. Pappu, Y. Namiki, Y. Ma, N. Tripuraneni, C. Cherry, M. Ikonomidis, Y. Ling, C. Ji, B. Westberg, A. Wright, D. Yu, D. Parkinson, S. Ramaswamy, J. Connor, S. H. Yeganeh, S. Grover, G. Kenwright, L. Litchev, C. Apps, A. Tomala, F. Halim, A. Castro-Ros, Z. Li, A. Boral, P. Sho, M. Yarom, E. Malmi, D. Klinghoffer, R. Lin, A. Ansell, P. K. S, S. Zhao, S. Zuo, A. Santoro, H. Cheng, S. Demmessie, Y. Liu, N. Brichtova, A. Culp, N. Braun, D. Graur, W. Ng, N. Mehta, A. Phillips, P. Sundberg, V. Godbole, F. Liu, Y. Katariya, D. Rim, M. Seyedhosseini, S. Ammirati, J. Valfridsson, M. Malihi, T. Knight, A. Toor, T. Lampe, A. Ittycheriah, L. Chiang, C. Yeung, A. Fréchette, J. Rao, H. Wang, H. Srivastava, R. Zhang, R. Rhodes, A. Brand, D. Weesner, I. Figotin, F. Gimeno, R. Fellinger, P. Marcenac, J. Leal, E. Marcus, V. Cotruta, R. Cabrera, S. Luo, D. Garrette, V. Axelrod, S. Baltateanu, D. Barker, D. Chen, H. Toma, B. Ingram, J. Riesa, C. Kulkarni, Y. Zhang, H. Liu, C. Wang, M. Polacek, W. Wu, K. Hui, A. N. Reyes, Y. Su, M. Barnes, I. Malhi, A. Siddiqui, Q. Feng, M. Damaschin, D. Pighin, A. Steiner, S. Yang, R. S. Boppana, S. Ivanov, A. Kandoor, A. Shah, A. Mujika, D. Huang, C. A. Choquette-Choo, M. Patel, T. Yu, T. Creswell, Jerry, Liu, C. Barros, Y. Razeghi, A. Roy, P. Culliton, B. Xiong, J. Pan, T. Strohmann, T. Powell, B. Seal, D. DeCarlo, P. Shyam, K. Katircioglu, X. Wang, C. Hardin, I. Odisho, J. Broder, O. Chang, A. Nair, A. Shtefan, M. O’Brien, M. Agarwal, S. Potluri, S. Goyal, A. Jhindal, S. Thakur, Y. Stuken, J. Lyon, K. Toutanova, F. Feng, A. Wu, B. Horn, A. Wang, A. Cullum, G. Taubman, D. Shrivastava, C. Shi, H. Tomlinson, R. Patel, T. Tu, A. M. Oflazer, F. Pongetti, M. Yang, A. A. Taïga, V. Perot, N. W. Pierse, F. Han, Y. Drori, I. Iturrate, A. Chakrabarti, L. Yeung, D. Dopson, Y. Chen, A. Kulshreshtha, T. Guo, P. Pham, T. Schuster, J. Chen, A. Polozov, J. Xing, H. Zhou, P. Kacham, D. Kukliansky, A. Miech, S. Yaroshenko, E. Chi, S. Douglas, H. Fei, M. Blondel, P. Myla, L. Madmoni, X. Wu, D. Keysers, K. Kjems, I. Albuquerque, L. Yu, J. D’sa, M. Plantan, V. Ionescu, J. S. Elias, A. Gupta, M. R. Vuyyuru, F. Alcober, T. Zhou, K. Ji, F. Hartmann, S. Puttagunta, H. Song, E. Amid, A. Stefanoiu, A. Lee, P. Pucciarelli, E. Wang, A. Raul, S. Petrov, I. Tian, V. Anklin, N. Nti, V. Gomes, M. Schumacher, G. Vesom, A. Panagopoulos, K. Bousmalis, D. Andor, J. Jacob, Y. Zhang, B. Rosgen, M. Kecman, M. Tung, A. Belias, N. Goodman, P. Covington, B. Wieder, N. Saxena, E. Davoodi, M. Huang, S. Maddineni, V. Roulet, F. Campbell-Ajala, P. G. Sessa, Xintian, Wu, G. Lai, P. Collins, A. Haig, V. Sakenas, X. Xu, M. Giustina, L. E. Shafey, P. Charoenpanit, S. Garg, J. Ainslie, B. Severson, M. G. Arenas, S. Pathak, S. Rajayogam, J. Feng, M. Bakker, S. Li, N. Wichers, J. Rogers, X. Geng, Y. Li, R. Jagerman, C. Jia, N. Olmert, D. Sharon, M. Mauger, S. Mariserla, H. Ma, M. Mohabey, K. Kim, A. Andreev, S. Pollom, J. Love, V. Jain, P. Agrawal, Y. Schroecker, A. Fortin, M. Warmuth, J. Liu, A. Leach, I. Blok, G. P. Girirajan, R. Aharoni, B. Uria, A. Sozanschi, D. Goldberg, L. Ionita, M. T. Ribeiro, M. Zlocha, V. Birodkar, S. Lachgar, L. Yuan, H. Choudhury, M. Ginsberg, F. Zheng, G. Dibb, E. Graves, S. Lokhande, G. Rasskin, G. Muraru, C. Quick, S. Tata, P. Sermanet, A. Chawla, I. Karo, Y. Wang, S. Zhang, O. Keller, A. Dragan, G. Su, I. Chou, X. Liu, Y. Tao, S. Prabhakara, M. Wilson, R. Liu, S. Wang, G. Evans, D. Du, A. Castaño, G. Prasad, M. E. Mahdy, S. Gerlach, M. Reid, J. Kahn, A. Zait, T. S. Pillai, T. Ulrich, G. Wang, J. Wassenberg, E. Farkash, K. Yalasangi, C. Wang, M. Bauza, S. Bucher, T. Liu, J. Yan, G. Leung, V. Sindhwani, P. Barnes, A. Singh, I. Jurin, J. Chang, N. K. Bhumihar, S. Eiger, G. Citovsky, B. Withbroe, Z. Li, S. Xue, N. D. Santo, G. Stoyanov, Y. Raimond, S. Zheng, Y. Gao, V. Listík, S. Kwasiborski, R. Saputro, A. Ozturel, G. Mallya, K. Majmundar, R. West, P. Caron, J. Wei, L. Castrejon, S. Vikram, D. Ramachandran, N. Dhawan, J. Park, S. Smoot, G. van den Driessche, Y. Blau, C. Malik, W. Liang, R. Hirsch, C. N. dos Santos, E. Weinstein, A. van den Oord, S. Lall, N. FitzGerald, Z. Jiang, X. Yang, D. Webster, A. Elqursh, A. Pope, G. Rotival, D. Raposo, W. Zhu, J. Dean, S. Alabed, D. Tran, A. Gupta, Z. Gleicher, J. Austin, E. Rosseel, M. Umekar, D. Das, Y. Sun, K. Chen, K. Misiunas, X. Zhou, Y. Di, A. Loo, J. Newlan, B. Li, V. Ramasesh, Y. Xu, A. Chen, S. Gandhe, R. Soricut, N. Gupta, S. Hu, S. El-Sayed, X. Garcia, I. Brusilovsky, P. Chen, A. Bolt, L. Huang, A. Gurney, Z. Zhang, A. Pritzel, J. Wilkiewicz, B. Seybold, B. K. Shamanna, F. Fischer, J. Dean, K. Gill, R. Mcilroy, A. Bhowmick, J. Selier, A. Yang, D. Cheng, V. Magay, J. Tan, D. Varma, C. Walder, T. Kocisky, R. Nakashima, P. Natsev, M. Kwong, I. Gog, C. Zhang, S. Dieleman, T. Jimma, A. Ryabtsev, S. Brahma, D. Steiner, D. Du, A. Žužul, M. Žanić, M. Raghavachari, W. Gierke, Z. Zheng, D. Petrova, Y. Dauphin, Y. Liu, I. Kessler, S. Hand, C. Duvarney, S. Kim, H. Lee, L. Hussenot, J. Hui, J. Smith, D. Jain, J. Xia, G. S. Tomar, K. Amiri, D. Phan, F. Fuchs, T. Weyand, N. Tomasev, A. Cordell, X. Liu, J. Mallinson, P. Joshi, A. Crawford, A. Suggala, S. Chien, N. Fernando, M. Sanchez-Vargas, D. Williams, P. Crone, X. Luo, I. Karpov, J. Shan, T. Thurk, R. Strudel, P. Voigtlaender, P. Patil, T. Dozat, A. Khodaei, S. Singla, P. Ambroszczyk, Q. Wu, Y. Chang, B. Roark, C. Hegde, T. Ding, A. Filos, Z. Wu, A. S. Pinto, S. Liu, S. Khanna, A. Pandey, S. Mcloughlin, Q. Li, S. Haves, A. Zhou, E. Buchatskaya, I. Leal, P. de Boursac, N. Akazawa, N. Anderson, T. Chen, K. Somandepalli, C. Liang, S. Goenka, S. Winkler, A. Grushetsky, Y. Ding, J. Smith, F. Ye, J. Pont-Tuset, E. Li, R. Li, T. Golany, D. Wegner, T. Jiang, O. Barak, Y. Shangguan, E. Vértes, R. Wong, J. Bornschein, A. Tudor, M. Bevilacqua, T. Schaul, A. S. Rawat, Y. Zhao, K. Axiotis, L. Meng, C. McLean, J. Lai, J. Beattie, N. Kushman, Y. Liu, B. Kutzman, F. Lang, J. Ye, P. Netrapalli, P. Mishra, M. Khan, M. Goel, R. Willoughby, D. Tian, H. Zhuang, J. Chen, Z. Tsai, T. Kementsietsidis, A. Khare, J. Keeling, K. Xu, N. Waters, F. Altché, A. Popat, B. Mittal, D. Saxton, D. E. Badawy, M. Mathieu, Z. Zheng, H. Zhou, N. Ranka, R. Shin, Q. Duan, T. Salimans, I. Mihailescu, U. Shaham, M. Chang, Y. Assael, N. Dikkala, M. Izzard, V. Cohen-Addad, C. Graves, V. Feinberg, G. Chung, D. Strouse, D. Karmon, S. Sharifzadeh, Z. Ashwood, K. Pham, J. Blanton, A. Vasiloff, J. Barber, M. Geller, A. Zhou, F. Zubach, T. Huang, L. Zhang, H. Gupta, M. Young, J. Proskurnia, R. Votel, V. Gabeur, G. Barcik, A. Tripathi, H. Yu, G. Yan, B. Changpinyo, F. Pavetić, A. Coyle, Y. Fujii, J. G. Mendez, T. Zhou, H. Rajamani, B. Hechtman, E. Cao, D. Juan, Y. Tan, V. Dalibard, Y. Du, N. Clay, K. Yao, W. Jia, D. Vijaykumar, Y. Zhou, X. Bai, W. Hung, S. Pecht, G. Todorov, N. Khadke, P. Gupta, P. Lahoti, A. Autef, K. Duddu, J. Lee-Thorp, A. Bykovsky, T. Misiunas, S. Flennerhag, S. Thangaraj, J. McGiffin, Z. Nado, M. Kunesch, A. Noever, A. Hertz, M. Liang, V. Stone, E. Palmer, S. Daruki, A. Pramanik, S. Põder, A. Kyker, M. Khan, E. Sluzhaev, M. Ritter, A. Ruderman, W. Zhou, C. Nagpal, K. Vodrahalli, G. Necula, P. Barham, E. Pavlick, J. Hartford, I. Shafran, L. Zhao, M. Mikuła, T. Eccles, H. Shimokawa, K. Garg, L. Vilnis, H. Chen, I. Shumailov, K. Lee, A. Abdelhamed, M. Xie, V. Cohen, E. Hlavnova, D. Malkin, C. Sitawarin, J. Lottes, P. Coquinot, T. Yu, S. Kumar, J. Zhang, A. Mahendru, Z. Ahmed, J. Martens, T. Chen, A. Boag, D. Peng, C. Devin, A. Klimovskiy, M. Phuong, D. Vainstein, J. Xie, B. Ramabhadran, N. Howard, X. Yu, G. Goswami, J. Cui, S. Shleifer, M. Pinto, C. Yeh, M. Yang, S. Javanmardi, D. Ethier, C. Lee, J. Orbay, S. Kotecha, C. Bromberg, P. Shaw, J. Thornton, A. G. Rosenthal, S. Gu, M. Thomas, I. Gemp, A. Ayyar, A. Ushio, A. Selvan, J. Wee, C. Liu, M. Majzoubi, W. Yu, J. Abernethy, T. Liechty, R. Pan, H. Nguyen, Qiong, Hu, S. Perrin, A. Arora, E. Pitler, W. Wang, K. Shivakumar, F. Prost, B. Limonchik, J. Wang, Y. Gao, T. Cour, S. Buch, H. Gui, M. Ivanova, P. Neubeck, K. Chan, L. Kim, H. Chen, N. Goyal, D. Chung, L. Liu, Y. Su, A. Petrushkina, J. Shen, A. Joulin, Y. Xu, S. X. Lin, Y. Kulizhskaya, C. Chelba, S. Vasudevan, E. Collins, V. Bashlovkina, T. Lu, D. Fritz, J. Park, Y. Zhou, C. Su, R. Tanburn, M. Sushkov, M. Rasquinha, J. Li, J. Prendki, Y. Li, P. LV, S. Sharma, H. Fitoussi, H. Huang, A. Dai, P. Dao, M. Burrows, H. Prior, D. Qin, G. Pundak, L. L. Sjoesund, A. Khurshudov, Z. Zhu, A. Webson, E. Kemp, T. Tan, S. Agrawal, S. Sargsyan, L. Cheng, J. Stephan, T. Kwiatkowski, D. Reid, A. Byravan, A. H. Michaely, N. Heess, L. Zhou, S. Goenka, V. Carpenter, A. Levskaya, B. Wang, R. Roberts, R. Leblond, S. Chikkerur, S. Ginzburg, M. Chang, R. Riachi, Chuqiao, Xu, Z. Borsos, M. Pliskin, J. Pawar, M. Lustman, H. Kirkwood, A. Anand, A. Chaudhary, N. Kalb, K. Milan, S. Augenstein, A. Goldie, L. Prince, K. Raman, Y. Sun, V. Xia, A. Cohen, Z. Huo, J. Camp, S. Ellis, L. Zilka, D. V. Torres, L. Patel, S. Arora, B. Chan, J. Adler, K. Ayoub, J. Liang, F. Jamil, J. Jiang, S. Baumgartner, H. Sun, Y. Karov, Y. Akulov, H. Zheng, I. Cai, C. Fantacci, J. Rubin, A. R. Acha, M. Wang, N. D’Souza, R. Sathyanarayana, S. Dai, S. Rowe, A. Simanovsky, O. Goldman, Y. Kuang, X. Pan, A. Rosenberg, T. Rojas-Esponda, P. Dutta, A. Zeng, I. Jurenka, G. Farquhar, Y. Bansal, S. Iqbal, B. Roelofs, G. Joung, P. Beak, C. Ryu, R. Poplin, Y. Wu, J. Alayrac, S. Buthpitiya, O. Ronneberger, C. Habtegebriel, W. Li, P. Cavallaro, A. Wei, G. Bensky, T. Denk, H. Ganapathy, J. Stanway, P. Joshi, F. Bertolini, J. Lo, O. Ma, Z. Charles, G. Sampemane, H. Sahni, X. Chen, H. Askham, D. Gaddy, P. Young, J. Tan, M. Eyal, A. Bražinskas, L. Zhong, Z. Wu, M. Epstein, K. Bailey, A. Hard, K. Lee, S. Goldshtein, A. Ruiz, M. Badawi, M. Lochbrunner, J. Kearns, A. Brown, F. Pardo, T. Weber, H. Yang, P. Jiang, B. Akin, Z. Fu, M. Wainwright, C. Zou, M. Gaba, P. Manzagol, W. Kan, Y. Song, K. Zainullina, R. Lin, J. Ko, S. Deshmukh, A. Jindal, J. Svensson, D. Tyam, H. Zhao, C. Kaeser-Chen, S. Baird, P. Moradi, J. Hall, Q. Guo, V. Tsang, B. Liang, F. Pereira, S. Ganesh, I. Korotkov, J. Adamek, S. Thiagarajan, V. Tran, C. Chen, C. Tar, S. Jain, I. Dasgupta, T. Bilal, D. Reitter, K. Zhao, G. Vezzani, Y. Gehman, P. Mehta, L. Beltrone, X. Dotiwalla, S. Guadarrama, Z. Abbas, S. Karp, P. Georgiev, C. Ferng, M. Brockschmidt, L. Peng, C. Hirnschall, V. Verma, Y. Bi, Y. Xiao, A. Dabush, K. Xu, P. Wallis, R. Parker, Q. Wang, Y. Xu, I. Safarli, D. Tewari, Y. Zhang, S. Kim, A. Gesmundo, M. Thomas, S. Levi, A. Chowdhury, K. Rao, P. Garst, S. Conway-Rahman, H. Ran, K. McKinney, Z. Xiao, W. Yu, R. Agrawal, A. Stjerngren, C. Ionescu, J. Chen, V. Sharma, J. Chiu, F. Liu, K. Franko, C. Sanford, X. Cai, P. Michel, S. Ganapathy, J. Labanowski, Z. Garrett, B. Vargas, S. Sun, B. Gale, T. Buschmann, G. Desjardins, N. Ghelani, P. Jain, M. Verma, C. Asawaroengchai, J. Eisenschlos, J. Harlalka, H. Kazawa, D. Metzler, J. Howland, Y. Jian, J. Ades, V. Shah, T. Gangwani, S. Lee, R. Ring, S. M. Hernandez, D. Reich, A. Sinha, A. Sathe, J. Kovac, A. Gill, A. Kannan, A. D’olimpio, M. Sevenich, J. Whang, B. Kim, K. C. Sim, J. Chen, J. Zhang, S. Lall, Y. Matias, B. Jia, A. Friesen, S. Nasso, A. Thapliyal, B. Perozzi, T. Yu, A. Shekhawat, S. Huda, P. Grabowski, E. Wang, A. Sreevatsa, H. Dib, M. Hassen, P. Schuh, V. Milutinovic, C. Welty, M. Quinn, A. Shah, B. Wang, G. Barth-Maron, J. Frye, N. Axelsson, T. Zhu, Y. Ma, I. Giannoumis, H. Sedghi, C. Ye, Y. Luan, K. Aydin, B. Chandra, V. Sampathkumar, R. Huang, V. Lavrenko, A. Eleryan, Z. Hong, S. Hansen, S. M. Carthy, B. Samanta, D. Ćevid, X. Wang, F. Li, M. Voznesensky, M. Hoffman, A. Terzis, V. Sehwag, G. Fidel, L. He, M. Cai, Y. He, A. Feng, M. Nikoltchev, S. Phatale, J. Chase, R. Lawton, M. Zhang, T. Ouyang, M. Tragut, M. H. Manshadi, A. Narayanan, J. Shen, X. Gao, T. Bolukbasi, N. Roy, X. Li, D. Golovin, L. Panait, Z. Qin, G. Han, T. Anthony, S. Kudugunta, V. Patraucean, A. Ray, X. Chen, X. Yang, T. Bhatia, P. Talluri, A. Morris, A. Ražnatović, B. Brownfield, J. An, S. Peng, P. Kane, C. Zheng, N. Duduta, J. Kessinger, J. Noraky, S. Liu, K. Rong, P. Veličković, K. Rush, A. Goldin, F. Wei, S. M. R. Garlapati, C. Pantofaru, O. Kwon, J. Ni, E. Noland, J. D. Trapani, F. Beaufays, A. G. Roy, Y. Chow, A. Turker, G. Cideron, L. Mei, J. Clark, Q. Dou, M. Bošnjak, R. Leith, Y. Du, A. Yazdanbakhsh, M. Nasr, C. Kwak, S. S. Sheth, A. Kaskasoli, A. Anand, B. Lakshminarayanan, S. Jerome, D. Bieber, C. Chu, A. Senges, T. Shen, M. Sridhar, N. Ndebele, B. Beyret, S. Mohamed, M. Chen, M. Freitag, J. Guo, L. Liu, P. Roit, H. Chen, S. Yan, T. Stone, J. Co-Reyes, J. Cole, S. Scellato, S. Azizi, H. Hashemi, A. Jin, A. Iyer, M. Valentine, A. György, A. Ahuja, D. H. Diaz, C. Lee, N. Clement, W. Kong, D. Garmon, I. Watts, K. Bhatia, K. Gupta, M. Miecnikowski, H. Vallet, A. Taly, E. Loper, S. Joshi, J. Atwood, J. Chick, M. Collier, F. Iliopoulos, R. Trostle, B. Gunel, R. Leal-Cavazos, A. M. Hrafnkelsson, M. Guzman, X. Ju, A. Forbes, J. Emond, K. Chauhan, B. Caine, L. Xiao, W. Zeng, A. Moufarek, D. Murphy, M. Meng, N. Gupta, F. Riedel, A. Das, E. Lawal, S. Narayan, T. Sosea, J. Swirhun, L. Friso, B. Neyshabur, J. Lu, S. Girgin, M. Wunder, E. Yvinec, A. Pyne, V. Carbune, S. Rijhwani, Y. Guo, T. Doshi, A. Briukhov, M. Bain, A. Hitron, X. Wang, A. Gupta, K. Chen, C. Du, W. Zhang, D. Shah, A. Akula, M. Dylla, A. Kachra, W. Kuo, T. Zou, L. Wang, L. Xu, J. Zhu, J. Snyder, S. Menon, O. Firat, I. Mordatch, Y. Yuan, N. Ponomareva, R. Blevins, L. Moore, W. Wang, P. Chen, M. Scholz, A. Dwornik, J. Lin, S. Li, D. Antognini, T. I, X. Song, M. Miller, U. Kalra, A. Raveret, O. Akerlund, F. Wu, A. Nystrom, N. Godbole, T. Liu, H. DeBalsi, J. Zhao, B. Liu, A. Caciularu, L. Lax, U. Khandelwal, V. Langston, E. Bailey, S. Lattanzi, Y. Wang, N. Kovelamudi, S. Mondal, G. Guruganesh, N. Hua, O. Roval, P. Wesołowski, R. Ingale, J. Halcrow, T. Sohn, C. Angermueller, B. Raad, E. Stickgold, E. Lu, A. Kosik, J. Xie, T. Lillicrap, A. Huang, L. L. Zhang, D. Paulus, C. Farabet, A. Wertheim, B. Wang, R. Joshi, C. Ko, Y. Wu, S. Agrawal, L. Lin, X. Sheng, P. Sung, T. Breland-King, C. Butterfield, S. Gawde, S. Singh, Q. Zhang, R. Apte, S. Shetty, A. Hutter, T. Li, E. Salesky, F. Lebron, J. Kanerva, M. Paganini, A. Nguyen, R. Vallu, J. Peter, S. Velury, D. Kao, J. Hoover, A. Bortsova, C. Bishop, S. Jakobovits, A. Agostini, A. Agarwal, C. Liu, C. Kwong, S. Tavakkol, I. Bica, A. Greve, A. GP, J. Marcus, L. Hou, T. Duerig, R. Moroshko, D. Lacey, A. Davis, J. Amelot, G. Wang, F. Kim, T. Strinopoulos, H. Wan, C. L. Lan, S. Krishnan, H. Tang, P. Humphreys, J. Bai, I. H. Shtacher, D. Machado, C. Pang, K. Burke, D. Liu, R. Aravamudhan, Y. Song, E. Hirst, A. Singh, B. Jou, L. Bai, F. Piccinno, C. K. Fu, R. Alazard, B. Meiri, D. Winter, C. Chen, M. Zhang, J. Heitkaemper, J. Lambert, J. Lee, A. Frömmgen, S. Rogulenko, P. Nair, P. Niemczyk, A. Bulyenov, B. Xu, H. Shemtov, M. Zadimoghaddam, S. Toropov, M. Wirth, H. Dai, S. Gollapudi, D. Zheng, A. Kurakin, C. Lee, K. Bullard, N. Serrano, I. Balazevic, Y. Li, J. Schalkwyk, M. Murphy, M. Zhang, K. Sequeira, R. Datta, N. Agrawal, C. Sutton, N. Attaluri, M. Chiang, W. Farhan, G. Thornton, K. Lin, T. Choma, H. Nguyen, K. Dasgupta, D. Robinson, I. Comşa, M. Riley, A. Pillai, B. Mustafa, B. Golan, A. Zandieh, J. Lespiau, B. Porter, D. Ross, S. Rajayogam, M. Agarwal, S. Venugopalan, B. Shahriari, Q. Yan, H. Xu, T. Tobin, P. Dubov, H. Shi, A. Recasens, A. Kovsharov, S. Borgeaud, L. Dery, S. Vasanth, E. Gribovskaya, L. Qiu, M. Mahdieh, W. Skut, E. Nielsen, C. Zheng, A. Yu, C. G. Bostock, S. Gupta, A. Archer, C. Rawles, E. Davies, A. Svyatkovskiy, T. Tsai, Y. Halpern, C. Reisswig, B. Wydrowski, B. Chang, J. Puigcerver, M. H. Taege, J. Li, E. Schnider, X. Li, D. Dena, Y. Xu, U. Telang, T. Shi, H. Zen, K. Kastner, Y. Ko, N. Subramaniam, A. Kumar, P. Blois, Z. Dai, J. Wieting, Y. Lu, Y. Zeldes, T. Xie, A. Hauth, A. Ţifrea, Y. Li, S. El-Husseini, D. Abolafia, H. Zhou, W. Ding, S. Ghalebikesabi, C. Guía, A. Maksai, Á. Weisz, S. Arik, N. Sukhanov, A. Świetlik, X. Jia, L. Yu, W. Wang, M. Brand, D. Bloxwich, S. Kirmani, Z. Chen, A. Go, P. Sprechmann, N. Kannen, A. Carin, P. Sandhu, I. Edkins, L. Nooteboom, J. Gupta, L. Maggiore, J. Azizi, Y. Pritch, P. Yin, M. Gupta, D. Tarlow, D. Smith, D. Ivanov, M. Babaeizadeh, A. Goel, S. Kambala, G. Chu, M. Kastelic, M. Liu, H. Soltau, A. Stone, S. Agrawal, M. Kim, K. Soparkar, S. Tadepalli, O. Bunyan, R. Soh, A. Kannan, D. Kim, B. J. Chen, A. Halumi, S. Roy, Y. Wang, O. Sercinoglu, G. Gibson, S. Bhatnagar, M. Sano, D. von Dincklage, Q. Ren, B. Mitrevski, M. Olšák, J. She, C. Doersch, Jilei, Wang, B. Liu, Q. Tan, T. Yakar, T. Warkentin, A. Ramirez, C. Lebsack, J. Dillon, R. Mathews, T. Cobley, Z. Wu, Z. Chen, J. Simon, S. Nath, T. Sainath, A. Bendebury, R. Julian, B. Mankalale, D. Ćurko, P. Zacchello, A. R. Brown, K. Sodhia, H. Howard, S. Caelles, A. Gupta, G. Evans, A. Bulanova, L. Katzen, R. Goldenberg, A. Tsitsulin, J. Stanton, B. Schillings, V. Kovalev, C. Fry, R. Shah, K. Lin, S. Upadhyay, C. Li, S. Radpour, M. Maggioni, J. Xiong, L. Haas, J. Brennan, A. Kamath, N. Savinov, A. Nagrani, T. Yacovone, R. Kappedal, K. Andriopoulos, L. Lao, Y. Li, G. Rozhdestvenskiy, K. Hashimoto, A. Audibert, S. Austin, D. Rodriguez, A. Ruoss, G. Honke, D. Karkhanis, X. Xiong, Q. Wei, J. Huang, Z. Leng, V. Premachandran, S. Bileschi, G. Evangelopoulos, T. Mensink, J. Pavagadhi, D. Teplyashin, P. Chang, L. Xue, G. Tanzer, S. Goldman, K. Patel, S. Li, J. Wiesner, I. Zheng, I. Stewart-Binks, J. Han, Z. Li, L. Luo, K. Lenc, M. Lučić, F. Xue, R. Mullins, A. Guseynov, C. Chang, I. Galatzer-Levy, A. Zhang, G. Bingham, G. Hu, A. Hartman, Y. Ma, J. Griffith, A. Irpan, C. Radebaugh, S. Yue, L. Fan, V. Ungureanu, C. Sorokin, H. Teufel, P. Li, R. Anil, D. Paparas, T. Wang, C. Lin, H. Peng, M. Shum, G. Petrovic, D. Brady, R. Nguyen, K. Macherey, Z. Li, H. Singh, M. Yenugula, M. Iinuma, X. Chen, K. Kopparapu, A. Stern, S. Dave, C. Thekkath, F. Perot, A. Kumar, F. Li, Y. Xiao, M. Bilotti, M. H. Bateni, I. Noble, L. Lee, A. Vázquez-Reina, J. Salazar, X. Yang, B. Wang, E. Gruzewska, A. Rao, S. Raghuram, Z. Xu, E. Ben-David, J. Mei, S. Dalmia, Z. Zhang, Y. Liu, G. Bansal, H. Pankov, S. Schwarcz, A. Burns, C. Chan, S. Sanghai, R. Liang, E. Liang, A. He, A. Stuart, A. Narayanan, Y. Zhu, C. Frank, B. Fatemi, A. Sabne, O. Lang, I. Bhattacharya, S. Settle, M. Wang, B. McMahan, A. Tacchetti, L. B. Soares, M. Hadian, S. Cabi, T. Chung, N. Putikhin, G. Li, J. Chen, A. Tarango, H. Michalewski, M. Kazemi, H. Masoom, H. Sheftel, R. Shivanna, A. Vadali, R. Comanescu, D. Reid, J. Moore, A. Neelakantan, M. Sander, J. Herzig, A. Rosenberg, M. Dehghani, J. Choi, M. Fink, R. Hayes, E. Ge, S. Weng, C. Ho, J. Karro, K. Krishna, L. N. Thiet, A. Skerry-Ryan, D. Eppens, M. Andreetto, N. Sarma, S. Bonacina, B. K. Ayan, M. Nawhal, Z. Shan, M. Dusenberry, S. Thakoor, S. Gubbi, D. D. Nguyen, R. Tsarfaty, S. Albanie, J. Mitrović, M. Gandhi, B. Chen, A. Epasto, G. Stephanov, Y. Jin, S. Gehman, A. Amini, J. Weber, F. Behbahani, S. Xu, M. Allamanis, X. Chen, M. Ott, C. Sha, M. Jastrzebski, H. Qi, D. Greene, X. Wu, A. Toki, D. Vlasic, J. Shapiro, R. Kotikalapudi, Z. Shen, T. Saeki, S. Xie, A. Cassirer, S. Bharadwaj, T. Kiyono, S. Bhojanapalli, E. Rosenfeld, S. Ritter, J. Mao, J. G. Oliveira, Z. Egyed, B. Bandemer, E. Parisotto, K. Kinoshita, J. Pluto, P. Maniatis, S. Li, Y. Guo, G. Ghiasi, J. Tarbouriech, S. Chatterjee, J. Jin, Katrina, Xu, J. Palomaki, S. Arnold, M. Sewak, F. Piccinini, M. Sharma, B. Albrecht, S. Purser-haskell, A. Vaswani, C. Chen, M. Wisniewski, Q. Cao, J. Aslanides, N. M. Phu, M. Sieb, L. Agubuzu, A. Zheng, D. Sohn, M. Selvi, A. Andreassen, K. Subudhi, P. Eruvbetine, O. Woodman, T. Mery, S. Krause, X. Ren, X. Ma, J. Luo, D. Chen, W. Fan, H. Griffiths, C. Schuler, A. Li, S. Zhang, J. Sarr, S. Luo, R. Patana, M. Watson, D. Naboulsi, M. Collins, S. Sidhwani, E. Hoogeboom, S. Silver, E. Caveness, X. Zhao, M. Rodriguez, M. Deines, L. Bai, P. Griffin, M. Tagliasacchi, E. Xue, S. R. Babbula, B. Pang, N. Ding, G. Shen, E. Peake, R. Crocker, S. S. Raghvendra, D. Swisher, W. Han, R. Singh, L. Wu, V. Pchelin, T. Munkhdalai, D. Alon, G. Bacon, E. Robles, J. Bulian, M. Johnson, G. Powell, F. T. Ferreira, Y. Li, F. Benzing, M. Velimirović, H. Soyer, W. Kong, Tony, Nguyên, Z. Yang, J. Liu, J. van Amersfoort, D. Gillick, B. Sun, N. Rauschmayr, K. Zhang, S. Zhan, T. Zhou, A. Frolov, C. Yang, D. Vnukov, L. Rouillard, H. Li, A. Mandhane, N. Fallen, R. Venkataraman, C. H. Hu, J. Brennan, J. Lee, J. Chang, M. Sundermeyer, Z. Pan, R. Ke, S. Tong, A. Fabrikant, W. Bono, J. Gu, R. Foley, Y. Mao, M. Delakis, D. Bhaswar, R. Frostig, N. Li, A. Zipori, C. Hope, O. Kozlova, S. Mishra, J. Djolonga, C. Schiff, M. A. Merey, E. Briakou, P. Morgan, A. Wan, A. Hassidim, R. Skerry-Ryan, K. Sengupta, M. Jasarevic, P. Kallakuri, P. Kunkle, H. Brennan, T. Lieber, H. Mansoor, J. Walker, B. Zhang, A. Xie, G. Žužić, A. Chukwuka, A. Druinsky, D. Cho, R. Yao, F. Naeem, S. Butt, E. Kim, Z. Jia, M. Jordan, A. Lelkes, M. Kurzeja, S. Wang, J. Zhao, A. Over, A. Chakladar, M. Prasetya, N. Jha, S. Ganapathy, Y. Cong, P. Shroff, C. Saroufim, S. Miryoosefi, M. Hammad, T. Nasir, W. Xi, Y. Gao, Y. Maeng, B. Hora, C. Cheng, P. Haghani, Y. Lewenberg, C. Lu, M. Matysiak, N. Raisinghani, H. Wang, L. Baugher, R. Sukthankar, M. Giang, J. Schultz, N. Fiedel, M. Chen, C. Lee, T. Dey, H. Zheng, S. Paul, C. Smith, A. Ly, Y. Wang, R. Bansal, B. Perz, S. Ricco, S. Blank, V. Keshava, D. Sharma, M. Chow, K. Lad, K. Jalan, S. Osindero, C. Swanson, J. Scott, A. Ilić, X. Li, S. R. Jonnalagadda, A. S. Soudagar, Y. Xiong, B. Batsaikhan, D. Jarrett, N. Kumar, M. Shah, M. Lawlor, A. Waters, M. Graham, R. May, S. Ramos, S. Lefdal, Z. Cankara, N. Cano, B. O’Donoghue, J. Borovik, F. Liu, J. Grimstad, M. Alnahlawi, K. Tsihlas, T. Hudson, N. Grigorev, Y. Jia, T. Huang, T. P. Igwe, S. Lebedev, X. Tang, I. Krivokon, F. Garcia, M. Tan, E. Jia, P. Stys, S. Vashishth, Y. Liang, B. Venkatraman, C. Gu, A. Kementsietsidis, C. Zhu, J. Jung, Y. Bai, M. J. Hosseini, F. Ahmed, A. Gupta, X. Yuan, S. Ashraf, S. Nigam, G. Vasudevan, P. Awasthi, A. M. Gilady, Z. Mariet, R. Eskander, H. Li, H. Hu, G. Garrido, P. Schlattner, G. Zhang, R. Saxena, P. Dević, K. Muralidharan, A. Murthy, Y. Zhou, M. Choi, A. Wongpanich, Z. Wang, P. Shah, Y. Xu, Y. Huang, S. Spencer, A. Chen, J. Cohan, J. Wang, J. Tompson, J. Wu, R. Haroun, H. Li, B. Huergo, F. Yang, T. Yin, J. Wendt, M. Bendersky, R. Chaabouni, J. Snaider, J. Ferret, A. Jindal, T. Thompson, A. Xue, W. Bishop, S. M. Phal, A. Sharma, Y. Sung, P. Radhakrishnan, M. Shomrat, R. Ingle, R. Vij, J. Gilmer, M. D. Istin, S. Sobell, Y. Lu, E. Nottage, D. Sadigh, J. Willcock, T. Zhang, S. Xu, S. Brown, K. Lee, G. Wang, Y. Zhu, Y. Tay, C. Kim, A. Gutierrez, A. Sharma, Y. Xian, S. Seo, C. Cui, E. Pochernina, C. Baetu, K. Jastrzębski, M. Ly, M. Elhawaty, D. Suh, E. Sezener, P. Wang, N. Yuen, G. Tucker, J. Cai, Z. Yang, C. Wang, A. Muzio, H. Qian, J. Yoo, D. Lockhart, K. R. McKee, M. Guo, M. Mehrotra, A. Mendonça, S. V. Mehta, S. Ben, C. Tekur, J. Mu, M. Zhu, V. Krakovna, H. Lee, A. Maschinot, S. Cevey, H. Choe, A. Bai, H. Srinivasan, D. Gasaway, N. Young, P. Siegler, D. Holtmann-Rice, V. Piratla, K. Baumli, R. Yogev, A. Hofer, H. van Hasselt, S. Grant, Y. Chervonyi, D. Silver, A. Hogue, A. Agarwal, K. Wang, P. Singh, F. Flynn, J. Lipschultz, R. David, L. Bellot, Y. Yang, L. Le, F. Graziano, K. Olszewska, K. Hui, A. Maurya, N. Parotsidis, W. Chen, T. Oguntebi, J. Kelley, A. Baddepudi, J. Mauerer, G. Shaw, A. Siegman, L. Yang, S. Shetty, S. Roy, Y. Song, W. Stokowiec, R. Burnell, O. Savant, R. Busa-Fekete, J. Miao, S. Ghosh, L. MacDermed, P. Lippe, M. Dektiarev, Z. Behrman, F. Mentzer, K. Nguyen, M. Wei, S. Verma, C. Knutsen, S. Dasari, Z. Yan, P. Mitrichev, X. Wang, V. Shejwalkar, J. Austin, S. Sunkara, N. Potti, Y. Virin, C. Wright, G. Liu, O. Riva, E. Pot, G. Kochanski, Q. Le, G. Balasubramaniam, A. Dhar, Y. Liao, A. Bloniarz, D. Shukla, E. Cole, J. Lee, S. Zhang, S. Kafle, S. Vashishtha, P. Mahmoudieh, G. Chen, R. Hoffmann, P. Srinivasan, A. D. Lago, Y. B. Shalom, Z. Wang, M. Elabd, A. Sharma, J. Oh, S. Kothawade, M. Le, M. Monteiro, S. Yang, K. Alarakyia, R. Geirhos, D. Mincu, H. Garnes, H. Kobayashi, S. Mariooryad, K. Krasowiak, Zhixin, Lai, S. Mourad, M. Wang, F. Bu, O. Aharoni, G. Chen, A. Goyal, V. Zubov, A. Bapna, E. Dabir, N. Kothari, K. Lamerigts, N. D. Cao, J. Shar, C. Yew, N. Kulkarni, D. Mahaarachchi, M. Joshi, Z. Zhu, J. Lichtarge, Y. Zhou, H. Muckenhirn, V. Selo, O. Vinyals, P. Chen, A. Brohan, V. Mehta, S. Cogan, R. Wang, T. Geri, W. Ko, W. Chen, F. Viola, K. Shivam, L. Wang, M. C. Elish, R. A. Popa, S. Pereira, J. Liu, R. Koster, D. Kim, G. Zhang, S. Ebrahimi, P. Talukdar, Y. Zheng, P. Poklukar, A. Mikhalap, D. Johnson, A. Vijayakumar, M. Omernick, M. Dibb, A. Dubey, Q. Hu, A. Suman, V. Aggarwal, I. Kornakov, F. Xia, W. Lowe, A. Kolganov, T. Xiao, V. Nikolaev, S. Hemingray, B. Li, J. Iljazi, M. Rybiński, B. Sandhu, P. Lu, T. Luong, R. Jenatton, V. Govindaraj, Hui, Li, G. Dulac-Arnold, W. Park, H. Wang, A. Modi, J. Pouget-Abadie, K. Greller, R. Gupta, R. Berry, P. Ramachandran, J. Xie, L. McCafferty, J. Wang, K. Gupta, H. Lim, B. Bratanič, A. Brock, I. Akolzin, J. Sproch, D. Karliner, D. Kim, A. Goedeckemeyer, N. Shazeer, C. Schmid, D. Calandriello, P. Bhatia, K. Choromanski, C. Montgomery, D. Dua, A. Ramalho, H. King, Y. Gao, L. Nguyen, D. Lindner, D. Pitta, O. Johnson, K. Salama, D. Ardila, M. Han, E. Farnese, S. Odoom, Z. Wang, X. Ding, N. Rink, R. Smith, H. T. Lehri, E. Cohen, N. Vats, T. He, P. Gopavarapu, A. Paszke, M. Patel, W. V. Gansbeke, L. Loher, L. Castro, M. Voitovich, T. von Glehn, N. George, S. Niklaus, Z. Eaton-Rosen, N. Rakićević, E. Jue, S. Perel, C. Zhang, Y. Bahat, A. Pouget, Z. Xing, F. Huot, A. Shenoy, T. Bos, V. Coriou, B. Richter, N. Noy, Y. Wang, S. Ontanon, S. Qin, G. Makarchuk, D. Hassabis, Z. Li, M. Sharma, K. Venkatesan, I. Kemaev, R. Daniel, S. Huang, S. Shah, O. Ponce, Warren, Chen, M. Faruqui, J. Wu, S. Andačić, S. Payrits, D. McDuff, T. Hume, Y. Cao, M. Tessler, Q. Wang, Y. Wang, I. Rendulic, E. Agustsson, M. Johnson, T. Lando, A. Howard, S. G. S. Padmanabhan, M. Daswani, A. Banino, M. Kilgore, J. Heek, Z. Ji, A. Caceres, C. Li, N. Kassner, A. Vlaskin, Z. Liu, A. Grills, Y. Hou, R. Sukkerd, G. Cheon, N. Shetty, L. Markeeva, P. Stanczyk, T. Iyer, Y. Gong, S. Gao, K. Gopalakrishnan, T. Blyth, M. Reynolds, A. Bhoopchand, M. Bilenko, D. Gharibian, V. Zayats, A. Faust, A. Singh, M. Ma, H. Jiao, S. Vijayanarasimhan, L. Aroyo, V. Yadav, S. Chakera, A. Kakarla, V. Meshram, K. Gregor, G. Botea, E. Senter, D. Jia, G. Kovacs, N. Sharma, S. Baur, K. Kang, Y. He, L. Zhuo, M. Kostelac, I. Laish, S. Peng, L. O’Bryan, D. Kasenberg, G. R. Rao, E. Leurent, B. Zhang, S. Stevens, A. Salazar, Y. Zhang, I. Lobov, J. Walker, A. Porter, M. Redshaw, H. Ke, A. Rao, A. Lee, H. Lam, M. Moffitt, J. Kim, S. Qiao, T. Koo, R. Dadashi, X. Song, M. Sundararajan, P. Xu, C. Kawamoto, Y. Zhong, C. Barbu, A. Reddy, M. Verzetti, L. Li, G. Papamakarios, H. Klimczak-Plucińska, M. Cassin, K. Kavukcuoglu, R. Swavely, A. Vaucher, J. Zhao, R. Hemsley, M. Tschannen, H. Ge, G. Menghani, Y. Yu, N. Ha, W. He, X. Wu, M. Song, R. Sterneck, S. Zinke, D. A. Calian, A. Marsden, A. C. Ruiz, M. Hessel, A. Gueta, B. Lee, B. Farris, M. Gupta, Y. Li, M. Saleh, V. Misra, K. Xiao, P. Mendolicchio, G. Buttimore, V. Krayvanova, N. Nayakanti, M. Wiethoff, Y. Pande, A. Mirhoseini, N. Lao, J. Liu, Y. Hua, A. Chen, Y. Malkov, D. Kalashnikov, S. Gupta, K. Audhkhasi, Y. Zhai, S. Kopalle, P. Jain, E. Ofek, C. Meyer, K. Baatarsukh, H. Strejček, J. Qian, J. Freedman, R. Figueira, M. Sokolik, O. Bachem, R. Lin, D. Kharrat, C. Hidey, P. Xu, D. Duan, Y. Li, M. Ersoy, R. Everett, K. Cen, R. Santamaria-Fernandez, A. Taubenfeld, I. Mackinnon, L. Deng, P. Zablotskaia, S. Viswanadha, S. Goel, D. Yates, Y. Deng, P. Choy, M. Chen, A. Sinha, A. Mossin, Y. Wang, A. Szlam, S. Hao, P. K. Rubenstein, M. Toksoz-Exley, M. Aperghis, Y. Zhong, J. Ahn, M. Isard, O. Lacombe, F. Luisier, C. Anastasiou, Y. Kalley, U. Prabhu, E. Dunleavy, S. Bijwadia, J. Mao-Jones, K. Chen, R. Pasumarthi, E. Wood, A. Dostmohamed, N. Hurley, J. Simsa, A. Parrish, M. Pajarskas, M. Harvey, O. Skopek, Y. Kochinski, J. Rey, V. Rieser, D. Zhou, S. J. Lee, T. Acharya, G. Li, J. Jiang, X. Zhang, B. Gipson, E. Mahintorabi, M. Gelmi, N. Khajehnouri, A. Yeh, K. Lee, L. Matthey, L. Baker, T. Pham, H. Fu, A. Pak, P. Gupta, C. Vasconcelos, A. Sadovsky, B. Walker, S. Hsiao, P. Zochbauer, A. Marzoca, N. Velan, J. Zeng, G. Baechler, D. Driess, D. Jain, Y. Huang, L. Tao, J. Maggs, N. Levine, J. Schneider, E. Gemzer, S. Petit, S. Han, Z. Fisher, D. Zelle, C. Biles, E. Ie, A. Fadeeva, C. Liu, J. V. Franco, A. Collister, H. Zhang, R. Wang, R. Zhao, L. Kieliger, K. Shuster, R. Zhu, B. Gong, L. Chan, R. Sun, S. Basu, R. Zimmermann, J. Hayes, A. Bapna, J. Snoek, W. Yang, P. Datta, J. A. Abdallah, K. Kilgour, L. Li, S. Mah, Y. Jun, M. Rivière, A. Karmarkar, T. Spalink, T. Huang, L. Gonzalez, D. Tran, A. Nowak, J. Palowitch, M. Chadwick, E. Talius, H. Mehta, T. Sellam, P. Fränken, M. Nicosia, K. He, A. Kini, D. Amos, S. Basu, H. Jobe, E. Shaw, Q. Xu, C. Evans, D. Ikeda, C. Yan, L. Jin, L. Wang, S. Yadav, I. Labzovsky, R. Sampath, A. Ma, C. Schumann, A. Siddhant, R. Shah, J. Youssef, R. Agarwal, N. Dabney, A. Tonioni, M. Ambar, J. Li, I. Guyon, B. Li, D. Soergel, B. Fang, G. Karadzhov, C. Udrescu, T. Trinh, V. Raunak, S. Noury, D. Guo, S. Gupta, M. Finkelstein, D. Petek, L. Liang, G. Billock, P. Sun, D. Wood, Y. Song, X. Yu, T. Matejovicova, R. Cohen, K. Andra, D. D’Ambrosio, Z. Deng, V. Nallatamby, E. Songhori, R. Dangovski, A. Lampinen, P. Botadra, A. Hillier, J. Cao, N. Baddi, A. Kuncoro, T. Yoshino, A. Bhagatwala, M. Ranzato, R. Schaeffer, T. Liu, S. Ye, O. Sarvana, J. Nham, C. Kuang, I. Gao, J. Baek, S. Mittal, A. Wahid, A. Gergely, B. Ni, J. Feldman, C. Muir, P. Lamblin, W. Macherey, E. Dyer, L. Kilpatrick, V. Campos, M. Bhutani, S. Fort, Y. Ahmad, A. Severyn, K. Chatziprimou, O. Ferludin, M. Dimarco, A. Kusupati, J. Heyward, D. Bahir, K. Villela, K. Millican, D. Marcus, S. Bahargam, C. Unlu, N. Roth, Z. Wei, S. Gopal, D. Ghoshal, E. Lee, S. Lin, J. Lees, D. Lee, A. Hosseini, C. Fan, S. Neel, M. Wu, Y. Altun, H. Cai, E. Piqueras, J. Woodward, A. Bissacco, S. Haykal, M. Bordbar, P. Sundaram, S. Hodkinson, D. Toyama, G. Polovets, A. Myers, A. Sinha, T. Levinboim, K. Krishnakumar, R. Chhaparia, T. Sholokhova, N. B. Gundavarapu, G. Jawahar, H. Qureshi, J. Hu, N. Momchev, M. Rahtz, R. Wu, A. P. S, K. Dhamdhere, M. Guo, U. Gupta, A. Eslami, M. Schain, M. Blokzijl, D. Welling, D. Orr, L. Bolelli, N. Perez-Nieves, M. Sirotenko, A. Prasad, A. Kar, B. D. B. Pigem, T. Terzi, G. Weisz, D. Ghosh, A. Mavalankar, D. Madeka, K. Daugaard, H. Adam, V. Shah, D. Berman, M. Tran, S. Baker, E. Andrejczuk, G. Chole, G. Raboshchuk, M. Mirzazadeh, T. Kagohara, S. Wu, C. Schallhart, B. Orlando, C. Wang, A. Rrustemi, H. Xiong, H. Liu, A. Vezer, N. Ramsden, S. Chang, S. Mudgal, Y. Li, N. Vieillard, Y. Hoshen, F. Ahmad, A. Slone, A. Hua, N. Potikha, M. Rossini, J. Stritar, S. Prakash, Z. Wang, X. Dong, A. Nazari, E. Nehoran, K. Tekelioglu, Y. Li, K. Badola, T. Funkhouser, Y. Li, V. Yerram, R. Ganeshan, D. Formoso, K. Langner, T. Shi, H. Li, Y. Yamamori, A. Panda, A. Saade, A. S. Scarpati, C. Breaux, C. Carey, Z. Zhou, C. Hsieh, S. Bridgers, A. Butryna, N. Gupta, V. Tulsyan, S. Woo, E. Eltyshev, W. Grathwohl, C. Parks, S. Benjamin, R. Panigrahy, S. Dodhia, D. D. Freitas, C. Sauer, W. Song, F. Alet, J. Tolins, C. Paduraru, X. Zhou, B. Albert, Z. Zhang, L. Shu, M. Bansal, S. Nguyen, A. Globerson, O. Xiao, J. Manyika, T. Hennigan, R. Rong, J. Matak, A. Bakalov, A. Sharma, D. Sinopalnikov, A. Pierson, S. Roller, G. Brown, M. Gao, T. Fukuzawa, A. Ghafouri, K. Vassigh, I. Barr, Z. Wang, A. Korsun, R. Jayaram, L. Ren, T. Zaman, S. Khan, Y. Lunts, D. Deutsch, D. Uthus, N. Katz, M. Samsikova, A. Khalifa, N. Sethi, J. Sun, L. Tang, U. Alon, X. Luo, D. Yu, A. Nayyar, B. Petrini, W. Truong, V. Hellendoorn, N. Chinaev, C. Alberti, W. Wang, J. Hu, V. Mirrokni, A. Balashankar, A. Aharon, A. Mehta, A. Iscen, J. Kready, L. Manning, A. Mohananey, Y. Chen, A. Tripathi, A. Wu, I. Petrovski, D. Hwang, M. Baeuml, S. Chandrakaladharan, Y. Liu, R. Coaguila, M. Chen, S. Ma, P. Tafti, S. Tatineni, T. Spitz, J. Ye, P. Vicol, M. Rosca, A. Puigdomènech, Z. Yahav, S. Ghemawat, H. Lin, P. Kirk, Z. Nabulsi, S. Brin, B. Bohnet, K. Caluwaerts, A. S. Veerubhotla, D. Zheng, Z. Dai, P. Petrov, Y. Xu, R. Mehran, Z. Xu, L. Zintgraf, J. Choi, S. A. Hombaiah, R. Thoppilan, S. Reddi, L. Lew, L. Li, K. Webster, K. Sawhney, L. Lamprou, S. Shakeri, M. Lunayach, J. Chen, S. Bagri, A. Salcianu, Y. Chen, Y. Donchev, C. Magister, S. Nørly, V. Rodrigues, T. Izo, H. Noga, J. Zou, T. Köppe, W. Zhou, K. Lee, X. Long, D. Eisenbud, A. Chen, C. Schenck, C. M. To, P. Zhong, E. Taropa, M. Truong, O. Levy, D. Martins, Z. Zhang, C. Semturs, K. Zhang, A. Yakubovich, P. Moreno, L. McConnaughey, D. Lu, S. Redmond, L. Weerts, Y. Bitton, T. Refice, N. Lacasse, A. Conmy, C. Tallec, J. Odell, H. Forbes-Pollard, A. Socala, J. Hoech, P. Kohli, A. Walton, R. Wang, M. Sazanovich, K. Zhu, A. Kapishnikov, R. Galt, M. Denton, B. Murdoch, C. Sikora, K. Mohamed, W. Wei, U. First, T. McConnell, L. C. Cobo, J. Qin, T. Avrahami, D. Balle, Y. Watanabe, A. Louis, A. Kraft, S. Ariafar, Y. Gu, E. Rives, C. Yoon, A. Rusu, J. Cobon-Kerr, C. Hahn, J. Luo, Yuvein, Zhu, N. Ahuja, R. Benenson, R. L. Kaufman, H. Yu, L. Hightower, J. Zhang, D. Ni, L. A. Hendricks, G. Wang, G. Yona, L. Jain, P. Barrio, S. Bhupatiraju, S. Velusamy, A. Dafoe, S. Riedel, T. Thomas, Z. Yuan, M. Bellaiche, S. Panthaplackel, K. Kloboves, S. Jauhari, C. Akbulut, T. Davchev, E. Gladchenko, D. Madras, A. Chuklin, T. Hill, Q. Yuan, M. Madhavan, L. Leonhard, D. Scandinaro, Q. Chen, N. Niu, A. Douillard, B. Damoc, Y. Onoe, F. Pedregosa, F. Bertsch, C. Leichner, J. Pagadora, J. Malmaud, S. Ponda, A. Twigg, O. Duzhyi, J. Shen, M. Wang, R. Garg, J. Chen, U. Evci, J. Lee, L. Liu, K. Kojima, M. Yamaguchi, A. Rajendran, A. Piergiovanni, V. K. Rajendran, M. Fornoni, G. Ibagon, H. Ragan, S. M. Khan, J. Blitzer, A. Bunner, G. Sun, T. Kosakai, S. Lundberg, N. Elue, K. Guu, S. Park, J. Park, A. Narayanaswamy, C. Wu, J. Mudigonda, T. Cohn, H. Mu, R. Kumar, L. Graesser, Y. Zhang, R. Killam, V. Zhuang, M. Giménez, W. A. Jishi, R. Ley-Wild, A. Zhai, K. Osawa, D. Cedillo, J. Liu, M. Upadhyay, M. Sieniek, R. Sharma, T. Paine, A. Angelova, S. Addepalli, C. Parada, K. Majumder, A. Lamp, S. Kumar, X. Deng, A. Myaskovsky, T. Sabolić, J. Dudek, S. York, F. de Chaumont Quitry, J. Nie, D. Cattle, A. Gunjan, B. Piot, W. Khawaja, S. Bang, S. Wang, S. Khodadadeh, R. R, P. Rawlani, R. Powell, K. Lee, J. Griesser, G. Oh, C. Magalhaes, Y. Li, S. Tokumine, H. N. Vogel, D. Hsu, A. BC, D. Jindal, M. Cohen, Z. Yang, J. Yuan, D. de Cesare, T. Bruguier, J. Xu, M. Roy, A. Jacovi, D. Belov, R. Arya, P. Meadowlark, S. Cohen-Ganor, W. Ye, P. Morris-Suzuki, P. Banzal, G. Song, P. Ponnuramu, F. Zhang, G. Scrivener, S. Zaiem, A. R. Rochman, K. Han, B. Ghazi, K. Lee, S. Drath, D. Suo, A. Girgis, P. Shenoy, D. Nguyen, D. Eck, S. Gupta, L. Yan, J. Carreira, A. Gulati, R. Sang, D. Mirylenka, E. Cooney, E. Chou, M. Ling, C. Fan, B. Coleman, G. Tubone, R. Kumar, J. Baldridge, F. Hernandez-Campos, A. Lazaridou, J. Besley, I. Yona, N. Bulut, Q. Wellens, A. Pierigiovanni, J. George, R. Green, P. Han, C. Tao, G. Clark, C. You, A. Abdolmaleki, J. Fu, T. Chen, A. Chaugule, A. Chandorkar, A. Rahman, W. Thompson, P. Koanantakool, M. Bernico, J. Ren, A. Vlasov, S. Vassilvitskii, M. Kula, Y. Liang, D. Kim, Y. Huang, C. Ye, D. Lepikhin, and W. Helmholz (2025) Gemini 2.5: pushing the frontier with advanced reasoning, multimodality, long context, and next generation agentic capabilities. External Links: 2507.06261, Link Cited by: §1, Table 11, Table 12, Table 1, Table 4, §5.Source
- [13] S. Di, Z. Yu, G. Zhang, H. Li, T. Zhong, H. Cheng, B. Li, W. He, F. Shu, and H. Jiang (2025) Streaming video question-answering with in-context video kv-cache retrieval. External Links: 2503.00540, Link Cited by: §1, Table 11, Table 11, Table 12, Table 12, §2, §4.1, Table 1, Table 1, Table 3, Table 3, Table 3, Table 4, §5, §5.Source
- [14] H. Ebbinghaus (2013) Memory: a contribution to experimental psychology. Annals of neurosciences 20 (4), pp. 155. Cited by: 1st item.
- [15] J. Fei, D. Li, Z. Deng, Z. Wang, G. Liu, and H. Wang (2024) Video-ccam: enhancing video-language understanding with causal cross-attention masks for short and long videos. External Links: 2408.14023, Link Cited by: Table 11, Table 1, Table 4.Source
- [16] C. Fu, Y. Dai, Y. Luo, L. Li, S. Ren, R. Zhang, Z. Wang, C. Zhou, Y. Shen, M. Zhang, P. Chen, Y. Li, S. Lin, S. Zhao, K. Li, T. Xu, X. Zheng, E. Chen, C. Shan, R. He, and X. Sun (2025) Video-mme: the first-ever comprehensive evaluation benchmark of multi-modal llms in video analysis. External Links: 2405.21075, Link Cited by: 3rd item, §2, §4.1.Source
- [17] K. Grauman, A. Westbury, E. Byrne, Z. Chavis, A. Furnari, R. Girdhar, J. Hamburger, H. Jiang, M. Liu, X. Liu, M. Martin, T. Nagarajan, I. Radosavovic, S. K. Ramakrishnan, F. Ryan, J. Sharma, M. Wray, M. Xu, E. Z. Xu, C. Zhao, S. Bansal, D. Batra, V. Cartillier, S. Crane, T. Do, M. Doulaty, A. Erapalli, C. Feichtenhofer, A. Fragomeni, Q. Fu, A. Gebreselasie, C. Gonzalez, J. Hillis, X. Huang, Y. Huang, W. Jia, W. Khoo, J. Kolar, S. Kottur, A. Kumar, F. Landini, C. Li, Y. Li, Z. Li, K. Mangalam, R. Modhugu, J. Munro, T. Murrell, T. Nishiyasu, W. Price, P. R. Puentes, M. Ramazanova, L. Sari, K. Somasundaram, A. Southerland, Y. Sugano, R. Tao, M. Vo, Y. Wang, X. Wu, T. Yagi, Z. Zhao, Y. Zhu, P. Arbelaez, D. Crandall, D. Damen, G. M. Farinella, C. Fuegen, B. Ghanem, V. K. Ithapu, C. V. Jawahar, H. Joo, K. Kitani, H. Li, R. Newcombe, A. Oliva, H. S. Park, J. M. Rehg, Y. Sato, J. Shi, M. Z. Shou, A. Torralba, L. Torresani, M. Yan, and J. Malik (2022) Ego4D: around the world in 3,000 hours of egocentric video. External Links: 2110.07058, Link Cited by: 3rd item, 2nd item.Source
- [18] S. Hu, Y. Tu, X. Han, C. He, G. Cui, X. Long, Z. Zheng, Y. Fang, Y. Huang, W. Zhao, X. Zhang, Z. L. Thai, K. Zhang, C. Wang, Y. Yao, C. Zhao, J. Zhou, J. Cai, Z. Zhai, N. Ding, C. Jia, G. Zeng, D. Li, Z. Liu, and M. Sun (2024) MiniCPM: unveiling the potential of small language models with scalable training strategies. External Links: 2404.06395, Link Cited by: Table 11, Table 1, Table 4.Source
- [19] Y. Hu, S. Liu, Y. Yue, G. Zhang, B. Liu, F. Zhu, J. Lin, H. Guo, S. Dou, Z. Xi, S. Jin, J. Tan, Y. Yin, J. Liu, Z. Zhang, Z. Sun, Y. Zhu, H. Sun, B. Peng, Z. Cheng, X. Fan, J. Guo, X. Yu, Z. Zhou, Z. Hu, J. Huo, J. Wang, Y. Niu, Y. Wang, Z. Yin, X. Hu, Y. Liao, Q. Li, K. Wang, W. Zhou, Y. Liu, D. Cheng, Q. Zhang, T. Gui, S. Pan, Y. Zhang, P. Torr, Z. Dou, J. Wen, X. Huang, Y. Jiang, and S. Yan (2025) Memory in the age of ai agents. External Links: 2512.13564, Link Cited by: §1, 3rd item, §3.2.Source
- [20] Q. Huang, Y. Xiong, A. Rao, J. Wang, and D. Lin (2020) MovieNet: a holistic dataset for movie understanding. External Links: 2007.10937, Link Cited by: 3rd item.Source
- [21] M. Kim, K. Shim, J. Choi, and S. Chang (2024) InfiniPot: infinite context processing on memory-constrained llms. External Links: 2410.01518, Link Cited by: §3.3.Source
- [22] M. Kim, K. Shim, J. Choi, and S. Chang (2025) InfiniPot-v: memory-constrained kv cache compression for streaming video understanding. External Links: 2506.15745, Link Cited by: §3.3, Table 3.Source
- [23] B. Li, Y. Zhang, D. Guo, R. Zhang, F. Li, H. Zhang, K. Zhang, P. Zhang, Y. Li, Z. Liu, and C. Li (2024) LLaVA-onevision: easy visual task transfer. External Links: 2408.03326, Link Cited by: §1, Table 11, Table 11, Table 12, Table 12, §4.1, Table 1, Table 1, Table 3, Table 3, Table 4, §5.Source
- [24] K. Li, Y. Wang, Y. He, Y. Li, Y. Wang, Y. Liu, Z. Wang, J. Xu, G. Chen, P. Luo, L. Wang, and Y. Qiao (2024) MVBench: a comprehensive multi-modal video understanding benchmark. External Links: 2311.17005, Link Cited by: 1st item, §4.1.Source
- [25] Y. Li, J. Niu, Z. Miao, C. Ge, Y. Zhou, Q. He, X. Dong, H. Duan, S. Ding, R. Qian, P. Zhang, Y. Zang, Y. Cao, C. He, and J. Wang (2025) OVO-bench: how far is your video-llms from real-world online video understanding?. External Links: 2501.05510, Link Cited by: 2nd item, §4.1.Source
- [26] J. Lin, H. Yin, W. Ping, Y. Lu, P. Molchanov, A. Tao, H. Mao, J. Kautz, M. Shoeybi, and S. Han (2024) VILA: on pre-training for visual language models. External Links: 2312.07533, Link Cited by: Table 11, Table 1, Table 4.Source
- [27] J. Lin, Z. Fang, C. Chen, Z. Wan, F. Luo, P. Li, Y. Liu, and M. Sun (2024) StreamingBench: assessing the gap for mllms to achieve streaming video understanding. External Links: 2411.03628, Link Cited by: 1st item, §4.1.Source
- [28] H. Liu, C. Li, Y. Li, B. Li, Y. Zhang, S. Shen, and Y. J. Lee (2024) LLaVA-next: improved reasoning, ocr, and world knowledge. Cited by: Table 11, Table 1, Table 4.
- [29] J. Liu, Y. Wang, H. Ma, X. Wu, X. Ma, X. Wei, J. Jiao, E. Wu, and J. Hu (2024) Kangaroo: a powerful video-language model supporting long-context video input. External Links: 2408.15542, Link Cited by: Table 11, Table 4.Source
- [30] K. Mangalam, R. Akshulakov, and J. Malik (2023) EgoSchema: a diagnostic benchmark for very long-form video language understanding. External Links: 2308.09126, Link Cited by: 2nd item, §4.1.Source
- [31] Z. Ning, G. Liu, Q. Jin, W. Ding, M. Guo, and J. Zhao (2025) LiveVLM: efficient online video understanding via streaming-oriented kv cache and retrieval. External Links: 2505.15269, Link Cited by: §1, Table 11, Table 1, §5, §5.Source
- [32] OpenAI, :, A. Hurst, A. Lerer, A. P. Goucher, A. Perelman, A. Ramesh, A. Clark, A. Ostrow, A. Welihinda, A. Hayes, A. Radford, A. Mądry, A. Baker-Whitcomb, A. Beutel, A. Borzunov, A. Carney, A. Chow, A. Kirillov, A. Nichol, A. Paino, A. Renzin, A. T. Passos, A. Kirillov, A. Christakis, A. Conneau, A. Kamali, A. Jabri, A. Moyer, A. Tam, A. Crookes, A. Tootoochian, A. Tootoonchian, A. Kumar, A. Vallone, A. Karpathy, A. Braunstein, A. Cann, A. Codispoti, A. Galu, A. Kondrich, A. Tulloch, A. Mishchenko, A. Baek, A. Jiang, A. Pelisse, A. Woodford, A. Gosalia, A. Dhar, A. Pantuliano, A. Nayak, A. Oliver, B. Zoph, B. Ghorbani, B. Leimberger, B. Rossen, B. Sokolowsky, B. Wang, B. Zweig, B. Hoover, B. Samic, B. McGrew, B. Spero, B. Giertler, B. Cheng, B. Lightcap, B. Walkin, B. Quinn, B. Guarraci, B. Hsu, B. Kellogg, B. Eastman, C. Lugaresi, C. Wainwright, C. Bassin, C. Hudson, C. Chu, C. Nelson, C. Li, C. J. Shern, C. Conger, C. Barette, C. Voss, C. Ding, C. Lu, C. Zhang, C. Beaumont, C. Hallacy, C. Koch, C. Gibson, C. Kim, C. Choi, C. McLeavey, C. Hesse, C. Fischer, C. Winter, C. Czarnecki, C. Jarvis, C. Wei, C. Koumouzelis, D. Sherburn, D. Kappler, D. Levin, D. Levy, D. Carr, D. Farhi, D. Mely, D. Robinson, D. Sasaki, D. Jin, D. Valladares, D. Tsipras, D. Li, D. P. Nguyen, D. Findlay, E. Oiwoh, E. Wong, E. Asdar, E. Proehl, E. Yang, E. Antonow, E. Kramer, E. Peterson, E. Sigler, E. Wallace, E. Brevdo, E. Mays, F. Khorasani, F. P. Such, F. Raso, F. Zhang, F. von Lohmann, F. Sulit, G. Goh, G. Oden, G. Salmon, G. Starace, G. Brockman, H. Salman, H. Bao, H. Hu, H. Wong, H. Wang, H. Schmidt, H. Whitney, H. Jun, H. Kirchner, H. P. de Oliveira Pinto, H. Ren, H. Chang, H. W. Chung, I. Kivlichan, I. O’Connell, I. O’Connell, I. Osband, I. Silber, I. Sohl, I. Okuyucu, I. Lan, I. Kostrikov, I. Sutskever, I. Kanitscheider, I. Gulrajani, J. Coxon, J. Menick, J. Pachocki, J. Aung, J. Betker, J. Crooks, J. Lennon, J. Kiros, J. Leike, J. Park, J. Kwon, J. Phang, J. Teplitz, J. Wei, J. Wolfe, J. Chen, J. Harris, J. Varavva, J. G. Lee, J. Shieh, J. Lin, J. Yu, J. Weng, J. Tang, J. Yu, J. Jang, J. Q. Candela, J. Beutler, J. Landers, J. Parish, J. Heidecke, J. Schulman, J. Lachman, J. McKay, J. Uesato, J. Ward, J. W. Kim, J. Huizinga, J. Sitkin, J. Kraaijeveld, J. Gross, J. Kaplan, J. Snyder, J. Achiam, J. Jiao, J. Lee, J. Zhuang, J. Harriman, K. Fricke, K. Hayashi, K. Singhal, K. Shi, K. Karthik, K. Wood, K. Rimbach, K. Hsu, K. Nguyen, K. Gu-Lemberg, K. Button, K. Liu, K. Howe, K. Muthukumar, K. Luther, L. Ahmad, L. Kai, L. Itow, L. Workman, L. Pathak, L. Chen, L. Jing, L. Guy, L. Fedus, L. Zhou, L. Mamitsuka, L. Weng, L. McCallum, L. Held, L. Ouyang, L. Feuvrier, L. Zhang, L. Kondraciuk, L. Kaiser, L. Hewitt, L. Metz, L. Doshi, M. Aflak, M. Simens, M. Boyd, M. Thompson, M. Dukhan, M. Chen, M. Gray, M. Hudnall, M. Zhang, M. Aljubeh, M. Litwin, M. Zeng, M. Johnson, M. Shetty, M. Gupta, M. Shah, M. Yatbaz, M. J. Yang, M. Zhong, M. Glaese, M. Chen, M. Janner, M. Lampe, M. Petrov, M. Wu, M. Wang, M. Fradin, M. Pokrass, M. Castro, M. O. T. de Castro, M. Pavlov, M. Brundage, M. Wang, M. Khan, M. Murati, M. Bavarian, M. Lin, M. Yesildal, N. Soto, N. Gimelshein, N. Cone, N. Staudacher, N. Summers, N. LaFontaine, N. Chowdhury, N. Ryder, N. Stathas, N. Turley, N. Tezak, N. Felix, N. Kudige, N. Keskar, N. Deutsch, N. Bundick, N. Puckett, O. Nachum, O. Okelola, O. Boiko, O. Murk, O. Jaffe, O. Watkins, O. Godement, O. Campbell-Moore, P. Chao, P. McMillan, P. Belov, P. Su, P. Bak, P. Bakkum, P. Deng, P. Dolan, P. Hoeschele, P. Welinder, P. Tillet, P. Pronin, P. Tillet, P. Dhariwal, Q. Yuan, R. Dias, R. Lim, R. Arora, R. Troll, R. Lin, R. G. Lopes, R. Puri, R. Miyara, R. Leike, R. Gaubert, R. Zamani, R. Wang, R. Donnelly, R. Honsby, R. Smith, R. Sahai, R. Ramchandani, R. Huet, R. Carmichael, R. Zellers, R. Chen, R. Chen, R. Nigmatullin, R. Cheu, S. Jain, S. Altman, S. Schoenholz, S. Toizer, S. Miserendino, S. Agarwal, S. Culver, S. Ethersmith, S. Gray, S. Grove, S. Metzger, S. Hermani, S. Jain, S. Zhao, S. Wu, S. Jomoto, S. Wu, Shuaiqi, Xia, S. Phene, S. Papay, S. Narayanan, S. Coffey, S. Lee, S. Hall, S. Balaji, T. Broda, T. Stramer, T. Xu, T. Gogineni, T. Christianson, T. Sanders, T. Patwardhan, T. Cunninghman, T. Degry, T. Dimson, T. Raoux, T. Shadwell, T. Zheng, T. Underwood, T. Markov, T. Sherbakov, T. Rubin, T. Stasi, T. Kaftan, T. Heywood, T. Peterson, T. Walters, T. Eloundou, V. Qi, V. Moeller, V. Monaco, V. Kuo, V. Fomenko, W. Chang, W. Zheng, W. Zhou, W. Manassra, W. Sheu, W. Zaremba, Y. Patil, Y. Qian, Y. Kim, Y. Cheng, Y. Zhang, Y. He, Y. Zhang, Y. Jin, Y. Dai, and Y. Malkov (2024) GPT-4o system card. External Links: 2410.21276, Link Cited by: Table 11, Table 12, Table 1, Table 4.Source
- [33] C. Packer, S. Wooders, K. Lin, V. Fang, S. G. Patil, I. Stoica, and J. E. Gonzalez (2024) MemGPT: towards llms as operating systems. External Links: 2310.08560, Link Cited by: §3.2.Source
- [34] V. Pătrăucean, L. Smaira, A. Gupta, A. R. Continente, L. Markeeva, D. Banarse, S. Koppula, J. Heyward, M. Malinowski, Y. Yang, C. Doersch, T. Matejovicova, Y. Sulsky, A. Miech, A. Frechette, H. Klimczak, R. Koster, J. Zhang, S. Winkler, Y. Aytar, S. Osindero, D. Damen, A. Zisserman, and J. Carreira (2023) Perception test: a diagnostic benchmark for multimodal video models. External Links: 2305.13786, Link Cited by: 1st item.Source
- [35] R. Qian, S. Ding, X. Dong, P. Zhang, Y. Zang, Y. Cao, D. Lin, and J. Wang (2025) Dispider: enabling video llms with active real-time interaction via disentangled perception, decision, and reaction. External Links: 2501.03218, Link Cited by: Table 11, Table 12, Table 1, Table 4.Source
- [36] A. Shahroudy, J. Liu, T. Ng, and G. Wang (2016) NTU rgb+d: a large scale dataset for 3d human activity analysis. External Links: 1604.02808, Link Cited by: 1st item.Source
- [37] L. Shan, S. Luo, Z. Zhu, Y. Yuan, and Y. Wu (2025) Cognitive memory in large language models. External Links: 2504.02441, Link Cited by: 1st item, 2nd item.Source
- [38] X. Shen, Y. Xiong, C. Zhao, L. Wu, J. Chen, C. Zhu, Z. Liu, F. Xiao, B. Varadarajan, F. Bordes, Z. Liu, H. Xu, H. J. Kim, B. Soran, R. Krishnamoorthi, M. Elhoseiny, and V. Chandra (2024) LongVU: spatiotemporal adaptive compression for long video-language understanding. External Links: 2410.17434, Link Cited by: Table 12.Source
- [39] H. Sun and S. Zeng (2025) Hierarchical memory for high-efficiency long-term reasoning in llm agents. External Links: 2507.22925, Link Cited by: §3.2.Source
- [40] K. Tao, C. Qin, H. You, Y. Sui, and H. Wang (2025) DyCoke: dynamic compression of tokens for fast video large language models. External Links: 2411.15024, Link Cited by: §1, §5.Source
- [41] H. Wang, B. Feng, Z. Lai, M. Xu, S. Li, W. Ge, A. Dehghan, M. Cao, and P. Huang (2025) StreamBridge: turning your offline video large language model into a proactive streaming assistant. External Links: 2505.05467, Link Cited by: §1.Source
- [42] H. Wang, Y. Nie, Y. Ye, D. GuanYu, Y. Wang, S. Li, H. Yu, J. Lu, and C. Huang (2024) Dynamic-vlm: simple dynamic visual token compression for videollm. External Links: 2412.09530, Link Cited by: §5.Source
- [43] P. Wang, S. Bai, S. Tan, S. Wang, Z. Fan, J. Bai, K. Chen, X. Liu, J. Wang, W. Ge, Y. Fan, K. Dang, M. Du, X. Ren, R. Men, D. Liu, C. Zhou, J. Zhou, and J. Lin (2024) Qwen2-vl: enhancing vision-language model’s perception of the world at any resolution. External Links: 2409.12191, Link Cited by: Table 12, Table 1, Table 4.Source
- [44] Z. Wang, S. Yu, E. Stengel-Eskin, J. Yoon, F. Cheng, G. Bertasius, and M. Bansal (2025) VideoTree: adaptive tree-based video representation for llm reasoning on long videos. External Links: 2405.19209, Link Cited by: §1, §5.Source
- [45] H. Xiong, Z. Yang, J. Yu, Y. Zhuge, L. Zhang, J. Zhu, and H. Lu (2025) Streaming video understanding and multi-round interaction with memory-enhanced knowledge. External Links: 2501.13468, Link Cited by: §1.Source
- [46] R. Xu, G. Xiao, Y. Chen, L. He, K. Peng, Y. Lu, and S. Han (2025) StreamingVLM: real-time understanding for infinite video streams. External Links: 2510.09608, Link Cited by: §1, §11, §2, §3.3, §5.Source
- [47] H. Yang, F. Tang, L. Zhao, X. An, M. Hu, H. Li, X. Zhuang, Y. Lu, X. Zhang, A. Swikir, J. He, Z. Ge, and I. Razzak (2025) StreamAgent: towards anticipatory agents for streaming video understanding. External Links: 2508.01875, Link Cited by: §1.Source
- [48] S. Yang, Y. Chen, Z. Tian, C. Wang, J. Li, B. Yu, and J. Jia (2024) VisionZip: longer is better but not necessary in vision language models. External Links: 2412.04467, Link Cited by: §1, §5.Source
- [49] Y. Yang, Z. Zhao, S. N. Shukla, A. Singh, S. K. Mishra, L. Zhang, and M. Ren (2025) StreamMem: query-agnostic kv cache memory for streaming video understanding. External Links: 2508.15717, Link Cited by: §1, §2, Table 3, §5, §5.Source
- [50] L. Yao, Y. Li, Y. Wei, L. Li, S. Ren, Y. Liu, K. Ouyang, L. Wang, S. Li, S. Li, L. Kong, Q. Liu, Y. Zhang, and X. Sun (2025) TimeChat-online: 80% visual tokens are naturally redundant in streaming videos. External Links: 2504.17343, Link Cited by: §1, Table 11, Table 12, Table 1, Table 4, §5.Source
- [51] X. Zeng, K. Qiu, Q. Zhang, X. Li, J. Wang, J. Li, Z. Yan, K. Tian, M. Tian, X. Zhao, Y. Wang, and L. Wang (2025) StreamForest: efficient online video understanding with persistent event memory. External Links: 2509.24871, Link Cited by: §1, Table 11, Table 12, Table 1, Table 4, §5.Source
- [52] H. Zhang, Y. Wang, Y. Tang, Y. Liu, J. Feng, J. Dai, and X. Jin (2024) Flash-vstream: memory-based real-time understanding for long video streams. External Links: 2406.08085, Link Cited by: Table 11, Table 12, Table 1, Table 3.Source
- [53] H. Zhang, Y. Wang, Y. Tang, Y. Liu, J. Feng, J. Dai, and X. Jin (2024) Flash-vstream: memory-based real-time understanding for long video streams. External Links: 2406.08085, Link Cited by: 3rd item, §4.1.Source
- [54] P. Zhang, K. Zhang, B. Li, G. Zeng, J. Yang, Y. Zhang, Z. Wang, H. Tan, C. Li, and Z. Liu (2024) Long context transfer from language to vision. External Links: 2406.16852, Link Cited by: Table 11, Table 1, Table 4.Source
- [55] Y. Zhang, J. Wu, W. Li, B. Li, Z. Ma, Z. Liu, and C. Li (2025) LLaVA-video: video instruction tuning with synthetic data. External Links: 2410.02713, Link Cited by: Table 12, Table 4.Source
We provide more detailed attention visualization in figure 6 under different sliding window sizes, showing that the observed attention patterns consistently hold across varying window lengths, thus confirming the generality of the findings in section 2.
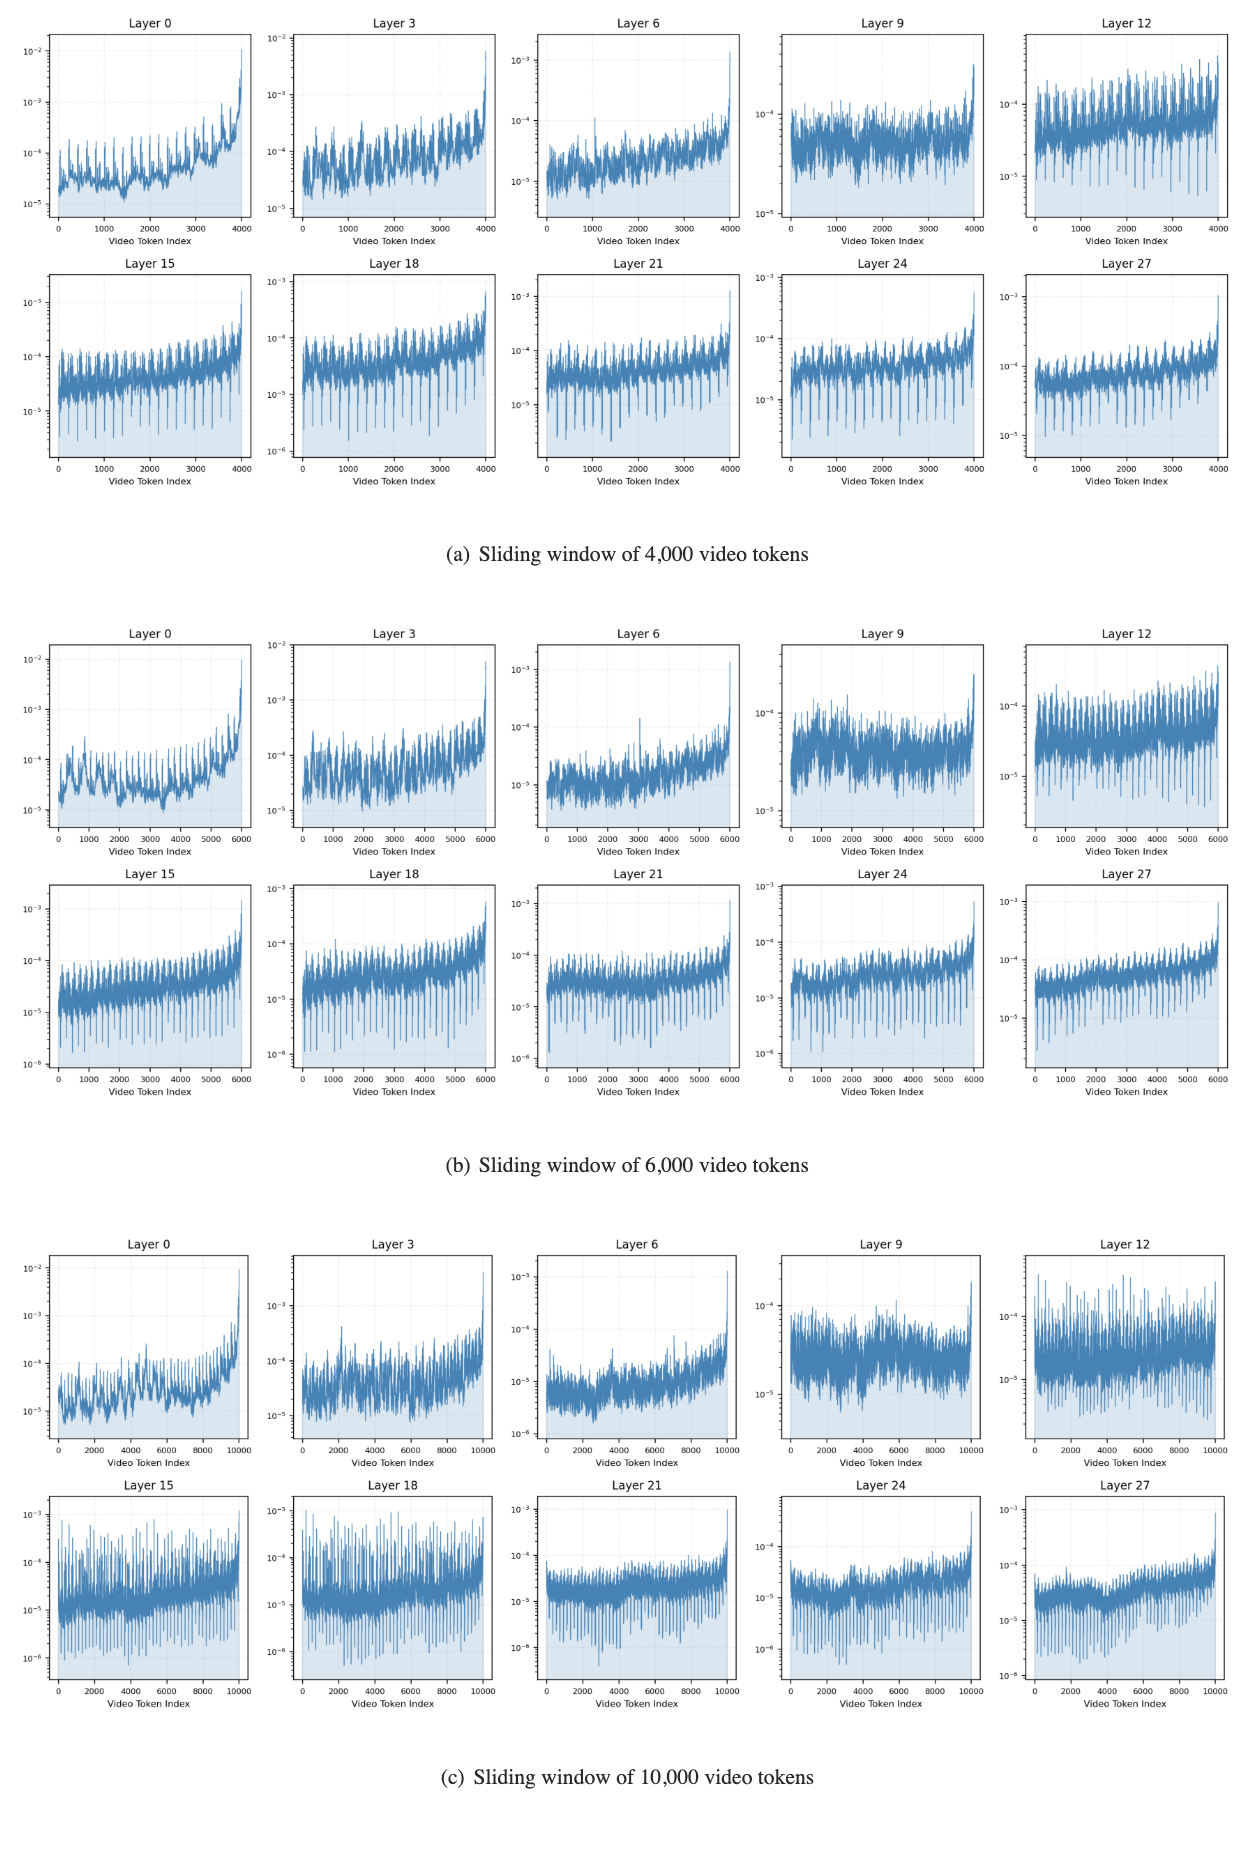
The following two figures show the local and global guidance prompt with and without conversation history to guide the token compression, respectively. For the deep layers, since they primarily focus on frame-level global semantic information, we employ a global guidance prompt as a pseudo-query to extract attention weights of video tokens. In contrast, the middle layers lie in a transition between recency-biased attention and global semantic focus. Therefore, we adopt a hybrid guidance strategy, in which the local guidance prompt and the global guidance prompt are concatenated into a single prompt string to jointly guide the token compression.
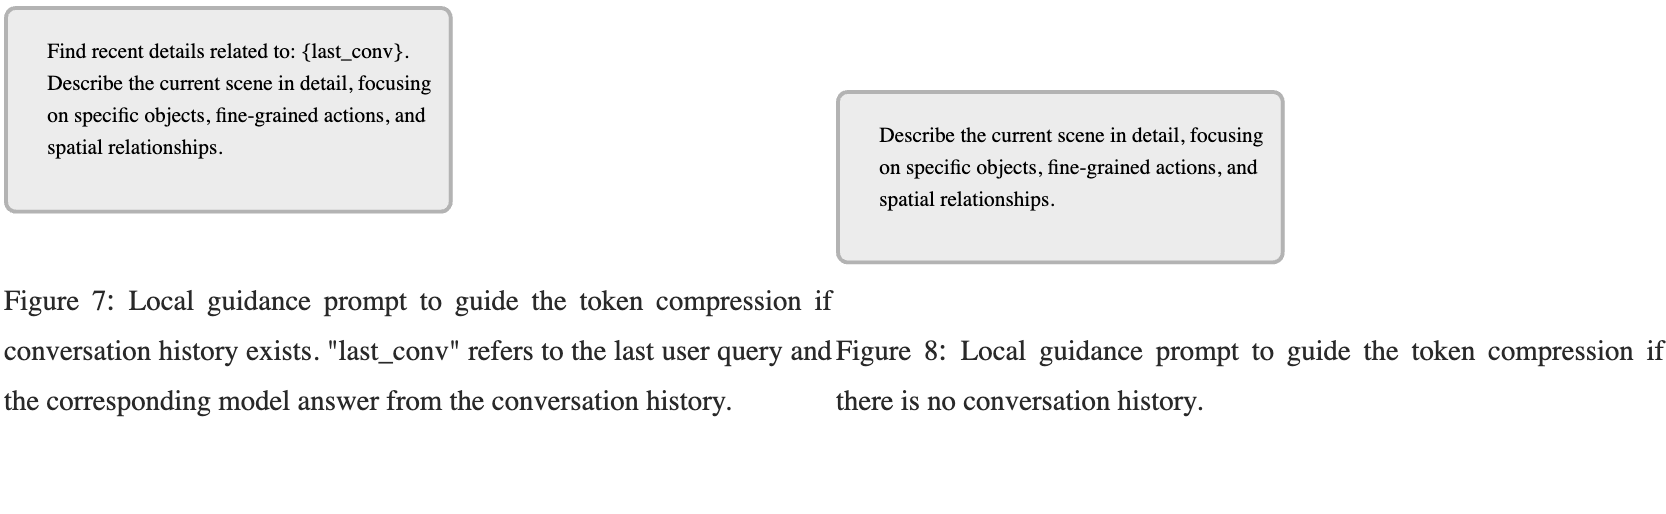
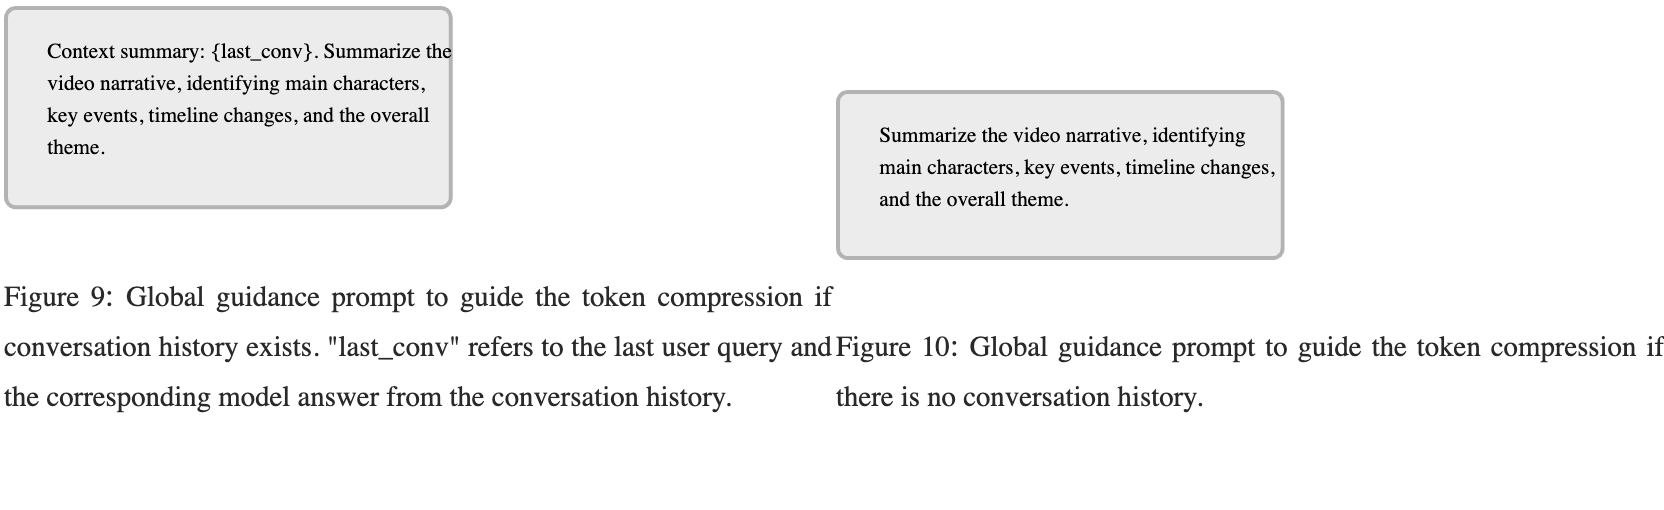
Given that long-term memory tends to remain relatively stable, while short-term memory focuses on diverse perception, we set different for different layer stages:
The ablation study table 6 shows the effectiveness of this hyperparameter choice.
| Benchmark | Duration | #Videos | #QA | Type |
| StreamingBench | 10.1min | 500 | 2,500 | MC |
| OVO-Bench | 5.9 min | 275 | 631 | MC |
| OVO-Bench | 8.8 min | 237 | 837 | MC |
| RVS-Ego | 60 min | 10 | 1,465 | OE |
| RVS-Movie | 30 min | 22 | 1,905 | OE |
| Benchmark | Duration | #Videos | #QA | Type |
| MVBench | 16 s | 3,641 | 4,000 | MC |
| Egoschema | 3 min | 5,063 | 5,063 | MC |
| VideoMME | 17 min | 900 | 2,700 | MC |
Table 10 Key statistics of the offline benchmarks. In the "Type" column, "MC" denotes multiple-choice questions.
View original table
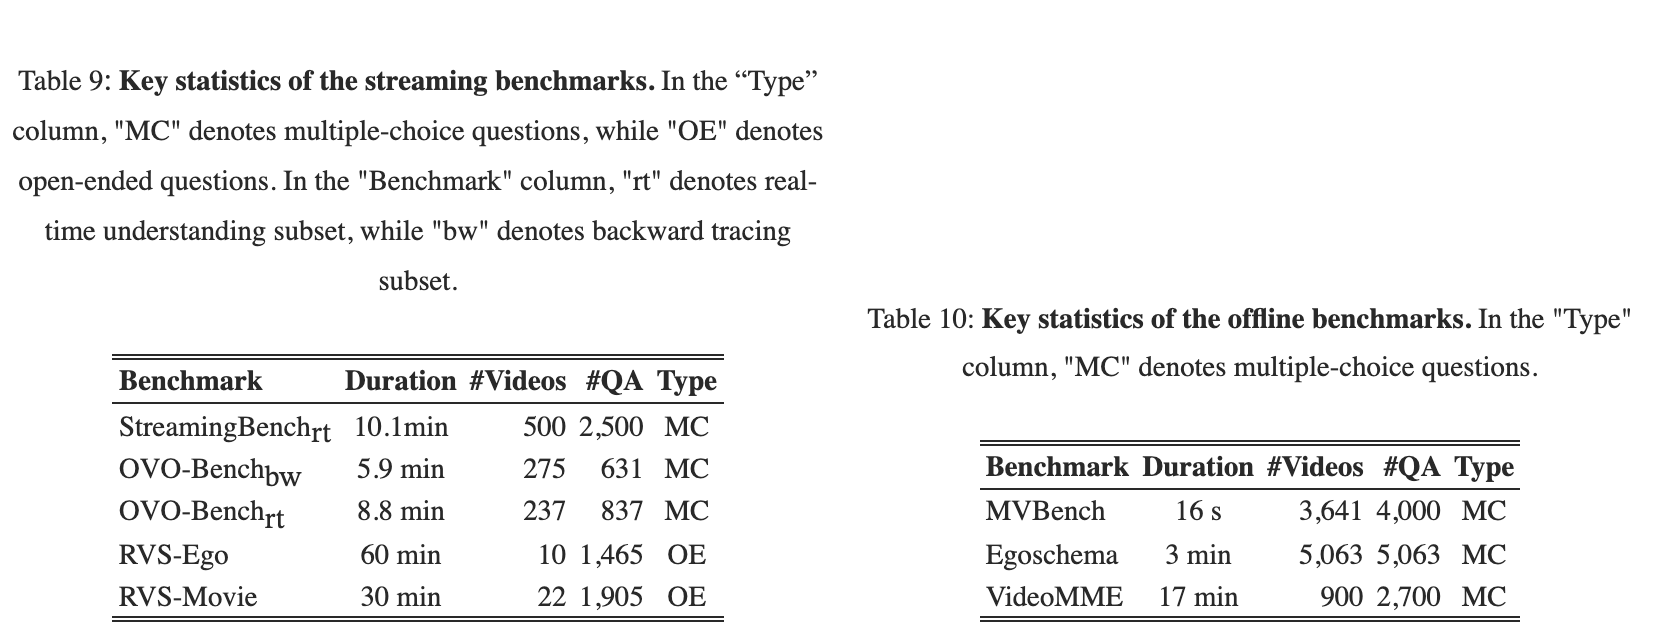
- •
StreamingBench [27] assesses the streaming video understanding capabilities of MLLMs. It evaluates three core aspects: real-time visual understanding, omni-source understanding, and contextual understanding. The Real-Time Visual Understanding subset is the most extensive component, featuring 2,500 questions across 500 videos. It covers 10 tasks, such as object perception and causal reasoning. In this paper, we focus on the Real-Time Visual Understanding subset for evaluation.
- •
OVO-Bench [25] evaluates the online reasoning and temporal awareness of MLLMs, featuring 644 videos with approximately 2,800 fine-grained multiple-choice QA pairs. It organizes 12 tasks into three distinct categories, which are real-time visual perception, backward tracing, and forward active responding. Given that we do not focus on the proactive responding ability of MLLMs in this paper, we exclusively utilize the real-time perception and the backward tracing subsets.
- •
RVS-Ego and RVS-Movie [53] are designed to evaluate the real-time understanding capabilities of models in online streaming scenarios. The datasets consist of 10 long ego-centric videos from the Ego4D dataset [17] and 22 long movie clips from the MovieNet dataset [20] dataset, totaling over 21 hours of video content.
- •
MVBench [24] systematically evaluates the temporal understanding capabilities of MLLMs. It utilizes a novel static-to-dynamic method to define 20 distinct temporal tasks, such as action sequence and moving direction, which cannot be effectively solved with a single frame. The videos are collected from a wide range of datasets, including NTU RGB+D [36], Perception [34], etc.
- •
- •
VideoMME [16] is a full-spectrum, multimodal benchmark designed for the comprehensive evaluation of MLLMs in video analysis. It comprises 900 manually curated videos spanning six primary domains and diverse durations to assess temporal adaptability. The dataset features 2,700 high-quality QA pairs that necessitate processing multimodal inputs, including video frames, subtitles, and audio.
Inspired by StreamingVLM’s strategy of managing positional stability in streaming scenarios [46], we adopt a unified left-compaction re-indexing scheme to eliminate positional gaps introduced by KV-cache pruning while preserving the semantic anchoring of the system prompt. Concretely, system text tokens are kept fixed to provide a stable textual anchor, whereas retained video tokens are re-indexed in a left-compact manner and placed contiguously after the static prefix. To reuse cached key states without re-computation, we further apply a delta-based rotary correction that compensates for the positional displacement.
LLaVA-OV employs standard 1D RoPE, where each token is associated with a scalar positional index . Therefore, we perform left-compaction of the 1D indices: the system prefix positions remain unchanged, while the retained positions of video tokens are reassigned to form a dense contiguous segment immediately following the fixed prefix.
Let offset denote the length of the system prompt prefix tokens, and let
be the sorted set of retained video token positions (excluding the fixed prefix). For a retained video token originally at position , its compacted 1D position is defined as
This mapping removes gaps while preserving the original temporal ordering along the stream, and ensures that the video region occupies a dense range directly after the static text region.
To align cached key states with the updated positions, we avoid re-generating keys and instead apply a rotary delta correction induced by the positional shift. For a cached key vector associated with position and remapped to , we compute
where the relative phase shift is
and denotes the RoPE frequency vector. This update preserves the correctness of attention under the new indexing while enabling direct reuse of the cached KV states.
For Qwen2.5-VL, video tokens are indexed by a 3D M-RoPE coordinate , covering temporal and spatial dimensions. After pruning, the retained video tokens typically occupy sparse coordinates along each dimension . To eliminate the gaps without disturbing the monotonic ordering, we apply dimension-wise left-compaction independently along each axis, while keeping the system token prefix fixed.
Let
denote the sorted set of retained coordinates along dimension . For a token originally located at , its compacted coordinate is defined by its rank within , shifted by the fixed prefix offset:
This procedure yields a dense and contiguous grid for the video tokens placed immediately after the static text region, thereby ensuring positional continuity while preserving the distinct semantic roles of temporal and spatial indices.
As in the 1D case, we reuse cached keys by applying a M-RoPE correction. Given a key associated with
and remapped to
the corrected key is obtained as
with the relative phase shift:
where denotes the concatenation operation along the channel dimension, and represents the rotary frequency vector corresponding to the channel section allocated for dimension .
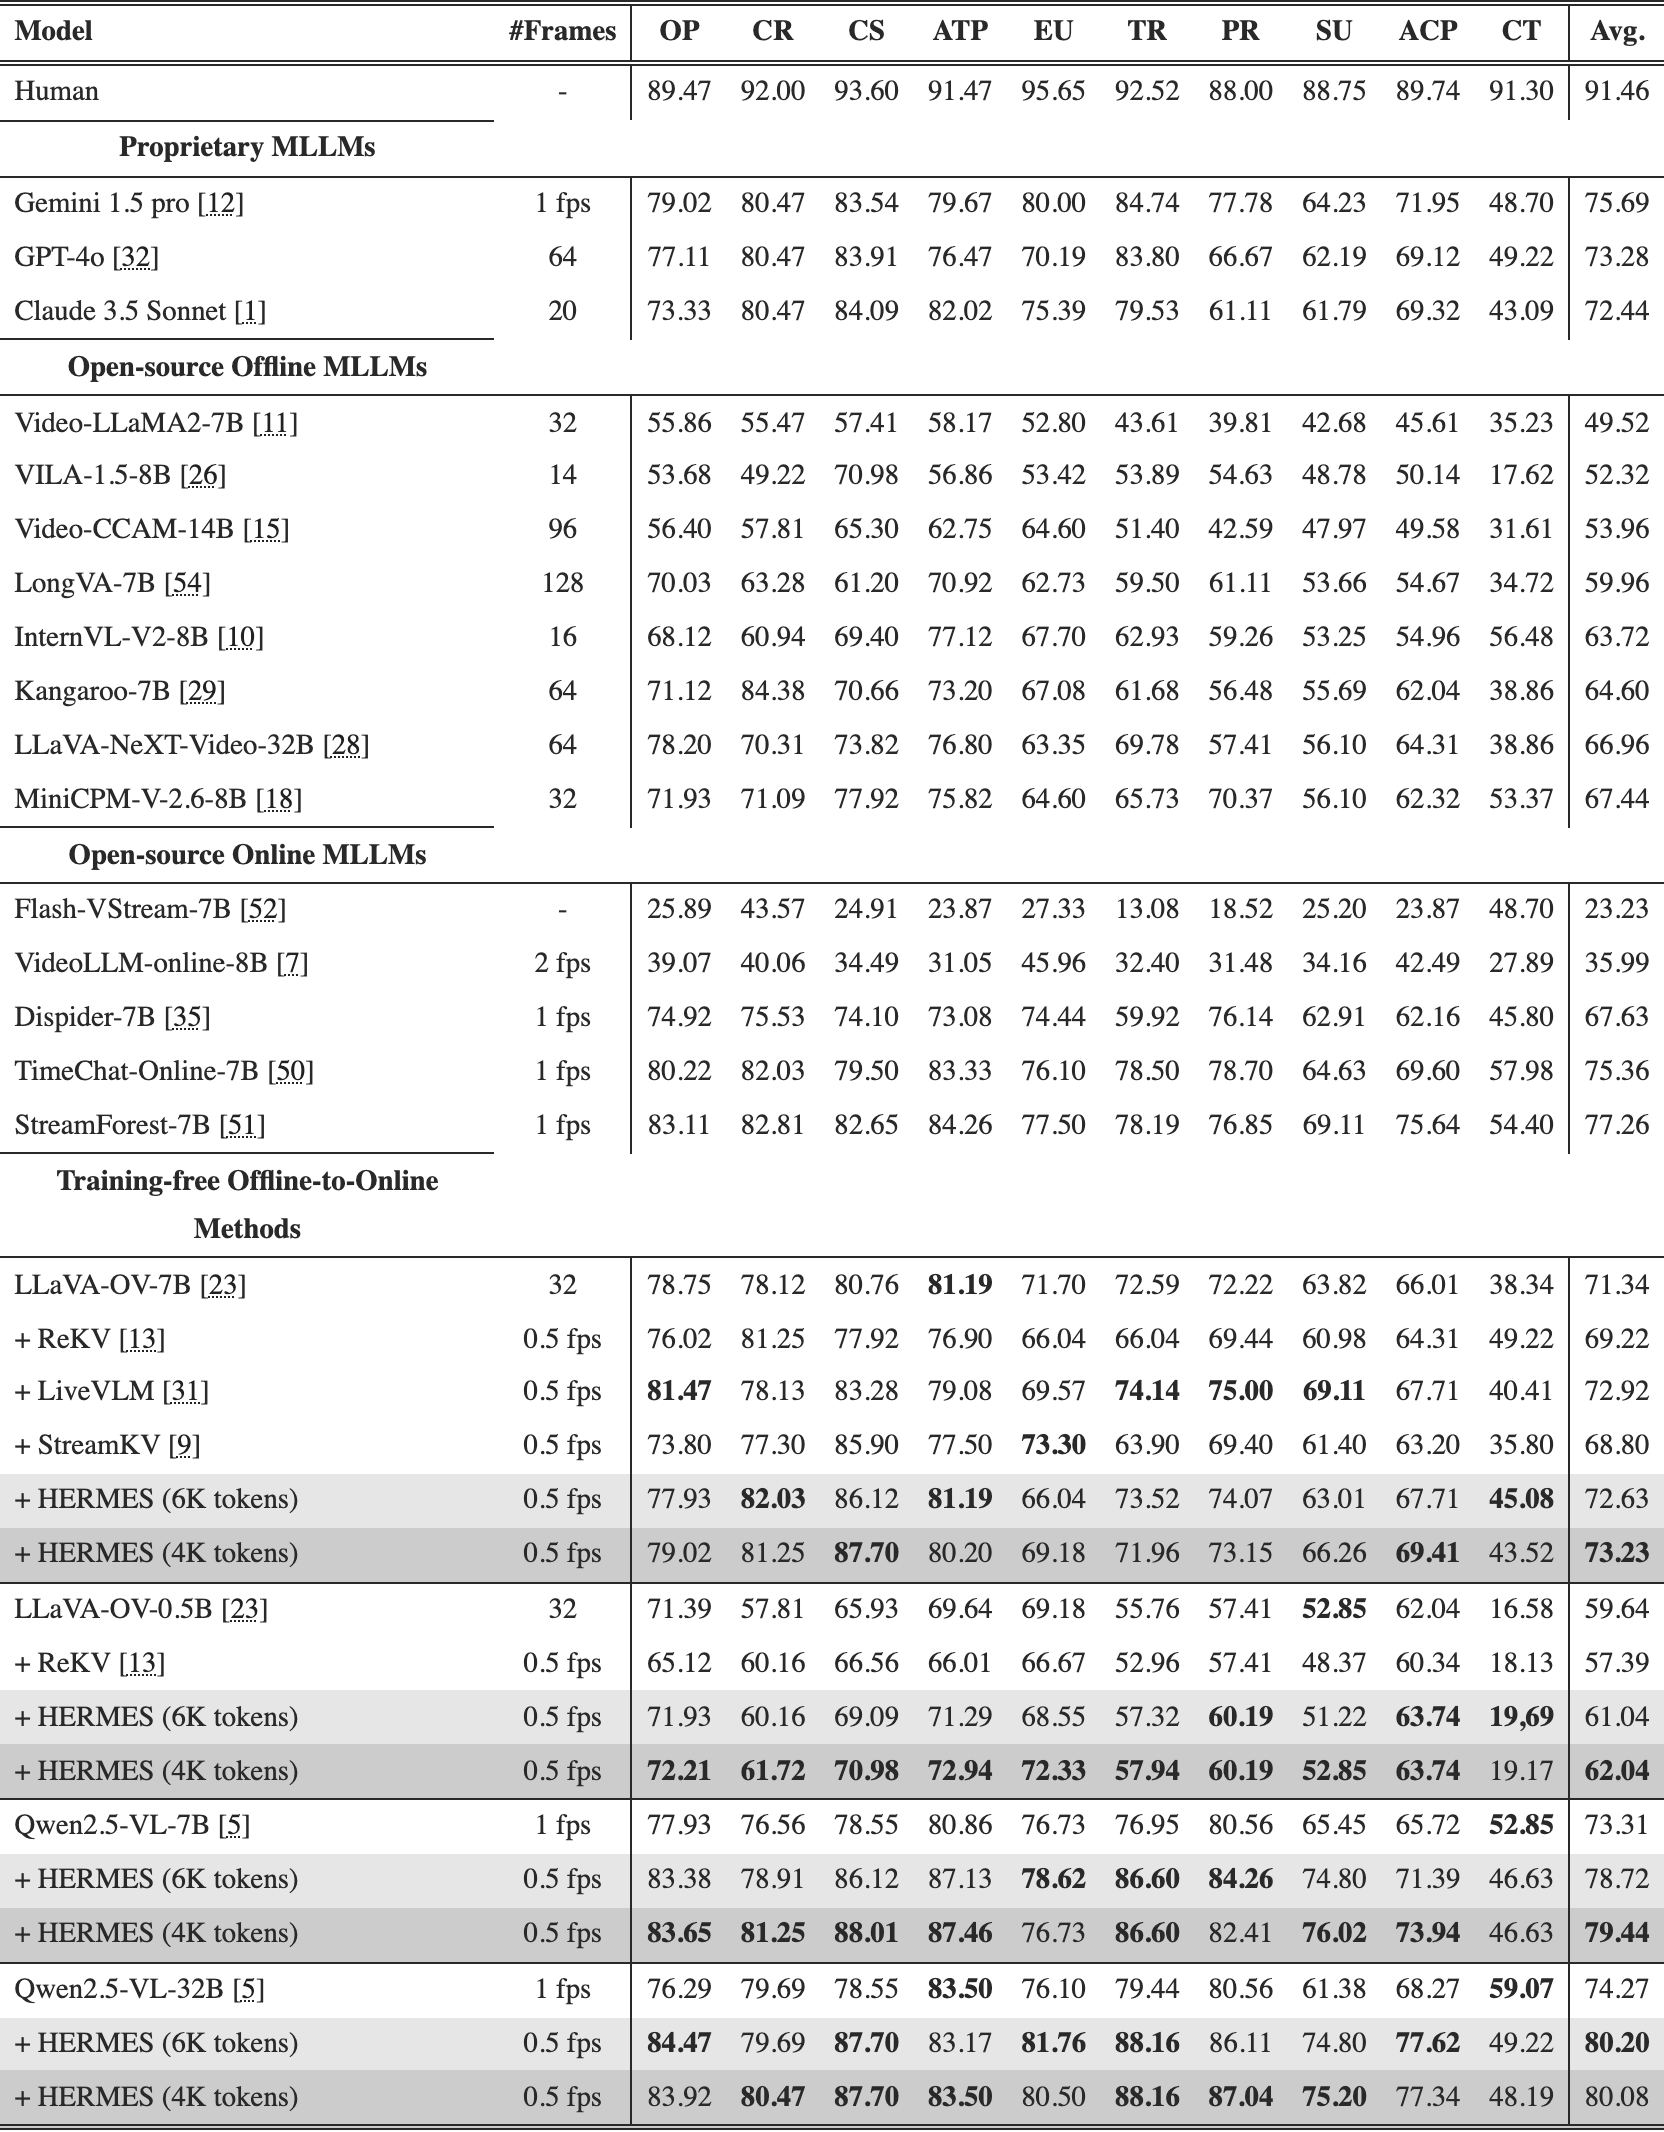
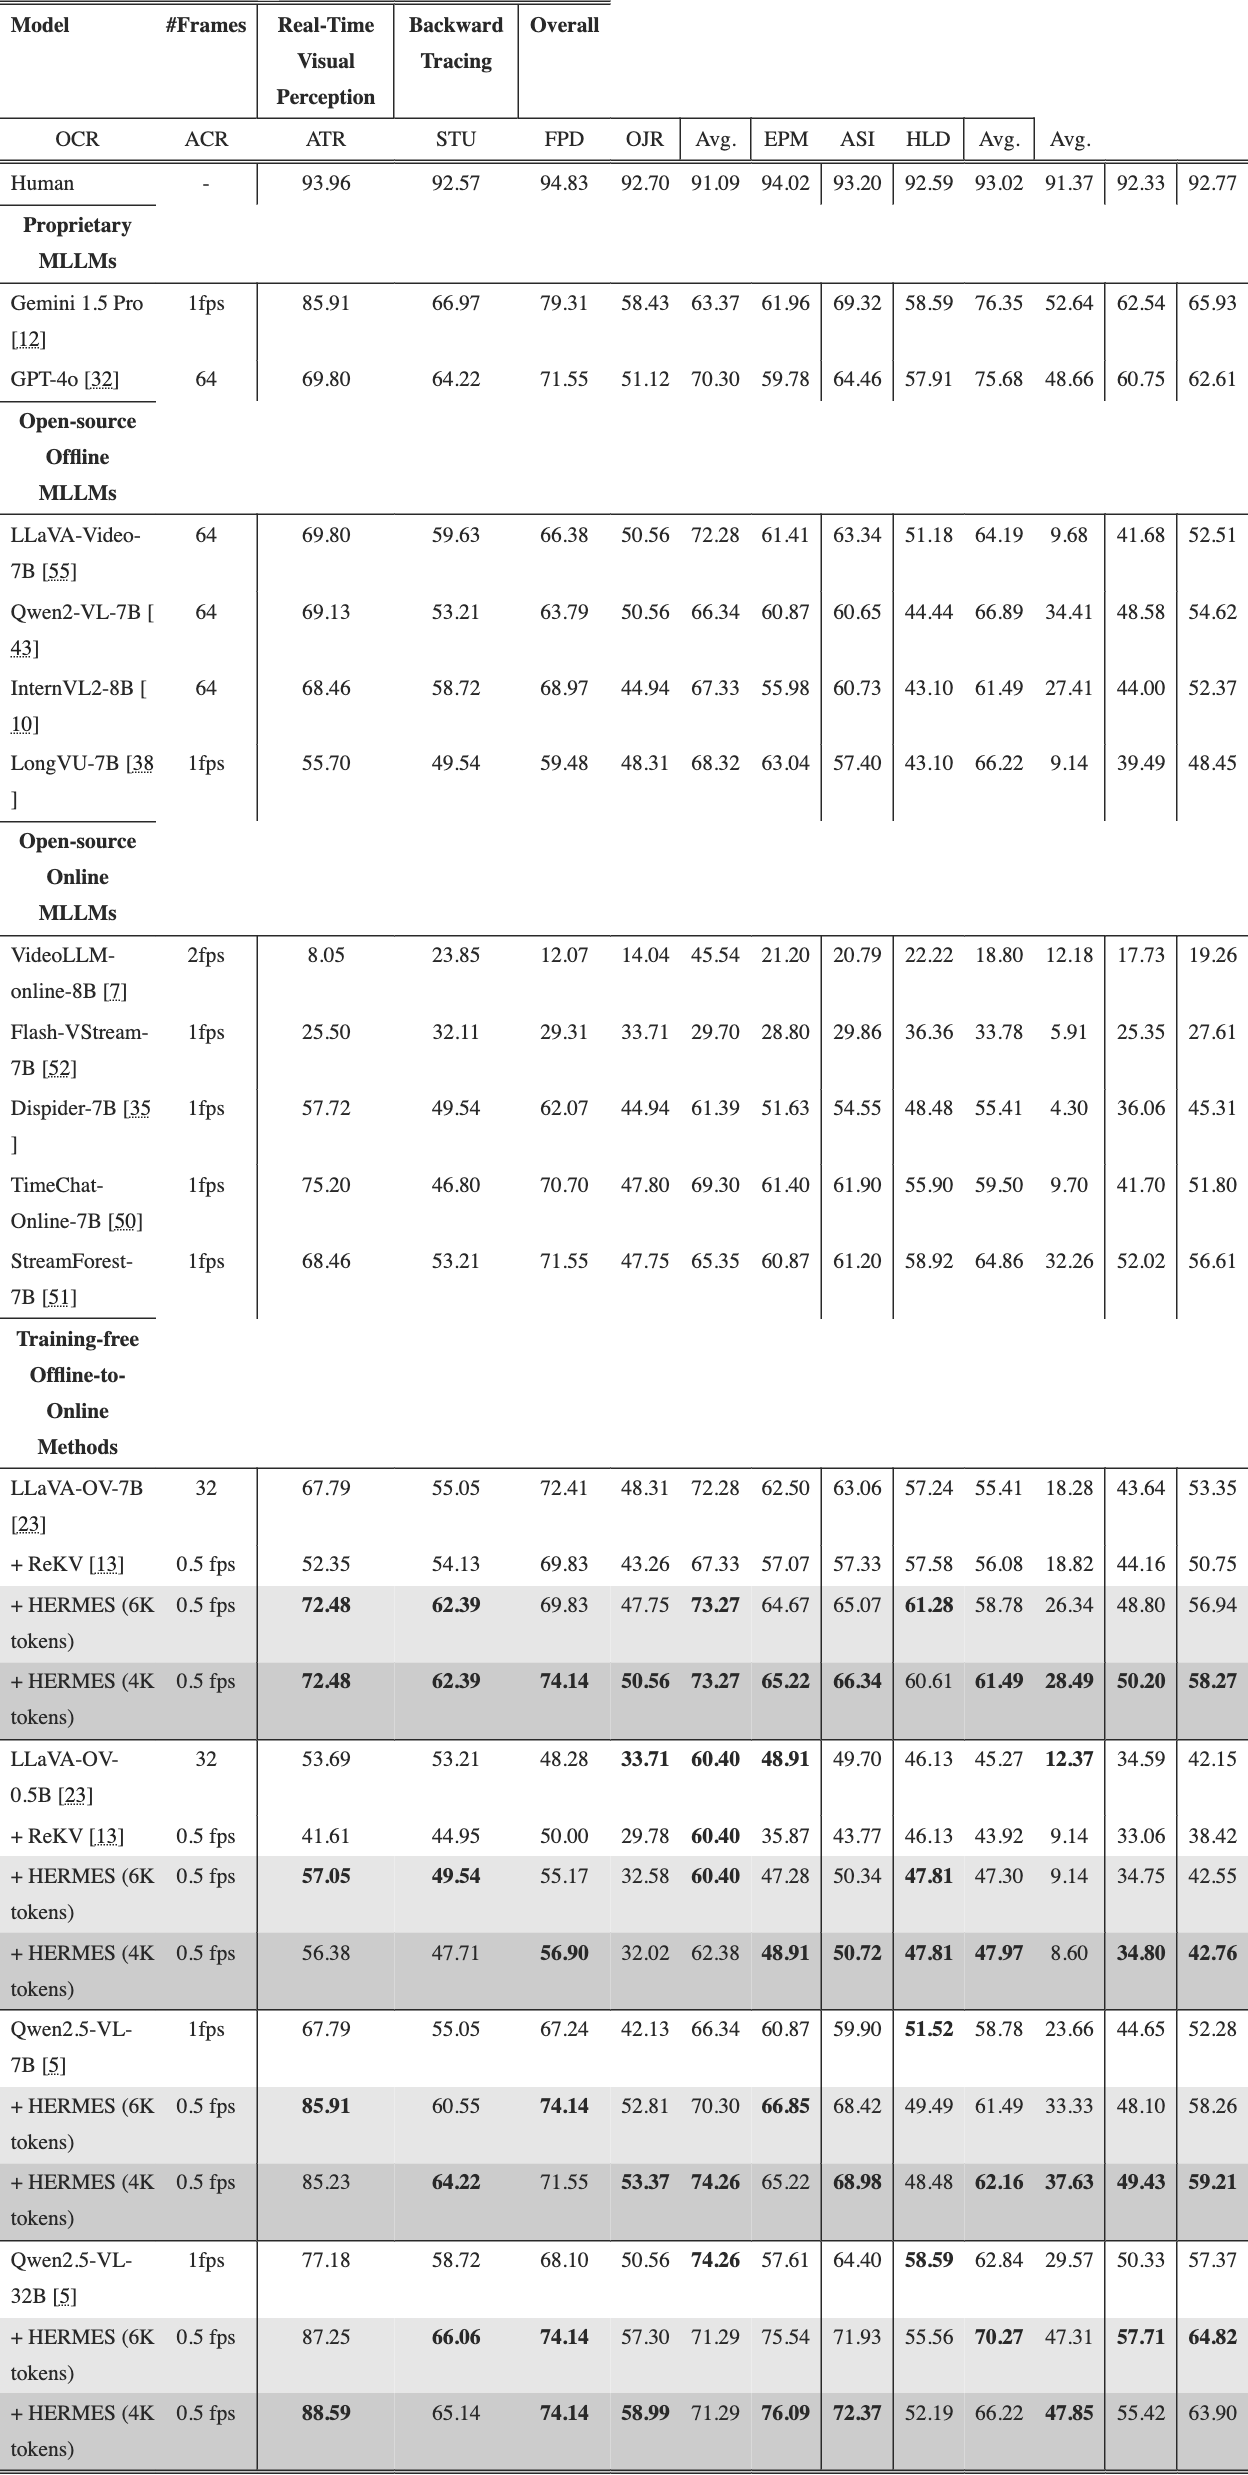
We provide six representative case study examples from RVS-Ego and RVS-Movie to demonstrate the advantages of HERMES compared to the foundation model LLaVA-OV-7B. During the understanding of streaming long videos, HERMES exhibits significantly finer-grained temporal (shown in figure 11) and spatial understanding figure 12 capabilities than its corresponding foundation model.