DeepPlanning: Benchmarking Long-Horizon Agentic Planning with Verifiable Constraints
arXiv:2601.18137v1 · This workspace stays on this version. Check arXiv for newer versions
Some source details need review 1 to check
Original formulas, table values and figures are preserved. Comparison can miss differences; use the original PDF to check details.
Reading view checked: 12 math expressions, 0 rendering failures; 12 of 12 images available.
Compared 72 of 72 source passages against 31 of 31 PDF pages.
The HTML source contains failed formatting commands; these were omitted from the reading view. The original sources are retained. (8)
- An unsupported comparison claim was rejected; source verification is incomplete.
12 of 12 figure, table and graphic images captured. Open original PDF
Abstract
While agent evaluation has shifted toward long-horizon tasks, most benchmarks still emphasize local, step-level reasoning rather than the global constrained optimization (e.g., time and financial budgets) that demands genuine planning ability. Meanwhile, existing LLM planning benchmarks underrepresent the active information gathering and fine-grained local constraints typical of real-world settings. To address this, we introduce DeepPlanning, a challenging benchmark for practical long-horizon agent planning. It features multi-day travel planning and multi-product shopping tasks that require proactive information acquisition, local constrained reasoning, and global constrained optimization. Evaluations on DeepPlanning show that even frontier agentic LLMs struggle with these problems, highlighting the importance of reliable explicit reasoning patterns and parallel tool use for achieving better effectiveness-efficiency trade-offs. Error analysis further points to promising directions for improving agentic LLMs over long planning horizons. We open-source the code and data to support future research.
Agentic tool use has emerged as a fundamental capability for large language models (LLMs), extending their utility far beyond parametric knowledge. Recently, evaluation of agents has shifted from short-horizon, tool-centric benchmarks (Li et al., 2023; Qin et al., 2024; Patil et al., 2025) toward long-horizon, user-centric tasks (Qian et al., 2025; Andrews et al., 2025; He et al., 2025). In these evolving settings, agents are expected to utilize tools not merely to execute isolated commands, but to satisfy complex, implicit user requests while adhering to strictly defined domain policies (Yao et al., 2024; Barres et al., 2025).
Despite this progress, a critical gap remains in how these capabilities are evaluated. Existing tool-use benchmarks predominantly emphasize local, step-level constrained reasoning within individual actions, such as filtering hotels based on amenities or modifying a specific flight segment. While necessary, this perspective is insufficient for real-world complexity. Practical scenarios often impose global constrained optimization requirements, where constraints such as total time budgets, cumulative financial costs, and cross-subtask dependencies restrict the entire solution space rather than any single step. Current agent evaluation benchmarks largely fail to assess their ability to navigate these holistic boundaries, leaving the community without a reliable measure for comprehensive agent planning.
While efforts exist to benchmark LLMs on classical (Valmeekam et al., 2023; Stechly et al., 2025) and temporal planning tasks (Zhang et al., 2024; Ding et al., 2025), these settings are simplified and abstract away the complex information acquisition process inherent to reality. In contrast, real-life long-horizon tasks such as multi-day travel and multi-product shopping require agents to proactively seek information from environments. However, existing benchmarks impede thorough evaluation: they suffer from either ineffective global constraints (Yao et al., 2022; Lyu et al., 2025), trivial local constraints (Shao et al., 2025), or overly coarse global constraints (Xie et al., 2024; Singh et al., 2024).
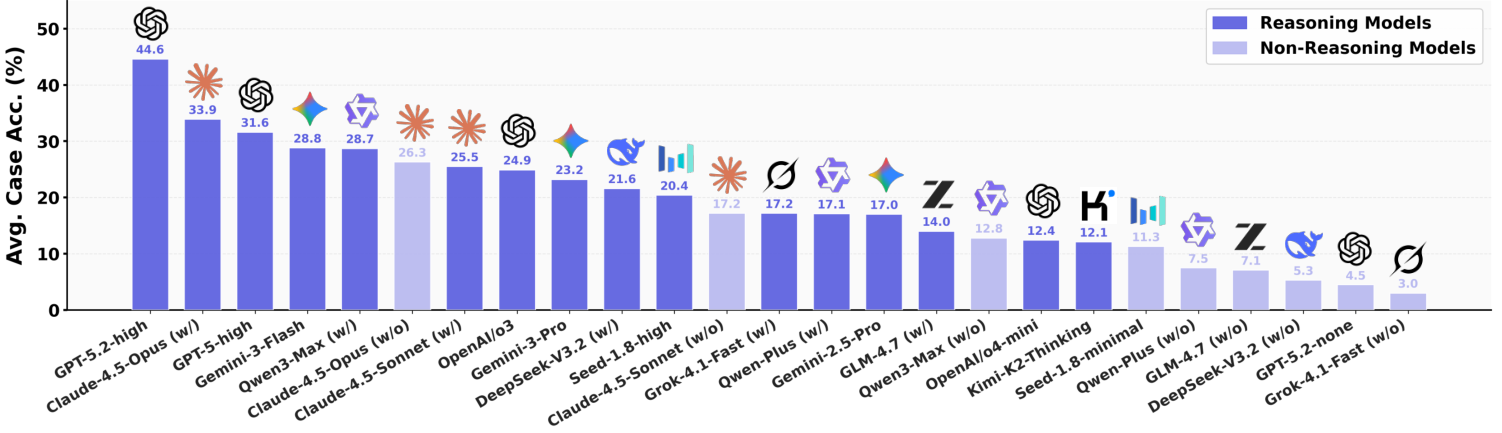
To address these limitations, we introduce DeepPlanning, a comprehensive benchmark grounded in challenging real-world tasks designed to evaluate practical LLM agents. We posit that a capable agent must integrate three key competencies: (i) Proactive Information Acquisition—the ability to actively search for and retrieve necessary state information from the environment; (ii) Local Constrained Reasoning—the ability to handle explicit and implicit logic within sub-tasks; and (iii) Global Constrained Optimization—the ability to optimize the overall solution under holistic constraints. Guided by this perspective, we build our benchmark across two complex real-world domains, Travel Planning and Shopping Planning, by constructing realistic yet challenging planning tasks through a comprehensive pipeline encompassing database and toolbox design, layered task generation, and manual quality control. We then evaluate frontier LLMs from multiple model families on DeepPlanning and expose clear limitations in their ability to solve these tasks (see Figure 1). Our experiments show that reliable explicit reasoning patterns and parallel tool use are critical for achieving better effectiveness-efficiency trade-offs in complex planning. Detailed error analyses further underscore the importance of the three competencies: (i) even top-performing agents may omit necessary tool calls over long planning horizons; (ii) implicit environmental constraints (e.g., limited seat availability on flights or mismatched attraction opening hours) are harder to detect than explicit user requirements; and (iii) agents still lack robust global consistency checking and backtracking for long-horizon, tightly coupled tasks.
Our contributions are summarized as follows:
- •
We introduce DeepPlanning, a benchmark designed to challenge the long-horizon planning abilities of LLM agents through complex travel and shopping tasks. It supports reproducible, easy-to-verify evaluation via offline sandboxes and rule-based checkers.
- •
Our large-scale evaluation exposes fundamental limitations of frontier agentic LLMs in long-horizon planning, highlighting the need for more complex and realistic evaluation settings.
- •
Through comprehensive analysis, we identify key factors that improve effectiveness–efficiency trade-offs on DeepPlanning and outline promising directions for strengthening agentic LLMs over extended planning horizons.
The inherent complexity of real-world scenarios is pushing LLMs beyond explicit, short-term tool use (Li et al., 2023; Qin et al., 2024) toward more implicit, long-horizon tasks (Yao et al., 2024; Barres et al., 2025; Andrews et al., 2025; Qian et al., 2025; He et al., 2025). Another line of research evaluates agents’ ability to solve complex objectives in noisy, web-based environments (Yao et al., 2022; Deng et al., 2023; Zhou et al., 2024; He et al., 2024; Lyu et al., 2025; Wei et al., 2025), where performance is fundamentally constrained by grounding limitations. However, these benchmarks largely emphasize complex instruction following rather than deliberative, multi-step planning, and thus fail to rigorously assess LLMs’ ability to verify plans and backtrack under global resource constraints.
In the era of LLMs, planning has been widely studied as a high-level reasoning capability central to achieving human-level intelligence. Early studies on classical (Valmeekam et al., 2023; Stechly et al., 2025) and temporal planning tasks (Zhang et al., 2024; Ding et al., 2025) show that LLM-based agents struggle to plan reliably under specific global constraints. Recent benchmarks shift to real-world scenarios like complex travel planning (Xie et al., 2024; Shao et al., 2025; Qu et al., 2025; Singh et al., 2024; Wang et al., 2025), but often simplify planning horizons (e.g., day-level instead of minute-level) (Xie et al., 2024; Qu et al., 2025) or lack complex constraints (Shao et al., 2025). These limitations motivate the need for a more comprehensive benchmark to evaluate long-horizon agent planning.
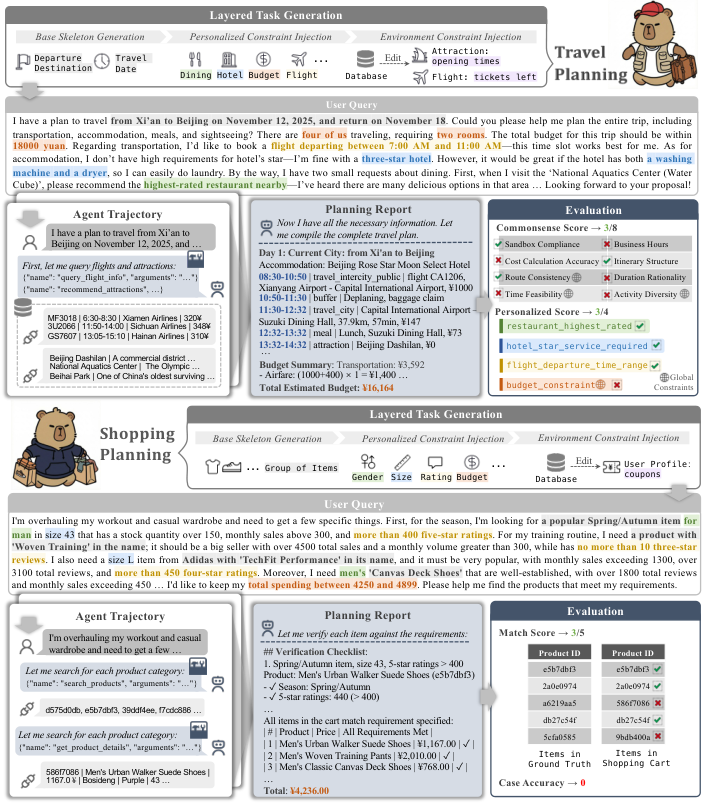
We illustrate DeepPlanning in Figure 2, which systematically evaluates language agents across two complex, real-world scenarios: Travel Planning and Shopping Planning. Each task runs in a self-contained offline sandbox backed by a database, which is accessible only via the provided Python toolkits, ensuring reproducibility and ease of deployment. During execution, an agent receives a user query, iteratively invokes tools to retrieve the required information, and produces a plan that satisfies both task policies and user needs.
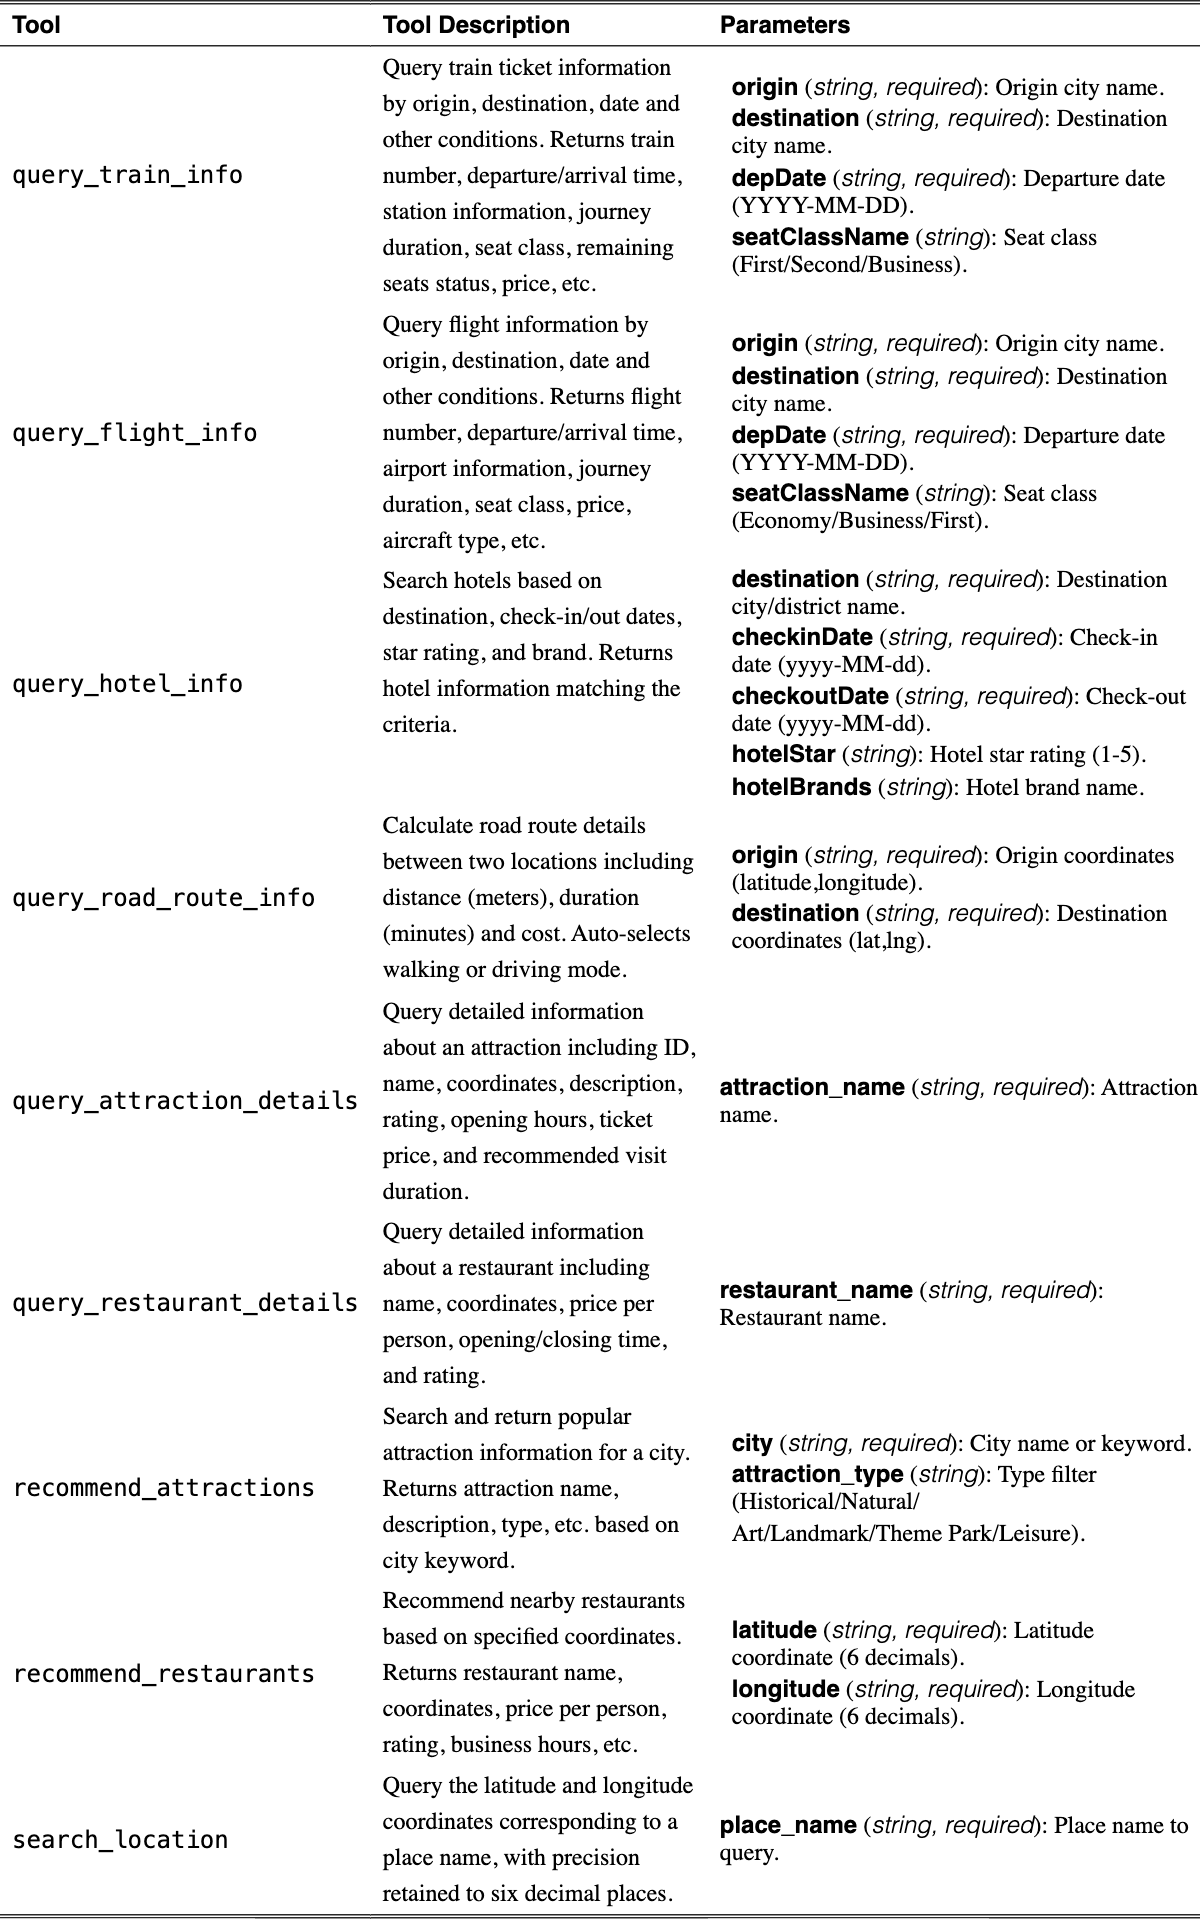
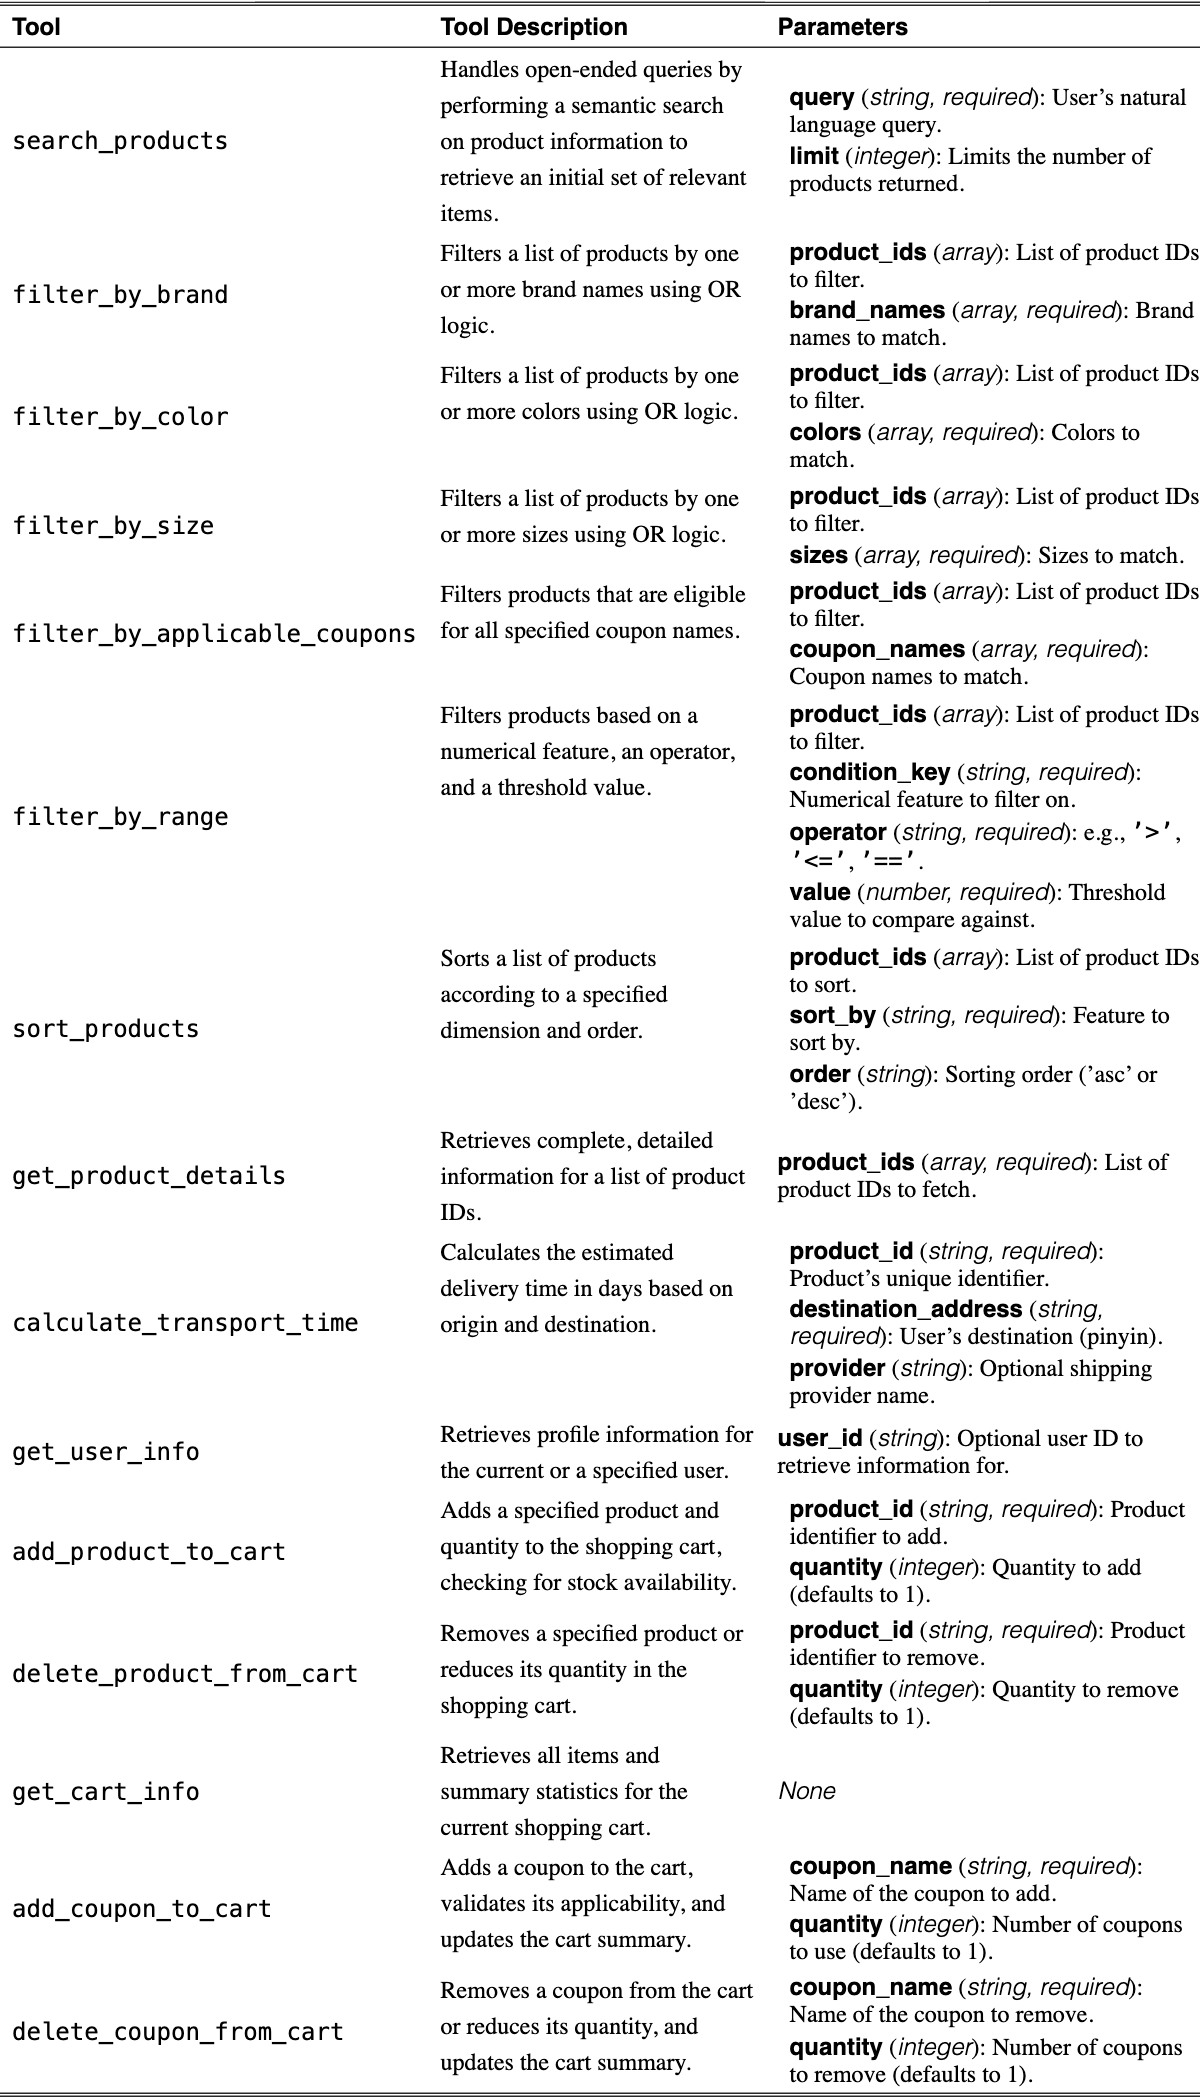
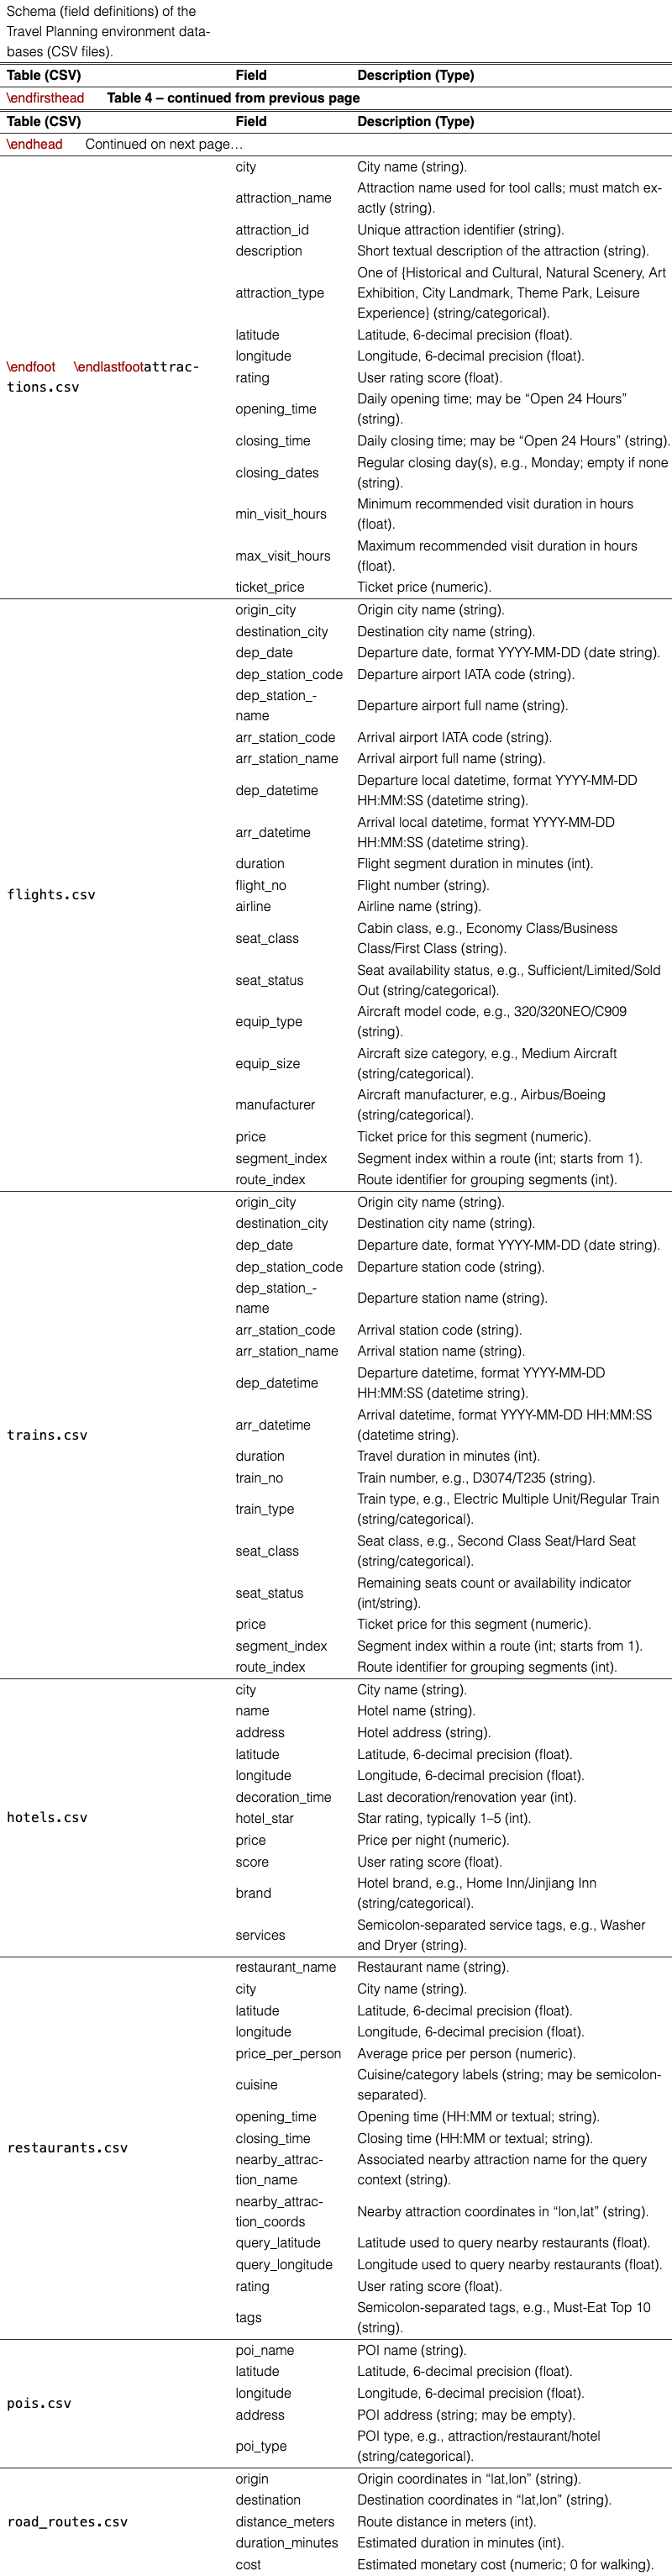
Concretely, Travel Planning consists of 120 unique tasks, each available in both Chinese and English. Every task runs in an isolated sandbox with seven task-specific sub-databases accessed via 9 specialized APIs (e.g., query_hotel_info). Agents must generate realistic multi-day itineraries by integrating information about transportation, accommodation, attractions, and dining, producing a structured, minute-level schedule with itemized costs and a final budget summary. The core difficulty lies in the tight coupling among time, location, and budget, where small changes can cascade into downstream failures. Shopping Planning comprises 120 English tasks, each running in an isolated sandbox with three sub-databases and 15 specialized APIs (e.g., search_products). Agents must construct an optimal purchasing plan by combining user requirements with product details, sizing, shipping times, coupon availability, and budget constraints (see Appendix A.1). Using these tools, they assemble a final shopping cart returned as a structured JSON object. Agents must construct an optimal purchasing plan by combining user requirements with product specifications, sizing, shipping times, coupon availability, and budget constraints, ultimately returning a structured JSON shopping cart (see Appendix A.2). Challenges lies in the combinatorial optimization across user needs, product attributes, coupon applicability, and budget.
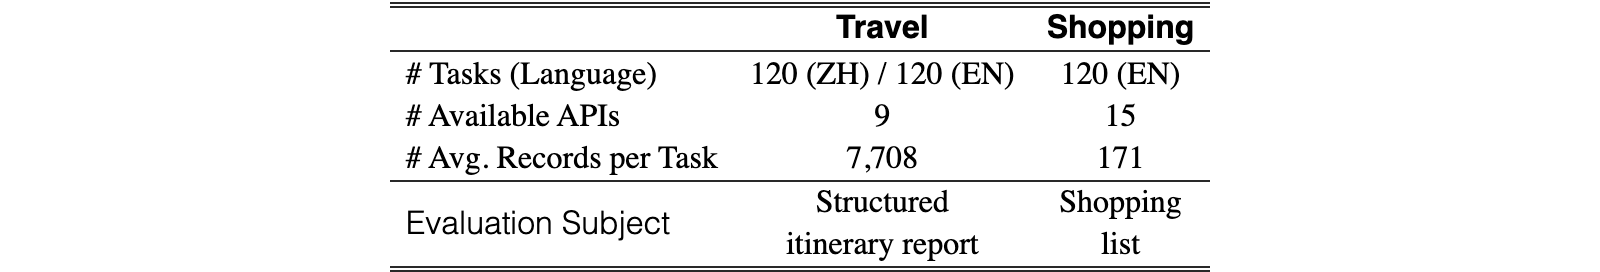
Table 1 summarizes key statistics for each domain in DeepPlanning, along with the aspects assessed during evaluation. We describe the goals and challenges in terms of the three core capabilities required of capable agents later.
| Travel | Shopping | |
| # Tasks (Language) | 120 (ZH) / 120 (EN) | 120 (EN) |
| # Available APIs | 9 | 15 |
| # Avg. Records per Task | 7,708 | 171 |
| Evaluation Subject | Structured | Shopping |
| itinerary report | list |
View original table
In Travel Planning, agents must discover key environment states via APIs rather than making facts in a plan. A common failure is planning intra-city travel (travel_city), which requires a complex, multi-step query (e.g., location coordinates available transportation options) that is easy to overlook. In Shopping Planning, beyond the information explicitly stated in the user query, agents must uncover critical implicit details. For example, user-specific attributes such as clothing size or shipping destination are often omitted and must be actively retrieved via the appropriate tools.
In Travel Planning, agents must handle both explicit user preferences stated in the query (e.g., a three-star hotel with a washing machine) and implicit constraints that emerge during interactions with the environment (e.g., a target attraction closed today). In Shopping Planning, agents must satisfy explicit user preferences by selecting appropriate tools and applying relevant filters, such as preferred brands, colors, or minimum required product ratings. They must integrate these multi-faceted constraints to identify the product that best matches the user’s intent.
In Travel Planning, the itinerary must satisfy global constraints across three dimensions: time (avoid overlaps; respect visit durations and opening hours), space (ensure feasible transportation between consecutive locations), and budget (accurately aggregate costs and comply with trip-level limits). In Shopping Planning, the challenge extends beyond selecting individual items to managing combinatorial constraints across the entire cart. Agents must assemble a set of products that fits the total budget, often prioritizing the lowest overall cart cost rather than the cheapest items in isolation. Likewise, effective coupon use may require choosing a higher-priced item to reduce the final total.
A three-stage data construction pipeline is utilized to generate high-complexity agent planning tasks along with verifiable, unique solutions. Figure 2 highlights the central stage, Layered Task Generation, to aid understanding.
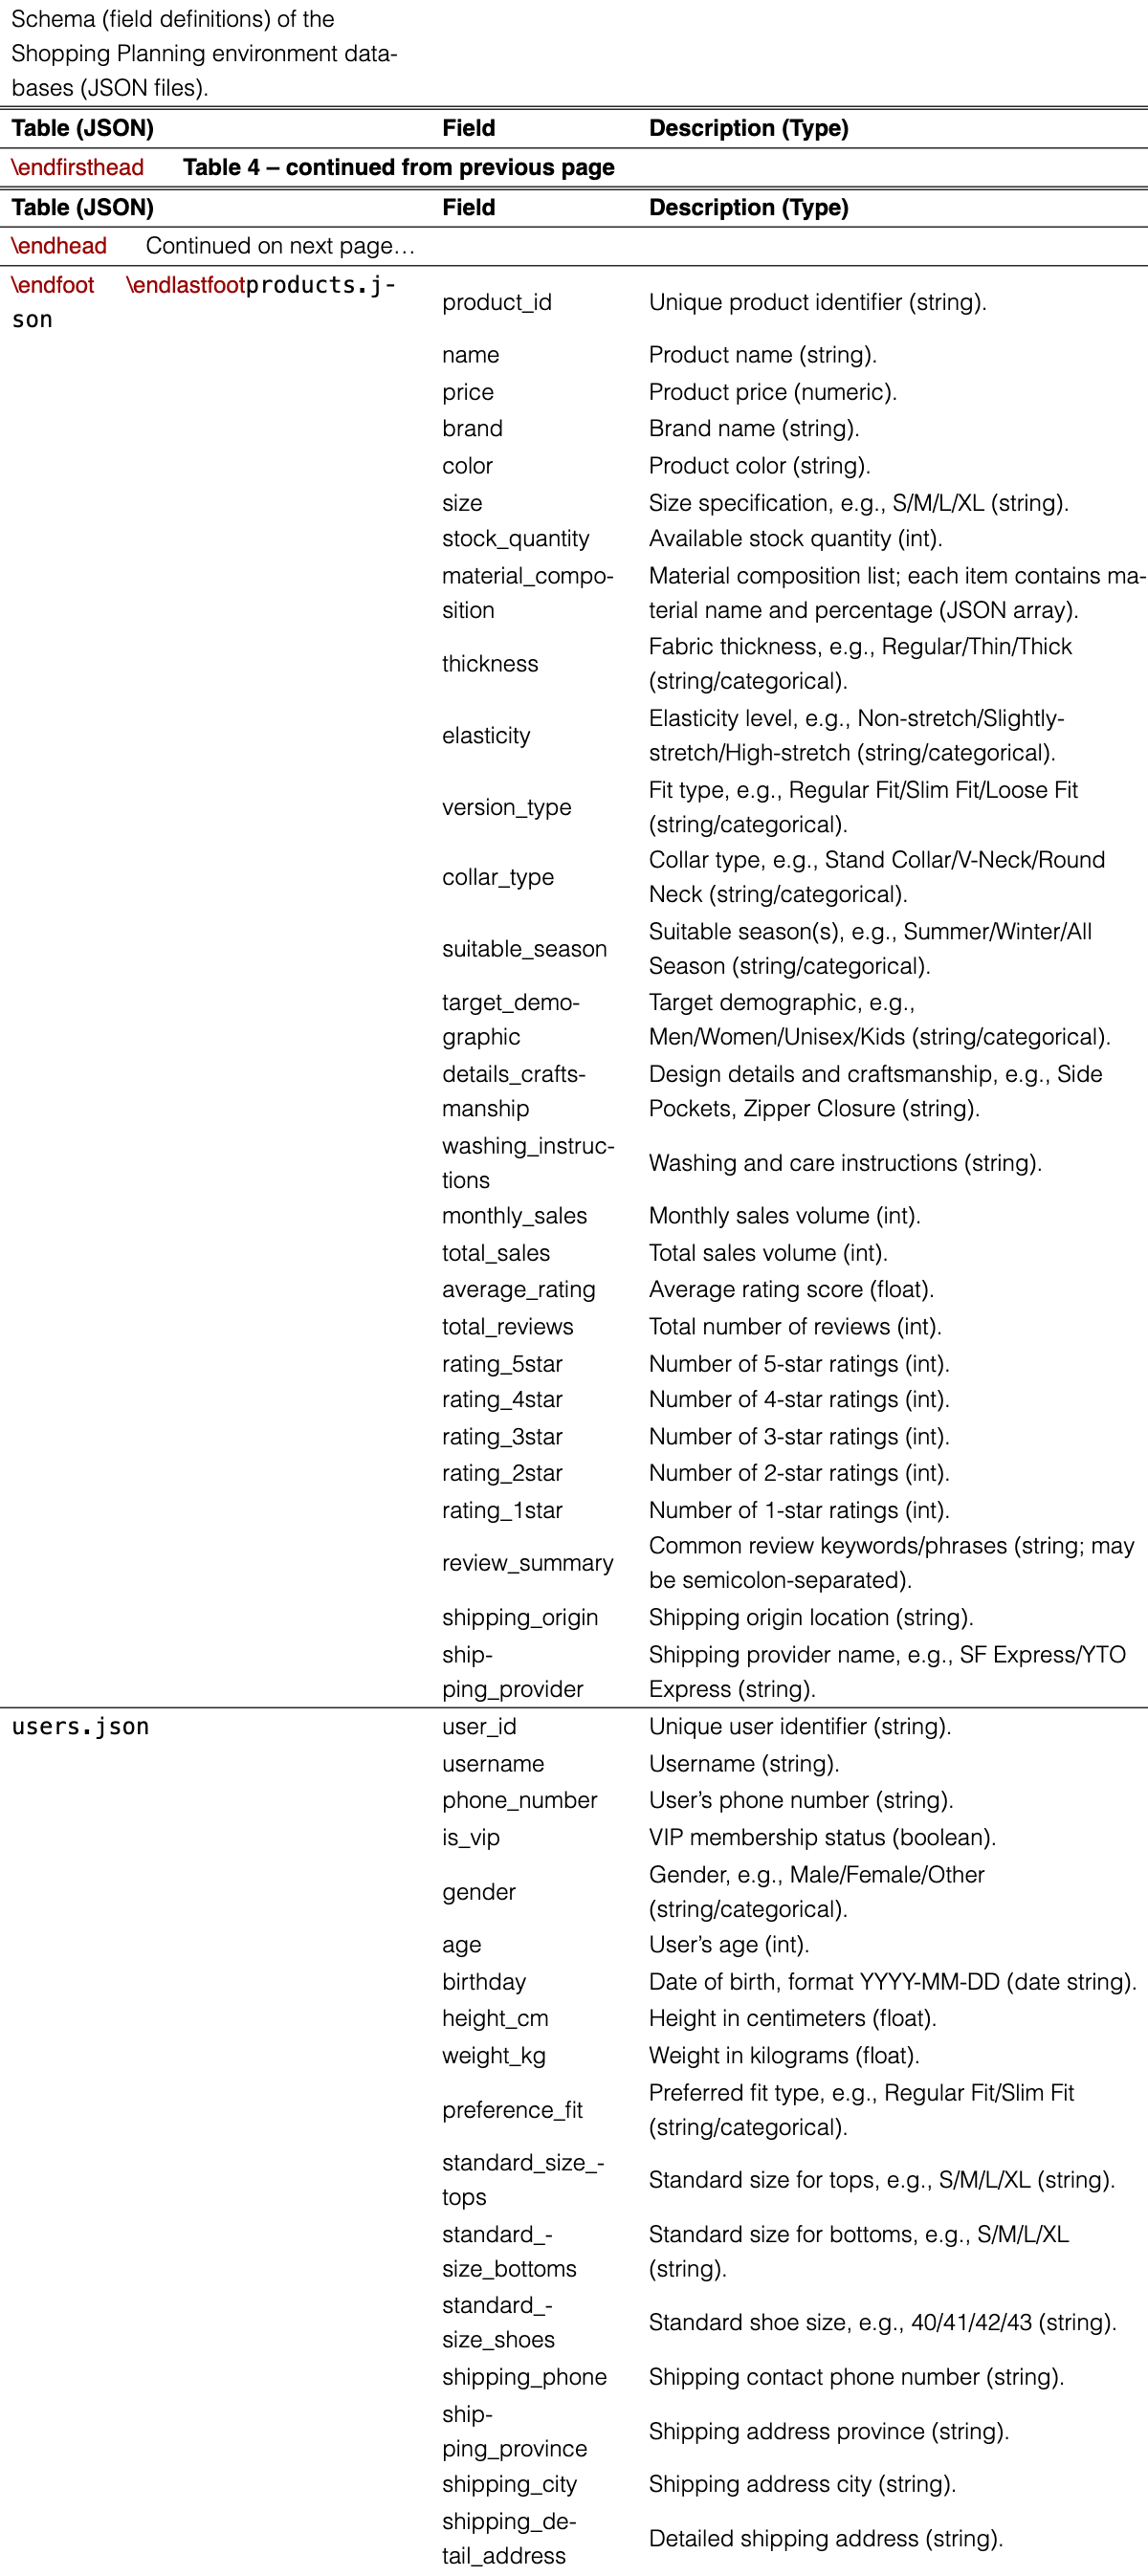
To build sandbox environments for agent planning, we develop domain-specific databases and a suite of custom Python APIs that abstract database query behavior. We populate these databases with domain-specific data. For Travel Planning, we use public APIs (e.g., Fliggy, Amap and Web Search) to collect real-world data from popular tourist cities in China, covering transportation, accommodation, dining, and attractions, with key fields such as prices, schedules, geographic coordinates, and ratings. For Shopping Planning, we synthesize fine-grained product data to enable controlled complexity, including attributes such as price, stock levels, monthly sales, user ratings, and promotion details. Tools in each domain follow a hierarchical design that encourages multi-step agent interaction with the environment. See Appendix B.1 and Appendix B.2 for detailed tool schemas and example database entries.
We adopt a solution-centric, reverse-generation process to construct complex agent planning tasks by progressively adding constraints:
- •
Base Skeleton Generation. We derive a base skeleton from the database: in Travel Planning, this skeleton specifies the departure city, destination, and travel date; in Shopping Planning, it defines a set of items with a common theme (e.g., clothes and shoes for spring travel).
- •
Personalized Constraint Injection. We build domain-specific pools of personalized constraints and sample multiple, potentially complex constraints to augment the task skeleton. In Travel Planning, examples include “recommend the highest-rated restaurant nearby” or “book a flight departing after 7:00 AM”. In Shopping Planning, examples include “find a product named ShockWave with a rating above 4.7” or “keep my total spending above 4500 yuan”.
- •
Environment Constraint Injection. We further inject implicit environmental constraints that introduce dynamic challenges discoverable only through tool use. In Travel Planning, these include cases where a key attraction is closed on the planned day or where flights have limited ticket availability. In Shopping Planning, they appear as combinatorial optimization problems, such as coupon-stacking rules that make a seemingly more expensive cart the cheapest after all discounts are applied. After adding these constraints, candidates in databases are automatically adjusted so that exactly one optimal solution exists, ensuring solvability and uniqueness.
Finally, we use an LLM to convert all structured constraints into a conversational user query for each agent task.
This stage provides the final quality check for generated tasks. Human experts review and revise the LLM-generated queries and the full task to ensure: (i) natural, fluent language; (ii) clear, unambiguous logic; and (iii) a reachable solution for every task, ensuring the overall quality of DeepPlanning.
To ensure accurate and consistent task evaluation in DeepPlanning, we rely on code-based automated evaluation rather than LLM-based scoring.
In Travel Planning, we first use Qwen-Plus-2507 to parse the models’ natural-language itineraries into a predefined structured format, and then apply the following metrics for rule-based scoring:
- -
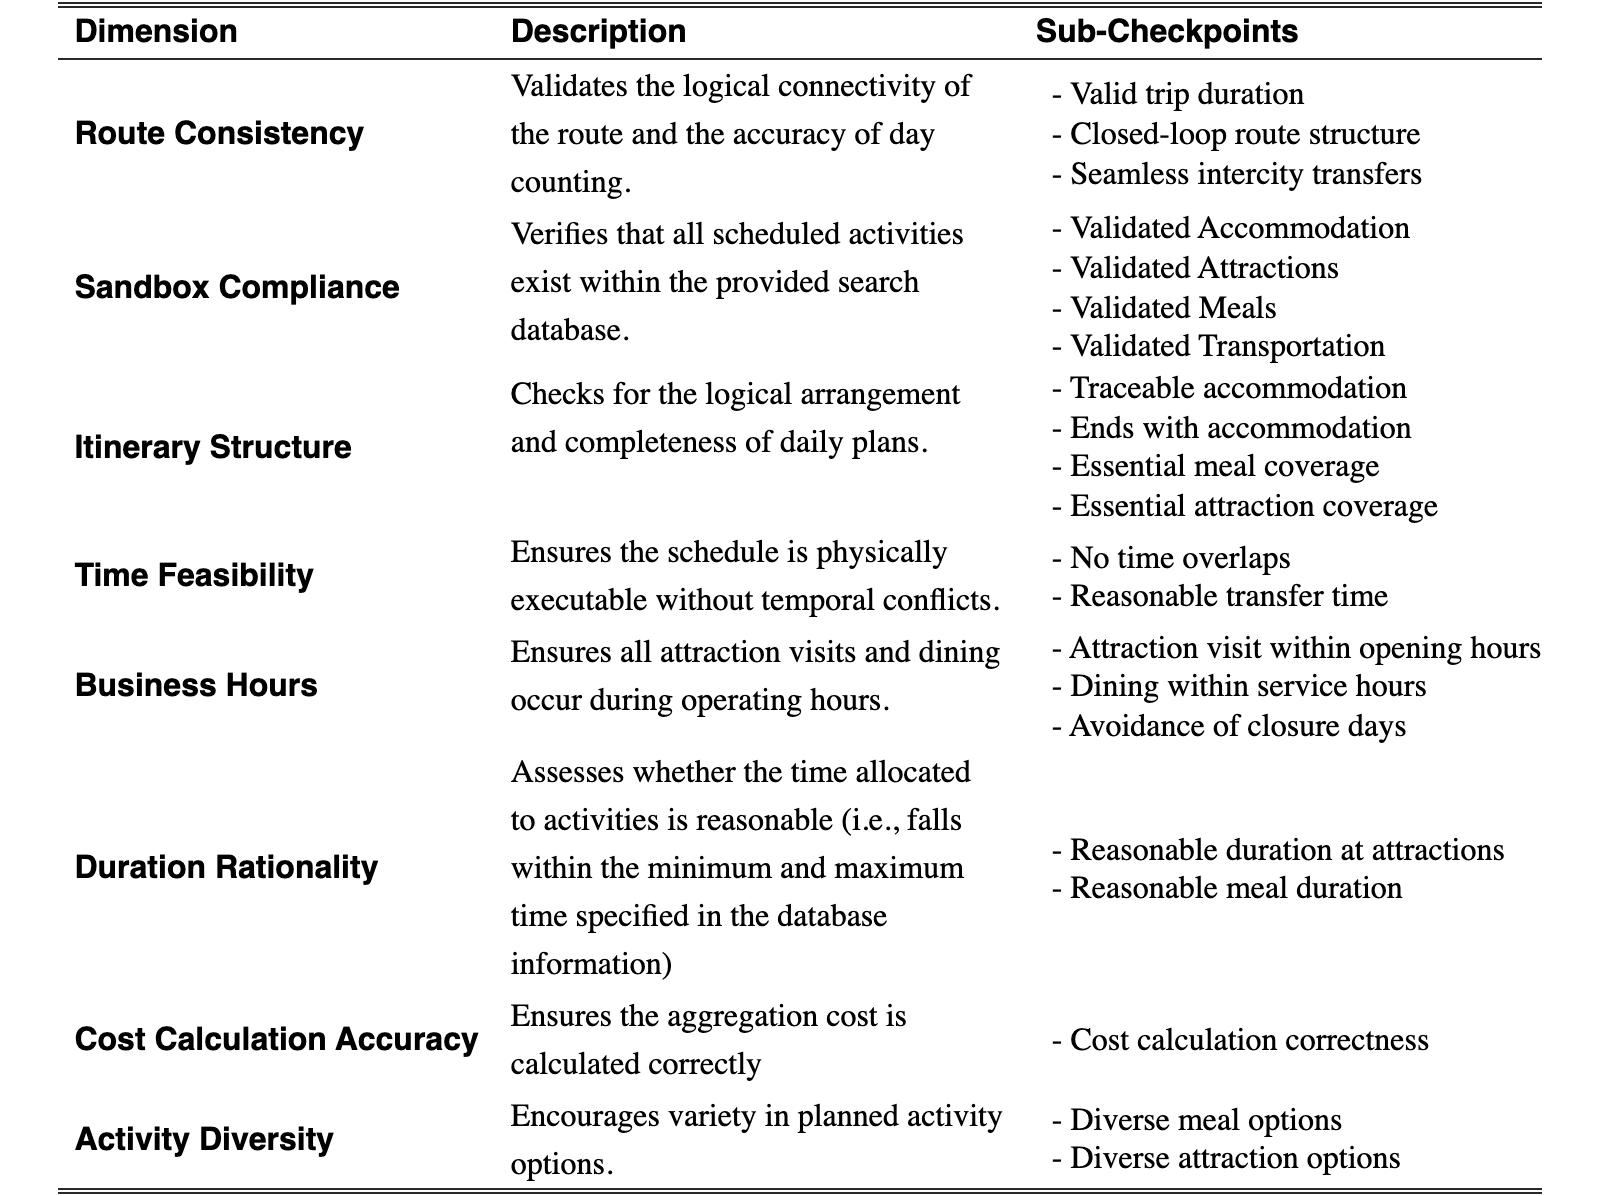
Commonsense Score. We evaluate agents’ ability to produce a real-world feasible plan along eight dimensions spanning 21 checkpoints, including route consistency, sandbox compliance, itinerary structure, time feasibility, business hours compliance, duration rationality, cost calculation accuracy, and activity diversity. All sub-checkpoints are verified automatically via code execution. Each dimension contributes equally to the commonsense score: it receives if all its sub-checkpoints are satisfied, and otherwise. For each task, the commonsense score is the sum of the eight dimension scores. See Appendix C for the full taxonomy and descriptions.
- -
Personalized Score. We use this metric to evaluate agents’ ability to satisfy user-specific requirements stated in the query. All injected personalized constraints in the Layered Task Generation stage are automatically translated into code-based checks, which are then used to verify whether the structured plan meets the user’s needs. For each task, the personalized score is if all constraints are satisfied and otherwise.
- -
Composite Score. This metric provides a holistic evaluation of agent performance on Travel Planning. For each task, it is the average of the Commonsense Score and the Personalized Score.
- -
Case Accuracy. This metric is a stricter, case-level measure of performance. For each task, it is only if both the Commonsense Score and the Personalized Score are perfect, and otherwise.
| Model | Avg Acc. | Travel Planning | Shopping Planning | ||||
| CS Score | PS Score | Comp Score | Case Acc. | Match Score | Case Acc. | ||
| Non-Reasoning Models | |||||||
| Anthropic/Claude-4.5-Opus (w/o thinking) | 26.3 | 67.5 | 58.8 | 63.1 | 6.7 | 82.2 | 45.8 |
| Anthropic/Claude-4.5-Sonnet (w/o thinking) | 17.2 | 53.4 | 42.8 | 48.1 | 1.1 | 75.8 | 33.3 |
| Alibaba/Qwen3-Max (w/o thinking) | 12.8 | 36.7 | 30.7 | 31.8 | 0.8 | 70.2 | 24.7 |
| ByteDance/Seed-1.8-minimal | 11.3 | 43.0 | 47.5 | 45.3 | 0.0 | 68.1 | 22.5 |
| Alibaba/Qwen-Plus (w/o thinking) | 7.5 | 37.3 | 13.0 | 25.1 | 0.0 | 63.9 | 15.0 |
| Z.ai/GLM-4.7 (w/o thinking) | 7.1 | 38.9 | 22.5 | 30.7 | 0.0 | 61.2 | 14.2 |
| DeepSeek-AI/DeepSeek-V3.2 (w/o thinking) | 5.3 | 37.4 | 12.1 | 24.7 | 0.0 | 58.3 | 10.6 |
| OpenAI/GPT-5.2-none | 4.5 | 54.3 | 29.9 | 42.1 | 0.4 | 58.6 | 8.6 |
| xAI/Grok-4.1-Fast (non-reasoning) | 3.0 | 39.6 | 19.7 | 29.6 | 0.0 | 50.1 | 5.9 |
| Reasoning Models | |||||||
| OpenAI/GPT-5.2-high | 44.6 | 88.5 | 83.3 | 85.8 | 35.0 | 84.8 | 54.2 |
| Anthropic/Claude-4.5-Opus (w/ thinking) | 33.9 | 79.3 | 70.9 | 75.1 | 22.7 | 80.0 | 45.0 |
| OpenAI/GPT-5-high | 31.6 | 78.7 | 65.9 | 72.3 | 18.9 | 80.4 | 44.2 |
| Google/Gemini-3-Flash-Preview | 28.8 | 67.1 | 57.7 | 62.4 | 5.9 | 80.6 | 51.7 |
| Alibaba/Qwen3-Max (w/ thinking) | 28.7 | 64.0 | 61.7 | 62.8 | 13.8 | 82.6 | 43.5 |
| Anthropic/Claude-4.5-Sonnet (w/ thinking) | 25.5 | 65.2 | 58.4 | 61.8 | 7.6 | 80.0 | 43.3 |
| OpenAI/o3 | 24.9 | 76.5 | 55.6 | 66.1 | 11.3 | 76.9 | 38.5 |
| Google/Gemini-3-Pro-Preview | 23.2 | 58.4 | 25.1 | 41.8 | 0.7 | 78.0 | 45.8 |
| Deepseek-AI/DeepSeek-V3.2 (w/ thinking) | 21.6 | 47.4 | 35.0 | 41.2 | 0.7 | 78.8 | 42.5 |
| ByteDance/Seed-1.8-high | 20.4 | 43.6 | 56.7 | 50.1 | 0.0 | 77.5 | 40.8 |
| xAI/Grok-4.1-Fast (reasoning) | 17.2 | 57.1 | 37.7 | 47.4 | 2.7 | 74.0 | 31.7 |
| Alibaba/Qwen-Plus (w/ thinking) | 17.1 | 35.4 | 22.4 | 28.9 | 0.0 | 73.3 | 34.1 |
| Google/Gemini-2.5-Pro | 17.0 | 62.3 | 42.0 | 52.2 | 3.2 | 69.1 | 30.8 |
| Z.ai/GLM-4.7 (w/ thinking) | 14.0 | 44.0 | 44.6 | 44.3 | 0.4 | 72.5 | 27.5 |
| OpenAI/o4-mini | 12.4 | 58.0 | 36.6 | 47.2 | 3.0 | 69.1 | 21.7 |
| Moonshot-AI/Kimi-K2-Thinking | 12.1 | 45.2 | 32.5 | 38.9 | 0.0 | 65.8 | 24.2 |
View original table
We compare the products the agent adds to the shopping cart against the ground-truth cart and evaluate their performance using the following metrics:
- -
Match Score. This metric measures the agent’s ability to identify the products requested by the user. For each task, it is computed as the number of products in the agent’s cart that match the ground-truth items, divided by the total number of ground-truth items.
- -
Case Accuracy. This metric provides a stricter measure of performance. For each task, it is only if all products in the cart exactly match the ground-truth products and otherwise.
We benchmark a wide range of state-of-the-art LLMs on DeepPlanning, including OpenAI GPT and o series (OpenAI, 2025a; OpenAI, 2025b), Anthropic Claude series (Anthropic, 2025), Google Gemini series (Comanici et al., 2025; Google, 2025), xAI Grok series (xAI, 2025), DeepSeek-AI DeepSeek series (Liu et al., 2025), Alibaba Qwen series (Yang et al., 2025), Z.ai GLM series (Zeng et al., 2025), Moonshot-AI Kimi series (Team et al., 2025), ByteDance Seed series (Seed et al., 2025). We experiment on both reasoning and non-reasoning models. For hybrid-thinking model families, the reasoning effort is set to the maximum when operating in thinking mode. All models are instantiated as function-calling agents, with tools specified in the OpenAI tool schema format, and a maximum of 400 tool calls allowed per task. For robustness, each task is run four times, and results are averaged across all runs and tasks. Notably, results for Travel Planning are averaged over both the Chinese and English case variants. Detailed system prompts for each domain are provided in Appendix D.
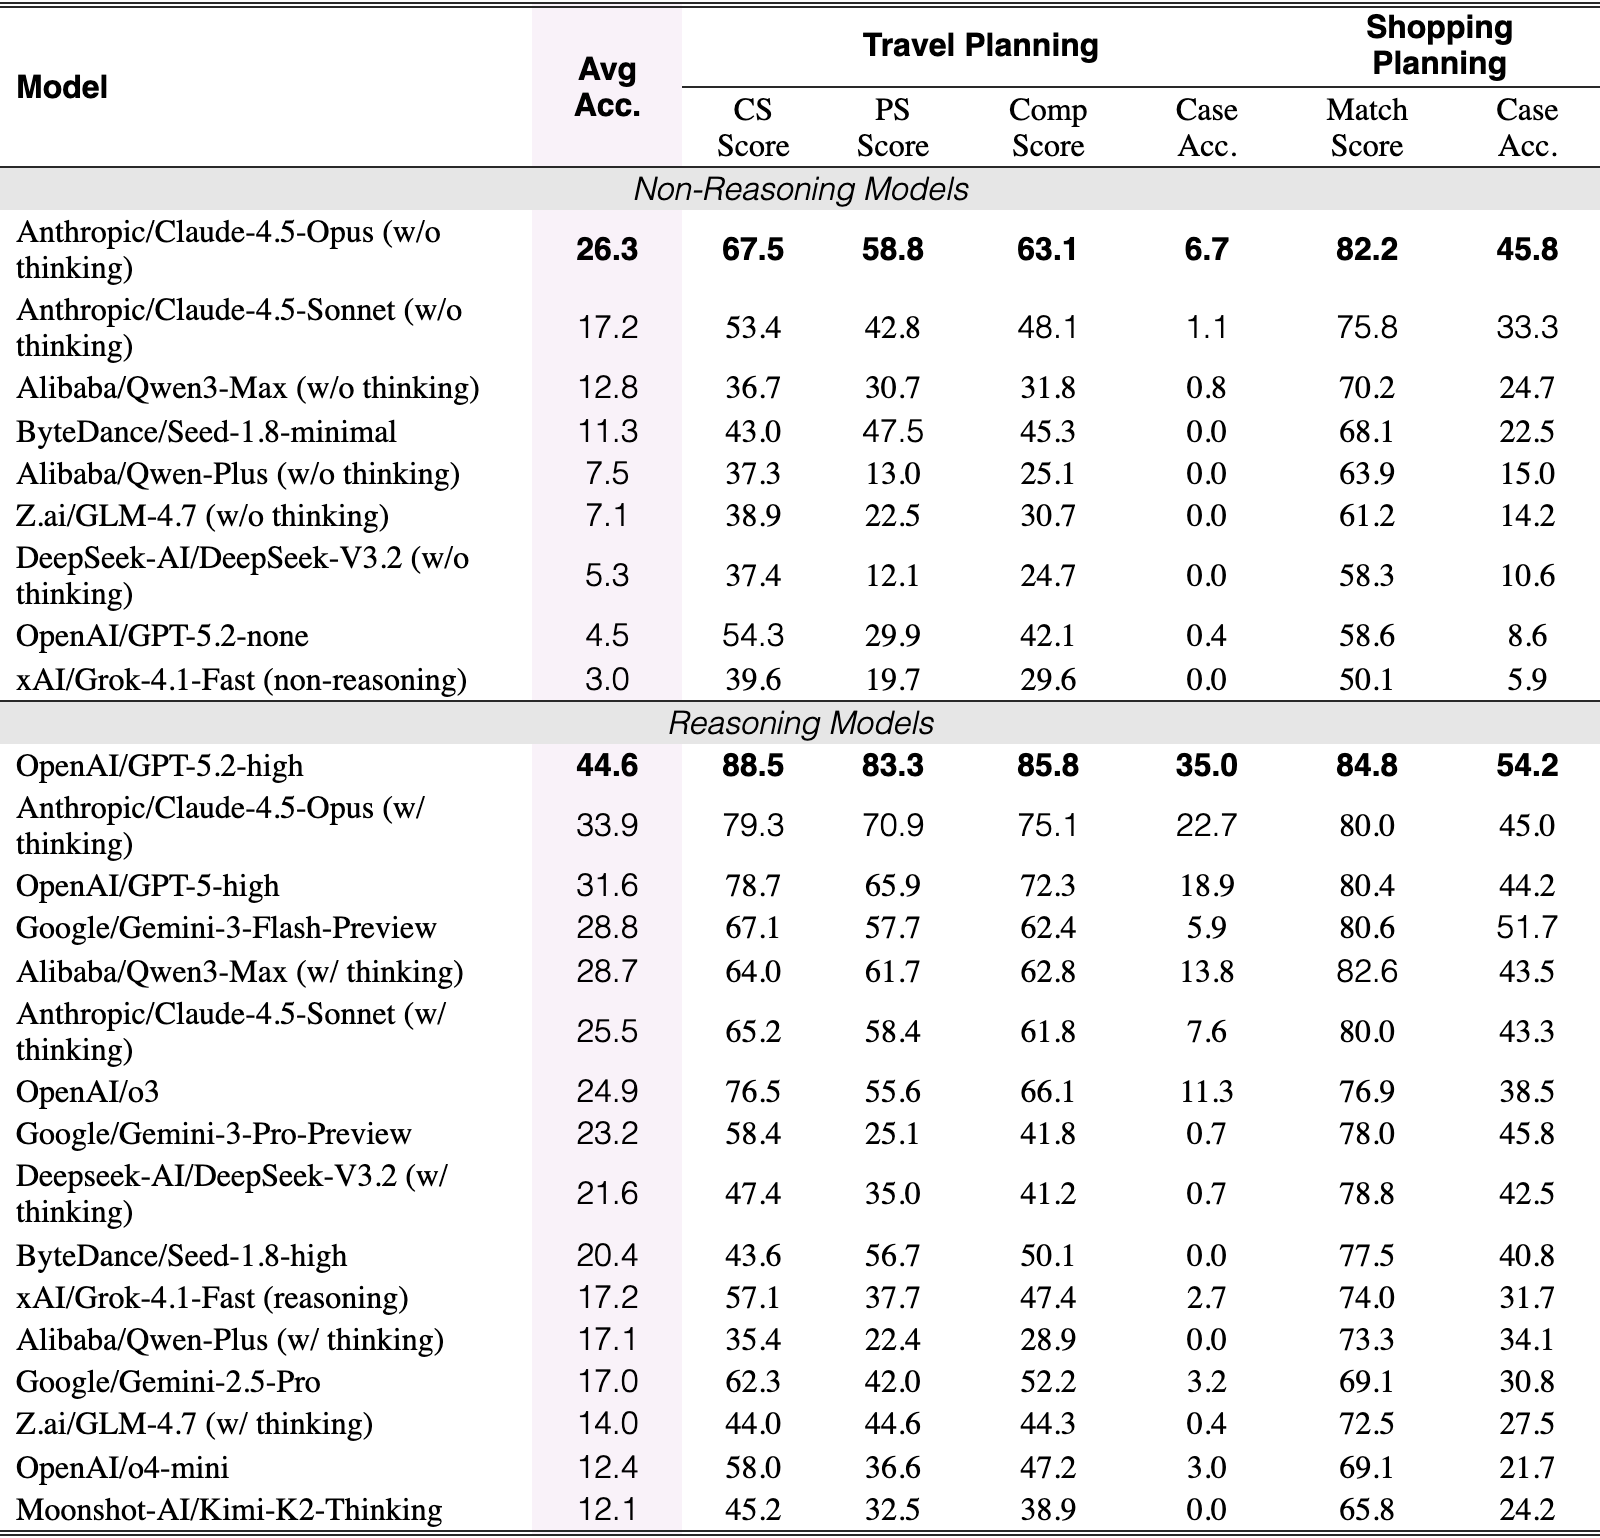
Table 2 presents the evaluation results of all models on DeepPlanning. We rank the models by their average case accuracy across both domains, revealing several notable findings:
Even frontier LLM agents are unable to fully solve complex planning tasks in DeepPlanning. A clear discrepancy emerges between relatively high constraint-level scores and low case-level accuracy. In Travel Planning, for example, even the best-performing model produces fully correct plans in only 35.0% of cases. Although a model may satisfy most individual requirements and achieve a high composite score, a single critical failure—such as exceeding the budget or introducing a scheduling conflict—can invalidate the entire plan. This fragility is also evident in Shopping Planning, where high Match Scores frequently fail to translate into high Case Accuracy. These results suggest that current agents struggle to integrate individually correct actions into a globally coherent and executable plan, exposing fundamental limitations in end-to-end long-horizon planning.
In general, the benchmark is led by models from the GPT-5 series and Claude-4.5 when operated with maximal reasoning effort. Notably, we observe pronounced domain specialization across models: although Gemini-3-Flash-Preview performs poorly on Travel Planning, it excels in Shopping Planning, outperforming all other baselines with a Case Accuracy of 60.0%. Crucially, models equipped with deliberate internal reasoning consistently surpass their non-reasoning counterparts, underscoring the importance of such capabilities for long-horizon planning tasks.
We further examine the relationship between inference cost and agent performance on DeepPlanning. Using Travel Planning as an example, Figure 3 plots the average composite score across all tasks against agent cost, measured by the average number of tool invocations and interaction turns per task. We observe the following:
As shown at the top of Figure 3, model performances generally increase with the number of tool calls, suggesting that long-horizon agent planning in real-world tasks relies on extensive, proactive information gathering (e.g., validating times, checking transfer feasibility, and verifying budgets) beyond parametric knowledge. In extreme cases, GPT-5.2-high achieves the best score while making roughly 224 tool invocations per task.
Reasoning models consistently sit in a better part of the trade-off curve, achieving higher scores with comparable or lower interaction costs. For example, enabling thinking mode in Claude-4.5-Opus both improves performance and reduces interaction turns (16.912.5) and tool calls (79.572.9). This suggests that internal planning curbs redundant trial-and-error and consolidates tool use into fewer, higher-quality actions.
Models exhibit distinct interaction strategies even within the same lineage (Figure 3). Within the GPT-5 family, GPT-5.1-high favors parallel execution by bundling multiple tool calls into a single turn, whereas GPT-5.2-high adopts a more sequential, step-by-step workflow. Although GPT-5.2-high achieves better performance (+12.7%), it requires nearly more turns than GPT-5.1-high, highlighting a clear cost-performance trade-off between parallel, more efficient interaction and sequential thorough verification.
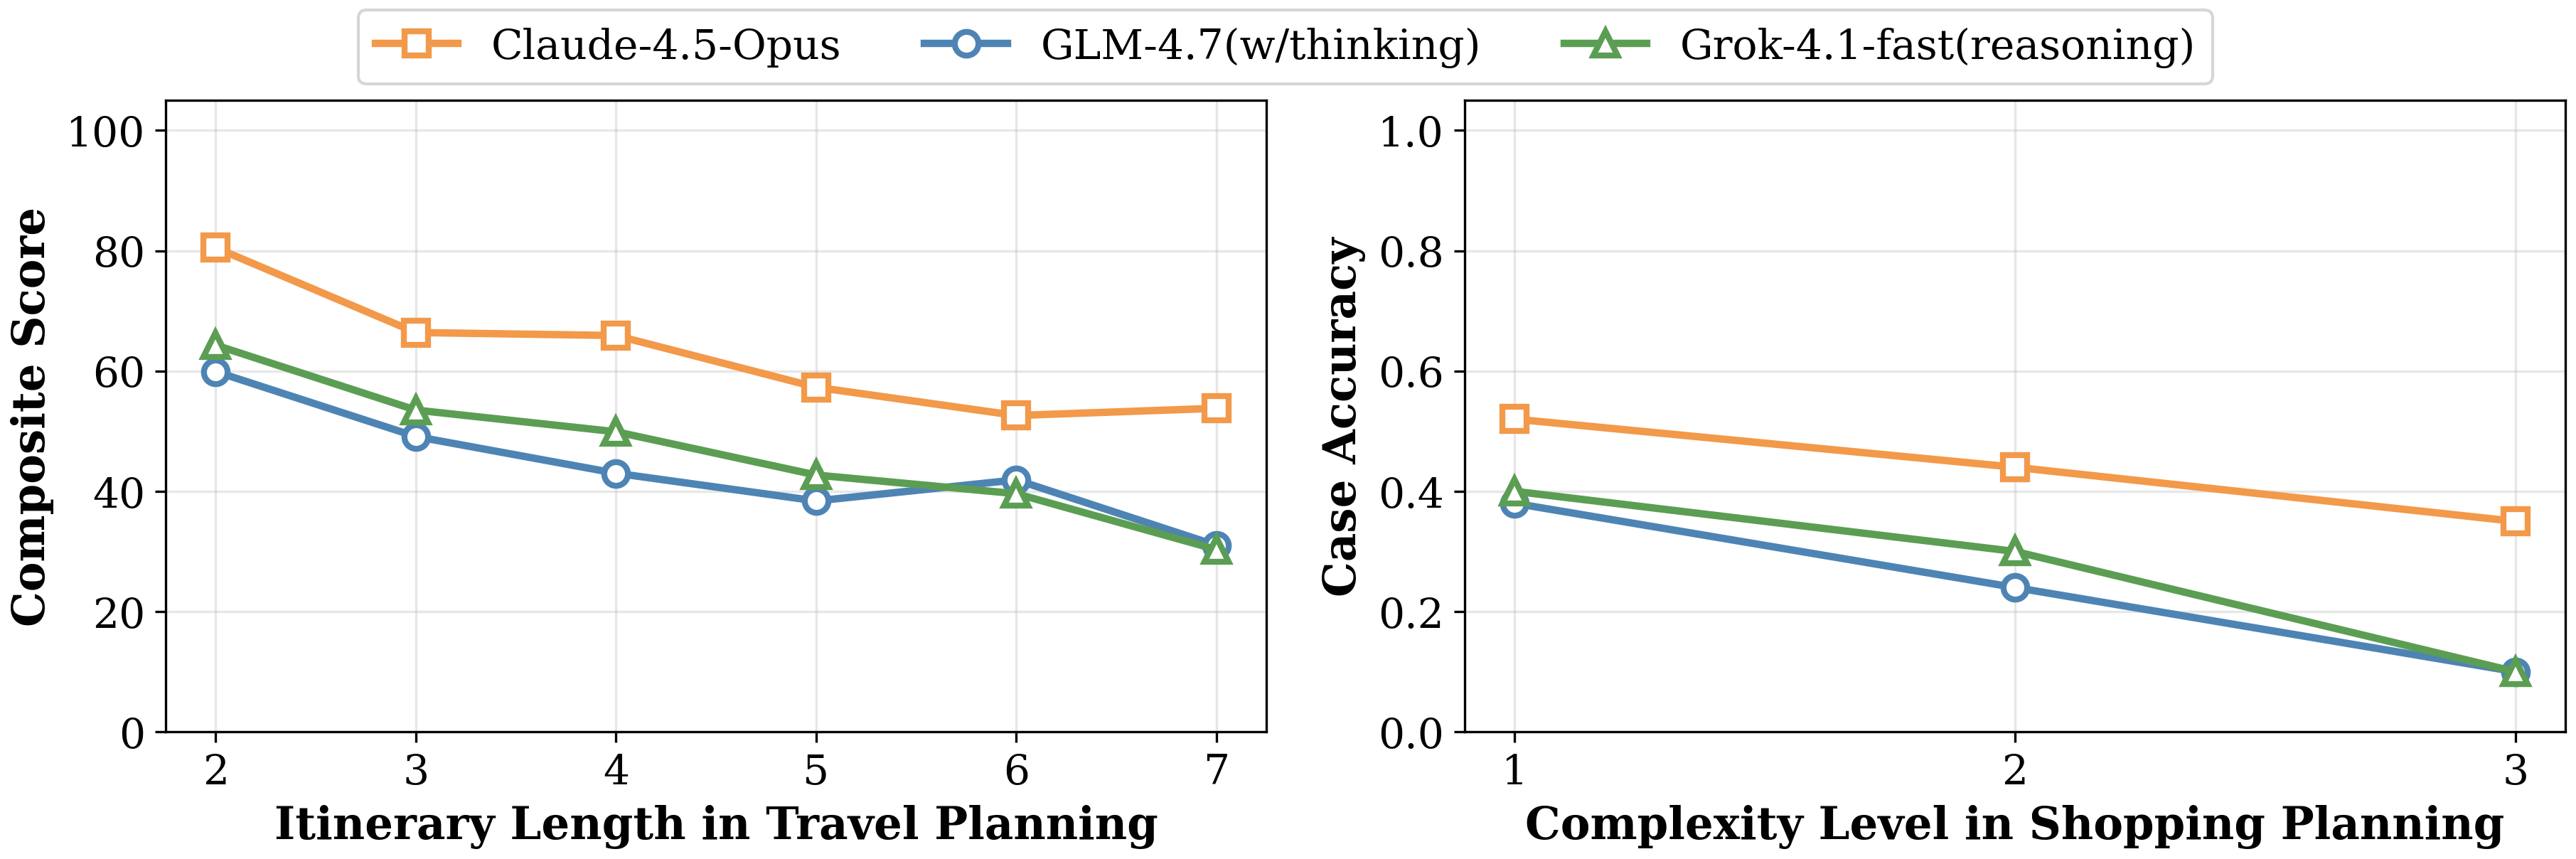
We investigate how task complexity influences model performance in DeepPlanning. We report results for three models from distinct families: Claude-4.5-Opus, GLM-4.7 (w/ thinking), and Grok-4.1-Fast (reasoning). As shown in Figure 4, model performance consistently drops as task complexity increases in both domains. In Travel Planning, composite scores decline as itinerary length increases from 2 to 7 days, indicating that long-horizon planning remains a major bottleneck. As the number of days grows, agents must retrieve and integrate substantially more information, increasing runtime and expanding the space of interacting constraints. Consequently, small local mistakes can propagate across days and ultimately render the overall itinerary infeasible. In Shopping Planning, case accuracy declines from Level 1 to Level 3 as tasks incorporate more cross-item constraints (e.g., price-range requirements for Level 2, and coupon timing for Level 3). This progression shifts the problem from straightforward item matching to a global, joint optimization challenge.
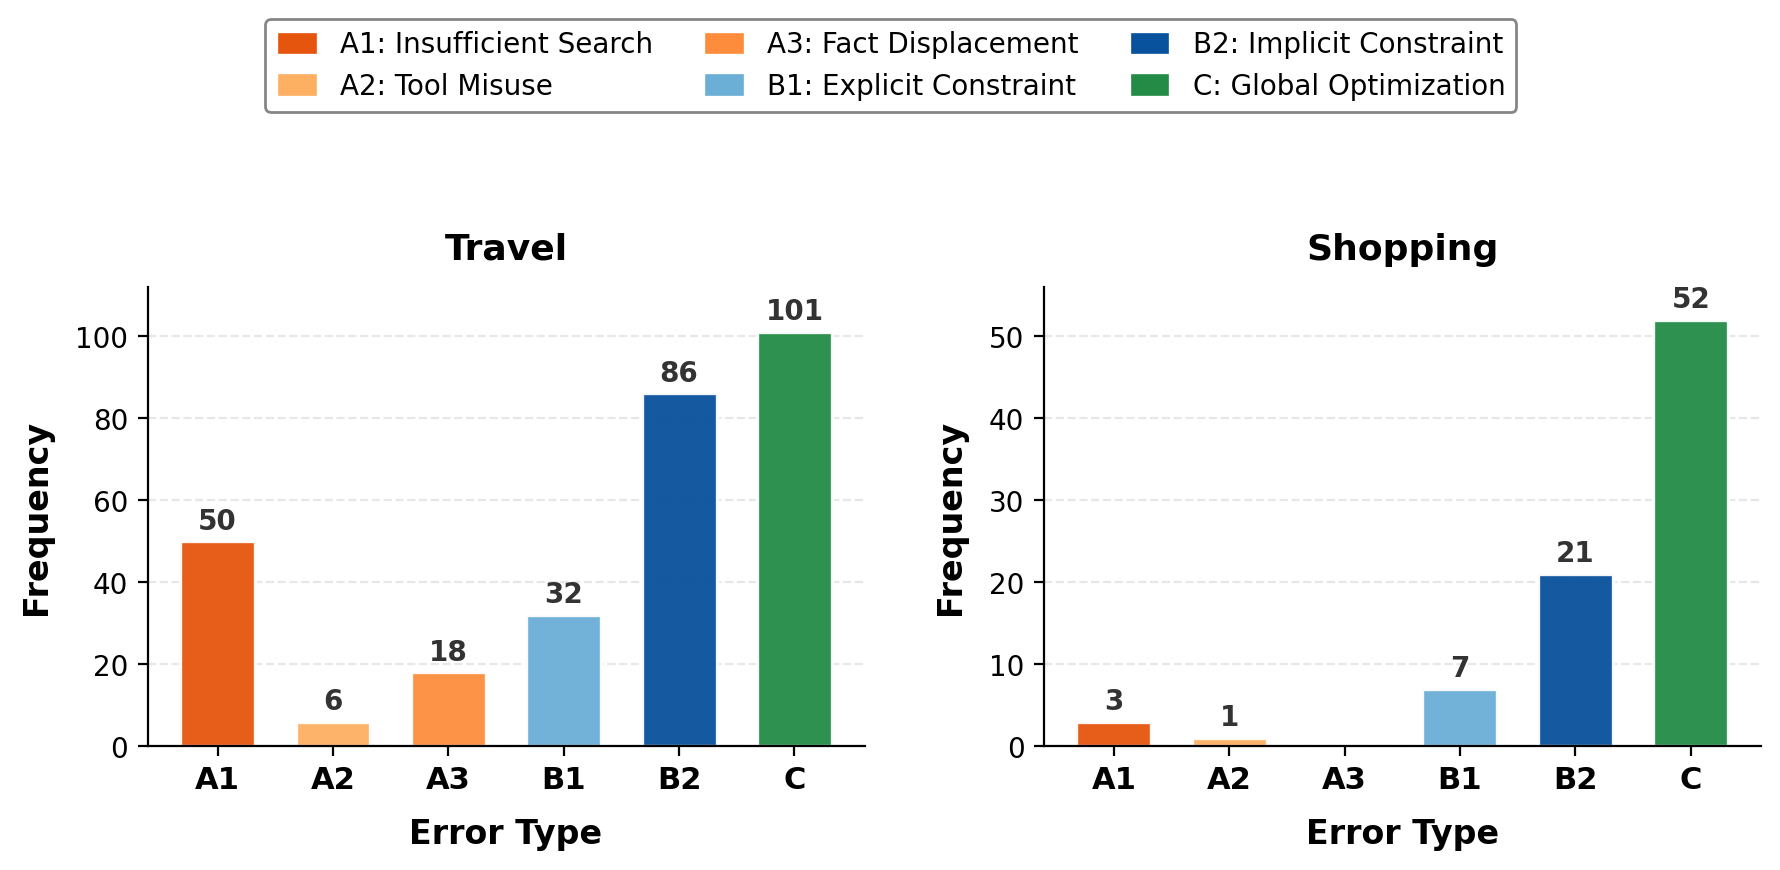
To better understand what drives agent failures in DeepPlanning, we categorize error patterns into the agent competencies discussed earlier and annotate 140 failed trajectories generated by Claude-4.5-Opus (w/ thinking): 80 from Travel Planning and 60 from Shopping Planning. Note that a single failed trajectory may result from a combination of issues. We show their distribution in Figure 5.
This category covers failures in retrieving, perceiving, or correctly using essential environmental information. A1: Insufficient Search refers to the omission of querying critical information. In Travel Planning, this error often exists as agents overlook transit times or distances between specific locations; moreover, as the number of required attractions increases, agents are more likely to skip these critical search steps. A2: Tool Misuse involves selecting inappropriate tools or providing malformed arguments (e.g., coordinate precision mismatches). A3: Fact Displacement arises when agents retrieve the correct information but later misstate it in the final plan or replace it with fabricated values (e.g., recording a retrieved ¥100 price as ¥150 in the itinerary).
These errors arise when the model fails to satisfy constraints at specific decision points despite having access to the correct information. B1: Explicit Constraint violations disregard user-specified requirements (e.g., ignoring a “three-star hotel” preference). B2: Implicit Constraint (86 in Travel, 21 in Shopping) occurs when plans conflict with common sense or environmental reality (e.g., attempting to book flights for 4 people when only 2 tickets are available), indicating deficiencies in non-explicit constraint reasoning.
As the most prevalent failure (101 in Travel, 52 in Shopping), this category reflects a breakdown in integrating interdependent decisions into a holistic plan. This involves an inability to perform systematic trade-offs under overarching constraints, such as failing to find the optimal combination of items and coupons to achieve the lowest final price in shopping, or violating diversity requirements in travel (e.g., repetitive restaurant types or attraction categories over a multi-day trip). It also covers structural incoherence, such as temporal overlaps between steps or logical discontinuities between days, indicating that agents struggle with combinatorial optimization and with satisfying multiple complex constraints in long-horizon tasks.
We introduce DeepPlanning, a challenging benchmark for assessing long-horizon LLM agent planning in real-world settings. Building on multi-day travel and complex shopping scenarios, it enables a systematic evaluation of proactive information gathering and multi-level constrained optimization. Our analysis shows that even state-of-the-art agents struggle significantly with these tasks, revealing a fundamental gap in their planning reliability. This work provides a foundation for developing next-generation agents capable of tackling complex, grounded planning challenges.
Though carefully designed, our proposed benchmark still has several limitations. First, the agent-planning tasks and corresponding environments in DeepPlanning are restricted to the travel and shopping domains. Incorporating a broader range of real-world scenarios would make the benchmark more comprehensive. Second, although we use real-world data to construct databases in sandboxes, the user queries are synthesized by adding multi-level constraints, which may lead to a distribution shift relative to real user queries in these domains. Finally, while the tasks in this work focus on single-turn, multi-step agent planning, modeling multi-turn user-agent interactions remains an important direction for future work.
References
- Andrews et al. (2025) Pierre Andrews, Amine Benhalloum, Gerard Moreno-Torres Bertran, Matteo Bettini, Amar Budhiraja, Ricardo Silveira Cabral, Virginie Do, Romain Froger, Emilien Garreau, Jean-Baptiste Gaya, and 1 others. 2025. ARE: Scaling up agent environments and evaluations. arXiv preprint arXiv:2509.17158.
- Anthropic (2025) Anthropic. 2025. System card: Claude Opus 4.5. https://assets.anthropic.com/m/64823ba7485345a7/Claude-Opus-4-5-System-Card.pdf. Accessed: 2025-12-22.Source
- Barres et al. (2025) Victor Barres, Honghua Dong, Soham Ray, Xujie Si, and Karthik Narasimhan. 2025. $\tau^{2}$-Bench: Evaluating conversational agents in a dual-control environment. arXiv preprint arXiv:2506.07982.
- Comanici et al. (2025) Gheorghe Comanici, Eric Bieber, Mike Schaekermann, Ice Pasupat, Noveen Sachdeva, Inderjit Dhillon, Marcel Blistein, Ori Ram, Dan Zhang, Evan Rosen, and 1 others. 2025. Gemini 2.5: Pushing the frontier with advanced reasoning, multimodality, long context, and next generation agentic capabilities. arXiv preprint arXiv:2507.06261.
- Deng et al. (2023) Xiang Deng, Yu Gu, Boyuan Zheng, Shijie Chen, Samuel Stevens, Boshi Wang, Huan Sun, and Yu Su. 2023. Mind2Web: Towards a generalist agent for the web. In Thirty-seventh Conference on Neural Information Processing Systems Datasets and Benchmarks Track.Source
- Ding et al. (2025) Zifeng Ding, Sikuan Yan, Moy Yuan, Xianglong Hu, Fangru Lin, and Andreas Vlachos. 2025. TCP: a benchmark for temporal constraint-based planning. In Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing, pages 22463–22486, Suzhou, China. Association for Computational Linguistics.Source
- Google (2025) Google. 2025. Gemini 3 pro model card. https://storage.googleapis.com/deepmind-media/Model-Cards/Gemini-3-Pro-Model-Card.pdf. Accessed: 2025-12-22.Source
- He et al. (2024) Hongliang He, Wenlin Yao, Kaixin Ma, Wenhao Yu, Yong Dai, Hongming Zhang, Zhenzhong Lan, and Dong Yu. 2024. WebVoyager: Building an end-to-end web agent with large multimodal models. In Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), pages 6864–6890, Bangkok, Thailand. Association for Computational Linguistics.Source
- He et al. (2025) Wei He, Yueqing Sun, Hongyan Hao, Xueyuan Hao, Zhikang Xia, Qi Gu, Chengcheng Han, Dengchang Zhao, Hui Su, Kefeng Zhang, and 1 others. 2025. VitaBench: Benchmarking llm agents with versatile interactive tasks in real-world applications. arXiv preprint arXiv:2509.26490.
- Li et al. (2023) Minghao Li, Yingxiu Zhao, Bowen Yu, Feifan Song, Hangyu Li, Haiyang Yu, Zhoujun Li, Fei Huang, and Yongbin Li. 2023. API-bank: A comprehensive benchmark for tool-augmented LLMs. In Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing, pages 3102–3116, Singapore. Association for Computational Linguistics.Source
- Liu et al. (2025) Aixin Liu, Aoxue Mei, Bangcai Lin, Bing Xue, Bingxuan Wang, Bingzheng Xu, Bochao Wu, Bowei Zhang, Chaofan Lin, Chen Dong, and 1 others. 2025. DeepSeek-v3.2: Pushing the frontier of open large language models. arXiv preprint arXiv:2512.02556.
- Lyu et al. (2025) Yougang Lyu, Xiaoyu Zhang, Lingyong Yan, Maarten de Rijke, Zhaochun Ren, and Xiuying Chen. 2025. DeepShop: A benchmark for deep research shopping agents. arXiv preprint arXiv:2506.02839.
- OpenAI (2025a) OpenAI. 2025a. GPT-5 system card. https://cdn.openai.com/gpt-5-system-card.pdf. Accessed: 2025-12-22.Source
- OpenAI (2025b) OpenAI. 2025b. OpenAI o3 and o4-mini system card. https://cdn.openai.com/pdf/2221c875-02dc-4789-800b-e7758f3722c1/o3-and-o4-mini-system-card.pdf. Accessed: 2025-12-22.Source
- Patil et al. (2025) Shishir G Patil, Huanzhi Mao, Fanjia Yan, Charlie Cheng-Jie Ji, Vishnu Suresh, Ion Stoica, and Joseph E. Gonzalez. 2025. The berkeley function calling leaderboard (BFCL): From tool use to agentic evaluation of large language models. In Forty-second International Conference on Machine Learning.Source
- Qian et al. (2025) Cheng Qian, Zuxin Liu, Akshara Prabhakar, Zhiwei Liu, Jianguo Zhang, Haolin Chen, Heng Ji, Weiran Yao, Shelby Heinecke, Silvio Savarese, and Huan Wang. 2025. UserBench: An interactive gym environment for user-centric agents. In Workshop on Scaling Environments for Agents.Source
- Qin et al. (2024) Yujia Qin, Shihao Liang, Yining Ye, Kunlun Zhu, Lan Yan, Yaxi Lu, Yankai Lin, Xin Cong, Xiangru Tang, Bill Qian, Sihan Zhao, Lauren Hong, Runchu Tian, Ruobing Xie, Jie Zhou, Mark Gerstein, dahai li, Zhiyuan Liu, and Maosong Sun. 2024. ToolLLM: Facilitating large language models to master 16000+ real-world APIs. In The Twelfth International Conference on Learning Representations.Source
- Qu et al. (2025) Yincen Qu, Huan Xiao, Feng Li, Gregory Li, Hui Zhou, Xiangying Dai, and Xiaoru Dai. 2025. TripScore: Benchmarking and rewarding real-world travel planning with fine-grained evaluation. arXiv preprint arXiv:2510.09011.
- Seed et al. (2025) ByteDance Seed, Jiaze Chen, Tiantian Fan, Xin Liu, Lingjun Liu, Zhiqi Lin, Mingxuan Wang, Chengyi Wang, Xiangpeng Wei, Wenyuan Xu, and 1 others. 2025. Seed1.5-Thinking: Advancing superb reasoning models with reinforcement learning. arXiv preprint arXiv:2504.13914.
- Shao et al. (2025) Jie-Jing Shao, Bo-Wen Zhang, Xiao-Wen Yang, Baizhi Chen, Siyu Han, Wen-Da Wei, Guohao Cai, Zhenhua Dong, Lan-Zhe Guo, and Yu-Feng Li. 2025. ChinaTravel: An open-ended benchmark for language agents in chinese travel planning. In NeurIPS 2025 Workshop on Evaluating the Evolving LLM Lifecycle: Benchmarks, Emergent Abilities, and Scaling.Source
- Singh et al. (2024) Harmanpreet Singh, Nikhil Verma, Yixiao Wang, Manasa Bharadwaj, Homa Fashandi, Kevin Ferreira, and Chul Lee. 2024. Personal large language model agents: A case study on tailored travel planning. In Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing: Industry Track, pages 486–514, Miami, Florida, US. Association for Computational Linguistics.Source
- Stechly et al. (2025) Kaya Stechly, Karthik Valmeekam, and Subbarao Kambhampati. 2025. On the self-verification limitations of large language models on reasoning and planning tasks. In The Thirteenth International Conference on Learning Representations.Source
- Team et al. (2025) Kimi Team, Yifan Bai, Yiping Bao, Guanduo Chen, Jiahao Chen, Ningxin Chen, Ruijue Chen, Yanru Chen, Yuankun Chen, Yutian Chen, and 1 others. 2025. Kimi K2: Open agentic intelligence. arXiv preprint arXiv:2507.20534.
- Valmeekam et al. (2023) Karthik Valmeekam, Matthew Marquez, Alberto Olmo, Sarath Sreedharan, and Subbarao Kambhampati. 2023. PlanBench: An extensible benchmark for evaluating large language models on planning and reasoning about change. In Thirty-seventh Conference on Neural Information Processing Systems Datasets and Benchmarks Track.Source
- Wang et al. (2025) Kaimin Wang, Yuanzhe Shen, Changze Lv, Xiaoqing Zheng, and Xuanjing Huang. 2025. TripTailor: A real-world benchmark for personalized travel planning. In Findings of the Association for Computational Linguistics: ACL 2025, pages 9705–9723, Vienna, Austria. Association for Computational Linguistics.Source
- Wei et al. (2025) Jason Wei, Zhiqing Sun, Spencer Papay, Scott McKinney, Jeffrey Han, Isa Fulford, Hyung Won Chung, Alex Tachard Passos, William Fedus, and Amelia Glaese. 2025. Browsecomp: A simple yet challenging benchmark for browsing agents. arXiv preprint arXiv:2504.12516.
- xAI (2025) xAI. 2025. Grok 4.1 model card. https://data.x.ai/2025-11-17-grok-4-1-model-card.pdf. Accessed: 2025-12-22.Source
- Xie et al. (2024) Jian Xie, Kai Zhang, Jiangjie Chen, Tinghui Zhu, Renze Lou, Yuandong Tian, Yanghua Xiao, and Yu Su. 2024. TravelPlanner: A benchmark for real-world planning with language agents. In Forty-first International Conference on Machine Learning.Source
- Yang et al. (2025) An Yang, Anfeng Li, Baosong Yang, Beichen Zhang, Binyuan Hui, Bo Zheng, Bowen Yu, Chang Gao, Chengen Huang, Chenxu Lv, and 1 others. 2025. Qwen3 technical report. arXiv preprint arXiv:2505.09388.
- Yao et al. (2022) Shunyu Yao, Howard Chen, John Yang, and Karthik R Narasimhan. 2022. WebShop: Towards scalable real-world web interaction with grounded language agents. In Advances in Neural Information Processing Systems.Source
- Yao et al. (2024) Shunyu Yao, Noah Shinn, Pedram Razavi, and Karthik Narasimhan. 2024. $\tau$-Bench: A benchmark for tool-agent-user interaction in real-world domains. arXiv preprint arXiv:2406.12045.
- Zeng et al. (2025) Aohan Zeng, Xin Lv, Qinkai Zheng, Zhenyu Hou, Bin Chen, Chengxing Xie, Cunxiang Wang, Da Yin, Hao Zeng, Jiajie Zhang, and 1 others. 2025. GLM-4.5: Agentic, reasoning, and coding (arc) foundation models. arXiv preprint arXiv:2508.06471.
- Zhang et al. (2024) Yikai Zhang, Siyu Yuan, Caiyu Hu, Kyle Richardson, Yanghua Xiao, and Jiangjie Chen. 2024. TimeArena: Shaping efficient multitasking language agents in a time-aware simulation. In Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), pages 3894–3916, Bangkok, Thailand. Association for Computational Linguistics.Source
- Zhou et al. (2024) Shuyan Zhou, Frank F. Xu, Hao Zhu, Xuhui Zhou, Robert Lo, Abishek Sridhar, Xianyi Cheng, Tianyue Ou, Yonatan Bisk, Daniel Fried, Uri Alon, and Graham Neubig. 2024. WebArena: A realistic web environment for building autonomous agents. In The Twelfth International Conference on Learning Representations.Source
Box shows an example output for the travel planning task: a two-day travel plan including the itinerary and budget.
Box shows an example output for the shopping planning task: a shopping cart that includes the items selected by the agent and the coupons to be used.
Table 5 shows the detailed descriptions of the 21 scoring criteria for commonsense score in Travel Planning.
This section presents the system prompts for the Travel Planning (Box ) and Shopping Planning tasks (Box ), as well as the prompt used for plan format conversion in the Travel Planning domain (Box ).
| Tool | Tool Description | Parameters |
| query_train_info | Query train ticket information by origin, destination, date and other conditions. Returns train number, departure/arrival time, station information, journey duration, seat class, remaining seats status, price, etc. | origin (string, required): Origin city name. destination (string, required): Destination city name. depDate (string, required): Departure date (YYYY-MM-DD). seatClassName (string): Seat class (First/Second/Business). |
| query_flight_info | Query flight information by origin, destination, date and other conditions. Returns flight number, departure/arrival time, airport information, journey duration, seat class, price, aircraft type, etc. | origin (string, required): Origin city name. destination (string, required): Destination city name. depDate (string, required): Departure date (YYYY-MM-DD). seatClassName (string): Seat class (Economy/Business/First). |
| query_hotel_info | Search hotels based on destination, check-in/out dates, star rating, and brand. Returns hotel information matching the criteria. | destination (string, required): Destination city/district name. checkinDate (string, required): Check-in date (yyyy-MM-dd). checkoutDate (string, required): Check-out date (yyyy-MM-dd). hotelStar (string): Hotel star rating (1-5). hotelBrands (string): Hotel brand name. |
| query_road_route_info | Calculate road route details between two locations including distance (meters), duration (minutes) and cost. Auto-selects walking or driving mode. | origin (string, required): Origin coordinates (latitude,longitude). destination (string, required): Destination coordinates (lat,lng). |
| query_attraction_details | Query detailed information about an attraction including ID, name, coordinates, description, rating, opening hours, ticket price, and recommended visit duration. | attraction_name (string, required): Attraction name. |
| query_restaurant_details | Query detailed information about a restaurant including name, coordinates, price per person, opening/closing time, and rating. | restaurant_name (string, required): Restaurant name. |
| recommend_attractions | Search and return popular attraction information for a city. Returns attraction name, description, type, etc. based on city keyword. | city (string, required): City name or keyword. attraction_type (string): Type filter (Historical/Natural/ Art/Landmark/Theme Park/Leisure). |
| recommend_restaurants | Recommend nearby restaurants based on specified coordinates. Returns restaurant name, coordinates, price per person, rating, business hours, etc. | latitude (string, required): Latitude coordinate (6 decimals). longitude (string, required): Longitude coordinate (6 decimals). |
| search_location | Query the latitude and longitude coordinates corresponding to a place name, with precision retained to six decimal places. | place_name (string, required): Place name to query. |
View original table
| Tool | Tool Description | Parameters |
| search_products | Handles open-ended queries by performing a semantic search on product information to retrieve an initial set of relevant items. | query (string, required): User’s natural language query. limit (integer): Limits the number of products returned. |
| filter_by_brand | Filters a list of products by one or more brand names using OR logic. | product_ids (array): List of product IDs to filter. brand_names (array, required): Brand names to match. |
| filter_by_color | Filters a list of products by one or more colors using OR logic. | product_ids (array): List of product IDs to filter. colors (array, required): Colors to match. |
| filter_by_size | Filters a list of products by one or more sizes using OR logic. | product_ids (array): List of product IDs to filter. sizes (array, required): Sizes to match. |
| filter_by_applicable_coupons | Filters products that are eligible for all specified coupon names. | product_ids (array): List of product IDs to filter. coupon_names (array, required): Coupon names to match. |
| filter_by_range | Filters products based on a numerical feature, an operator, and a threshold value. | product_ids (array): List of product IDs to filter. condition_key (string, required): Numerical feature to filter on. operator (string, required): e.g., ’>’, ’<=’, ’==’. value (number, required): Threshold value to compare against. |
| sort_products | Sorts a list of products according to a specified dimension and order. | product_ids (array): List of product IDs to sort. sort_by (string, required): Feature to sort by. order (string): Sorting order (’asc’ or ’desc’). |
| get_product_details | Retrieves complete, detailed information for a list of product IDs. | product_ids (array, required): List of product IDs to fetch. |
| calculate_transport_time | Calculates the estimated delivery time in days based on origin and destination. | product_id (string, required): Product’s unique identifier. destination_address (string, required): User’s destination (pinyin). provider (string): Optional shipping provider name. |
| get_user_info | Retrieves profile information for the current or a specified user. | user_id (string): Optional user ID to retrieve information for. |
| add_product_to_cart | Adds a specified product and quantity to the shopping cart, checking for stock availability. | product_id (string, required): Product identifier to add. quantity (integer): Quantity to add (defaults to 1). |
| delete_product_from_cart | Removes a specified product or reduces its quantity in the shopping cart. | product_id (string, required): Product identifier to remove. quantity (integer): Quantity to remove (defaults to 1). |
| get_cart_info | Retrieves all items and summary statistics for the current shopping cart. | None |
| add_coupon_to_cart | Adds a coupon to the cart, validates its applicability, and updates the cart summary. | coupon_name (string, required): Name of the coupon to add. quantity (integer): Number of coupons to use (defaults to 1). |
| delete_coupon_from_cart | Removes a coupon from the cart or reduces its quantity, and updates the cart summary. | coupon_name (string, required): Name of the coupon to remove. quantity (integer): Number of coupons to remove (defaults to 1). |
View original table
| Schema (field definitions) of the Travel Planning environment databases (CSV files). | ||
| Table (CSV) | Field | Description (Type) |
| Table 4 – continued from previous page | ||
| Table (CSV) | Field | Description (Type) |
| Continued on next page… | ||
| attractions.csv | city | City name (string). |
| attraction_name | Attraction name used for tool calls; must match exactly (string). | |
| attraction_id | Unique attraction identifier (string). | |
| description | Short textual description of the attraction (string). | |
| attraction_type | One of {Historical and Cultural, Natural Scenery, Art Exhibition, City Landmark, Theme Park, Leisure Experience} (string/categorical). | |
| latitude | Latitude, 6-decimal precision (float). | |
| longitude | Longitude, 6-decimal precision (float). | |
| rating | User rating score (float). | |
| opening_time | Daily opening time; may be “Open 24 Hours” (string). | |
| closing_time | Daily closing time; may be “Open 24 Hours” (string). | |
| closing_dates | Regular closing day(s), e.g., Monday; empty if none (string). | |
| min_visit_hours | Minimum recommended visit duration in hours (float). | |
| max_visit_hours | Maximum recommended visit duration in hours (float). | |
| ticket_price | Ticket price (numeric). | |
| flights.csv | origin_city | Origin city name (string). |
| destination_city | Destination city name (string). | |
| dep_date | Departure date, format YYYY-MM-DD (date string). | |
| dep_station_code | Departure airport IATA code (string). | |
| dep_station_name | Departure airport full name (string). | |
| arr_station_code | Arrival airport IATA code (string). | |
| arr_station_name | Arrival airport full name (string). | |
| dep_datetime | Departure local datetime, format YYYY-MM-DD HH:MM:SS (datetime string). | |
| arr_datetime | Arrival local datetime, format YYYY-MM-DD HH:MM:SS (datetime string). | |
| duration | Flight segment duration in minutes (int). | |
| flight_no | Flight number (string). | |
| airline | Airline name (string). | |
| seat_class | Cabin class, e.g., Economy Class/Business Class/First Class (string). | |
| seat_status | Seat availability status, e.g., Sufficient/Limited/Sold Out (string/categorical). | |
| equip_type | Aircraft model code, e.g., 320/320NEO/C909 (string). | |
| equip_size | Aircraft size category, e.g., Medium Aircraft (string/categorical). | |
| manufacturer | Aircraft manufacturer, e.g., Airbus/Boeing (string/categorical). | |
| price | Ticket price for this segment (numeric). | |
| segment_index | Segment index within a route (int; starts from 1). | |
| route_index | Route identifier for grouping segments (int). | |
| trains.csv | origin_city | Origin city name (string). |
| destination_city | Destination city name (string). | |
| dep_date | Departure date, format YYYY-MM-DD (date string). | |
| dep_station_code | Departure station code (string). | |
| dep_station_name | Departure station name (string). | |
| arr_station_code | Arrival station code (string). | |
| arr_station_name | Arrival station name (string). | |
| dep_datetime | Departure datetime, format YYYY-MM-DD HH:MM:SS (datetime string). | |
| arr_datetime | Arrival datetime, format YYYY-MM-DD HH:MM:SS (datetime string). | |
| duration | Travel duration in minutes (int). | |
| train_no | Train number, e.g., D3074/T235 (string). | |
| train_type | Train type, e.g., Electric Multiple Unit/Regular Train (string/categorical). | |
| seat_class | Seat class, e.g., Second Class Seat/Hard Seat (string/categorical). | |
| seat_status | Remaining seats count or availability indicator (int/string). | |
| price | Ticket price for this segment (numeric). | |
| segment_index | Segment index within a route (int; starts from 1). | |
| route_index | Route identifier for grouping segments (int). | |
| hotels.csv | city | City name (string). |
| name | Hotel name (string). | |
| address | Hotel address (string). | |
| latitude | Latitude, 6-decimal precision (float). | |
| longitude | Longitude, 6-decimal precision (float). | |
| decoration_time | Last decoration/renovation year (int). | |
| hotel_star | Star rating, typically 1–5 (int). | |
| price | Price per night (numeric). | |
| score | User rating score (float). | |
| brand | Hotel brand, e.g., Home Inn/Jinjiang Inn (string/categorical). | |
| services | Semicolon-separated service tags, e.g., Washer and Dryer (string). | |
| restaurants.csv | restaurant_name | Restaurant name (string). |
| city | City name (string). | |
| latitude | Latitude, 6-decimal precision (float). | |
| longitude | Longitude, 6-decimal precision (float). | |
| price_per_person | Average price per person (numeric). | |
| cuisine | Cuisine/category labels (string; may be semicolon-separated). | |
| opening_time | Opening time (HH:MM or textual; string). | |
| closing_time | Closing time (HH:MM or textual; string). | |
| nearby_attraction_name | Associated nearby attraction name for the query context (string). | |
| nearby_attraction_coords | Nearby attraction coordinates in “lon,lat” (string). | |
| query_latitude | Latitude used to query nearby restaurants (float). | |
| query_longitude | Longitude used to query nearby restaurants (float). | |
| rating | User rating score (float). | |
| tags | Semicolon-separated tags, e.g., Must-Eat Top 10 (string). | |
| pois.csv | poi_name | POI name (string). |
| latitude | Latitude, 6-decimal precision (float). | |
| longitude | Longitude, 6-decimal precision (float). | |
| address | POI address (string; may be empty). | |
| poi_type | POI type, e.g., attraction/restaurant/hotel (string/categorical). | |
| road_routes.csv | origin | Origin coordinates in “lat,lon” (string). |
| destination | Destination coordinates in “lat,lon” (string). | |
| distance_meters | Route distance in meters (int). | |
| duration_minutes | Estimated duration in minutes (int). | |
| cost | Estimated monetary cost (numeric; 0 for walking). | |
View original table
| Schema (field definitions) of the Shopping Planning environment databases (JSON files). | ||
| Table (JSON) | Field | Description (Type) |
| Table 4 – continued from previous page | ||
| Table (JSON) | Field | Description (Type) |
| Continued on next page… | ||
| products.json | product_id | Unique product identifier (string). |
| name | Product name (string). | |
| price | Product price (numeric). | |
| brand | Brand name (string). | |
| color | Product color (string). | |
| size | Size specification, e.g., S/M/L/XL (string). | |
| stock_quantity | Available stock quantity (int). | |
| material_composition | Material composition list; each item contains material name and percentage (JSON array). | |
| thickness | Fabric thickness, e.g., Regular/Thin/Thick (string/categorical). | |
| elasticity | Elasticity level, e.g., Non-stretch/Slightly-stretch/High-stretch (string/categorical). | |
| version_type | Fit type, e.g., Regular Fit/Slim Fit/Loose Fit (string/categorical). | |
| collar_type | Collar type, e.g., Stand Collar/V-Neck/Round Neck (string/categorical). | |
| suitable_season | Suitable season(s), e.g., Summer/Winter/All Season (string/categorical). | |
| target_demographic | Target demographic, e.g., Men/Women/Unisex/Kids (string/categorical). | |
| details_craftsmanship | Design details and craftsmanship, e.g., Side Pockets, Zipper Closure (string). | |
| washing_instructions | Washing and care instructions (string). | |
| monthly_sales | Monthly sales volume (int). | |
| total_sales | Total sales volume (int). | |
| average_rating | Average rating score (float). | |
| total_reviews | Total number of reviews (int). | |
| rating_5star | Number of 5-star ratings (int). | |
| rating_4star | Number of 4-star ratings (int). | |
| rating_3star | Number of 3-star ratings (int). | |
| rating_2star | Number of 2-star ratings (int). | |
| rating_1star | Number of 1-star ratings (int). | |
| review_summary | Common review keywords/phrases (string; may be semicolon-separated). | |
| shipping_origin | Shipping origin location (string). | |
| shipping_provider | Shipping provider name, e.g., SF Express/YTO Express (string). | |
| users.json | user_id | Unique user identifier (string). |
| username | Username (string). | |
| phone_number | User’s phone number (string). | |
| is_vip | VIP membership status (boolean). | |
| gender | Gender, e.g., Male/Female/Other (string/categorical). | |
| age | User’s age (int). | |
| birthday | Date of birth, format YYYY-MM-DD (date string). | |
| height_cm | Height in centimeters (float). | |
| weight_kg | Weight in kilograms (float). | |
| preference_fit | Preferred fit type, e.g., Regular Fit/Slim Fit (string/categorical). | |
| standard_size_tops | Standard size for tops, e.g., S/M/L/XL (string). | |
| standard_size_bottoms | Standard size for bottoms, e.g., S/M/L/XL (string). | |
| standard_size_shoes | Standard shoe size, e.g., 40/41/42/43 (string). | |
| shipping_phone | Shipping contact phone number (string). | |
| shipping_province | Shipping address province (string). | |
| shipping_city | Shipping address city (string). | |
| shipping_detail_address | Detailed shipping address (string). | |
View original table
| Dimension | Description | Sub-Checkpoints |
| Route Consistency | Validates the logical connectivity of the route and the accuracy of day counting. | - Valid trip duration - Closed-loop route structure - Seamless intercity transfers |
| Sandbox Compliance | Verifies that all scheduled activities exist within the provided search database. | - Validated Accommodation - Validated Attractions - Validated Meals - Validated Transportation |
| Itinerary Structure | Checks for the logical arrangement and completeness of daily plans. | - Traceable accommodation - Ends with accommodation - Essential meal coverage - Essential attraction coverage |
| Time Feasibility | Ensures the schedule is physically executable without temporal conflicts. | - No time overlaps - Reasonable transfer time |
| Business Hours | Ensures all attraction visits and dining occur during operating hours. | - Attraction visit within opening hours - Dining within service hours - Avoidance of closure days |
| Duration Rationality | Assesses whether the time allocated to activities is reasonable (i.e., falls within the minimum and maximum time specified in the database information) | - Reasonable duration at attractions - Reasonable meal duration |
| Cost Calculation Accuracy | Ensures the aggregation cost is calculated correctly | - Cost calculation correctness |
| Activity Diversity | Encourages variety in planned activity options. | - Diverse meal options - Diverse attraction options |
View original table