SkillNet: Create, Evaluate, and Connect AI Skills
arXiv:2603.04448v3 · This workspace stays on this version. Check arXiv for newer versions
Some source details need review 5 to check
Original formulas, table values and figures are preserved. Comparison can miss differences; use the original PDF to check details.
Reading view checked: 30 math expressions, 0 rendering failures; 9 of 10 images available.
Compared 88 of 88 source passages against 31 of 34 PDF pages.
The HTML source contains failed formatting commands; these were omitted from the reading view. The original sources are retained. (4)
- Some figure, table or graphic images are unavailable; the original paper is still accessible. (1)
- S5_SS4_tab1: blank, oversized or incomplete source rendering; capture unavailable.
- This long paper was only partially compared; the original sources remain available.
HTML S5_T2 says “Detailed explanations for each trait are provided in Appendix [12](#S12).” The original PDF page 12 says “Detailed explanations for each trait are provided in Appendix A.” Check PDF page 12
PDF page 12 visibly reads “as illustrated in Figure ??”; HTML block S5_SS3_SSS0_Px1_p1_1 reads “as illustrated in Figure .” Check PDF page 12
9 of 10 figure, table and graphic images captured. Open original PDF
Abstract
Current AI agents can flexibly invoke tools and execute complex tasks, yet their long-term advancement is hindered by the lack of systematic accumulation and transfer of skills. Without a unified mechanism for skill consolidation, agents frequently “reinvent the wheel”, rediscovering solutions in isolated contexts without leveraging prior strategies. To address this challenge, we introduce SkillNet, an open infrastructure for creating, evaluating, and organizing AI skills at scale. SkillNet structures skills within a unified ontology that supports creating skills from heterogeneous sources, establishing rich relational connections, and performing multi-dimensional evaluation across Safety, Completeness, Executability, Maintainability, and Cost-awareness. Our infrastructure integrates a repository of over 600,000 skills, an interactive platform, and a versatile Python toolkit. Experiments on ALFWorld, WebShop, and ScienceWorld show 40% higher average rewards and 30% fewer execution steps across multiple backbone models. Furthermore, SkillNet-Gym benchmarks skill retrieval, utilization, and composition, while SkillNet-Fabric enables task-specific skill routing through lightweight Wikis. By formalizing skills as evolving, composable assets, SkillNet provides a robust foundation for agents to move from transient experience to durable mastery.
1]Zhejiang University 2]Tongji University 3]Southeast University 4]Alibaba Group 5]Ant Group 6]Tencent 7]OPPO 8]HomologyAI 9]Fudan University 10]MemTensor (Shanghai) Technology 11]UCLA 12]UCSD 13]The University of Edinburgh 14]Monash University 15]NUS 16]NTU 17]Huzhou University 18]Honor Device Co., Ltd 19]Hangzhou Institute for Advanced Study, UCAS , Website , https://github.com/zjunlp/SkillNet
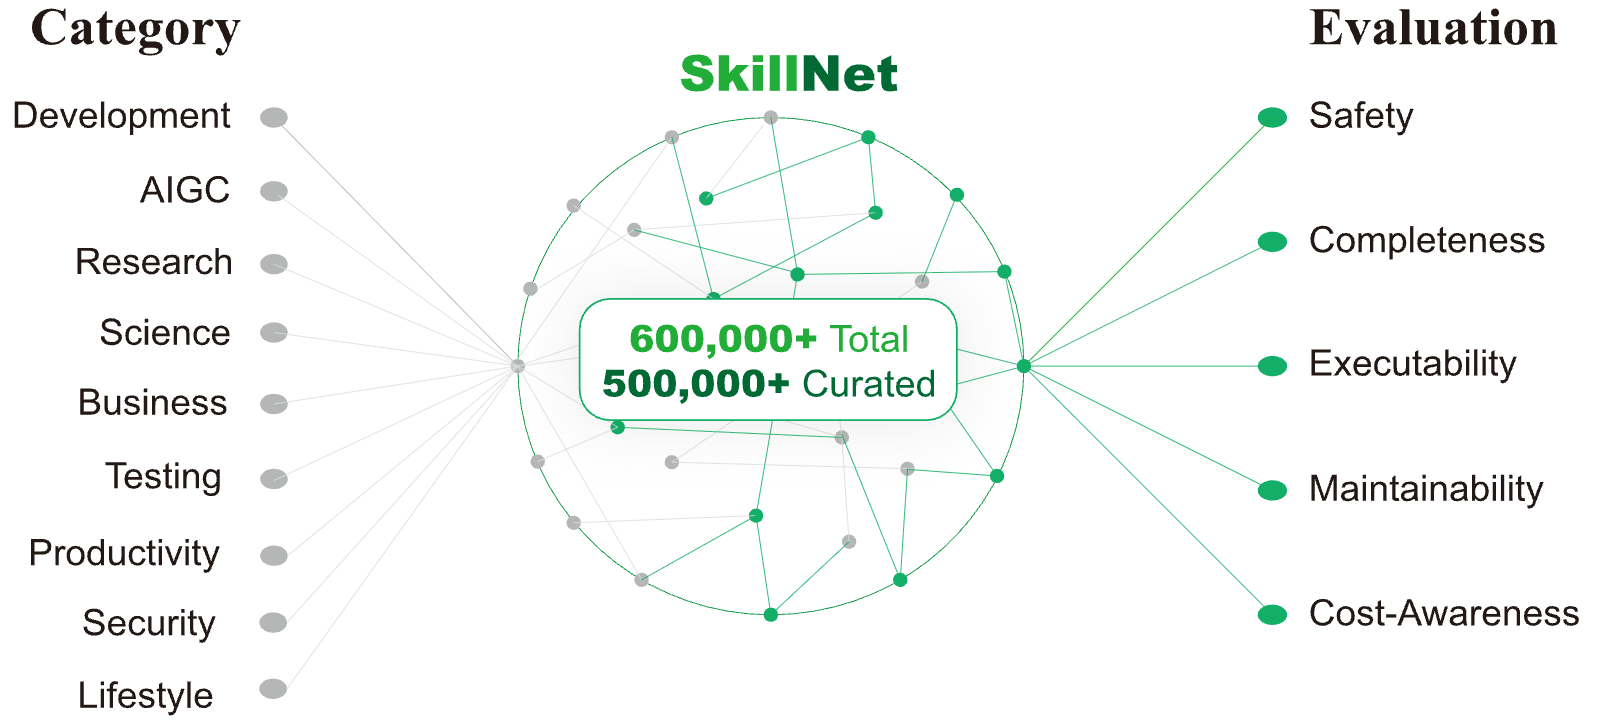
As Richard S. Sutton noted, “we are in the era of experience” [1]. Intelligence is increasingly grounded not in ab initio knowledge acquisition, but in the efficient retrieval and adaptive reuse of heuristics distilled from prior experience. This transition marks the advent of the agent era, where AI moves beyond static question answering to orchestrate long-horizon, executable tasks [2, 3, 4, 5, 6, 7, 8]. Despite recent progress in agentic systems, a critical yet underexplored question remains: How can agents systematically consolidate episodic experience into durable, transferable mastery?
Current AI methods largely rely on manual engineering or transient in-context learning [9, 10, 11]. While humans excel at consolidating episodic experience into reusable schemas [12], for instance when a programmer internalizes the logic of an algorithm rather than merely memorizing its syntax, contemporary AI systems struggle to bridge the divide between transient context and long-term capability. Without a unified mechanism for skill consolidation and sharing, agents repeatedly “reinvent the wheel” in isolated contexts, and even well-established strategies rarely inform future tasks. This gap highlights a broader, longstanding tension in AI between explicit structure and scalable representation, a limitation that becomes especially evident when examined through the historical evolution of knowledge engineering [13]:
- •
- •
- •
This historical trajectory suggests a natural progression toward skills as modular, externalized units of knowledge that reconcile structural interpretability with scalable representation. Consequently, the central challenge in the agent era is no longer merely learning from experience, but transforming fragmented experience into durable, composable skill units that support generalizable intelligence. However, current AI approaches fall short in two fundamental respects. First, there is no unified mechanism to acquire and consolidate skills from experience. Valuable expertise exists at scale across open-source repositories, academic publications, and agent execution traces [23, 24], yet it remains largely unstructured and disconnected. Unlike human learners, who continuously internalize external information into organized knowledge schemas, AI agents cannot automatically distill these resources into reusable, executable capabilities. As a result, skill acquisition remains a manual and episodic process rather than an autonomous, cumulative one [3]. Second, there is no principled framework to validate and maintain skill quality at scale. Without intrinsic and systematic evaluation, skill repositories are prone to “pollution,” where executability, safety, and robustness are assessed only indirectly through downstream task success [25, 26, 27]. Such stochastic and opaque validation introduces technical debt, undermining long-term capability growth and preventing agents from leveraging accumulated experience in a reliable and scalable manner. Together, these gaps highlight the need for a structured framework that not only captures and organizes skills, but also rigorously evaluates and interconnects them to enable dependable, large-scale knowledge reuse.
To address these issues, we introduce SkillNet (Figure 1), an open infrastructure for creating, evaluating, and organizing AI skills at scale. We conceptualize a skill as a unified knowledge representation that bridges unstructured language understanding with structured, machine-executable logic. SkillNet constructs a comprehensive Skill Ontology with three interconnected layers: a taxonomic layer for functional categorization, a relational layer encoding dependencies and composition, and a skill-package layer for modular deployment. To ensure the reliability of these skills, we propose a multi-dimensional evaluation framework that assesses skills based on Safety, Completeness, Executability, Maintainability, and Cost-awareness.
Our approach transforms fragmented experience from diverse sources, including execution trajectories, open-source repositories, and documentation, into a structured network of over 500,000 curated skills. Experimental results across three text-based simulated environments (ALFWorld, WebShop, and ScienceWorld) demonstrate that agents augmented with SkillNet achieve substantial gains. For instance, our approach improves the average reward by 40% while reducing interaction steps by 30% across various backbone models (e.g., DeepSeek V3, Gemini 2.5 Pro, and o4 Mini), validating that systematic skill accumulation effectively enhances agent competence cumulatively rather than episodically.
Our contributions are summarized as follows:
- 1.
We introduce SkillNet, a unified framework that transforms fragmented agent experience into a structured network of modular, composable skills with rich relational modeling, serving as a scalable foundation for actionable knowledge engineering.
- 2.
We establish a rigorous skill evaluation protocol that quantitatively measures safety, completeness, executability, maintainability, and cost-awareness, ensuring the reliability of large-scale skill repositories.
- 3.
We release an open-source ecosystem, including a repository of over 500,000 curated skills, a Python toolkit, and comprehensive benchmarks, which empirically demonstrate significant performance improvements in agent planning and execution tasks.
- 4.
We introduce SkillNet-Gym, a dynamic benchmark automatically constructed from real-world skill ecosystems to evaluate skill construction, retrieval, and composition. Experiments across diverse frontier models and agent harnesses reveal that current agents remain limited in open-world skill utilization, particularly in skill retrieval and multi-skill orchestration.
- 5.
We develop SkillNet-Fabric, a task time routing layer that places a task specific Wiki between the global skill ecosystem and final set formation. Evaluations on routing and downstream benchmarks demonstrate improved routing quality and task performance across the tested settings.
In the context of agentic systems, skills represent a lightweight, modular, and reusable abstraction for extending the capabilities of AI agents [28]. Conceptually, a skill encapsulates procedural knowledge, task-specific instructions, and supporting resources, enabling agents to perform complex tasks more accurately, efficiently, and consistently.
Functionally, skills are organized as structured folders containing a central SKILL.md file, which defines the skill’s metadata and detailed instructions. The metadata typically includes the skill’s name, a brief description of its purpose, and usage conditions, while the instructions provide step-by-step guidance for execution. Skills may optionally include scripts, templates, documentation, and other resources required to perform tasks, forming a self-contained capability package.
The core purpose of skills is to provide agents with access to reusable procedural knowledge and context-specific information on demand. For example, an agent can leverage a skill to automate a data analysis pipeline, perform domain-specific reasoning, or generate structured outputs such as reports or presentations. By encapsulating these capabilities, skills enable consistent and repeatable workflows, reduce reliance on hard-coded rules or ad hoc prompts, and allow knowledge to be shared across agents, teams, or applications.
Skills operate through a progressive three-step process:
- 1.
Discovery: Agents initially load only minimal metadata (e.g., name and description) to identify potentially relevant skills for a given task.
- 2.
Activation: When a task matches a skill’s description, the agent reads the full instructions from SKILL.md and prepares any associated resources.
- 3.
Execution: The agent follows the instructions and optionally executes bundled code or utilizes referenced assets to complete the task.
One of the key benefits of skills is that they are self-documenting. The embedded instructions and structured metadata make it straightforward to understand, audit, and iteratively improve each capability. Fundamentally, a skill serves as a unified knowledge representation that integrates entities, relationships, workflows, and executable code, encompassing both textual semantics and symbolic outcomes. This hybrid representation enables skills to bridge unstructured language understanding with structured, machine-executable logic. Skills are highly extensible, ranging from lightweight textual guidance to complex bundles that include executable programs and supporting assets. Their file-based, version-controlled nature ensures portability, allowing the same skill to be shared, reused, and deployed across different agents or systems with minimal adaptation.
Note that by encapsulating domain-specific knowledge and operational workflows in a structured and reusable form, skills provide an effective mechanism for institutionalizing business logic. This structured accumulation of expertise not only supports the systematic propagation of domain knowledge, but also enhances agent performance through reusable, reliable, and composable capabilities. However, in practice, these skills are often fragmented, scattered across scripts, prompts, or isolated workflows, and their quality, reliability, and reusability are rarely evaluated in a systematic way. Without a unified framework to organize, verify, and evolve skills, agents cannot fully realize the potential of this modular knowledge, limiting their ability to evolve continuously and adapt to new tasks. This motivates the development of SkillNet.
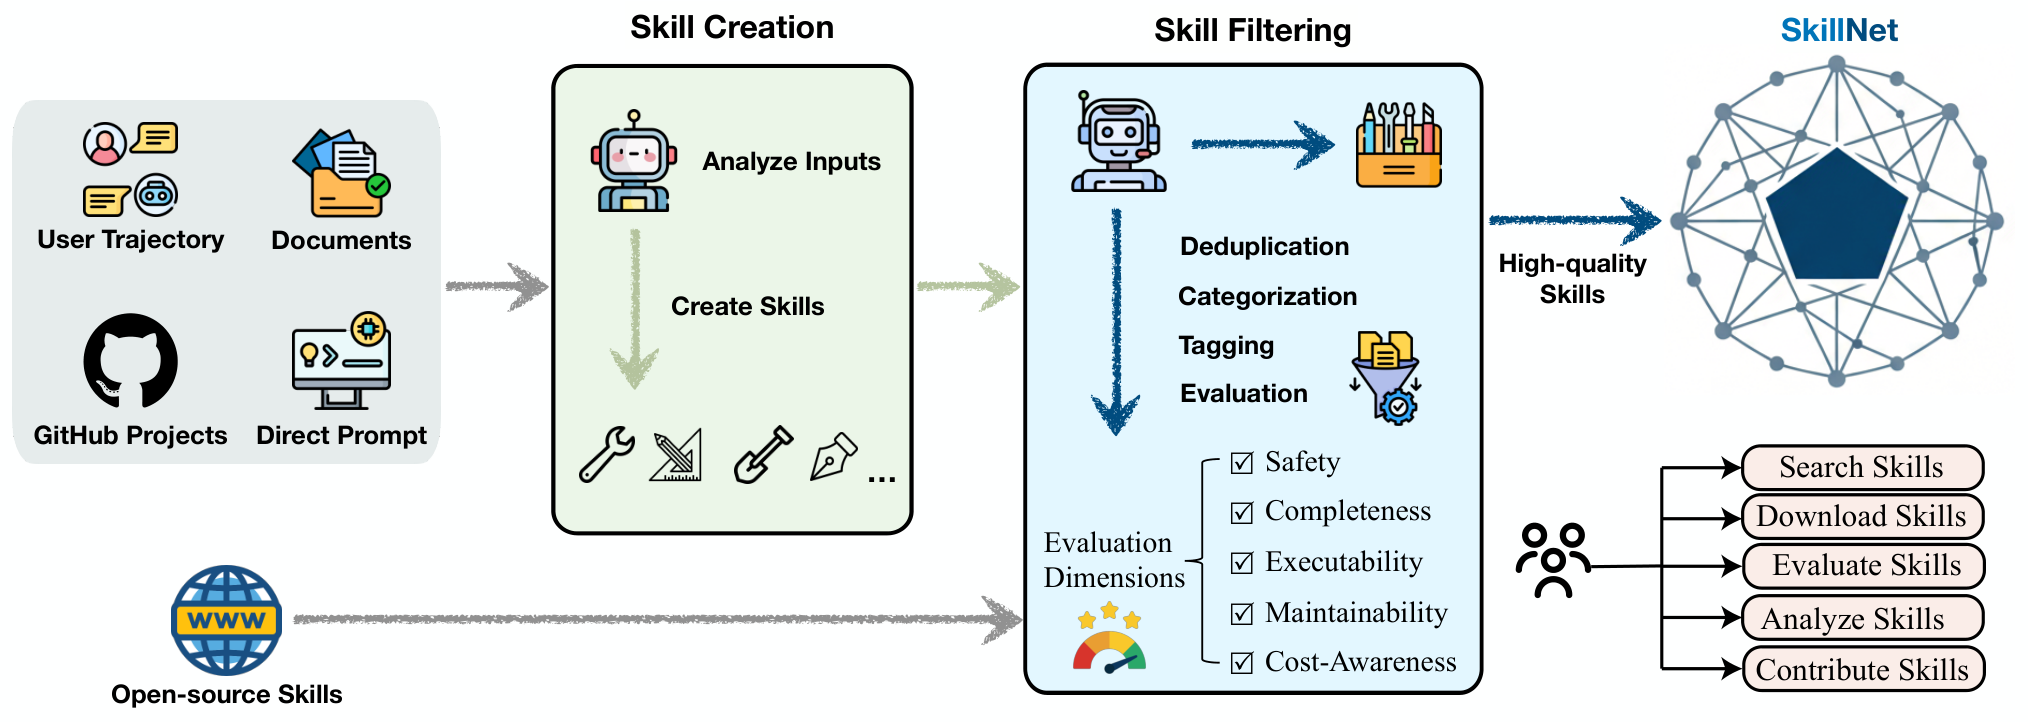
Figure 2 illustrates the overall architecture of SkillNet, which systematically creates, evaluates, and organizes high-quality skills for agent systems. SkillNet is designed to transform fragmented agent experiences and human knowledge into reusable and verifiable skill entities, enabling scalable and reliable capability growth. SkillNet consists of three core modules:
This module analyzes diverse inputs, including user trajectories, office documents, GitHub projects, direct prompts, and open internet resources. Based on these inputs, SkillNet generates new skills by extracting executable patterns and structuring them as reusable capabilities.
Generated skills are filtered and evaluated along multiple principal dimensions, including safety, completeness, executability, maintainability, and cost-awareness. This evaluation ensures that only high-quality skills are retained, mitigating redundancy, brittleness, and potential risks.
Beyond isolated skills, SkillNet automatically analyzes structural and functional relationships among skills, constructing large-scale skill graphs that capture similarity, hierarchy, composition, and dependency patterns. This structured representation enables global reasoning over skill repositories, supporting efficient retrieval, composition, and workflow synthesis.
SkillNet organizes curated, high-quality skills within a structured repository, offering versatile toolkits that enable users and agents to efficiently search, download, create, evaluate, analyze, and contribute skills. By providing these standardized interfaces for skill interaction, SkillNet facilitates seamless skill reuse and collaborative evolution across tasks, domains, and agent populations.
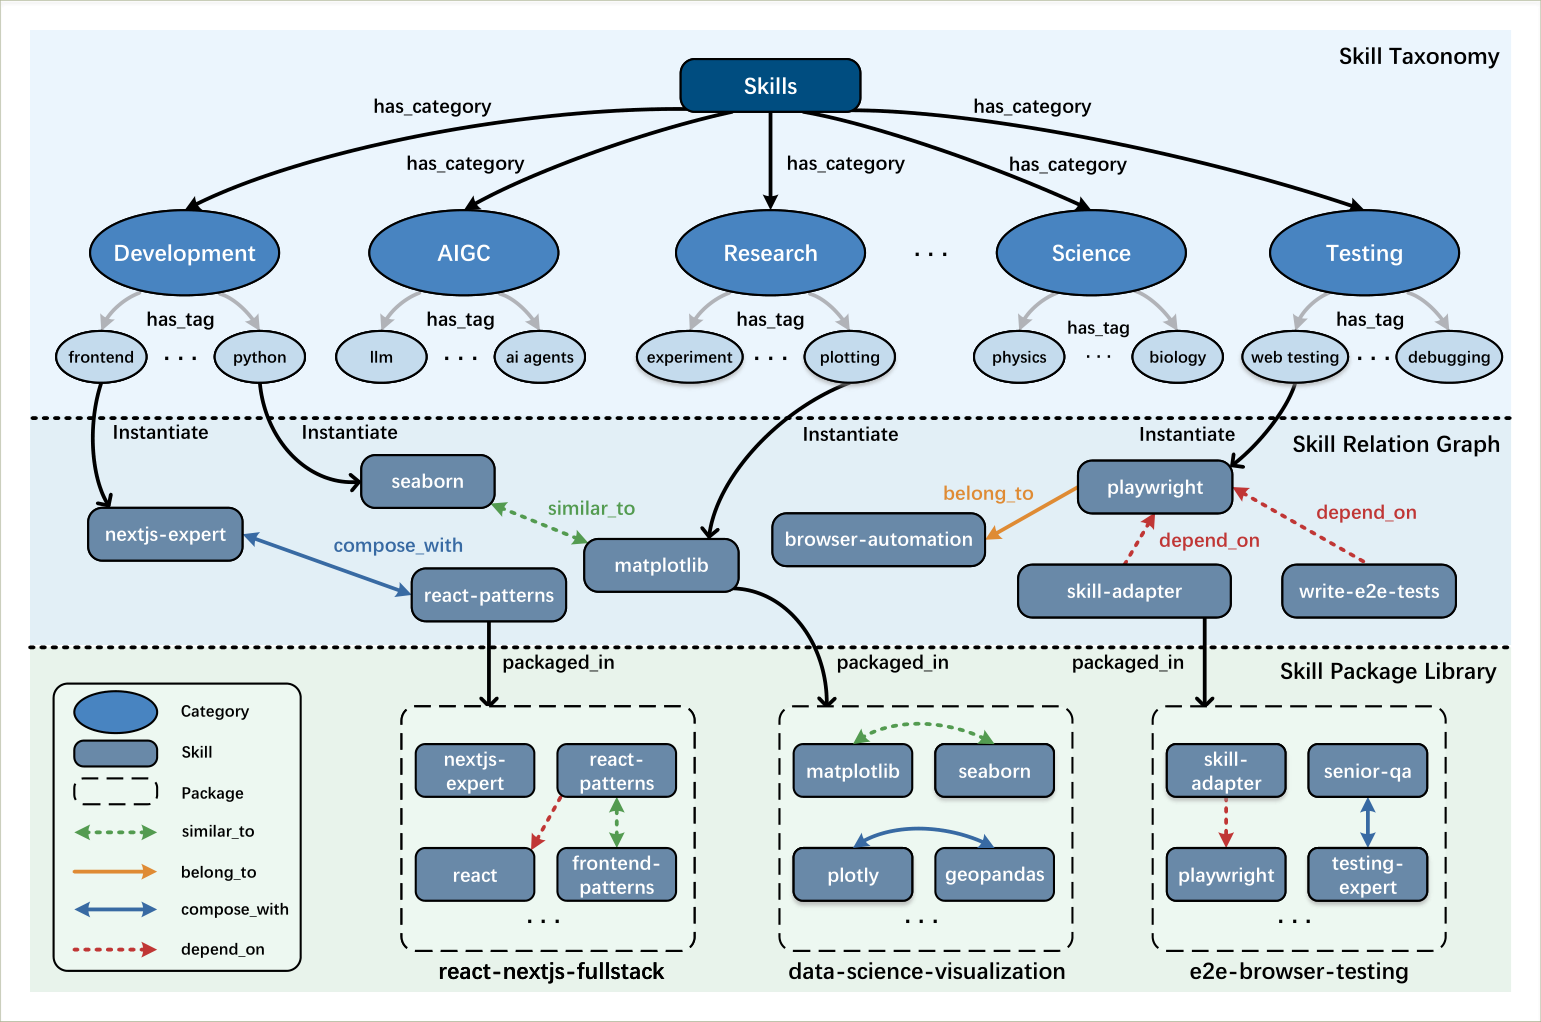
The Skill Ontology organizes individual skills into a structured, composable network, as illustrated in Figure 3. The architecture is organized into three progressive layers:
This layer organizes skills into a multi-level hierarchy using category and tag relations. It categorizes broad domains (e.g., Development, AIGC, Science …) into fine-grained tags (e.g., frontend, llm, physics), providing a high-level semantic skeleton.
This layer instantiates abstract tags into specific Skill Entities (e.g., Matplotlib, Playwright). It defines the core interaction logic through multi-relational edges: similar_to, compose_with, belong_to, and depend_on, forming the backbone for reasoning and planning.
The bottom layer represents the physical organization of skills. Individual skills are encapsulated into Skill Packages (e.g., data-science-visualization) via the packaged_in relation, facilitating modular release and deployment.
Note that the skill ontology is dynamic, modeling relations between skills. Tags can be continually added from the taxonomy, and LLMs infer relations from them, enabling the instantiation of a skill relation graph.
SkillNet conceptualizes skills as intermediate capability units that bridge abstract, declarative knowledge and concrete, executable programs. Specifically, we develop an automated creation pipeline that systematically transforms heterogeneous information sources into standardized, reusable agent skills.
To construct a comprehensive and versatile skill repository, SkillNet abstracts skills from diverse data sources, transforming heterogeneous information into reusable structured agent skills.
We design a multi-source automated skill creation pipeline that enables SkillNet to induce agentic skills from heterogeneous human knowledge and experience. Specifically, SkillNet supports four major categories of data sources: (1) execution trajectories and conversational interaction logs, (2) open-source GitHub repositories, (3) semi-structured documents including PDF, PowerPoint, and Word files, and (4) direct natural language prompts provided by users. This process is fully implemented through LLMs, and users can also customize the underlying models. In addition, SkillNet continuously expands its skill pool through open internet resources, in-house development, and community contributions, ensuring sustained scalability and coverage expansion.
Automatic construction of skills does not imply indiscriminate accumulation. Instead, SkillNet introduces a data-driven filtering and consolidation pipeline to ensure the quality of the skill repository. Specifically, SkillNet applies a multi-stage curation process consisting of deduplication, filtering, categorization and tagging, evaluation, and final selective consolidation.
Deduplication is performed by jointly comparing skill directory structures and MD5 hashes of skill markdown files, effectively removing redundant skills. Filtering eliminates low-quality, incomplete, or semantically meaningless skills through rule-based validation and model-based checking. Categorization and tagging classify each skill into one of ten functional categories (Development, AIGC, Research, Science, Business, Testing, Productivity, Security, Lifestyle, Other) and assign fine-grained semantic tags to facilitate retrieval and composition. Then, a multi-dimensional evaluation mechanism is applied to determine whether a skill is admitted into the SkillNet repository. SkillNet automatically establishes inter-skill associations based on ontology-defined relations, ultimately resulting in a structured skill package library.
This structured pipeline enables SkillNet to function as a self-evolving skill ecosystem rather than a static skill collection, continuously improving both skill quality and coverage.
Although skill creation is important, the utility of a skill repository ultimately depends on its reliability. To bridge the gap left by existing repositories that lack standardized assessment, we propose a multi-dimensional systematic evaluation framework.
We define five core dimensions to quantitatively characterize the quality and readiness of each skill:
- •
Safety: Assesses potential risks, including hazardous system operations (e.g., unauthorized file deletion) and robustness against prompt injection or adversarial manipulation.
- •
Completeness: Evaluates whether the skill encapsulates all critical procedural steps and explicitly defines necessary prerequisites, dependencies, and execution constraints.
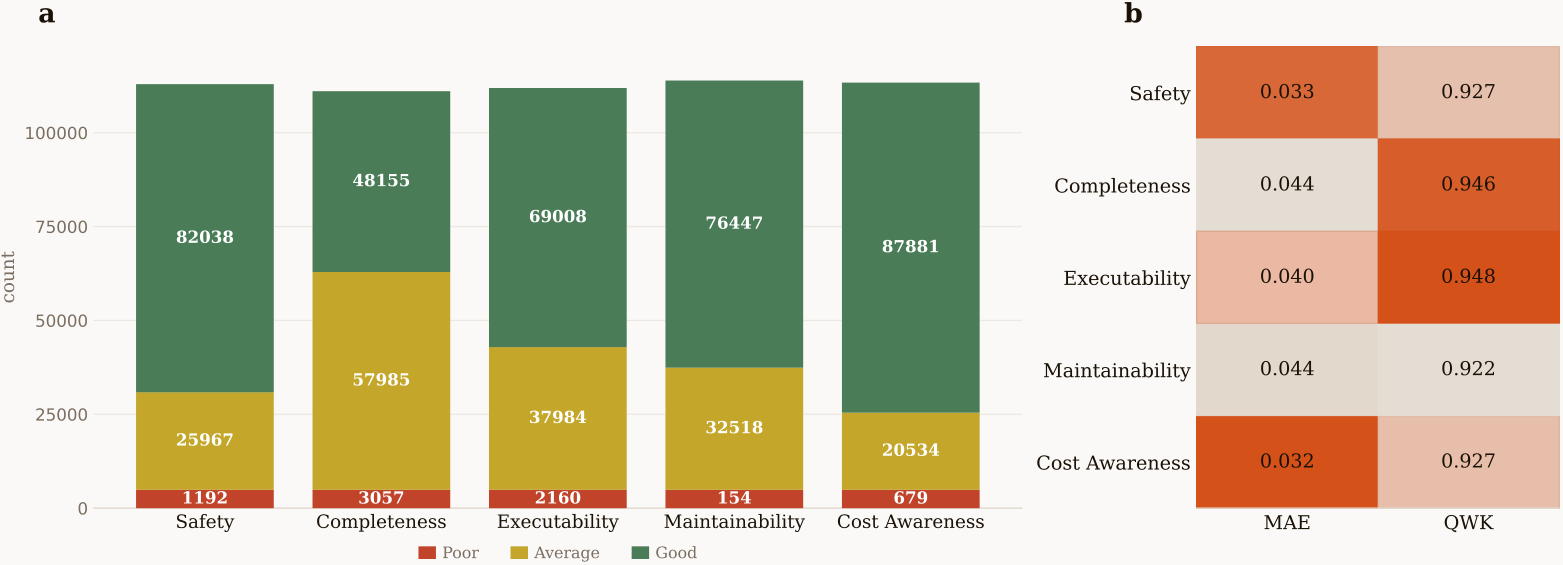
Figure 4: Multi-dimensional Skill Evaluation and Reliability Analysis. (a) Quality distribution of curated skills in SkillNet, assessed using a three-level grading scheme, where most skills are rated Good or Average. (b) Reliability validation of the automated evaluator on 200 randomly sampled skills. The heatmap shows mean absolute error (MAE) and quadratic weighted kappa (QWK) between human annotators and the model evaluator, with near-perfect QWK and low MAE across all dimensions, demonstrating the robustness and scalability of the evaluation framework. - •
Executability: Verifies if the skill can be successfully implemented by agents in sandboxed environments, identifying hallucinated tool calls or ambiguous instructions.
- •
Maintainability: Measures the modularity and composability of skills, ensuring they can be locally updated without disrupting global dependencies or breaking backward compatibility.
- •
Cost-awareness: Quantifies execution overhead, including time latency, computational resource consumption, and API usage costs to support efficiency optimization.
To achieve high-throughput assessment, all dimensions are primarily evaluated via an automated LLM-based evaluator, guided by fine-grained rubrics. For Safety, the evaluator assesses potentially risky instructions and operations at the semantic level, providing a scalable repository-level signal for skill curation. This assessment is intended to support large-scale quality control rather than substitute for deployment-level security validation. For Executability, we complement LLM judgment with empirical validation: skills containing code or tool invocations are executed in controlled sandbox environments to verify runtime correctness. Each dimension is categorized into three levels: Good, Average, and Poor.
The quality distribution across the repository is illustrated in Figure 4(a). We observe that while Safety and Maintainability maintain a high proportion of “Good” ratings, Executability presents a greater challenge, with a larger fraction of skills rated as Average. This reflects our rigorous filtering criteria, ensuring that only high-fidelity skills are prioritized for complex task execution.
To validate the reliability of this automated pipeline, we randomly sampled 200 skills and recruited three PhD-level computer science annotators for independent blind reviews. As shown in Figure 4(b), the inter-rater agreement between human judgments and LLM-based scores exhibits exceptional consistency. Across all dimensions, the Mean Absolute Error (MAE) remains below 0.03, and the Quadratic Weighted Kappa (QWK) consistently reaches near-perfect levels (above 0.90). These results confirm that our automated evaluator provides a human-aligned, robust, and scalable foundation for managing the SkillNet ecosystem.
Beyond isolated skill creation and evaluation, large-scale skill repositories introduce a new challenge: how to systematically understand, organize, and exploit the relations among skills. To address this, SkillNet introduces a dedicated Skill Analysis module that automatically discovers and models structural relations between skills, forming a structured and interpretable skill relation graph. This enables global reasoning over large skill repositories and supports advanced downstream applications such as skill retrieval, composition, dependency resolution, and workflow synthesis.
SkillNet formulates skill analysis as a structured relations discovery problem. Given a large amount of heterogeneous skills, the system automatically identifies and annotates multiple types of
semantic and functional relations between skills, including (task-specific relations are omitted here, and users may extend the schema by defining custom relations as needed):
- •
similar_to: Two skills perform functionally equivalent or highly similar tasks and can often be used interchangeably, enabling redundancy detection, replacement, and robustness enhancement.
- •
belong_to: A skill serves as a sub-component or atomic step within a larger composite workflow, capturing hierarchical structures and supporting skill abstraction and modularization.
- •
compose_with: Two skills are frequently co-invoked in workflows, where one typically produces outputs consumed by the other, enabling automatic workflow composition and pipeline generation.
- •
depend_on: A skill cannot execute independently without prerequisite skills, such as environment setup or API initialization, enabling explicit dependency tracking and safe execution planning.
SkillNet can construct large-scale skill relation graphs through a hybrid pipeline that integrates semantic embedding and LLM-based relational inference. Candidate relations are first generated via similarity matching, dependency extraction, and execution trace alignment, and LLM reasoning, enabling scalable and accurate discovery of structured skill relations. These relations jointly form a directed, typed multi-relational graph, where nodes represent skills and edges encode fine-grained structural dependencies and functional associations.
To promote reproducibility and practical adoption, SkillNet releases over 20 task-specific skill collections, covering domains such as scientific research automation, software development, data processing pipelines, web automation, etc. In particular, several collections are designed for academic benchmarks, and we conduct quantitative evaluations to assess the effectiveness of this paradigm, as detailed in a later section. These released collections provide structured and reusable infrastructures for studying large-scale agent planning, workflow synthesis, and skill evolution, offering a foundation for future research on structured agent intelligence.
SkillNet provides a comprehensive open infrastructure for creating, evaluating, and organizing AI skills at scale. This includes a large-scale skill repository, a front-end website, an open access API, and a versatile Python toolkit (skillnet-ai), forming a unified ecosystem for skill management and utilization.
The front-end website allows users to seamlessly browse, search, and download skills directly. Users can explore skill categories, view detailed API documentation and Python toolkit usage guidelines, and learn how to apply SkillNet to scientific research or coding scenarios. The platform also supports community
| Model | Method | ALFWorld | WebShop | ScienceWorld | |||||||
| Seen | Unseen | R ↑ | S ↓ | Seen | Unseen | ||||||
| R ↑ | S ↓ | R ↑ | S ↓ | R ↑ | S ↓ | R ↑ | S ↓ | ||||
| DeepSeek V3.2 | React | 66.43 | 19.51 | 69.40 | 19.27 | 31.55 | 24.06 | 69.86 | 17.59 | 64.67 | 19.26 |
| Expel | 67.86 | 18.86 | 76.12 | 17.41 | 29.23 | 24.00 | 74.91 | 15.98 | 74.09 | 17.53 | |
| + SkillNet | 80.60 | 14.54 | 83.57 | 14.81 | 46.18 | 17.84 | 84.87 | 11.89 | 81.31 | 12.48 | |
| Gemini 2.5 Pro | React | 60.00 | 18.72 | 61.94 | 19.18 | 31.66 | 22.12 | 58.24 | 18.42 | 56.13 | 19.07 |
| Expel | 68.57 | 17.88 | 70.15 | 17.04 | 33.12 | 19.31 | 72.76 | 15.01 | 67.37 | 14.91 | |
| + SkillNet | 91.43 | 12.80 | 91.04 | 11.96 | 53.02 | 14.91 | 88.84 | 11.49 | 86.26 | 11.30 | |
| o4 Mini | React | 45.71 | 23.31 | 49.25 | 23.33 | 24.19 | 22.02 | 64.89 | 15.12 | 59.93 | 14.99 |
| Expel | 56.43 | 21.35 | 58.96 | 21.85 | 26.71 | 21.91 | 67.95 | 13.65 | 65.68 | 13.95 | |
| + SkillNet | 68.57 | 18.94 | 73.28 | 17.08 | 36.21 | 18.79 | 73.24 | 13.30 | 71.06 | 12.35 | |
| Claude Sonnet 4.6 | React | 88.57 | 12.00 | 89.55 | 12.32 | 41.09 | 21.58 | 79.90 | 13.72 | 78.16 | 14.27 |
| Expel | 92.86 | 11.82 | 91.04 | 12.29 | 48.63 | 20.07 | 75.99 | 12.99 | 76.24 | 14.88 | |
| + SkillNet | 95.71 | 10.68 | 95.52 | 11.03 | 50.92 | 19.14 | 83.25 | 10.77 | 82.94 | 11.91 | |
View original table
contributions, enabling users to submit and share newly constructed skills, thus fostering a collaborative and continuously evolving skill ecosystem.
For API access, SkillNet supports both keyword-based and vector-based searches. Users can search for skills by keywords, categories, or semantic similarity via http://api-skillnet.openkg.cn/v1/search.
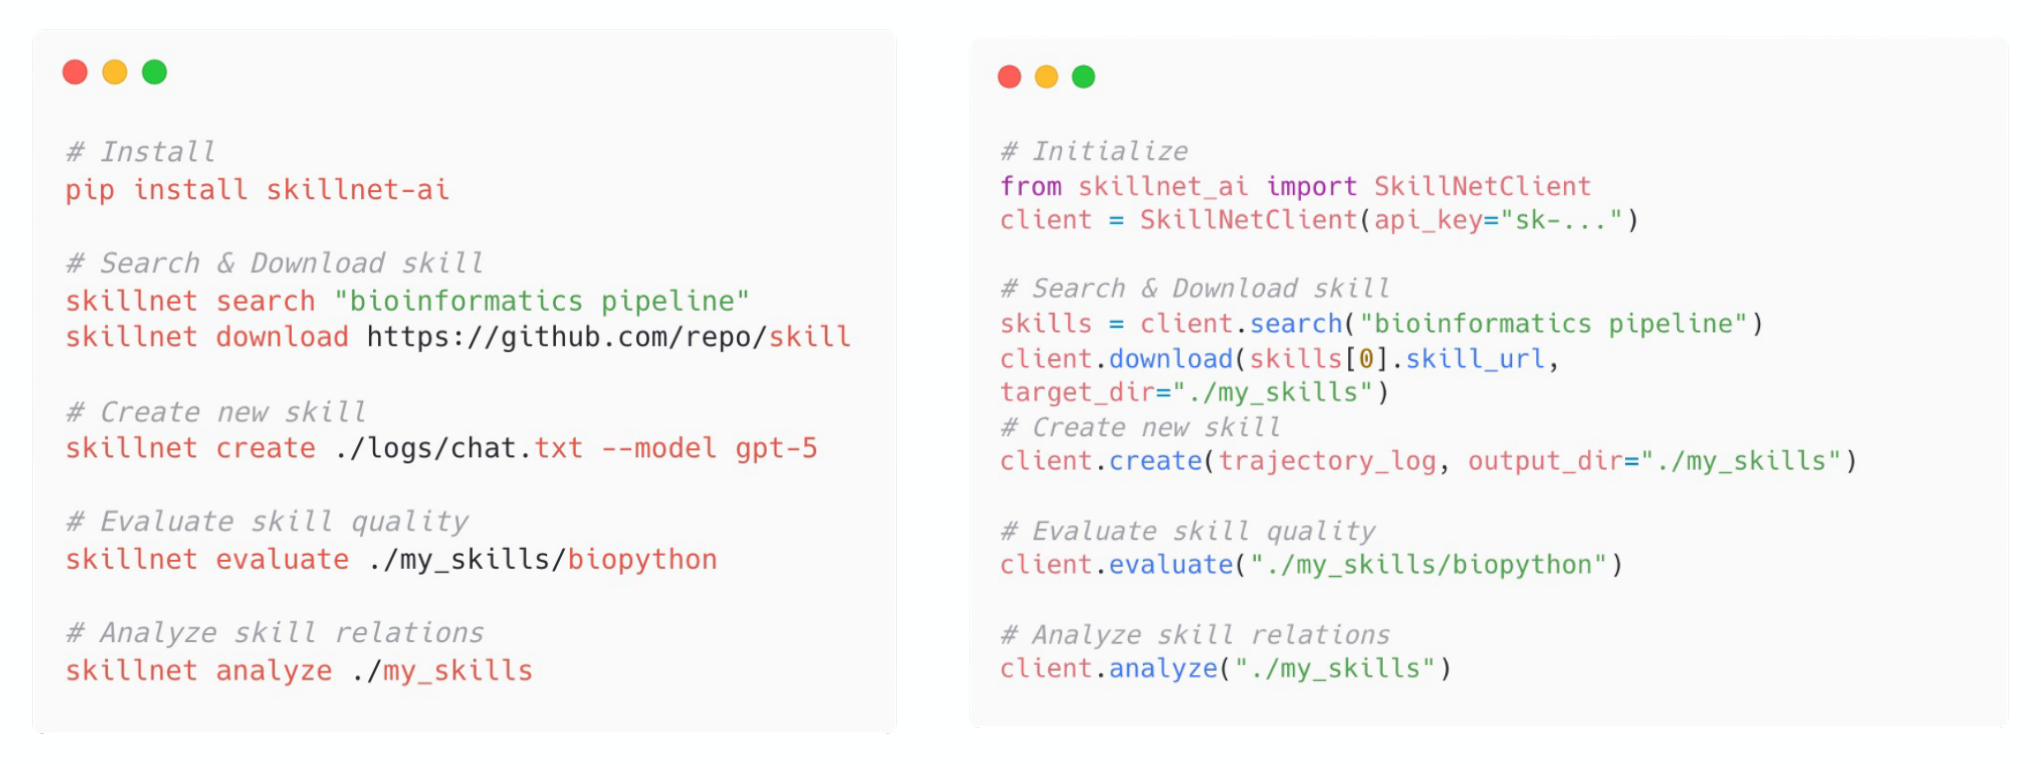
To bridge the gap between static repositories and dynamic execution, we developed skillnet-ai, a unified Python library and CLI tool that enables flexible integration with users. Through this toolkit, users can search for skills using keywords or semantic similarity, download skills directly from GitHub into local workspaces, and create structured skills from heterogeneous sources, including execution trajectories, GitHub repositories, office documents, and natural language prompts. The package also supports evaluating skills across multiple dimensions (safety, completeness, executability, maintainability, and cost-awareness) to ensure practical reliability, and analyzing relations between skills to uncover dependencies, hierarchical compositions, collaborations, and functional similarities. The practical use examples are illustrated in Figure 5.
SkillNet has initially aggregated over 600k candidate skills from open internet resources, automated creation pipelines, and community contributions. After multi-stage filtering and evaluating, more than 500k high-quality skills are curated in the final repository (and which is constantly expanding). This scale ensures broad coverage across scenarios while maintaining rigorous quality standards, enabling SkillNet to serve as a reliable skill infrastructure for both scientific investigation and real-world deployment. We actively encourage community contributions, and all community-submitted skills are subject to the same automated quality checks. In addition, we conduct periodic manual audits through random sampling to ensure the ongoing reliability and integrity of the shared skill repository.
To quantitatively assess the effectiveness of SkillNet, we conduct experiments across three text-based simulated environments. ALFWorld [29] provides an embodied household environment, requiring agents to navigate and manipulate objects to complete daily tasks; WebShop [30] simulates realistic online shopping scenarios, where agents perform product search, comparison, and purchasing under specified constraints; and ScienceWorld [31] presents a virtual scientific laboratory in which agents must conduct experiments and operate scientific instruments. All three environments are formulated as partially observable Markov decision processes (POMDPs), requiring agents to make sequential decisions under incomplete and noisy observations.
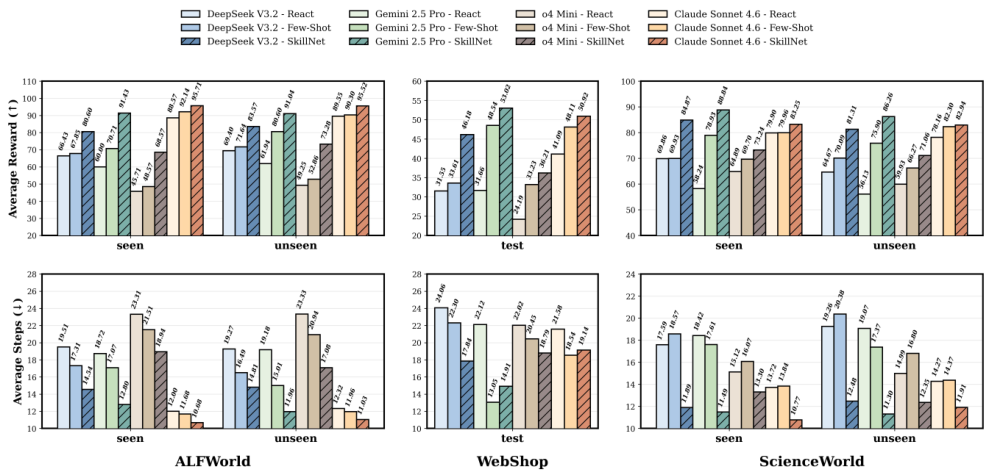
We adopt ReAct [32], Expel [20] and a standard Few-Shot approach as the baseline methods. ReAct interleaves reasoning, action, and observation for step-by-step task solving. ExpeL gathers experiences from past tasks to extract natural language insights and retrieves past successful trajectories as in-context examples during inference. The Few-Shot baseline randomly samples a complete expert trajectory to serve as a static in-context exemplar. In contrast, our proposed variant is augmented with SkillNet by leveraging expert trajectories from ETO [33] to synthesize benchmark-specific skill collections (these collections are integrated into SkillNet, and users can extend it to other datasets by creating corresponding skills). Note that the above experiences and the seen and unseen splits of the test set have no overlap, thereby preventing data leakage. During evaluation, agents are equipped with these collections and can dynamically select, activate, and execute the most relevant skills based on the current state. We employ four representative LLMs: DeepSeek V3.2 [34], Gemini 2.5 Pro [35], o4 Mini [36], and Claude Sonnet 4.6 [37] as backbone models.
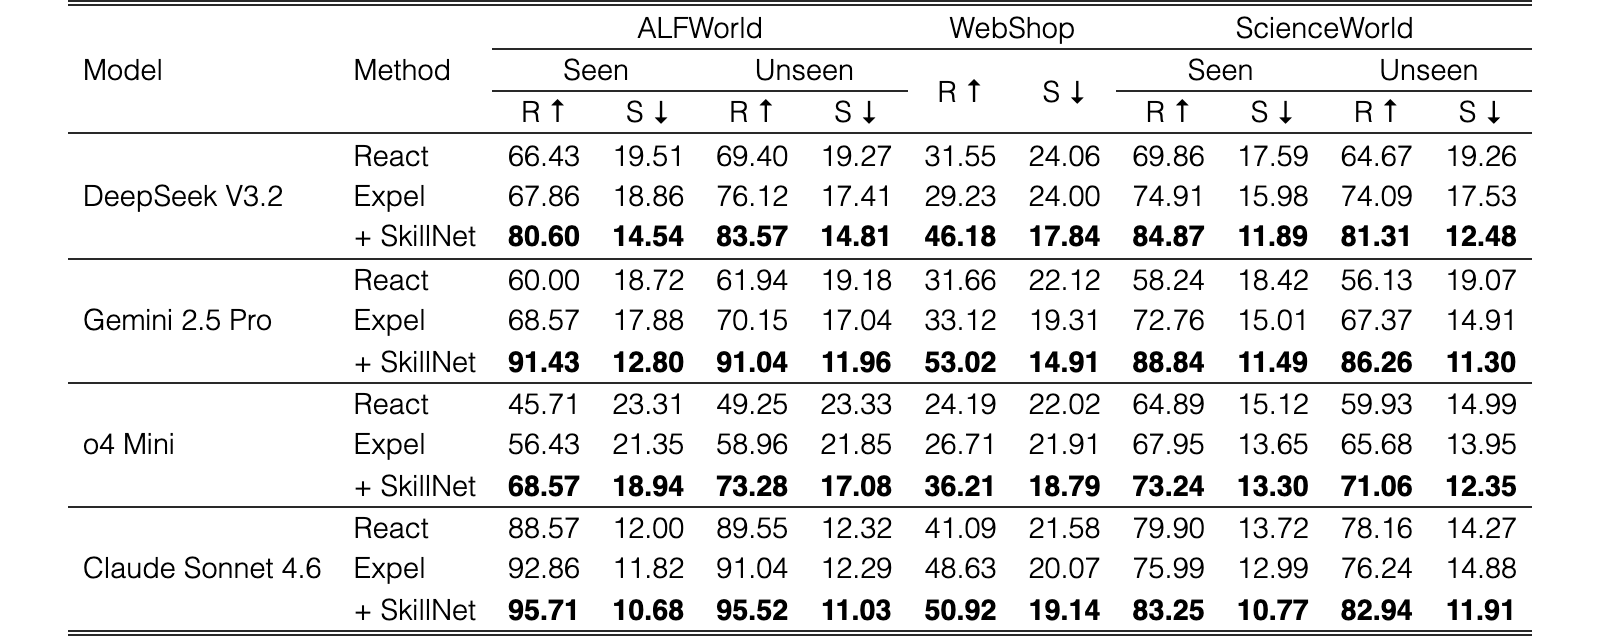
Table 1 and Figure 6 present the quantitative results across diverse environments and backbone models. In general, integrating SkillNet consistently yields substantial gains in both task effectiveness and execution efficiency, validating the effectiveness of our framework. Compared with ReAct, SkillNet improves the average reward by 40%, while reducing the number of interaction steps by 30% on average, indicating that agents equipped with SkillNet are able to solve tasks more reliably while executing shorter and more coherent action trajectories. This reflects SkillNet’s ability to transform fragmented experience into reusable procedural abstractions, enabling agents to perform structured planning, reduce redundant exploration, and execute complex behaviors in a more principled and systematic manner.
Importantly, the performance improvements remain robust across backbone models of varying capacities, ranging from compact models (+15.7 R for o4 Mini) to large-scale LLMs (+28.5 R for Gemini 2.5 Pro). This demonstrates that SkillNet provides complementary capabilities beyond parametric knowledge, effectively augmenting reasoning with persistent, executable skills. Moreover, the consistent gains observed under both seen and unseen settings highlight SkillNet’s strong generalization ability, suggesting that skill abstraction and reuse facilitate knowledge transfer across tasks and environments.
Taken together, these results substantiate the central design principle of SkillNet: by formalizing skills as independent, systematically accumulated, knowledge-grounded capability units, agent competence can be enhanced cumulatively rather than episodically, ultimately fostering domain-specialized and continually self-improving agents.
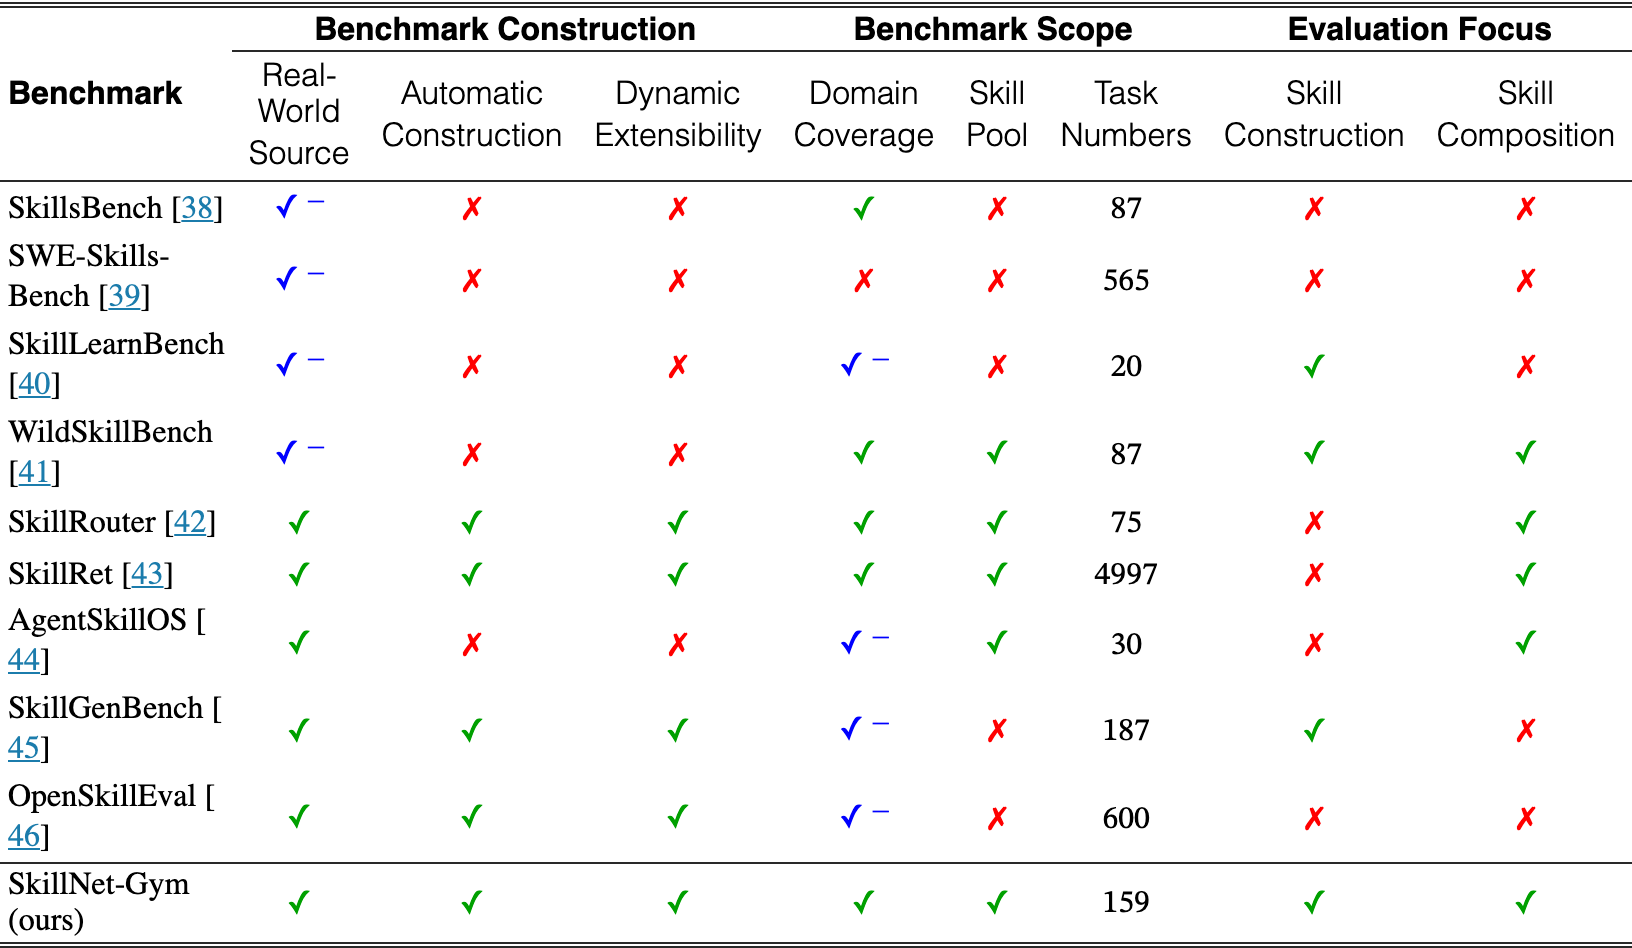
To reflect the demands of realistic and continuously evolving community, we design SkillNet-Gym around four key properties: (1) Real-World Source: SkillNet-Gym is grounded in artifacts collected from real community resources, rather than manually curated skills or synthetic files. This design choice ensures that the benchmark better reflects the structure, variability, and messiness of real-world usage scenarios. (2) Domain diversity: SkillNet-Gym spans 13 core domains and 81 subdomains, covering a broad range of practical settings, including data analysis, science, technology and so on. (3) Dynamic extensibility: To accommodate the continuously evolving community ecosystem, SkillNet is represented as a heterogeneous graph that can be incrementally expanded by adding new artifact nodes and their associated edges. This formulation enables the benchmark to evolve over time. (4) Automatic construction: Our pipeline automatically constructs the benchmark from SkillNet at scale, and also supports automatic control over task difficulty by varying the number of nodes visited during random walks and the topological structures induced by the traversal. The comparison of SkillNet-Gym with other benchmarks is detailed in Table 2. Next, we introduce the automated pipeline of SkillNet-Gym, covering SkillNet construction, benchmark data synthesis, and quality control. The pipeline is shown in Figure 7.
| Benchmark | Benchmark Construction | Benchmark Scope | Evaluation Focus | |||||
| Real-World Source | Automatic Construction | Dynamic Extensibility | Domain Coverage | Skill Pool | Task Numbers | Skill Construction | Skill Composition | |
| SkillsBench [38] | ✓ – | ✗ | ✗ | ✓ | ✗ | ✗ | ✗ | |
| SWE-Skills-Bench [39] | ✓ – | ✗ | ✗ | ✗ | ✗ | ✗ | ✗ | |
| SkillLearnBench [40] | ✓ – | ✗ | ✗ | ✓ – | ✗ | ✓ | ✗ | |
| WildSkillBench [41] | ✓ – | ✗ | ✗ | ✓ | ✓ | ✓ | ✓ | |
| SkillRouter [42] | ✓ | ✓ | ✓ | ✓ | ✓ | ✗ | ✓ | |
| SkillRet [43] | ✓ | ✓ | ✓ | ✓ | ✓ | ✗ | ✓ | |
| AgentSkillOS [44] | ✓ | ✗ | ✗ | ✓ – | ✓ | ✗ | ✓ | |
| SkillGenBench [45] | ✓ | ✓ | ✓ | ✓ – | ✗ | ✓ | ✗ | |
| OpenSkillEval [46] | ✓ | ✓ | ✓ | ✓ – | ✗ | ✗ | ✗ | |
| SkillNet-Gym (ours) | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | |
View original table
We construct skill graph (customized SkillNet) from real community resources by collecting three aligned artifact types: skills, supporting documents, and processable files. Specifically, we retrieve candidate skills from repositories such as ClawHub and SkillHub using LLM-generated domain-diverse queries, then perform filtering and deduplication. For each skill, we gather web documentation based on its functional semantics, or synthesize surrogate documentation when necessary, and retain functionally compatible files with source metadata for downstream normalization and quality control. On top of these artifacts, we build SkillNet as a skill-centric DAG: an LLM extracts each skill’s pre and post scenarios, we identify candidate edges by matching embedded post-scenarios to pre-scenarios, and then use an LLM to verify whether each match constitutes a valid workflow handoff. The resulting graph captures directed compositional dependencies among skills and, compared with scenario-centric formulations, more directly models skill topology for multi-skill task synthesis.
Given the constructed SkillNet, we synthesize task candidates by sampling structured subgraphs from the directed skill graph. We consider four common composition patterns: chains, fan-out, fan-in, and diamonds, with two to five skills depending on the structure, as illustrated in Figure . Each candidate preserves its participating skills, directed skill connections, and scenario-level evidence for every edge. We score each edge using alignment confidence, retrieval similarity, and the number of supporting scenario alignments, and score each task by combining mean edge quality with a structure bonus and a hub-node penalty. The resulting candidates are grouped by structure category and assigned difficulty labels from easy to expert according to their compositional complexity. We then select tasks either by quality ranking. This produces a pool of compositional task candidates grounded in verified SkillNet transitions.
Given the sampled skill Directed Acyclic Graph (DAG) and its associated input artifacts, we prompt an agent (Claude Code) to execute the skills by following the workflow specified by the DAG and operating directly on the input files. After the exploration phase, the agent produces an exploration report that summarizes actionable findings, such as feasible cross-skill workflows, potential intermediate artifacts, and common failure patterns. Compared with naively concatenating the full contents of all skill files, the exploration report is substantially more concise and better aligned with downstream task requirements.
A complete task should include at least four core components: a task instruction, a golden solution, an evaluation script, and the execution environment. We synthesize these components sequentially. 1) Task Instruction: Given the exploration report and snippet-level information about the input artifacts, we prompt an LLM to generate a task instruction that follows the workflow induced by the skill DAG. To encourage diversity, each synthesis run uses a randomly sampled writing style. 2) Golden Solution: After generating the instruction, we first derive high-level guidance from the exploration report to scaffold the downstream problem-solving process. We then prompt Claude Code to solve the task conditioned on this meta-information. From the resulting execution trajectory, we extract and compress the essential steps into a canonical reference solution, solve.sh. 3) Test Script: Based on the task instruction and the final output artifacts, we synthesize a test script test.sh that verifies not only the structural validity of the outputs but also their semantic correctness at the value level. 4) Execution Environment: Finally, we extract the minimal execution environment to get a Dockerfile from solve.sh.
We apply rigorous multi-stage quality control to the benchmark. First, during SkillNet construction, we filter low-quality nodes and edges to improve the reliability of the underlying skill graph. Second, for synthesized tasks, task-level quality control covers four core components of each instance: the instruction, the reference
| Models | Skill Construction | Skill Composition | ||||||||
| No Skill | Official Skill | Skill-Creator | Skills Retrieve | Skills Orchestration | ||||||
| Easy | Hard | Easy | Hard | Easy | Hard | Easy | Hard | Easy | Hard | |
| Methods | Complete | Recall | Precision | Avg sel. |
| Skills Retrieve | ||||
| Agent | 18.83 | 44.93 | 37.92 | 3.86 |
| AgentSkillOS | 42.14 | 61.77 | 55.00 | - |
| SkillRouter | ||||
| w/o Reranker | 36.48 | 60.28 | 19.06 | - |
| w/ Reranker | 44.03 | 67.40 | 21.01 | - |
| SkillRet | 59.12 | 78.40 | 24.09 | - |
| Skills Orchestration | ||||
| Agent | 18.36 | 25.17 | 18.63 | 3.27 |
| AgentSkillOS | 29.49 | 35.51 | 26.86 | - |
| (a) SkillsBench: Mean Verifier Reward (%) | ||||
| Methods | Easy | Medium | Hard | Overall [95% CI] |
| GPT-5.4 mini | ||||
| w/o Skills | 47.22 | 27.73 | 29.46 | 29.63 [22.54, 37.09] |
| Golden Skills | 48.14 | 50.13 | 32.20 | 44.22 [35.89, 52.51] |
| SkillRouter | 42.59 | 42.18 | 40.54 | 41.68 [33.26, 50.21] |
| SkillsVote | 40.74 | 34.91 | 33.93 | 34.99 [27.30, 42.93] |
| SkillNet-Fabric | 62.96 | 48.45 | 37.98 | 46.08 [37.51, 54.62] |
| GPT-5.6 Terra | ||||
| w/o Skills | 52.77 | 46.06 | 45.24 | 46.26 [37.12, 55.53] |
| Golden Skills | 48.14 | 66.17 | 52.92 | 60.66 [51.90, 69.29] |
| SkillRouter | 53.70 | 59.66 | 46.49 | 55.01 [45.82, 63.95] |
| SkillsVote | 59.26 | 60.34 | 50.42 | 57.07 [47.89, 65.89] |
| SkillNet-Fabric | 69.44 | 67.92 | 63.69 | 66.67 [58.75, 74.58] |
| (b) AgentSkillOS: Bradley–Terry Score | ||||
| Methods | Seed Pool | 500 Skills | 1,000 Skills | Pool Mean |
| GPT-5.4 mini | ||||
| w/o Skills | 33.16 | 42.16 | 46.96 | 40.76 |
| Full Pool | 53.85 | 50.99 | 46.30 | 50.38 |
| AgentSkillOS | 61.11 | 46.96 | 53.13 | 53.73 |
| SkillNet-Fabric | 61.89 | 65.20 | 65.54 | 64.21 |
| GPT-5.6 Terra | ||||
| w/o Skills | 34.42 | 30.03 | 39.34 | 34.60 |
| Full Pool | 28.38 | 46.29 | 34.28 | 36.32 |
| AgentSkillOS | 40.84 | 44.95 | 40.43 | 42.07 |
| SkillNet-Fabric | 90.03 | 78.53 | 80.45 | 83.00 |
| Variant | Wiki Components | Downstream Quality | Exploration | ||||
| Graph Expansion | Relation Evidence | Contract Cards | Complete Sources | BT Score | Tokens (K) | ||
| w/o Graph Expansion | ✗ | ✓ | ✓ | ✓ | 54.15 | 16.66 | |
| w/o Relation Evidence | ✓ | ✗ | ✓ | ✓ | 53.05 | 30.26 | |
| w/o Contract Cards | ✓ | ✓ | ✗ | ✓ | 49.80 | 34.23 | |
| w/o Complete Sources | ✓ | ✓ | ✓ | ✗ | 48.12 | 24.42 | |
| Full Wiki | ✓ | ✓ | ✓ | ✓ | 65.51 | 0.00 | 27.82 |
| Dimension | SkillNet (Ours) | ClawHub | SkillsMP | SkillHub | Skills.sh |
| Core Positioning | Full-lifecycle infrastructure (creation, evaluation, & connection) | npm-like version management hub | Massive open-source ecosystem catalog | Premium marketplace (curated & stacked) | Universal skill directory & leaderboard |
| Automated Creation | Supported (generates skills from trajectories, code, and documents via LLMs) | Not supported | Not supported | Not supported | Not supported |
| Quality Evaluation | Multi-dimensional metrics (safety, completeness, executability, maintainability, cost-aware) | None (relies on highlighted recommendations) | Basic filtering (e.g., GitHub stars) | Built-in LLM rating (e.g., S-rank/B-rank) | Community leaderboard (downloads/trends) |
| Relationship Analysis | Supported (extracts structural relations to build a skill graph) | Not supported | Not supported | Manual pre-configured skill stacks | Not supported |
| Integration & Distribution | Python SDK & CLI tool (skillnet-ai) | npx-based package manager (clawhub install) | GitHub repository aggregation & CLI | Desktop client 1-click install & CLI | Universal CLI (npx skills add) |
| Search Mechanism | Vector semantic search + keyword matching | Vector semantic search + version control | AI semantic search + keyword matching | Semantic search + ranking filters | Global directory search |
| Skill Quantity | 600k+ Total, 500k+ Curated | 9k+ | 261k+ | 21k+ | 71k+ |
| Models | Skill Creator | Skill Seeker Easy | Hard | Easy | Hard mydarkbrown!40 Claude Code Minimax-M2.7 | 66.88 | 20.73 | 60.39 | 23.17 Kimi-K2.6 | 73.38 | 31.10 | 75.32 | 38.41 Deepseek-V4 | 68.83 | 29.88 | 72.73 | 23.17 GLM-5.1 | 79.22 | 31.10 | 70.78 | 28.05 |
| Models | Official Skill | In Wild Easy | Hard | Easy | Hard mydarkbrown!40 Claude Code Minimax-M2.7 | 65.58 | 26.22 | 65.58 | 23.17 Kimi-K2.6 | 74.03 | 34.15 | 66.23 | 25.61 Deepseek-V4 | 69.44 | 29.87 | 68.83 | 24.39 GLM-5.1 | 71.43 | 32.93 | 66.23 | 24.39 |
Table 4 Performance of Skill Composition Baselines.
Figure 8 Failure Types
Figure 9 Skill utility across domains and task topologies. (a) Domain-wise Skill Effect: The bar chart reports the average performance delta of skill augmentation over the no skill setting. (b) Topology-wise skill effect: The heatmap shows the mean delta for each topology across eight models, revealing that skill effectiveness depends jointly on task structure and model capability.
Figure 10 Case Study: From SkillNet subgraphs to synthesized tasks.
Figure 12 Comparison of two routing paradigms with SkillNet-Fabric.
Table 6 Downstream task performance on SkillsBench and AgentSkillOS. Panel (a) reports task macro mean verifier rewards over 87 SkillsBench tasks; brackets contain 95% confidence intervals for the Overall score. Panel (b) reports task level Bradley–Terry scores rescaled to 0 to 100 and averaged over 30 AgentSkillOS tasks across pools of 53, 500, and 1,000 skills.
Table 7 Wiki component ablation on AgentSkillOS. “✓” and “✗” indicate whether each component is present or removed. is relative to the full Wiki. Explorer tokens are averaged per task and reported in thousands.
Figure 13 Effects of Wiki components on AgentSkillOS. Panel (a) relates overall Bradley–Terry score to Explorer tokens per task. Panel (b) reports category scores and the minimum across categories.
Figure 14 Candidate availability and final set formation on SkillRouter Hard. Panel (a) compares Candidate FullCoverage with mean Final FullCoverage@10 as grows. Panel (b) reports Final FullCoverage@10 by Explorer, and panel (c) relates Final FullCoverage@10 to Explorer tokens. Full denotes all 79,141 skills.
Figure 15 Example of SkillNet application scenarios. The framework decomposes user task into actionable steps (top), with representative skill acquisition and multi-dimensional evaluations for Science and Coding scenarios (bottom).
Table 8 Comparison of SkillNet and Existing AI Agent Skill Platforms
Table 9 Performance of skill construction baselines.
Table 10 End-to-End Task Performance in the Wild Setting.
References
- Silver and Sutton [2025] David Silver and Richard S Sutton. Welcome to the era of experience. Google AI, 1, 2025.
- Chen et al. [2022] Xiang Chen, Ningyu Zhang, Xin Xie, Shumin Deng, Yunzhi Yao, Chuanqi Tan, Fei Huang, Luo Si, and Huajun Chen. Knowprompt: Knowledge-aware prompt-tuning with synergistic optimization for relation extraction. In Proceedings of the ACM Web conference 2022, pages 2778–2788, 2022. URL https://dl.acm.org/doi/10.1145/3485447.3511998.Source
- Xi et al. [2025] Zhiheng Xi, Wenxiang Chen, Xin Guo, Wei He, Yiwen Ding, Boyang Hong, Ming Zhang, Junzhe Wang, Senjie Jin, Enyu Zhou, Rui Zheng, Xiaoran Fan, Xiao Wang, Limao Xiong, Yuhao Zhou, Weiran Wang, Changhao Jiang, Yicheng Zou, Xiangyang Liu, Zhangyue Yin, Shihan Dou, Rongxiang Weng, Wenjuan Qin, Yongyan Zheng, Xipeng Qiu, Xuanjing Huang, Qi Zhang, and Tao Gui. The rise and potential of large language model based agents: a survey. Sci. China Inf. Sci., 68(2), 2025. URL https://doi.org/10.1007/s11432-024-4222-0.Source
- Park et al. [2023] Joon Sung Park, Joseph C. O’Brien, Carrie Jun Cai, Meredith Ringel Morris, Percy Liang, and Michael S. Bernstein. Generative agents: Interactive simulacra of human behavior. In Sean Follmer, Jeff Han, Jürgen Steimle, and Nathalie Henry Riche, editors, Proceedings of the 36th Annual ACM Symposium on User Interface Software and Technology, UIST 2023, San Francisco, CA, USA, 29 October 2023- 1 November 2023, pages 2:1–2:22. ACM, 2023. URL https://doi.org/10.1145/3586183.3606763.Source
- Wang et al. [2024] Guanzhi Wang, Yuqi Xie, Yunfan Jiang, Ajay Mandlekar, Chaowei Xiao, Yuke Zhu, Linxi Fan, and Anima Anandkumar. Voyager: An open-ended embodied agent with large language models. Trans. Mach. Learn. Res., 2024, 2024. URL https://openreview.net/forum?id=ehfRiF0R3a.Source
- Zhu et al. [2023] Xizhou Zhu, Yuntao Chen, Hao Tian, Chenxin Tao, Weijie Su, Chenyu Yang, Gao Huang, Bin Li, Lewei Lu, Xiaogang Wang, Yu Qiao, Zhaoxiang Zhang, and Jifeng Dai. Ghost in the minecraft: Generally capable agents for open-world environments via large language models with text-based knowledge and memory, 2023. URL https://arxiv.org/abs/2305.17144.Source
- Fang et al. [2025] Runnan Fang, Xiaobin Wang, Yuan Liang, Shuofei Qiao, Jialong Wu, Zekun Xi, Ningyu Zhang, Yong Jiang, Pengjun Xie, Fei Huang, and Huajun Chen. Synworld: Virtual scenario synthesis for agentic action knowledge refinement. In Wanxiang Che, Joyce Nabende, Ekaterina Shutova, and Mohammad Taher Pilehvar, editors, Proceedings of the 63rd Annual Meeting of the Association for Computational Linguistics (Volume 2: Short Papers), ACL 2025, Vienna, Austria, July 27 - August 1, 2025, pages 437–448. Association for Computational Linguistics, 2025. URL https://doi.org/10.18653/v1/2025.acl-short.33.Source
- Zhao et al. [2023] Wayne Xin Zhao, Kun Zhou, Junyi Li, Tianyi Tang, Xiaolei Wang, Yupeng Hou, Yingqian Min, Beichen Zhang, Junjie Zhang, Zican Dong, et al. A survey of large language models. arXiv preprint arXiv:2303.18223, 1(2), 2023. URL https://arxiv.org/abs/2303.18223.Source
- Dong et al. [2024] Qingxiu Dong, Lei Li, Damai Dai, Ce Zheng, Jingyuan Ma, Rui Li, Heming Xia, Jingjing Xu, Zhiyong Wu, Baobao Chang, Xu Sun, Lei Li, and Zhifang Sui. A survey on in-context learning. In Yaser Al-Onaizan, Mohit Bansal, and Yun-Nung Chen, editors, Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing, EMNLP 2024, Miami, FL, USA, November 12-16, 2024, pages 1107–1128. Association for Computational Linguistics, 2024. URL https://doi.org/10.18653/v1/2024.emnlp-main.64.Source
- Sahoo et al. [2024] Pranab Sahoo, Ayush Kumar Singh, Sriparna Saha, Vinija Jain, Samrat Mondal, and Aman Chadha. A systematic survey of prompt engineering in large language models: Techniques and applications. CoRR, abs/2402.07927, 2024. URL https://doi.org/10.48550/arXiv.2402.07927.Source
- Dou et al. [2026] Shihan Dou, Ming Zhang, Zhangyue Yin, Chenhao Huang, Yujiong Shen, Junzhe Wang, Jiayi Chen, Yuchen Ni, Junjie Ye, Cheng Zhang, et al. Cl-bench: A benchmark for context learning. arXiv preprint arXiv:2602.03587, 2026.
- Hintzman [1986] Douglas L Hintzman. " schema abstraction" in a multiple-trace memory model. Psychological review, 93(4):411, 1986.
- Studer et al. [1998] Rudi Studer, V. Richard Benjamins, and Dieter Fensel. Knowledge engineering: Principles and methods. Data Knowl. Eng., 25(1-2):161–197, 1998. URL [https://doi.org/10.1016/S0169-023X(97)00056-6](https://doi.org/10.1016/S0169-023X(97)00056-6).Source
- Lewis et al. [1959] Clarence Irving Lewis, Cooper Harold Langford, and P Lamprecht. Symbolic logic, volume 170. Dover publications New York, 1959.
- Baldoni et al. [2018] Roberto Baldoni, Emilio Coppa, Daniele Cono D’elia, Camil Demetrescu, and Irene Finocchi. A survey of symbolic execution techniques. ACM Computing Surveys (CSUR), 51(3):1–39, 2018. URL https://dl.acm.org/doi/10.1145/3182657.Source
- Hogan et al. [2021] Aidan Hogan, Eva Blomqvist, Michael Cochez, Claudia d’Amato, Gerard De Melo, Claudio Gutierrez, Sabrina Kirrane, José Emilio Labra Gayo, Roberto Navigli, Sebastian Neumaier, et al. Knowledge graphs. ACM Computing Surveys (Csur), 54(4):1–37, 2021. URL https://dl.acm.org/doi/10.1145/3447772.Source
- LeCun et al. [2015] Yann LeCun, Yoshua Bengio, and Geoffrey Hinton. Deep learning. nature, 521(7553):436–444, 2015. URL https://www.nature.com/articles/nature14539.Source
- He et al. [2016] Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recognition. In 2016 IEEE Conference on Computer Vision and Pattern Recognition, CVPR 2016, Las Vegas, NV, USA, June 27-30, 2016, pages 770–778. IEEE Computer Society, 2016. URL https://doi.org/10.1109/CVPR.2016.90.Source
- Shinn et al. [2023] Noah Shinn, Federico Cassano, Ashwin Gopinath, Karthik Narasimhan, and Shunyu Yao. Reflexion: language agents with verbal reinforcement learning. In Alice Oh, Tristan Naumann, Amir Globerson, Kate Saenko, Moritz Hardt, and Sergey Levine, editors, Advances in Neural Information Processing Systems 36: Annual Conference on Neural Information Processing Systems 2023, NeurIPS 2023, New Orleans, LA, USA, December 10 - 16, 2023, 2023. URL http://papers.nips.cc/paper_files/paper/2023/hash/1b44b878bb782e6954cd888628510e90-Abstract-Conference.html.Source
- Zhao et al. [2024] Andrew Zhao, Daniel Huang, Quentin Xu, Matthieu Lin, Yong-Jin Liu, and Gao Huang. Expel: LLM agents are experiential learners. In Michael J. Wooldridge, Jennifer G. Dy, and Sriraam Natarajan, editors, Thirty-Eighth AAAI Conference on Artificial Intelligence, AAAI 2024, Thirty-Sixth Conference on Innovative Applications of Artificial Intelligence, IAAI 2024, Fourteenth Symposium on Educational Advances in Artificial Intelligence, EAAI 2014, February 20-27, 2024, Vancouver, Canada, pages 19632–19642. AAAI Press, 2024. URL https://doi.org/10.1609/aaai.v38i17.29936.Source
- Zheng et al. [2025a] Boyuan Zheng, Michael Y Fatemi, Xiaolong Jin, Zora Zhiruo Wang, Apurva Gandhi, Yueqi Song, Yu Gu, Jayanth Srinivasa, Gaowen Liu, Graham Neubig, et al. Skillweaver: Web agents can self-improve by discovering and honing skills. arXiv preprint arXiv:2504.07079, 2025a. URL https://arxiv.org/abs/2504.07079.Source
- Li [2026] Xiaoxiao Li. When single-agent with skills replace multi-agent systems and when they fail. arXiv preprint arXiv:2601.04748, 2026. URL https://arxiv.org/abs/2601.04748.Source
- Ye et al. [2026] Haoran Ye, Xuning He, Vincent Arak, Haonan Dong, and Guojie Song. Meta context engineering via agentic skill evolution, 2026. URL https://arxiv.org/abs/2601.21557.Source
- Chen et al. [2026a] Tianyi Chen, Yinheng Li, Michael Solodko, Sen Wang, Nan Jiang, Tingyuan Cui, Junheng Hao, Jongwoo Ko, Sara Abdali, Leon Xu, Suzhen Zheng, Hao Fan, Pashmina Cameron, Justin Wagle, and Kazuhito Koishida. Cua-skill: Develop skills for computer using agent, 2026a. URL https://arxiv.org/abs/2601.21123.Source
- SkillsMP Team [2026] SkillsMP Team. Skillsmp: Claude skills marketplace. https://skillsmp.com/, 2026. Accessed: 2026-02-06.Source
- SkillHub Team [2026] SkillHub Team. Skillhub: A marketplace for claude and agent skills. https://www.skillhub.club/, 2026. Accessed: 2026-02-06.Source
- Qin et al. [2024] Yujia Qin, Shihao Liang, Yining Ye, Kunlun Zhu, Lan Yan, Yaxi Lu, Yankai Lin, Xin Cong, Xiangru Tang, Bill Qian, Sihan Zhao, Lauren Hong, Runchu Tian, Ruobing Xie, Jie Zhou, Mark Gerstein, Dahai Li, Zhiyuan Liu, and Maosong Sun. Toolllm: Facilitating large language models to master 16000+ real-world apis. In The Twelfth International Conference on Learning Representations, ICLR 2024, Vienna, Austria, May 7-11, 2024. OpenReview.net, 2024. URL https://openreview.net/forum?id=dHng2O0Jjr.Source
- Anthropic [2025a] Anthropic. Agent skills: An open standard for modular ai agent capabilities. https://agentskills.io/, 2025a. Accessed: 2026-02-05.Source
- Shridhar et al. [2021] Mohit Shridhar, Xingdi Yuan, Marc-Alexandre Côté, Yonatan Bisk, Adam Trischler, and Matthew Hausknecht. Alfworld: Aligning text and embodied environments for interactive learning, 2021. URL https://arxiv.org/abs/2010.03768.Source
- Yao et al. [2023a] Shunyu Yao, Howard Chen, John Yang, and Karthik Narasimhan. Webshop: Towards scalable real-world web interaction with grounded language agents, 2023a. URL https://arxiv.org/abs/2207.01206.Source
- Wang et al. [2022] Ruoyao Wang, Peter Jansen, Marc-Alexandre Côté, and Prithviraj Ammanabrolu. Scienceworld: Is your agent smarter than a 5th grader?, 2022. URL https://arxiv.org/abs/2203.07540.Source
- Yao et al. [2023b] Shunyu Yao, Jeffrey Zhao, Dian Yu, Nan Du, Izhak Shafran, Karthik Narasimhan, and Yuan Cao. React: Synergizing reasoning and acting in language models, 2023b. URL https://arxiv.org/abs/2210.03629.Source
- Song et al. [2024] Yifan Song, Da Yin, Xiang Yue, Jie Huang, Sujian Li, and Bill Yuchen Lin. Trial and error: Exploration-based trajectory optimization for llm agents, 2024. URL https://arxiv.org/abs/2403.02502.Source
- DeepSeek-AI [2024] DeepSeek-AI. Deepseek-v3 technical report. https://github.com/deepseek-ai/DeepSeek-V3, 2024. Accessed: 2026-02-07.Source
- [35] Google DeepMind. Gemini 2.5 technical report and model card (referencing gemini 2.5 pro). URL https://deepmind.google/models/gemini/pro/. Accessed: 2026-02-07.Source
- OpenAI [2025] OpenAI. Openai o4-mini model documentation. https://platform.openai.com/docs/models, 2025. Accessed: 2026-02-07.Source
- Anthropic [2026] Anthropic. Announcing claude sonnet 4.6. https://www.anthropic.com/news/claude-sonnet-4-6, 2026. Accessed: 2026-04-26.Source
- Li et al. [2026a] Xiangyi Li, Wenbo Chen, Yimin Liu, Shenghan Zheng, Xiaokun Chen, Yifeng He, Yubo Li, Bingran You, Haotian Shen, Jiankai Sun, Shuyi Wang, Qunhong Zeng, Di Wang, Xuandong Zhao, Yuanli Wang, Roey Ben Chaim, Zonglin Di, Yipeng Gao, Junwei He, Yizhuo He, Liqiang Jing, Luyang Kong, Xin Lan, Jiachen Li, Songlin Li, Yijiang Li, Yueqian Lin, Xinyi Liu, Xuanqing Liu, Haoran Lyu, Ze Ma, Bowei Wang, Runhui Wang, Tianyu Wang, Wengao Ye, Yue Zhang, Hanwen Xing, Yiqi Xue, Steven Dillmann, and Han chung Lee. Skillsbench: Benchmarking how well agent skills work across diverse tasks, 2026a. URL https://arxiv.org/abs/2602.12670.Source
- Han et al. [2026] Tingxu Han, Yi Zhang, Wei Song, Chunrong Fang, Zhenyu Chen, Youcheng Sun, and Lijie Hu. Swe-skills-bench: Do agent skills actually help in real-world software engineering?, 2026. URL https://arxiv.org/abs/2603.15401.Source
- Zhong et al. [2026] Shanshan Zhong, Yi Lu, Jingjie Ning, Yibing Wan, Lihan Feng, Yuyi Ao, Leonardo F. R. Ribeiro, Markus Dreyer, Sean Ammirati, and Chenyan Xiong. Skilllearnbench: Benchmarking continual learning methods for agent skill generation on real-world tasks, 2026. URL https://arxiv.org/abs/2604.20087.Source
- Liu et al. [2026a] Yujian Liu, Jiabao Ji, Li An, Tommi Jaakkola, Yang Zhang, and Shiyu Chang. How well do agentic skills work in the wild: Benchmarking llm skill usage in realistic settings, 2026a. URL https://arxiv.org/abs/2604.04323.Source
- Zheng et al. [2026] YanZhao Zheng, ZhenTao Zhang, Chao Ma, YuanQiang Yu, JiHuai Zhu, Yong Wu, Tianze Xu, Baohua Dong, Hangcheng Zhu, Ruohui Huang, and Gang Yu. Skillrouter: Skill routing for llm agents at scale, 2026. URL https://arxiv.org/abs/2603.22455.Source
- Cho et al. [2026] Hongcheol Cho, Ryangkyung Kang, and Youngeun Kim. Skillret: A large-scale benchmark for skill retrieval in llm agents, 2026. URL https://arxiv.org/abs/2605.05726.Source
- Li et al. [2026b] Hao Li, Chunjiang Mu, Jianhao Chen, Siyue Ren, Zhiyao Cui, Yiqun Zhang, Lei Bai, and Shuyue Hu. Organizing, orchestrating, and benchmarking agent skills at ecosystem scale, 2026b. URL https://arxiv.org/abs/2603.02176.Source
- Zhou et al. [2026] Yifan Zhou, Zhentao Zhang, Ziming Cheng, Shuo Zhang, Qizhen Lan, Zhangquan Chen, Zhi Yang, QianyuXu, Ronghao Chen, Huacan Wang, and Sen Hu. Skillgenbench: Benchmarking skill generation pipelines for llm agents, 2026. URL https://arxiv.org/abs/2605.18693.Source
- Ying et al. [2026] Jiahao Ying, Boxian Ai, Wei Tang, Siyuan Liu, and Yixin Cao. Openskilleval: Automatically auditing the open skill ecosystem for llm agents, 2026. URL https://arxiv.org/abs/2605.23657.Source
- Anthropic [2025b] Anthropic. Claude Code: an agentic coding tool. https://github.com/anthropics/claude-code, 2025b.Source
- OpenAI [2025] OpenAI. Codex CLI: Lightweight coding agent that runs in your terminal. https://github.com/openai/codex, 2025.Source
- MiniMax [2026] MiniMax. The minimax-m2 series: Mini activations unleashing max real-world intelligence. CoRR, abs/2605.26494, 2026. 10.48550/ARXIV.2605.26494. URL https://doi.org/10.48550/arXiv.2605.26494.SourceSource
- Team [2026] Kimi Team. Kimi K2.5: visual agentic intelligence, 2026. URL https://doi.org/10.48550/arXiv.2602.02276.Source
- DeepSeek-AI [2026] DeepSeek-AI. Deepseek-v4: Towards highly efficient million-token context intelligence, 2026.
- GLM [2026] GLM. GLM-5: from vibe coding to agentic engineering. CoRR, abs/2602.15763, 2026. 10.48550/ARXIV.2602.15763. URL https://doi.org/10.48550/arXiv.2602.15763.SourceSource
- Karaaslan [2026] Yusuf Karaaslan. Skill seekers, 2026. URL https://github.com/yusufkaraaslan/Skill_Seekers. Repository for converting documentation websites, GitHub repositories, and PDFs into Claude-compatible skills.Source
- Chen et al. [2026b] Le Chen, Erhu Feng, Yubin Xia, and Haibo Chen. Skvm: Revisiting language vm for skills across heterogenous llms and harnesses, 2026b. URL https://arxiv.org/abs/2604.03088.Source
- Zhang et al. [2026a] Hanrong Zhang, Shicheng Fan, Henry Peng Zou, Yankai Chen, Zhenting Wang, Jiayu Zhou, Chengze Li, Wei-Chieh Huang, Yifei Yao, Kening Zheng, Xue Liu, Xiaoxiao Li, and Philip S. Yu. Coevoskills: Self-evolving agent skills via co-evolutionary verification, 2026a. URL https://arxiv.org/abs/2604.01687.Source
- Si et al. [2026] Shuzheng Si, Haozhe Zhao, Yu Lei, Qingyi Wang, Dingwei Chen, Zhitong Wang, Zhenhailong Wang, Kangyang Luo, Zheng Wang, Gang Chen, Fanchao Qi, Minjia Zhang, and Maosong Sun. From context to skills: Can language models learn from context skillfully?, 2026. URL https://arxiv.org/abs/2604.27660.Source
- Wang et al. [2026] Zifei Wang, Wei Wen, Qiang Ji, Keyu Chen, Ruizhi Qiao, and Xing Sun. Skill is not document: Query-conditioned compatibility for llm agent skill routing, 2026. URL https://arxiv.org/abs/2606.03565.Source
- Liu et al. [2026b] Dawei Liu, Zongxia Li, Hongyang Du, Xiyang Wu, Shihang Gui, Yongbei Kuang, and Lichao Sun. Graph-of-skills: Dependency-aware structural retrieval for massive agent skills. In First Workshop on Agent Skills, 2026b. URL https://openreview.net/forum?id=HfGDY8mV67.Source
- Robertson and Zaragoza [2009] Stephen Robertson and Hugo Zaragoza. The probabilistic relevance framework: Bm25 and beyond. Found. Trends Inf. Retr., 3(4):333–389, April 2009. ISSN 1554-0669. 10.1561/1500000019. URL https://doi.org/10.1561/1500000019.Source
- Cormack et al. [2009] Gordon V. Cormack, Charles L A Clarke, and Stefan Buettcher. Reciprocal rank fusion outperforms condorcet and individual rank learning methods. In Proceedings of the 32nd International ACM SIGIR Conference on Research and Development in Information Retrieval, SIGIR ’09, page 758–759, New York, NY, USA, 2009. Association for Computing Machinery. ISBN 9781605584836. 10.1145/1571941.1572114. URL https://doi.org/10.1145/1571941.1572114.Source
- Bradley and Terry [1952] Ralph Allan Bradley and Milton E. Terry. Rank analysis of incomplete block designs: I. the method of paired comparisons. Biometrika, 39(3/4):324–345, 1952. ISSN 00063444, 14643510. URL http://www.jstor.org/stable/2334029.Source
- Xiao et al. [2024] Shitao Xiao, Zheng Liu, Peitian Zhang, Niklas Muennighoff, Defu Lian, and Jian-Yun Nie. C-pack: Packed resources for general chinese embeddings. In Proceedings of the 47th International ACM SIGIR Conference on Research and Development in Information Retrieval, SIGIR ’24, page 641–649, New York, NY, USA, 2024. Association for Computing Machinery. ISBN 9798400704314. 10.1145/3626772.3657878. URL https://doi.org/10.1145/3626772.3657878.Source
- Zhang et al. [2025a] Yanzhao Zhang, Mingxin Li, Dingkun Long, Xin Zhang, Huan Lin, Baosong Yang, Pengjun Xie, An Yang, Dayiheng Liu, Junyang Lin, Fei Huang, and Jingren Zhou. Qwen3 embedding: Advancing text embedding and reranking through foundation models, 2025a. URL https://arxiv.org/abs/2506.05176.Source
- Liu et al. [2026c] Hongyi Liu, Haoyan Yang, Tao Jiang, Bo Tang, Feiyu Xiong, Yuyu Luo, and Zhiyu Li. Skillsvote: Lifecycle governance of agent skills from collection, recommendation to evolution, 2026c.
- Chen et al. [2024] Jianlyu Chen, Shitao Xiao, Peitian Zhang, Kun Luo, Defu Lian, and Zheng Liu. M3-embedding: Multi-linguality, multi-functionality, multi-granularity text embeddings through self-knowledge distillation. In Lun-Wei Ku, Andre Martins, and Vivek Srikumar, editors, Findings of the Association for Computational Linguistics: ACL 2024, pages 2318–2335, Bangkok, Thailand, August 2024. Association for Computational Linguistics. 10.18653/v1/2024.findings-acl.137. URL https://aclanthology.org/2024.findings-acl.137/.SourceSource
- OpenAI [2026a] OpenAI. GPT-5.6: Frontier intelligence that scales with your ambition. https://openai.com/index/gpt-5-6/, July 2026a. Accessed: 2026-07-29.Source
- OpenAI [2026b] OpenAI. Introducing GPT-5.4 mini and nano. https://openai.com/index/introducing-gpt-5-4-mini-and-nano/, March 2026b. Accessed: 2026-07-29.Source
- Wang et al. [2025a] Zora Zhiruo Wang, Jiayuan Mao, Daniel Fried, and Graham Neubig. Agent workflow memory. In Aarti Singh, Maryam Fazel, Daniel Hsu, Simon Lacoste-Julien, Felix Berkenkamp, Tegan Maharaj, Kiri Wagstaff, and Jerry Zhu, editors, Forty-second International Conference on Machine Learning, ICML 2025, Vancouver, BC, Canada, July 13-19, 2025, volume 267 of Proceedings of Machine Learning Research. PMLR / OpenReview.net, 2025a. URL https://proceedings.mlr.press/v267/wang25bx.html.Source
- Fang et al. [2026] Runnan Fang, Yuan Liang, Xiaobin Wang, Jialong Wu, Shuofei Qiao, Pengjun Xie, Fei Huang, Huajun Chen, and Ningyu Zhang. Memp: Exploring agent procedural memory, 2026. URL https://arxiv.org/abs/2508.06433.Source
- Zhang et al. [2025b] Guibin Zhang, Muxin Fu, and Shuicheng Yan. Memgen: Weaving generative latent memory for self-evolving agents, 2025b. URL https://arxiv.org/abs/2509.24704.Source
- Ouyang et al. [2025] Siru Ouyang, Jun Yan, I-Hung Hsu, Yanfei Chen, Ke Jiang, Zifeng Wang, Rujun Han, Long T. Le, Samira Daruki, Xiangru Tang, Vishy Tirumalashetty, George Lee, Mahsan Rofouei, Hangfei Lin, Jiawei Han, Chen-Yu Lee, and Tomas Pfister. Reasoningbank: Scaling agent self-evolving with reasoning memory, 2025. URL https://arxiv.org/abs/2509.25140.Source
- Wang et al. [2025b] Jiongxiao Wang, Qiaojing Yan, Yawei Wang, Yijun Tian, Soumya Smruti Mishra, Zhichao Xu, Megha Gandhi, Panpan Xu, and Lin Lee Cheong. Reinforcement learning for self-improving agent with skill library, 2025b. URL https://arxiv.org/abs/2512.17102.Source
- Zheng et al. [2025b] Boyuan Zheng, Michael Y. Fatemi, Xiaolong Jin, Zora Zhiruo Wang, Apurva Gandhi, Yueqi Song, Yu Gu, Jayanth Srinivasa, Gaowen Liu, Graham Neubig, and Yu Su. Skillweaver: Web agents can self-improve by discovering and honing skills, 2025b. URL https://arxiv.org/abs/2504.07079.Source
- Yu et al. [2025] Simon Yu, Gang Li, Weiyan Shi, and Peng Qi. Polyskill: Learning generalizable skills through polymorphic abstraction, 2025. URL https://arxiv.org/abs/2510.15863.Source
- Tang et al. [2025] Xiangru Tang, Tianrui Qin, Tianhao Peng, Ziyang Zhou, Daniel Shao, Tingting Du, Xinming Wei, Peng Xia, Fang Wu, He Zhu, Ge Zhang, Jiaheng Liu, Xingyao Wang, Sirui Hong, Chenglin Wu, Hao Cheng, Chi Wang, and Wangchunshu Zhou. Agent kb: Leveraging cross-domain experience for agentic problem solving, 2025. URL https://arxiv.org/abs/2507.06229.Source
- Wu et al. [2026] Yue Wu, Tianhao Su, Shunbo Hu, and Deng Pan. Skill-based autonomous agents for material creep database construction, 2026. URL https://arxiv.org/abs/2602.03069.Source
- Xia et al. [2026] Peng Xia, Jianwen Chen, Hanyang Wang, Jiaqi Liu, Kaide Zeng, Yu Wang, Siwei Han, Yiyang Zhou, Xujiang Zhao, Haifeng Chen, Zeyu Zheng, Cihang Xie, and Huaxiu Yao. Skillrl: Evolving agents via recursive skill-augmented reinforcement learning, 2026. URL https://arxiv.org/abs/2602.08234.Source
- Zhang et al. [2026b] Haozhen Zhang, Quanyu Long, Jianzhu Bao, Tao Feng, Weizhi Zhang, Haodong Yue, and Wenya Wang. Memskill: Learning and evolving memory skills for self-evolving agents, 2026b. URL https://arxiv.org/abs/2602.02474.Source
- Vercel [2026] Vercel. Skills.sh: The open agent skills ecosystem. https://skills.sh/, 2026. Accessed: 2026-02-06.Source
- OpenClaw [2026] OpenClaw. Clawhub: The skill dock for sharp agents. https://clawhub.ai/, 2026. Accessed: 2026-02-22.Source
- Liu et al. [2026d] Yi Liu, Weizhe Wang, Ruitao Feng, Yao Zhang, Guangquan Xu, Gelei Deng, Yuekang Li, and Leo Zhang. Agent skills in the wild: An empirical study of security vulnerabilities at scale, 2026d. URL https://arxiv.org/abs/2601.10338.Source
- Ling et al. [2026] George Ling, Shanshan Zhong, and Richard Huang. Agent skills: A data-driven analysis of claude skills for extending large language model functionality, 2026. URL https://arxiv.org/abs/2602.08004.Source
- Li et al. [2026c] Xiangyi Li, Wenbo Chen, Yimin Liu, Shenghan Zheng, Xiaokun Chen, Yifeng He, Yubo Li, Bingran You, Haotian Shen, Jiankai Sun, et al. Skillsbench: Benchmarking how well agent skills work across diverse tasks. arXiv preprint arXiv:2602.12670, 2026c. URL https://arxiv.org/abs/2602.12670.Source