Planning under Noise with Neural Operators
arXiv:2610.28623v1 · This workspace stays on this version. Check arXiv for newer versions
Some source details need review 3 to check
Original formulas, table values and figures are preserved. Comparison can miss differences; use the original PDF to check details.
Reading view checked: 802 math expressions, 0 rendering failures; 18 of 18 images available.
Compared 251 of 288 source passages against 28 of 28 PDF pages.
- Some graphics are laid out differently in the HTML source than in the paper (text or formulas outside their frame); check the original PDF. (1)
- S1_F2: the arXiv HTML draws text or formulas of this graphic outside its frame and it could not be corrected safely (too-small); the image shows the HTML layout, which differs from the PDF.
- This long paper was only partially compared; the original sources remain available.
18 of 18 figure, table and graphic images captured. Open original PDF
Abstract
Planning under uncertain control execution noise requires reliable feedback policies across diverse environments. We introduce Planning Under Noise (PUN), a neural operator that learns noise-aware value fields for planning in unseen geometries. Building on an established screened-Poisson formulation of stochastic optimal control, we address two challenges: specifying boundary conditions that support navigation across varying geometries and efficiently computing fields with reliable gradients. Zero-Dirichlet obstacle boundaries terminate sampled paths at walls, weakening the goal signal along long routes and making it harder to estimate reliably. We instead impose reflecting Neumann conditions on obstacles and a Dirichlet condition at the goal, allowing sampled paths to continue exploring free space until they reach the target. To solve the resulting PDE without a configuration-space mesh, we extend a Monte Carlo (MC) solver, Walk on Stars (WoSt), to higher dimensions. However, local MC fluctuations can reverse estimated gradient directions and cause planning failures, making direct planning require costly sampling. PUN amortizes this computation by learning geometry-to-field mappings from noisy, partially converged Monte Carlo labels, avoiding expensive convergence for every training example. At inference, test-time scaling uses bounded local search guided by the predicted global field. We evaluate PUN on planning tasks across dimensions. Across four noise levels, PUN matches or outperforms all compared planners, achieving 95–100% success on the 4D replanning benchmark while maintaining the lowest runtime. At the highest tested noise level in 4D (), PUN achieves 10.7–60.6% relative gains in success rate over other methods while running 3.29–32.15 faster.
Planning (Latombe, 1991) is one of the most fundamental problems in robotics. Given a robot’s configuration space (LaValle, 2006), planning computes a path from the current configuration to a goal that is optimal under a given cost function. Real robots do not execute a commanded motion exactly (Thrun, 2002). These errors accumulate along a motion, so a route planned with a few centimetres of clearance can be executed into a wall. Sampling-based planners such as PRM (Kavraki et al., 1996) and RRT (LaValle and Kuffner, 2001), and graph search such as A⋆ (Hart et al., 1968), plan for a nominal system that executes commands exactly and leave the noise to a tracking controller. Sampling-based methods such as MPPI (Williams et al., 2017a) and PI-CMA (Stulp and Sigaud, 2012) optimize control sequences or policy parameters using sampled trajectory costs. Optimal feedback under execution noise can be derived from a value function, which gives the minimum expected cost of reaching the goal from each configuration and satisfies the nonlinear Hamilton–Jacobi–Bellman (HJB) equation (Fleming and Soner, 2006). Solving this equation on a grid scales exponentially with the dimension of the configuration space (Bellman, 1957; Han et al., 2018).
While the problem can be converted into a linear screened Poisson equation (Theodorou et al., 2010) under control–noise matching (Assumption 1), a central difficulty in Poisson-based planning is specifying boundary conditions that produce a reliable value field across varying geometries.
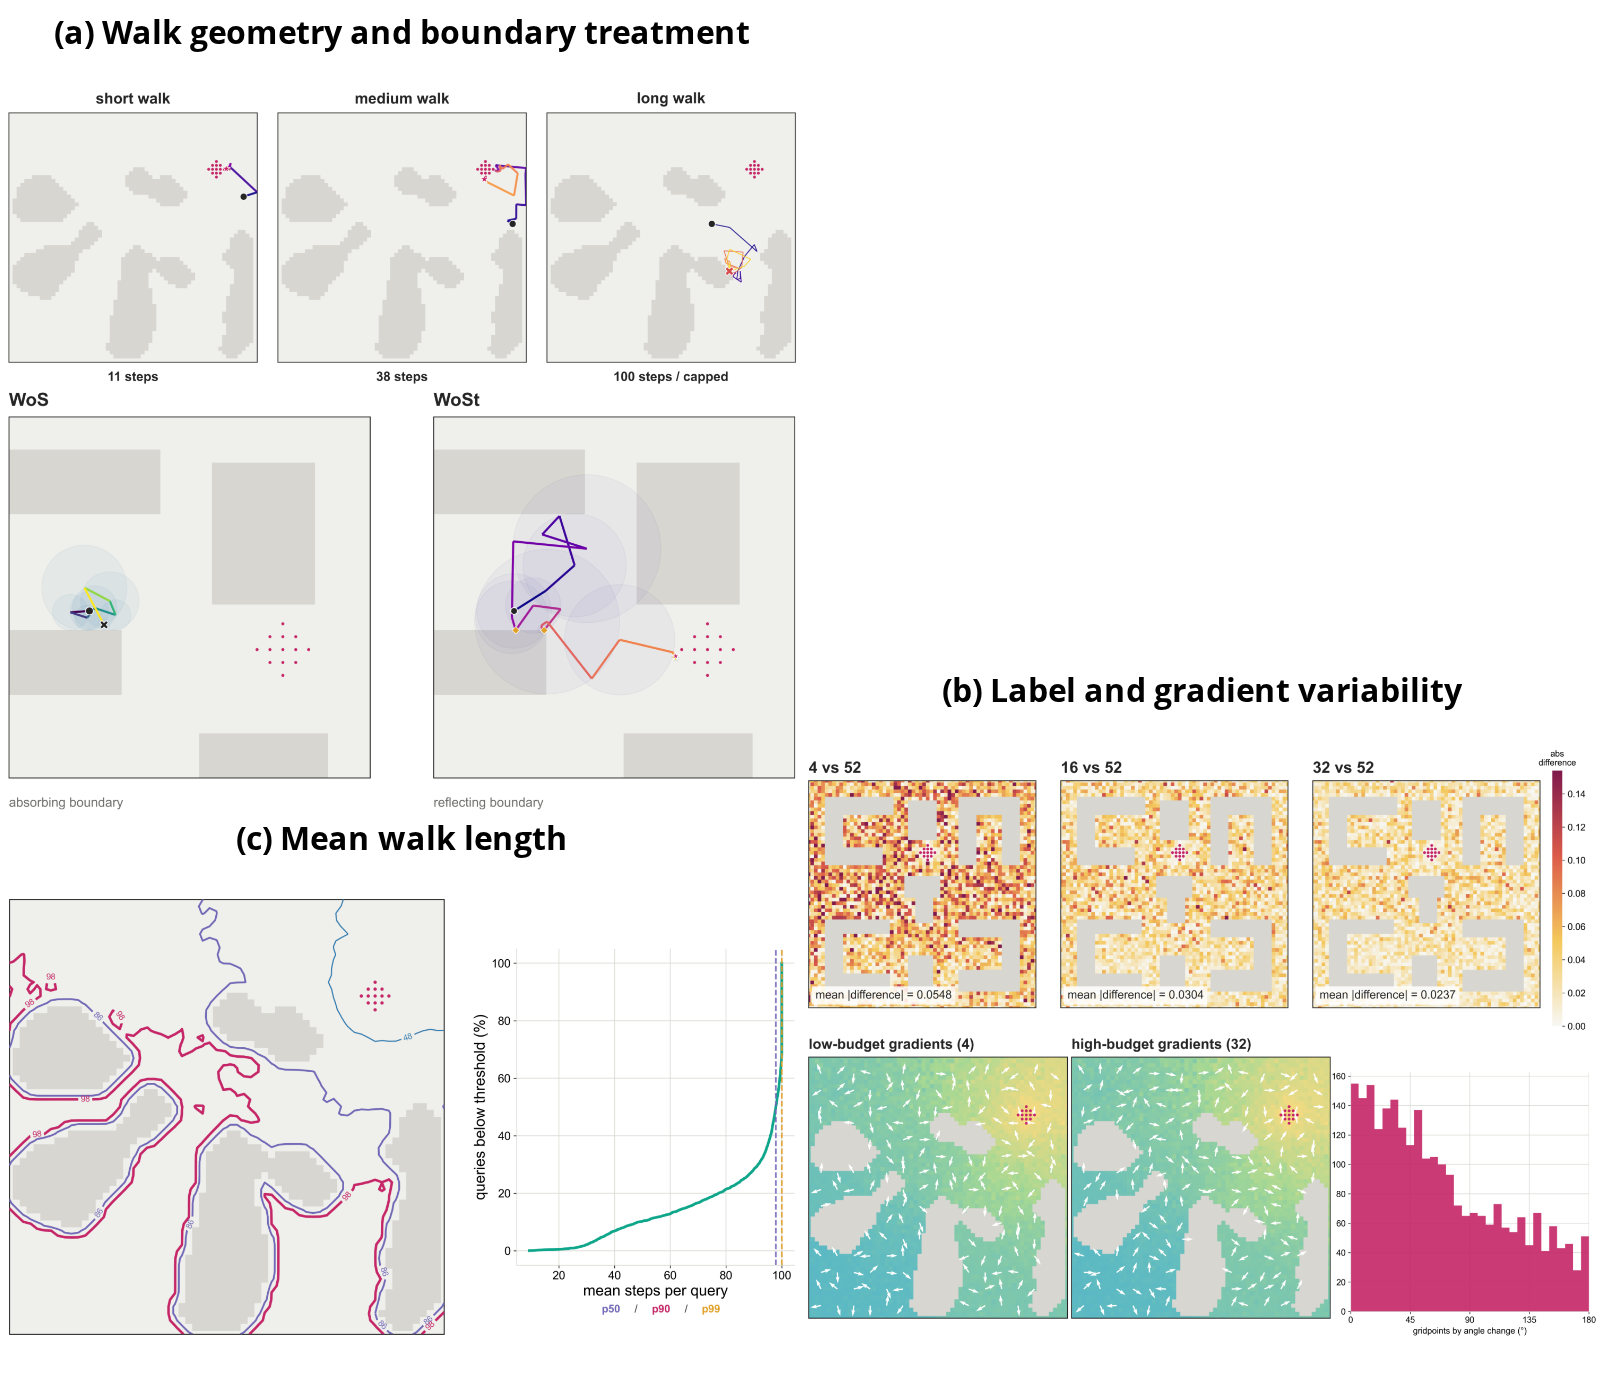
Conventional mesh-based numerical methods can solve the screened Poisson equation efficiently in two and three dimensions. However, a robot with degrees of freedom (DoF) induces a -dimensional configuration space, making volumetric discretizations and numerical PDE solution increasingly expensive. Planning must also accommodate complex and previously unseen obstacle geometries, for which constructing a new mesh and solving the PDE from scratch can be costly. Mesh-free Monte Carlo methods (Muller, 1956; Sawhney and Crane, 2020; Sawhney et al., 2023; Jambon et al., 2026) support PDE solution on complex geometries, motivating their use for planning in higher-dimensional configuration spaces.
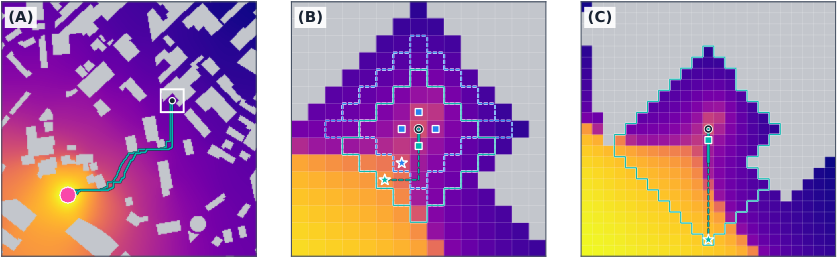
Among these, Walk-on-Spheres (WoS) (Muller, 1956) estimates the solution at a point by jumping repeatedly to a uniformly sampled point on the largest ball fitting in free space, until it reaches a boundary of known value, which requires every reachable boundary to be Dirichlet. Walk-on-Stars (WoSt) (Sawhney et al., 2023) accommodates reflecting obstacles by replacing that ball with a star-shaped region that may contain part of the obstacle boundary, keeping every boundary point visible from the center so that one ray continues the walk instead of branching at each contact. The screened kernels for Walk-on-Stars have been derived only in two and three dimensions (Sawhney et al., 2023). Moreover, directly planning with Monte Carlo estimates is unreliable: trajectories depend on local value gradients, and even modest estimator noise can corrupt or reverse the estimated direction, leading to planning failure.
Neural operators (Kovachki et al., 2023) can amortize expensive PDE solves by learning mappings from input geometries directly to solution fields. Moreover, prior work has shown that fully converged labels are unnecessary when training from Monte Carlo simulations: neural operators can recover accurate predictions from noisy, partially converged estimates (Viswanath et al., 2026). This enables training of neural operators with inexpensive Monte Carlo supervision while providing fast, smooth value-field predictions at inference time.
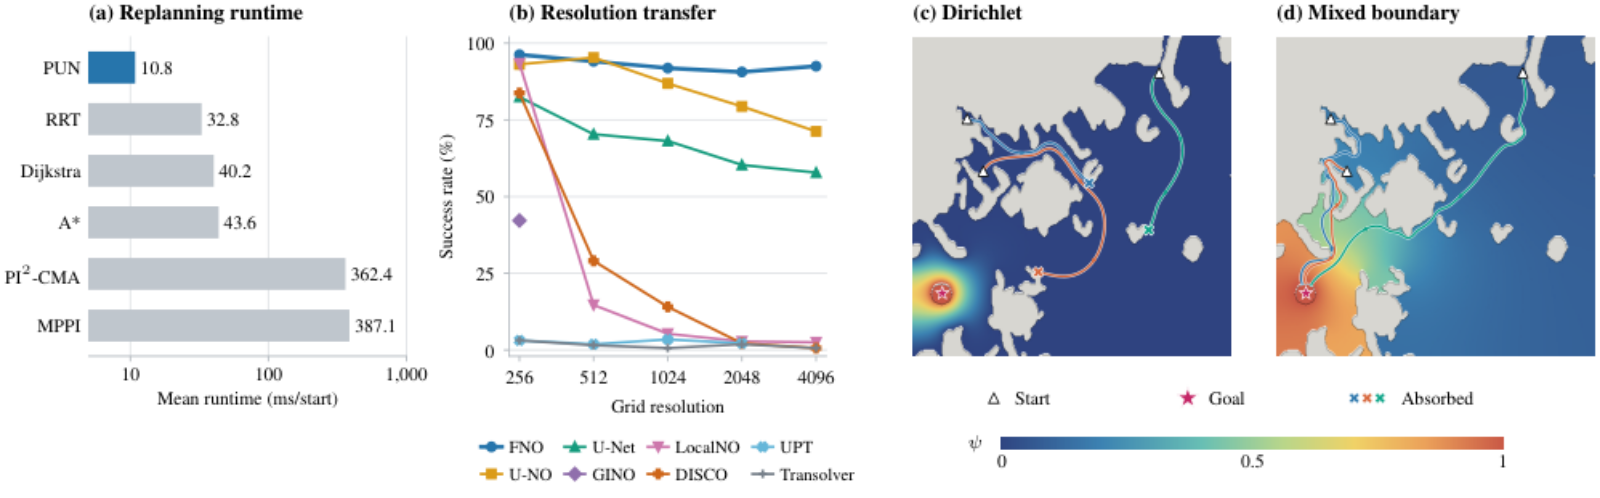
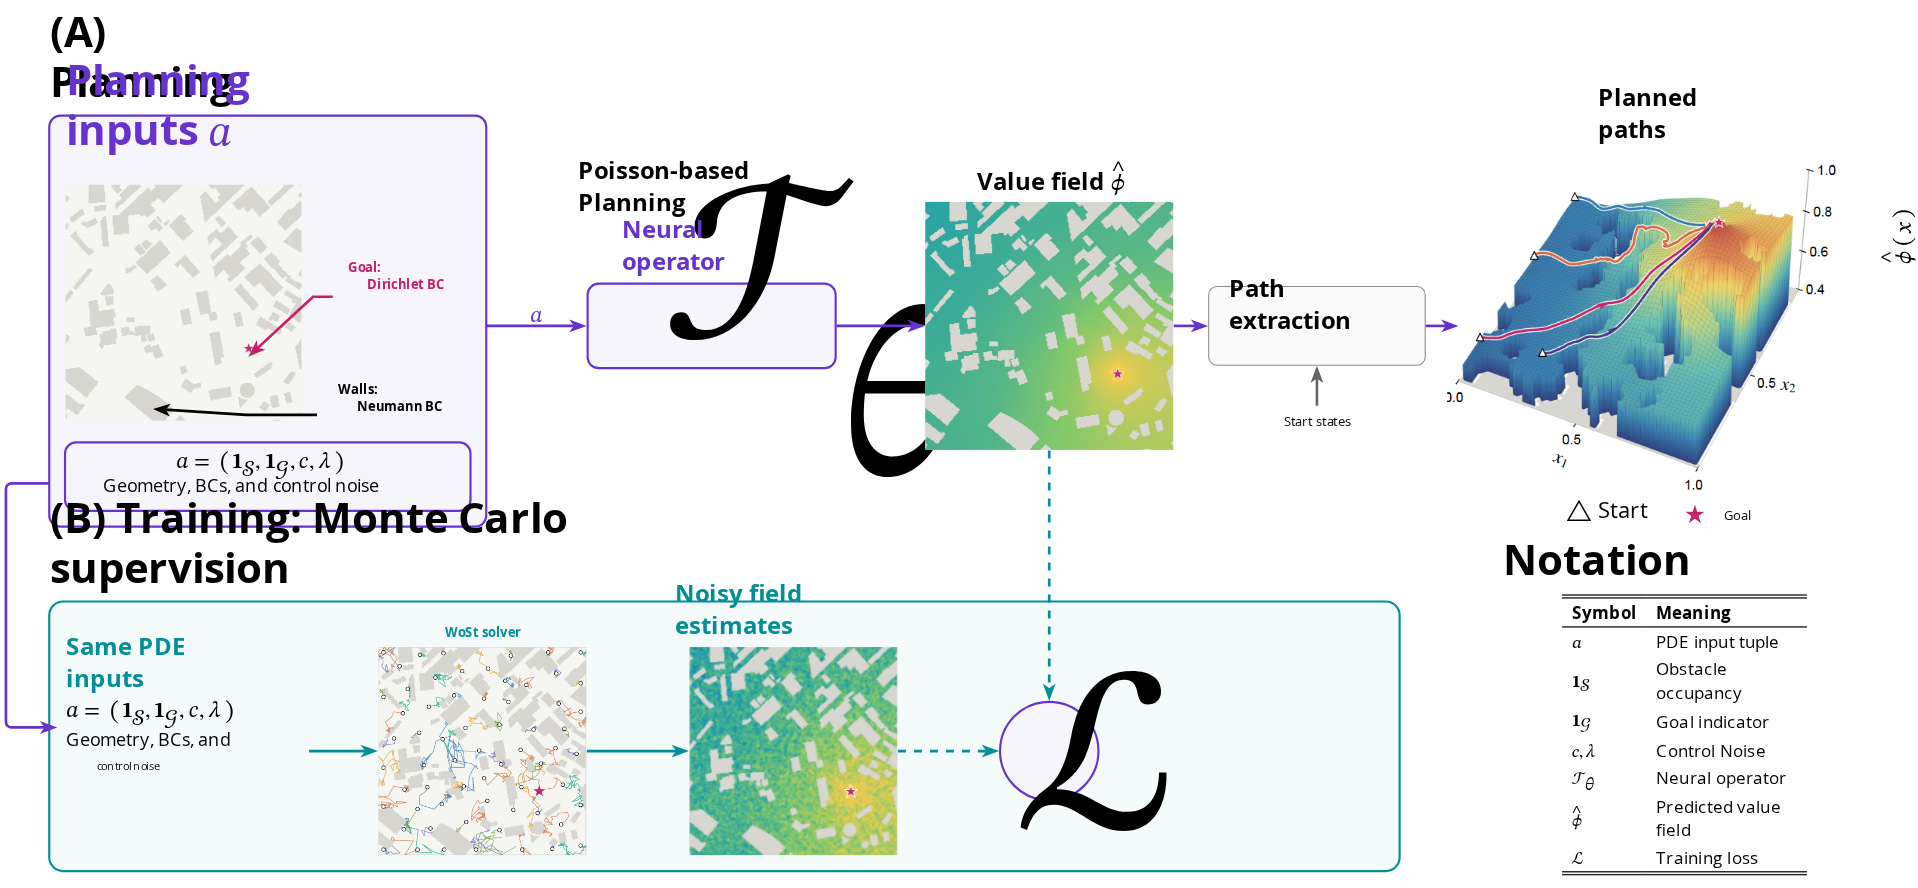
We propose Planning Under Noise (PUN), shown in Fig. 2, an operator-learning framework that maps environment geometry to value fields that account for control noise. Boundary conditions can be understood through a heat analogy. With unit desirability at the goal and zero desirability on obstacle boundaries, the goal acts like a hot source, while the obstacle walls act like cold sinks. The zero-Dirichlet condition fixes the field to zero along each obstacle surface, making the entire obstacle boundary a heat sink. In a long or narrow passage, heat spreading from the goal therefore leaks into the walls along the route. The farther the goal’s influence must travel, the more it is attenuated, leaving a weak signal in distant parts of free space that discretization, sampling, or learning errors can obscure. Narrow passages make this particularly pronounced because the absorbing walls remain close on both sides. This attenuation is visible in Fig. 1(c), where the weak goal signal provides insufficient directional guidance for starting points far from the goal, making it difficult to navigate toward the target. Moreover, the screened Poisson equation already includes decay throughout free space through its screening term; absorbing obstacle boundaries introduce an additional source of attenuation. We therefore keep a Dirichlet condition at the goal but impose homogeneous Neumann (zero-flux) conditions on obstacle boundaries. The walls now act like insulation: they prevent heat from escaping through the boundary without forcing the desirability itself to vanish there. Heat can spread along a corridor without continually draining into its walls, allowing the goal’s influence to reach farther into free space. Screening still causes decay, but the additional loss through obstacles is removed. This is precisely the effect illustrated in Fig. 1(d): compared with the absorbing Dirichlet field in Fig. 1(c), the mixed-boundary field extends the goal’s influence much farther through the environment, preserving a stronger signal for planning along long routes. The Neumann condition also makes the value gradient parallel to smooth obstacle boundaries; therefore, gradient-based planning directs motion along walls rather than into them. This permits guidance along walls in narrow passages without the strong repulsion induced by zero-Dirichlet conditions. Under our regularity assumptions, the value field and control remain bounded at obstacles, whereas zero-Dirichlet desirability makes both diverge there (Appendix C.4).
We first derive dimension-general Poisson kernels and Monte Carlo weights, extending mesh-free supervision beyond three dimensions for scalability. This enables supervision generation without a volumetric configuration-space mesh. We then train PUN using noisy, partially converged Monte Carlo estimates in the weak supervision paradigm. By amortizing the PDE solution across geometries, PUN produces spatially coherent value fields that guide gradient following and local search without requiring a fully converged Monte Carlo solve for every environment. We evaluate PUN across 2D–4D environments and compare its planning success and runtime with nominal planners and stochastic controllers under execution noise. In the experiments varying the execution noise level , we plan a path from the current state at each control step, follow it briefly, and repeat from the updated state; we refer to this as replanning. Our contributions can be summarized as follows:
- •
We formulate Poisson-based path planning as a mixed boundary-value problem, imposing a Dirichlet condition at the goal and homogeneous Neumann conditions on obstacle boundaries.
- •
We introduce an operator-learning framework that maps environment geometry to noise-aware value fields, enabling zero-shot planning in unseen complex geometries without per-instance retraining or numerical PDE solves.
- •
We generalize the mesh-free Monte Carlo solver WoSt beyond three dimensions by deriving the dimension-dependent Green’s function and step weights for the screened Poisson equation.
- •
On 2D application benchmarks, zero-shot WoSt-supervised FNO reaches 93.62% local-search success, up from 83.87% with gradient following on the same fields (Table 1). With the same local-search, FNO-based PUN achieves approximately and speedups over direct WoSt on the 2D zero-shot application benchmarks and 4D manipulator test set, respectively (Table 12). In 4D replanning, PUN achieves 95.00–100% success at 10.51–11.66 ms/start across the tested noise levels (Table 5; Fig. 1(a)). At , PUN is faster than RRT and – faster than A⋆, Dijkstra, MPPI, and PI-CMA. FNO also maintains over 90% local-search success across resolutions up to ( as many grid points as used in training) without retraining (Fig. 1(b)).
In this section we derive the elliptic boundary value problem that our operator learns, and fix the notation used throughout.
Let and let be the starting point. The controlled process has interior dynamics
with control and standard Brownian motion ; the process reflects normally at obstacles and workspace boundaries () and stops at the goal (). We minimize
where is the first goal hit, , , and is the terminal cost. Write for the Dirichlet desirability; operator learning fixes , hence , while the PDE identities retain general positive . Where the value is it satisfies the stationary HJB equation, which is nonlinear: eliminating the optimal control leaves a term quadratic in (Appendix C.2, Eq. 29).
There exists with for all .
This is the standard condition of linearly solvable stochastic optimal control (Kappen, 2005; Todorov, 2006; Todorov, 2009; Theodorou et al., 2010): a direction that is cheap to actuate is also one along which the system is uncertain, and sets the exchange rate between the two. This matching condition enables the exact linearization of the HJB equation used here. The Cole–Hopf change of variable (Hopf, 1950; Cole, 1951; Fleming, 1977) cancels the quadratic term and turns the HJB equation into a linear elliptic equation for , as shown in Appendix C.2.
For a fully actuated, passive system we take , , and , so Assumption 1 forces . Writing the state cost as with , the linearized equation becomes the screened Poisson equation:
Throughout, we take constant within each environment, so is constant.
Let be the workspace, the obstacle interiors, and an open goal region. The free domain is , assumed connected, with boundary partitioned into and . We impose
A neural operator learns a map from problem data to a solution field (Li et al., 2021). Here we learn the desirability operator
Both geometric inputs are masks on the workspace: is the occupancy map of the obstacles and marks the goal region; goal data is fixed. A single trained model predicts the field for new environments. Its spatial gradients provide control through Eq. 11, and its values support local search (Section 4.4).
Classical planners divide into two families. Sampling-based methods such as PRM (Kavraki et al., 1996), RRT (LaValle and Kuffner, 2001), and RRT⋆ (Karaman and Frazzoli, 2011) build a graph of collision-free motions, while search-based methods such as A⋆ (Hart et al., 1968), Dijkstra (Dijkstra, 1959), and fast marching (Sethian, 1996) compute a cost-to-go over a discretization; both plan for a deterministic system and defer execution noise to tracking and replanning. Sampling-based methods such as MPPI (Williams et al., 2017a; Williams et al., 2017b) and PI-CMA (Stulp and Sigaud, 2012) optimize control sequences or policy parameters using sampled trajectory costs. Our implementations and their treatment of execution noise are described in Appendix D.1. We compare against these planners in Table 5. Planning Neural Operator (PNO) (Matada et al., 2025) learns the solution operator of the Eikonal equation from labels produced by a deterministic solver, but it is limited to deterministic systems. NTFields (Ni and Qureshi, 2023) and EikoNet (Smith et al., 2021) train a physics-informed network on the Eikonal residual, which fits a single geometry per model and must be retrained for each new environment. In contrast, PUN is trained over a family of geometry classes with approximate Monte Carlo supervision across diverse noise ranges to support planning with different noise spectra while achieving reliable stability.
Monte Carlo estimators for PDEs can be categorized depending on the type of PDE, include Walk-on-Spheres (Sawhney and Crane, 2020), Walk-on-Boundaries (Sugimoto et al., 2023), and Backward Stochastic Differential Equations (BSDE) (Zhang, 2017). Recent works combine Monte Carlo methods with neural networks to further reduce variance (Nam et al., 2024; Li et al., 2023a), which train a network by regressing on noisy Monte Carlo targets and thereby amortize repeated pointwise Monte Carlo estimation into a forward pass. Two of their ingredients we adopt directly: a deterministic cap on the number of walk steps, and evaluation of the partially trained model when a walk exceeds that cap. The diffusion loss (Nüsken and Richter, 2021) truncates an SDE simulation and supplements it with a boundary physics loss.
Neural operators parameterize maps between function spaces and can be evaluated on different discretizations, with numerical accuracy depending on the representation (Kovachki et al., 2023). The architectures we compare differ in how they propagate information: FNO (Li et al., 2021), UNO (Rahman et al., 2023), LocalNO (Liu-Schiaffini et al., 2024), DISCO (Ocampo et al., 2023), GINO (Li et al., 2023b), UPT (Alkin et al., 2024) and Transolver (Wu et al., 2024). We include U-Net (Ronneberger et al., 2015) as a fixed-resolution reference. Physics-informed operators such as PINO (Li et al., 2024) add a PDE residual to the objective; we use walk labels as the primary signal with regularization on gradient terms.
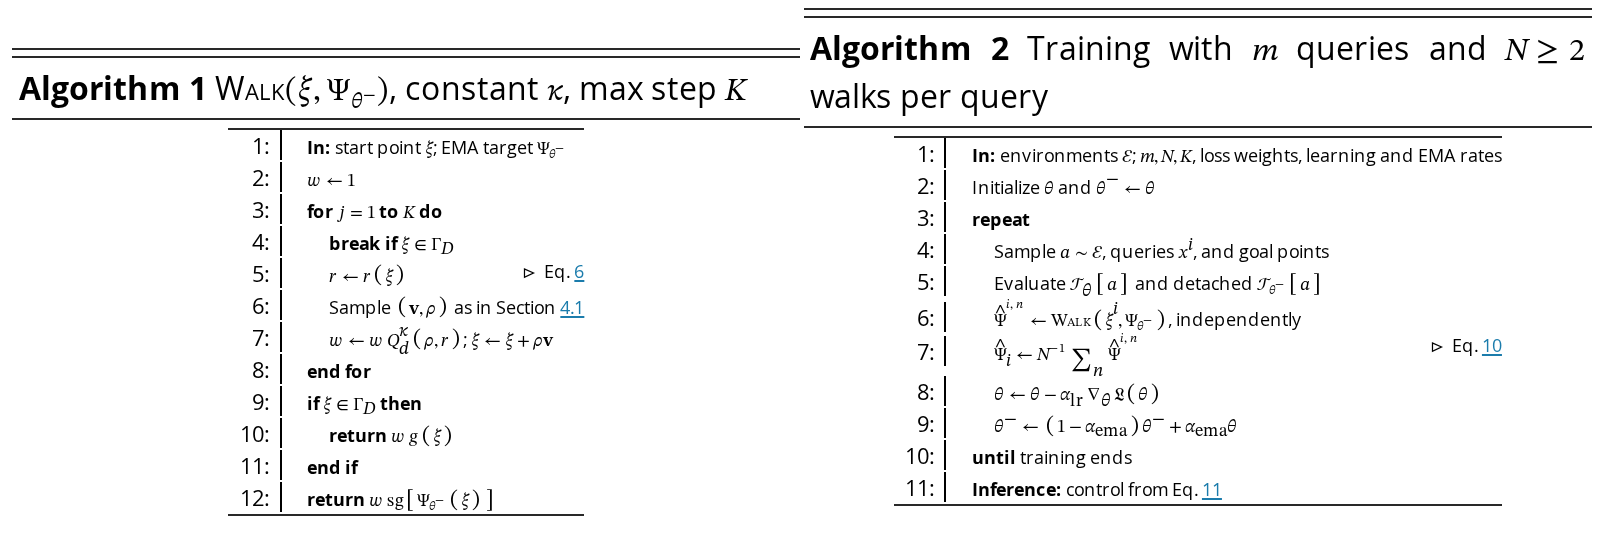
PUN learns a desirability field from Walk-on-Stars supervision and uses the predicted field to guide local search. Labels are constructed directly in -space using finite-horizon walks, with learned continuation for unfinished trajectories. The neural operator is trained online on these labels. Algorithms 1 and 2 describe a single walk and the training loop, respectively; walks and terminal evaluations are batched.
Let be the first exact goal-boundary hit, possibly infinite. The ideal chain stops at an exact hit, where the terminal value is ; practical walks stop in a goal shell or at a finite horizon. For a spatial location , the star radius is
Here is the distance to the closest visibility silhouette of . An admissible star step additionally requires that this component be star-shaped about and that its boundary consist only of the sphere and . Appendix D.1 describes the shell stopping rule and radius floor used in place of exact absorption.
Write for the WoSt position after steps, with the starting point and random for . Given , construct with radius . Draw a direction uniformly on the sphere in the interior or on the inward hemisphere at a smooth reflecting boundary point, then move to the first positive hit of the sphere or an obstacle/domain boundary:
The hemisphere restriction replaces the first distribution at . We assume measurable geometry queries and positive hit distances almost surely.
On an admissible star, the direction law has surface density
Screening discounts each step by , given in closed form for every in Appendix C.5. For constant , Green’s identity on each admissible active star gives
Multiplying by the preceding weights makes a bounded martingale. This gives the finite-horizon identity below without requiring an exact goal hit in finitely many steps. The identity concerns the weighted ray sampler; its steps need not follow Brownian exit distributions.
For a finite walk cap , write . Repeated conditional expectation in Eq. 9, keeping the chain fixed after a goal hit, gives
The terminal factor is on a goal hit and the true continuation otherwise. With true continuation and admissible steps, averaging independent replicas gives an unbiased label. Training substitutes learned continuation as described below. See Appendix C.6 for the log-space alternative and its bias correction.
Practical walks stop within a goal shell of width and use a radius floor. Under the smooth-domain and admissibility assumptions, shell stopping with true continuation changes the mean by at most , where . The radius floor can violate admissibility and introduces an additional error of unknown sign (Sawhney et al., 2023). Appendix D.1 gives the implementation and the finite-horizon shell bound.
At the horizon is not available, so training substitutes a detached EMA copy of the model. The resulting bias is that copy’s own error at the endpoint, weighted by the product of the step weights over the steps, so it is discounted wherever steps are long compared with the screening length.
For and a positive differentiable prediction, the desirability field defines the feedback control through its logarithm:
For a coordinate-differentiable decoder, the gradient is obtained by automatic differentiation. A grid-output backbone requires a specified differentiable interpolant or a spatial differentiation rule. The input is defined in Eq. 5, with fixed.
We combine value and goal supervision with gradient loss to train fields for downstream planning:
The target gradient is computed by finite differences of the label field. The displayed gradient loss normalization assumes positive target gradient energy.
The objective is their weighted sum,
The goal loss carries the exact boundary value rather than a walk label. The gradient term is included because a small value error need not give a small gradient error, and the control in Eq. 11 is computed from the gradient: normalizes gradient error by target gradient energy, treating the denominator as fixed during differentiation. Direct- supervision avoids log-transform bias and weights absolute field error, giving small absolute errors in low-desirability regions less weight than log-space supervision. Appendix C.6 reports the log-space alternative, in which errors are measured on a relative scale.
PUN supports test-time scaling by increasing the local search budget without modifying the learned global field. More depth lets the search evaluate more reachable endpoints, while using the field for guidance. The same endpoint search can be run on other fields; in PUN, it is run on a global noise-aware field that is reused across replans.
Paths are extracted from on a lattice. Let be the free cells at spacing . The feasible neighbors of are , the axis-adjacent free cells. Write for the states reachable from in at most such moves, including itself. A plan is a feasible lattice path with , scored by the predicted desirability at its endpoint. For and , maximizing this score is equivalent to minimizing at the endpoint. The score itself is well defined for any finite prediction.
A controller is specified by a depth and commit length . With one edge committed per replan, the next move is
a step towards the largest desirability reachable through a candidate neighbor. For , a path maximizing endpoint desirability is constructed, its first edges are executed, and the search is repeated from the new state. Execution stops early upon reaching the goal. See Appendix D.1 for further details.
A key idea is that evaluating reachable endpoints permits an intermediate decrease in desirability when it leads to a better state, so local fluctuations need not determine the next move. This might happen when the field is not smooth and there are local valleys, so local search allows jumps over imperfect predictions. Appendix C.8 derives the graph-search rule and its large-depth limit, and Section 5 evaluates planning performance.
Optionally, local search can include a soft wall penalty,
where , is the preferred clearance in cells, and measures distance to obstacles or the outer boundary. Normally ; near a goal reachable within the local depth, it decreases with the remaining free-edge distance to that goal. Among paths retaining at least half the best positive local field gain, we prefer the smallest penalty. Narrow passages and starts or goals near walls are still possible.
We evaluate how backbone, supervision, training objective, and controller affect planning, then test transfer across grid resolutions and replanning under execution noise. Table 1 compares controllers on the same fields, while Table 5 compares complete planners under common execution rules. Models are pretrained on generated environments and evaluated on unseen maps without fine-tuning. The main 2D application suite contains 592 maps and 37,888 starts across robotics, terrain, marine, urban, and game environments (Appendix E). Success measures goal-reaching rate; relative measures field error against FEM references. Unless specified, local search (LS) denotes local search (10). Bold marks the best value in each comparison, including ties. Experiments use NVIDIA B300 and B200 GPUs; training and evaluation protocols are in Appendix D.1.
| Model | Gradient (%) | Local search (4) (%) | Local search (10) (%) | Relative |
|---|---|---|---|---|
| UPT | 2.48 | 2.78 | 3.57 | 0.5533 |
| Transolver | 3.26 | 5.34 | 15.30 | 0.5158 |
| WoSt | 2.71 | 6.30 | 36.45 | 0.1852 |
| GINO | 46.56 | 51.24 | 53.11 | 0.2628 |
| U-Net | 74.21 | 84.22 | 88.98 | 0.1605 |
| DISCO | 82.49 | 87.60 | 91.08 | 0.1041 |
| LocalNO | 80.34 | 86.63 | 91.35 | 0.0915 |
| U-NO | 78.08 | 86.11 | 91.68 | 0.0792 |
| FNO | 83.87 | 91.25 | 93.62 | 0.0615 |
View original table
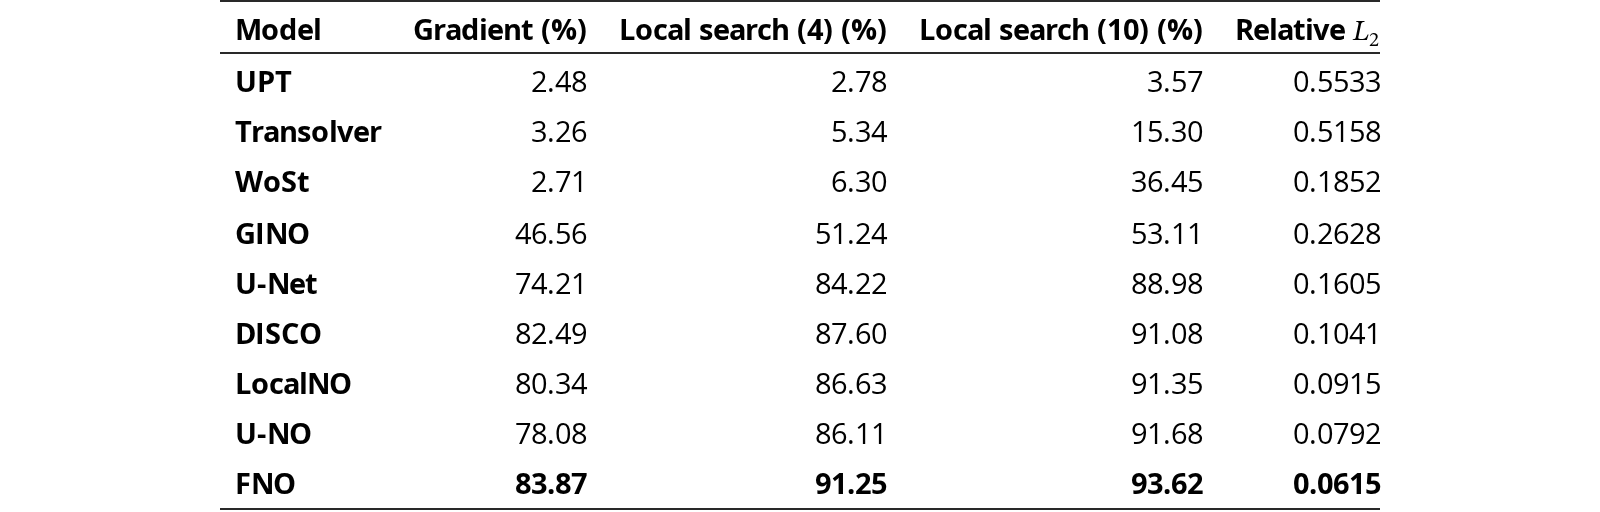
Table 1 compares FNO (Li et al., 2021), U-NO (Rahman et al., 2023), U-Net (Ronneberger et al., 2015), GINO (Li et al., 2023b), LocalNO (Liu-Schiaffini et al., 2024), DISCO (Ocampo et al., 2023), UPT (Alkin et al., 2024), and Transolver (Wu et al., 2024), all trained with WoSt supervision. FNO has the highest success under all three controllers and the lowest relative error (0.0615); its local-search (10) success is 93.62%, compared with 91.68% for the next-best U-NO. These rankings apply to the tested implementations under the training-compute policy in Appendix D.1. Direct WoSt inference reaches only 2.71% gradient and 36.45% local-search (10) success, versus 83.87% and 93.62% for FNO. Thus, at the reported solver settings, learning from approximate WoSt targets yields more useful planning fields than direct inference. We use FNO in the remaining ablations.
With FNO fixed, Table 4 compares WoSt targets, Deep Ritz training (E and Yu, 2018), and PDE-residual training with PINO (Li et al., 2024). WoSt achieves 93.62% local-search success, versus 91.46% for Deep Ritz and 59.69% for PINO; gradient success follows the same ordering (83.87%, 81.41%, and 32.50%). Deep Ritz has slightly lower field error than WoSt (0.0608 versus 0.0615), but lower planning success. Field error is therefore not a reliable indicator of how useful these learned fields are for control.
| Source | Grad. (%) | LS (%) | Rel. err. |
|---|---|---|---|
| WoSt | 83.87 | 93.62 | 0.0615 |
| Deep Ritz | 81.41 | 91.46 | 0.0608 |
| PINO | 32.50 | 59.69 | 0.5644 |
| Steps | Grad. (%) | LS (%) |
|---|---|---|
| 10 | 32.18 | 51.89 |
| 100 | 40.55 | 66.80 |
| 400 | 38.06 | 69.69 |
| 800 | 37.84 | 69.66 |
| Model | Grad. (%) | LS (%) |
|---|---|---|
| Full model | 83.87 | 93.62 |
| value loss | 67.71 | 83.26 |
| goal loss | 82.93 | 93.11 |
| gradient loss | 80.17 | 92.04 |
Table 3 Walk-horizon ablation on the generated 2D test set: planning success (%).
Table 4 FNO loss ablations on 2D application benchmarks: planning success (%).
View original table
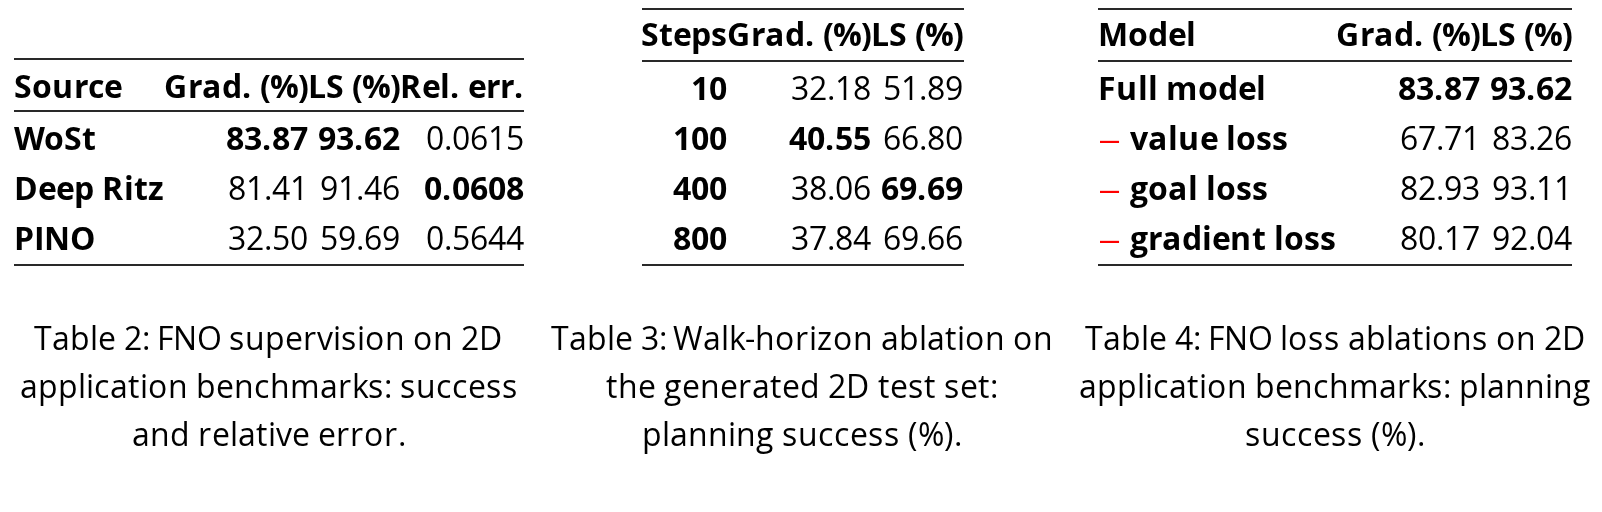
In Table 4, we vary the walk cap using a smaller training budget of 16 maps, eight goals per map, four trajectories per query, and 40 epochs, evaluated on generated 2D maps. Local-search success increases from 51.89% at 10 steps to 69.69% at 400 steps, but is 69.66% at 800 steps. Gradient success instead peaks at 40.55% with 100 steps. Longer walks therefore do not uniformly improve planning: the horizon changes both sampled propagation and reliance on the learned continuation (Section 4.2). Further details of this study are in Appendix D.2. These success rates should not be compared directly with the full-budget application results.
In Table 4, we remove one loss term at a time from Eq. 13. Removing value supervision causes the largest decrease: gradient success falls from 83.87% to 67.71%, and local-search success from 93.62% to 83.26%. Removing goal or gradient supervision gives smaller local-search decreases, to 93.11% and 92.04%, respectively. All three terms help in this setting, with value supervision making the largest measured contribution. These ablations use direct desirability supervision.
On the same learned FNO fields, Table 1 shows success rising from 83.87% with gradient following to 91.25% with local search (4) and 93.62% with local search (10), a total gain of 9.75 percentage points. This test-time refinement requires no retraining. In 2D, the two local-search variants use and , so both depth and committed prefix length change. Local search (10) also exceeds gradient success for every other backbone, although it reaches only 36.45% on direct WoSt fields. Looking beyond immediate neighbors can therefore recover useful routes, but does not eliminate dependence on field quality. Figure 7 illustrates the two search neighborhoods on one fixed field; controller details are in Appendix D.1.
In Fig. 1(b), we test models trained at on grids up to , without retraining. FNO maintains 90.62–96.25% local-search (10) success across the five resolutions and reaches 92.50% at , compared with 71.25% for U-NO and 57.81% for U-Net. U-NO leads at (95.31% versus 94.06% for FNO); FNO leads at the other four resolutions. GINO runs out of memory above . The quantitative comparison supports FNO’s transfer across these discretizations; Fig. 4 separately illustrates predicted fields and paths at three resolutions.
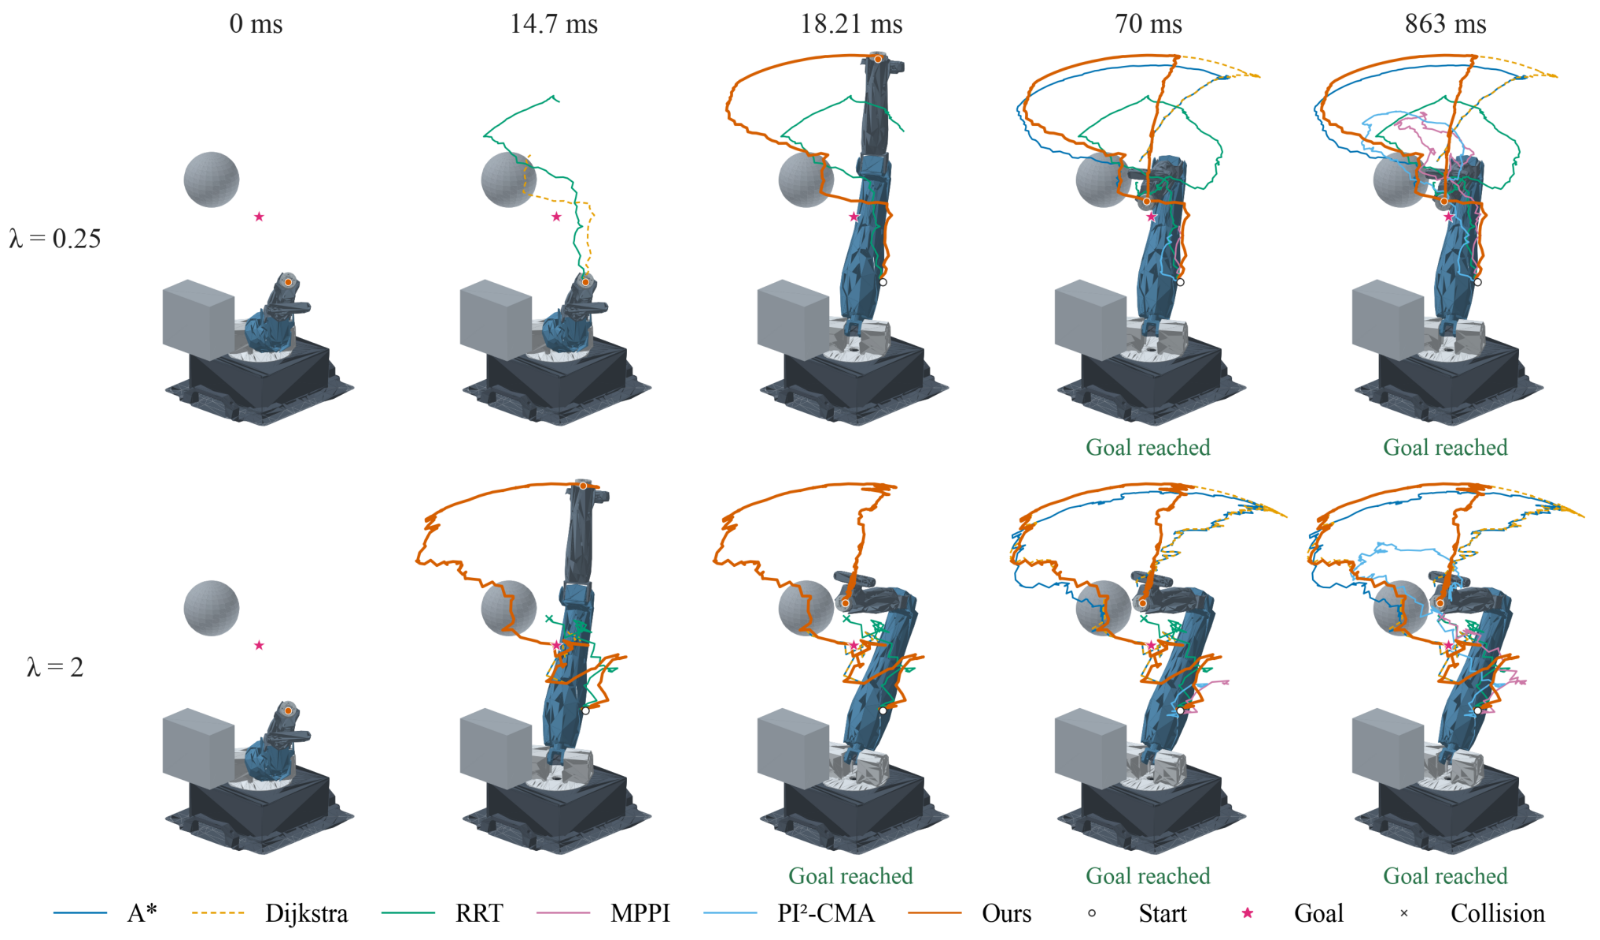
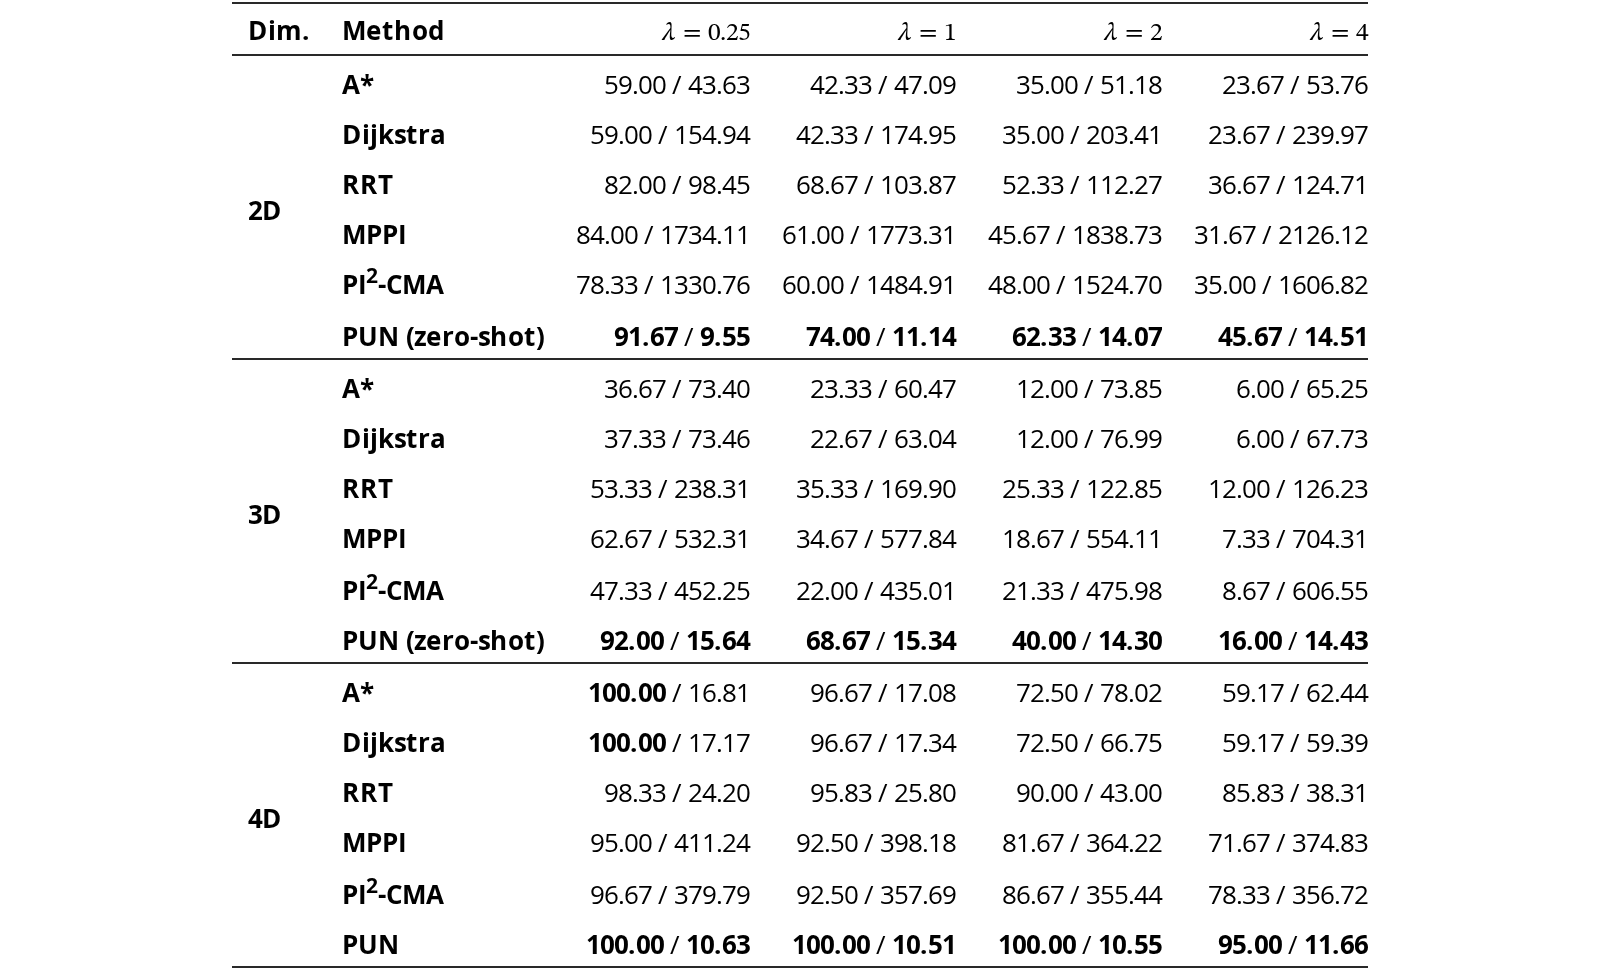
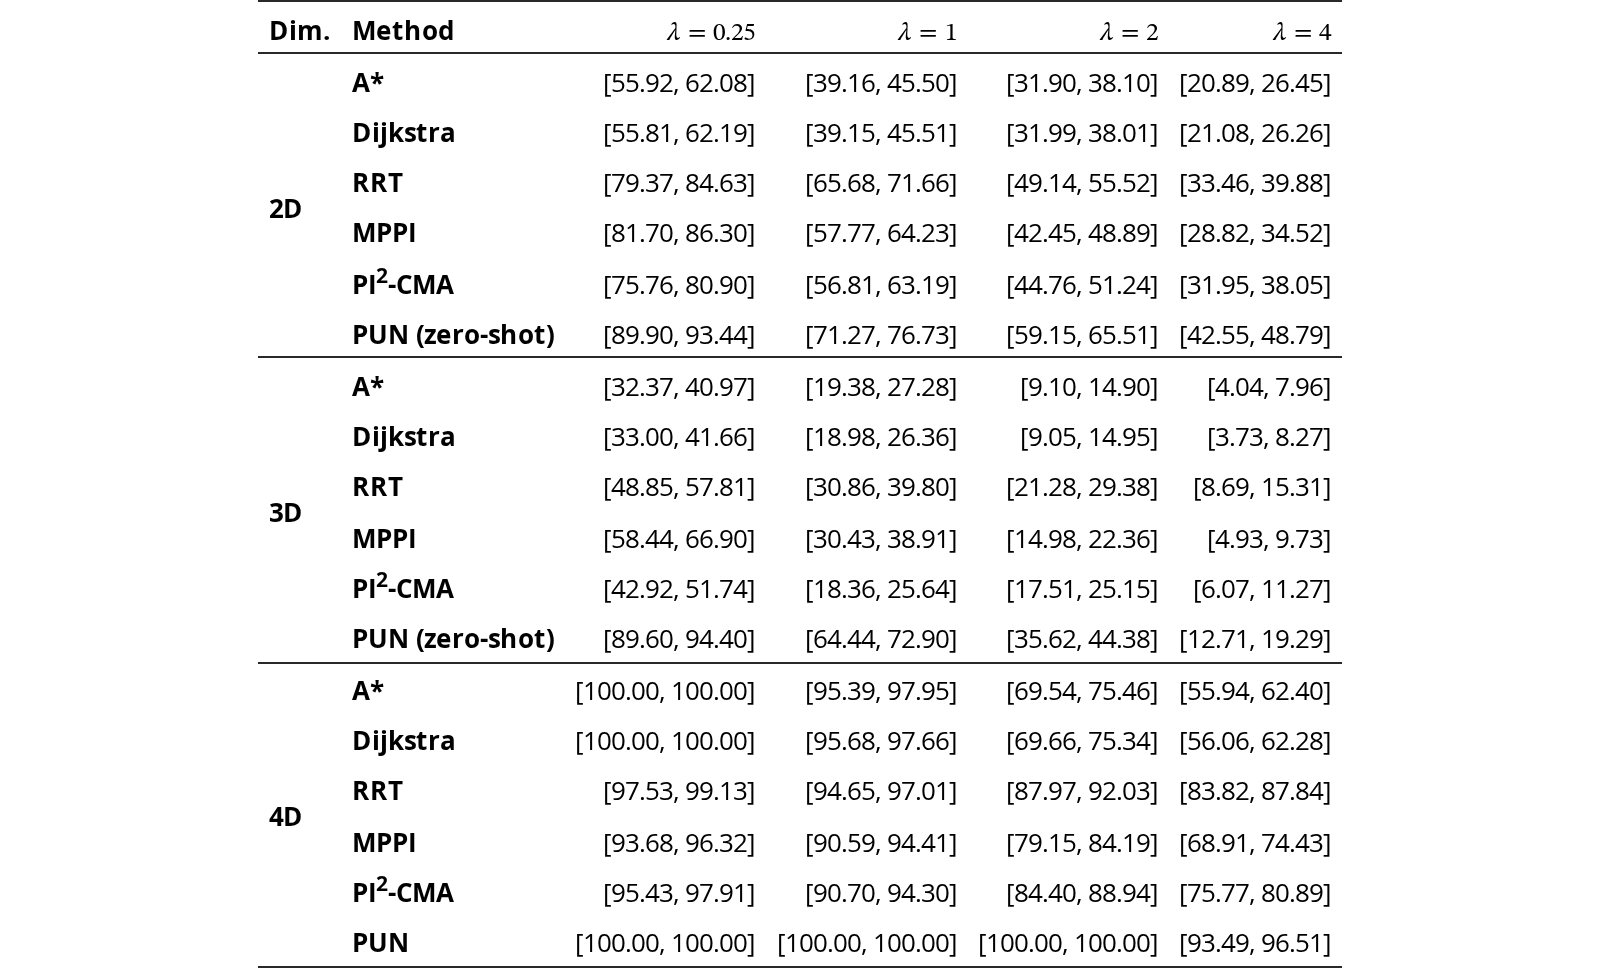
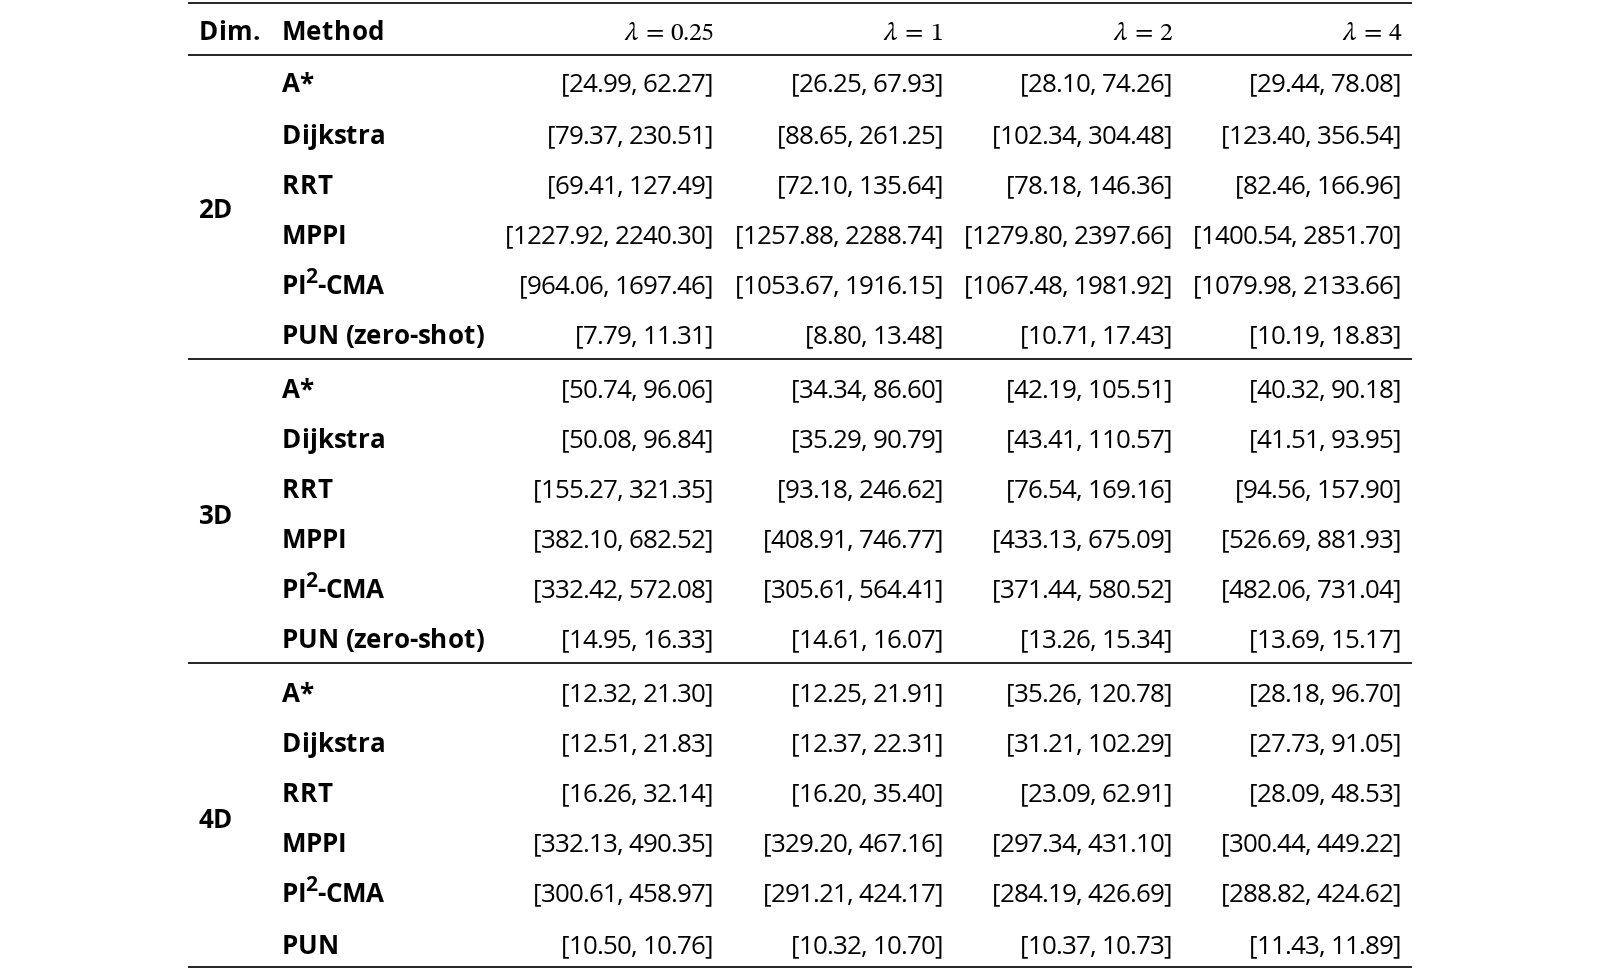
Table 5 compares PUN with A⋆ (Hart et al., 1968), Dijkstra (Dijkstra, 1959), RRT (LaValle and Kuffner, 2001), MPPI (Williams et al., 2017a), and PI-CMA (Stulp and Sigaud, 2012) on 2D and 3D application benchmarks and 4D manipulators. Obstacle hits count as failures (Appendix D.1). PUN has the highest reported success in all 12 dimension–noise settings, tying A⋆ and Dijkstra at in 4D. At , PUN exceeds the strongest baseline, RRT, by 9.00 percentage points in 2D (45.67% versus 36.67%), 4.00 in 3D (16.00% versus 12.00%), and 9.17 in 4D (95.00% versus 85.83%). PUN also has the lowest reported runtime throughout: 9.55–14.51 ms/start in 2D, 14.30–15.64 in 3D, and 10.51–11.66 in 4D. At in 4D, its 11.66 ms/start is 3.29 times faster than the fastest baseline, RRT (38.31 ms/start); Fig. 1(a) summarizes mean 4D runtimes. The advantage is relative: PUN’s 3D success still falls from 92.00% to 16.00% as noise increases. These comparisons concern the reported implementations and settings. Figure 3 shows PUN reaching the goal in two illustrative 4D rollouts at and .
| Dim. | Method | ||||
|---|---|---|---|---|---|
| 2D | A* | 59.00 / 43.63 | 42.33 / 47.09 | 35.00 / 51.18 | 23.67 / 53.76 |
| Dijkstra | 59.00 / 154.94 | 42.33 / 174.95 | 35.00 / 203.41 | 23.67 / 239.97 | |
| RRT | 82.00 / 98.45 | 68.67 / 103.87 | 52.33 / 112.27 | 36.67 / 124.71 | |
| MPPI | 84.00 / 1734.11 | 61.00 / 1773.31 | 45.67 / 1838.73 | 31.67 / 2126.12 | |
| PI-CMA | 78.33 / 1330.76 | 60.00 / 1484.91 | 48.00 / 1524.70 | 35.00 / 1606.82 | |
| PUN (zero-shot) | 91.67 / 9.55 | 74.00 / 11.14 | 62.33 / 14.07 | 45.67 / 14.51 | |
| 3D | A* | 36.67 / 73.40 | 23.33 / 60.47 | 12.00 / 73.85 | 6.00 / 65.25 |
| Dijkstra | 37.33 / 73.46 | 22.67 / 63.04 | 12.00 / 76.99 | 6.00 / 67.73 | |
| RRT | 53.33 / 238.31 | 35.33 / 169.90 | 25.33 / 122.85 | 12.00 / 126.23 | |
| MPPI | 62.67 / 532.31 | 34.67 / 577.84 | 18.67 / 554.11 | 7.33 / 704.31 | |
| PI-CMA | 47.33 / 452.25 | 22.00 / 435.01 | 21.33 / 475.98 | 8.67 / 606.55 | |
| PUN (zero-shot) | 92.00 / 15.64 | 68.67 / 15.34 | 40.00 / 14.30 | 16.00 / 14.43 | |
| 4D | A* | 100.00 / 16.81 | 96.67 / 17.08 | 72.50 / 78.02 | 59.17 / 62.44 |
| Dijkstra | 100.00 / 17.17 | 96.67 / 17.34 | 72.50 / 66.75 | 59.17 / 59.39 | |
| RRT | 98.33 / 24.20 | 95.83 / 25.80 | 90.00 / 43.00 | 85.83 / 38.31 | |
| MPPI | 95.00 / 411.24 | 92.50 / 398.18 | 81.67 / 364.22 | 71.67 / 374.83 | |
| PI-CMA | 96.67 / 379.79 | 92.50 / 357.69 | 86.67 / 355.44 | 78.33 / 356.72 | |
| PUN | 100.00 / 10.63 | 100.00 / 10.51 | 100.00 / 10.55 | 95.00 / 11.66 |
View original table
Several extensions are possible. A spatially varying cost is the most useful: with constant , the state-cost term penalizes elapsed time and the objective also penalizes control effort. Reflection carries no additional contact cost; choosing as a function of obstacle clearance would add a clearance-dependent running cost. Transient problems replace the stationary equation by its time-dependent counterpart, giving a finite-horizon value function rather than a first-exit one, which suits tasks with deadlines or moving goals. Partial information is the most direct use of our amortization: since the operator maps geometry to a field in one forward pass, replanning as a robot discovers obstacles requires only a forward pass on the updated geometry instead of a new solve. The open question is how to condition the operator on a partially observed occupancy map.
The value field is derived for reflecting boundaries. Local search allows its use in collision-failure tasks, but nominal graph feasibility does not guarantee collision-free execution under noise. Deriving the exact value function for that execution model would require a corresponding boundary condition. Assumption 1 is a further restriction. The control–noise matching assumption enables exact HJB linearization and is standard in classical path-integral control (Kappen, 2005; Theodorou et al., 2010). Our experiments are also limited to settings where this assumption is reasonable: we test geometric planning problems in up to four dimensions and do not include full robot models with contact. Evaluating on humanoid robots with contact would test both the assumption and the capacity of the operator. Finally, adversarial geometries such as mazes remain challenging, since long corridors can lead to weak or poorly resolved learned gradients.
We introduced Planning Under Noise (PUN), a neural operator framework that learns noise-aware planning fields from approximate Walk-on-Stars supervision. Dimension-general screening kernels support mesh-free supervision beyond three dimensions, and local search converts predicted fields into paths on unseen geometries. Experiments across 2D–4D environments demonstrate zero-shot planning and effective learning from stochastic labels. In replanning comparisons under execution noise, PUN achieves the lowest reported runtime among the tested methods, while matching or exceeding the success of every compared planner at each tested noise level across 2D–4D.
In this work, we used generative AI tools to assist with parts of method implementation. Additionally, we used generative AI tools to polish writing and proofs and identify relevant literature. We did not use generative AI tools for other applicable tasks requiring disclosure. All AI-assisted work was reviewed and verified by the authors. We take responsibility for the final content of this work, including text, claims, and artifacts produced with the aid of generative AI.
Anima Anandkumar and Xi Deng are both supported in part by the Bren endowed chair and the AI2050 senior fellow program at Schmidt Sciences. Hong Chul Nam is supported by a PhD fellowship for the Center for Data Science at NYU.
References
- Alkin et al. (2024) B. Alkin, A. Fürst, S. Schmid, L. Gruber, M. Holzleitner, and J. Brandstetter Universal physics transformers: a framework for efficiently scaling neural operators. In Advances in Neural Information Processing Systems (NeurIPS), Cited by: §3, §5.
- Bellman (1957) R. Bellman Dynamic programming. Princeton University Press, Princeton, NJ. Cited by: §1.
- Cole (1951) J. D. Cole On a quasi-linear parabolic equation occurring in aerodynamics. Quarterly of Applied Mathematics 9 (3), pp. 225–236. Cited by: §2.1.
- Dijkstra (1959) E. W. Dijkstra A note on two problems in connexion with graphs. Numerische Mathematik 1 (1), pp. 269–271. Cited by: §3, §5.
- E and Yu (2018) W. E and B. Yu The Deep Ritz method: a deep learning-based numerical algorithm for solving variational problems. Communications in Mathematics and Statistics 6 (1), pp. 1–12. External Links: Document Cited by: §5.Source
- Fleming and Soner (2006) W. H. Fleming and H. M. Soner Controlled markov processes and viscosity solutions. 2 edition, Stochastic Modelling and Applied Probability, Vol. 25, Springer, New York. Cited by: §1.
- Fleming (1977) W. H. Fleming Exit probabilities and optimal stochastic control. Applied Mathematics and Optimization 4 (1), pp. 329–346. Cited by: §2.1.
- Gilbarg and Trudinger (2001) D. Gilbarg and N. S. Trudinger Elliptic partial differential equations of second order. 2nd edition, Springer. Cited by: §C.1, §C.3.
- Han et al. (2018) J. Han, A. Jentzen, and W. E Solving high-dimensional partial differential equations using deep learning. Proceedings of the National Academy of Sciences 115 (34), pp. 8505–8510. Cited by: §1.
- Hart et al. (1968) P. E. Hart, N. J. Nilsson, and B. Raphael A formal basis for the heuristic determination of minimum cost paths. IEEE Transactions on Systems Science and Cybernetics 4 (2), pp. 100–107. Cited by: §1, §3, §5.
- Hopf (1950) E. Hopf The partial differential equation $u_{t}+uu_{x}=\mu u_{xx}$. Communications on Pure and Applied Mathematics 3 (3), pp. 201–230. External Links: Document Cited by: §2.1.Source
- Jambon et al. (2026) C. Jambon, M. S. Nabizadeh, and M. Konaković Luković Walk on decomposed subdomains: a hybrid monte carlo–deterministic solver for elliptic pdes. ACM Transactions on Graphics (TOG) 45 (4), pp. 132:1–132:22. Cited by: §1.
- Kappen (2005) H. J. Kappen Path integrals and symmetry breaking for optimal control theory. Journal of Statistical Mechanics: Theory and Experiment 2005 (11), pp. P11011. Cited by: §2.1, §6.
- Karaman and Frazzoli (2011) S. Karaman and E. Frazzoli Sampling-based algorithms for optimal motion planning. The International Journal of Robotics Research 30 (7), pp. 846–894. Cited by: §3.
- Kavraki et al. (1996) L. E. Kavraki, P. Svestka, J. Latombe, and M. H. Overmars Probabilistic roadmaps for path planning in high-dimensional configuration spaces. IEEE Transactions on Robotics and Automation 12 (4), pp. 566–580. Cited by: §1, §3.
- Kovachki et al. (2023) N. Kovachki, Z. Li, B. Liu, K. Azizzadenesheli, K. Bhattacharya, A. Stuart, and A. Anandkumar Neural operator: learning maps between function spaces with applications to pdes. Journal of Machine Learning Research 24 (89), pp. 1–97. Cited by: §1, §3.
- Latombe (1991) J. Latombe Robot motion planning. The Kluwer International Series in Engineering and Computer Science, Vol. 124, Kluwer Academic Publishers. Cited by: §1.
- LaValle and Kuffner (2001) S. M. LaValle and J. J. Kuffner Randomized kinodynamic planning. The International Journal of Robotics Research 20 (5), pp. 378–400. Cited by: §1, §3, §5.
- LaValle (2006) S. M. LaValle Planning algorithms. Cambridge University Press, Cambridge, UK. Cited by: §1.
- Li et al. (2023a) Z. Li, G. Yang, X. Deng, C. De Sa, B. Hariharan, and S. Marschner Neural caches for monte carlo partial differential equation solvers. In SIGGRAPH Asia 2023 Conference Papers, pp. 1–10. Cited by: §3.
- Li et al. (2021) Z. Li, N. Kovachki, K. Azizzadenesheli, B. Liu, K. Bhattacharya, A. Stuart, and A. Anandkumar Fourier neural operator for parametric partial differential equations. In International Conference on Learning Representations (ICLR), Cited by: §2.2, §3, §5.
- Li et al. (2023b) Z. Li, N. Kovachki, C. Choy, B. Li, J. Kossaifi, S. Otta, M. A. Nabian, M. Stadler, C. Hundt, K. Azizzadenesheli, and A. Anandkumar Geometry-informed neural operator for large-scale 3d pdes. In Advances in Neural Information Processing Systems (NeurIPS), Cited by: §3, §5.
- Li et al. (2024) Z. Li, H. Zheng, N. Kovachki, D. Jin, H. Chen, B. Liu, K. Azizzadenesheli, and A. Anandkumar Physics-informed neural operator for learning partial differential equations. ACM / IMS Journal of Data Science 1 (3), pp. 1–27. Cited by: §3, §5.
- Liu-Schiaffini et al. (2024) M. Liu-Schiaffini, J. Berner, B. Bonev, T. Kurth, K. Azizzadenesheli, and A. Anandkumar Neural operators with localized integral and differential kernels. In International Conference on Machine Learning (ICML), Cited by: §3, §5.
- Matada et al. (2025) S. Matada, L. Bhan, Y. Shi, and N. Atanasov Generalizable motion planning via operator learning. In International Conference on Learning Representations (ICLR), Cited by: §3.
- Muller (1956) M. E. Muller Some continuous monte carlo methods for the dirichlet problem. The Annals of Mathematical Statistics 27 (3), pp. 569–589. Cited by: §1, §1.
- Nam et al. (2024) H. C. Nam, J. Berner, and A. Anandkumar Solving poisson equations using neural walk-on-spheres. In Proceedings of the 41st International Conference on Machine Learning, Proceedings of Machine Learning Research, Vol. 235. Cited by: §3.
- Ni and Qureshi (2023) R. Ni and A. H. Qureshi NTFields: neural time fields for physics-informed robot motion planning. In International Conference on Learning Representations (ICLR), Cited by: §3.
- Nüsken and Richter (2021) N. Nüsken and L. Richter Interpolating between BSDEs and PINNs: deep learning for elliptic and parabolic boundary value problems. Note: arXiv preprint arXiv:2112.03749 Cited by: §3.
- Ocampo et al. (2023) J. Ocampo, M. A. Price, and J. D. McEwen Scalable and equivariant spherical cnns by discrete-continuous (disco) convolutions. In International Conference on Learning Representations (ICLR), Cited by: §3, §5.
- Rahman et al. (2023) M. A. Rahman, Z. E. Ross, and K. Azizzadenesheli U-no: u-shaped neural operators. Transactions on Machine Learning Research. Cited by: §3, §5.
- Ronneberger et al. (2015) O. Ronneberger, P. Fischer, and T. Brox U-net: convolutional networks for biomedical image segmentation. In Medical Image Computing and Computer-Assisted Intervention (MICCAI), pp. 234–241. Cited by: §3, §5.
- Sawhney and Crane (2020) R. Sawhney and K. Crane Monte carlo geometry processing: a grid-free approach to pde-based methods on volumetric domains. ACM Transactions on Graphics 39 (4). Cited by: §1, §3.
- Sawhney et al. (2023) R. Sawhney, B. Miller, I. Gkioulekas, and K. Crane Walk on stars: a grid-free monte carlo method for pdes with neumann boundary conditions. ACM Transactions on Graphics 42 (4). Cited by: §B.4, §B.4, §B.5, §C.4, item 1, §D.1, §1, §1, §4.2.
- Sethian (1996) J. A. Sethian A fast marching level set method for monotonically advancing fronts. Proceedings of the National Academy of Sciences 93 (4), pp. 1591–1595. Cited by: §3.
- Smith et al. (2021) J. D. Smith, K. Azizzadenesheli, and Z. E. Ross EikoNet: solving the eikonal equation with deep neural networks. IEEE Transactions on Geoscience and Remote Sensing 59 (12), pp. 10685–10696. Cited by: §3.
- Stulp and Sigaud (2012) F. Stulp and O. Sigaud Path integral policy improvement with covariance matrix adaptation. In International Conference on Machine Learning, Cited by: §D.1, §1, §3, §5.
- Sugimoto et al. (2023) R. Sugimoto, T. Chen, Y. Jiang, C. Batty, and T. Hachisuka A practical walk-on-boundary method for boundary value problems. ACM Transactions on Graphics 42 (4). Cited by: §3.
- Theodorou et al. (2010) E. Theodorou, J. Buchli, and S. Schaal A generalized path integral control approach to reinforcement learning. The Journal of Machine Learning Research 11, pp. 3137–3181. Cited by: §1, §2.1, §6.
- Thrun (2002) S. Thrun Probabilistic robotics. Communications of the ACM 45 (3), pp. 52–57. Cited by: §1.
- Todorov (2006) E. Todorov Linearly-solvable Markov decision problems. In Advances in Neural Information Processing Systems (NIPS), Vol. 19, pp. 1369–1376. Cited by: §2.1.
- Todorov (2009) E. Todorov Efficient computation of optimal actions. Proceedings of the National Academy of Sciences 106 (28), pp. 11478–11483. Cited by: §2.1.
- Viswanath et al. (2026) H. Viswanath, H. C. Nam, X. Deng, J. Berner, A. Anandkumar, and A. Bera Operator learning using weak supervision from walk-on-spheres. arXiv preprint arXiv:2603.01193. Cited by: §1.
- Williams et al. (2017a) G. Williams, A. Aldrich, and E. A. Theodorou Model predictive path integral control: from theory to parallel computation. Journal of Guidance, Control, and Dynamics 40 (2), pp. 344–357. Cited by: §D.1, §1, §3, §5.
- Williams et al. (2017b) G. Williams, N. Wagener, B. Goldfain, P. Drews, J. M. Rehg, B. Boots, and E. A. Theodorou Information theoretic MPC for model-based reinforcement learning. In IEEE International Conference on Robotics and Automation (ICRA), pp. 1714–1721. Cited by: §3.
- Wu et al. (2024) H. Wu, H. Luo, H. Wang, J. Wang, and M. Long Transolver: a fast transformer solver for pdes on general geometries. In International Conference on Machine Learning (ICML), Cited by: §3, §5.
- Zhang (2017) J. Zhang Backward stochastic differential equations. In Backward Stochastic Differential Equations: From Linear to Fully Nonlinear Theory, pp. 79–99. Cited by: §3.
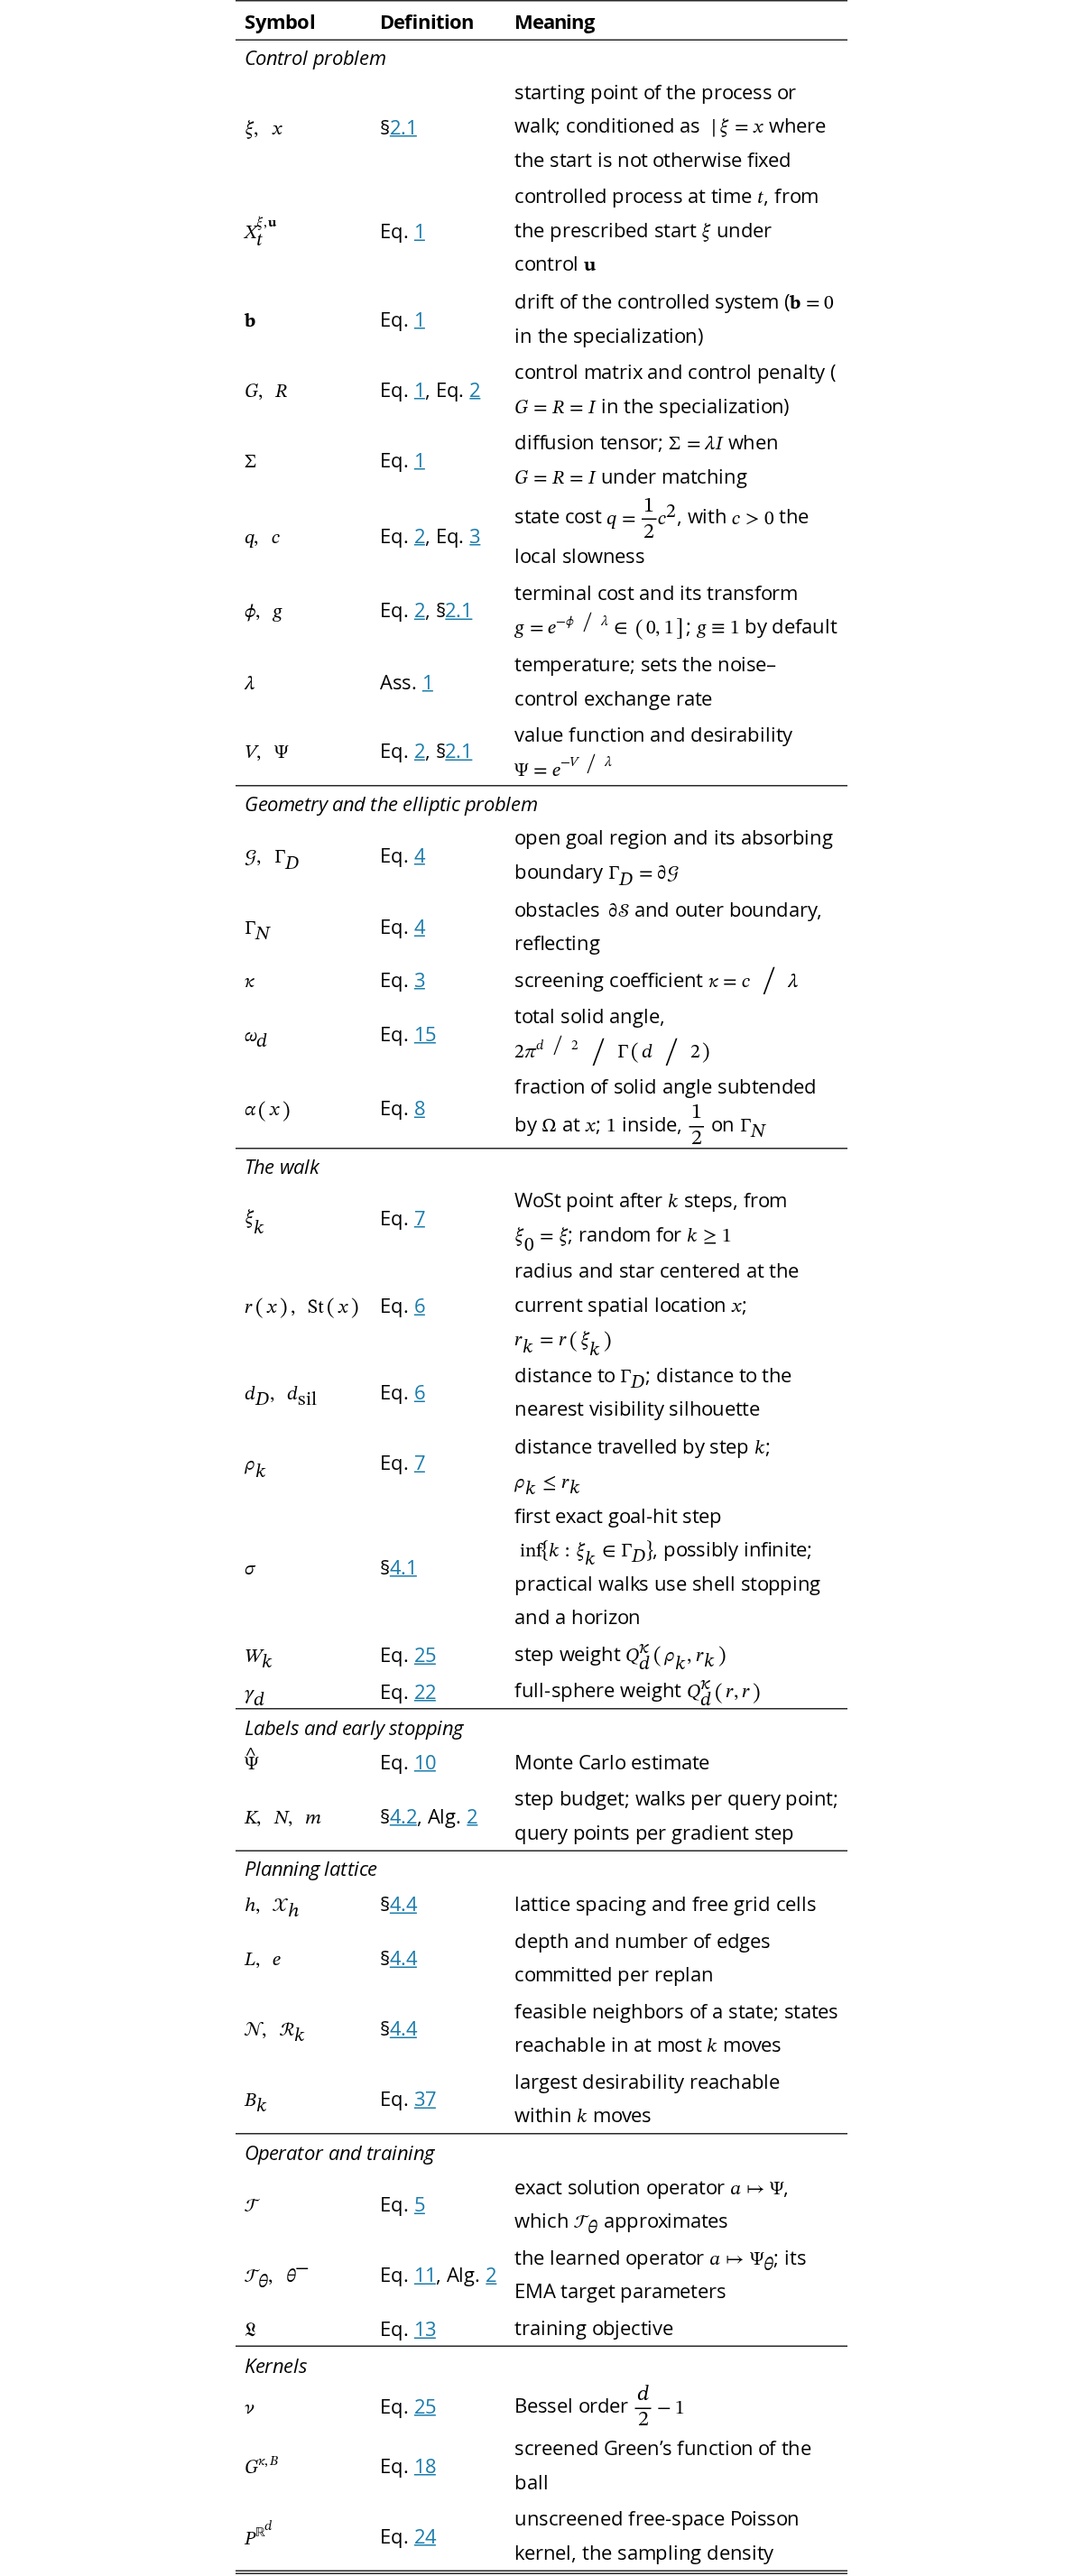
Table 6 collects the shared symbols used across the paper.
| Symbol | Definition | Meaning |
|---|---|---|
| Control problem | ||
| §2.1 | starting point of the process or walk; conditioned as where the start is not otherwise fixed | |
| Eq. 1 | controlled process at time , from the prescribed start under control | |
| Eq. 1 | drift of the controlled system ( in the specialization) | |
| Eq. 1, Eq. 2 | control matrix and control penalty ( in the specialization) | |
| Eq. 1 | diffusion tensor; when under matching | |
| Eq. 2, Eq. 3 | state cost , with the local slowness | |
| Eq. 2, §2.1 | terminal cost and its transform ; by default | |
| Ass. 1 | temperature; sets the noise–control exchange rate | |
| Eq. 2, §2.1 | value function and desirability | |
| Geometry and the elliptic problem | ||
| Eq. 4 | open goal region and its absorbing boundary | |
| Eq. 4 | obstacles and outer boundary, reflecting | |
| Eq. 3 | screening coefficient | |
| Eq. 15 | total solid angle, | |
| Eq. 8 | fraction of solid angle subtended by at ; inside, on | |
| The walk | ||
| Eq. 7 | WoSt point after steps, from ; random for | |
| Eq. 6 | radius and star centered at the current spatial location ; | |
| Eq. 6 | distance to ; distance to the nearest visibility silhouette | |
| Eq. 7 | distance travelled by step ; | |
| §4.1 | first exact goal-hit step , possibly infinite; practical walks use shell stopping and a horizon | |
| Eq. 25 | step weight | |
| Eq. 22 | full-sphere weight | |
| Labels and early stopping | ||
| Eq. 10 | Monte Carlo estimate | |
| §4.2, Alg. 2 | step budget; walks per query point; query points per gradient step | |
| Planning lattice | ||
| §4.4 | lattice spacing and free grid cells | |
| §4.4 | depth and number of edges committed per replan | |
| §4.4 | feasible neighbors of a state; states reachable in at most moves | |
| Eq. 37 | largest desirability reachable within moves | |
| Operator and training | ||
| Eq. 5 | exact solution operator , which approximates | |
| Eq. 11, Alg. 2 | the learned operator ; its EMA target parameters | |
| Eq. 13 | training objective | |
| Kernels | ||
| Eq. 25 | Bessel order | |
| Eq. 18 | screened Green’s function of the ball | |
| Eq. 24 | unscreened free-space Poisson kernel, the sampling density | |
View original table
This appendix derives the kernels used by the estimator of Section 4.1 in general dimension. Throughout, , , and
In Appendix B.1 the radial variable is the source separation ; from Appendix B.2 onward is the radius of the ball or star and denotes the source separation. We seek Green’s functions for the screened Laplacian
Away from the pole every case below solves the same radial ODE,
with regular at the origin and singular. Cases differ only in which combination the outer boundary condition selects; the overall constant is fixed once and for all by the flux jump at .
In free space the radial solution of Eq. 16 that decays at infinity is the branch, and the flux jump at the pole fixes its constant:
As a check, for () this gives , and for (), using gives the Yukawa potential .
The Neumann part of requires the normal derivative of Eq. 17. Using ,
which is strictly negative for all , so the kernel is monotonically decreasing in every dimension.
Let with the pole at the center, as in every walk step. The solution is radial and takes the form
with the same prefactor as Eq. 17, since the flux jump at the origin is unchanged by the boundary. Only depends on the boundary condition. Writing and using the scaled-derivative identities
the radial derivative of Eq. 18 is proportional to . The two cases we use follow:
Note the order shift in : since and likewise for , imposing on produces the order- ratio rather than the naive , for which the derivative vanishes only when .
The walk uses the Poisson kernel, for , which by radial symmetry is constant on the sphere. Its total mass has a closed form, and it is exactly the factor appearing in Eq. 22.
Let solve in with on . Then
where the full-sphere weight is
Consequently
Regularity at the origin selects the branch of Eq. 16, and the stated normalization gives . Taking with ,
The mass identity follows since with on the boundary, and Eq. 23 follows from constancy on the sphere. ∎
Proposition 1 is the case of the star-step weight Eq. 25, and Appendix C.5 shows the general weight reduces to it. It also gives the two asymptotic regimes. Expanding and using ,
so a short step is nearly weight-preserving with deficit , while a step much longer than the screening length is damped exponentially; hence steps beyond a few screening lengths contribute negligibly.
Appendix B.3 treated the Poisson kernel at the center of a ball, which corresponds to a full-length sphere step. A star step may instead terminate against at a distance , so we need the kernel at interior points of the ball.
Following Sawhney et al. (2023), the screened ball Green’s functions are
with , which agree with the general- expression Eq. 18 at . Both vanish at , which is the cancellation that removes the unknown-flux term on the spherical part of the boundary.
The corresponding Poisson kernels factor as a scalar times the free-space kernel,
with given for all by Eq. 25.
For every and ,
and .
The scaled-derivative identities Eq. 19 give
using for the power of . For , the denominator has with , hence , where . Dividing the preceding display by this and collecting the powers of and gives Eq. 25. Setting makes the bracket , and the Bessel identity reduces it to , leaving . For , use and directly; the same ratio follows. The sphere reduction follows from the standard Wronskian . We verified Eq. 25 against the tabulated forms and the reduction against at to fourteen digits. ∎
Specializing Eq. 25 to the two dimensions tabulated by Sawhney et al. (2023),
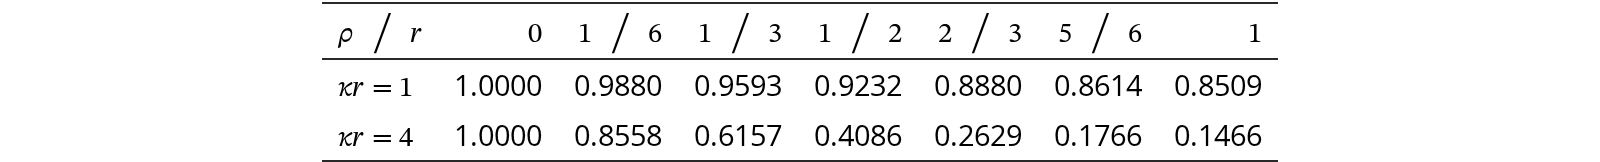
Table 7 gives representative values. Because of this factorization, the estimator is inexpensive: the geometric part is exactly the signed solid angle subtended by at , so sampling directions uniformly gives unit importance weights, and screening enters only through the scalar .
| 1.0000 | 0.9880 | 0.9593 | 0.9232 | 0.8880 | 0.8614 | 0.8509 | |
| 1.0000 | 0.8558 | 0.6157 | 0.4086 | 0.2629 | 0.1766 | 0.1466 |
View original table
The kernels of Appendices B.1–B.4 are constructed for free space and for a ball, yet Eq. 28 integrates them over , which is not a sphere. The following identity justifies this.
Let be a bounded Lipschitz domain with , let solve on , and let be any function with on a neighborhood of , so that is its only singularity in . Then with and the outward normal,
Green’s second identity on for the pair with the operator gives
the zeroth-order terms canceling identically between the two products. The second integrand on the left vanishes by hypothesis, and the first collapses to by the defining property of . Rearranging gives Eq. 28. ∎
The chain’s one-step identity is the case , the screened Dirichlet Green’s function of the ball , applied on an admissible star . Since vanishes on the spherical part of and on the reflecting part, the flux term drops and with . At a smooth boundary pole , the same steps on minus a half-ball of radius about , with , give the identity with replaced by , because the small hemisphere carries half of the singular flux; this is the factor in Eq. 8. The direction law is the solid-angle density with , and the weight is the flux ratio of Eq. 34, so , the one-step property of Section 4.1. Multiplying by the earlier weights gives the martingale property before ; the stopped sequence is constant afterwards.
The hypotheses require neither that be the Green’s function of nor that it satisfy any boundary condition on . All that is needed is a fundamental solution whose singularity inside is the single pole at . Since , the ball kernel has that property, and so do the free-space kernel and the ball kernel of any radius . Each of these kernels gives a valid representation of , so we must choose among them.
The choice is governed by the unknown flux in Eq. 28. On that flux is zero on but unknown on , which lies in the interior of where no boundary condition applies. A usable identity therefore needs a kernel that vanishes on while remaining finite on , and that is exactly the ball’s Dirichlet kernel: on , and it is finite and nonzero at the interior points constituting . The free-space kernel is admissible but unsuitable here: on , so the unknown flux term does not vanish.
The walk nonetheless samples directions by the free-space solid angle. For the Laplace operator the two Poisson kernels agree on all of , because the boundary corrector for a centered pole is the constant radial homogeneous solution and so has zero normal derivative; directional sampling then importance-samples the kernel exactly and the step weight is . Screening replaces that constant by the branch of Eq. 16, and the resulting -dependent corrector is precisely the second term of Eq. 25. This explains why depends on the star radius and not only on the hit distance : the -dependence comes from the free-space fundamental solution, and the -dependence comes from the ball corrector, whose normal derivative is nonzero only when .
Proposition 2 is exact, so the ball-on-star transfer contributes no error of its own. One further term is specific to the identity: for nonzero Neumann data the second integrand of Eq. 28 requires at interior points of , which is available in closed form but is estimated with a separate sample, since reusing the walk direction gives an estimator that is zero on flat boundaries and high-variance elsewhere (Sawhney et al., 2023). With that term drops entirely, which is the case throughout this paper.
| general |
|---|
View original table
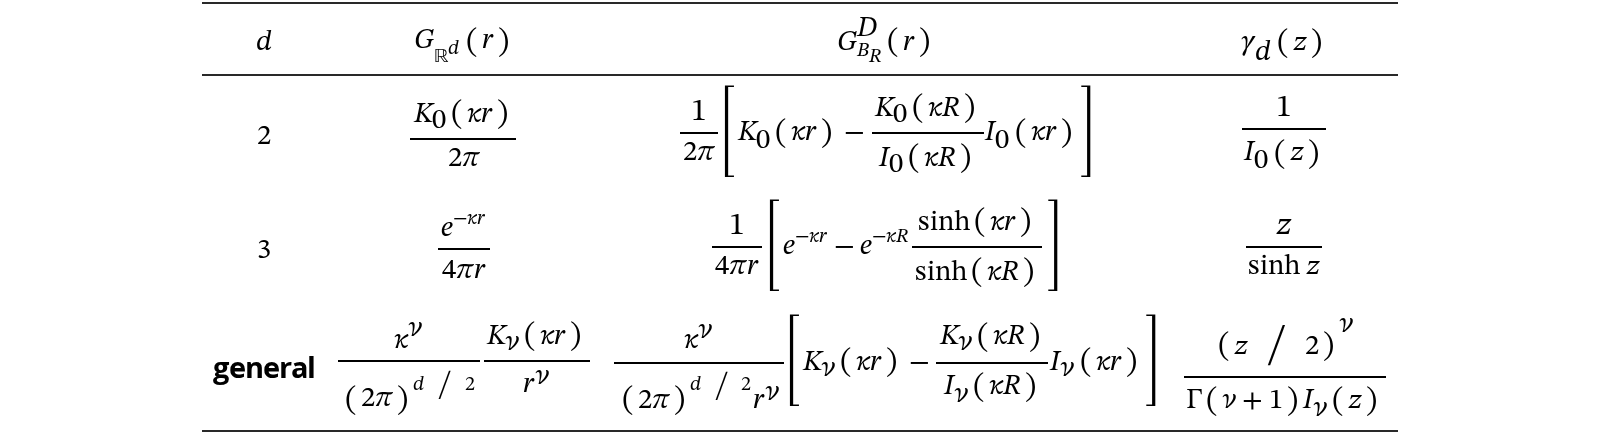
Table 8 collects the dimension-specific forms. For , gives the unscreened limit
which is in three dimensions. In two dimensions the free-space Green’s function diverges by an additive constant as ; subtracting that constant gives . In the Dirichlet ball kernel the constants cancel, giving . In all dimensions and , recovering the unscreened weights. A purely Neumann unscreened problem needs a separate compatibility and normalization condition.
The free domain is bounded and connected with boundary, for . Its Dirichlet and Neumann sets are disjoint unions of boundary components, each with positive surface measure. Hence they are separated by a positive distance. This excludes Dirichlet–Neumann junctions, near which the solution can have singular gradients. The goal data satisfies and . The cost satisfies and . The noise parameter is fixed for each problem.
Under Assumption 2, the mixed elliptic problem has a unique (Gilbarg and Trudinger, 2001). These regularity statements concern the ideal smooth domain. Voxel edges and corners are not covered by this assumption; the smooth-boundary factor and global gradient bounds do not automatically extend to them. The exact PDE identities for the chain additionally require constant screening and admissible stars; regularity does not guarantee that the radius-clamped sampler is exact. Write .
Where is it satisfies the interior stationary HJB equation
whose inner minimization is attained at . Substituting that minimizer leaves a quadratic nonlinearity in ,
and this term cancels under the desirability transform.
Let satisfy Eq. 29 and set . Then
In particular the right side vanishes for every with if and only if as quadratic forms, which is Assumption 1.
From we get and Substitute into Eq. 29 term by term. The diffusion term becomes
and the quadratic control term becomes
Adding the two quadratic contributions gives
which is Eq. 30 up to the stated factor. The remaining terms are and ; multiplying the whole equation by yields the stationary backward Kolmogorov equation
exactly when Eq. 31 vanishes.
For universal cancellation of the transformed differential expression, put . The symmetric quadratic form vanishes for every if and only if . Smooth positive test fields can have an arbitrary gradient at a point, so matching is necessary for this operator identity. For a particular solution , the residual can vanish even when matching fails. ∎
For the fully actuated reflected model under Assumption 2, let solve the mixed problem and set and . Assume admissible controls, including , give well-defined dynamics with finite expected goal-hitting time and control energy. Completing the HJB square and applying Itô’s formula up to , then taking , yields
The Neumann condition removes the reflection term; bounded and at the goal justify the stopped limit. Thus , with equality for , proving optimality.
Part (ii) below fixes the scale on which varies. For constant the screening length is , but additional length scales arise from the domain size, goal size, and obstacle geometry, so exponential decay with distance holds only asymptotically.
Under Assumption 2:
- (i)
on , with ;
- (ii)
for the fixed annulus , , constant , , and , the log range is as .
For (i), the maximum principle excludes an interior maximum above one or a nonpositive interior minimum. At a reflecting boundary, the Hopf boundary lemma (Gilbarg and Trudinger, 2001) excludes either extremum unless the solution is constant. A constant violating the bounds contradicts the positive Dirichlet data. Continuity and compactness then give a strictly positive minimum.
For (ii), put . The radial solution is
Integrating backward from shows for . Thus the range is . At fixed , the large-argument Bessel asymptotics give , which proves (ii). ∎
Reflection lets the process remain in the free domain and continue toward the goal after reaching an obstacle boundary. Its corresponding condition is , as in Eq. 4 and the reflecting walks of Sawhney et al. (2023). This choice also keeps , and so the control, finite up to the boundary under Assumption 2.
Suppose instead that obstacles are absorbing, with zero terminal desirability. Denote the resulting solution by , retaining positive goal data and reflection at the outer workspace boundary. Then
as approaches an obstacle from the free domain. Thus zero desirability represents an infinite collision penalty. The singularity is in the logarithmic representation and value function; the linear PDE solution can remain smooth.
The control also becomes singular at a smooth obstacle surface. With the smoothness and separation assumptions of Assumption 2, now replacing the obstacle condition by zero Dirichlet data, fix and write , where measures distance into the free domain. The Hopf boundary lemma gives . Taylor expansion and , for , yield
The leading control points away from the obstacle and grows as inverse distance. A bounded log-output model cannot approximate this target uniformly all the way to the obstacle surface. Clipping the desirability to a positive floor removes the divergence numerically but introduces a boundary approximation.
For the reflected problem, Proposition 3 gives on the closed free domain. Consequently and are bounded, , and under the stated regularity assumptions. The reflected dynamics enforce the boundary constraint; the Neumann condition does not impose a positive clearance from obstacles.
We therefore use reflection because it permits continued goal seeking with a bounded log target; other formulations need not use it. Strictly positive Dirichlet obstacle data with finite avoids this logarithmic singularity, but models termination at an obstacle with a finite penalty. The singularity claim applies specifically to zero Dirichlet data for , not to Dirichlet conditions in general.
Throughout, and denote the unscreened and screened Dirichlet Green’s functions of with pole at the center; both are radial in . By Lemma 1, the step weight is the flux ratio
Both Green’s functions are radial about the center, so the outward normal derivative at factors as and the geometric factor cancels in the ratio, which is why Eq. 34 is also the ratio of the two Poisson kernels in Eq. 24.
For , and the step weight is bounded on both sides,
with the full-sphere weight of Eq. 22. By the upper bound, the weighted chain of Section 4.1 remains bounded; the lower bound gives when the star radius is at most , which yields the replica bounds used in Appendix C.7.
Positivity is immediate from Eq. 25, since , and are all positive. For the upper bound, set , which is radial and vanishes at . Subtracting the two defining equations cancels the point sources and leaves in , so in flux form, the constant vanishing because the right side is locally integrable at the origin,
Dividing the first by the second gives the weight-deficit identity
The integrand is strictly positive on the interior of , so the right side is strictly positive for and . For the lower bound, and the integrand is nonnegative, so the deficit is at most ; integrating over gives by Proposition 1. Hence , with equality on the left at . This follows directly from ; monotonicity in also follows from the same identity but is not needed. ∎
Alternatively, can be fitted to log labels. There the weights are accumulated as plus the log of the terminal value, which avoids underflow for long products, but is a biased estimate of , since the logarithm of a sample mean is not the mean of logarithms. The correction below removes that bias to .
For i.i.d. replicas with fixed bounds and variance ,
The constants can depend on the replica bounds. For a fixed environment, such bounds follow from a finite horizon and a bounded target log field (Appendix C.7).
For , compute all ratios from shifted exponentials. Set , , , and . Then
Here is the sample variance of the shifted replicas . The random common shift makes those replicas dependent; unbiasedness is invoked only for the unshifted replicas below. Writing for the unbiased sample variance of the unshifted replicas , the ratio is unchanged by the common shift, , so Eq. 36 adds the bias correction . The correction removes the leading log bias, leaving under the stated assumptions.
Let be i.i.d. with , , mean , and variance . For , write and let be the unbiased sample variance. Then
The constants depend on the replica bounds.
Set . Taylor’s theorem through degree three gives with because . Independence gives , , , and , proving the first expansion.
For the correction, expand , where . Since is bounded, . Also and , with the third central moment of . Hence , which proves the corrected expansion. Jensen’s inequality gives the nonpositive bias of the uncorrected logarithm for every . ∎
For a fixed environment, horizon , and target bounded by , let be a lower bound on the step weight, which exists by Eq. 35 when the star radius is bounded. The walk replicas then lie in with and . The target bounds hold because the log field is continuous on the compact domain. They are not assumed uniform over all trained parameters or environments. The shifted calculation in Eq. 36 preserves the variance ratio exactly in real arithmetic and avoids underflow from a common small scale.
Recall the lattice of Section 4.4, with vertices and edges between axis-adjacent free cells. We take this graph to be finite and finite at every vertex.
The largest desirability reachable in moves is computed by
Indeed, and
so induction gives . Equation 14 therefore compares at candidate neighbors. Moving to that neighbor uses the first of the moves.
In each propagation layer, the previous score is kept unless a neighbor has a strictly higher score, in which case the corresponding edge is stored. Starting at horizon , follow the stored edges while decreasing the remaining horizon. A layer with no edge is skipped because its maximum was already reachable at a shorter horizon. Induction on the remaining horizon gives a feasible route of at most edges ending at a cell with score . Executing a prefix preserves graph feasibility, although the next replan may select a different endpoint. Continuous-motion feasibility additionally requires valid edges; collision-free sampled endpoints are insufficient. The implemented lattice uses cells marked free in the saved occupancy mask, connected through face-adjacent free cells. Continuous segments from off-center states are checked across all traversed voxels. All edges are checked for collisions. For , Eq. 14 instead selects a neighbor anew from the fixed map at each visited state.
The reachable sets are nested, hence . On a connected component of graph diameter , every gives for all . Once , the candidate scores in Eq. 14 coincide and direction depends on tie-breaking. For a reconstructed route, maximizing the terminal score likewise does not distinguish the lengths of paths to the same endpoint. Thus increasing depth enlarges the set of candidate endpoints, but does not guarantee a shortest path or a successful rollout.
The pretrained 2D application benchmark contains 592 maps (37,888 starts); the 2D generated and 4D manipulator test sets each contain 512 maps (32,768 starts). Every map uses eight goals and every goal uses eight starts, chosen at the centers of eight equal goal-distance quantile bins. Success is evaluated on the matched saved queries, including failed rollouts in the denominator. Field prediction or solve, controller preprocessing, and rollout/search all contribute to reported test-time cost. These costs are amortized over the corresponding starts; they include more than the neural forward time. FEM solutions provide the numerical ground-truth fields for reconstruction-error evaluation.
Table 5 compares nominal planners, sampling-based controllers, and PUN at execution-noise levels . Before boundary handling, the proposed transition is , with independent , , and , where is the largest grid dimension. Each control interval contains eight microsteps. Coordinates occupy a unit square in 2D, a domain in 3D, and normalized joint coordinates in 4D. The noise-increment covariance is , consistent with the PDE specialization . In these replanning evaluations, all compared methods use the same execution and collision-checking rules. Collision checks cover the entire executed motion segment, and an obstacle hit is counted as a rollout failure. Thus, success requires reaching the goal without an obstacle hit or an outer-domain boundary violation. The reflected PDE provides the planning field, whose effectiveness is evaluated here under collision-failure execution. Joint limits are not modeled in these experiments. Moves outside the outer workspace or configuration-domain boundary are also counted as rollout failures. For each environment–goal query at a given noise level, PUN predicts the entire field in a single forward pass and reuses it throughout the rollout. The reported replanning comparisons use positive noise levels, consistent with the scope of the screened-Poisson derivation. Success requires entry into the saved goal-cell mask before failure. Methods replan from the current noisy state every eight microsteps. Execution also stops on a collision failure, an unavailable route, or the controller’s stopping condition.
The MPPI and PI-CMA implementations share a horizon of steps, sampled trajectories per optimization iteration, and one iteration per planning call. Both use double precision, componentwise action bounds , initial exploration standard deviation , and optimization temperature . This temperature is distinct from the execution-noise parameter . A fresh call initializes every action to , where is the goal center. Thus each call evaluates sampled transitions, followed by a rollout of the selected nominal sequence. The wrapper supports resuming interrupted optimization from saved parameters and random-generator state; ordinary calls initialize a new optimizer rather than carrying its solution between replans. The configuration uses , where is the iteration count. These factors describe nominal sampled work . No validation-based parameter sweep was performed. We use standard values for temperature, exploration scale, action bounds, the objective weights.
A⋆ and Dijkstra use standard C++ implementations with face-neighbor connectivity and unit edge costs. Grids are the native 2D maps, in 3D, and in 4D. A⋆ uses Manhattan distance to the goal-mask bounding box; Dijkstra uses zero heuristic. CPU RRT uses OMPL 2.0.1, goal bias 0.05, uniform domain sampling, and maximum extension 0.4 in normalized coordinates. Search stops on a goal solution; there is no fixed sample or tree-size cap.
Both sampling-based optimizers use the following task cost, with stage costs evaluated after each predicted transition:
Here flags a proposed segment rejected by the geometry-validity routine when its starting state is not already in the goal. Before calling the geometry step routine, the wrapper replaces rejected actions and actions starting in the goal with zero displacement. This is a penalized planning surrogate; executed collisions are failures under the evaluation protocol above. Goal absorption is delegated to the geometry step routine. After optimization, the wrapper returns the predicted state path, truncated at its first recorded goal state. Execution noise is applied outside the optimization wrapper; its action-exploration distribution should not be identified with the execution-noise distribution. Geometry routines traverse all crossed voxels, including incident cells at edge/corner crossings, to detect goal entry, obstacle contact, and domain exit. Collision takes precedence over simultaneous goal entry in first-contact scoring. Actions are displacements in the normalized coordinates specified above. Predicted trajectories use deterministic geometry; the outer rollout adds execution noise. Returned paths are subdivided into bounded microsteps.
We use the MPPI class from pytorch_mppi (Williams et al., 2017a), with , , the task costs above, and the stated action bounds. The one call to command refines the nominal sequence at the same state with shift_nominal_trajectory=False. We retain the library’s MPPI update and control-perturbation cost in addition to the supplied task cost, and generate the returned path from the final nominal action sequence. The implementation uses the original MPPI update and control-perturbation cost.
Our adaptation of PI-CMA (Stulp and Sigaud, 2012) represents the action sequence by 16 uniformly spaced knots per coordinate, linearly interpolated to the 32-step horizon with aligned endpoints and clipped to the action bounds. A single parameter vector is sampled for each trajectory from , with initial covariance . For sampled parameters , let be the remaining task cost from step , including the terminal cost once. We compute
then update and , centering the covariance at the old mean. This implements temporal averaging of the per-step updates for exploration that is constant over a trajectory. The implementation symmetrizes the covariance and samples using an eigendecomposition, checking negative eigenvalues against a numerical tolerance before clipping them to zero; it imposes no positive exploration floor. We use a fixed temperature on unnormalized costs, rather than the cost-range normalization used in the original paper’s experiments. The custom wrapper implements knot-based PI-CMA, without CMA-ES evolution paths, rank-based selection, or step-size adaptation.
Both CPU and CUDA implementations were evaluated; the CPU version was faster in the implementation comparison. The optimizer’s wall-clock timer includes initialization, the one optimization iteration, logging, the final nominal rollout, and conversion of the returned path to host memory. The CUDA implementation also synchronizes after each iteration and before returning. These are per-call measurements; the tables report per-start costs and require the outer execution loop’s accounting across planning calls. Table 5 uses CPU baseline timings in 2D/3D/4D since they are faster than GPU, and GPU PUN timings throughout. Hardware is an Intel Xeon Platinum 8480+ or an NVIDIA B200. CPU software is Python 3.11.11, PyTorch 2.7.1+cpu, and NumPy 1.26.4; GPU software is Python 3.9.21, PyTorch 2.7.1+cu128, and NumPy 2.0.2.
Timing excludes loading and warmup and uses three observations per selected pair, method, and noise level for the benchmark sets. Variability is minimal. Per-start measurements include initialization, all replanning calls, geometry, and execution, including failed rollouts; the number of calls depends on the realized trajectory. GPU work is synchronized at timing boundaries.
PUN timings include fresh field prediction and preparation for each start, with the field reused during replanning.
Table 5 uses 500 maps in 2D, 250 in 3D, and 480 in 4D, with three goals per map and one start per goal. Each query uses one seeded execution-noise combination at each noise level; methods share the saved queries and Gaussian noise sequence. Rollouts receive equal weight, which also gives maps equal weight because each contributes three queries. One trained model per dimension is evaluated. We compute 95% intervals using 50,000 paired map-level bootstrap resamples, retaining all queries within each sampled map. Nondegenerate intervals are the estimate bootstrap standard errors. Runtime intervals use separate samples of maps, respectively.
| Dim. | Method | ||||
|---|---|---|---|---|---|
| 2D | A* | [55.92, 62.08] | [39.16, 45.50] | [31.90, 38.10] | [20.89, 26.45] |
| Dijkstra | [55.81, 62.19] | [39.15, 45.51] | [31.99, 38.01] | [21.08, 26.26] | |
| RRT | [79.37, 84.63] | [65.68, 71.66] | [49.14, 55.52] | [33.46, 39.88] | |
| MPPI | [81.70, 86.30] | [57.77, 64.23] | [42.45, 48.89] | [28.82, 34.52] | |
| PI-CMA | [75.76, 80.90] | [56.81, 63.19] | [44.76, 51.24] | [31.95, 38.05] | |
| PUN (zero-shot) | [89.90, 93.44] | [71.27, 76.73] | [59.15, 65.51] | [42.55, 48.79] | |
| 3D | A* | [32.37, 40.97] | [19.38, 27.28] | [9.10, 14.90] | [4.04, 7.96] |
| Dijkstra | [33.00, 41.66] | [18.98, 26.36] | [9.05, 14.95] | [3.73, 8.27] | |
| RRT | [48.85, 57.81] | [30.86, 39.80] | [21.28, 29.38] | [8.69, 15.31] | |
| MPPI | [58.44, 66.90] | [30.43, 38.91] | [14.98, 22.36] | [4.93, 9.73] | |
| PI-CMA | [42.92, 51.74] | [18.36, 25.64] | [17.51, 25.15] | [6.07, 11.27] | |
| PUN (zero-shot) | [89.60, 94.40] | [64.44, 72.90] | [35.62, 44.38] | [12.71, 19.29] | |
| 4D | A* | [100.00, 100.00] | [95.39, 97.95] | [69.54, 75.46] | [55.94, 62.40] |
| Dijkstra | [100.00, 100.00] | [95.68, 97.66] | [69.66, 75.34] | [56.06, 62.28] | |
| RRT | [97.53, 99.13] | [94.65, 97.01] | [87.97, 92.03] | [83.82, 87.84] | |
| MPPI | [93.68, 96.32] | [90.59, 94.41] | [79.15, 84.19] | [68.91, 74.43] | |
| PI-CMA | [95.43, 97.91] | [90.70, 94.30] | [84.40, 88.94] | [75.77, 80.89] | |
| PUN | [100.00, 100.00] | [100.00, 100.00] | [100.00, 100.00] | [93.49, 96.51] |
View original table
| Dim. | Method | ||||
|---|---|---|---|---|---|
| 2D | A* | [24.99, 62.27] | [26.25, 67.93] | [28.10, 74.26] | [29.44, 78.08] |
| Dijkstra | [79.37, 230.51] | [88.65, 261.25] | [102.34, 304.48] | [123.40, 356.54] | |
| RRT | [69.41, 127.49] | [72.10, 135.64] | [78.18, 146.36] | [82.46, 166.96] | |
| MPPI | [1227.92, 2240.30] | [1257.88, 2288.74] | [1279.80, 2397.66] | [1400.54, 2851.70] | |
| PI-CMA | [964.06, 1697.46] | [1053.67, 1916.15] | [1067.48, 1981.92] | [1079.98, 2133.66] | |
| PUN (zero-shot) | [7.79, 11.31] | [8.80, 13.48] | [10.71, 17.43] | [10.19, 18.83] | |
| 3D | A* | [50.74, 96.06] | [34.34, 86.60] | [42.19, 105.51] | [40.32, 90.18] |
| Dijkstra | [50.08, 96.84] | [35.29, 90.79] | [43.41, 110.57] | [41.51, 93.95] | |
| RRT | [155.27, 321.35] | [93.18, 246.62] | [76.54, 169.16] | [94.56, 157.90] | |
| MPPI | [382.10, 682.52] | [408.91, 746.77] | [433.13, 675.09] | [526.69, 881.93] | |
| PI-CMA | [332.42, 572.08] | [305.61, 564.41] | [371.44, 580.52] | [482.06, 731.04] | |
| PUN (zero-shot) | [14.95, 16.33] | [14.61, 16.07] | [13.26, 15.34] | [13.69, 15.17] | |
| 4D | A* | [12.32, 21.30] | [12.25, 21.91] | [35.26, 120.78] | [28.18, 96.70] |
| Dijkstra | [12.51, 21.83] | [12.37, 22.31] | [31.21, 102.29] | [27.73, 91.05] | |
| RRT | [16.26, 32.14] | [16.20, 35.40] | [23.09, 62.91] | [28.09, 48.53] | |
| MPPI | [332.13, 490.35] | [329.20, 467.16] | [297.34, 431.10] | [300.44, 449.22] | |
| PI-CMA | [300.61, 458.97] | [291.21, 424.17] | [284.19, 426.69] | [288.82, 424.62] | |
| PUN | [10.50, 10.76] | [10.32, 10.70] | [10.37, 10.73] | [11.43, 11.89] |
View original table
The experiments use the following estimator and numerical choices.
- 1.
Absorption and radius floor. A walk reaches only in the limit, so absorption is triggered on the shell and the terminal value is at the nearest point of ; is chosen below the tubular-neighborhood radius of and its distance to . The star radius also carries a floor, , so that steps do not become arbitrarily short near a silhouette. The shell costs at most (Eq. 38); the floor can break star-shapedness, and the error it introduces has unknown sign (Sawhney et al., 2023).
- 2.
Weighted survival. The solid-angle sampling law in Eq. 8 leaves the scalar screening factor as the per-step weight. We multiply these factors rather than sample killing events or apply Russian roulette. Conditioning out the killing randomness removes that source of variance and avoids zero replicas caused by stochastic killing.
- 3.
Fixed-horizon continuation. Walks stop at the prescribed step cap or the goal. Capped paths contribute their accumulated weight times the detached EMA prediction at the endpoint, as in Section 4.2. Goal-reaching paths use the known boundary value. Every requested trajectory remains in the sample mean, including capped paths.
- 4.
Log accumulation and bias correction. The trace records the sum of log step weights independently of their floating-point product, so product underflow does not erase the log evidence. The log-label variants use log-sum-exp and the sample-variance correction in Eq. 36. The direct-label variants use the weighted arithmetic mean without this correction. Direct and log targets are constructed from the same sampled paths.
- 5.
Reuse of model-independent walks. Cached endpoints, weights, and completion states are independent of the neural parameters. The EMA continuation is reevaluated during training rather than frozen into the cache.
- 6.
Stable screening kernels. The voxel backend for dimensions three through seven evaluates the full-sphere factor using the positive series
The CUDA implementation sums in double precision and uses a logarithmic large-argument asymptotic branch. For interior reflecting hits, it evaluates Eq. 25 with and , combining nonnegative terms with an exponential factor no greater than one. With , , and , the near-sphere branch uses
This reproduces the sphere endpoint without two separately rounded Bessel evaluations. The CUDA branches use this expansion for and the limiting value one for or .
- 7.
Voxel boundary queries. The same backend uses bounding-volume hierarchies for goal faces and view-dependent reflecting silhouettes, and voxel traversal for first boundary hits. This avoids triangulating the voxel boundary. Grid-plane and corner handling preserves the appropriate incident free cell and resolves boundary hits before accepting a sphere endpoint. These geometric operations implement the first-hit chain in Eq. 7.
Let and for finite . Assume admissible active steps, the smooth-domain regularity assumptions, and an below the goal’s tubular-neighborhood radius and its separation from reflecting boundaries. Define as the expected product of weights through times if , or the true continuation otherwise. Then
To prove this, bounded stopping gives . Only the shell event changes the terminal value. Since , the projection segment lies in the closed free domain, and its length is below , the terminal difference is bounded by . The product of weights is at most one. This proves the bound without an infinite-walk termination assumption. If almost surely for each start, bounded convergence also yields the same bound for the uncapped shell estimator. Replacing true continuation by a fixed bounded target adds its discounted endpoint error on , as described in Section 4.2. The radius floor is not covered: a clamped step can violate admissibility and introduce an error of unknown sign (Sawhney et al., 2023).
Antithetic directions, first-step gradient control variates, weight-floor stopping, expected-clock stopping, and randomized horizons are disabled in the reported pretrained models. In particular, the full-sphere gradient control variate is not transferred to arbitrary WoSt stars.
FNO uses 200 epochs. Each alternative backbone has a maximum of 200 epochs and a registered training-compute allowance of 66,856.484 seconds; an epoch is not started if it is not expected to fit within the remaining allowance. Each completed epoch uses 64 training maps and eight goals per map. The 200-epoch cosine schedule is retained when a run stops at the compute cap. The allowance was derived from 1.5 times an estimated individual FNO training cost; shared work in the reference run means it is not an exact equal-GPU-time comparison. Completed training epochs were 200 for FNO, 200 for U-NO, 185 for U-Net, 13 for GINO, 200 for LocalNO, 200 for DISCO, 146 for UPT, and 134 for Transolver. Our overall method is architecture-agnostic; we chose FNO because it gives the highest planning success among the tested implementations under this compute policy, but our overall method is compatible with other neural-operator architectures. Planning benefits from balancing sensitivity to local obstacle geometry with a global view of the environment.
The primary WoSt rows fit direct desirability with value, goal, and gradient loss terms. The loss ablations use 200 epochs and remove one term at a time. All predictions are evaluated through the stated controller; a small field error does not guarantee path success.
Unless a depth is stated, Local search denotes Local search (10). The finite-lattice controllers use legal axis-adjacent moves, with cycle detection and a step cap. Greedy uses and requires strict improvement. Local search (4) uses in 2D, 3D, and 4D. Local search (10) uses with route reconstruction in 2D, and in 3D and 4D. In the single-move variants, four or ten propagation steps are counted after the candidate first move, explaining the extra edge in . Direct models use their raw finite desirability predictions, without clipping or enforcing a goal score during search. For the convention in Appendix C.6, the maximizing search score is . If a model instead predicts or , its output must be negated to preserve this ranking (for in the latter case). The implemented log-label model predicts , reconstructs desirability as , and uses as its search score. Maximizing gives the same ranking as maximizing , consistent with this convention. Success requires entering the saved goal mask. Ties in the single-move rule favor the candidate’s own field score, then fewer previous visits, then a fixed lexicographic coordinate order (ascending in 2D, descending in 3D/4D). Route reconstruction retains an existing choice on equal scores, using a fixed axis traversal order for competing improvements. The 2D ten-step controller stops when the best endpoint does not improve the current score by more than . Missing legal moves, a fifth visit to a cell under local search, or exhaustion of the rollout budget are recorded as failures. The local diagrams below use one stored field to display these rules, with no new benchmark outcomes inferred from the illustration.
Details of the walk-horizon study and qualitative resolution-transfer examples are provided below.
The controlled horizon study in Table 4 uses 16 training maps, eight goals per map, four trajectories per query, and 40 epochs, with evaluation on the generated 2D test set. With the intermediate 100- and 400-step settings, gradient / local-search (10) success is 40.55% / 66.80% and 38.06% / 69.69%, respectively. Local-search success is highest at 400 steps (69.69%) and 0.03 percentage points lower at 800 steps, whereas gradient success is highest at 100 steps. A separate study of budget allocation without pretraining is reported in Appendix F.1.
| Test set | Gradient | Local search (10) |
|---|---|---|
| 3D application benchmarks | 65.95 | 89.46 |
| 4D manipulators | 97.50 | 99.48 |
View original table
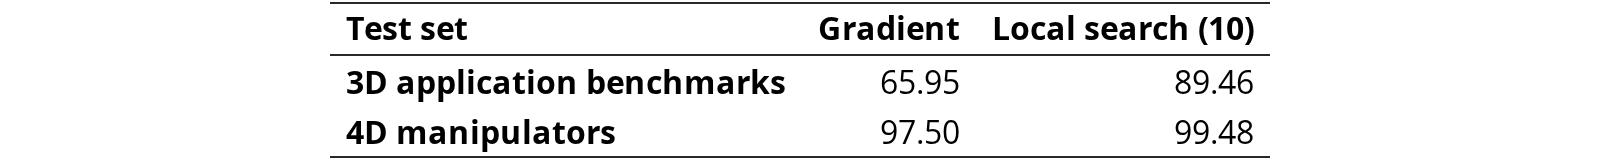
| Method | 2D zero-shot | 4D manipulators |
|---|---|---|
| WoSt + FNO | 1.20 | 2.79 |
| Direct WoSt | 1128.60 | 160.59 |
View original table
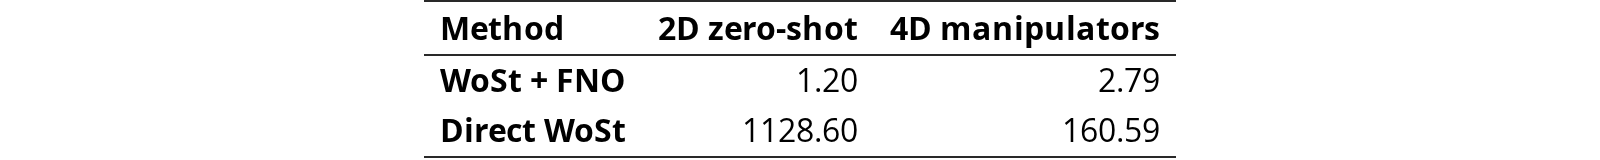
Figure 4 shows FNO predictions on held-out maps at , , and . Each field supports paths from multiple starts to one goal. These examples illustrate field reuse at different discretizations; the aggregate comparison across architectures and larger grids is Fig. 1(b).
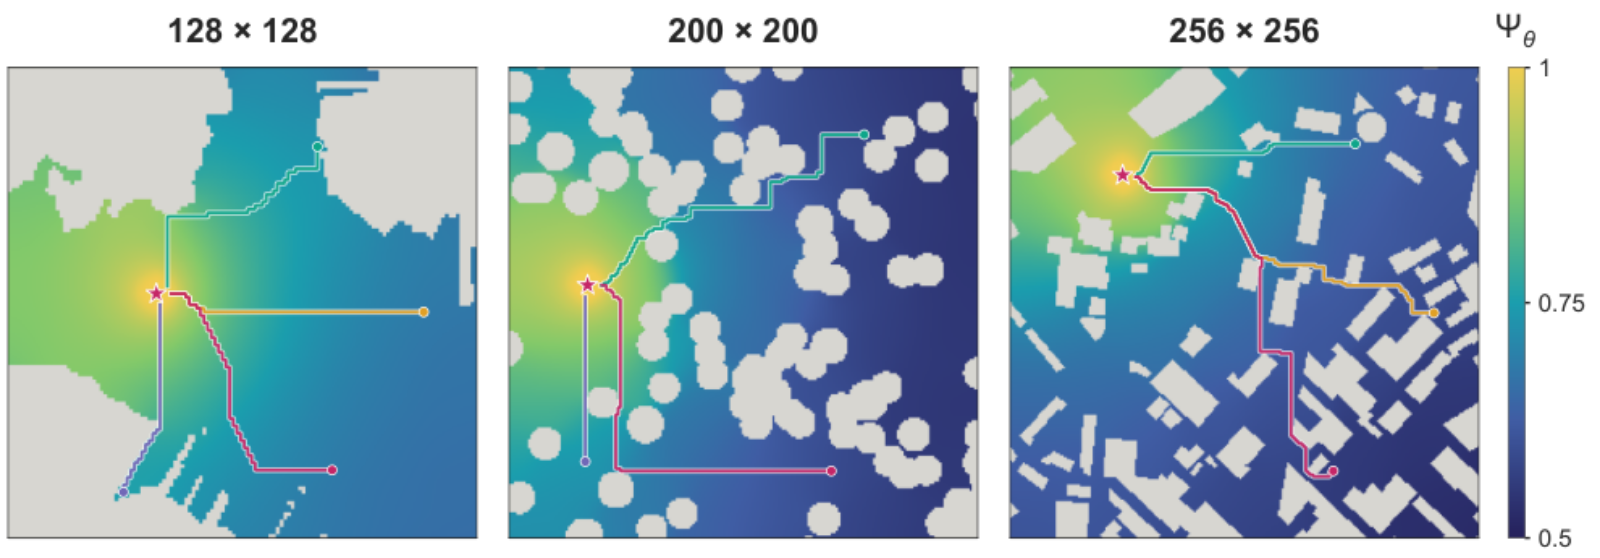
AI4Arctic Sea Ice (Arctic sea-ice maps from satellite observations); Fields2Benchmark (agricultural field geometries); HiRISE DTM (terrain models of the surface of Mars); HydroLAKES ASV (lake-shoreline geometries for autonomous surface vessels); LOLA LDEM (lunar elevation maps from laser altimetry); MovingAI BG512 (Baldur’s Gate maps); MovingAI Street (urban street-map grids); NOAA ENC Harbor (harbor geometries from navigational charts); Open Forest Observatory (forest structure maps from drone imagery); PNO2D (synthetic obstacle environments); TartanDrive 2 (terrain from off-road driving data).
Dryad SIC Foam (porous foam geometries); Falkor MAR AUV (Mid-Atlantic Ridge seafloor for autonomous underwater vehicles); Flybo UAV (scenes for aerial-robot navigation); HVaCT Liver Tip (liver and vessel anatomy for navigation); Industrial Pipe Routing (industrial layouts for pipe routing); Lung Needle (lung anatomy for needle-path planning); MOSAiC Under-Ice AUV (Arctic under-ice geometry for autonomous underwater vehicles); PNO3D iGibson/HouseExpo (indoor scene and floor-plan geometries); ReplicaCAD Indoor UAV (indoor CAD scenes for aerial navigation); Trabecular Bone (porous internal bone structure); Underwater AT40-02 MAR (seafloor surveyed for the Mid-Atlantic Ridge); Axial North Rift (seafloor terrain at Axial Seamount’s north rift); Escanaba (seafloor terrain in Escanaba Trough); Loihi Pele’s Pit (a submarine volcanic crater); Squid5 EDR (Eastern Dry Rocks coral reef topography from underwater imagery); USGS Tahoe (Lake Tahoe lakebed topography).
eCobra600 (Omron industrial robot arm); Kinova MICO (robot arm); OpenManipulator (ROBOTIS open-source robot arm); qArm (Quanser robot arm). Each 4D state represents a manipulator configuration in joint coordinates.
Shifting from 64 walks per query and 8 goals per map to 4 walks and 128 goals reduces 2D test success from 62.6% to 51.5% for DISCO and from 61.6% to 56.3% for FNO. In 3D, the same shift raises FNO success from 25.0% to 28.8%; Transolver success changes from 6.3% to 7.0%, while label-generation cost rises from 244.35 to 621.46 GPU hours. Equal nominal label budgets therefore need not imply equal computation or a common preferred allocation.
The following examples illustrate the geometry-to-field mapping, stochastic labels, and path extraction. The sampling budget for each field and walk figure is indicated in its panel.
Figure 5 illustrates the reuse of a goal-conditioned field across multiple initial states: the field represents a map and goal, while path extraction starts from each selected location.
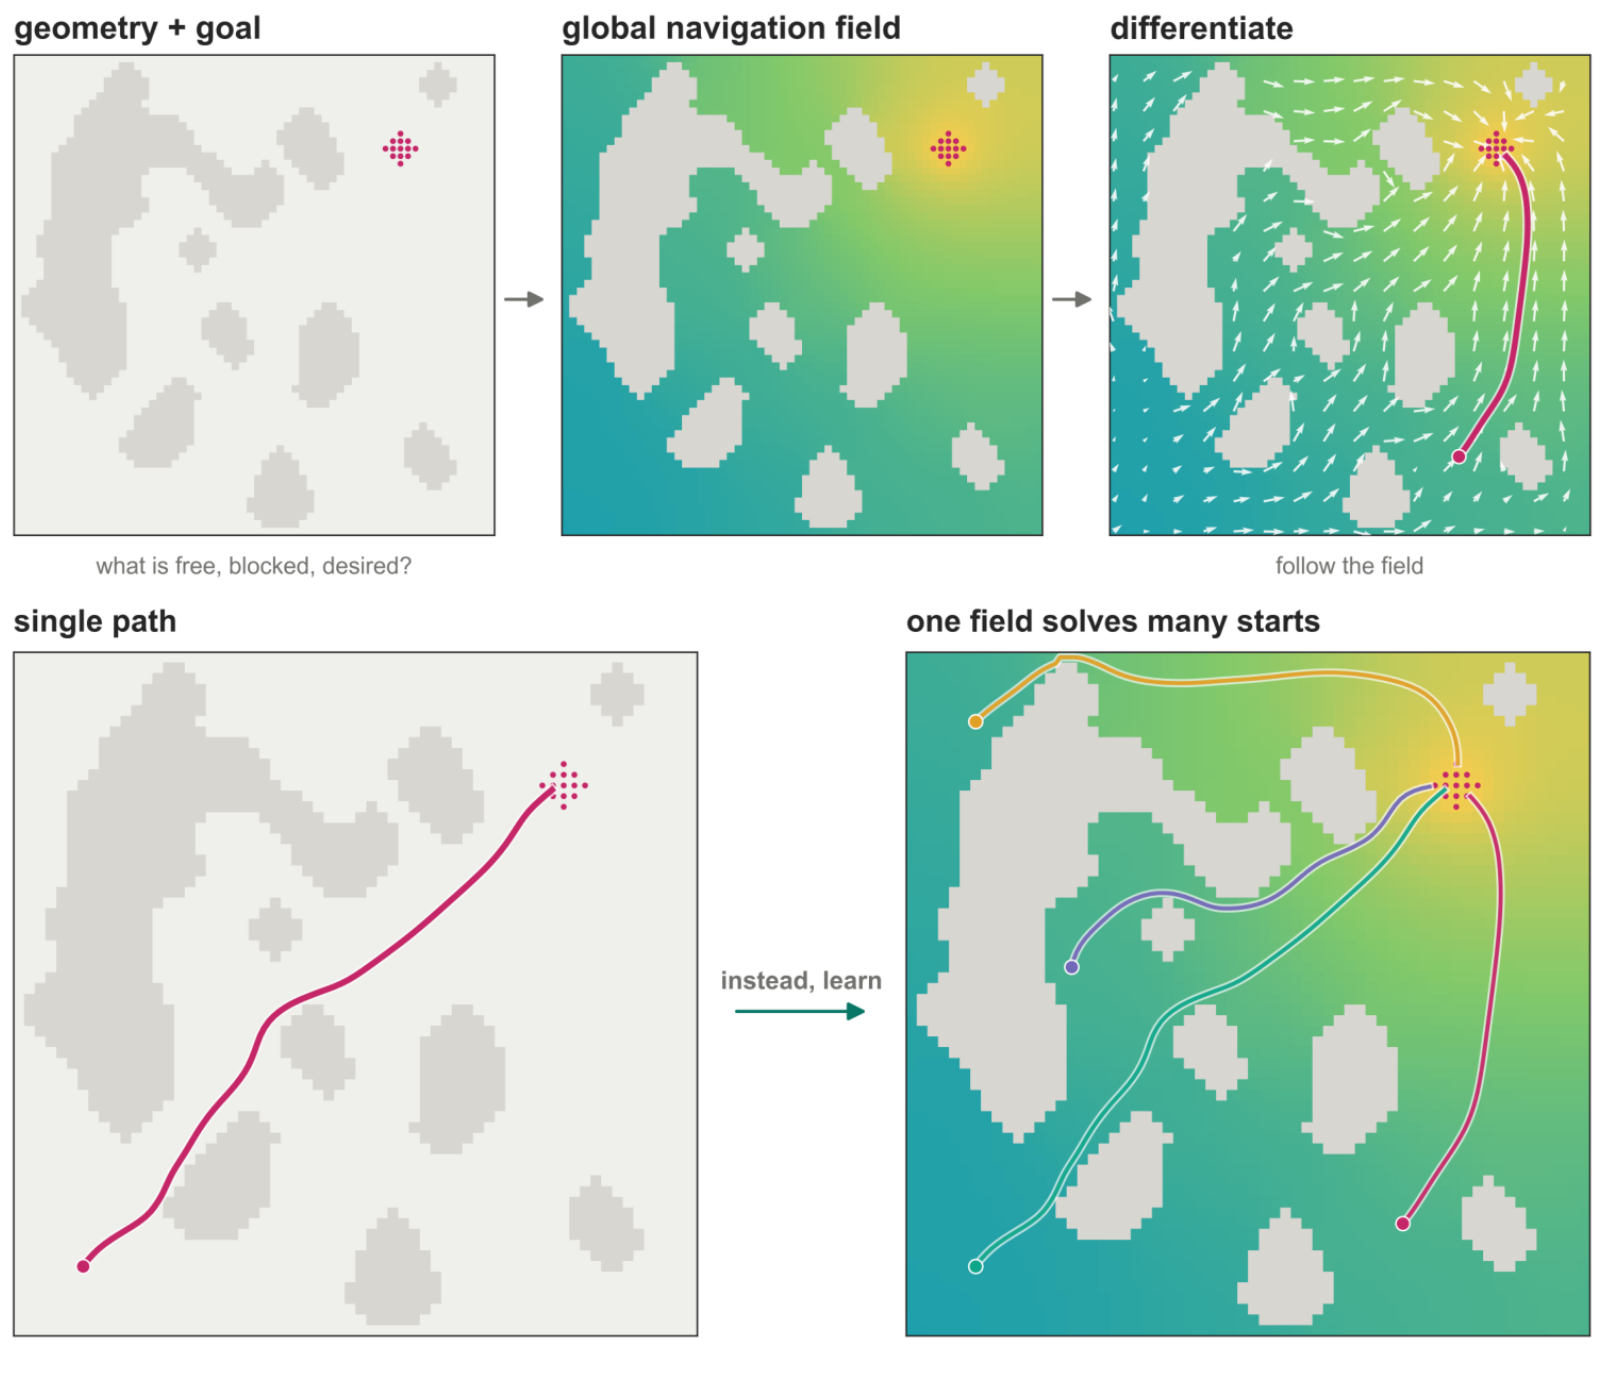
Figure 6 brings together walk geometry, label variability, and spatial sampling cost.