PhysiCalWorld: In-Context Physics Calibration for World Models
arXiv:2610.30125v1 · This workspace stays on this version. Check arXiv for newer versions
Some source details need review 2 to check
Original formulas, table values and figures are preserved. Comparison can miss differences; use the original PDF to check details.
Reading view checked: 350 math expressions, 1 rendering failures; 37 of 37 images available.
Compared 139 of 151 source passages against 30 of 36 PDF pages.
- Some formulas could not be rendered; their original TeX is shown. Check the original PDF. (1)
- This long paper was only partially compared; the original sources remain available.
37 of 37 figure, table and graphic images captured. Open original PDF
Abstract
Existing world models typically perceive a scene through current visual frame or a narrow history window. However, these observations may not reveal the physics properties that determine transition dynamics, such as an object’s mass distribution, joint damping, or surface friction. Without calibrating these physics factors for world models, predictions tend to regress toward an empirical prior and induce severe drift in novel test scenes. To this end, we propose PhysiCalWorld, which calibrates action-conditioned world models to the instance-specific dynamics via in-context prompting, without fine-tuning or analytical physics modeling. Our method encodes an exploratory interaction clip collected within the test scene into a compact physics descriptor token, which grounds subsequent predictions in the scene’s actual physical behavior. PhysiCalWorld is trained end-to-end with the latent prediction loss alone, without physics labels. At inference time, the descriptor token is extracted once and can be reused across rollouts with negligible compute overhead. We evaluate PhysiCalWorld across four environments covering diverse physics variations and show that it substantially improves rollout prediction accuracy and visual planning success rate. The learned descriptors also form a physically structured latent space and generalize beyond the physics ranges seen during training. Project page at https://physical-world.github.io/.
World models predict how a scene evolves given its current state and the intended actions of the agents within it. Trained on internet-scale data, video-based world models (Bruce et al., 2024; Yang et al., 2023; Team et al., 2026; Agarwal et al., 2026) are now able to generate photorealistic visual predictions of complex scene dynamics that are difficult to model with traditional physics engines. Modeling the world in image space is thus becoming a promising alternative to hand-built physics modeling in such areas as robotics (Hou et al., 2026) and autonomous driving (Feng et al., 2025).
Existing world models usually generate predictions from the current frame or a short visual history. However, such observations may leave the underlying physical properties unconstrained, forcing the world models to guess a future state among multiple possible ones. For example, an opaque bottle appears identical whether or not it is filled with water, yet it will respond differently under identical actuation. A world model that relies only on empirical priors over object category or appearance will produce incorrect predictions in such scenarios, limiting its applicability in downstream applications that require accurate dynamics (Zhou et al., 2025; Quevedo et al., 2026). This motivates calibrating the world model to the hidden physical properties of each scene.
A natural way to resolve this physics ambiguity is to physically interact with the scene to infer its hidden properties, similar to how we humans would do for an object with unknown properties. Inspired by this, prior system identification methods (Wu et al., 2015; Yu et al., 2017; Kumar et al., 2021) attempt to construct accurate physical models with closed-form equations and fit the predefined physics parameters to the in-situ interaction data. However, real-world systems exhibit complex, coupled physics factors, thus building a geometric model or formulating closed-form equations can be challenging. Hence, to adapt to each deployment setting, existing world models (Gao et al., 2026) are typically finetuned on a small set of in-house data, which is computationally expensive.
To this end, we propose PhysiCalWorld, a method for in-context Physics Calibration for World models. Inspired by the in-context learning capabilities of large sequence models (Brown et al., 2020; Bar et al., 2022), we prompt world models with a sequence of observation-action pairs collected in the test environment (i.e., an environment whose physics configuration is unknown) for physics calibration. Our in-context prompting method sidesteps both the need for human effort to build analytical physics simulators for system identification and expensive model finetuning. Our method requires only an exploratory interaction clip without any gradient descent steps. PhysiCalWorld compresses the interaction sequence into a compact physics descriptor token that conditions the world model. The entire system is trained end-to-end with only a video prediction objective, requiring neither ground-truth physics parameters nor a simulator.
At test time, PhysiCalWorld first extracts the descriptor from a few exploratory interactions with the test scene (e.g., via random exploration or scripted policies). This descriptor then conditions all subsequent rollouts in that scene, enabling the world model to generate physically consistent predictions in novel configurations without any test-time weight updates.
In summary, our contributions are three-fold:
- •
In-Context Physics Calibration: We formulate physics calibration of generative world models as in-context conditioning: from a short interaction sequence, the model adapts zero-shot to instance-specific dynamics, with no test-time weight updates.
- •
Physics Descriptors Learned from Video Alone: We introduce a physics descriptor token that grounds the world model in hidden physical properties. It is learned end-to-end from video prediction alone, requiring neither ground-truth physics parameters nor a simulator.
- •
Performance and Analysis: Across four environments with single and coupled physics variations, PhysiCalWorld consistently improves rollout accuracy and planning success on two world model backbones. Its single-token descriptor matches or exceeds raw-context conditioning at a fraction of the cost. Without physics labels, the descriptors form a physically structured latent space and extrapolate beyond the training parameter range.
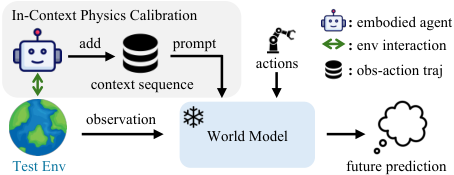
World models predict future states conditioned on current observations and agent actions, serving as an increasingly foundational framework for robotics (Li et al., 2025c; Hou et al., 2026). For example, they are scalable neural simulators, enabling low-cost policy evaluation without real-world execution (Guo et al., 2026; Gao et al., 2026; Wang et al., 2026e; Team et al., 2025; Tseng et al., 2025). Through future imagination, world models can also substantially improve sample efficiency in reinforcement learning (Hafner et al., 2019; Hansen et al., 2022; Seo et al., 2023; Wu et al., 2023) and facilitate policy learning (Saxena et al., 2026; Luo & Du, 2025). Moreover, optimizing action sequences with world models enables embodied agents to complete novel tasks via visual trajectory planning (Zhou et al., 2025; Assran et al., 2025; Wang et al., 2024). However, existing methods typically condition only on the current frame or a narrow observation history, assuming that these observations suffice to identify the underlying transition dynamics of the test scene. As a result, predictions tend to suffer from severe drift if latent physical properties vary across test scenes. In this work, we ground model predictions in the actual test-scene dynamics by introducing an additional in-context interaction prompt collected within the test scene as input to the world model, substantially enhancing the prediction accuracy and visual planning performance.
Context can serve embodied agents in various forms. For example, it can adapt a robot policy to test-scene dynamics by conditioning directly on execution history or by explicitly recovering physical parameters (Lee et al., 2020; Kumar et al., 2021; Liu et al., 2025; Zhang et al., 2025). Another role is in-context policy learning, where task demonstrations steer actions either through structured representations such as keypoints and graphs (Di Palo & Johns, 2024; Vosylius & Johns, 2025; Hwang et al., 2024) or raw video-action pairs (Fu et al., 2024; Shah et al., 2025; Ding et al., 2026), and in-context reinforcement learning (Lee et al., 2023; Lu et al., 2023). Most recently, context has been applied to action-conditioned world models by prepending context prefixes to adapt to new camera viewpoints or embodiments (Yang et al., 2026). However, prior works focus on policy adaptation, require privileged physical priors, or prepend raw context frames at high computational cost. In contrast, we use context to enable physics-grounded future prediction in world models, introducing a compact physics descriptor token to minimize computational overhead while maintaining high prediction accuracy and rollout efficiency.
Video generative models have advanced rapidly (Yang et al., 2025; Zheng et al., 2025; Chen et al., 2026), with widespread commercial deployment (Seedance et al., 2026; Wan et al., 2025). However, their adherence to physical laws remains limited (Motamed et al., 2026; Upadhyay et al., 2026; Bansal et al., 2025; Meng et al., 2024). Recent efforts seek to improve physical awareness in video models by incorporating explicit physics equations or parameters in the generation process (Zhang et al., 2024; Wang et al., 2026a; Yuan et al., 2026; Wang et al., 2026b), coupling with external physics simulators (Liu et al., 2024; Xie et al., 2025; Foo et al., 2026), leveraging foundation models (Xue et al., 2025; Zhang et al., 2026b), or optimizing handcrafted rewards (Zhang et al., 2026a; Li et al., 2025a). However, these approaches either rely on analytical formulations and are restricted to a pre-defined set of physics properties, or focus on learning general physics and tend to fail in scenarios that require fine-grained instance-level physics grounding. In comparison, our work focuses on calibrating action-conditioned world models to the instance-specific dynamics of a test scene from an exploratory interaction prompt, operating entirely end-to-end without prior assumptions or ground-truth supervision of the environment’s underlying physics.
We consider an embodied agent interacting with an environment over discrete timesteps . At each step, the agent receives a high-dimensional visual observation (and an optional proprioceptive state ) and executes a control action . Our objective is to learn an action-conditioned world model that predicts future observations directly in a compact latent space and enables both long-horizon rollout and visual planning.
While our proposed in-context prompting framework is a plug-and-play module applicable to different world model architectures, we base the proposed method on two recent latent world models, DINO-WM (Zhou et al., 2025) and LeWM (Maes et al., 2026), due to their efficiency and strong trajectory planning performance. In these latent world models, each input RGB frame is encoded by a visual encoder into a set of visual tokens :
where denotes the number of visual tokens per frame and is the feature dimension. Meanwhile, actions are mapped into action embeddings via a learned MLP :
The latent dynamics predictor (a causal transformer with weights ) models temporal transitions over a history window of steps. At step , the predictor takes a sequence of past visual tokens and action embeddings to predict the next latent tokens:
For visual evaluation and pixel-space rollouts, we train a lightweight convolutional decoder that reconstructs images from latent tokens, , while downstream visual planning can be conducted directly within the latent space .
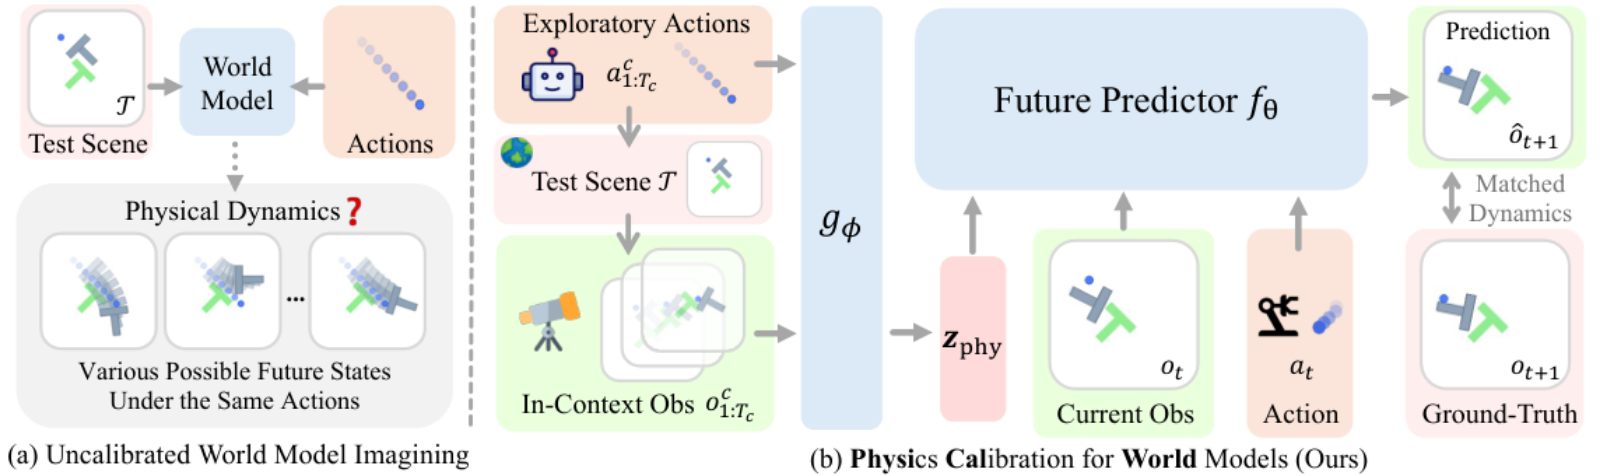
The forward transition function of an environment depends not only on the current states and actions, but also on a set of underlying physics properties (e.g., mass, surface friction, or joint damping). Because many of these physics properties rarely correlate with surface appearance, a static visual frame or a brief observation window can hardly identify and hence leaves the true transition dynamics underdetermined.
Consequently, action-conditioned future prediction becomes an ill-posed, one-to-many problem. Without sufficient interaction data from the test scene to calibrate the future predictor , its prediction may collapse to the expectation over the training distribution with compounding dynamic drift when the test environment deviates from the nominal mean. While one could explicitly estimate and feed the test-scene physics parameters to , this usually relies on ad-hoc analytical modeling (as one must know in advance which physics properties determine the dynamics) and also introduces cascading estimation errors. An alternative strategy is to scale up the history window of world models, so that the future predictor can directly extract the physical transition dynamics from previous interaction. However, self-attention complexity in transformers scales quadratically with sequence length, making long-history conditioning computationally prohibitive. Furthermore, continuously carrying long raw frame histories (e.g., thousands of tokens) in every inference step introduces substantial redundancy, as the underlying physics configuration can usually be represented far more compactly.
To address these challenges, our method calibrates world models through a single compact representation, termed physics descriptor token , which is extracted from an exploratory interaction sequence collected in the test scene. Formally, given an interaction clip of length , the context encoder maps it to a descriptor token . Internally, a lightweight visual encoder extracts per-frame visual features and an action encoder maps the control actions into action embeddings. At each timestep , the two are concatenated along the channel dimension into a joint transition token . A transformer then fuses these transition tokens across time and pools them via a learnable query token :
where denotes channel-wise concatenation and denotes the output at the query-token position. We use to collectively denote the parameters of , including , , , and . The world model’s latent dynamics predictor is subsequently conditioned on alongside the default observation-action history window , predicting future latents as:
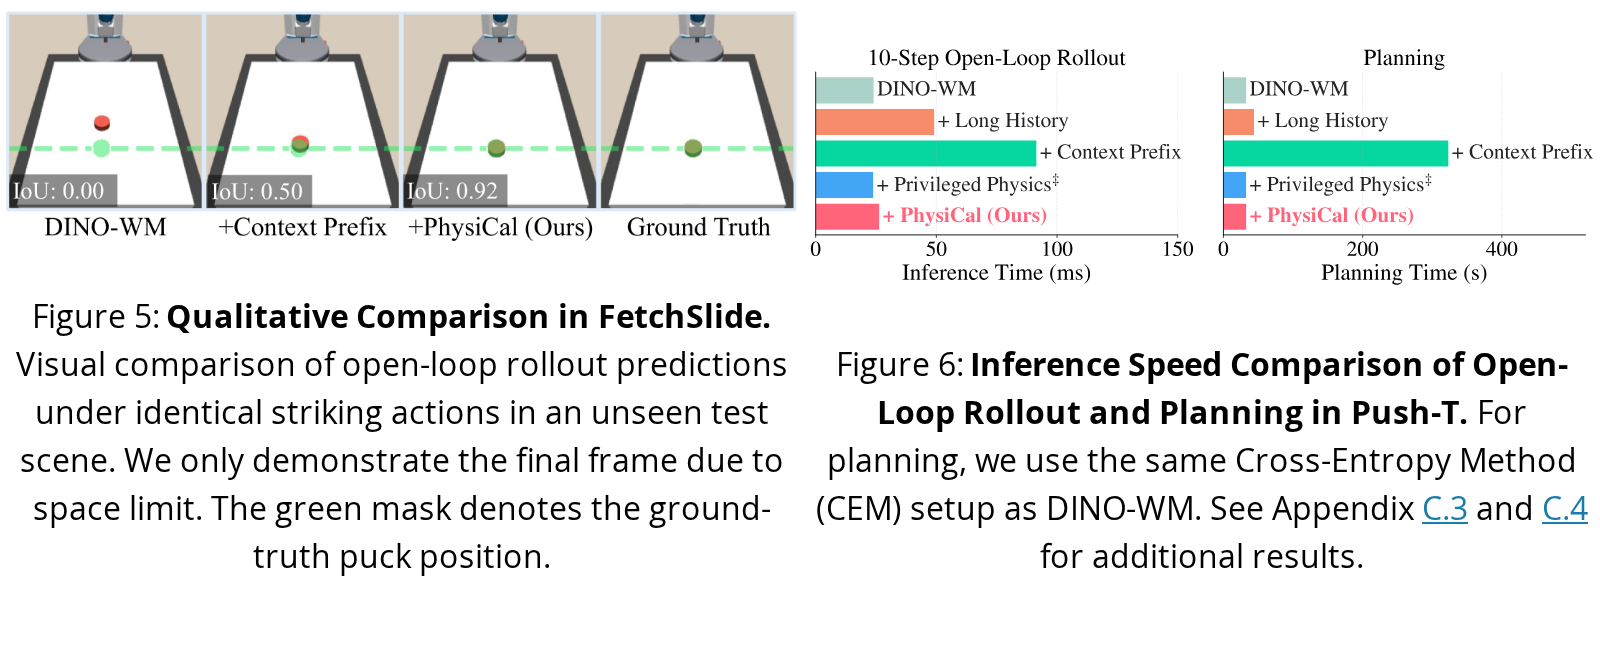
\hat{z}_{t+1}=f_{\theta}\Bigl(\bigl\{(z_{i},e_{i}^{a})\bigr\}_{i=t-K+1}^{t},\;\mathbf{z}_{\text{phy}}\Bigr).\vskip-5.0pt\tag{(5)}Efficiency and Reusability. The design of physics descriptor token provides two practical advantages. (1) minimal rollout overhead: adding a single additional token into the predictor introduces only a constant and almost negligible computational cost, circumventing the quadratic attention overhead compared to using longer history or simply prepending raw context frames to (see +Long-History and +Context-Prefix in Section 4 and Figure 6 for comparison); (2) one-pass extraction and in-context reuse: is computed via a single forward pass of a lightweight context encoder and can then be cached. If the dynamics of the test scene remain unchanged, the same descriptor can be reused across arbitrarily many future rollouts or planning tasks with no additional encoding cost.
To enable physics-calibrated predictions, existing models typically rely on pre-specified analytical equations (Li et al., 2025b; Wang et al., 2026c) or train explicit system identification modules using privileged physical parameters (Yu et al., 2017; Kumar et al., 2021). However, constructing analytical physics formulations often demands substantial human effort and is often intractable for unstructured scenes with coupled dynamics. Meanwhile, obtaining the ground-truth physics parameters requires instrumented environments and often introduces measurement errors, which would then propagate to model training. As a result, these approaches are typically confined to controlled settings and struggle to scale to novel, uncalibrated in-the-wild scenes governed by unknown physical properties.
In contrast, PhysiCalWorld requires neither prior physics equations nor the error-prone explicit parameter estimation during both training and evaluation. While deriving analytical formulations or measuring exact physical parameters of in-the-wild scenes is intractable, constructing data groups where each group consists of interaction data collected within the same physical environment is simple and requires minimal additional effort during data collection. Such data grouping alone is sufficient to train PhysiCalWorld and learn an effective physics descriptor token.
Specifically, the training dataset is categorized into groups , where each group comprises episodes that share the same underlying physics configuration . In training, for any transition , we independently sample another clip from the same group as the interaction prompt. Because both sequences share the identical underlying transition dynamics , the context encoder can learn to distill the scene’s physical characteristics into the compact descriptor token to synthesize the correct prediction. We jointly optimize the context encoder and dynamics predictor end-to-end using the latent prediction objective:
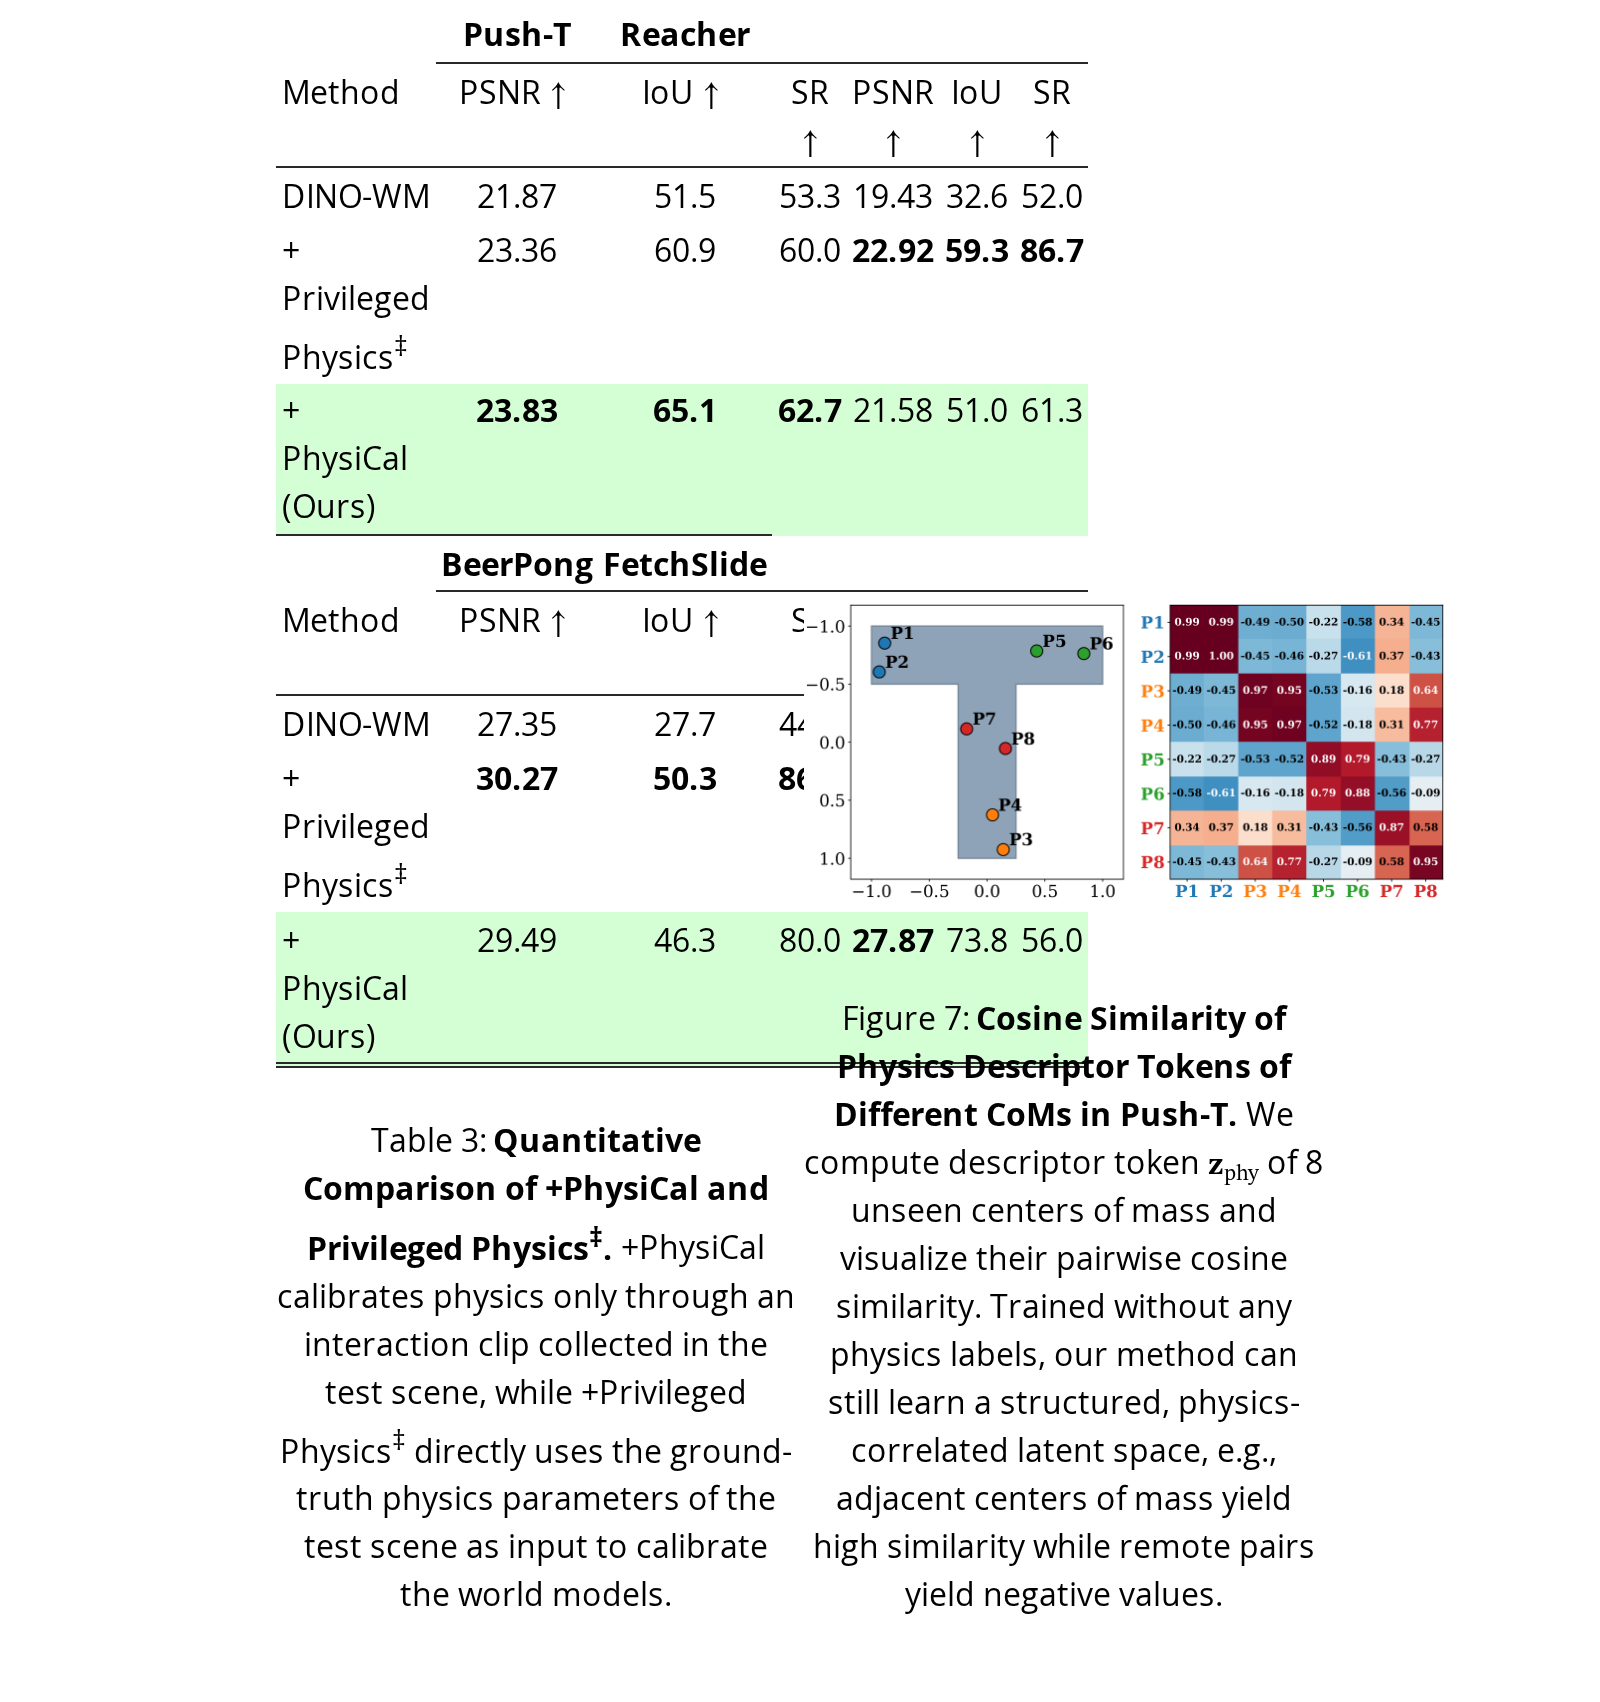
For simplicity, we assume the input window size of to be 1 in Equation 6. This formulation enables PhysiCalWorld to extract instance-specific physical dynamics directly from the interaction clip into the compact physics descriptor token , circumventing the need for ground-truth physics labels as supervision. As in Figure 7, this self-supervised predictive objective can autonomously learn a structured latent space correlated to the underlying physics variations of the scenes.
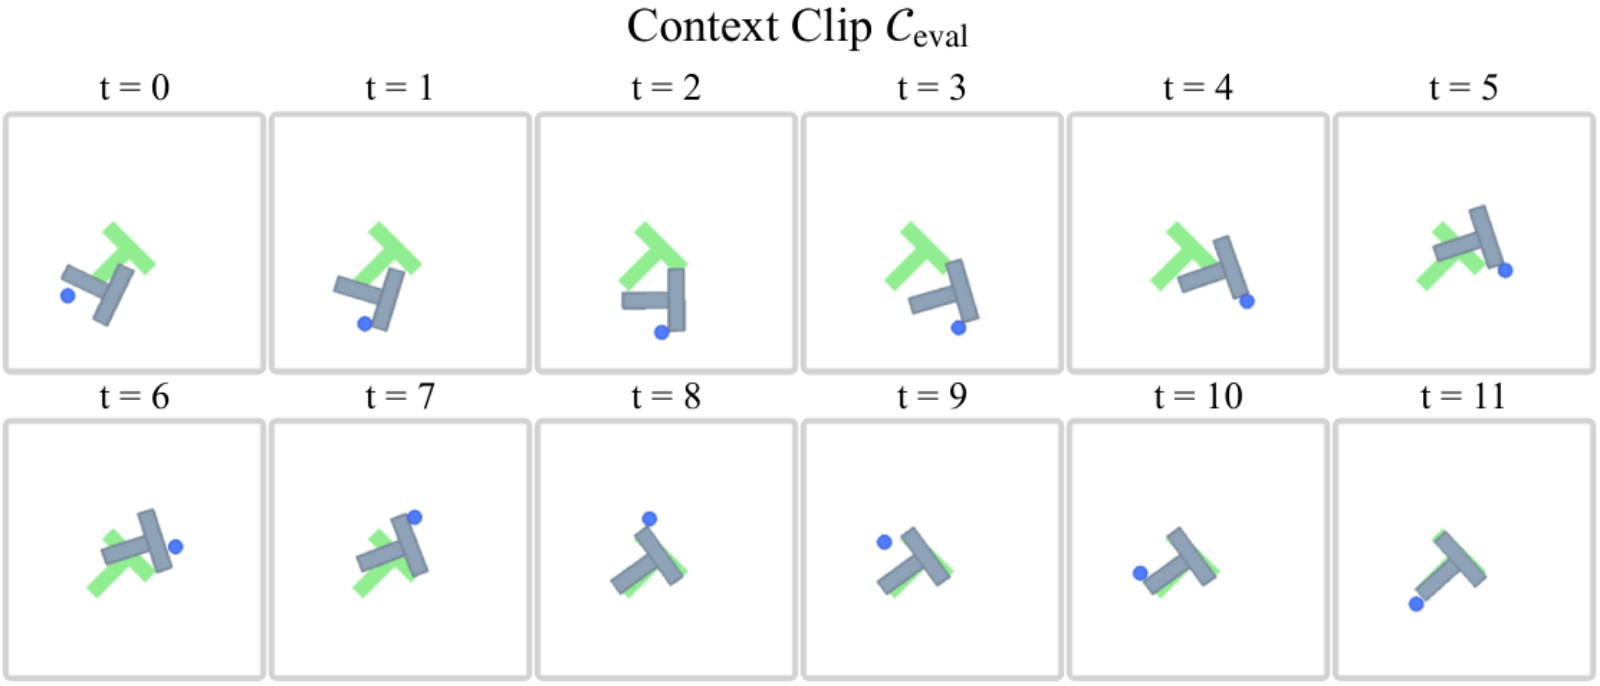
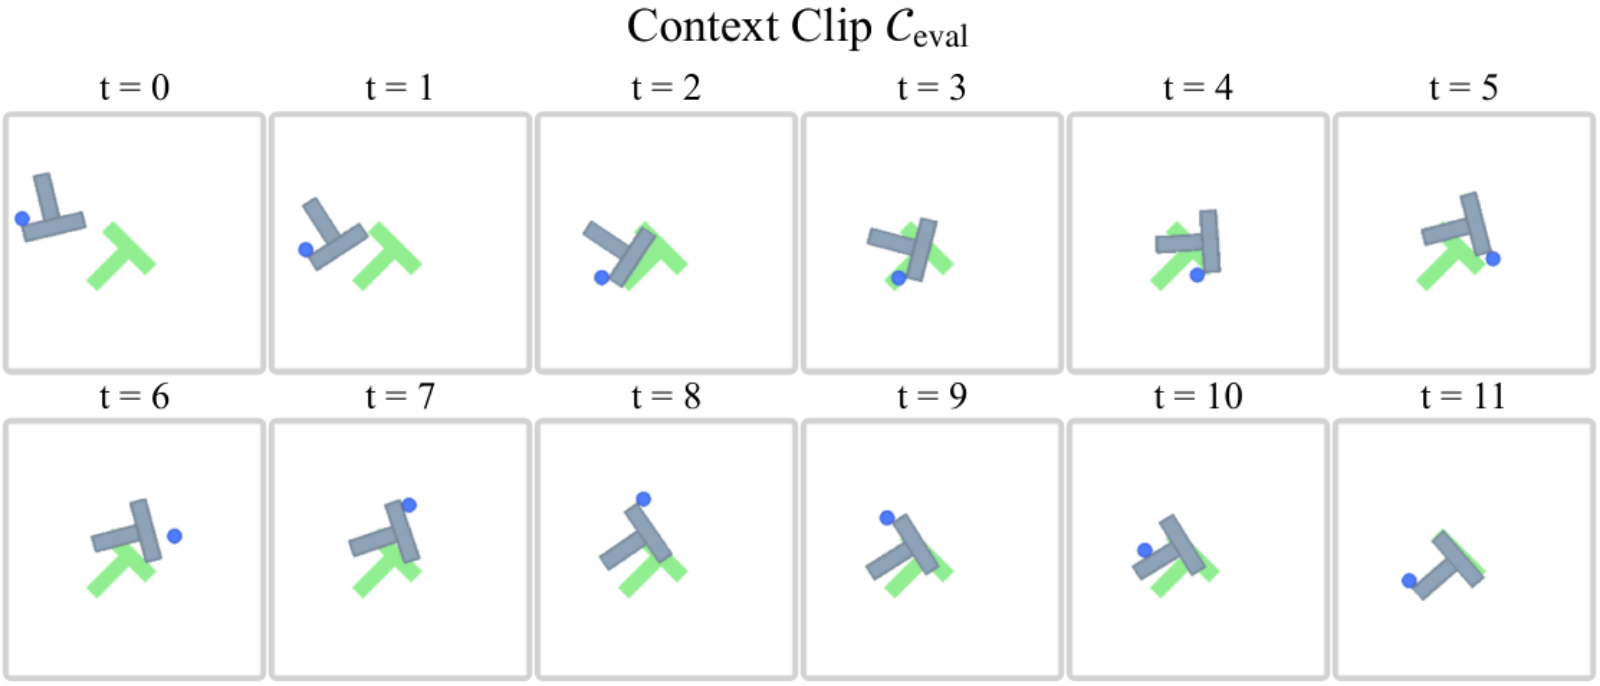
At test time, PhysiCalWorld enables zero-shot adaptation to environments with novel physics configurations without fine-tuning. To calibrate the world model to an unseen test scene, the agent first executes a sequence of exploratory actions to collect a context prompt of length , which consists of the applied actions and the corresponding observations. The actions can be either randomly sampled or generated by a task-agnostic playful policy, as this interaction prompt is only for revealing the physical dynamics of the scene. However, these actions should produce physical contact with the environment since interactions lacking contact or motion cannot reveal the underlying dynamics.
Given collected in the test scene, the physics descriptor token is computed once by the context encoder and can be held fixed if the test scene dynamics remain unchanged. Calibrated by descriptor , the predictor can then predict the future latents as:
where predicted latents can be fed back to as observation to enable long-horizon open-loop rollout (see Algorithm 2 for pseudocode). If the intrinsic physics of the scene does not change, can be shared across every rollout step and across every candidate trajectory to be evaluated during visual planning. Therefore, the prompt only needs to be encoded once per scene, regardless of the planning horizon or the number of sampled action sequences. Notably, no physical parameters, analytical models, or task-specific fine-tuning are required at inference: adapting PhysiCalWorld to a new scene only requires collecting a period of in-context interaction.
Our experiments evaluate five questions: (1) Physics Calibration: Does conditioning on in-context interaction clips enable effective physics calibration and yield more accurate future predictions? (2) Descriptor Expressiveness and Efficiency: Can PhysiCalWorld learn compact, expressive physics descriptor tokens without analytical physics priors and enable high compute efficiency? (3) Coupled Physics Dynamics: Can PhysiCalWorld scale to complex scenes whose dynamics are jointly governed by multiple physics properties? (4) Backbone Generalization: Can PhysiCalWorld function as an architecture-agnostic, plug-and-play module across diverse world-model backbones? (5) Out-of-Distribution Extrapolation: Can PhysiCalWorld extrapolate to unseen environments whose physics parameters lie outside the training distribution?
Baselines. Our in-context prompting framework can be integrated into various world model backbones. We use DINO-WM (Zhou et al., 2025) and LeWM (Maes et al., 2026) as our base world models due to their rollout efficiency and strong trajectory planning performance, alongside Temporal Straightening (TS-WM) (Wang et al., 2026d) as a competitive latent world model baseline.
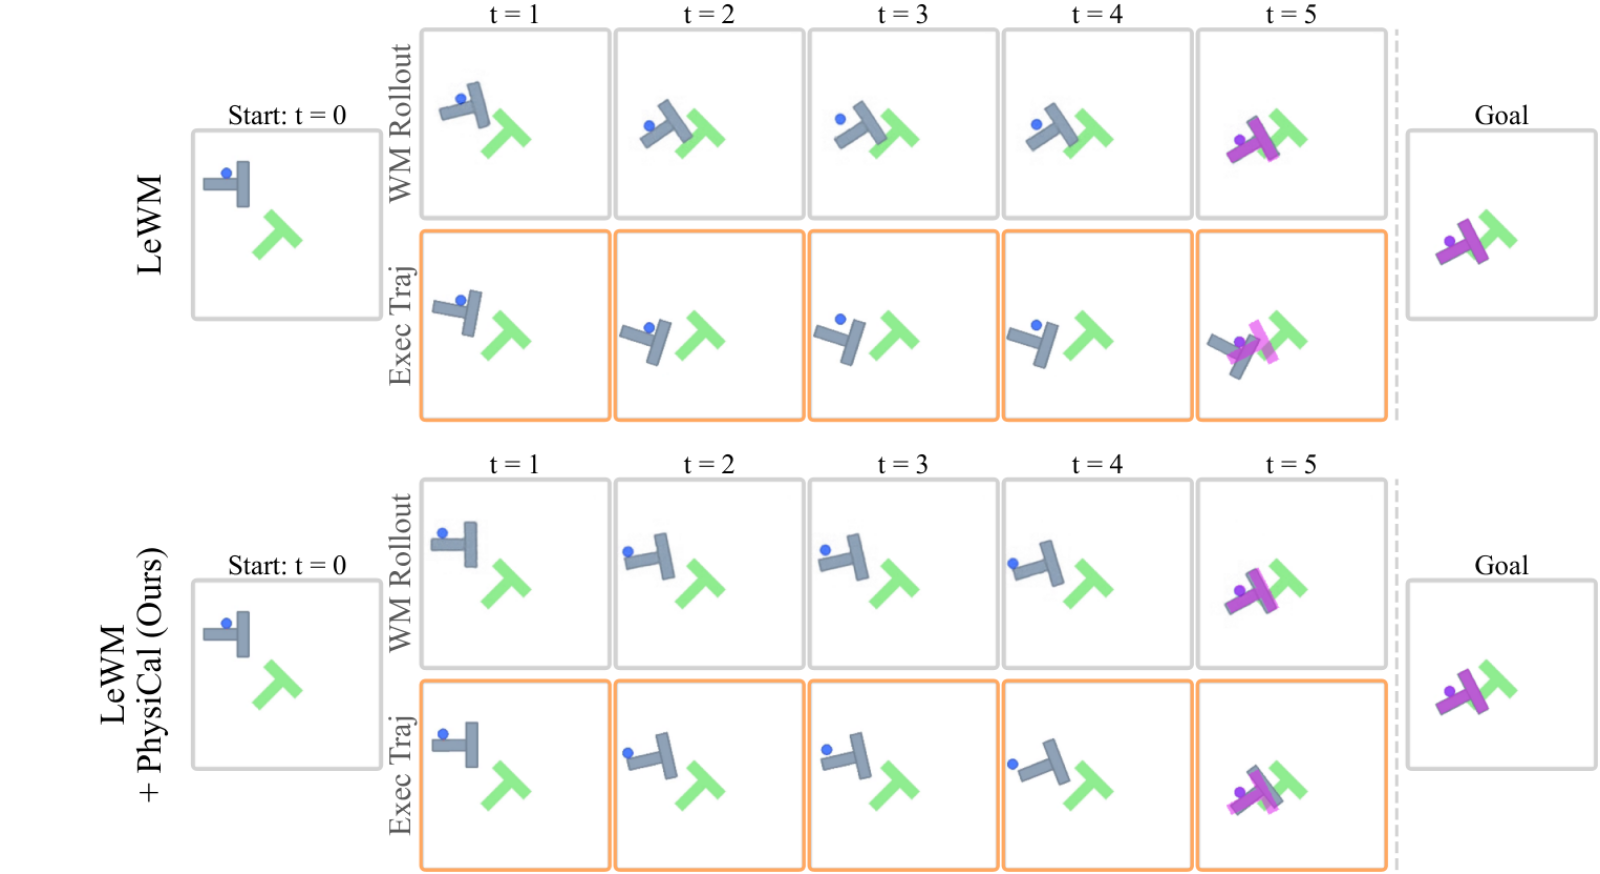
We train several variants of models for systematic study: (1) +Long History, which takes in a long history window to investigate if simply extending history memory in world models can enable physics-calibrated predictions; (2) +Context Prefix, which directly prepends the raw context interaction prompt to the input of the world model instead of using the proposed physics descriptor token; (3) +Estimated Physics†, which trains an encoder to predict physics parameters from a context clip and feeds the estimated physics values to the world model (hence this baseline requires additional physics labels for model training). For further analysis, we additionally evaluate (4) +Privileged Physics‡ in Section 4.3, which takes the ground-truth test-scene physics parameters as input, serving as an oracle ceiling rather than a directly comparable baseline. Finally, we compare LeWM against LeWM+PhysiCal to verify that our method generalizes across different world model backbones. See Appendix A.1 for detailed description of each baseline.
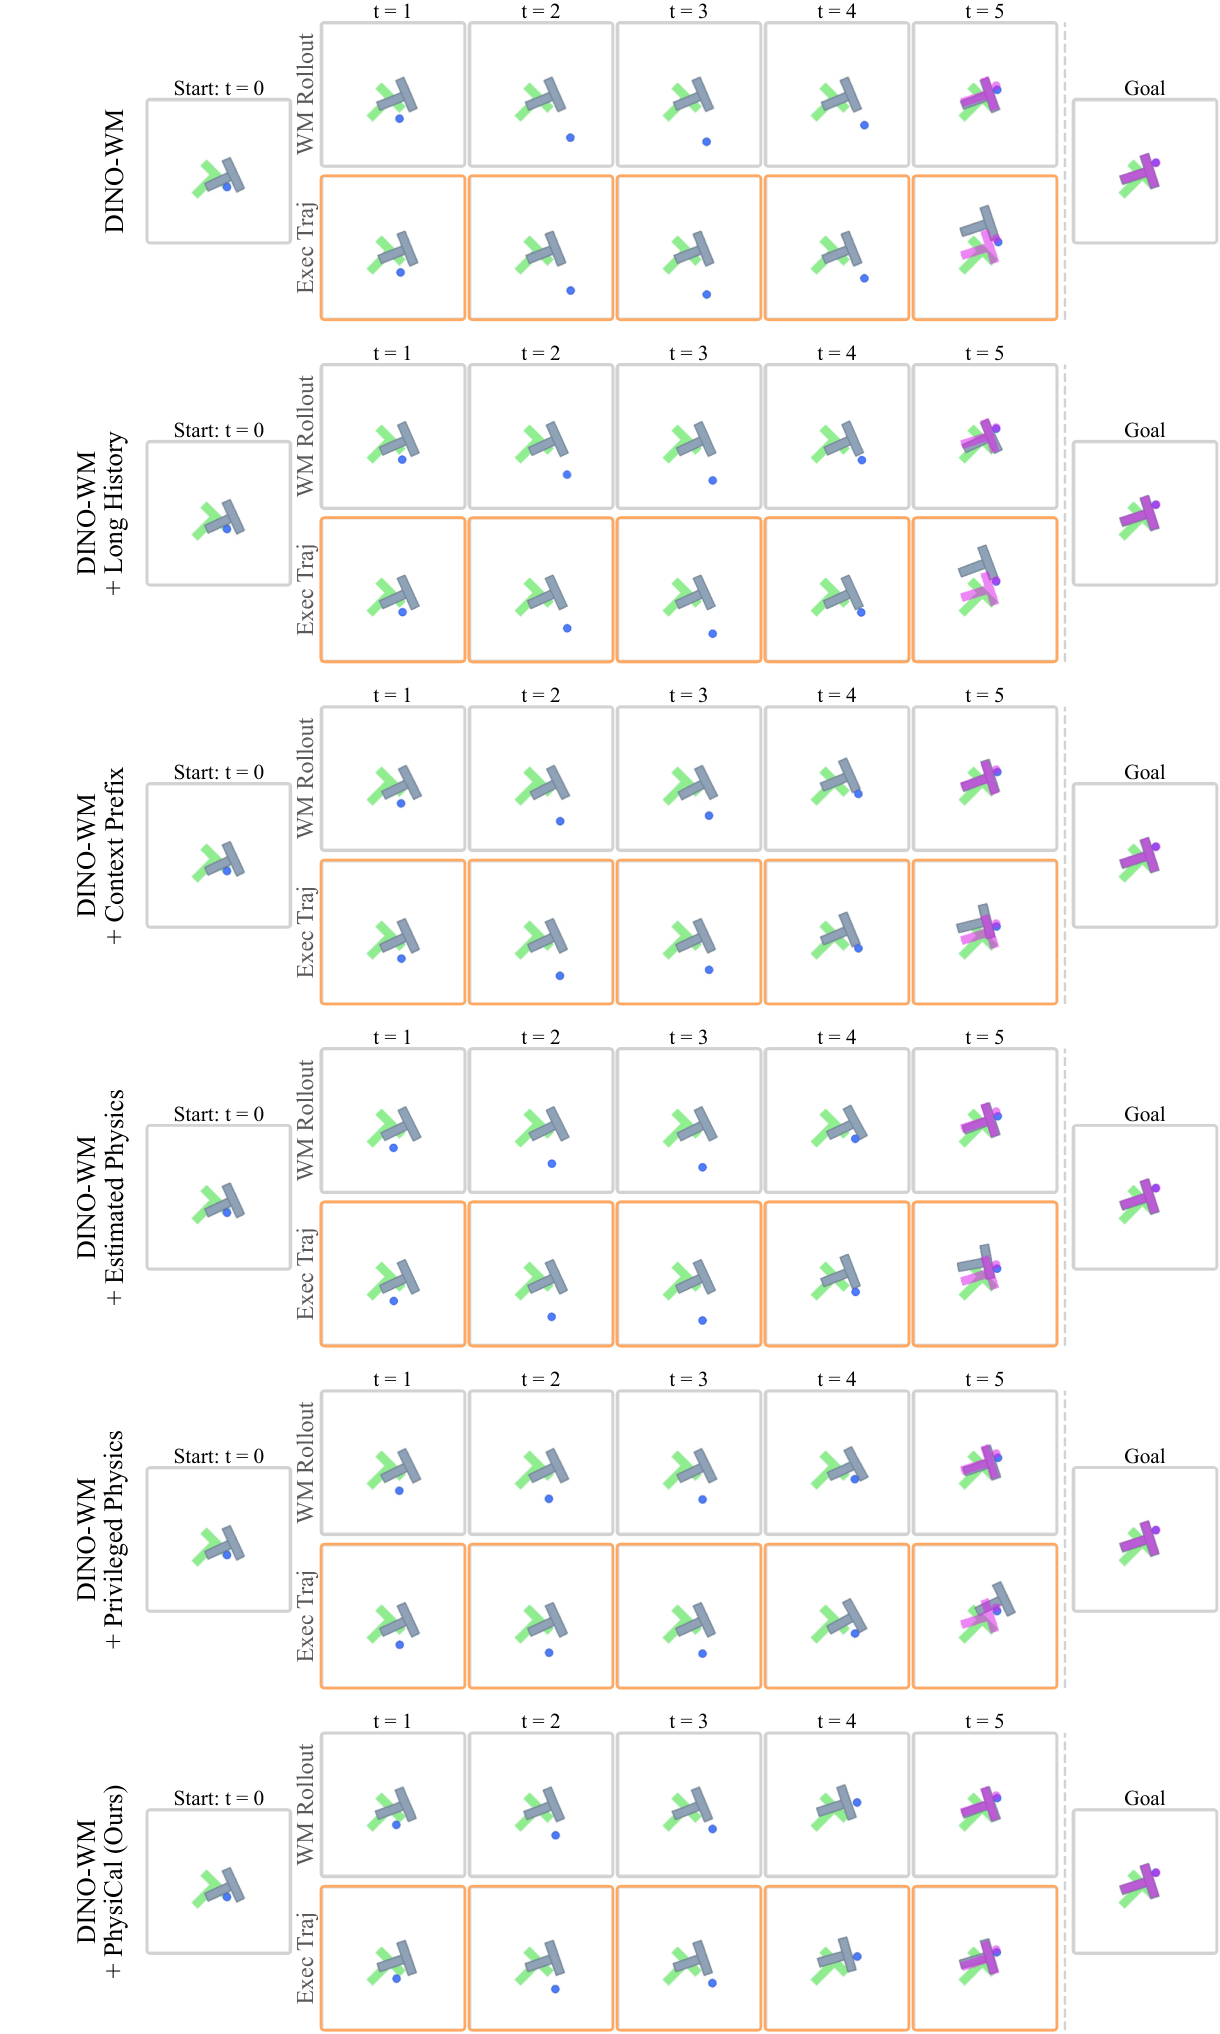
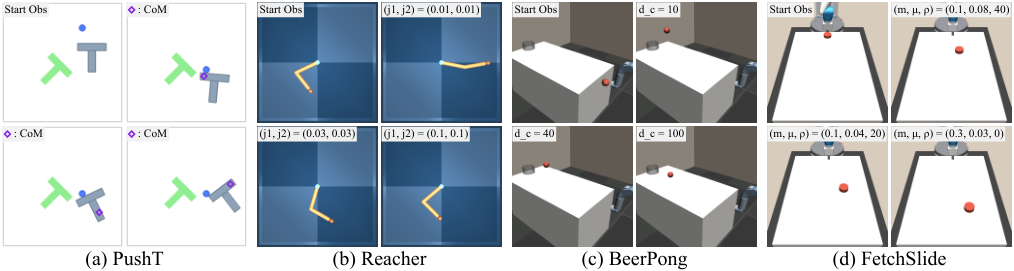
Environments and Evaluation. We illustrate all our environments in Figure 3 and show how different physics configurations will affect the future world states. We train the models on different configurations and report the results on 15 unseen configurations, with 5 validation episodes per configuration, giving 75 episodes in total. We report four visual metrics (PSNR, SSIM, LPIPS, IoU) in open-loop rollout, which starts from the initial frame and autoregressively predicts all frames of an episode by recursively feeding the model’s own predictions back as input. We also evaluate on 75 planning tasks per environment and report the success rate (SR). Each task is defined by a start image and a goal image. We execute the planned actions in the environments. The success criterion is whether the target object reaches the goal within a threshold. See Appendix B for details.
The Push-T environment consists of a circular pusher (the agent) and a T-shaped block (see Figure 3). The world model predicts the future latents of the scene alongside the pusher’s proprioception conditioned on the pusher’s actions. In planning, each goal is defined by an image and a target agent state. The block’s center of mass (CoM) is randomly sampled. Different CoMs will not change the block’s appearance but will alter how the block rotates and slides when pushed, hence resulting in significantly different states even under identical push actions.
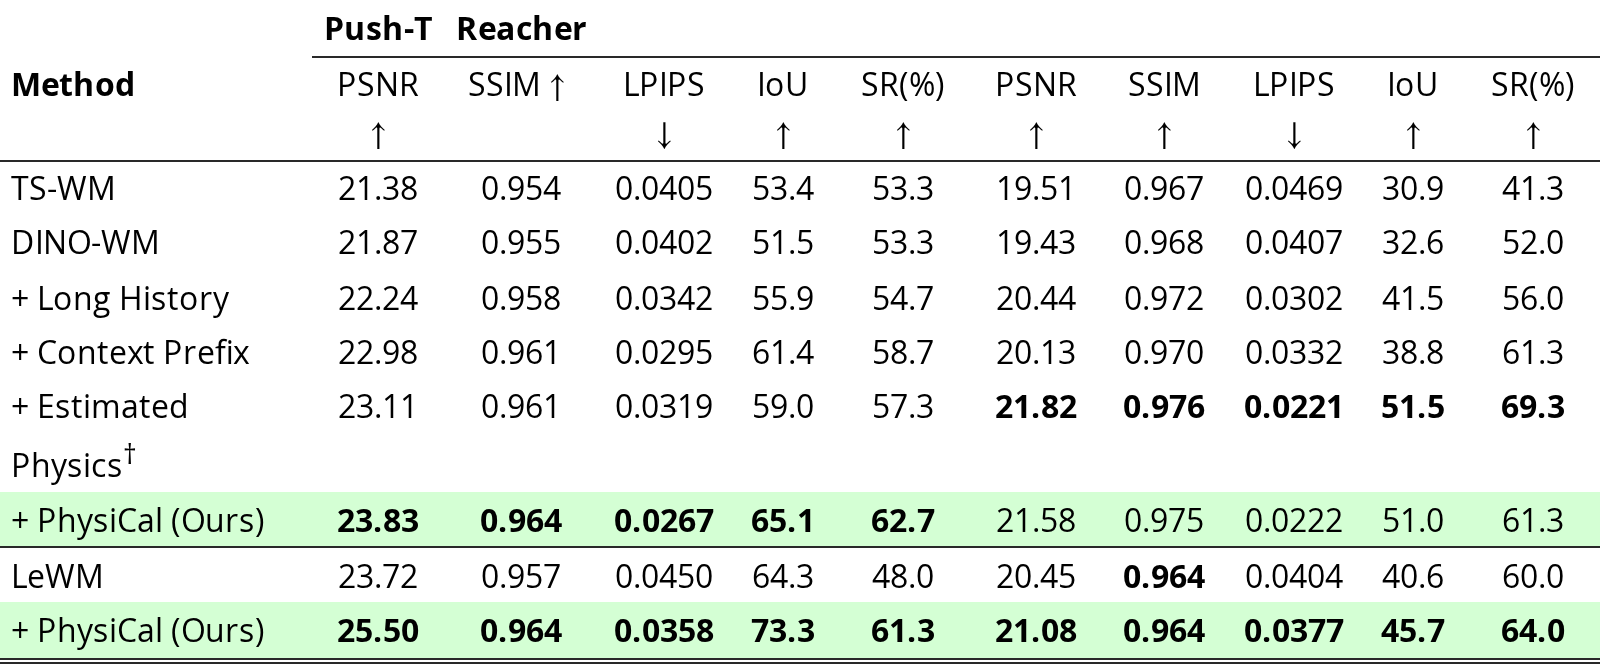
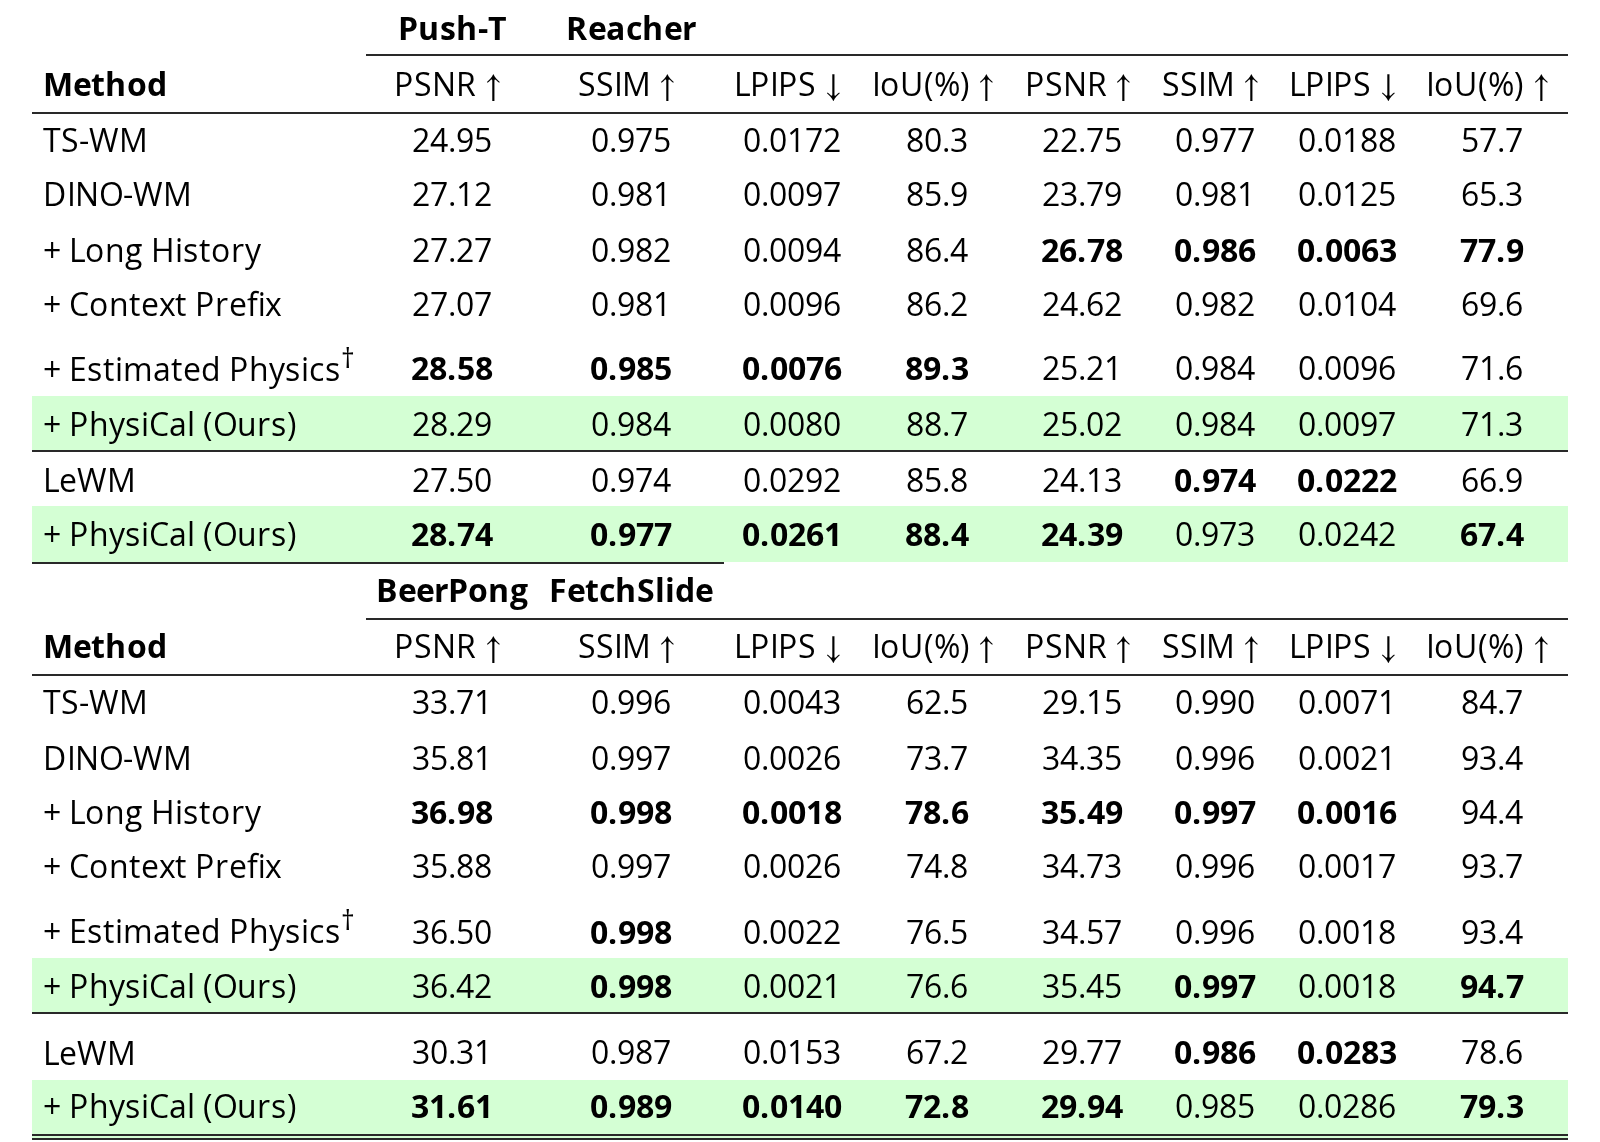
As in Table 1, methods without in-context prompts as input (e.g., DINO-WM and TS-WM) generally underperform, showing that in-context interaction prompts can effectively facilitate physics calibration. We observe that compared to other long-context variants (e.g., +Long History and +Context Prefix, see Appendix A.1 for details), +PhysiCal achieves significantly better performance, especially in challenging open-loop rollout, showing that a single descriptor token can stably ground the physics over long-horizon rollout. Our method also outperforms +Estimated Physics† in all open-loop rollout visual metrics without using any physics labels during training. Moreover, compared to +Context Prefix, our compact descriptor token design avoids the quadratic self-attention cost caused by the long context sequence, yielding markedly speedup in both training and inference (Figure 6 and Table A8).
This environment consists of a two-link robot arm actuated by continuous joint torques. The damping coefficients of the two joints can affect how much the arm moves under the same applied torques. Each planning task optimizes a torque trajectory to steer the arm toward a target state specified by a goal image. The in-context prompts are randomly sampled actions. We present the quantitative results in Table 1. Our in-context conditioning consistently improves both DINO-WM and LeWM, outperforming all unprivileged baselines and trailing only +Estimated Physics, which requires ground-truth joint damping parameters for model training. While +PhysiCal achieves a similar planning success rate as +Context Prefix, our method surpasses it across all visual prediction metrics by a margin and is more compute efficient. We specify implementation details of the Reacher environment in Appendix B.2.
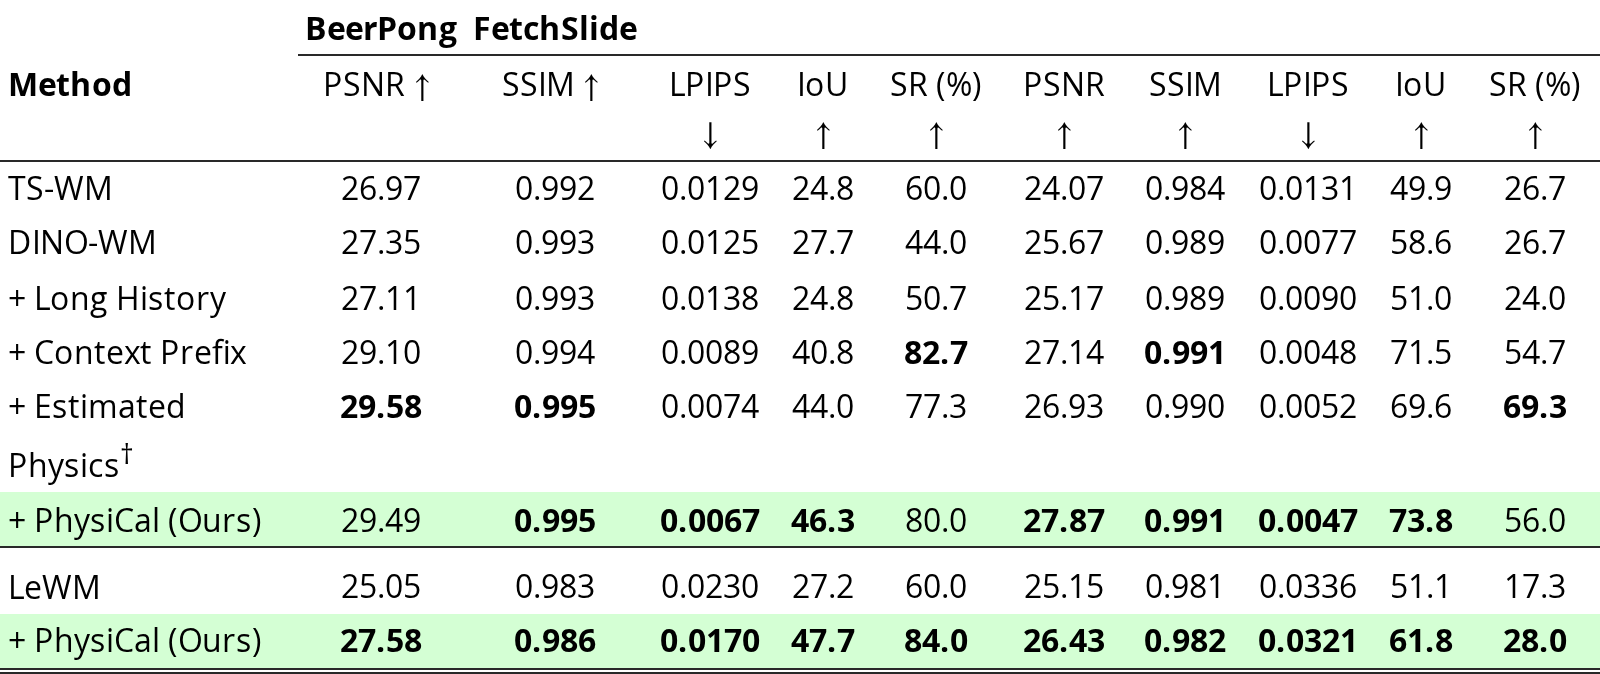
In BeerPong, a robot arm throws a ball toward a target cup on a tabletop. The ball needs to bounce off the table at least once to enter the cup due to the long distance. We vary impact energy dissipation by changing the table’s contact damping (e.g., higher damping causes greater energy loss, resulting in lower bounce height). The action input to the world models is the end-effector release velocity. The cup location is randomly initialized in each planning task. The planner then optimizes the release velocity so that the ball can land right inside the cup after bounce. The in-context prompts are collected via randomly sampled actions. Please see Appendix B.3 for additional details.
We present quantitative results in Table 2. Across both world-model backbones, +PhysiCal consistently improves visual prediction accuracy over the uncalibrated baselines. While our method surpasses +Context Prefix across all visual metrics, it achieves a slightly lower planning success rate. This is potentially because the physics variation in BeerPong manifests only when the ball contacts the table, leading to temporally sparse physical cues. Under such observation sparsity, self-attention over the full raw context frames may provide an advantage in identifying collision dynamics.
FetchSlide under Multiple Physics Variations. We next investigate whether PhysiCal can calibrate world models in environments where transition dynamics are simultaneously governed by multiple physics properties. To this end, in FetchSlide, we concurrently vary three physics parameters: puck mass, table surface friction, and aerodynamic drag. In this environment, a robot arm strikes a flat puck across a tabletop, where these three properties jointly determine the puck’s post-strike deceleration and sliding distance. The action space is end-effector delta position, which subsequently defines the striking velocity and angle. In planning, we optimize the strike actions so that the puck can stop at the target position specified by a goal image. The context sequence is collected via random actions.
Quantitative results are presented in Table 2. Despite the added complexity of coupled physical factors, +PhysiCal effectively calibrates predictions without requiring analytical physics equations,
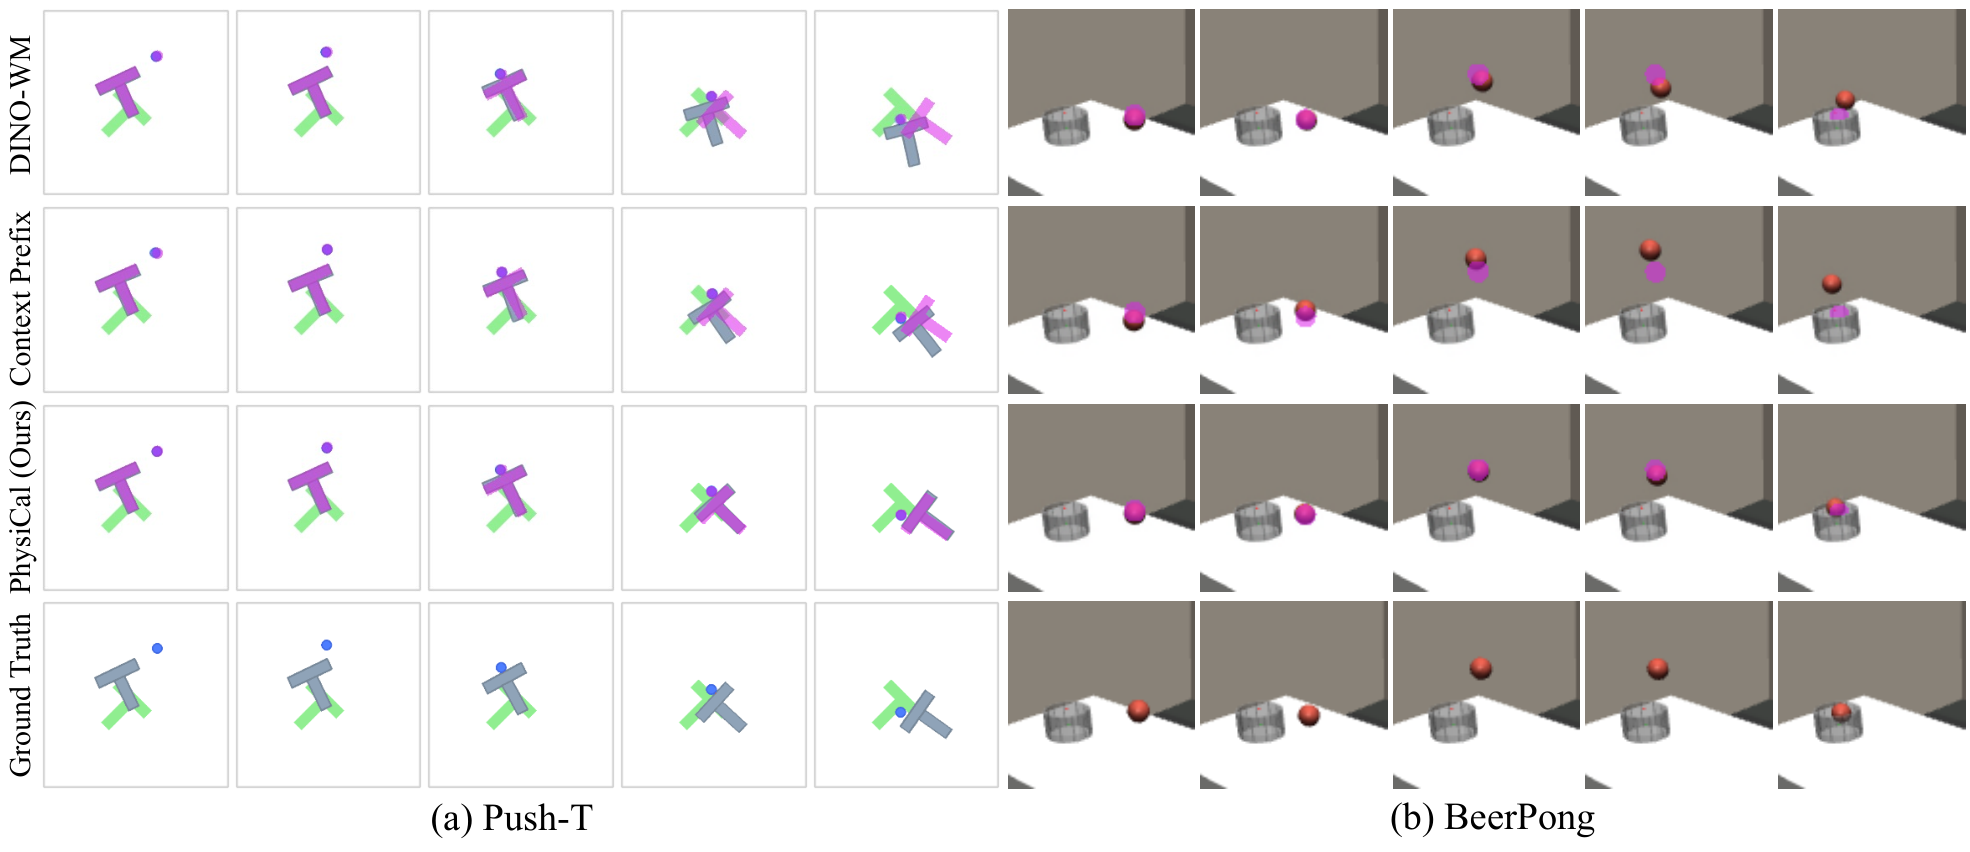
yielding significant gains across both backbones. Our method is only surpassed by +Estimated Physics†, which is trained with the ground-truth values of all three physical properties. However, oftentimes finding what physics parameters govern the scene and precisely measuring them are impractical, whereas +PhysiCal is trained directly via the future latent prediction objective without any physics labels. We also provide qualitative results of the final prediction of an open-loop rollout in Figure 6, where uncalibrated DINO-WM deviates from the target position, while +PhysiCal generates predictions that faithfully capture the ground-truth puck state.
Physics Calibration vs. Privileged Physics‡. We additionally compare our method against an oracle baseline, +Privileged Physics‡, serving as an upper-bound reference. Specifically, this baseline directly receives ground-truth physics parameters as supplementary inputs during both training and inference (Privileged Physics‡ and Estimated Physics† share the same future predictor , but at inference, Estimated Physics† uses physics parameters estimated by a neural network). In contrast, +PhysiCal accesses only an unannotated interaction clip from the test scene for calibration, and nevertheless, as shown in Table 3, our method achieves competitive performance across most metrics and even surpasses this privileged baseline in Push-T.
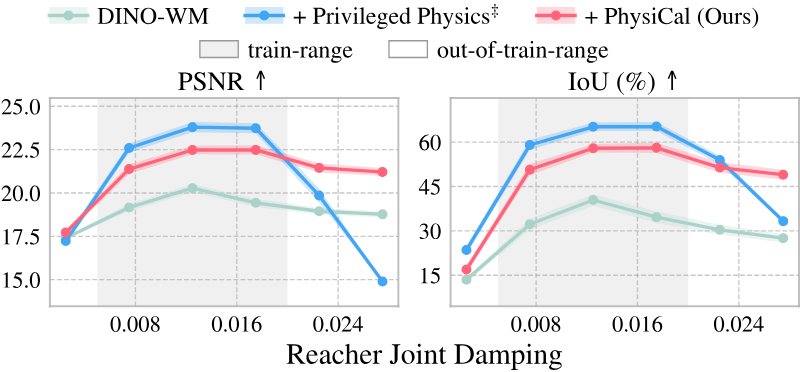
Generalization to Out-of-Distribution Physics Parameters. We investigate whether PhysiCalWorld can extrapolate to environments where physics parameters lie outside the training distribution (Figure 8). Specifically, in Reacher, we sweep the first joint’s damping coefficient beyond its training range while holding the second joint’s damping fixed. While +Privileged Physics achieves higher accuracy in-distribution, its performance deteriorates sharply when the damping falls below or exceeds the training interval. In particular, its rollout PSNR significantly drops, producing blurry predictions (Figure A6). In contrast, our method demonstrates robust extrapolation over unseen regimes, probably because our model learns latent patterns to infer dynamics rather than overfitting to rigid scalars.
Interpretability and Latent Structure of the Physics Descriptor . We analyze whether the physics descriptor learns structured representations of the test-scene physics. Specifically, in Push-T, we collect 10 interaction clips in each of the 8 unseen center of mass (CoM) locations (–) and encode each clip into a physics descriptor token using the context encoder . We then compute the pairwise cosine similarities between these tokens and average them across each CoM pair. As shown in Figure 7, descriptors from adjacent CoM locations exhibit strong positive correlation, while CoMs that are far apart yield negative similarity values. This indicates that our training objective enables the context encoder to capture meaningful physics properties correlated with the scene dynamics, even without using ground-truth physics labels during training.
Limitations. Our approach has several limitations. First, training PhysiCalWorld requires grouping trajectories by the physics configurations under which they were collected. While partitioning data by environment identity is far less demanding than deriving analytical equations, curating grouped data from in-the-wild video remains non-trivial. One potential direction to relax this is leveraging self-supervised representation learning to automatically cluster latent transition dynamics into environment groups. Moreover, the proposed test-time calibration depends on the quality of the interaction prompt given to the model. While we find that simple playful or even random policies often suffice, future work could explore active or curiosity-driven exploration to collect more informative prompts. Finally, our framework assumes the physics properties are stationary: the dynamics remain unchanged within an episode. Extending this approach to non-stationary environments (e.g., fluctuating wind fields) may require additional techniques such as reactive prompting or online descriptor updates.
Conclusion. We believe that world models should go beyond generic visual fidelity toward instance-specific physics-grounded prediction. In this work, we take a step toward this goal by introducing an in-context calibration framework that grounds action-conditioned world models in the actual physics dynamics of novel test scenes. We achieve this by prompting the model with an interaction sequence collected within the test scene, enabling zero-shot calibration without finetuning or analytical physics priors. Evaluations across diverse environments demonstrate that our approach substantially improves predictive accuracy and downstream visual planning.
This work is supported in part by the National Science Foundation under CAREER Award No. 2544116.
References
- Agarwal et al. (2026) Niket Agarwal, Arslan Ali, Jon Allen, Martin Antolini, Adeline Aubame, Alisson Azzolini, Junjie Bai, Maciej Bala, Yogesh Balaji, Josh Bapst, et al. Cosmos 3: Omnimodal world models for physical ai. arXiv preprint arXiv:2606.02800, 2026.
- Assran et al. (2025) Mido Assran, Adrien Bardes, David Fan, Quentin Garrido, Russell Howes, Matthew Muckley, Ammar Rizvi, Claire Roberts, Koustuv Sinha, Artem Zholus, et al. V-jepa 2: Self-supervised video models enable understanding, prediction and planning. arXiv preprint arXiv:2506.09985, 2025.
- Bansal et al. (2025) Hritik Bansal, Zongyu Lin, Tianyi Xie, Zeshun Zong, Michal Yarom, Yonatan Bitton, Chenfanfu Jiang, Yizhou Sun, Kai-Wei Chang, and Aditya Grover. Videophy: Evaluating physical commonsense for video generation. In International Conference on Learning Representations, volume 2025, pp. 102075–102121, 2025.
- Bar et al. (2022) Amir Bar, Yossi Gandelsman, Trevor Darrell, Amir Globerson, and Alexei Efros. Visual prompting via image inpainting. Advances in neural information processing systems, 35:25005–25017, 2022.
- Brown et al. (2020) Tom Brown, Benjamin Mann, Nick Ryder, Melanie Subbiah, Jared D Kaplan, Prafulla Dhariwal, Arvind Neelakantan, Pranav Shyam, Girish Sastry, Amanda Askell, et al. Language models are few-shot learners. Advances in neural information processing systems, 33:1877–1901, 2020.
- Bruce et al. (2024) Jake Bruce, Michael D Dennis, Ashley Edwards, Jack Parker-Holder, Yuge Shi, Edward Hughes, Matthew Lai, Aditi Mavalankar, Richie Steigerwald, Chris Apps, et al. Genie: Generative interactive environments. In Forty-first international conference on machine learning, 2024.
- Chen et al. (2026) Junsong Chen, Yuyang Zhao, Jincheng Yu, Ruihang Chu, Junyu Chen, Shuai Yang, Xianbang Wang, Yicheng Pan, Zhou Daquan, Huan Ling, et al. Sana-video: Efficient video generation with block linear diffusion transformer. In International Conference on Learning Representations, volume 2026, pp. 38973–38997, 2026.
- de Lazcano et al. (2024) Rodrigo de Lazcano, Kallinteris Andreas, Jun Jet Tai, Seungjae Ryan Lee, and Jordan Terry. Gymnasium robotics, 2024. URL https://github.com/Farama-Foundation/Gymnasium-Robotics.Source
- Di Palo & Johns (2024) Norman Di Palo and Edward Johns. Keypoint action tokens enable in-context imitation learning in robotics. arXiv preprint arXiv:2403.19578, 2024.
- Ding et al. (2026) Jian Ding, Xianjie Dai, Roei Herzig, Nussair Hroub, Jinjie Mai, Dengxin Dai, Bernard Ghanem, and Mohamed Elhoseiny. Contextflow: In-context flow matching for robot manipulation. arXiv preprint arXiv:2609.06852, 2026.
- Feng et al. (2025) Tuo Feng, Wenguan Wang, and Yi Yang. A survey of world models for autonomous driving. arXiv preprint arXiv:2501.11260, 2025.
- Finn et al. (2016) Chelsea Finn, Xin Yu Tan, Yan Duan, Trevor Darrell, Sergey Levine, and Pieter Abbeel. Deep spatial autoencoders for visuomotor learning. In 2016 IEEE International conference on robotics and automation (ICRA), pp. 512–519. IEEE, 2016.
- Foo et al. (2026) Lin Geng Foo, Mark He Huang, Alexandros Lattas, Stylianos Moschoglou, Thabo Beeler, and Christian Theobalt. Physical simulator in-the-loop video generation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pp. 4301–4311, 2026.
- Fu et al. (2024) Letian Fu, Huang Huang, Gaurav Datta, Lawrence Yunliang Chen, William Chung-Ho Panitch, Fangchen Liu, Hui Li, and Ken Goldberg. In-context imitation learning via next-token prediction. arXiv preprint arXiv:2408.15980, 2024.
- Gao et al. (2026) Shenyuan Gao, William Liang, Kaiyuan Zheng, Ayaan Malik, Seonghyeon Ye, Sihyun Yu, Wei-Cheng Tseng, Yuzhu Dong, Kaichun Mo, Chen-Hsuan Lin, et al. Dreamdojo: A generalist robot world model from large-scale human videos. arXiv preprint arXiv:2602.06949, 2026.
- Guo et al. (2026) Yanjiang Guo, Lucy Shi, Jianyu Chen, and Chelsea Finn. Ctrl-world: A controllable generative world model for robot manipulation. In International Conference on Learning Representations, volume 2026, pp. 6121–6138, 2026.
- Hafner et al. (2019) Danijar Hafner, Timothy Lillicrap, Ian Fischer, Ruben Villegas, David Ha, Honglak Lee, and James Davidson. Learning latent dynamics for planning from pixels. In International conference on machine learning, pp. 2555–2565. PMLR, 2019.
- Hansen et al. (2022) Nicklas Hansen, Xiaolong Wang, and Hao Su. Temporal difference learning for model predictive control. arXiv preprint arXiv:2203.04955, 2022.
- Hou et al. (2026) Bohan Hou, Gen Li, Jindou Jia, Tuo An, Xinying Guo, Sicong Leng, Haoran Geng, Yanjie Ze, Tatsuya Harada, Philip Torr, et al. World model for robot learning: A comprehensive survey. arXiv preprint arXiv:2605.00080, 2026.
- Hwang et al. (2024) Minyoung Hwang, Luca Weihs, Chanwoo Park, Kimin Lee, Aniruddha Kembhavi, and Kiana Ehsani. Promptable behaviors: Personalizing multi-objective rewards from human preferences. In 2024 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), pp. 16216–16226. IEEE, 2024.
- Kumar et al. (2021) Ashish Kumar, Zipeng Fu, Deepak Pathak, and Jitendra Malik. Rma: Rapid motor adaptation for legged robots. arXiv preprint arXiv:2107.04034, 2021.
- Lee et al. (2023) Jonathan Lee, Annie Xie, Aldo Pacchiano, Yash Chandak, Chelsea Finn, Ofir Nachum, and Emma Brunskill. Supervised pretraining can learn in-context reinforcement learning. Advances in Neural Information Processing Systems, 36:43057–43083, 2023.
- Lee et al. (2020) Joonho Lee, Jemin Hwangbo, Lorenz Wellhausen, Vladlen Koltun, and Marco Hutter. Learning quadrupedal locomotion over challenging terrain. Science robotics, 5(47):eabc5986, 2020.
- Li et al. (2025a) Chenyu Li, Oscar Michel, Xichen Pan, Sainan Liu, Mike Roberts, and Saining Xie. Pisa experiments: Exploring physics post-training for video diffusion models by watching stuff drop. arXiv preprint arXiv:2503.09595, 2025a.
- Li et al. (2025b) Wenxuan Li, Hang Zhao, Zhiyuan Yu, Yu Du, Qin Zou, Ruizhen Hu, and Kai Xu. Pin-wm: Learning physics-informed world models for non-prehensile manipulation. arXiv preprint arXiv:2504.16693, 2025b.
- Li et al. (2025c) Xinqing Li, Xin He, Le Zhang, Min Wu, Xiaoli Li, and Yun Liu. A comprehensive survey on world models for embodied ai. arXiv preprint arXiv:2510.16732, 2025c.
- Liu et al. (2026) Chang Liu, Fei Suo, Yanzhou Jin, Zeyu Ping, Yusuke Iwasawa, Yutaka Matsuo, and Yaonan Zhu. Temporally centered sigreg improves leworldmodel representations for robot policy learning, 2026. URL https://arxiv.org/abs/2607.26924.Source
- Liu et al. (2025) Min Liu, Deepak Pathak, and Ananye Agarwal. Locoformer: Generalist locomotion via long-context adaptation. arXiv preprint arXiv:2509.23745, 2025.
- Liu et al. (2024) Shaowei Liu, Zhongzheng Ren, Saurabh Gupta, and Shenlong Wang. Physgen: Rigid-body physics-grounded image-to-video generation. In European Conference on Computer Vision, pp. 360–378. Springer, 2024.
- Lu et al. (2023) Chris Lu, Yannick Schroecker, Albert Gu, Emilio Parisotto, Jakob Foerster, Satinder Singh, and Feryal Behbahani. Structured state space models for in-context reinforcement learning. Advances in Neural Information Processing Systems, 36:47016–47031, 2023.
- Luo & Du (2025) Yunhao Luo and Yilun Du. Grounding video models to actions through goal conditioned exploration. In International Conference on Learning Representations, volume 2025, pp. 92200–92232, 2025.
- Maes et al. (2026) Lucas Maes, Quentin Le Lidec, Damien Scieur, Yann LeCun, and Randall Balestriero. Leworldmodel: Stable end-to-end joint-embedding predictive architecture from pixels. arXiv preprint arXiv:2603.19312, 2026.
- Meng et al. (2024) Fanqing Meng, Jiaqi Liao, Xinyu Tan, Wenqi Shao, Quanfeng Lu, Kaipeng Zhang, Yu Cheng, Dianqi Li, Yu Qiao, and Ping Luo. Towards world simulator: Crafting physical commonsense-based benchmark for video generation. arXiv preprint arXiv:2410.05363, 2024.
- Motamed et al. (2026) Saman Motamed, Laura Culp, Kevin Swersky, Priyank Jaini, and Robert Geirhos. Do generative video models understand physical principles? In 2026 IEEE/CVF Winter Conference on Applications of Computer Vision (WACV), pp. 948–958. IEEE, 2026.
- Oquab et al. (2023) Maxime Oquab, Timothée Darcet, Théo Moutakanni, Huy Vo, Marc Szafraniec, Vasil Khalidov, Pierre Fernandez, Daniel Haziza, Francisco Massa, Alaaeldin El-Nouby, et al. Dinov2: Learning robust visual features without supervision. arXiv preprint arXiv:2304.07193, 2023.
- (36) Fabian Otto, Onur Celik, Dominik Roth, and Hongyi Zhou. Fancy gym. URL https://github.com/ALRhub/fancy_gym.Source
- Quevedo et al. (2026) Julian Quevedo, Ansh Kumar Sharma, Yixiang Sun, Varad Suryavanshi, Percy Liang, and Sherry Yang. Worldgym: World model as an environment for policy evaluation. In International Conference on Learning Representations, volume 2026, pp. 78932–78957, 2026.
- Saxena et al. (2026) Vaibhav Saxena, Yunhao Luo, Yotto Koga, and Danfei Xu. Nostra: Enabling robust robot imitation via multimodal latent imagination. IEEE Robotics and Automation Letters, 2026.
- Seedance et al. (2026) Team Seedance, De Chen, Liyang Chen, Xin Chen, Ying Chen, Zhuo Chen, Zhuowei Chen, Feng Cheng, Tianheng Cheng, Yufeng Cheng, et al. Seedance 2.0: Advancing video generation for world complexity. arXiv preprint arXiv:2604.14148, 2026.
- Seo et al. (2023) Younggyo Seo, Danijar Hafner, Hao Liu, Fangchen Liu, Stephen James, Kimin Lee, and Pieter Abbeel. Masked world models for visual control. In Conference on Robot Learning, pp. 1332–1344. PMLR, 2023.
- Shah et al. (2025) Rutav Shah, Shuijing Liu, Qi Wang, Zhenyu Jiang, Sateesh Kumar, Mingyo Seo, Roberto Martín-Martín, and Yuke Zhu. Mimicdroid: In-context learning for humanoid robot manipulation from human play videos. arXiv preprint arXiv:2509.09769, 2025.
- Tassa et al. (2018) Yuval Tassa, Yotam Doron, Alistair Muldal, Tom Erez, Yazhe Li, Diego de Las Casas, David Budden, Abbas Abdolmaleki, Josh Merel, Andrew Lefrancq, et al. Deepmind control suite. arXiv preprint arXiv:1801.00690, 2018.
- Team et al. (2025) Gemini Robotics Team, Krzysztof Choromanski, Coline Devin, Yilun Du, Debidatta Dwibedi, Ruiqi Gao, Abhishek Jindal, Thomas Kipf, Sean Kirmani, Isabel Leal, et al. Evaluating gemini robotics policies in a veo world simulator. arXiv preprint arXiv:2512.10675, 2025.
- Team et al. (2026) Robbyant Team, Zelin Gao, Qiuyu Wang, Yanhong Zeng, Jiapeng Zhu, Ka Leong Cheng, Yixuan Li, Hanlin Wang, Yinghao Xu, Shuailei Ma, et al. Advancing open-source world models. arXiv preprint arXiv:2601.20540, 2026.
- Tseng et al. (2025) Wei-Cheng Tseng, Jinwei Gu, Qinsheng Zhang, Hanzi Mao, Ming-Yu Liu, Florian Shkurti, and Lin Yen-Chen. Scalable policy evaluation with video world models. arXiv preprint arXiv:2511.11520, 2025.
- Upadhyay et al. (2026) Rishi Upadhyay, Howard Zhang, Jim Solomon, Ayush Agrawal, Pranay Boreddy, Shruti Satya Narayana, Yunhao Ba, Alex Wong, Celso M de Melo, and Achuta Kadambi. Worldbench: Disambiguating physics for diagnostic evaluation of world models. arXiv preprint arXiv:2601.21282, 2026.
- Vosylius & Johns (2025) Vitalis Vosylius and Edward Johns. Instant policy: In-context imitation learning via graph diffusion. In International Conference on Learning Representations, volume 2025, pp. 35011–35030, 2025.
- Wan et al. (2025) Team Wan, Ang Wang, Baole Ai, Bin Wen, Chaojie Mao, Chen-Wei Xie, Di Chen, Feiwu Yu, Haiming Zhao, Jianxiao Yang, et al. Wan: Open and advanced large-scale video generative models. arXiv preprint arXiv:2503.20314, 2025.
- Wang et al. (2026a) Chen Wang, Chuhao Chen, Yiming Huang, Zhiyang Dou, Yuan Liu, Jiatao Gu, and Lingjie Liu. Physctrl: Generative physics for controllable and physics-grounded video generation. Advances in Neural Information Processing Systems, 38:167907–167932, 2026a.
- Wang et al. (2026b) Jing Wang, Ao Ma, Ke Cao, Jun Zheng, Jiasong Feng, Zhanjie Zhang, Wanyuan Pang, and Xiaodan Liang. Wisa: World simulator assistant for physics-aware text-to-video generation. Advances in Neural Information Processing Systems, 38:5388–5416, 2026b.
- Wang et al. (2026c) Meizhong Wang, Wanxin Jin, Kun Cao, Lihua Xie, and Yiguang Hong. Contactgaussian-wm: Learning physics-grounded world model from videos. arXiv preprint arXiv:2602.11021, 2026c.
- Wang et al. (2026d) Ying Wang, Oumayma Bounou, Gaoyue Zhou, Randall Balestriero, Tim GJ Rudner, Yann LeCun, and Mengye Ren. Temporal straightening for latent planning. arXiv preprint arXiv:2603.12231, 2026d.
- Wang et al. (2026e) Yixuan Wang, Rhythm Syed, Fangyu Wu, Mengchao Zhang, Aykut Onol, Jose Barreiros, Hooshang Nayyeri, Tony Dear, Huan Zhang, and Yunzhu Li. Interactive world simulator for robot policy training and evaluation. arXiv preprint arXiv:2603.08546, 2026e.
- Wang et al. (2024) Yuqi Wang, Jiawei He, Lue Fan, Hongxin Li, Yuntao Chen, and Zhaoxiang Zhang. Driving into the future: Multiview visual forecasting and planning with world model for autonomous driving. In 2024 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), pp. 14749–14759. IEEE, 2024.
- Wu et al. (2015) Jiajun Wu, Ilker Yildirim, Joseph J Lim, Bill Freeman, and Josh Tenenbaum. Galileo: Perceiving physical object properties by integrating a physics engine with deep learning. Advances in neural information processing systems, 28, 2015.
- Wu et al. (2023) Philipp Wu, Alejandro Escontrela, Danijar Hafner, Pieter Abbeel, and Ken Goldberg. Daydreamer: World models for physical robot learning. In Conference on robot learning, pp. 2226–2240. PMLR, 2023.
- Xie et al. (2025) Tianyi Xie, Yiwei Zhao, Ying Jiang, and Chenfanfu Jiang. Physanimator: Physics-guided generative cartoon animation. In 2025 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), pp. 10793–10804. IEEE, 2025.
- Xue et al. (2025) Qiyao Xue, Xiangyu Yin, Boyuan Yang, and Wei Gao. Phyt2v: Llm-guided iterative self-refinement for physics-grounded text-to-video generation. In 2025 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), pp. 18826–18836. IEEE, 2025.
- Yang et al. (2023) Sherry Yang, Yilun Du, Kamyar Ghasemipour, Jonathan Tompson, Leslie Kaelbling, Dale Schuurmans, and Pieter Abbeel. Learning interactive real-world simulators. arXiv preprint arXiv:2310.06114, 2023.
- Yang et al. (2026) Yuncong Yang, Zhengtao Han, Furkan Ozyurt, Zeyuan Yang, Han Yang, Junyi Cao, Haoyu Zhen, Yilun Du, and Chuang Gan. Syncworld: Visual calibration enables world models as zero-shot simulators. arXiv preprint arXiv:2609.09155, 2026.
- Yang et al. (2025) Zhuoyi Yang, Jiayan Teng, Wendi Zheng, Ming Ding, Shiyu Huang, Jiazheng Xu, Yuanming Yang, Wenyi Hong, Xiaohan Zhang, Guanyu Feng, et al. Cogvideox: Text-to-video diffusion models with an expert transformer. In International Conference on Learning Representations, volume 2025, pp. 83048–83077, 2025.
- Yu et al. (2017) Wenhao Yu, Jie Tan, C Karen Liu, and Greg Turk. Preparing for the unknown: Learning a universal policy with online system identification. arXiv preprint arXiv:1702.02453, 2017.
- Yuan et al. (2026) Yu Yuan, Xijun Wang, Tharindu Wickremasinghe, Zeeshan Nadir, Bole Ma, and Stanley Chan. Newtongen: Physics-consistent and controllable text-to-video generation via neural newtonian dynamics. In International Conference on Learning Representations, volume 2026, pp. 12847–12878, 2026.
- Zhang et al. (2026a) Qiyuan Zhang, Biao Gong, Shuai Tan, Zheng Zhang, Yujun Shen, Xing Zhu, Yuyuan Li, Kelu Yao, Chunhua Shen, and Changqing Zou. Physrvg: Physics-aware unified reinforcement learning for video generative models. arXiv preprint arXiv:2601.11087, 2026a.
- Zhang et al. (2024) Tianyuan Zhang, Hong-Xing Yu, Rundi Wu, Brandon Y Feng, Changxi Zheng, Noah Snavely, Jiajun Wu, and William T Freeman. Physdreamer: Physics-based interaction with 3d objects via video generation. In European Conference on Computer Vision, pp. 388–406. Springer, 2024.
- Zhang et al. (2026b) Xiangdong Zhang, Jiaqi Liao, Shaofeng Zhang, Fanqing Meng, Xiangpeng Wan, Junchi Yan, and Yu Cheng. Videorepa: Learning physics for video generation through relational alignment with foundation models. Advances in Neural Information Processing Systems, 38:122647–122676, 2026b.
- Zhang et al. (2025) Xilun Zhang, Shiqi Liu, Peide Huang, William Jongwon Han, Yiqi Lyu, Mengdi Xu, and Ding Zhao. Dynamics as prompts: In-context learning for sim-to-real system identifications. IEEE Robotics and Automation Letters, 10(4):3190–3197, 2025.
- Zheng et al. (2025) Zangwei Zheng, Xiangyu Peng, Yuxuan Lou, Chenhui Shen, Tom Young, Xinying Guo, Binluo Wang, Hang Xu, Hongxin Liu, Mingyan Jiang, et al. Open-sora 2.0: Training a commercial-level video generation model in \$200 k. arXiv preprint arXiv:2503.09642, 2025.
- Zhou et al. (2025) Gaoyue Zhou, Hengkai Pan, Yann Lecun, and Lerrel Pinto. Dino-wm: World models on pre-trained visual features enable zero-shot planning. In International Conference on Machine Learning, pp. 79115–79135. PMLR, 2025.
In this appendix, we first present our implementation details in Appendix A, such as description of each baseline, model architecture of PhysiCalWorld, hyperparameters, as well as our training and evaluation setups. Next, in Appendix B, we provide detailed description of each environment we used along with environment-specific implementation. Following this, we include additional quantitative results in Appendix C, such as comparison of multiple visual metrics on next-frame prediction and analyses of training and inference speed. Finally, we append additional qualitative results in Appendix D.
In this section, we provide a detailed description for each baseline we used in our paper. Please see the description of each method below:
- a)
DINO-WM (Zhou et al., 2025): We follow the implementation in the official codebase, using a frozen DINOv2 (Oquab et al., 2023) backbone as the visual encoder . The input to the dynamics predictor is an observation-action sequence of steps, including historical transitions alongside the current observation and action. The predictor predicts one-step future observation . Because this baseline receives no in-context interaction prompt, it must infer transition dynamics solely from this local history window. We observe that DINO-WM exhibits severe rollout drift when physical properties vary across test scenes.
- b)
DINO-WM + Context Prefix: This baseline uses the same model architecture and training objective as DINO-WM. The only difference is that it additionally feeds the latent embeddings of the whole in-context interaction prompt to the dynamics predictor . As a result, for this baseline, the total input window size of is . Since transformer self-attention scales quadratically with the number of input tokens, this uncompressed prefix adds substantially more computation to both model training and inference (see Figure 6 and Table A9 for runtime comparisons).
- c)
DINO-WM + Long History: This baseline uses the same model architecture and training objective as DINO-WM. The only difference is that it extends the target observation history from 3 to 15 consecutive frames (i.e., ). The goal of this baseline is to study whether extending history can enable effective physics-calibration in world models.
- d)
LeWM (Maes et al., 2026): LeWM is a latent world model directly trained from scratch (without using frozen pre-trained models like DINOv2), hence it learns task-specific latent visual representations and action-conditioned dynamics. We follow the implementation in its official codebase. Based on LeWM, we also include LeWM + PhysiCal (Ours), where we integrate the proposed physical calibration module into LeWM, to show that our proposed physics calibration method is a plug-and-play module that can potentially extend to any latent world models.
- e)
TC-LeWM (Liu et al., 2026): This method applies SIGReg to temporally centered residuals rather than the full latent distribution, preventing the suppression of fine-grained moving components. We include this to enhance the LeWM baseline, as vanilla LeWM’s latent representations fail to capture the ball in the BeerPong environment (yielding very low IoU and planning success). Similarly, we include TC-LeWM + PhysiCal (Ours) to evaluate whether our proposed method can be applied to this improved LeWM baseline.
- f)
Temporal Straightening (TS-WM) (Wang et al., 2026d): we adopt this TS-WM variant: DINOv2 (patch) + proj configuration with spatial features, as it achieves the strongest overall performance reported in the original paper. Similar to DINO-WM, this variant uses a frozen DINOv2 visual encoder and a causal transformer dynamics predictor, but inserts an additional lightweight projection head between the visual encoder and the predictor. During training, TS-WM introduces a curvature regularizer to enforce a more structured latent representation, and such regularization has demonstrated stronger planning performance. We include this baseline to study whether additional regularization can promote physics grounding in world models.
- g)
DINO-WM + Estimated Physics†: This baseline first estimates the physics configurations of the scenes (e.g., the center of mass in Push-T or the joint damping in Reacher) from a context clip and feeds the estimated value as condition for the dynamics predictor . Specifically, we train a separate physics estimator based on the same context-encoder architecture as our method but use the ground-truth physics labels as supervision. At inference time, the estimated parameters are provided to the dynamics predictor as additional input for conditioning. This baseline compares explicit, supervised physics estimation with our end-to-end in-context calibration method. Note that this baseline requires predefined physics labels for training, while our method does not.
- h)
DINO-WM + Privileged Physics‡: This baseline is based on DINO-WM but can access the ground-truth physics configurations of the scenes during both training and inference. Specifically, the dynamics predictor directly receives these true physical parameters as supplementary inputs alongside standard observation and action tokens.
Our experiments are implemented in Python 3.10 on Red Hat Enterprise Linux 8.10. We train and evaluate our models using NVIDIA L40S GPUs and NVIDIA RTX PRO 6000 Blackwell GPUs interchangeably.
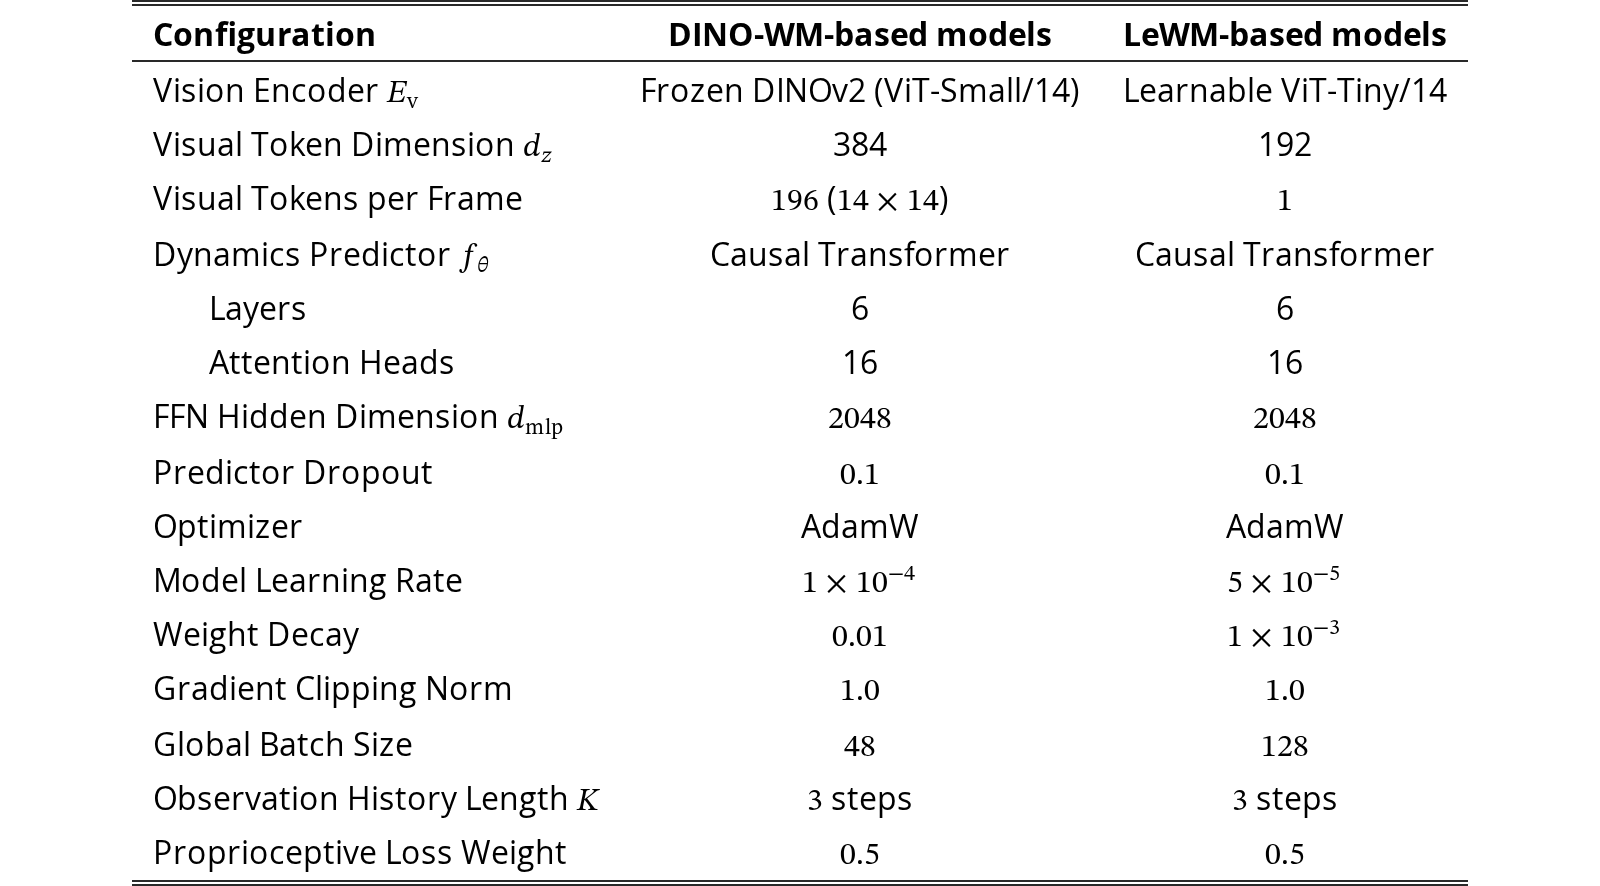
We implemented PhysiCalWorld on two latent world-model backbones, DINO-WM (Zhou et al., 2025) and LeWM (Maes et al., 2026), denoted as DINO-WM+PhysiCal and LeWM+PhysiCal, as in Table 1 and Table 2. The base architecture and optimization hyperparameters used for the two backbones are summarized in Table A1.
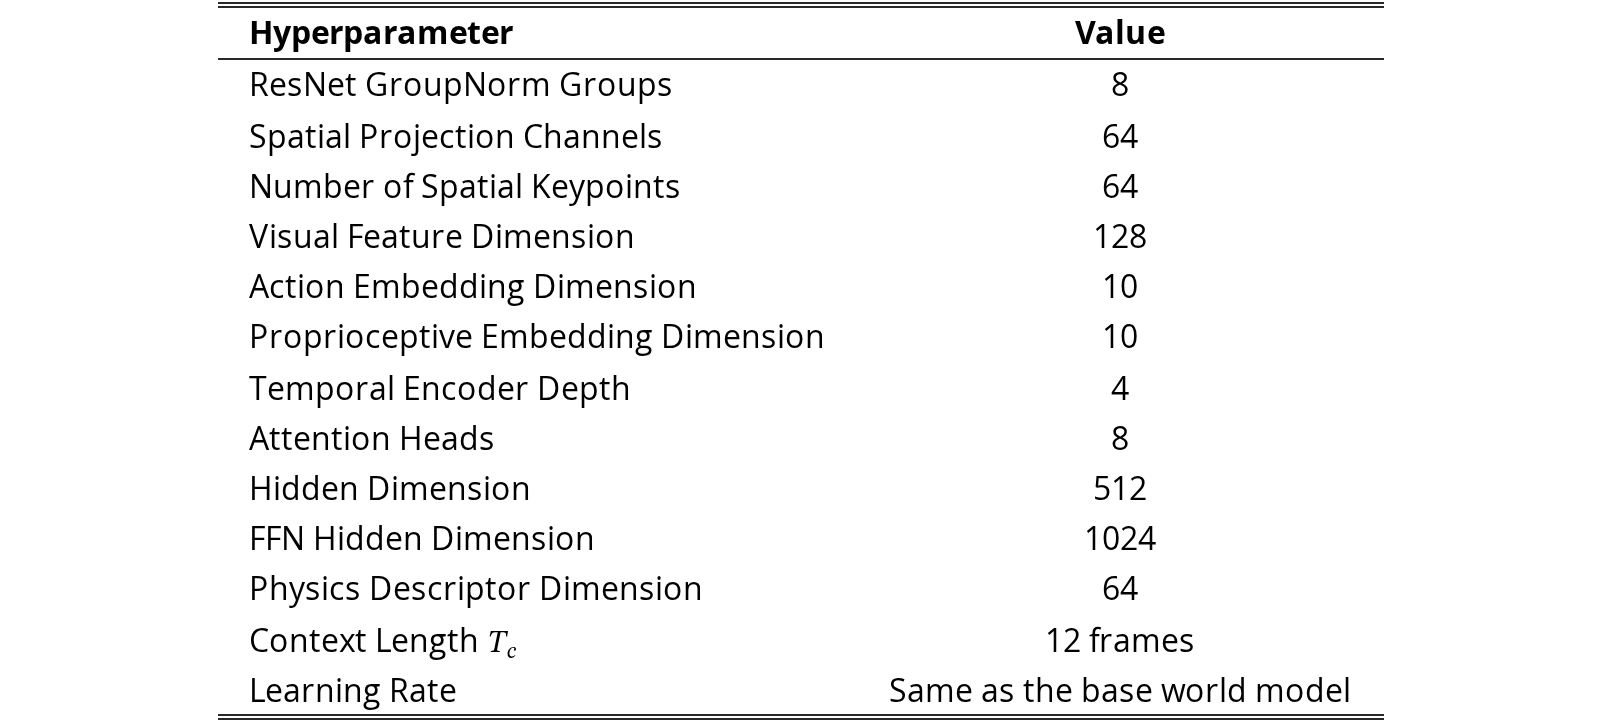
For all our experiments, the context encoder maps a 12-frame () interaction sequence to a 64-dimensional physics descriptor . Each frame is embedded by a ResNet-based visual encoder into 64 two-dimensional keypoints via spatial softmax (Finn et al., 2016). The world model’s input action is embedded by a single linear layer , where denotes the length of the input action chunk and denotes the dimension of a single action. For Push-T, the 4D observable pusher state is additionally embedded by . The resulting per-step features are concatenated channel-wise and mapped to one 512-dimensional latent embedding (i.e., data of each timestep is now represented by one latent embedding). A four-layer Transformer encoder with eight attention heads takes latent embeddings of all timesteps as input and pools them with a learnable token . Finally, the output corresponding to is fed to an MLP , whose output is the physics descriptor token . For simplicity, we set the dimension of to 64 across all our experiments. We summarize the hyperparameters of the context encoder in Table A2.
| Hyperparameter | Value |
| ResNet GroupNorm Groups | 8 |
| Spatial Projection Channels | 64 |
| Number of Spatial Keypoints | 64 |
| Visual Feature Dimension | 128 |
| Action Embedding Dimension | 10 |
| Proprioceptive Embedding Dimension | 10 |
| Temporal Encoder Depth | 4 |
| Attention Heads | 8 |
| Hidden Dimension | 512 |
| FFN Hidden Dimension | 1024 |
| Physics Descriptor Dimension | 64 |
| Context Length | 12 frames |
| Learning Rate | Same as the base world model |
View original table
For each prediction segment sampled from a physical-configuration group , we independently sample the interaction context from a different episode in the same group. Thus, the context shares the same underlying physical dynamics as the prediction target without containing trajectory-specific future observations. All contexts contain observations sampled at the model prediction gap of the corresponding world model.
For Push-T and Reacher, we uniformly sample the -frame context window within a prompt episode. That 12-frame clip typically spans a few seconds. For BeerPong, we sample the context from the beginning of the episode, such that the context contains both the initial release status and ball-table interaction that reveals the contact damping. Similarly, for FetchSlide, we also start the context from the beginning of each episode to include the initial robot-puck interaction sequence and also because episodes in FetchSlide are relatively short. If the in-context prompt episode has fewer than frames, we pad the context to length by repeating the final available frame.
For DINO-WM+PhysiCal, is broadcast across all spatial patches and temporal steps and concatenated with the predictor features along the channel dimension. For LeWM+PhysiCal, the 64-dimensional descriptor is concatenated with the 192-dimensional per-step latent representation before feeding into the causal future predictor , while action conditioning follows the original LeWM implementation through AdaLN-zero.
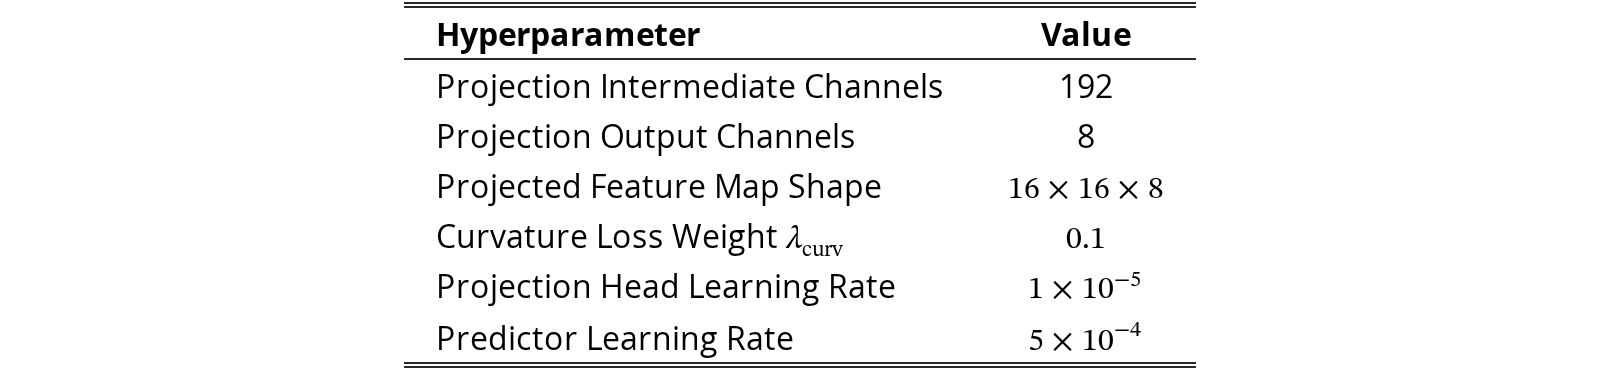
For Temporal Straightening (TS-WM) (Wang et al., 2026d), we follow the original implementation and use the DINOv2 (patch) + projection configuration with the default curvature regularization and optimization settings given by the authors, as it is the best-performing model reported in the original paper. We summarize the corresponding hyperparameters in Table A3.
| Hyperparameter | Value |
| Projection Intermediate Channels | 192 |
| Projection Output Channels | 8 |
| Projected Feature Map Shape | |
| Curvature Loss Weight | |
| Projection Head Learning Rate | |
| Predictor Learning Rate |
View original table
We present the pseudocode for training PhysiCalWorld in Algorithm 1, which is also described in Section 3.2. Training PhysiCalWorld requires neither ground-truth physics labels nor an analytical dynamics model; the only supervision structure it consumes is the group partition of the dataset (where data collected within environments sharing identical physics are grouped together).
Hence, unlike Estimated Physics† or Privileged Physics‡, PhysiCalWorld learns to calibrate directly from the dynamics patterns in the data: it does not need to know which physics properties actually govern the transition dynamics nor their corresponding values. Because every episode in shares the same underlying transition dynamics , if both the context prompt and the train target segment are sampled from the same group, context encoder can minimize the prediction loss by encoding context-specific physical dynamics from the prompt into . Note that we draw the interaction prompt from an episode distinct from the trajectory segment used for future prediction so as to prevent the prompt from carrying information about the future.
During training, the predictor is teacher-forced on the visual encoder representations under causal masking (e.g., cannot attend to ), with prediction loss gradients flowing jointly into both and . The visual decoder is trained separately using an reconstruction loss to map predicted latents back to pixel-space images.
We outline the procedure for open-loop rollout inference with PhysiCalWorld in Algorithm 2, as detailed in Section 3.3. At test time, the descriptor is extracted once prior to the rollout loop and subsequently held fixed. Inside the loop, autoregressive rollout runs similarly to the base world model except for the addition of the conditioning physics descriptor token, preserving per-step latency at the level of the unconditioned base predictor (Appendix C.4). Latent-to-pixel decoding through is only required for visual evaluation; our visual planning directly operates in the latent space, .
Following DINO-WM (Zhou et al., 2025), we employ the Cross-Entropy Method (CEM) for zero-shot visual latent planning (see Algorithm 3 for pseudocode). Given the current observation and the goal observation , both represented as RGB images, we first encode them into latent space via the visual encoder , namely and . We first collect an interaction clip as the context, either through purely random actions or a task-agnostic policy for ensuring sufficient contacts. We then extract the physics descriptor token of the test scene . As within each planning task, the physics configuration of the scene is constant, we can use the same across all the CEM iterations of one task, reducing the planning time.
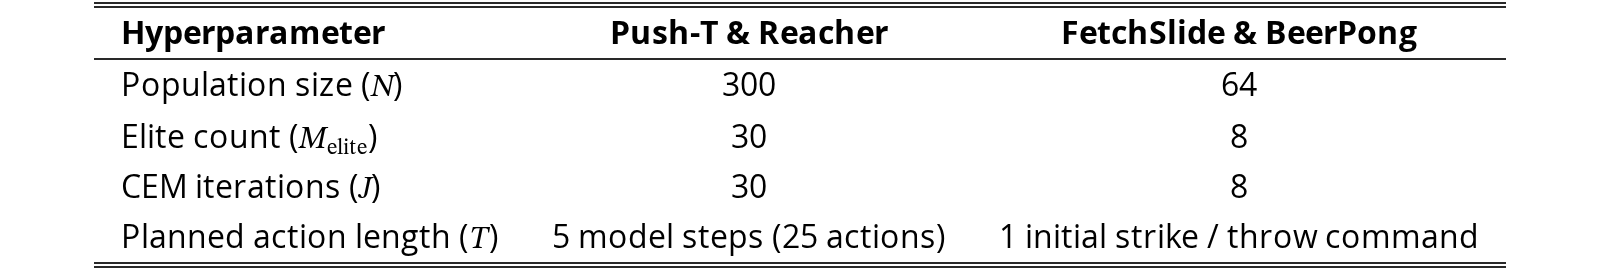
At each CEM iteration, we sample (e.g., ) candidate action sequences of horizon from a Gaussian distribution that is independent across time steps and action dimensions, parameterized by a mean and a standard deviation (initialized to ), where is the action dimension. For each candidate sequence, we unroll the physics-calibrated world model autoregressively in the latent space and evaluate the corresponding cost , which we define as the mean squared error (MSE) between the final predicted latent and the goal latent , as in Line 17. We then select the top (e.g., ) action sequences with the lowest costs and refit and to their element-wise mean and standard deviation. After optimization iterations (e.g., ), the planner outputs the updated elite-mean action sequence . We then execute in the environment. See Table A4 for the CEM hyperparameters in each environment.
| Hyperparameter | Push-T & Reacher | FetchSlide & BeerPong |
| Population size () | 300 | 64 |
| Elite count () | 30 | 8 |
| CEM iterations () | 30 | 8 |
| Planned action length () | 5 model steps (25 actions) | 1 initial strike / throw command |
View original table
In this section, we provide detailed descriptions of our experiments in each environment, including environment setup, training and evaluation details. Table A5 summarizes the dataset scale and hyperparameters of the world models in each environment. The resolution of the image observation is for all four environments.
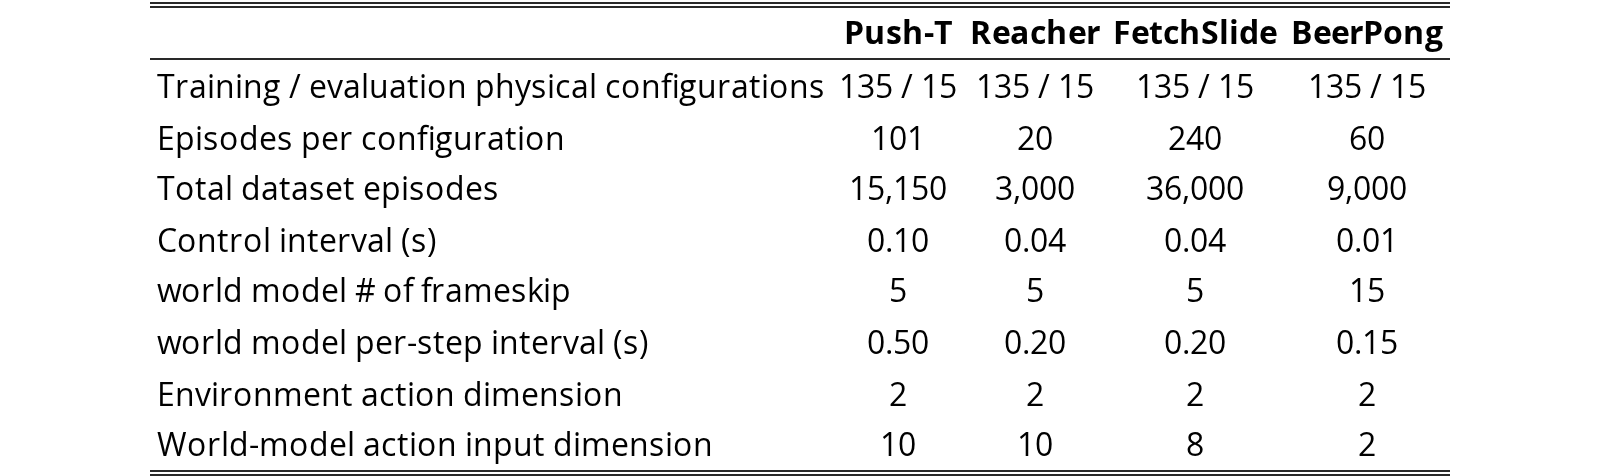
Push-T is a planar manipulation task in a pixel workspace, where a circular pusher of radius 15 pixels moves a rigid T-shaped block toward a goal configuration specified by an RGB image. The block consists of a pixel crossbar and a pixel stem. We uniformly sample the block’s local center of mass (CoM) inside its T-shaped interior and hold it fixed within each episode. Changing the CoM changes the moment arms of contact forces and the resulting translational and rotational response, while the block appearance remains fixed.
The dataset contains 150 CoM configurations, with 135 used for training and 15 held out for evaluation, totaling 15,150 episodes with 101 episodes per configuration. We train a CoM-agnostic PPO policy that targets pushing the T-block to the light-green area and use this policy to collect trajectories for training, since a random policy cannot ensure sufficient and meaningful interaction. In theory, any policy that produces sufficient contacts can serve as the data-collection policy. Each raw action specifies an absolute 2D pusher target in simulator pixel coordinates, tracked by a PD controller at a control frequency of 10 Hz. Following Zhou et al. (2025), we inject independent Gaussian noise into the output action during policy execution. The noise uses ten different standard deviations: pixels. This online noise injection enhances dataset coverage and generalization, which is particularly essential for downstream planning using CEM, as its initial optimization phase relies heavily on exploring noisy action trajectories. We subsample observations every 5 control steps and concatenate the 5 2D actions in between into a stacked 10D action. We use this 10D action as the input to the world models, yielding a prediction interval of 0.5 seconds. Models receive RGB images and a 4D pusher proprioceptive input , whose velocity entries are zero-filled so that only poisition information is provided.
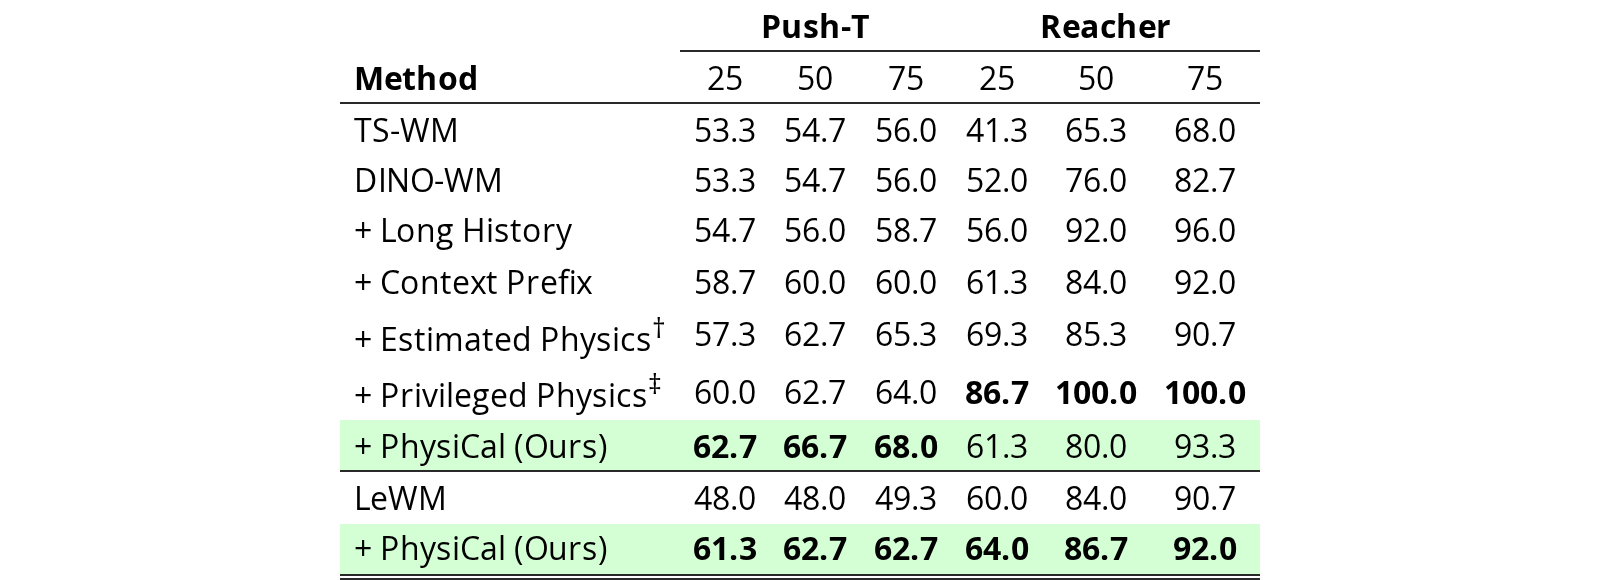
Please see Table A1, Table A2, and Table A3 for detailed model hyperparameters, and Table A8 for training wall-clock durations. Visual prediction IoU is computed on the union of the agent and block foreground masks. Each planning task pairs a single current observation with a goal observation recorded 15 control steps later in the same trajectory. Success requires the Euclidean position error over the concatenated agent and block coordinates to be below 20 pixels and the wrapped block-orientation error to be below (). For open-loop execution, we set the planning horizon to 25 control steps (i.e., 5-step future prediction in the world model). In Table 1, we report the success rate under this fixed 25-step budget when directly executing the planned action sequence from the initial observation. To leverage the world model for dynamic planning, we also experiment with model predictive control (MPC), in which the model actively replans if the task has not succeeded. Table A7 evaluates cumulative success rates with at most two replans (i.e., budgets of 25, 50, and 75 control steps). We observe that the success rate of our method consistently increases with larger step budgets, as iterative replanning allows for continuous error correction.
We modify the Reacher environment from the DeepMind Control Suite (Tassa et al., 2018), where a planar two-link arm moves toward a goal configuration specified by an RGB image. The proximal and distal links have lengths of 0.12 and 0.10 meters, respectively. We vary the two joint damping coefficients over using Latin-hypercube sampling and hold them fixed within each episode. Changing joint damping alters the two-link arm’s resistance to motion without changing the visual appearance.
The dataset contains 150 joint-damping configurations, with 135 used for training and 15 held out for evaluation, totaling 3,000 episodes with 20 episodes per configuration. Each episode contains 100 control steps and starts from randomly sampled joint angles with zero initial joint velocities. Unlike Push-T, random torque commands naturally induce diverse joint motions and provide broad coverage of the joint-state and velocity space, so no task-specific data-collection policy is required. Each 2D action is sampled independently from and specifies normalized motor commands corresponding to joint torques in . Each command is held for two 0.02-second simulation steps, giving a control frequency of 25 Hz. Similar to Push-T, we subsample observations every 5 control steps and concatenate the five intervening 2D actions into a 10D world-model action, yielding a prediction interval of 0.2 seconds. Unlike Push-T, Reacher does not provide proprioception inputs.
Visual prediction IoU is computed on the union of the two arm links’ foreground masks. Each planning task pairs a single current observation with a goal observation recorded 25 control steps later in the same trajectory. Success requires the angular error of each joint to be below ( radians). Similar to Push-T, we use a 25-control-step planning horizon (i.e., 5-step future prediction in the world model), and report the 25-step budget planning result in Table 1. We additionally evaluate MPC with at most two replans, yielding cumulative budgets of 25, 50, and 75 control steps, as reported in Table A7. Note that repeated replanning substantially reduces the effect of accumulated model error in Reacher, allowing even imperfect models to iteratively approach the target and resulting in high MPC success rates. We observed that LeWM-based models perform particularly well on Reacher, which may be attributed to its encoder being task-specific and able to focus on essential structures such as the angles of the joints, whereas DINOv2 is trained as a general-purpose image encoder.
We modify the BeerPong environment from Fancy Gym (Otto et al.,), where a simulated Barrett Whole-Arm Manipulator (WAM) throws a ball toward a cup across a table. We omit an explicit gripper and instead kinematically attach the ball to the end effector during the first five control steps, after which it is released with the end effector’s instantaneous velocity. The robot starts from a fixed configuration, while the cup position is sampled along the table’s central axis and remains fixed within each episode. We uniformly sample the ball-contact damping parameter over and hold it fixed within each episode. This changes energy dissipation during contact and the resulting bounce trajectory without changing visual appearance. We empirically choose the contact-damping range as lower values produce insufficient rebound while higher values lead to excessively unstable ball trajectories. With damping parameter inside this range, most episodes are physically feasible, with some throws capable of making the ball reach the cup after one or two bounces on the table. The table measures approximately meters, the cup has an inner radius of 0.10 meters, and the ball has a radius of 0.049 meters and a mass of 0.10 kilograms.
The dataset contains 150 contact-damping configurations, with 135 used for training and 15 held out for evaluation, totaling 9,000 episodes with 60 episodes per configuration. Each episode contains 300 control steps. A 2D throw command is sampled uniformly from for forward end-effector velocity and for upward end-effector velocity. After releasing the ball, the robot arm retracts to a fixed configuration to prevent its post-throw pose from leaking information about the throw command. Each control step spans two 0.005-second simulation steps, giving a control frequency of 100 Hz. We subsample observations every 15 control steps, yielding a prediction interval of 0.15 seconds (the time gap between two predicted frames by the world model). Since the robot actions cannot affect the ball after the robot releases the ball, we provide the normalized 2D throw command as the world model’s action input at every prediction step, both before and after the release. The world models receive RGB images without proprioception inputs.
Visual prediction IoU is computed on the ball’s foreground mask. Each planning task consists of a single initial observation and a final observation of a successful in-cup throw (i.e., an image in which the ball is inside the cup). The success criterion is that the ball can be thrown inside the cup and stay in the cup. We evaluate each method on 75 shared targets, where all planning tasks share the same initial robot and ball configuration and differ in the randomly sampled cup position and the table contact damping of the held-out configuration. Different from Push-T and Reacher, BeerPong is a one-shot planning task, in which the planner optimizes a single 2D throw command.
We modify the FetchSlide-v4 environment from Gymnasium Robotics (de Lazcano et al., 2024), where a Fetch manipulator strikes a cylindrical puck toward a goal position on a table. The puck has a radius of 0.05 meters and a height of 0.04 meters. We independently sample puck mass , surface friction , and fluid density from uniform distributions and hold them fixed within each episode. These numbers are selected under the principles that the environments can remain valid. For example, if we set the upper limit of the surface friction to a very large value, in most of the cases, the puck might simply stop very quickly, resulting in tiny difference between different environments.
At a high level, the interplay between these physics properties can be described as follows. For the same strike action, lower puck mass results in a higher post-strike velocity. The subsequent puck’s deceleration depends jointly on surface friction and aerodynamic drag, where stronger friction and higher fluid density will increase deceleration rate. In addition, since we do not vary the shape of the puck, given the same air density, a puck of larger mass will decelerate slower compared to a lighter puck.
The dataset contains 150 physical configurations, with 135 used for training and 15 held out for evaluation, totaling 36,000 episodes with 240 episodes per configuration. Each strike is specified by a 2D action sampled uniformly from .
Following the original setting of FetchSlide-v4 (de Lazcano et al., 2024), action is expanded into a 4D Cartesian command , where the first three components specify end-effector displacement and the final component controls the gripper, which is always closed. The same command is applied for the first two control steps. Each control step spans 0.04 seconds. We subsample observations every five control steps, yielding a prediction interval of 0.2 seconds, and concatenate the two initial 4D commands into a normalized 8D condition provided at every world-model step. After striking the puck, the robot arm moves to a fixed position to prevent information leakage from the post-strike pose. Models receive RGB images without proprioception input.
Visual prediction IoU is computed on the puck’s foreground mask. All planning tasks share the same initial robot and puck configuration and differ only in the target puck position. Similar to BeerPong, FetchSlide is a one-shot planning task, where the planner optimizes a single 2D strike command, after which the puck will move on the tabletop until it stops, without additional intervention from the robot. We evaluate all methods across a shared benchmark of 75 planning targets, defining the success of one target when the final puck position lies within Euclidean distance of the target position on the table.
We first present performance comparison of next-frame prediction in Section C.1, where we conduct teacher-forcing style evaluation (only score the immediate next frame when computing the metrics), complementing the open-loop rollout evaluation presented in the main paper. Then, we show the planning task success rates over more replanning budgets in Section C.2. Following this, we present the training time and inference time comparison of each method in Section C.3 and Section C.4, respectively. Finally, we report how different success thresholds will affect the planning success rate in Section C.5.
We provide additional next-frame prediction results on all four environments in Table A6. We report PSNR, SSIM, LPIPS, and foreground IoU to evaluate both pixel-level reconstruction quality and foreground prediction accuracy. Across all four environments, incorporating PhysiCal consistently improves the next-frame prediction performance of both DINO-WM and LeWM.
Following DINO-WM (Zhou et al., 2025), in addition to the open-loop CEM planning, we also evaluate model predictive control (MPC), where the model replans from the newly observed state after executing a sequence of optimized actions. Specifically, in Push-T and Reacher, CEM optimizes an action sequence spanning 25 control steps (i.e., 5 world model steps due to action stacking) using the world model. The full sequence is then executed in the environment. If this action sequence cannot complete the task, we replan an additional 25 control steps. We allow at most two additional replans, corresponding to maximum 25, 50, and 75 control steps.
The result is shown in Table A7. +PhysiCal consistently improves performance on Push-T under all maximum numbers of control steps, showing that the performance of our method can scale with additional compute. In Reacher, +PhysiCal shows a strong advantage over context-free baselines after the first 25 execution steps. However, the gap narrows after replanning because the task is highly feedback-correctable and the structure of the task is relatively easy (only consisting of two rotary joints), allowing MPC to quickly compensate for systematic model bias.
| Push-T | Reacher | |||||
| Method | 25 | 50 | 75 | 25 | 50 | 75 |
| TS-WM | 53.3 | 54.7 | 56.0 | 41.3 | 65.3 | 68.0 |
| DINO-WM | 53.3 | 54.7 | 56.0 | 52.0 | 76.0 | 82.7 |
| + Long History | 54.7 | 56.0 | 58.7 | 56.0 | 92.0 | 96.0 |
| + Context Prefix | 58.7 | 60.0 | 60.0 | 61.3 | 84.0 | 92.0 |
| + Estimated Physics† | 57.3 | 62.7 | 65.3 | 69.3 | 85.3 | 90.7 |
| + Privileged Physics‡ | 60.0 | 62.7 | 64.0 | 86.7 | 100.0 | 100.0 |
| + PhysiCal (Ours) | 62.7 | 66.7 | 68.0 | 61.3 | 80.0 | 93.3 |
| LeWM | 48.0 | 48.0 | 49.3 | 60.0 | 84.0 | 90.7 |
| + PhysiCal (Ours) | 61.3 | 62.7 | 62.7 | 64.0 | 86.7 | 92.0 |
View original table
We report the training time for all world models evaluated in this work, comparing the number of epochs, GPU configurations, and wall-clock training hours across tasks. We use two types of GPUs: L40S denotes NVIDIA L40S, and PRO 6000 denotes NVIDIA RTX PRO 6000.
As shown in Table A8, for DINO-WM based models, though our method introduces around 11% additional training cost over the vanilla DINO-WM on Push-T, the training speed of +PhysiCal remains faster compared to the Long History and Context Prefix models. Due to the significantly higher training time for the Long History and Context Prefix models, for fair comparison, we align their GPU hours spent on training with other methods. Specifically, for Long History we trained only 5 epochs in Push-T, and for Context Prefix we trained only 5 epochs in Push-T, 12 epochs in Reacher and 3 epochs in BeerPong.
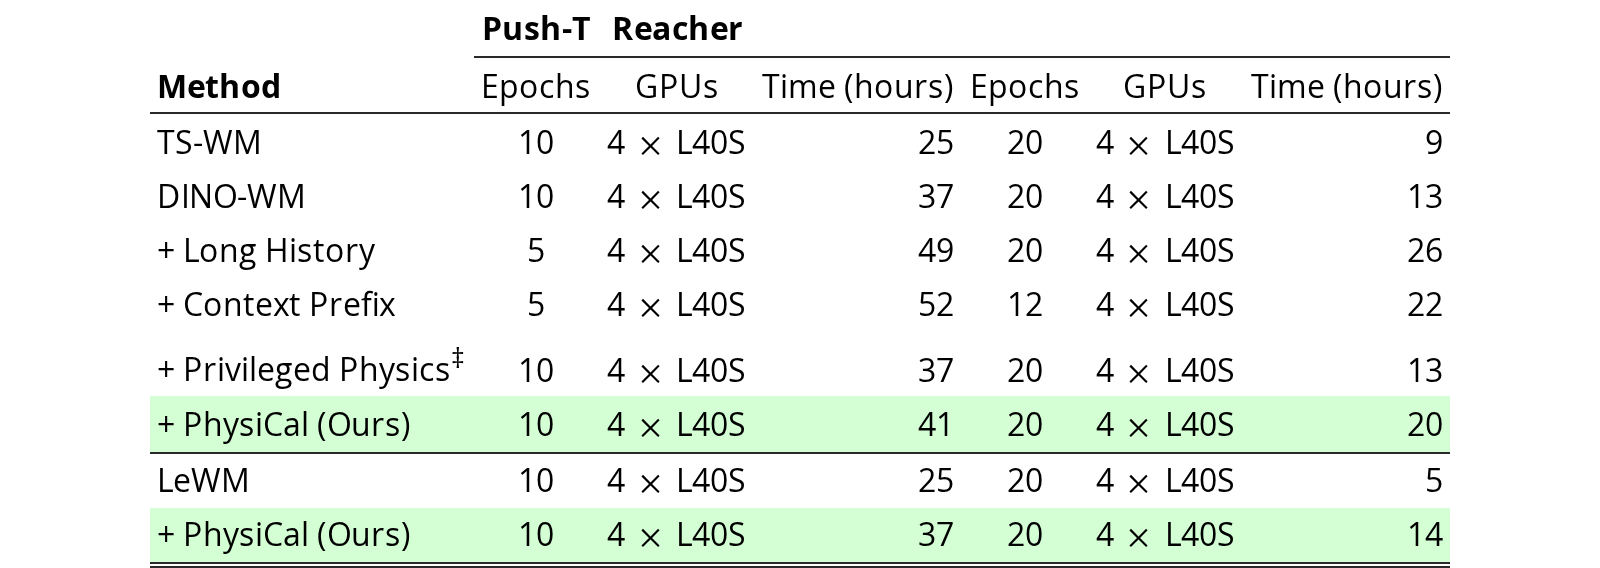
We measure latent model inference on Push-T using one NVIDIA RTX PRO 6000 Blackwell Server Edition GPU and FP32 with TF32 disabled. For next-frame prediction, we use 15 observed frames for Long History () and 3 for the remaining methods (). In open-loop rollouts, each model starts with three ground-truth observation frames. Long History grows its history autoregressively up to its 15-frame window. Context Prefix, Estimated Physics, and our method use the same 12-frame observation-action sequence as the context prompt. For planning inference time, we use the same CEM settings as in our main experiments and report the mean of ten repeated CEM solves.
Table A9shows that our method incurs a 2.30 ms condition-encoding cost. Including this cost, next-frame prediction takes 7.82 ms, adding 2.24 ms over DINO-WM (5.58 ms), compared with 13.91 ms for both Context Prefix and Long History. For open-loop rollouts, our method requires 16.03 ms for 5-step prediction and 45.83 ms for 20-step prediction, remaining close to DINO-WM (13.78 ms and 44.48 ms, respectively), compared with Context Prefix (48.36 ms and 177.61 ms) and Long History (18.05 ms and 131.27 ms). These results indicate that compressing context into a compact representation preserves near-baseline inference cost, avoiding the computational penalties of uncompressed prefixes or long observation histories.
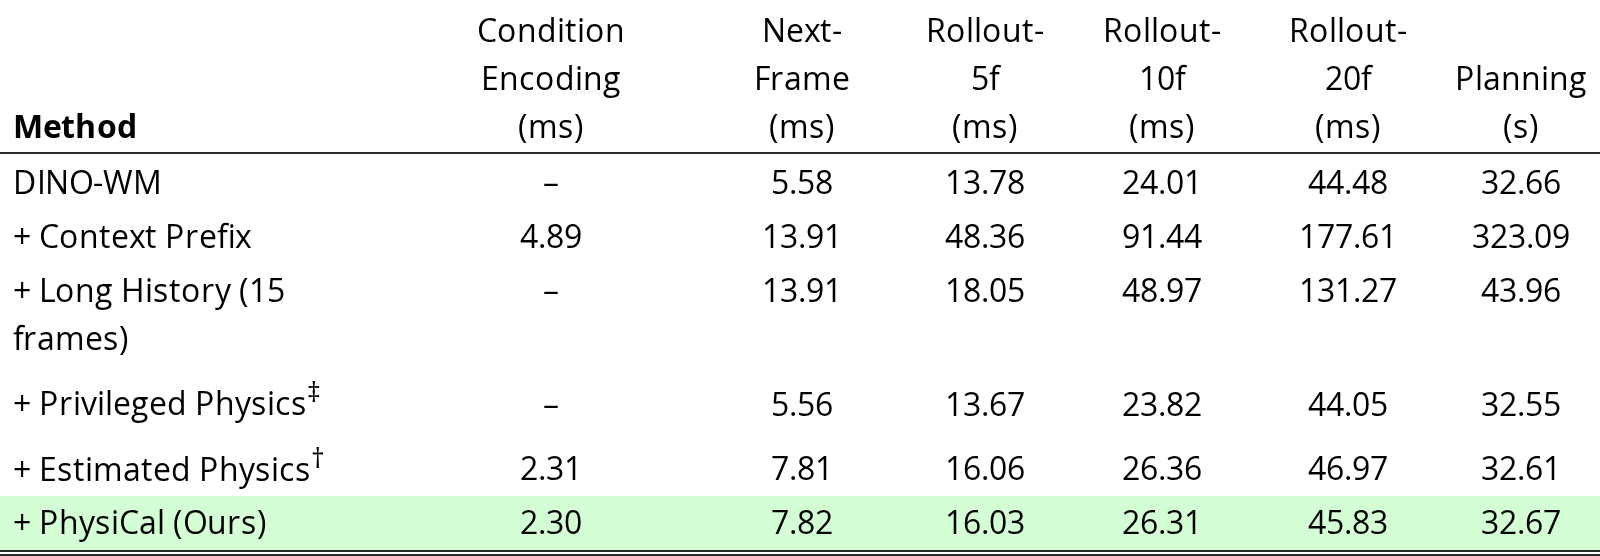
To better understand the planning performance in Reacher and FetchSlide (as reported in Table 1 and Table 2), we additionally present success rate vs. error-threshold curves in Figure A1.
Let the error threshold be , measured in degrees for Reacher and centimeters for FetchSlide. For Reacher, success requires both joint angular position errors to satisfy , where denotes the angle of joint after executing the 25 planned controls. For FetchSlide, the success criterion is that terminal puck-position error . For the results shown in Table 1 and Table 2, the error tolerance is for Reacher and for FetchSlide.
As shown in Figure A1, in both the Reacher and the FetchSlide environments, our method improves performance over the baseline world models (DINO-WM and LeWM), as evidenced by comparing DINO-WM (deep blue) and DINO-WM + ours (green). Our method improves substantially over the unprivileged baselines in FetchSlide. The gains are modest in the Reacher environment, likely due to its highly constrained state space, which consists of only two rotational joints.
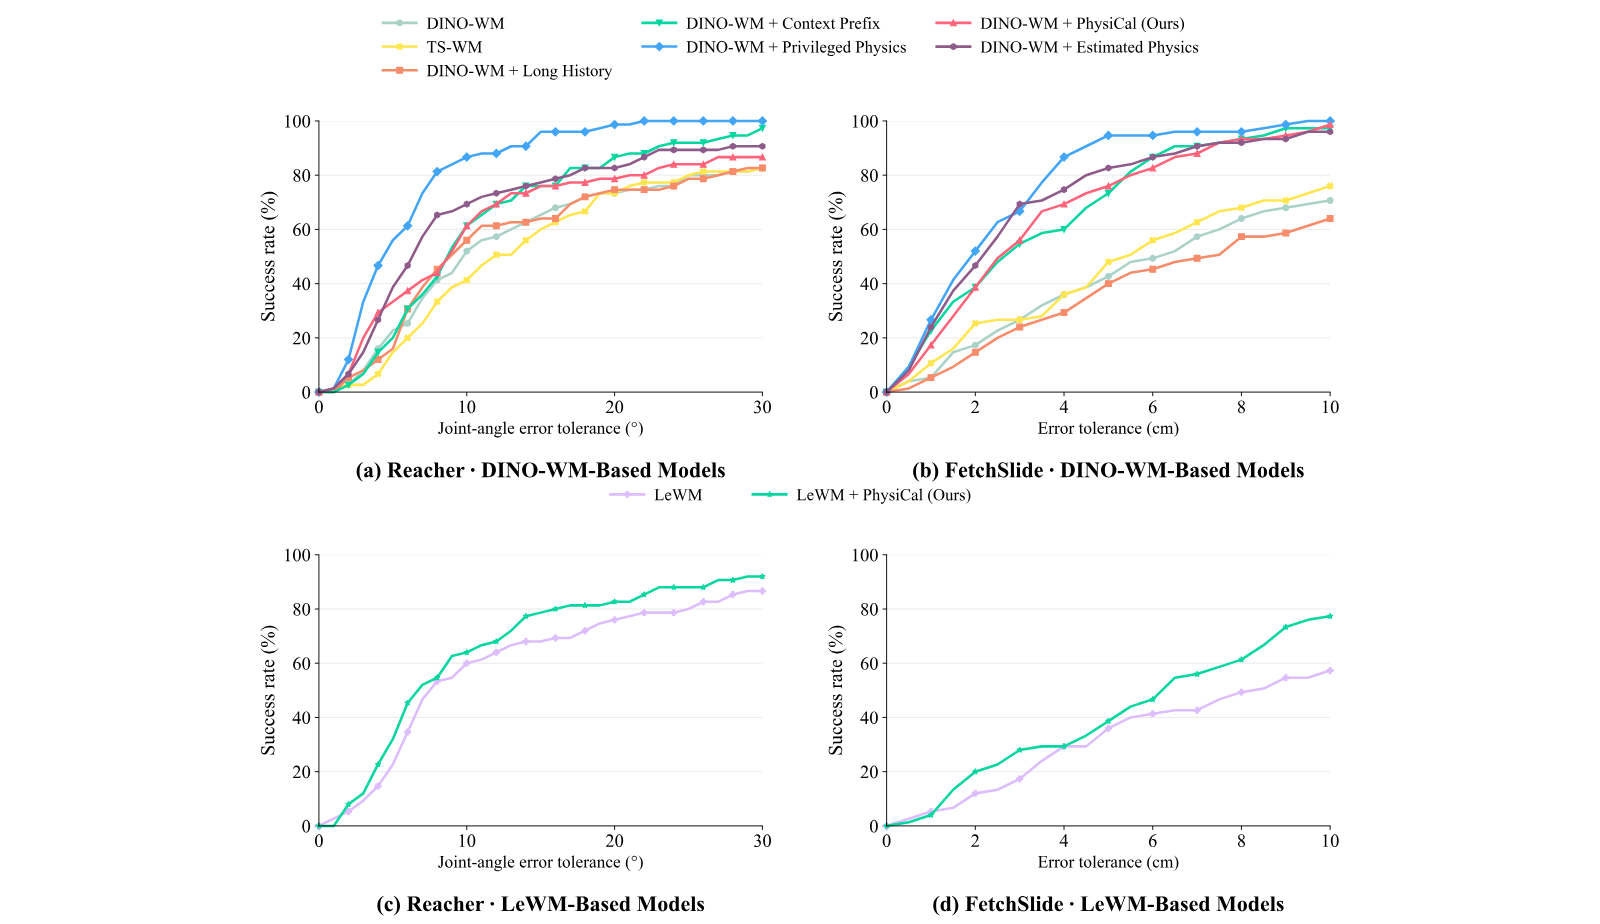
In this section, we provide additional qualitative results for both prediction and planning. We first present the in-context interaction clips that are used to generate the qualitative results shown in the main paper in Appendix D.1. We also append the uncropped version of Figure 4 (BeerPong qualitative results) in Appendix D.2.
In Appendix D.3, we show qualitative results of the extrapolation experiments as introduced in Section 4.3. We also provide additional qualitative open-loop rollout results in Appendix D.4 as well as planning results in Appendix D.5. For each result, we also provide the corresponding in-context interaction clips that PhysiCalWorld and other context-based baselines use.
We present the in-context interaction clips corresponding to the main-text qualitative results of Push-T (Figure 4), BeerPong (Figure 4), and FetchSlide (Figure 6) as in Figure A2, Figure A3, and Figure A4, respectively. For each example, all context-conditioned models receive the same interaction clip as input. PhysiCalWorld encodes this clip into a physics descriptor token, while in the Context Prefix baseline, the same clip is directly fed into the future predictor .
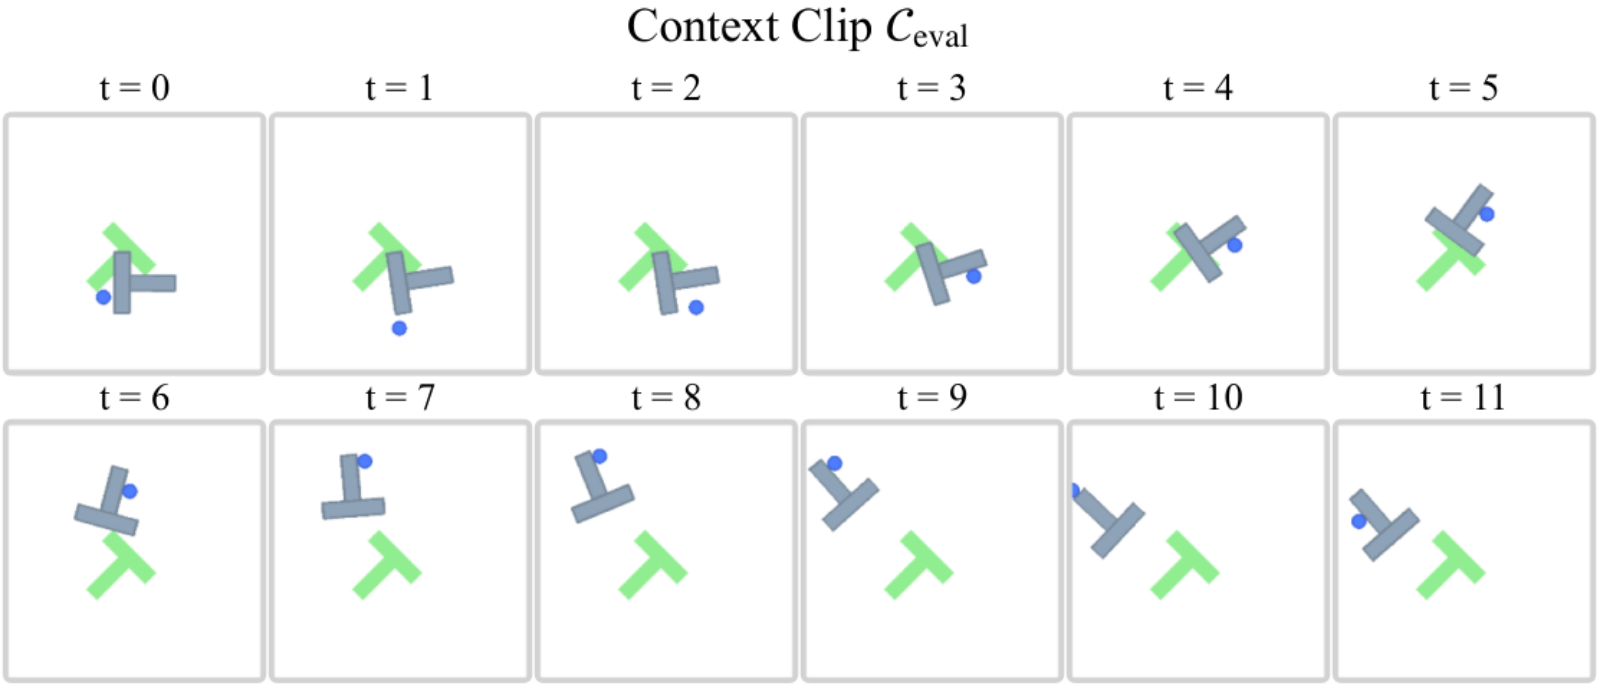
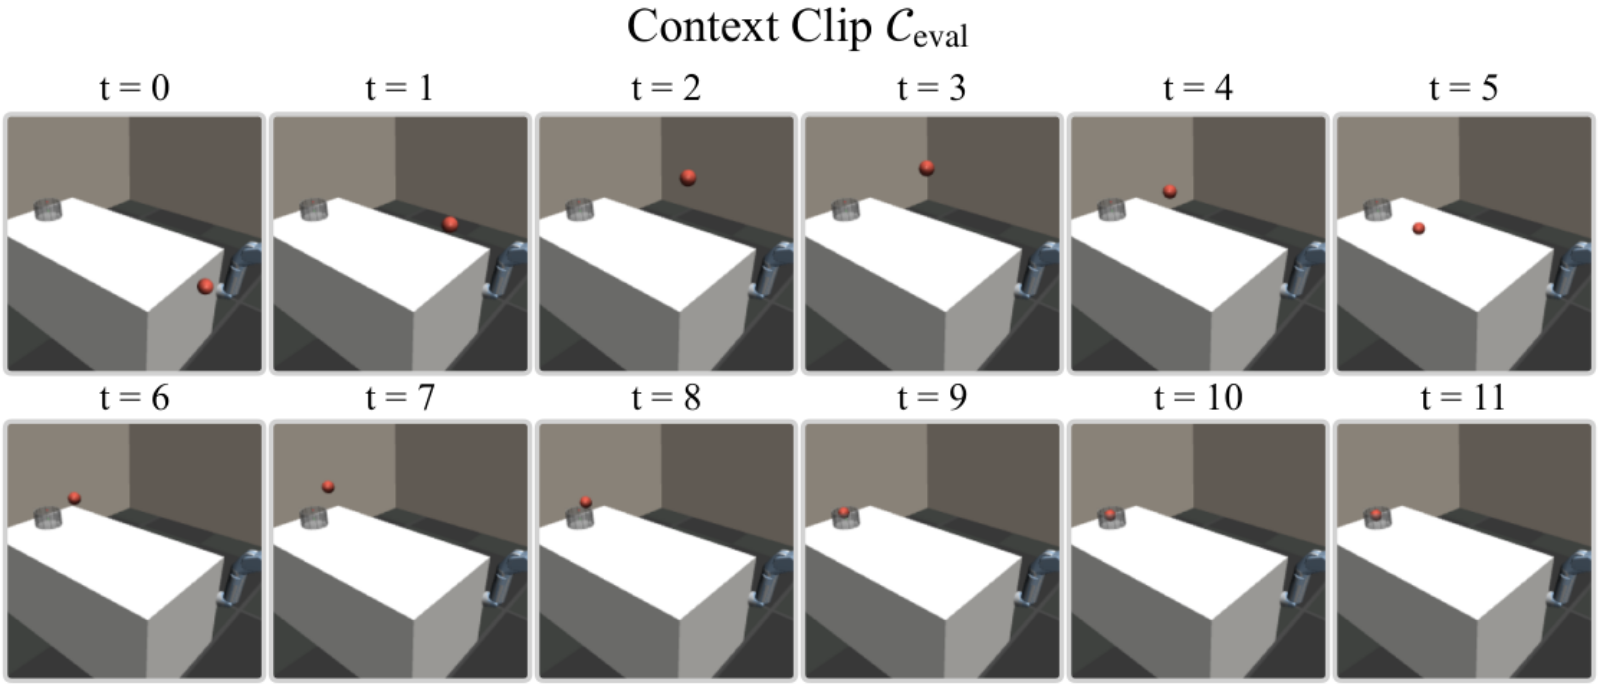
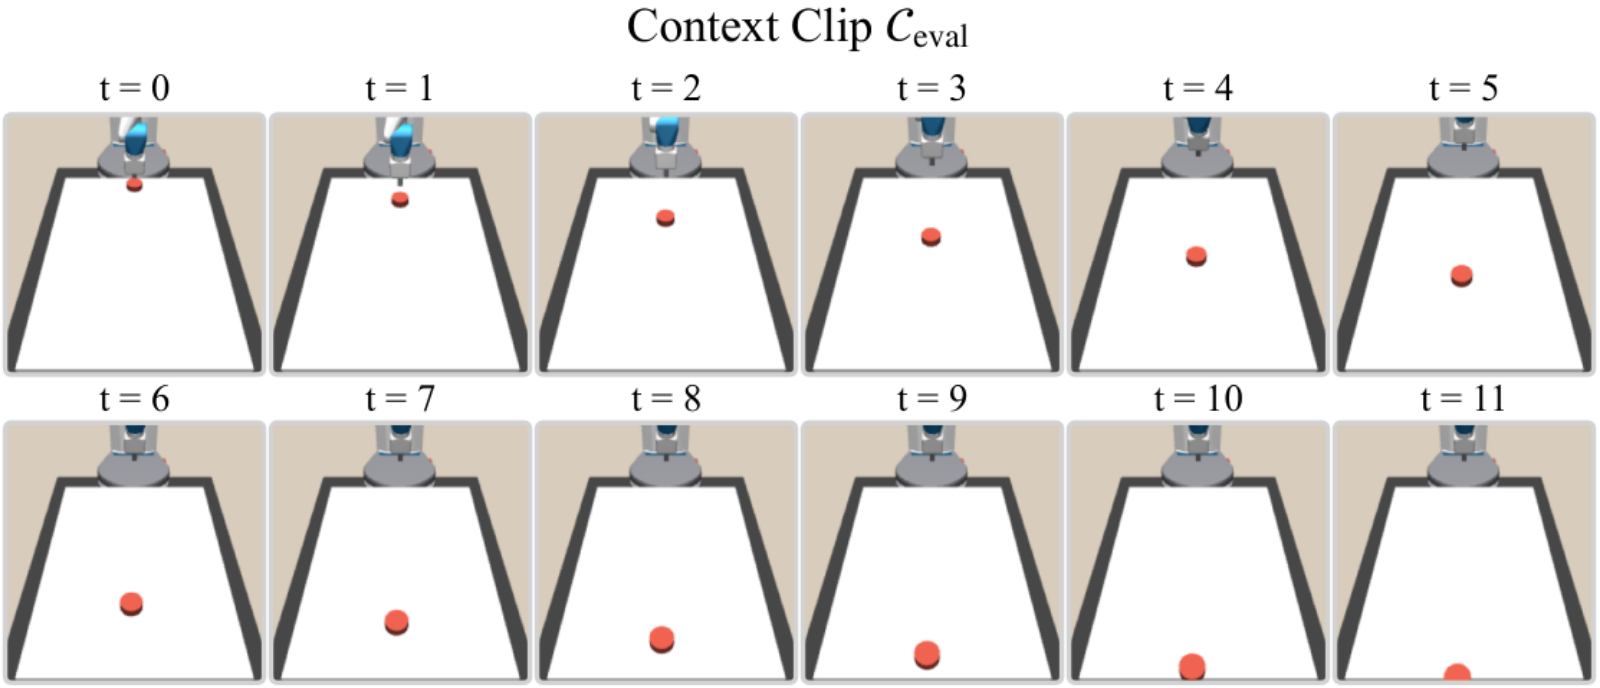
In Figure 4(b), we crop the predicted frames for a clearer view. In this section, we provide the uncropped version of the model’s predictions, as shown in Figure A5.
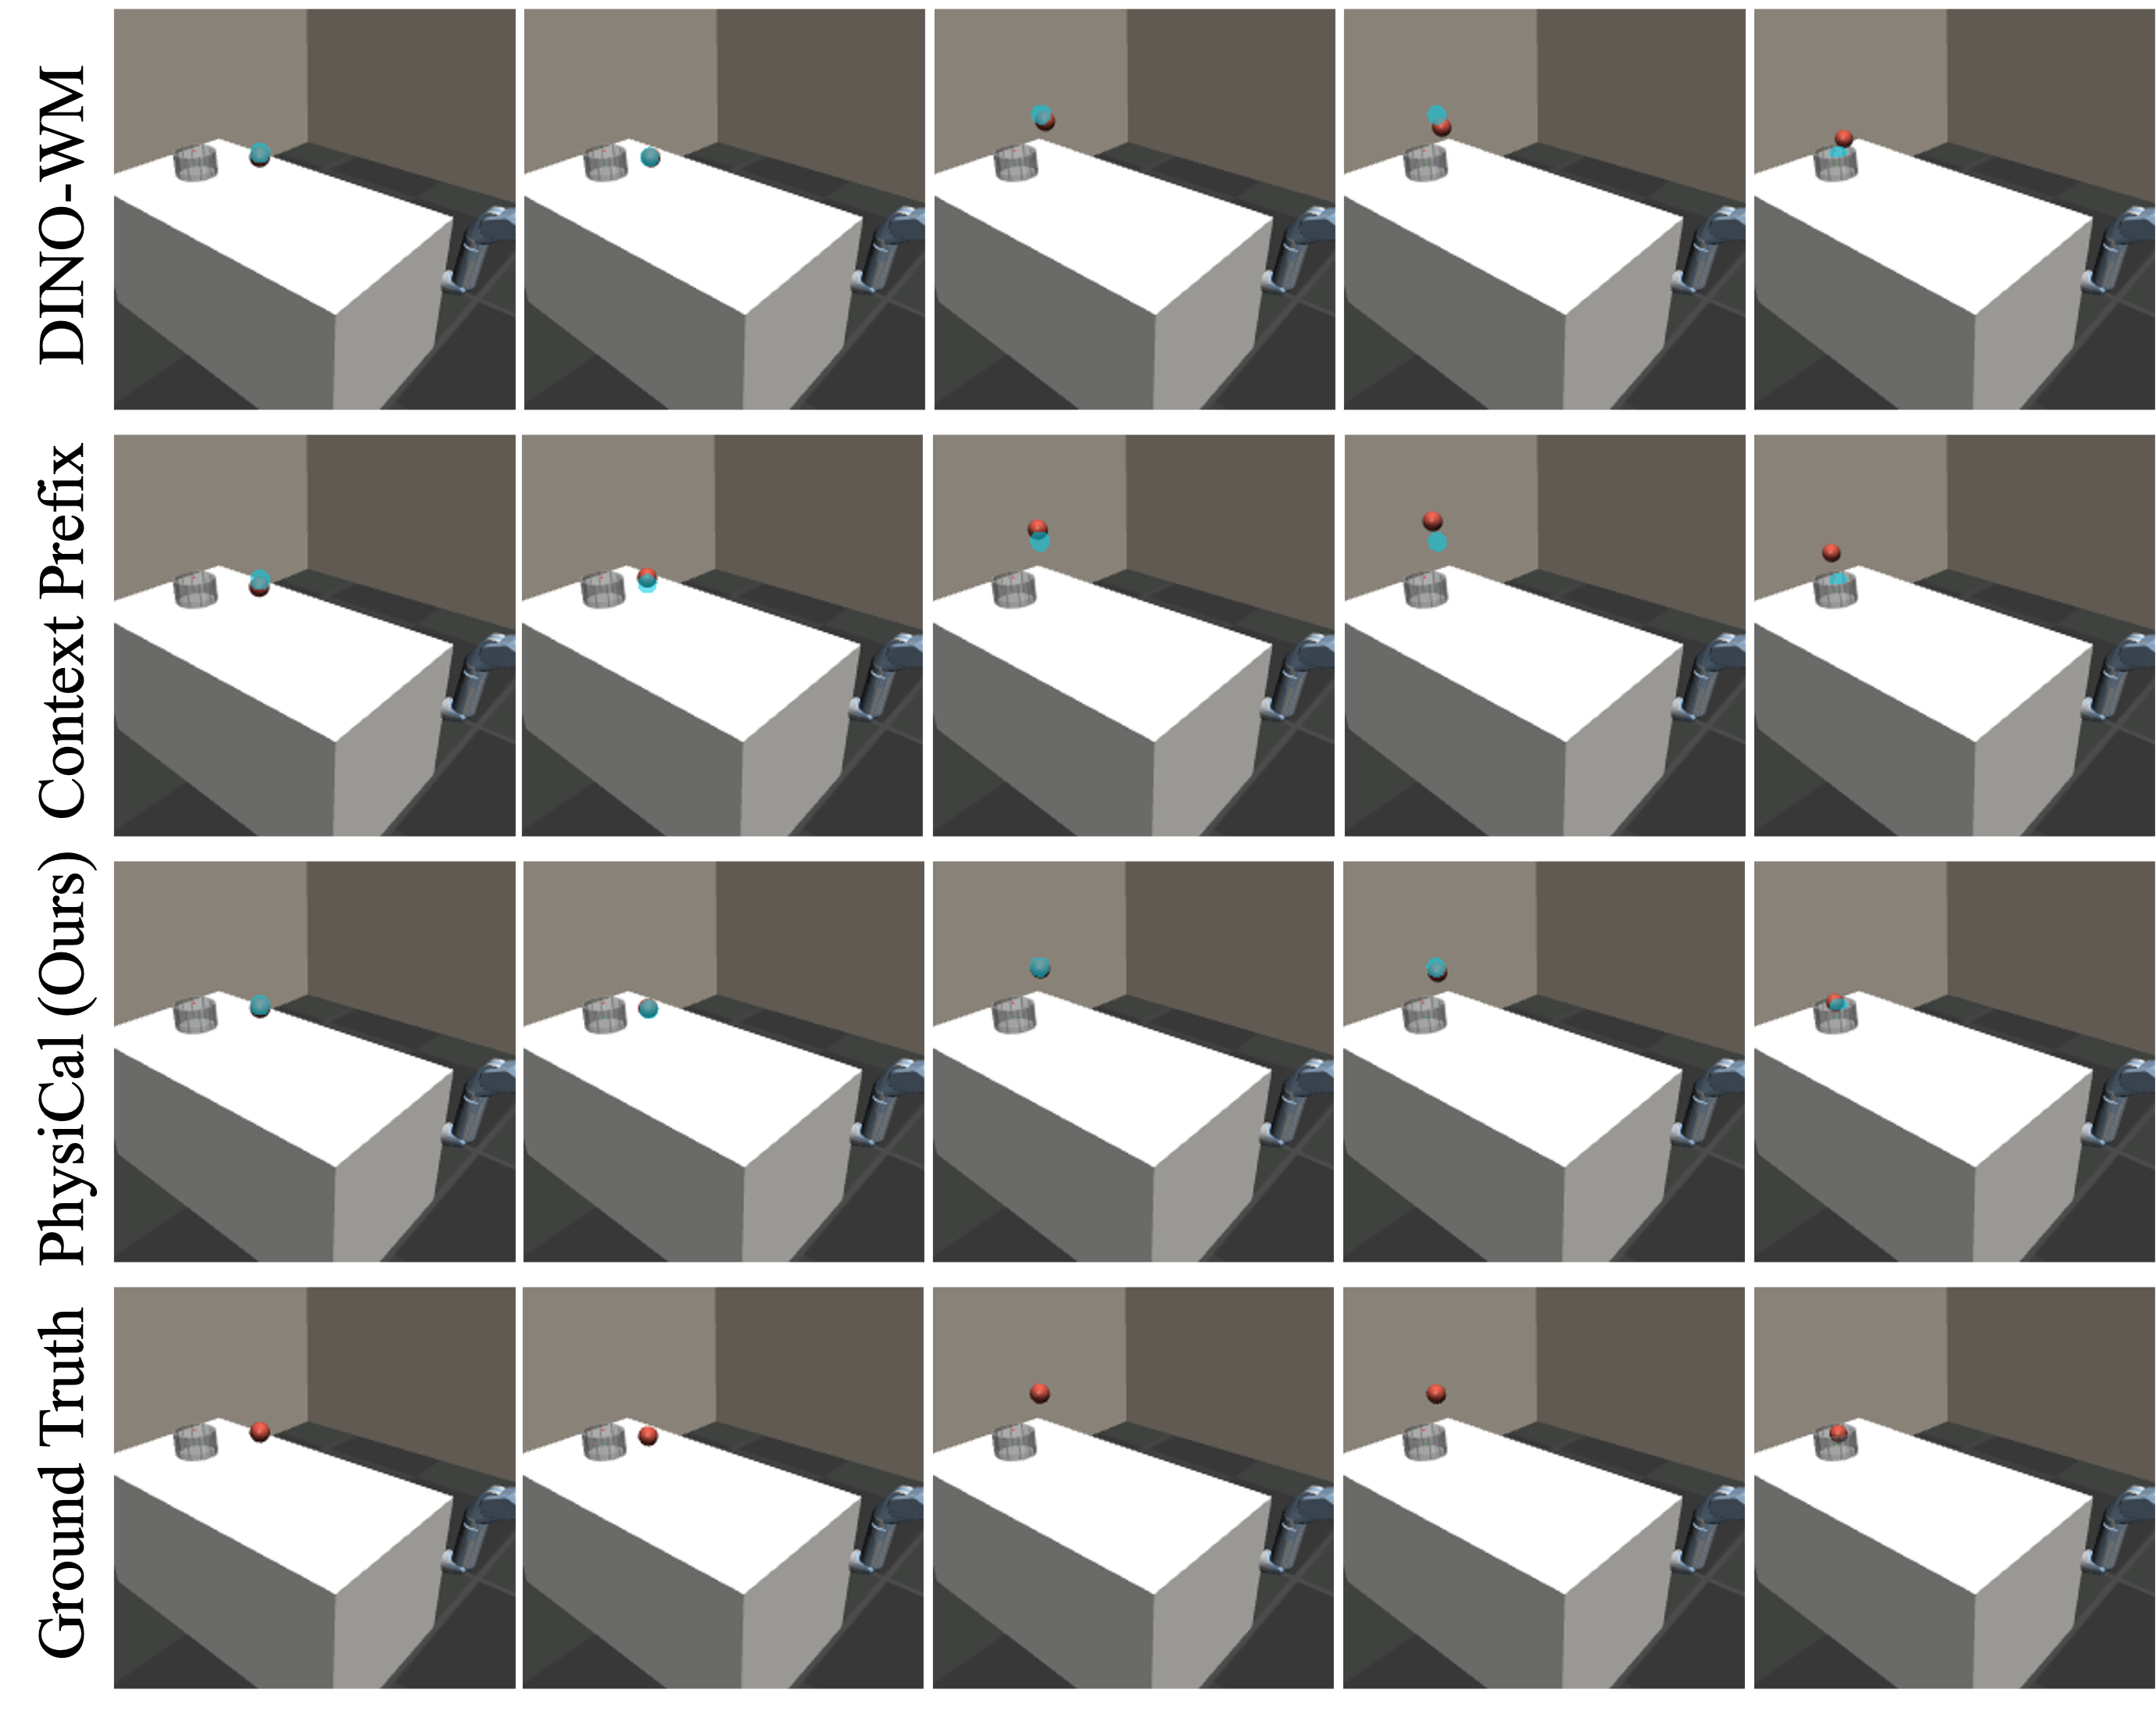
We provide qualitative world models’ predictions complementing the Reacher extrapolation results shown in Figure 8. Following the main-text experiment, the first joint’s damping lies outside the training range, while the second joint’s damping remains fixed. We present the open-loop predictions in Figure A6 and the interaction clip used by PhysiCalWorld in Figure A7. We observe that the prediction quality of DINO-WM + Privileged Physics deteriorates quickly after , while our method performs stably throughout the open-loop rollout (from to ).
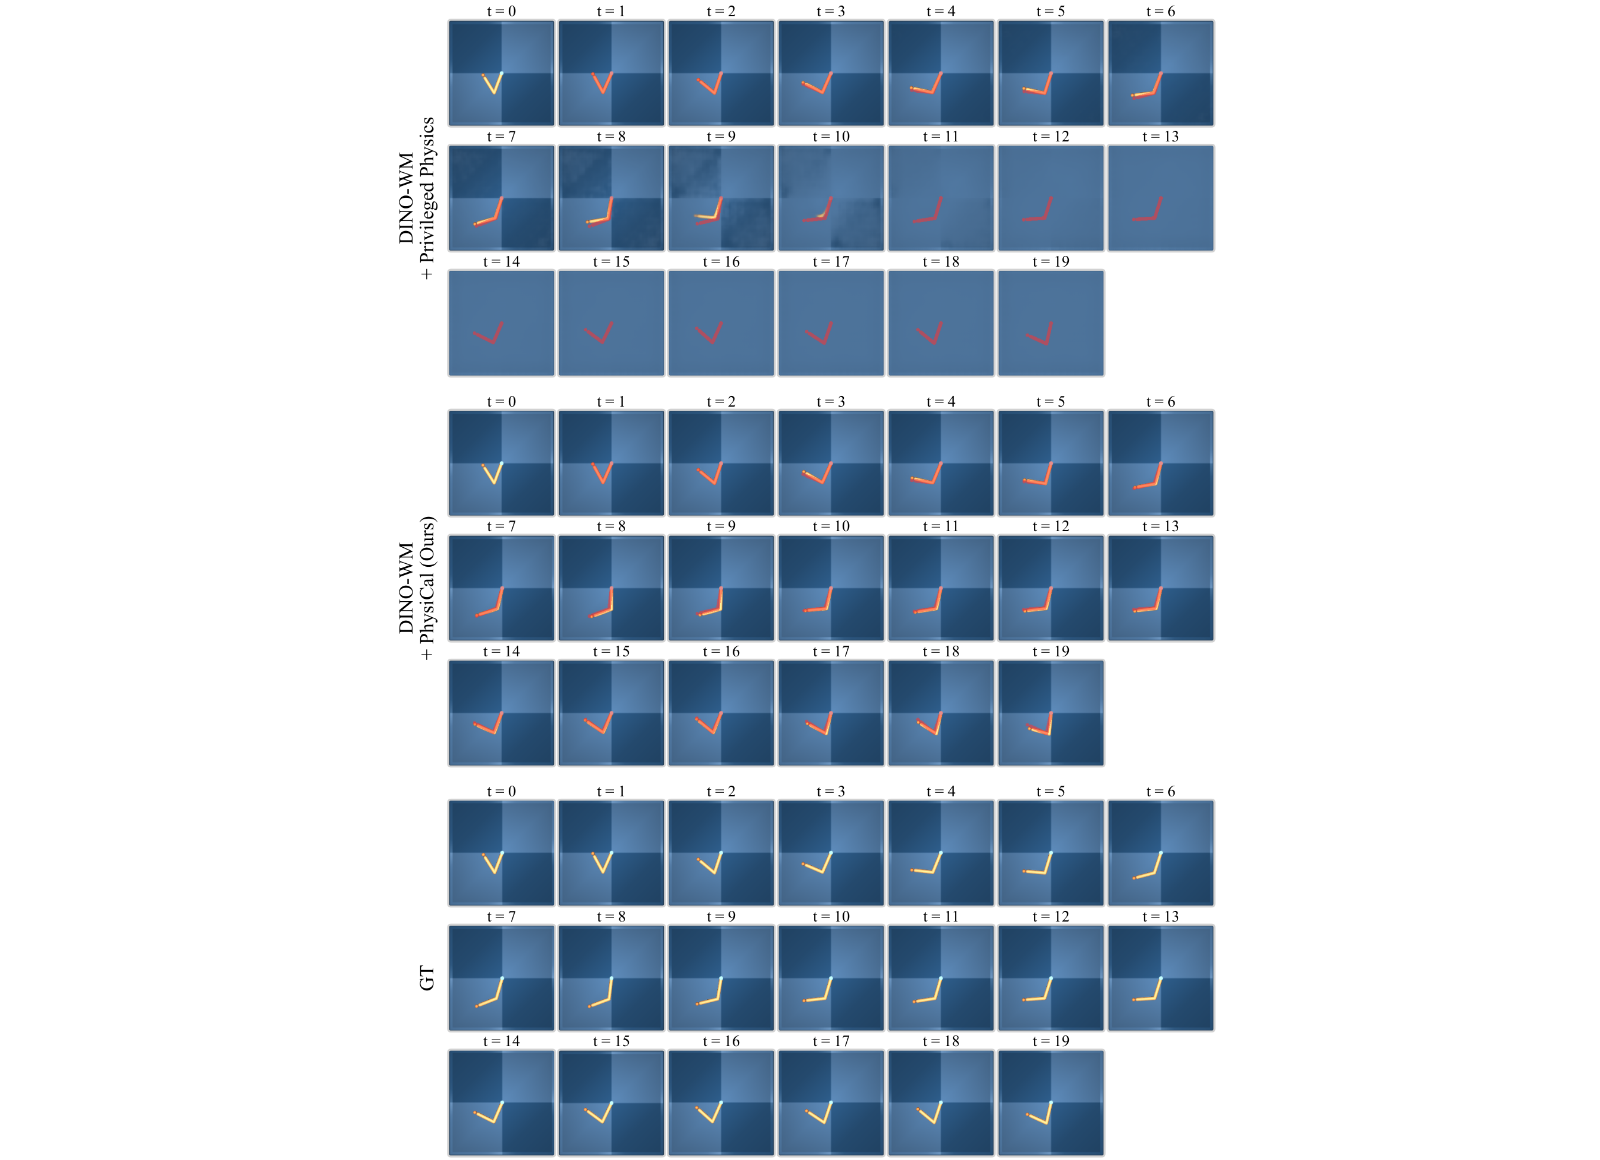
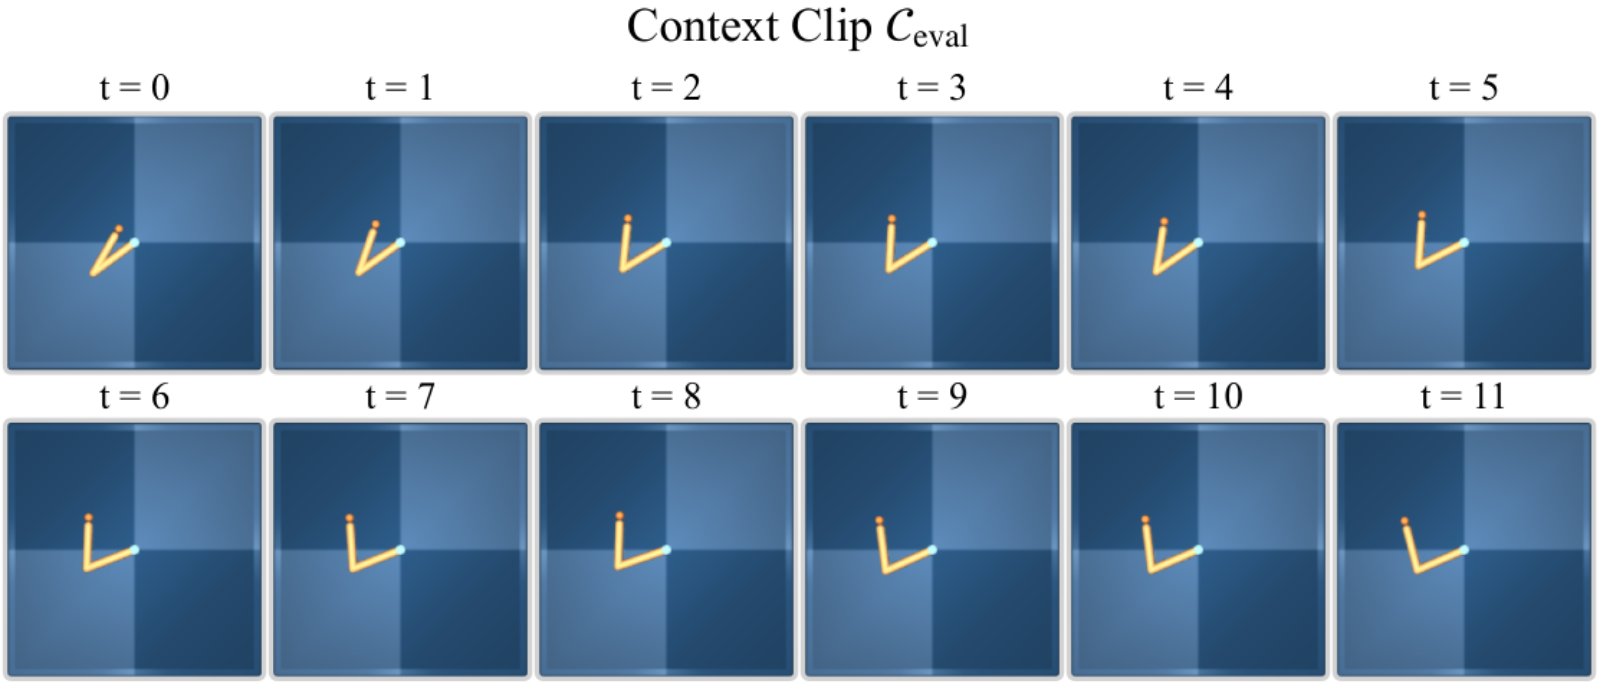
We provide additional qualitative open-loop rollout results in all four environments: Push-T (Figure A8), Reacher (Figure A10), BeerPong (Figure A12), and FetchSlide (Figure A14). Starting from the initial observations, each model predicts future observations autoregressively under a given sequence of evaluation actions. That is, the predicted observation will be fed back to the model as the current observation to synthesize next observation. Each rollout result is followed by the interaction clip used by the context-conditioned models.
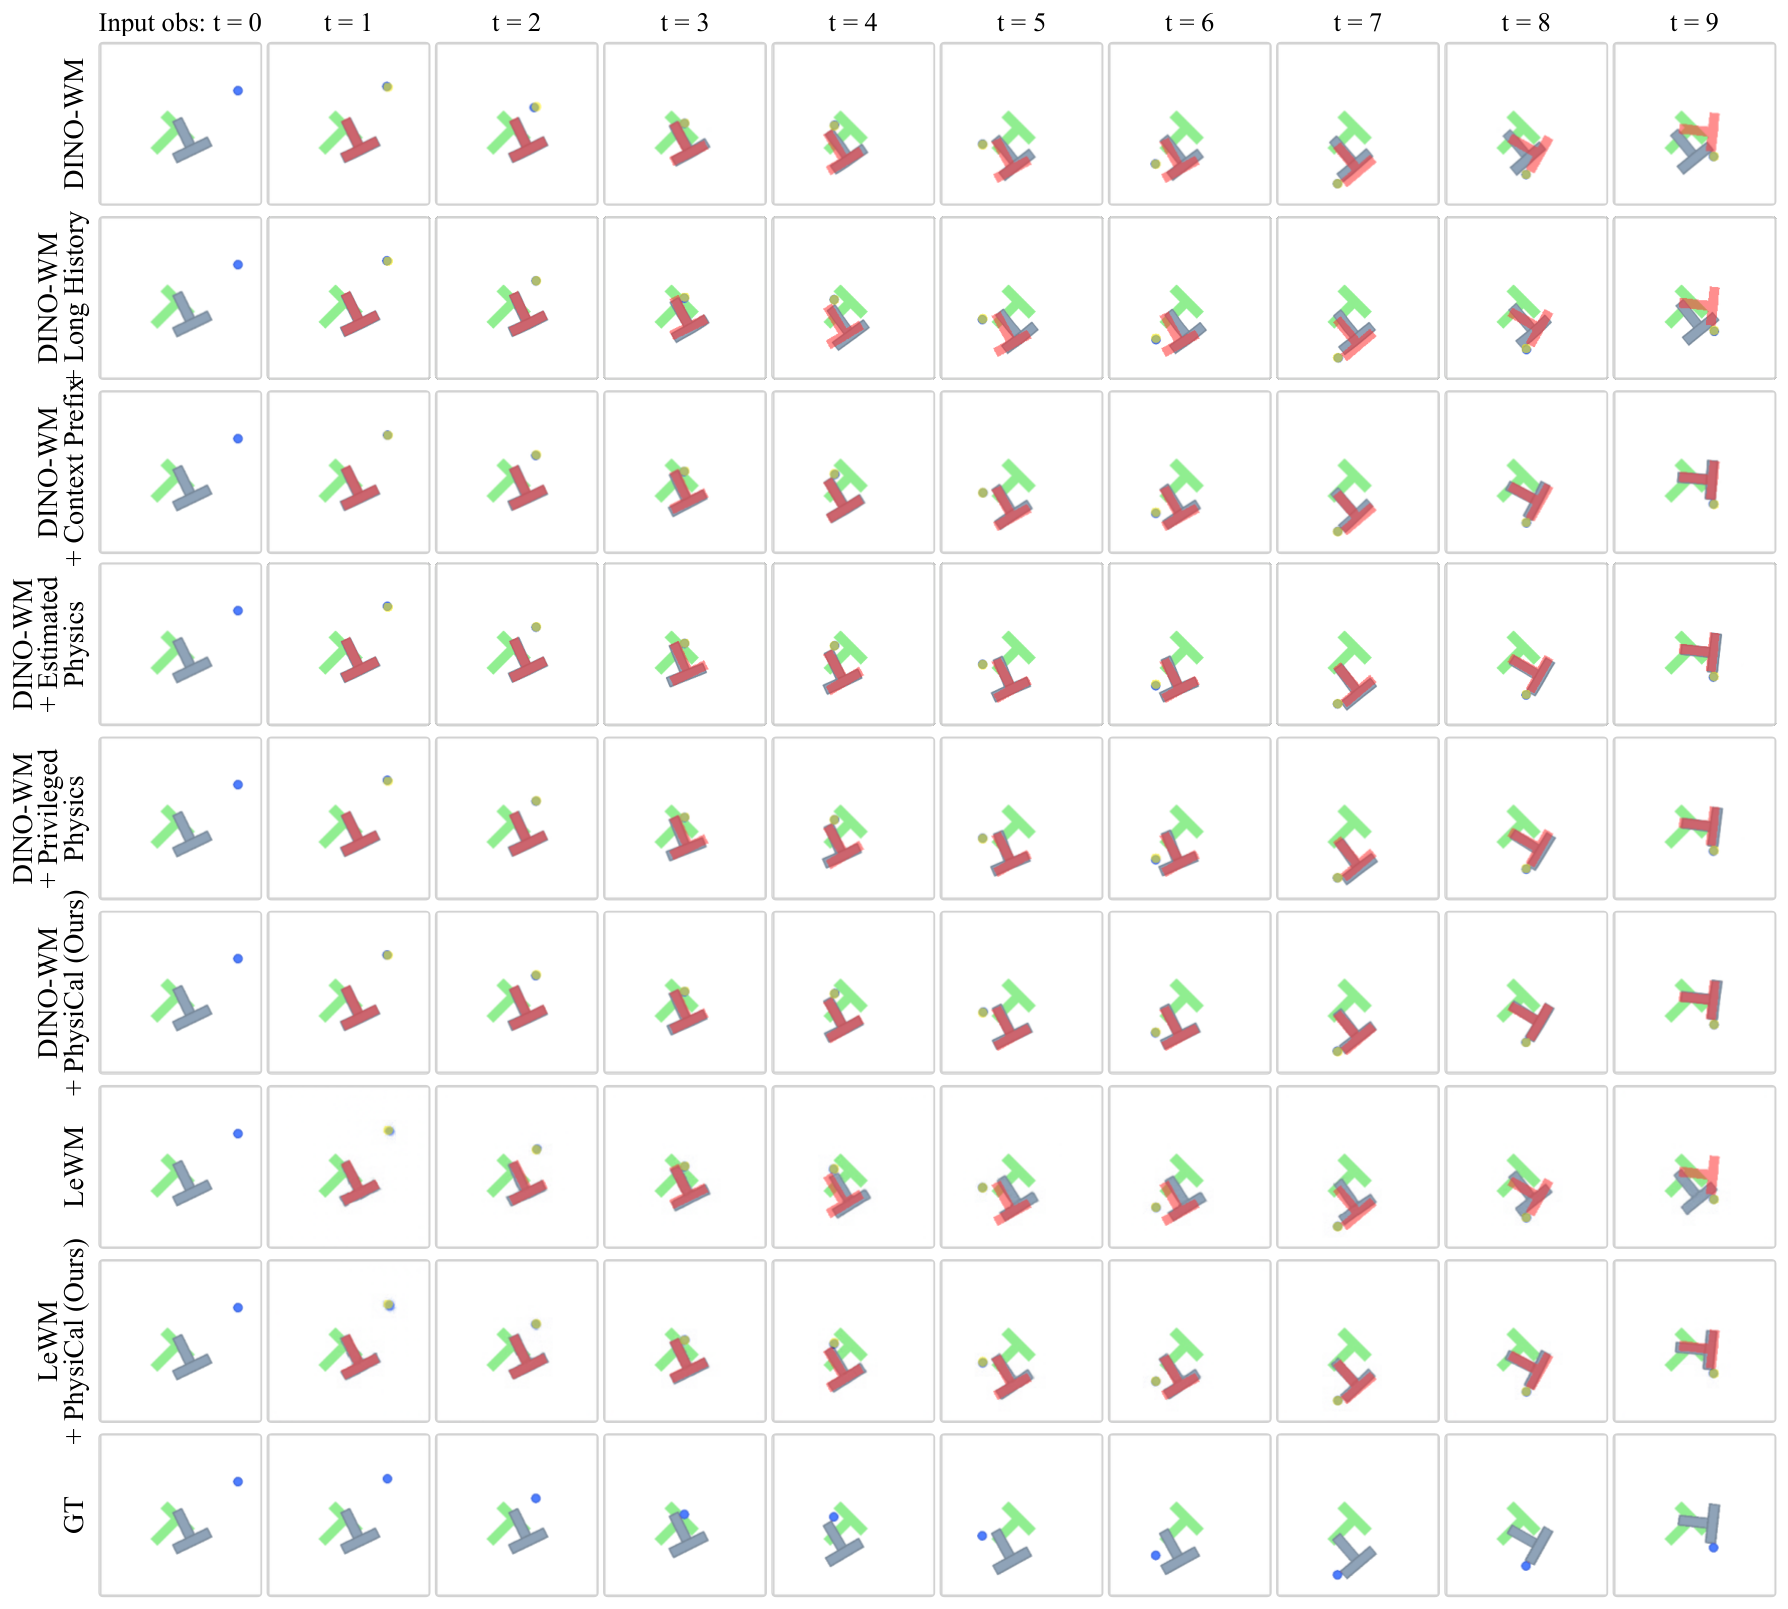
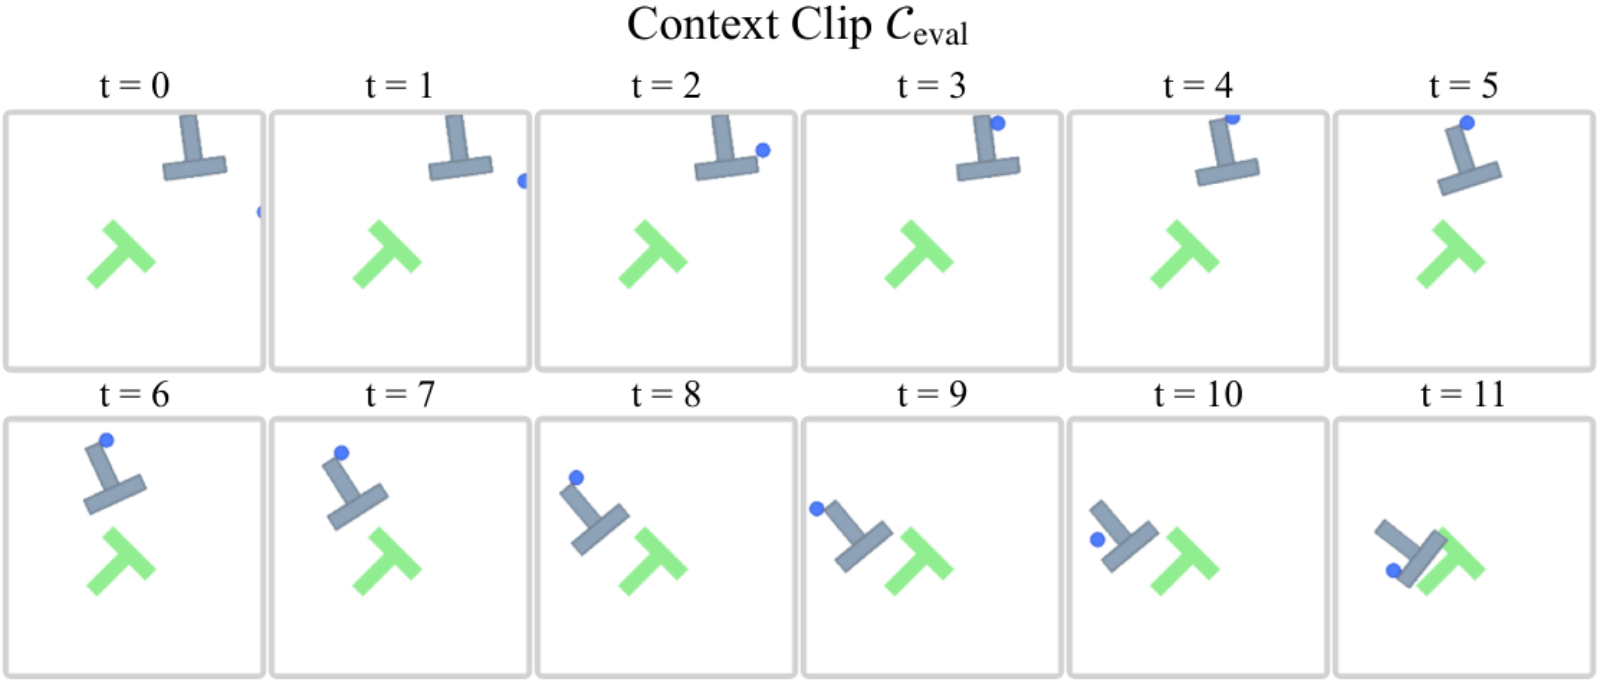
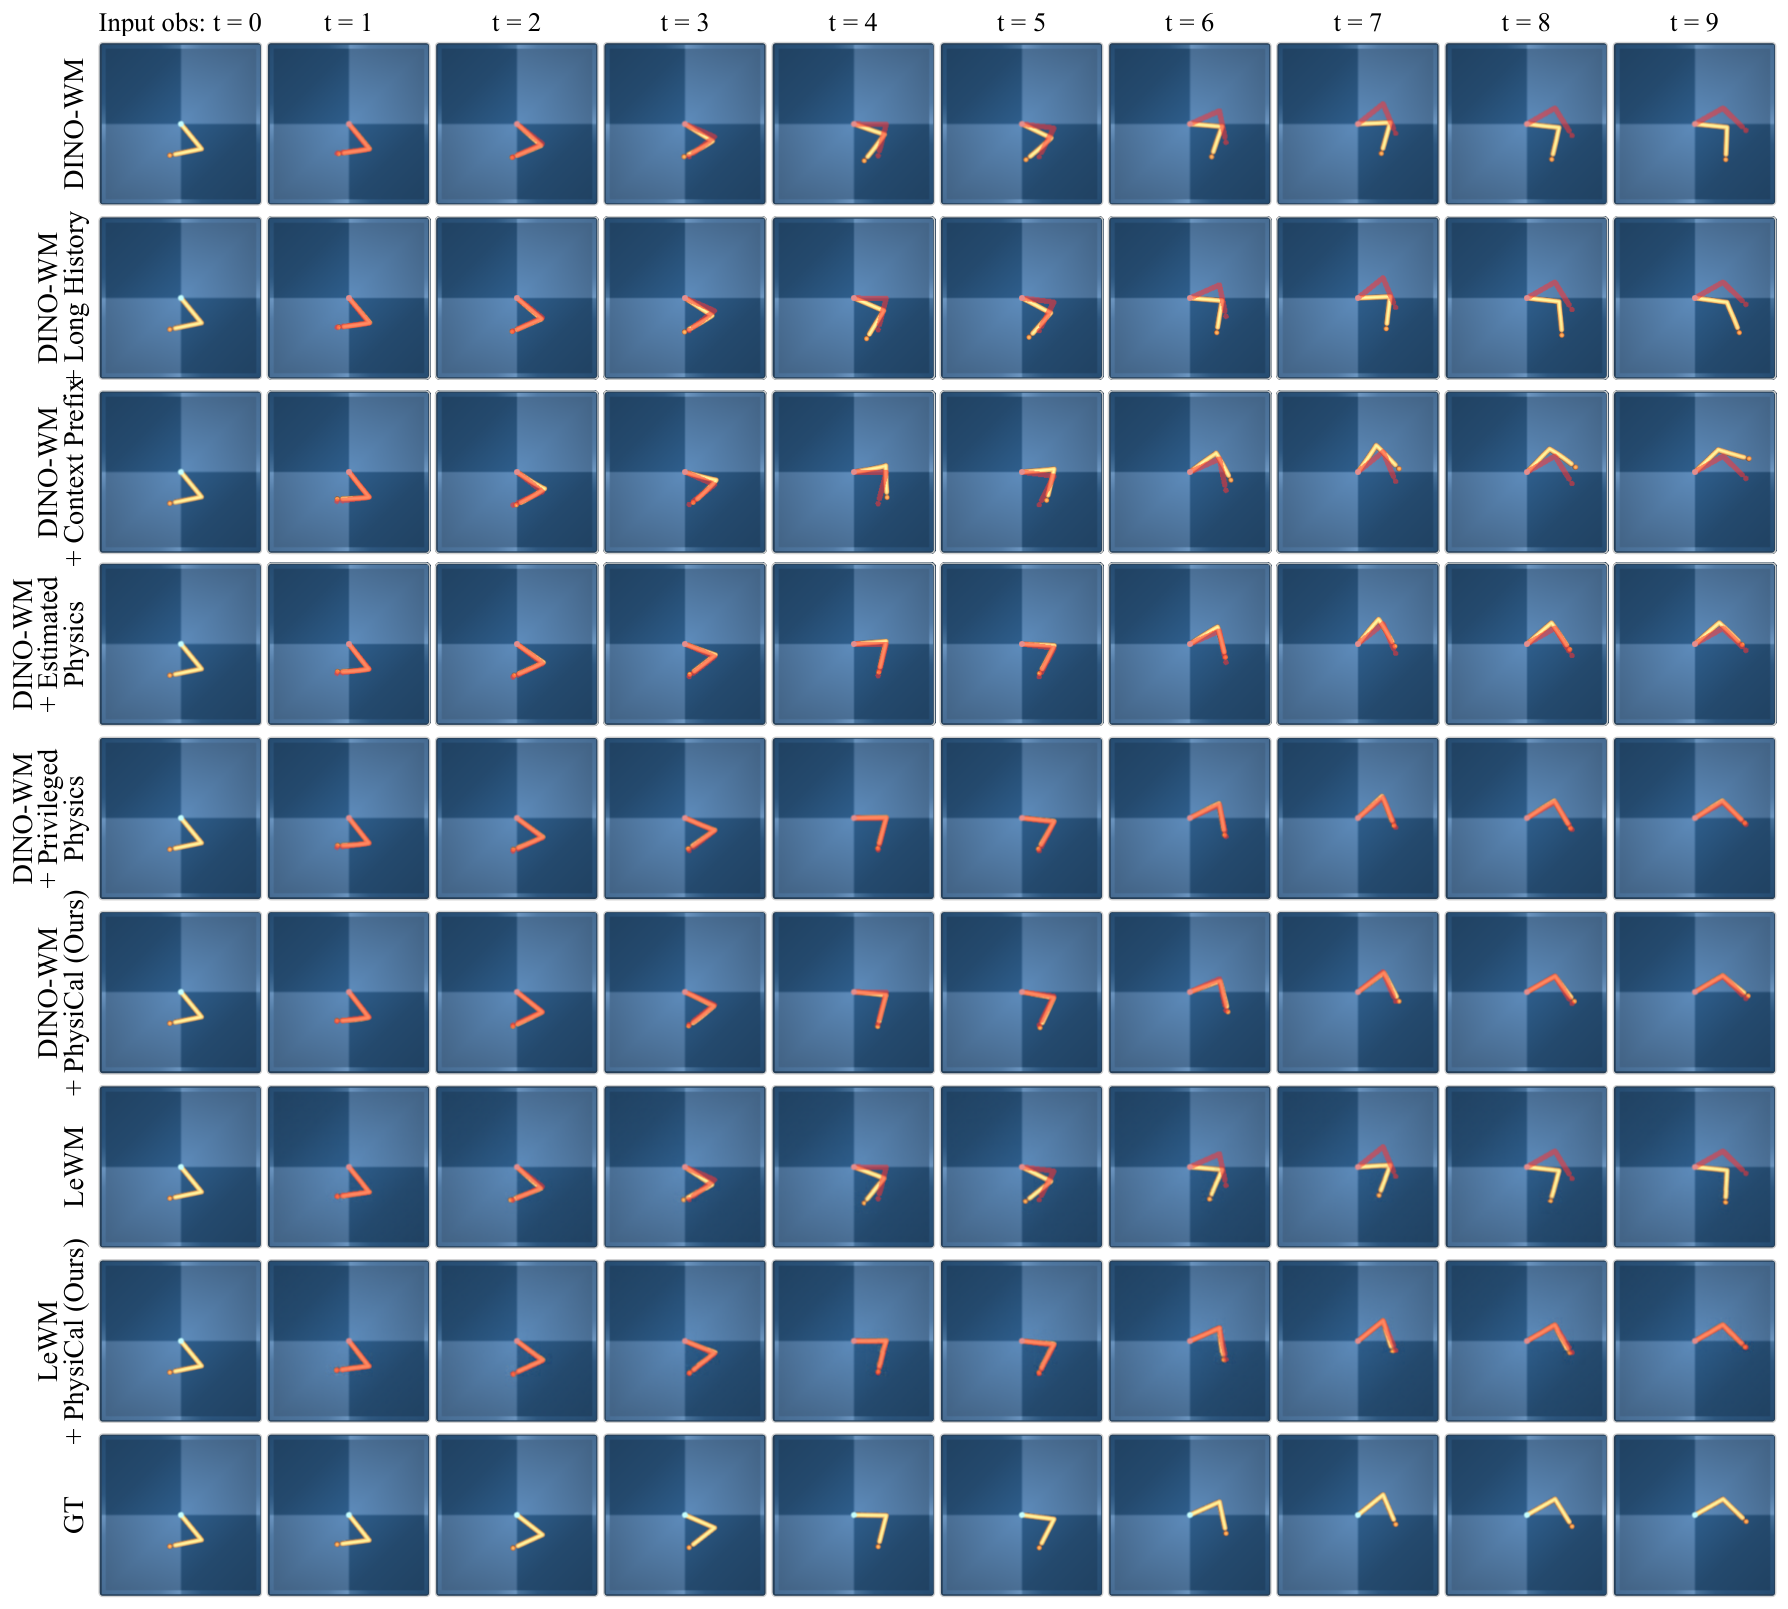
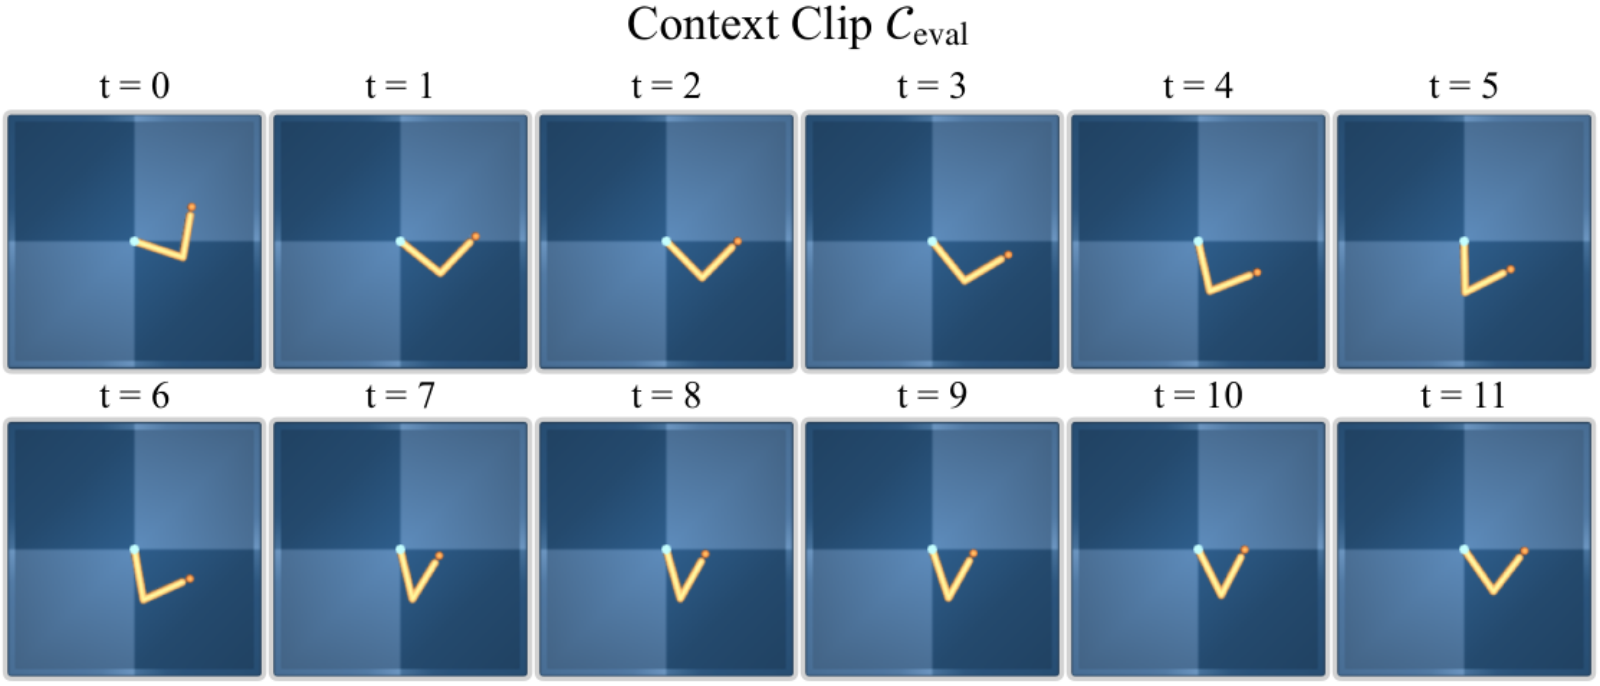
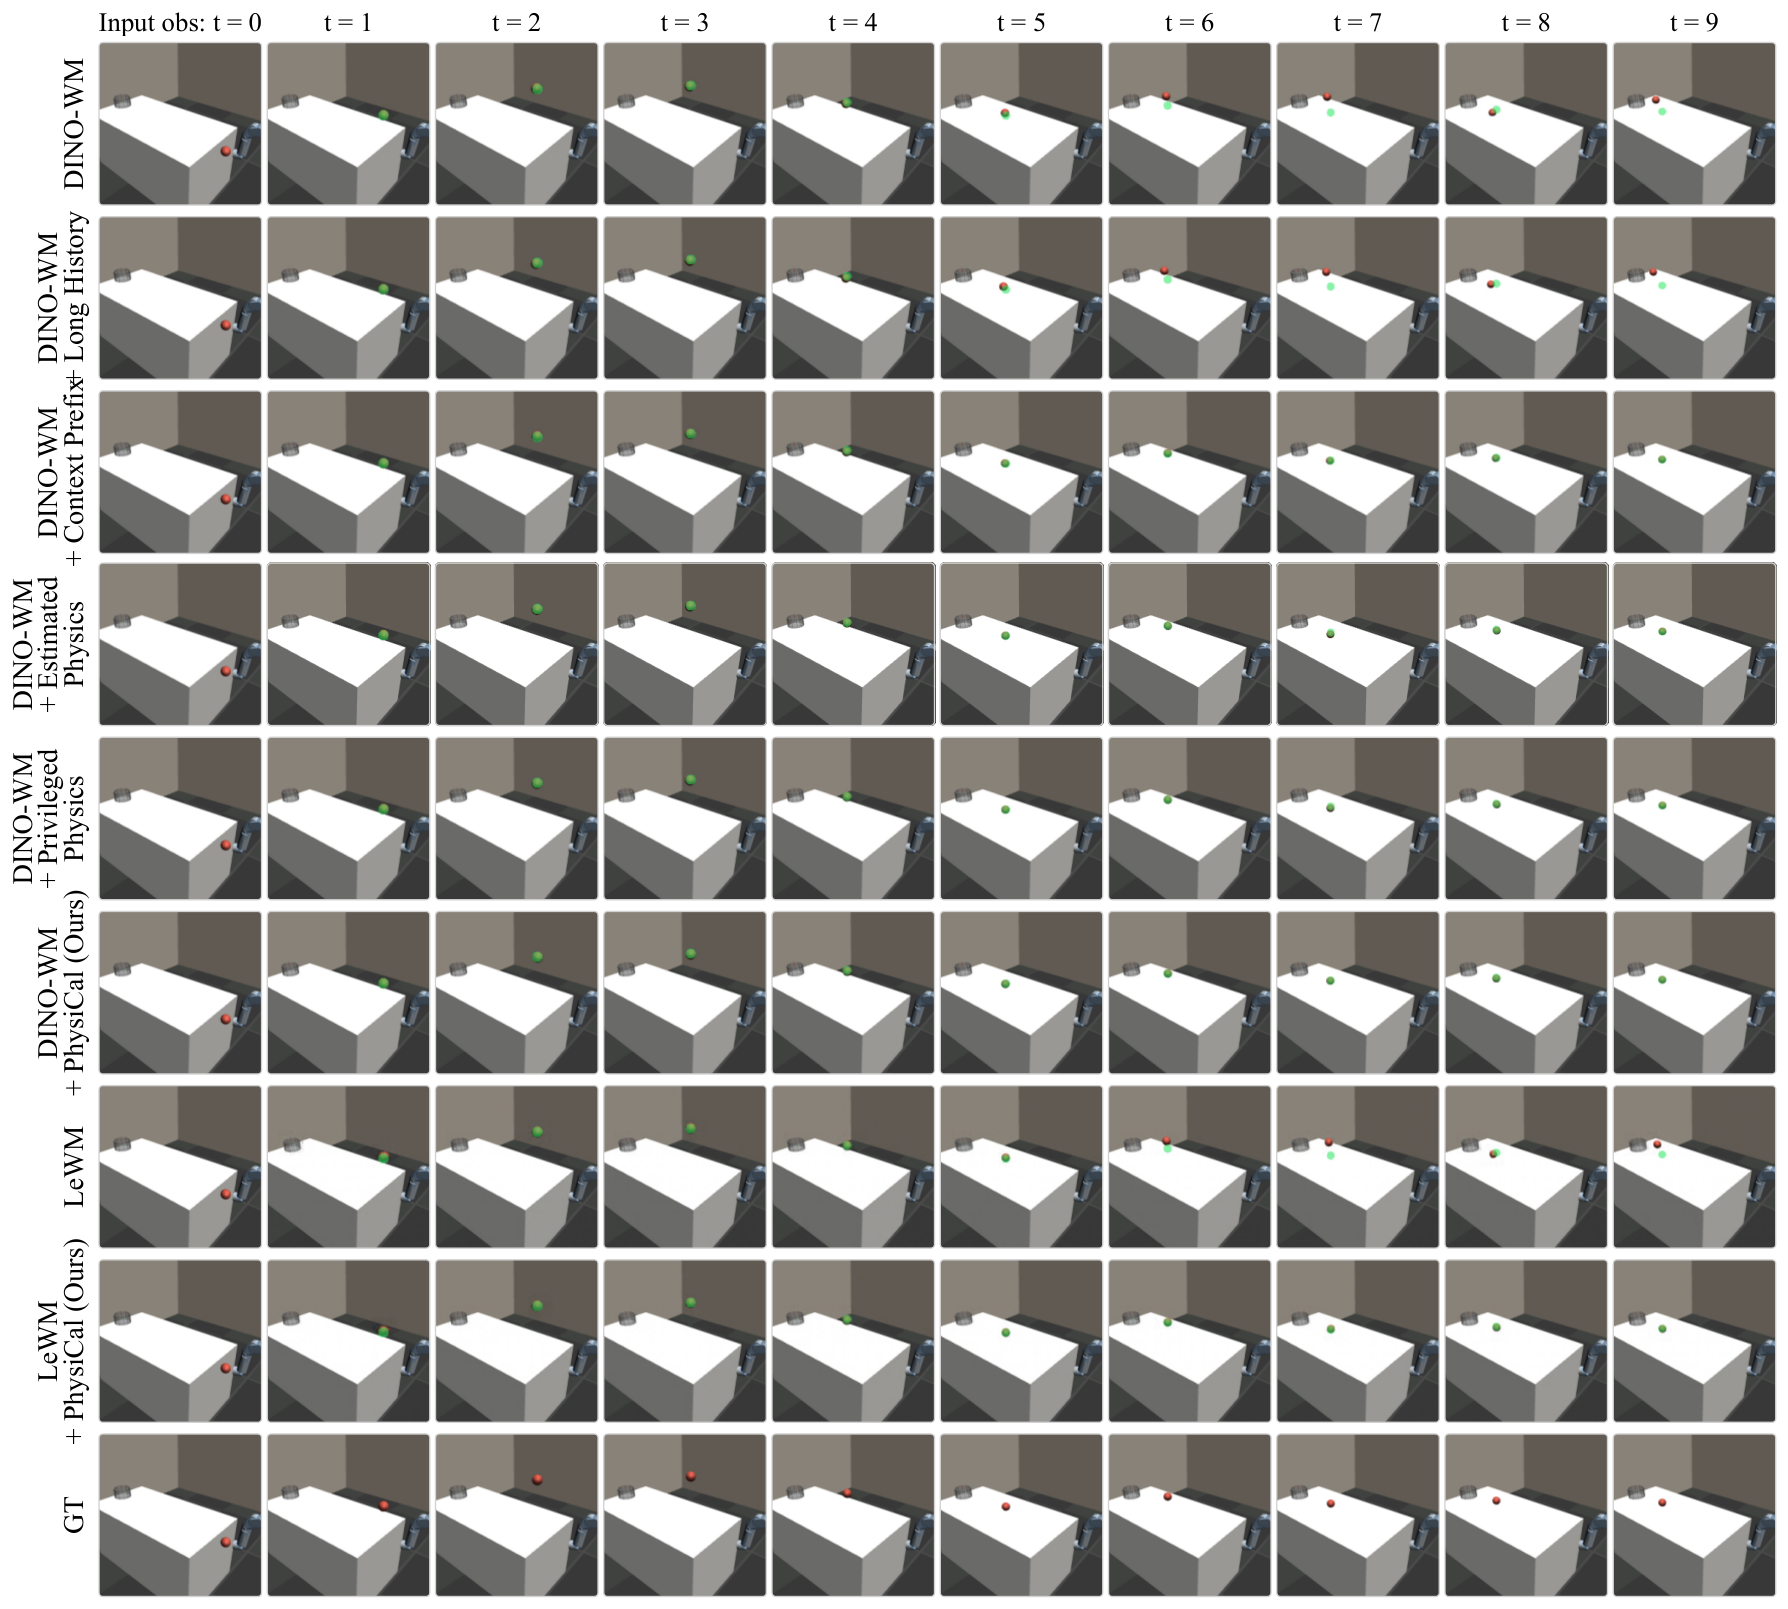
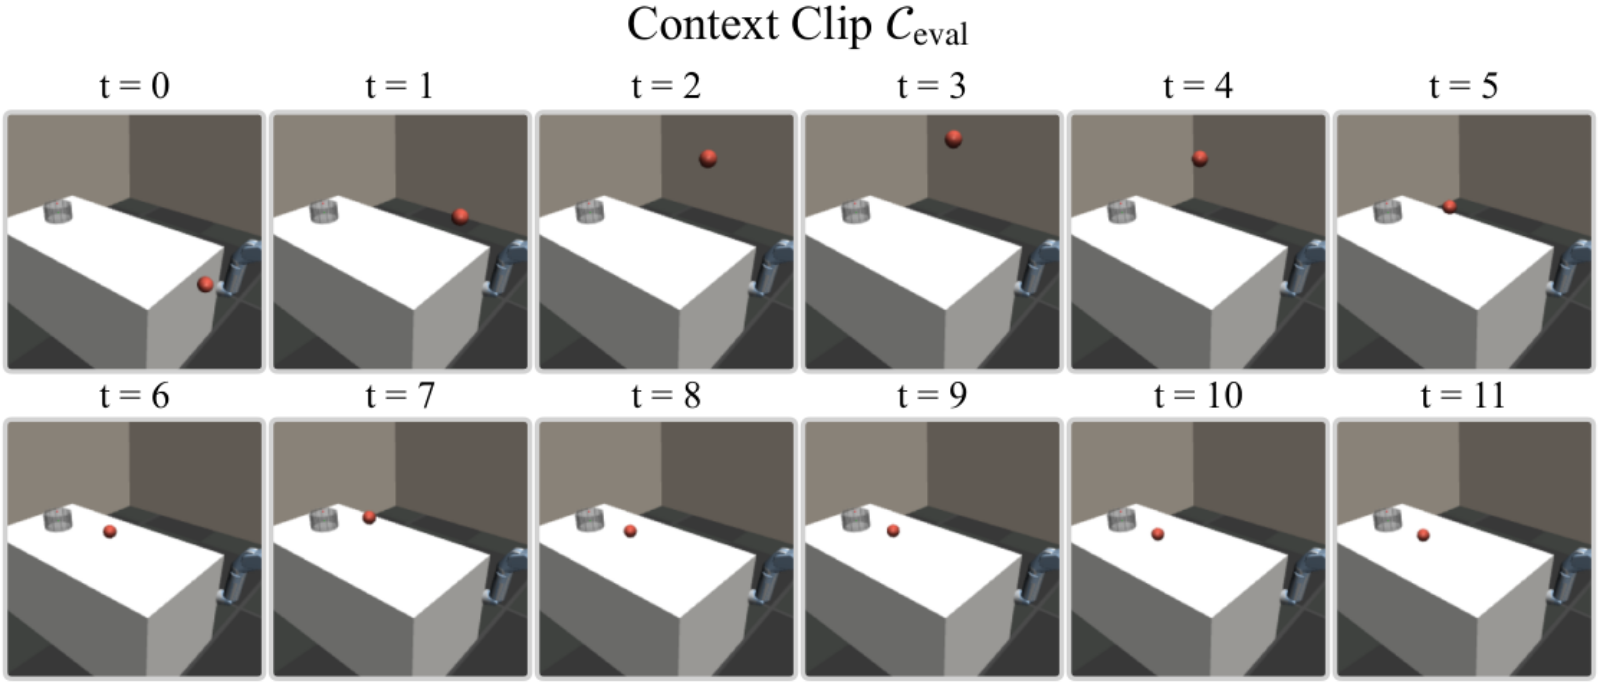
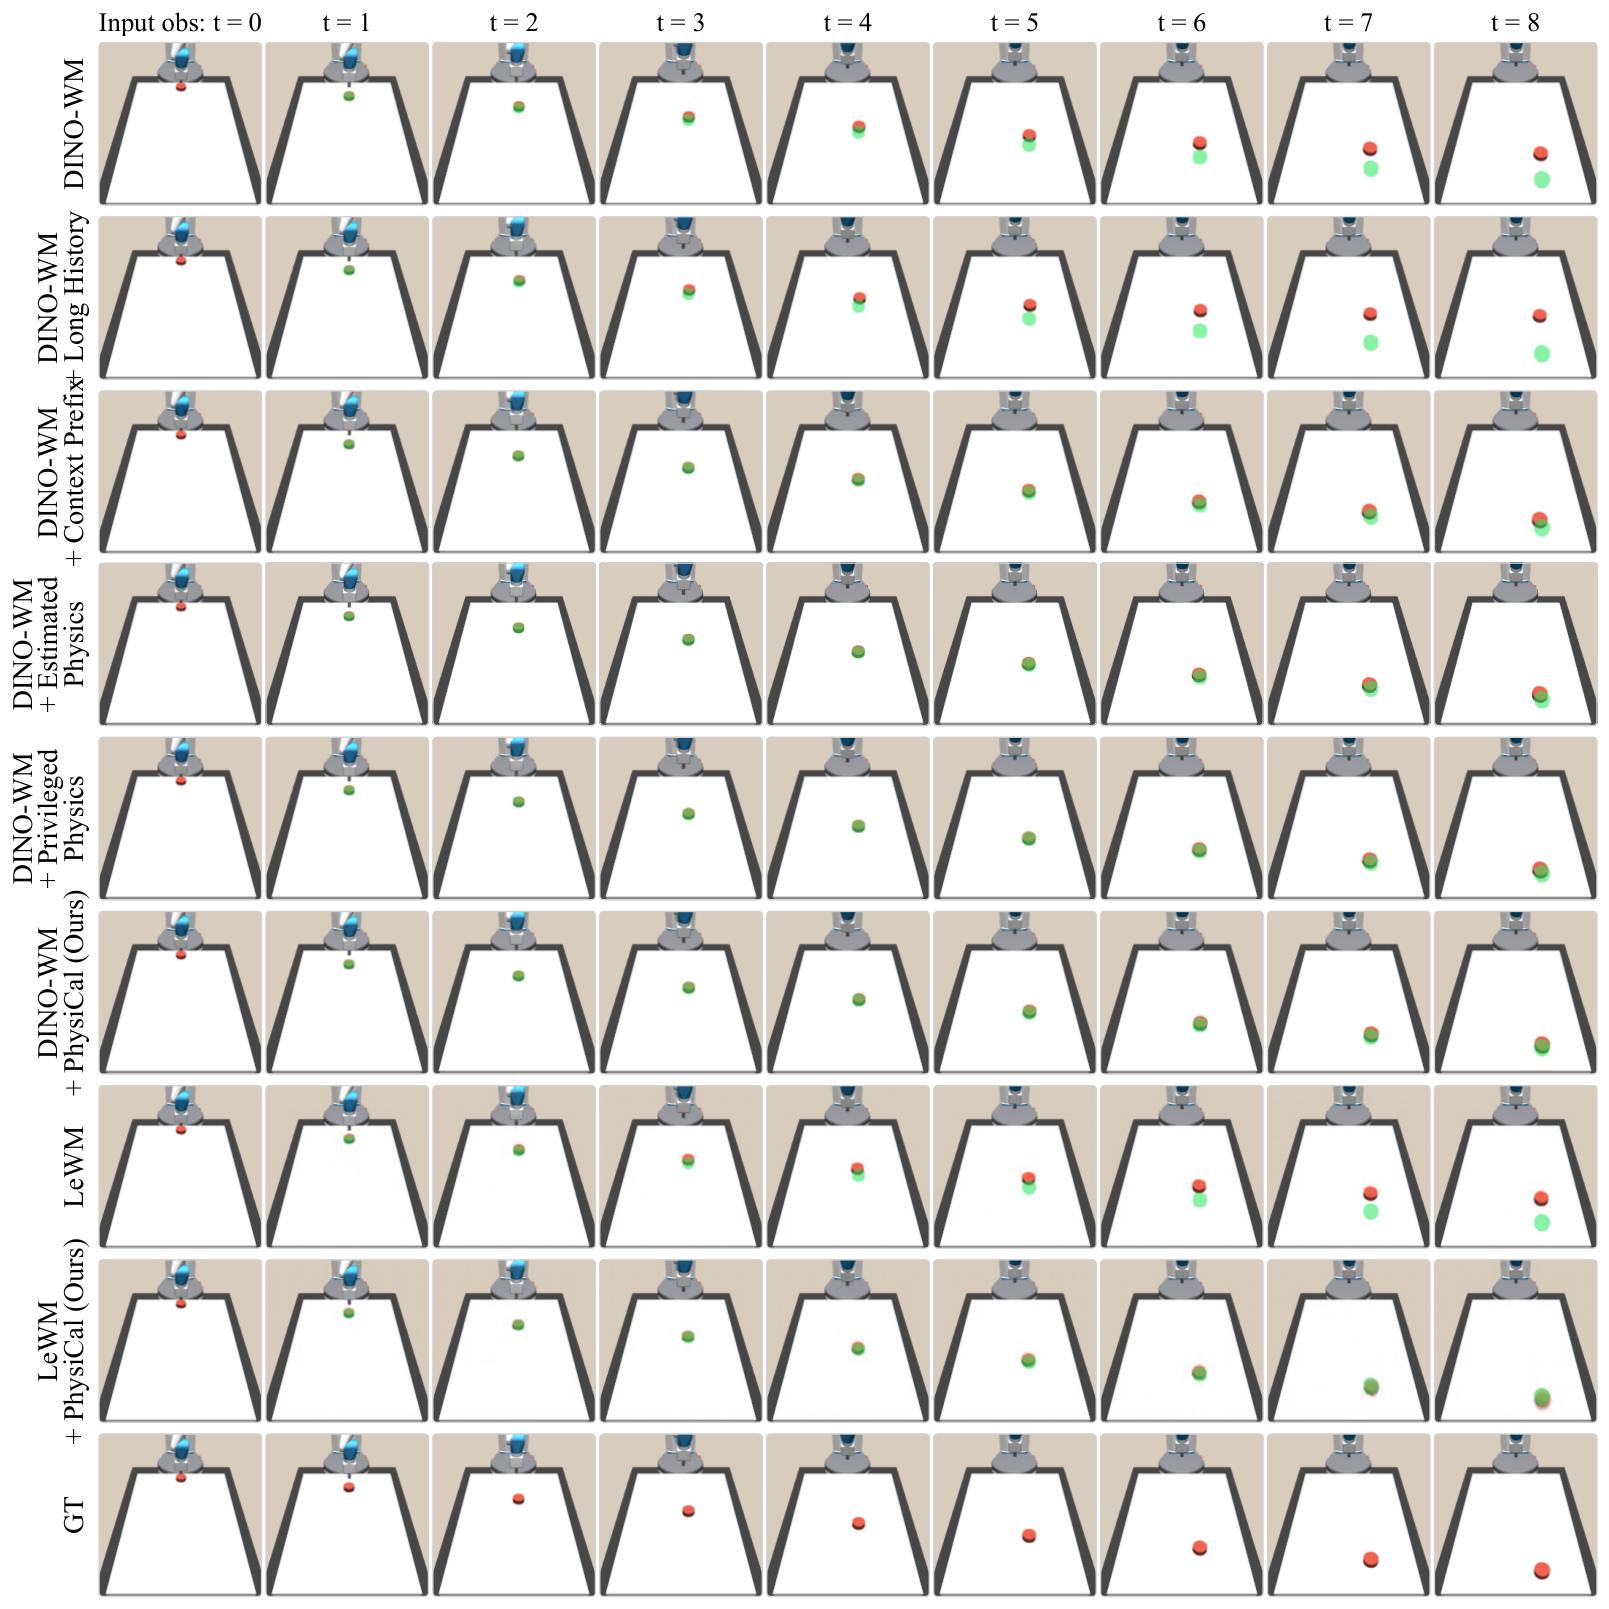
We present additional planning comparisons of both DINO-WM- and LeWM-based models. For each example, we use the world model with CEM to optimize a sequence of actions that reaches the goal observation. Planned actions are executed in the simulated environment. We present both the world models’ predicted observations (top row) and the actual execution in the simulated environments (bottom row). Each planning example is followed by the corresponding interaction clip.